

The DOI matches its Crossref record; 37 of the 37 references it cites were found in a registry or an index.
FastTree 2 – Approximately Maximum-Likelihood Trees for Large Alignments
Open accessAbstract
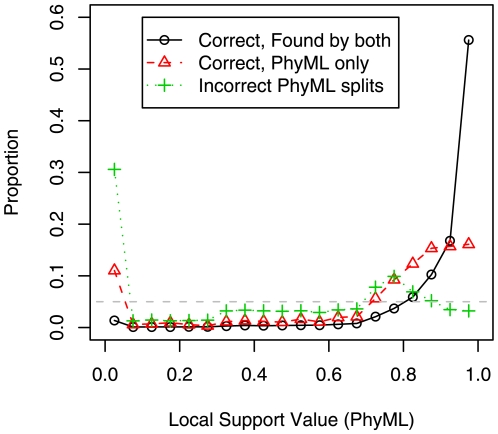
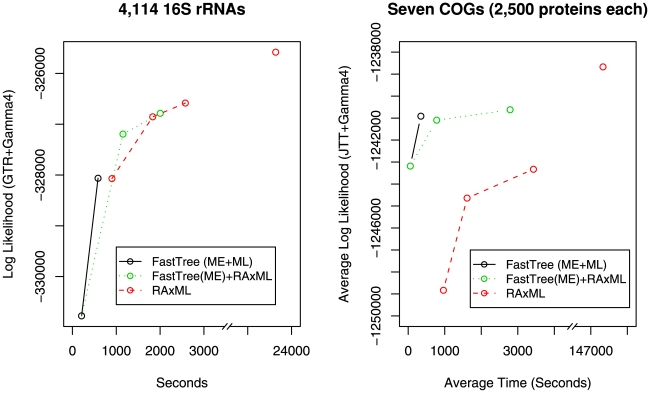
BACKGROUND: We recently described FastTree, a tool for inferring phylogenies for alignments with up to hundreds of thousands of sequences. Here, we describe improvements to FastTree that improve its accuracy without sacrificing scalability. METHODOLOGY/PRINCIPAL FINDINGS: Where FastTree 1 used nearest-neighbor interchanges (NNIs) and the minimum-evolution criterion to improve the tree, FastTree 2 adds minimum-evolution subtree-pruning-regrafting (SPRs) and maximum-likelihood NNIs. FastTree 2 uses heuristics to restrict the search for better trees and estimates a rate of evolution for each site (the "CAT" approximation). Nevertheless, for both simulated and genuine alignments, FastTree 2 is slightly more accurate than a standard implementation of maximum-likelihood NNIs (PhyML 3 with default settings). Although FastTree 2 is not quite as accurate as methods that use maximum-likelihood SPRs, most of the splits that disagree are poorly supported, and for large alignments, FastTree 2 is 100-1,000 times faster. FastTree 2 inferred a topology and likelihood-based local support values for 237,882 distinct 16S ribosomal RNAs on a desktop computer in 22 hours and 5.8 gigabytes of memory. CONCLUSIONS/SIGNIFICANCE: FastTree 2 allows the inference of maximum-likelihood phylogenies for huge alignments. FastTree 2 is freely available at http://www.microbesonline.org/fasttree.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The cited source says what the claim attributes to it.
In the citing paper
“Thus, the validation process for our methods is centered around the comparison of phylogenetic trees estimated from the alignment with FastTree 2.1 (ref. 34).”
From Improving microbial phylogeny with citizen science within a mass-market video game (2025) · cites this paper as [34]
In the citing paper
“On the other hand, FastTree was found to be much faster than RAxML and PhyML but reported lower likelihood scores for data sets with both small and large numbers of sequences (Guindon et al. 2010; Price et al. 2010; Liu et al. 2011).”
From Evaluating fast maximum likelihood-based phylogenetic programs using empirical phylogenomic data sets (2018) · cites this paper as Price et al. 2010
In the citing paper
“So far, these four programs have only been evaluated using simulated data (Guindon et al. 2010; Price et al. 2010; Liu et al. 2011), and empirical data sets with wide ranges of taxon numbers (e.g., up to 237,882 taxa in Price et al. [2010]) but relatively small numbers of genes (from ∼10 [Price et al. 2010; Liu et al. 2011; Chernomor et al. 2016] to ∼200 [Guindon et al. 2010; Money and Whelan 2012”
From Evaluating fast maximum likelihood-based phylogenetic programs using empirical phylogenomic data sets (2018) · cites this paper as Price et al. 2010
In the citing paper
“As a tradeoff, FastTree generates less accurate tree estimates than SPR-based ML methods (Price et al. 2010).”
From Evaluating fast maximum likelihood-based phylogenetic programs using empirical phylogenomic data sets (2018) · cites this paper as Price et al. 2010
In the citing paper
“For example, the recently developed FastTree program can be orders of magnitude faster than either PhyML or RAxML/ExaML (Price et al. 2010).”
From Evaluating fast maximum likelihood-based phylogenetic programs using empirical phylogenomic data sets (2018) · cites this paper as Price et al. 2010
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
The neighbor-joining method: a new method for reconstructing phylogenetic trees.
Saitou, N., & Nei, M. (1987) · Molecular Biology and Evolution · doi:10.1093/oxfordjournals.molbev.a040454 · Cited by 59,959
CONFIDENCE LIMITS ON PHYLOGENIES: AN APPROACH USING THE BOOTSTRAP
Felsenstein, J. (1985) · Evolution · doi:10.1111/j.1558-5646.1985.tb00420.x · Cited by 44,735
DeLong, E. R., DeLong, D. M., & Clarke-Pearson, D. L. (1988) · Biometrics · doi:10.2307/2531595 · Cited by 22,649
Guindon, S., Dufayard, J.-F., Lefort, V., Anisimova, M., Hordijk, W., & Gascuel, O. (2010) · Systematic Biology · doi:10.1093/sysbio/syq010 · Cited by 18,376
A Simple, Fast, and Accurate Algorithm to Estimate Large Phylogenies by Maximum Likelihood
Guindon, S., & Gascuel, O. (2003) · Systematic Biology · doi:10.1080/10635150390235520 · Cited by 16,923
RAxML-VI-HPC: maximum likelihood-based phylogenetic analyses with thousands of taxa and mixed models
Stamatakis, A. (2006) · Bioinformatics · doi:10.1093/bioinformatics/btl446 · Cited by 15,582
Evolutionary trees from DNA sequences: A maximum likelihood approach.
Felsenstein, J. (1981) · Journal of Molecular Evolution · doi:10.1007/bf01734359 · Cited by 14,571
Greengenes, a Chimera-Checked 16S rRNA Gene Database and Workbench Compatible with ARB
DeSantis, T. Z., Hugenholtz, P., Larsen, N., Rojas, M., Brodie, E. L., Keller, K., Huber, T., Dalevi, D., Hu, P., & Andersen, G. L. (2006) · Applied and Environmental Microbiology · doi:10.1128/aem.03006-05 · Cited by 10,891
A Rapid Bootstrap Algorithm for the RAxML Web Servers
Stamatakis, A., Hoover, P., & Rougemont, J. (2008) · Systematic Biology · doi:10.1080/10635150802429642 · Cited by 7,028
FastTree: Computing Large Minimum Evolution Trees with Profiles instead of a Distance Matrix
Price, M. N., Dehal, P. S., & Arkin, A. P. (2009) · Molecular Biology and Evolution · doi:10.1093/molbev/msp077 · Cited by 5,602
Self-citation
Cited by
Sorted by citations
Guindon, S., Dufayard, J.-F., Lefort, V., Anisimova, M., Hordijk, W., & Gascuel, O. (2010) · Systematic Biology · doi:10.1093/sysbio/syq010 · Cited by 18,376
IQ-TREE 2: New Models and Efficient Methods for Phylogenetic Inference in the Genomic Era
Minh, B. Q., Schmidt, H. A., Chernomor, O., Schrempf, D., Woodhams, M. D., von Haeseler, A., & Lanfear, R. (2020) · Molecular Biology and Evolution · doi:10.1093/molbev/msaa015 · Cited by 16,873
OrthoFinder: phylogenetic orthology inference for comparative genomics
Emms, D. M., & Kelly, S. (2019) · Genome Biology · doi:10.1186/s13059-019-1832-y · Cited by 7,676
Pfam: the protein families database
Finn, R. D., Bateman, A., Clements, J., Coggill, P., Eberhardt, R. Y., Eddy, S. R., Heger, A., Hetherington, K., Holm, L., Mistry, J., et al. (2014) · Nucleic Acids Research · doi:10.1093/nar/gkt1223 · Cited by 6,148
McDonald, D. T., Price, M. N., Goodrich, J. K., Nawrocki, E. P., DeSantis, T. Z., Probst, A. J., Andersen, G. L., Knight, R. D., & Hugenholtz, P. (2011) · The ISME Journal · doi:10.1038/ismej.2011.139 · Cited by 5,144
Self-citation
Metadata
- Authors
- Price, M. N., Dehal, P. S., & Arkin, A. P.
- Affiliations
- Lawrence Berkeley National Laboratory (US)
- Corresponding author
- Price, Morgan N.
- Venue
- PLoS ONE
- Publisher
- Public Library of Science (PLoS)
- Published
- 2010-03-10
- Volume
- 5
- Issue
- 3
- Pages
- e9490
- ISSN
- 1932-6203 (ISSN-L)
- PMC
- PMC2835736
- OpenAlex
- W2031611770
- Cited by
- 14,894
- References
- 37
- Citations by year
- 2026: 1298 · 2025: 1543 · 2024: 1657 · 2023: 1486 · 2022: 1676 · 2021: 1651 · 2020: 1363 · 2019: 1013 · 2018: 776 · 2017: 686 · 2016: 521 · 2015: 415 · 2014: 309 · 2013: 256 · 2012: 133
- FWCI
- 63.80
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Locations
- PLoS ONE (publishedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- OSTI OAI (U.S. Department of Energy Office of Scientific and Technical Information) (submittedVersion)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion, cc-by-sa)
- eScholarship (California Digital Library) (submittedVersion)
- eScholarship (California Digital Library) (submittedVersion, cc-by)
- Figshare (submittedVersion, cc-by)
- Funders
- U.S. Department of Energy (-AC02-05CH11231, 05CH11231, DE AC02 05CH11231, DE-AC02-)
- Topics
- Life Sciences › Biochemistry, Genetics and Molecular Biology › Molecular Biology › Genomics and Phylogenetic Studies
- Life Sciences › Biochemistry, Genetics and Molecular Biology › Molecular Biology › RNA and protein synthesis mechanisms
- Life Sciences › Biochemistry, Genetics and Molecular Biology › Molecular Biology › Fractal and DNA sequence analysis
- Keywords
- phylogenetic inference, maximum likelihood phylogeny, nearest neighbor interchange, cat model, 16S rRNA, phylogenetic accuracy, scalability
- MeSH terms
- Algorithms, Animals, Computers, Data Interpretation, Statistical, Genetic Techniques, Humans, Models, Genetic, Phylogeny, RNA, Ribosomal, 16S, Software, Likelihood Functions, Sequence Alignment, Databases, Protein
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
