

The DOI matches its Crossref record; 29 of the 29 references it cites were found in a registry or an index.
100% Classification Accuracy Considered Harmful: The Normalized Information Transfer Factor Explains the Accuracy Paradox
Open accessAbstract
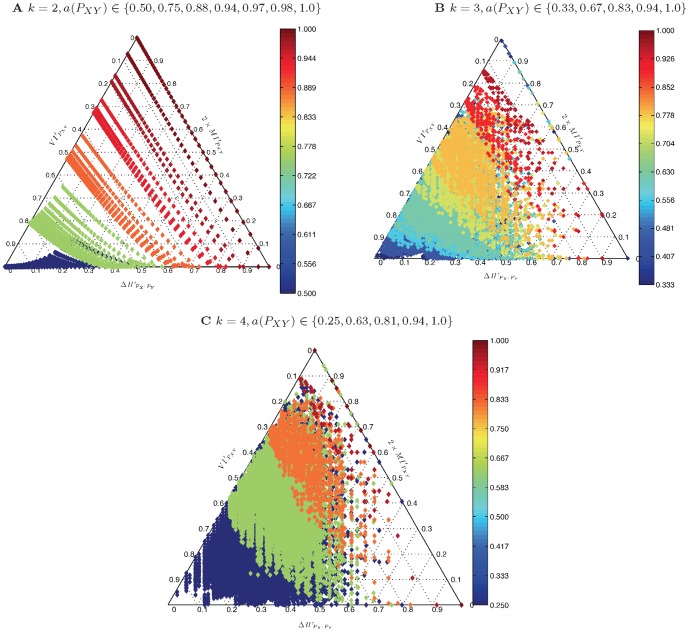
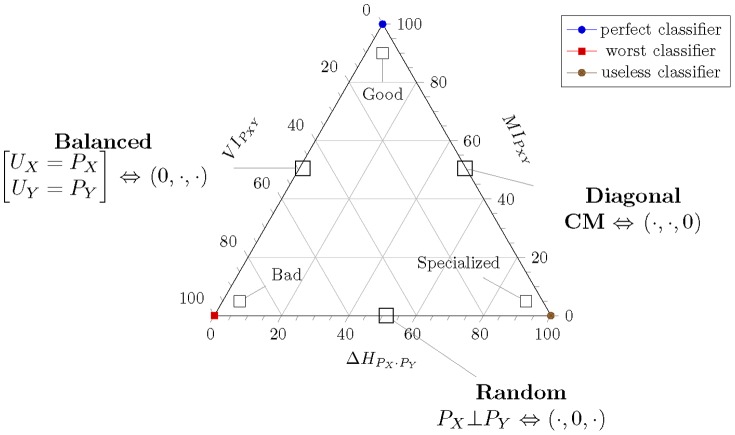
The most widely spread measure of performance, accuracy, suffers from a paradox: predictive models with a given level of accuracy may have greater predictive power than models with higher accuracy. Despite optimizing classification error rate, high accuracy models may fail to capture crucial information transfer in the classification task. We present evidence of this behavior by means of a combinatorial analysis where every possible contingency matrix of 2, 3 and 4 classes classifiers are depicted on the entropy triangle, a more reliable information-theoretic tool for classification assessment. Motivated by this, we develop from first principles a measure of classification performance that takes into consideration the information learned by classifiers. We are then able to obtain the entropy-modulated accuracy (EMA), a pessimistic estimate of the expected accuracy with the influence of the input distribution factored out, and the normalized information transfer factor (NIT), a measure of how efficient is the transmission of information from the input to the output set of classes. The EMA is a more natural measure of classification performance than accuracy when the heuristic to maximize is the transfer of information through the classifier instead of classification error count. The NIT factor measures the effectiveness of the learning process in classifiers and also makes it harder for them to "cheat" using techniques like specialization, while also promoting the interpretability of results. Their use is demonstrated in a mind reading task competition that aims at decoding the identity of a video stimulus based on magnetoencephalography recordings. We show how the EMA and the NIT factor reject rankings based in accuracy, choosing more meaningful and interpretable classifiers.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures

Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“These traditional metrics, however, propagate the underlying biases, ignore the trustworthiness of negative instances and do not take into account the chance-level performance [79,81].”
From A Survey of Underwater Acoustic Data Classification Methods Using Deep Learning for Shoreline Surveillance (2022) · cites this paper as [81]
Experimental — accuracy not yet measured
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
An introduction to ROC analysis
Fawcett, T. (2006) · Pattern Recognition Letters · doi:10.1016/j.patrec.2005.10.010 · Cited by 21,879
Measuring the Accuracy of Diagnostic Systems
Swets, J. A. (1988) · Science · doi:10.1126/science.3287615 · Cited by 10,058
A systematic analysis of performance measures for classification tasks
Sokolova, M., & Lapalme, G. (2009) · Information Processing & Management · doi:10.1016/j.ipm.2009.03.002 · Cited by 7,515
The use of the area under the ROC curve in the evaluation of machine learning algorithms
Bradley, A. P. (1997) · Pattern Recognition · doi:10.1016/s0031-3203(96)00142-2 · Cited by 7,217
Evaluation: from precision, recall and F-measure to ROC, informedness, markedness and correlation
Powers, D. M. W. (2020) · arXiv · doi:10.48550/arxiv.2010.16061 · Cited by 5,440
Comparison of the predicted and observed secondary structure of T4 phage lysozyme
Matthews, B. W. (1975) · Biochimica et Biophysica Acta (BBA) - Protein Structure · doi:10.1016/0005-2795(75)90109-9 · Cited by 5,399 · cited 2×
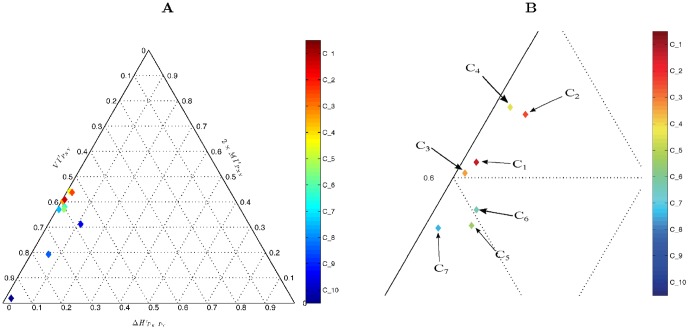
“A comparison of the classical Matthew Correlation Coefficient (MCC) [28] and the Confusion Entropy (CEN) [27]—whose similarities are also explored in [10]–on three different classifications tasks: the MEG Mind Reading task already explored, the TASS sentiment analysis task [29]–both machine learning tasks—and the well…”
MethodSpeech and language processing
Politt, R., Pollock, J., & Waller, E. (2010) · Taylor & Francis eBooks · doi:10.4324/9780203461891_chapter_3 · Cited by 3,594
Assessing the Accuracy of Remotely Sensed Data
Congalton, R. G., & Green, K. (1998) · Mapping sciences series/Mapping science · doi:10.1201/9781420048568 · Cited by 3,434
Statistical methods for speech recognition
Jelinek, F. (1997) · Journal of the American Statistical Association · doi:10.2307/2670189 · Cited by 2,376
An Analysis of Perceptual Confusions Among Some English Consonants
Miller, G. A., & Nicely, P. E. (1955) · The Journal of the Acoustical Society of America · doi:10.1121/1.1907526 · Cited by 1,860
Cited by
Sorted by citations
PANNZER —A practical tool for protein function prediction
Törönen, P., & Holm, L. (2021) · Protein Science · doi:10.1002/pro.4193 · Cited by 195
Benchmarking datasets for Anomaly-based Network Intrusion Detection: KDD CUP 99 alternatives
Divekar, A., Parekh, M., Savla, V., Mishra, R., & Shirole, M. R. (2018) · International Conference on Computing, Communication and Security (ICCCS) · doi:10.1109/cccs.2018.8586840 · Cited by 195
Benedetto, U., Dimagli, A., Sinha, S., Cocomello, L., Gibbison, B., Caputo, M., Gaunt, T. R., Lyon, M., Holmes, C., & Angelini, G. D. (2020) · Journal of Thoracic and Cardiovascular Surgery · doi:10.1016/j.jtcvs.2020.07.105 · Cited by 142
Malek, N. H. A., Yaacob, W. F. W., Nasir, S. A. M., & Shaadan, N. (2022) · Water · doi:10.3390/w14071067 · Cited by 129
Canbek, G., Sağıroğlu, Ş., Temizel, T. T., & Baykal, N. (2017) · doi:10.1109/ubmk.2017.8093539 · Cited by 111
Metadata
- Authors
- Valverde-Albacete, F. J., & Peláez-Moreno, C.
- Affiliations
- Universidad Nacional de Educación a Distancia (ES)
- Universidad Carlos III de Madrid (ES)
- Corresponding author
- Valverde-Albacete, Francisco J.
- Venue
- PLoS ONE
- Publisher
- Public Library of Science (PLoS)
- Published
- 2014-01-10
- Volume
- 9
- Issue
- 1
- Pages
- e84217
- ISSN
- 1932-6203 (ISSN-L)
- PMC
- PMC3888391
- OpenAlex
- W2015363484
- Cited by
- 212
- References
- 29
- Citations by year
- 2026: 13 · 2025: 12 · 2024: 27 · 2023: 14 · 2022: 35 · 2021: 38 · 2020: 20 · 2019: 21 · 2018: 12 · 2017: 8 · 2016: 8 · 2015: 1 · 2014: 2
- FWCI
- 6.31
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Licence
- Locations
- PLoS ONE (publishedVersion, cc-by)
- Europe PMC (PubMed Central) (publishedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- LA Referencia (Red Federada de Repositorios Institucionales de Publicaciones Científicas) (acceptedVersion, cc-by)
- RePEc: Research Papers in Economics (submittedVersion)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion, cc-by-sa)
- e-Archivo (Carlos III University of Madrid) (submittedVersion, cc-by)
- Figshare (submittedVersion, cc-by)
- Funders
- European Commission (288024)
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Machine Learning and Data Classification
- Physical Sciences › Computer Science › Artificial Intelligence › Imbalanced Data Classification Techniques
- Physical Sciences › Computer Science › Information Systems › Data Mining and Machine Learning Applications
- Keywords
- classification performance measures, contingency tables, information transmission, classifier evaluation, interpretability, theory of mind, magnetoencephalography, classification error rate
- MeSH terms
- Algorithms, Humans, Models, Theoretical
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
