

The DOI matches its Crossref record; 21 of the 25 references it cites were found in a registry or an index.
ProofWriter: Generating Implications, Proofs, and Abductive Statements over Natural Language
Open accessAbstract
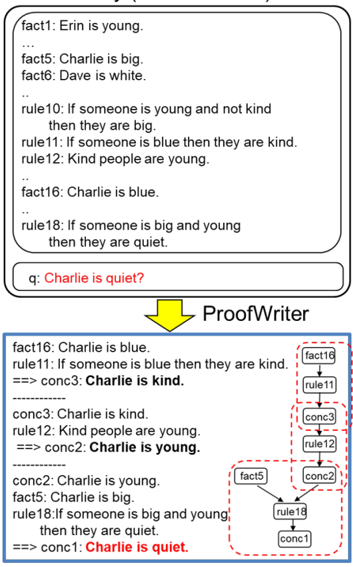
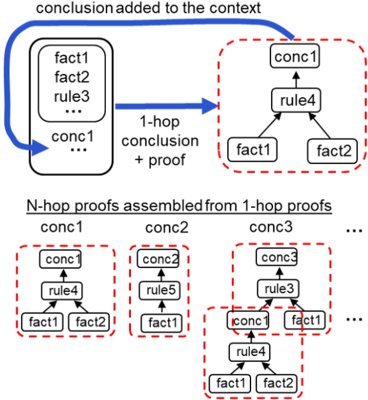
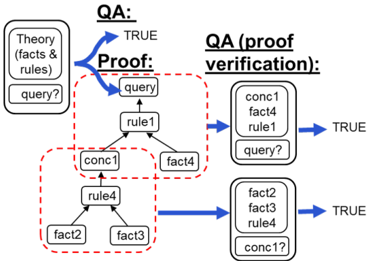
Transformers have been shown to emulate logical deduction over natural language theories (logical rules expressed in natural language), reliably assigning true/false labels to candidate implications.However, their ability to generate implications of a theory has not yet been demonstrated, and methods for reconstructing proofs of answers are imperfect.In this work we show that a generative model, called ProofWriter, can reliably generate both implications of a theory and the natural language proofs that support them.In particular, iterating a 1-step implication generator results in proofs that are highly reliable, and represent actual model decisions (rather than post-hoc rationalizations).On the RuleTaker dataset, the accuracy of ProofWriter's proofs exceed previous methods by +9% absolute, and in a way that generalizes to proof depths unseen in training and on out-of-domain problems.We also show that generative techniques can perform a type of abduction with high precision: Given a theory and an unprovable conclusion, identify a missing fact that allows the conclusion to be proved, along with a proof.These results significantly improve the viability of neural methods for systematically reasoning over natural language.1
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The cited source doesn’t support the claim as written.
In the citing paper
“ProofWriter (Tafjord et al., 2021) is a synthetic dataset created to assess deductive reasoning abilities of LLMs.”
From OpenHands: An Open Platform for AI Software Developers as Generalist Agents (2024) · cites this paper as Tafjord et al., 2021
Checked by a reasoning model — may be wrong.
Experimental — accuracy not yet measuredThe cited source doesn’t support the claim as written.
In the citing paper
“ProofWriter, meanwhile, is a synthetically generated dataset for logical reasoning over natural language.”
From LINC: A Neurosymbolic Approach for Logical Reasoning by Combining Language Models with First-Order Logic Provers (2023) · cites this paper as Tafjord et al., 2021
Checked by a reasoning model — may be wrong.
Experimental — accuracy not yet measuredThe cited source says what the claim attributes to it.
In the citing paper
“Early work on deductive reasoning benchmarks such as RuleTaker (Clark et al., 2020) and ProofWriter (Tafjord et al., 2021) established the basic setup of query answering over sets of rules and facts, with ProofWriter reaching a maximum proof depth of five steps.ProntoQA (Saparov and He, 2023) introduces proof-structure controls and formal error attribution, also evaluated up to five hops.”
From Probing for Long-Horizon Deductive Reasoning Capabilities in Language Models with Prolog (2026) · cites this paper as Tafjord et al., 2021
The cited source says what the claim attributes to it.
In the citing paper
“These benchmarks revealed that models at the time struggle as proof depth increases, but the depths studied remain shallow.”
From Probing for Long-Horizon Deductive Reasoning Capabilities in Language Models with Prolog (2026) · cites this paper as Tafjord et al., 2021
The cited source says what the claim attributes to it.
In the citing paper
“This process is algorithmic; a model that has learned a robust implementation of this algorithm should, in principle, generalize beyond the shallow depths seen in previous benchmarks (Clark et al., 2020;Tafjord et al., 2021;Saparov and He, 2023).”
From Probing for Long-Horizon Deductive Reasoning Capabilities in Language Models with Prolog (2026) · cites this paper as Tafjord et al., 2021
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Hobbs, J. R., Stickel, M. E., Appelt, D. E., & Martin, P. (1988) · Artificial Intelligence · doi:10.1016/0004-3702(93)90015-4 · Cited by 1,222
Applications of circumscription to formalizing common-sense knowledge
McCarthy, J. (1986) · Artificial Intelligence · doi:10.1016/0004-3702(86)90032-9 · Cited by 1,114
McCarthy, J. (1960) · Cited by 799
Language Models as Knowledge Bases?Preprint
Petroni, F., Rocktäschel, T., Lewis, P., Bakhtin, A., Wu, Y., Miller, A., & Riedel, S. (2019) · arXiv (Cornell University) · doi:10.48550/arxiv.1909.01066 · Cited by 714
What you always wanted to know about Datalog (and never dared to ask)
Ceri, S., Gottlob, G., & Tanca, L. (1989) · IEEE Transactions on Knowledge and Data Engineering · doi:10.1109/69.43410 · Cited by 704
ERASER: A Benchmark to Evaluate Rationalized NLP Models
DeYoung, J., Jain, S., Rajani, N. F., Lehman, E., Xiong, C., Socher, R., & Wallace, B. C. (2020) · Proceedings of the 58th Annual Meeting of the Association for Computational Linguistics · doi:10.18653/v1/2020.acl-main.408 · Cited by 561
e-SNLI: Natural language inference with natural language explanations
Camburu, O.-M., Rocktäschel, T., Lukasiewicz, T., & Blunsom, P. (2018) · arXiv · doi:10.48550/arxiv.1812.01193 · Cited by 367 · cited 2×
“Similarly, work on explanations has sought to gen-Proof erate human-style justifications, which again are typically supporting evidence rather than a fully-formed line of reasoning, and without explicit reasoning rules (Camburu et al., 2018; Jhamtani and Clark, 2020; Inoue et al., 2020).”
BackgroundWT5?! Training Text-to-Text Models to Explain their PredictionsPreprint
Narang, S., Raffel, C., Lee, K., Roberts, A., Fiedel, N., & Malkan, K. (2020) · arXiv (Cornell University) · doi:10.48550/arxiv.2004.14546 · Cited by 221
Transformers as Soft Reasoners over Language
Clark, P., Tafjord, O., & Richardson, K. (2020) · Proceedings of the Twenty-Ninth International Joint Conference on Artificial Intelligence · doi:10.24963/ijcai.2020/537 · Cited by 176
Self-citationA Survey on Semantic ParsingPreprint
Kamath, A., & Das, R. (2018) · arXiv (Cornell University) · doi:10.48550/arxiv.1812.00978 · Cited by 117
Research works printed but not linked: 4
- Chandra Bhagavatula, Ronan Le Bras, Chaitanya Malaviya, Keisuke Sakaguchi, Ari Holtzman, Han- nah Rashkin, Doug Downey, S. Yih, and Yejin Choi. 2020. Abductive commonsense reasoning. In ICLR'20.
- Tim Rocktäschel and S. Riedel. 2017. End-to-end dif- ferentiable proving. In NeurIPS.
- Daniel Selsam, Matthew Lamm, Benedikt Bünz, Percy Liang, Leonardo de Moura, and David L. Dill. 2019. Learning a SAT solver from single-bit supervision. In ICLR.
- Alon Talmor, Oyvind Tafjord, P. Clark, Y. Goldberg, and Jonathan Berant. 2020. LeapOfThought: Teach- ing pre-trained models to systematically reason over implicit knowledge. In NeurIPS.
Cited by
Sorted by citations
Logic-LM: Empowering Large Language Models with Symbolic Solvers for Faithful Logical Reasoning
Pan, L., Albalak, A., Wang, X., & Wang, W. Y. (2023) · arXiv · doi:10.48550/arxiv.2305.12295 · Cited by 144
“We randomly selected 300 examples from each subset of ProofWriter, ensuring a balanced label distribution.”
MethodInfluentialReasoning with Language Model Prompting: A Survey
Qiao, S., Ou, Y., Zhang, N., Chen, X., Yao, Y., Deng, S., Tan, C., Huang, F., & Chen, H. (2023) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2023.acl-long.294 · Cited by 346
Large Language Models Can Be Easily Distracted by Irrelevant Context
Shi, F., Chen, X., Misra, K., Scales, N., Dohan, D., Chi, E., Schärli, N., & Zhou, D. (2023) · arXiv · doi:10.48550/arxiv.2302.00093 · Cited by 134
“There exist some logical reasoning benchmarks that contain irrelevant content in task descriptions (Weston et al., 2015; Sinha et al., 2019; Clark et al., 2021; Han et al., 2022; Tafjord et al., 2020, inter alia ).”
BackgroundTowards Faithful Model Explanation in NLP: A Survey
Lyu, Q., Apidianaki, M., & Callison-Burch, C. (2024) · Computational Linguistics · doi:10.1162/coli_a_00511 · Cited by 196
Faith and Fate: Limits of Transformers on Compositionality
Dziri, N., Lu, X., Sclar, M., Li, X. (., Jiang, L., Lin, B. Y., Welleck, S., West, P., Bhagavatula, C., Bras, R. L., et al. (2023) · Advances in Neural Information Processing Systems 36 · doi:10.52202/075280-3081 · Cited by 335
“Lastly, leveraging LLMs to generate each reasoning step iteratively via a selection and inference mechanism [16, 15, 54].”
BackgroundMethod
Metadata
- Authors
- Tafjord, O., Dalvi, B., & Clark, P.
- Affiliations
- Allen Institute for Artificial Intelligence (US)
- ORCID
- Clark, Peter
- Venue
- Findings of the Association for Computational Linguistics: ACL-IJCNLP 2021
- Published
- 2021
- Pages
- 3621-3634
- OpenAlex
- W3115201256
- Cited by
- 122
- References
- 25
- Citations by year
- 2026: 22 · 2025: 18 · 2024: 14 · 2023: 32 · 2022: 27 · 2021: 9
- FWCI
- 9.47
- Type
- conference paper
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- cc-by
- Locations
- Findings of the Association for Computational Linguistics: ACL (Findings of ACL) (publishedVersion, cc-by)
- arXiv (Cornell University) (submittedVersion)
- arXiv (Cornell University)
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Topic Modeling
- Physical Sciences › Computer Science › Artificial Intelligence › Logic, Reasoning, and Knowledge
- Physical Sciences › Computer Science › Artificial Intelligence › Natural Language Processing Techniques
- Keywords
- proof generation, abductive reasoning, large language models, generative models
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
