

The DOI matches its Crossref record; 34 of the 34 references it cites were found in a registry or an index; none of the 7 sources its claims cite is checked for support yet.
Towards Understanding Chain-of-Thought Prompting: An Empirical Study of What Matters
Open accessAbstract
Boshi Wang, Sewon Min, Xiang Deng, Jiaming Shen, You Wu, Luke Zettlemoyer, Huan Sun. Proceedings of the 61st Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers). 2023.
Overview
AI snapshot
Written from the paper’s full text.
TL;DR
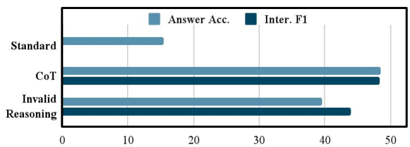
Chain-of-Thought (CoT) prompting remains effective even when the demonstrated rationales contain invalid reasoning, retaining over 80–90% of CoT performance under various metrics. The key factors for effective CoT are that rationales stay relevant to the query and that their steps are correctly ordered, rather than being logically valid.
Key findings
- Invalid reasoning in demonstrations still yields high performance: on GSM8K with text-davinci-002, CoT reaches 48.3 Inter. F1 and 48.5 Answer Acc., while invalid reasoning reaches 43.9 Inter. F1 and 39.5 Answer Acc.; on Bamboogle, CoT reaches 45.2 Inter. Recall and 45.2 Answer F1, while invalid reasoning reaches 44.4 Inter. Recall and 39.4 Answer F1.
- Relevance and coherence are key: the “no relevance” setting (both components irrelevant) underperforms standard prompting on GSM8K (11.0 Answer Acc. vs. 15.4 for STD), and “no coherence for language templates” drops to 28.3 Inter. F1 from CoT’s 48.3.
- For bridging objects, relevance matters more than coherence: incoherent bridging objects achieve 39.2 Inter. F1 on GSM8K, while irrelevant bridging objects achieve 26.2 Inter. F1.
- At the instance level, there are cases where CoT is wrong and invalid reasoning is correct: 62/196 for GSM8K and 6/20 for Bamboogle.
Methods
- The authors run ablation experiments on two multi-step reasoning tasks: arithmetic reasoning on GSM8K (800 of 1319 test examples sampled) and multi-hop factual QA on Bamboogle (all 125 test samples).
- Main backbone is InstructGPT-175B text-davinci-002 with greedy decoding; additional results are reported for text-davinci-003, PaLM, and Flan-PaLM in the appendix.
- Ablations alter CoT rationales by invalid reasoning, destroying relevance or coherence of bridging objects and language templates, and combined no-relevance/no-coherence settings; evaluation includes extrinsic answer accuracy/F1 and intrinsic Recall/F1 of bridging objects.
Limitations
- Stated: experiments cover only arithmetic reasoning and multi-hop QA; symbolic tasks are hard to ablate because their rationales are highly template-based with little variation.
- Stated: invalid reasoning rationales were manually written, and a more systematic treatment of invalid reasoning is left for future work.
- Stated: intrinsic evaluation relies on correctness of bridging objects and ground-truth annotations, which may not generalize and are costly to obtain; evident from the checklist: all results are reported with a single run due to limited budgets.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
33 Own result · 17 Own interpretation · 6 Not checked yet · 5 Own method · 2 No basis given
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“In this paper, we show that CoT reasoning is possible even with invalid demonstrations-prompting with invalid reasoning steps can achieve over 80-90% of the performance obtained using CoT under various metrics, while still generating coherent lines of reasoning during inference.”
- Also stated in: § Invalid Reasoning · plain
“We find that valid reasoning for the demonstrations matters only a small portion to the performance of CoT-by providing rationales with invalid reasoning, LLMs can achieve over 80-90% of the performance of CoT under various metrics while performing logically sound and pertinent reasoning.”
- Also stated in: § Invalid Reasoning · plain
“by providing rationales with completely invalid reasoning steps, the LLM can still achieve over 80-90% of the performance of CoT under various metrics while generating coherent lines of reasoning towards the answer ( §4).”
§ Towards Understanding Chain-of-Thought Prompting: An Empirical Study of What Matters > Abstract
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Also stated in: § Invalid Reasoning · plain
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“In particular, under Inter.Recall/Inter.F1, i.e., intrinsic evaluation, which is arguably a more faithful measurement of the rationale quality ( §3.3), all LLMs we tested can retain over 90% of the performance achieved under CoT prompting.”
§ Towards Understanding Chain-of-Thought Prompting: An Empirical Study of What Matters > 4.2 Results & Analysis
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“By checking the generated rationales for the invalid reasoning setting, we find that overall they look indistinguishable from the rationales generated by CoT prompting.”
§ Towards Understanding Chain-of-Thought Prompting: An Empirical Study of What Matters > 4.2 Results & Analysis
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“At the instance level, after omitting samples where both settings get the correct/wrong answer, there is a significant portion for the remaining ones (62/196 for GSM8K, 6/20 for Bamboogle) where CoT gets the wrong answer and the invalid reasoning setting gets the correct answer.”
§ Towards Understanding Chain-of-Thought Prompting: An Empirical Study of What Matters > 4.2 Results & Analysis
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Providing incoherent bridging objects ( 2 ) achieves better performance than providing irrelevant bridging objects ( 3 ), especially on the more challenging GSM8K dataset (39.2 v.s.26.2 Inter.F1).”
§ Towards Understanding Chain-of-Thought Prompting: An Empirical Study of What Matters > PaLM and Flan-PaLM in Appendix A.3. We summarize the main findings in what follows.
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
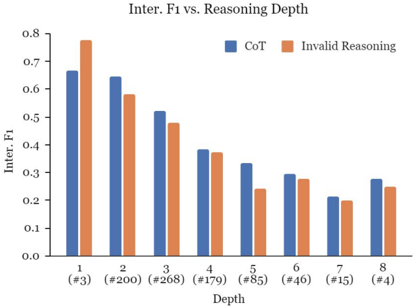
“The performance drop is also uniform across samples with different levels of difficulty.”
§ Towards Understanding Chain-of-Thought Prompting: An Empirical Study of What Matters > 4.2 Results & Analysis
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“while still generating coherent lines of reasoning during inference.”
- Also stated in: § Invalid Reasoning · plain
“while generating coherent lines of reasoning towards the answer ( §4).”
- Also stated in: § Invalid Reasoning · plain
“while performing logically sound and pertinent reasoning.”
§ Towards Understanding Chain-of-Thought Prompting: An Empirical Study of What Matters > Abstract
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Also stated in: § Invalid Reasoning · plain
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Different from the coherence of bridging objects 2 , the coherence of language templates 4 matters a lot to the performance of CoT prompting.”
§ Towards Understanding Chain-of-Thought Prompting: An Empirical Study of What Matters > PaLM and Flan-PaLM in Appendix A.3. We summarize the main findings in what follows.
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Further experiments show that other aspects of the rationales, such as being relevant to the query and correctly ordering the reasoning steps, are much more important for effective CoT reasoning.”
- Also stated in: § Invalid Reasoning · plain
“Through further examinations, we identify and formulate other aspects of a CoT rationale ( §5), and find that being relevant to the query and correctly ordering the reasoning steps are the key for the effectiveness of CoT prompting.”
§ Towards Understanding Chain-of-Thought Prompting: An Empirical Study of What Matters > Abstract
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Also stated in: § Invalid Reasoning · plain
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The distributions of errors in both cases are highly similar.”
§ Towards Understanding Chain-of-Thought Prompting: An Empirical Study of What Matters > 4.2 Results & Analysis
plainn = 20- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- It may state two separate claims as one. 15
- Probably not a substantial claim. 6
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“It can be seen that most of the settings for this section ( 2 -7 ) have rather large performance drops from CoT, where the low-performing ones approach or even underperform standard prompting.”
§ Towards Understanding Chain-of-Thought Prompting: An Empirical Study of What Matters > PaLM and Flan-PaLM in Appendix A.3. We summarize the main findings in what follows.
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“By examining the predicted rationales, we find that the LLM is indeed generating rationales with incoherent language templates (14 out of 20 examples), which negatively affects reasoning.”
§ Towards Understanding Chain-of-Thought Prompting: An Empirical Study of What Matters > PaLM and Flan-PaLM in Appendix A.3. We summarize the main findings in what follows.
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The no relevance setting 7 where both components of the rationale have no relevance achieves significantly poorer performance than other ablation settings, and even underperforms standard prompting (STD) where no rationale is given on GSM8K.”
§ Towards Understanding Chain-of-Thought Prompting: An Empirical Study of What Matters > PaLM and Flan-PaLM in Appendix A.3. We summarize the main findings in what follows.
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“In almost all cases where the predicted final answer is correct, the rationales do reach the answer with valid and sound reasoning steps (as in CoT), drastically different from those in the given demonstrations; for cases where the final answer is wrong, the errors the LLM makes are also in the same types with the errors made under CoT prompting.”
§ Towards Understanding Chain-of-Thought Prompting: An Empirical Study of What Matters > 4.2 Results & Analysis
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Each step of a rationale still follows the previous steps.”
§ Towards Understanding Chain-of-Thought Prompting: An Empirical Study of What Matters > 4.2 Results & Analysis
plaindirectSingle case- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The rationales still use information from the query; more specifically, they still start from bridging objects mentioned in the query, and the language templates are related to the query.”
§ Towards Understanding Chain-of-Thought Prompting: An Empirical Study of What Matters > 4.2 Results & Analysis
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“In particular, providing invalid reasoning for the rationales ( 1 ) overall only marginally harms the performance, and even outperforms CoT on GSM8K under intrinsic evaluation.”
§ Towards Understanding Chain-of-Thought Prompting: An Empirical Study of What Matters > A.3 Additional Results & Discussion
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“For the remaining settings where we ablate the relevance/coherence ( 2 -7 ), the same trend can be observed on the challenging GSM8K dataset, e.g., the model still suffers a lot when providing rationales that are irrelevant or have incoherent language templates.”
§ Towards Understanding Chain-of-Thought Prompting: An Empirical Study of What Matters > A.3 Additional Results & Discussion
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“For the relatively easier Bamboogle dataset, the high model capacity indicated by its impressive performance has basically erased significant impacts from the ablations, with the only standing observation that the model still needs the rationales to be relevant to maintain its performance.”
§ Towards Understanding Chain-of-Thought Prompting: An Empirical Study of What Matters > A.3 Additional Results & Discussion
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We do not use whole equations since we observe that the LLM may express the mathematical equation in different ways, e.g., “5 plus 3 is 8”, “5 + 3 = 8”.”
§ Towards Understanding Chain-of-Thought Prompting: An Empirical Study of What Matters > 2729
hedgedconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Relevance and coherence are key for the performance of CoT prompting.”
- Also stated in: § PaLM and Flan-PaLM in Appendix A.3. We summarize the main findings in what follows. · hedged
“This suggests that overall, relevance and coherence are key for the performance of CoT.”
§ Towards Understanding Chain-of-Thought Prompting: An Empirical Study of What Matters > PaLM and Flan-PaLM in Appendix A.3. We summarize the main findings in what follows.
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Also stated in: § PaLM and Flan-PaLM in Appendix A.3. We summarize the main findings in what follows. · hedged
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“which indicates that it is important for the bridging objects to be relevant, but not as important to have them in the right order to guide the LLM along the reasoning process.”
§ Towards Understanding Chain-of-Thought Prompting: An Empirical Study of What Matters > PaLM and Flan-PaLM in Appendix A.3. We summarize the main findings in what follows.
hedgeddirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“Our intrinsic evaluation of the generated rationales is based on the correctness of bridging objects, which, even though is a good indicator of the quality of language templates (Appendix A.2) in our experiments, may not be a good metric in general cases.”
§ Towards Understanding Chain-of-Thought Prompting: An Empirical Study of What Matters > Limitations
hedged- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“However, most (if not all) tasks there are highly templatebased and hence the reasoning steps have little variations, both within each example and across different examples.”
§ Towards Understanding Chain-of-Thought Prompting: An Empirical Study of What Matters > Limitations
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper may give no reason why it holds. It may state two separate claims as one.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“These edits only slightly affect the performance of CoT; we show our edited demonstration examples and include more details in Appendix A.1.”
§ Towards Understanding Chain-of-Thought Prompting: An Empirical Study of What Matters > 3.1 Datasets & In-context Exemplars
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“Due to limited budgets, we report all results with a single run.This is transparent from the paper.”
§ Towards Understanding Chain-of-Thought Prompting: An Empirical Study of What Matters > Additional information
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
In the paper
“LLMs may over-rely on their prior knowledge and ignore important information in the context that are presumably rare in the pretraining distribution, including those that are crucial for specifying the task semantics”
- Also stated in: § A.3 Additional Results & Discussion · hedged
“LLMs may over-rely on their prior knowledge and ignore important information in the context, including those that are crucial for specifying the task semantics”
§ Towards Understanding Chain-of-Thought Prompting: An Empirical Study of What Matters > 6 Discussion
What the sources say
- Not checked yetcites Jang et al., 2023
hedgedconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Also stated in: § A.3 Additional Results & Discussion · hedged
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“It also relies on ground truth bridging objects, which are usually not available and costly to annotate.”
§ Towards Understanding Chain-of-Thought Prompting: An Empirical Study of What Matters > Limitations
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. The paper may give no reason why it holds. It may state two separate claims as one.
The paper relies on this without support.
There is little understanding of what makes CoT prompting effective and which aspects of the demonstrated reasoning steps contribute to its performance.
“Despite its success, there is still little understanding of what makes CoT prompting effective and which aspects of the demonstrated reasoning steps contribute to its performance.”
The paper relies on this without support.
The two tasks used, arithmetic reasoning and multi-hop factual question answering, are representative of multi-step reasoning tasks.
“We experiment on two representative tasks involving multi-step reasoning: arithmetic reasoning & multi-hop factual question answering (QA).”
The paper relies on this without support.
Pretraining corpora are not always accessible.
“However, the pretraining corpora are not always accessible”
The paper relies on this without support.
Low-level statistics are usually not adequate when the topics of interest are abstract and high-level skills such as reasoning.
“low-level statistics are usually not adequate when the topics of interest are abstract and highlevel skills such as reasoning”
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
“Self-consistency [66] and ensemble refinement [9] are strategies that sample multiple model answers to arrive at a more consistent response, improving model reliability [9].”
From The Opportunities and Risks of Large Language Models in Mental Health (2024) · cites this paper as [66]
Citations
Cites
Language Models are Few-Shot Learners
Brown, T. B., Mann, B., Ryder, N., Subbiah, M., Kaplan, J., Dhariwal, P., Neelakantan, A., Shyam, P., Sastry, G., Askell, A., et al. (2020) · arXiv · doi:10.48550/arxiv.2005.14165 · Cited by 23,372
Chain-of-Thought Prompting Elicits Reasoning in Large Language Models
Wei, J., Wang, X., Schuurmans, D., Bosma, M., Ichter, B., Xia, F., Chi, E., Le, Q., & Zhou, D. (2022) · arXiv · doi:10.48550/arxiv.2201.11903 · Cited by 4,263
Training language models to follow instructions with human feedback
Ouyang, L., Wu, J., Jiang, X., Almeida, D., Wainwright, C. L., Mishkin, P., Zhang, C., Agarwal, S., Slama, K., Ray, A., et al. (2022) · arXiv · doi:10.48550/arxiv.2203.02155 · Cited by 4,208
PaLM: Scaling Language Modeling with Pathways
Chowdhery, A., Narang, S., Devlin, J., Bosma, M., Mishra, G., Roberts, A., Barham, P., Chung, H. W., Sutton, C., Gehrmann, S., et al. (2022) · arXiv · doi:10.48550/arxiv.2204.02311 · Cited by 2,590
Scaling Instruction-Finetuned Language Models
Chung, H. W., Hou, L., Longpre, S., Zoph, B., Tay, Y., Fedus, W., Li, Y., Wang, X., Dehghani, M., Brahma, S., et al. (2022) · arXiv · doi:10.48550/arxiv.2210.11416 · Cited by 1,441
Self-Consistency Improves Chain of Thought Reasoning in Language Models
Wang, X., Wei, J., Schuurmans, D., Le, Q., Chi, E., Narang, S., Chowdhery, A., & Zhou, D. (2022) · arXiv · doi:10.48550/arxiv.2203.11171 · Cited by 829
Rethinking the Role of Demonstrations: What Makes In-Context Learning Work?
Min, S., Lyu, X., Holtzman, A., Artetxe, M., Lewis, M., Hajishirzi, H., & Zettlemoyer, L. (2022) · Proceedings of the 2022 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/2022.emnlp-main.759 · Cited by 755
Self-citationRethinking the Role of Demonstrations: What Makes In-Context Learning Work?
Min, S., Lyu, X., Holtzman, A., Artetxe, M., Lewis, M., Hajishirzi, H., & Zettlemoyer, L. (2022) · arXiv · doi:10.48550/arxiv.2202.12837 · Cited by 752
Self-citationTraining Verifiers to Solve Math Word Problems
Cobbe, K., Kosaraju, V., Bavarian, M., Chen, M., Jun, H., Kaiser, L., Plappert, M., Tworek, J., Hilton, J., Nakano, R., et al. (2021) · arXiv · doi:10.48550/arxiv.2110.14168 · Cited by 575
Beyond the Imitation Game: Quantifying and extrapolating the capabilities of language models
Srivastava, A., Rastogi, A., Rao, A., Shoeb, A. A. M., Abid, A., Fisch, A., Brown, A. R., Santoro, A., Gupta, A., Garriga-Alonso, A., et al. (2022) · arXiv · doi:10.48550/arxiv.2206.04615 · Cited by 569
Towards Reasoning in Large Language Models: A Survey
Huang, J., & Chang, K. C.-C. (2023) · Findings of the Association for Computational Linguistics: ACL 2023 · doi:10.18653/v1/2023.findings-acl.67 · Cited by 428
Towards Reasoning in Large Language Models: A Survey
Huang, J., & Chang, K. C.-C. (2022) · arXiv · doi:10.48550/arxiv.2212.10403 · Cited by 428
Measuring and Narrowing the Compositionality Gap in Language Models
Press, O., Zhang, M., Min, S., Schmidt, L., Smith, N., & Lewis, M. (2023) · Findings of the Association for Computational Linguistics: EMNLP 2023 · doi:10.18653/v1/2023.findings-emnlp.378 · Cited by 303
Self-citationMeasuring and Narrowing the Compositionality Gap in Language Models
Press, O., Zhang, M., Min, S., Schmidt, L., Smith, N. A., & Lewis, M. (2022) · arXiv · doi:10.48550/arxiv.2210.03350 · Cited by 294
Self-citationAutomatic Chain of Thought Prompting in Large Language Models
Zhang, Z., Zhang, A., Li, M., & Smola, A. (2022) · arXiv · doi:10.48550/arxiv.2210.03493 · Cited by 274
Challenging BIG-Bench Tasks and Whether Chain-of-Thought Can Solve Them
Suzgun, M., Scales, N., Schärli, N., Gehrmann, S., Tay, Y., Chung, H. W., Chowdhery, A., Le, Q., Chi, E., Zhou, D., et al. (2023) · Findings of the Association for Computational Linguistics: ACL 2023 · doi:10.18653/v1/2023.findings-acl.824 · Cited by 253
On the Measure of Intelligence
Chollet, F. (2019) · arXiv · doi:10.48550/arxiv.1911.01547 · Cited by 218
Do Prompt-Based Models Really Understand the Meaning of Their Prompts?
Webson, A., & Pavlick, E. (2022) · Proceedings of the 2022 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies · doi:10.18653/v1/2022.naacl-main.167 · Cited by 203
An Explanation of In-context Learning as Implicit Bayesian Inference
Xie, S. M., Raghunathan, A., Liang, P., & Ma, T. (2021) · arXiv · doi:10.48550/arxiv.2111.02080 · Cited by 138
Complementary Explanations for Effective In-Context LearningPreprint
Ye, X., Iyer, S., Celikyilmaz, A., Stoyanov, V., Durrett, G., & Pasunuru, R. (2022) · Annual Meeting of the Association for Computational Linguistics · doi:10.48550/arxiv.2211.13892 · Cited by 127
Chen, W., Ma, X., Wang, X., & Cohen, W. W. (2022) · arXiv · doi:10.48550/arxiv.2211.12588 · Cited by 125
Larger language models do in-context learning differently
Wei, J., Wei, J., Tay, Y., Tran, D., Webson, A., Lu, Y., Chen, X., Liu, H., Huang, D., Zhou, D., et al. (2023) · arXiv · doi:10.48550/arxiv.2303.03846 · Cited by 109
Ground-Truth Labels Matter: A Deeper Look into Input-Label Demonstrations
Yoo, K. M., Kim, J., Kim, H. J., Cho, H., Jo, H., Lee, S., Lee, S., & Kim, T. (2022) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2022.emnlp-main.155 · Cited by 91
Impact of Pretraining Term Frequencies on Few-Shot Numerical Reasoning
Razeghi, Y., Logan IV, R. L., Gardner, M., & Singh, S. (2022) · Findings of the Association for Computational Linguistics: EMNLP 2022 · doi:10.18653/v1/2022.findings-emnlp.59 · Cited by 89
What learning algorithm is in-context learning? Investigations with linear models
Akyürek, E., Schuurmans, D., Andreas, J., Ma, T., & Zhou, D. (2022) · arXiv · doi:10.48550/arxiv.2211.15661 · Cited by 86
Complementary Explanations for Effective In-Context Learning
Ye, X., Iyer, S. V., Çelikyılmaz, A., Stoyanov, V., Durrett, G., & Pasunuru, R. (2023) · Findings of the Association for Computational Linguistics: ACL (Findings of ACL) · doi:10.18653/v1/2023.findings-acl.273 · Cited by 79
Language Models Are Greedy Reasoners: A Systematic Formal Analysis of Chain-of-Thought
Saparov, A., & He, H. (2022) · arXiv · doi:10.48550/arxiv.2210.01240 · Cited by 46
Challenging BIG-Bench Tasks and Whether Chain-of-Thought Can Solve Them
Suzgun, M., Scales, N., Schärli, N., Gehrmann, S., Tay, Y., Chung, H. W., Chowdhery, A., Le, Q. V., Chi, E. H., Zhou, D., et al. (2022) · arXiv · doi:10.48550/arxiv.2210.09261 · Cited by 44
Can Large Language Models Truly Understand Prompts? A Case Study with Negated PromptsPreprint
Jang, J., Ye, S., & Seo, M. (2022) · arXiv (Cornell University) · doi:10.48550/arxiv.2209.12711 · Cited by 39
ROSCOE: A Suite of Metrics for Scoring Step-by-Step ReasoningPreprint
Golovneva, O., Chen, M., Poff, S., Corredor, M., Zettlemoyer, L., Fazel-Zarandi, M., & Çelikyılmaz, A. (2022) · arXiv (Cornell University) · doi:10.48550/arxiv.2212.07919 · Cited by 37
Self-citationText and Patterns: For Effective Chain of Thought, It Takes Two to Tango
Madaan, A., & Yazdanbakhsh, A. (2022) · arXiv · doi:10.48550/arxiv.2209.07686 · Cited by 24
Ji, Y., & Gao, S. (2023) · DROPS (Schloss Dagstuhl – Leibniz Center for Informatics) · doi:10.4230/lipics.giscience.2023.43 · Cited by 10
Ground-Truth Labels Matter: A Deeper Look into Input-Label Demonstrations
Yoo, K. M., Kim, J., Kim, H. J., Cho, H., Jo, H., Lee, S.-W., Lee, S.-G., & Kim, T. (2022) · arXiv · doi:10.48550/arxiv.2205.12685 · Cited by 2
Assessing the (In)Ability of LLMs to Reason in Interval Temporal Logic
Bellodi, P., Casavecchia, P., Paparella, A., Sciavicco, G., & Stan, E. I. (2025) · Time · doi:10.4230/lipics.time.2025.4
Research works printed but not linked: 2
- Irving Copi, Carl Cohen, and Victor Rodych. 2016. In- troduction to logic. Routledge.
- Shivam Garg, Dimitris Tsipras, Percy S Liang, and Gre- gory Valiant. 2022. What can transformers learn in- context? a case study of simple function classes. In Advances in Neural Information Processing Systems, volume 35, pages 30583-30598.
Cited by
Sorted by citations
Toward expert-level medical question answering with large language models
Singhal, K., Tu, T., Gottweis, J., Sayres, R., Wulczyn, E., Amin, M., Hou, L., Clark, K., Pfohl, S. R., Cole-Lewis, H., et al. (2025) · Nature Medicine · doi:10.1038/s41591-024-03423-7 · Cited by 1,734
Explainability for Large Language Models: A Survey
Zhao, H., Chen, H., Yang, F., Liu, N., Deng, H., Cai, H., Wang, S., Yin, D., & Du, M. (2024) · ACM Transactions on Intelligent Systems and Technology · doi:10.1145/3639372 · Cited by 681
Towards Reasoning in Large Language Models: A Survey
Huang, J., & Chang, K. C.-C. (2023) · Findings of the Association for Computational Linguistics: ACL 2023 · doi:10.18653/v1/2023.findings-acl.67 · Cited by 428
Plan-and-Solve Prompting: Improving Zero-Shot Chain-of-Thought Reasoning by Large Language Models
Wang, L., Xu, W., Lan, Y., Hu, Z., Lan, Y., Lee, R. K.-W., & Lim, E.-P. (2023) · Proceedings of the 61st Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) · doi:10.18653/v1/2023.acl-long.147 · Cited by 344
Mersha, M. A., Lâm, K. N., Wood, J., AlShami, A. K., & Kalita, J. K. (2024) · Neurocomputing · doi:10.1016/j.neucom.2024.128111 · Cited by 346
Metadata
- Authors
- Wang, B., Min, S., Deng, X., Shen, J., Wu, Y., Zettlemoyer, L., & Sun, H.
- Affiliations
- The Ohio State University (US)
- University of Washington (US)
- Google (United States) (US)
- Venue
- Proceedings of the 61st Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers)
- Published
- 2023
- Pages
- 2717-2739
- ISSN
- 0736-587X (ISSN-L)
- OpenAlex
- W4385571045
- Cited by
- 120
- References
- 26
- Citations by year
- 2026: 23 · 2025: 57 · 2024: 22 · 2023: 18
- FWCI
- 21.26
- Type
- conference paper
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- cc-by
- Locations
- Proceedings of the conference - Association for Computational Linguistics. Meeting (publishedVersion, cc-by)
- Funders
- National Science Foundation (1942980, 2112606, 1815674, CAREER)
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Topic Modeling
- Physical Sciences › Computer Science › Artificial Intelligence › Natural Language Processing Techniques
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Multimodal Machine Learning Applications
- Keywords
- chain-of-thought prompting, large language models, prompting strategies, LLM reasoning
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
A language model drew the claims from the paper on 2026-10-06, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-10-06 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
