

The DOI matches its Crossref record; 10 of the 10 references it cites were found in a registry or an index.
SciRepEval: A Multi-Format Benchmark for Scientific Document Representations
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
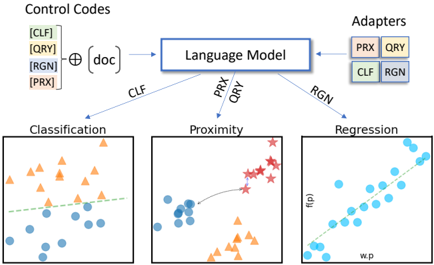
“Its successor, SPECTER2 (Singh et al., 2023), provides improved performance by training on 10x more data and introducing a new method that learns adapters (Houlsby et al., 2019) tailored to specific task formats.”
From The Semantic Scholar Open Data Platform (2023) · cites this paper as Singh et al., 2023
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2019) · Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers) · doi:10.18653/v1/n19-1423 · Cited by 54,325
Language Models are Few-Shot Learners
Brown, T. B., Mann, B., Ryder, N., Subbiah, M., Kaplan, J., Dhariwal, P., Neelakantan, A., Shyam, P., Sastry, G., Askell, A., et al. (2020) · arXiv · doi:10.48550/arxiv.2005.14165 · Cited by 23,372
Deep Contextualized Word Representations
Peters, M., Neumann, M., Iyyer, M., Gardner, M., Clark, C., Lee, K., & Zettlemoyer, L. (2018) · Proceedings of the 2018 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long Papers) · doi:10.18653/v1/n18-1202 · Cited by 11,983
Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer
Raffel, C., Shazeer, N., Roberts, A., Lee, K., Narang, S., Matena, M., Zhou, Y., Li, W., & Liu, P. J. (2019) · arXiv · doi:10.48550/arxiv.1910.10683 · Cited by 10,929
SciBERT: A Pretrained Language Model for Scientific Text
Beltagy, I., Lo, K., & Cohan, A. (2019) · Proceedings of the 2019 Conference on Empirical Methods in Natural Language Processing and the 9th International Joint Conference on Natural Language Processing (EMNLP-IJCNLP) · doi:10.18653/v1/d19-1371 · Cited by 3,218
Self-citationCTRL: A Conditional Transformer Language Model for Controllable Generation
Keskar, N. S., McCann, B., Varshney, L. R., Xiong, C., & Socher, R. (2019) · arXiv · doi:10.48550/arxiv.1909.05858 · Cited by 751
AdapterFusion: Non-Destructive Task Composition for Transfer Learning
Pfeiffer, J., Kamath, A., Rücklé, A., Cho, K., & Gurevych, I. (2021) · Proceedings of the 16th Conference of the European Chapter of the Association for Computational Linguistics: Main Volume · doi:10.18653/v1/2021.eacl-main.39 · Cited by 636
MTEB: Massive Text Embedding Benchmark
Muennighoff, N., Tazi, N., Magne, L., & Reimers, N. (2023) · Proceedings of the 17th Conference of the European Chapter of the Association for Computational Linguistics · doi:10.18653/v1/2023.eacl-main.148 · Cited by 548
Liu, X., Gao, J., He, X., Deng, L., Duh, K., & Wang, Y.-Y. (2015) · Proceedings of the 2015 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies · doi:10.3115/v1/n15-1092 · Cited by 395
Muppet: Massive Multi-task Representations with Pre-Finetuning
Aghajanyan, A., Gupta, A., Shrivastava, A., Chen, X., Zettlemoyer, L., & Gupta, S. (2021) · Proceedings of the 2021 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/2021.emnlp-main.468 · Cited by 183
Research works printed but not linked: 45
- Amit Bagga and Breck Baldwin. 1998. Algorithms for scoring coreference chains. In The first international conference on language resources and evaluation workshop on linguistics coreference.
- Vera Boteva, Demian Gholipour Ghalandari, Artem Sokolov, and Stefan Riezler. 2016. A full-text learn- ing to rank dataset for medical information retrieval. In European Conference on Information Retrieval.
- Peter Brown, Ameya Sadguru Kulkarni, Osama Re- fai, and Yaoqi Zhou. 2019. Large expert-curated database for benchmarking document similarity de- tection in biomedical literature search. Database: The Journal of Biological Databases and Curation, 2019.
- Rich Caruana. 1993. Multitask learning: A knowledge- based source of inductive bias. In Proceedings of the Tenth International Conference on International Conference on Machine Learning, ICML'93, page 41-48, San Francisco, CA, USA.
- Zhao Chen, Vijay Badrinarayanan, Chen-Yu Lee, and Andrew Rabinovich. 2018. GradNorm: Gradient nor- malization for adaptive loss balancing in deep mul- titask networks. In Proceedings of the 35th Interna- tional Conference on Machine Learning, volume 80 of Proceedings of Machine Learning Research, pages 794-803.
- PMLR.
- Arman Cohan, Sergey Feldman, Iz Beltagy, Doug Downey, and Daniel Weld. 2020. SPECTER: Document-level representation learning using citation-informed transformers. In Proceedings of the 58th Annual Meeting of the Association for Computational Linguistics, pages 2270-2282, Online. Association for Computational Linguistics. · DOI
- Christopher Fifty, Ehsan Amid, Zhe Zhao, Tianhe Yu, Rohan Anil, and Chelsea Finn. 2021. Efficiently identifying task groupings for multi-task learning. In NeurIPS.
- Tianyu Gao, Xingcheng Yao, and Danqi Chen. 2021. SimCSE: Simple contrastive learning of sentence em- beddings. In Proceedings of the 2021 Conference on Empirical Methods in Natural Language Process- ing, Online and Punta Cana, Dominican Republic. Association for Computational Linguistics. · DOI · Paper page
- Winston Haynes. 2013. Tukey's Test, pages 2303-2304. Springer New York, New York, NY. · DOI
- Neil Houlsby, Andrei Giurgiu, Stanislaw Jastrzebski, Bruna Morrone, Quentin De Laroussilhe, Andrea Gesmundo, Mona Attariyan, and Sylvain Gelly. 2019. Parameter-efficient transfer learning for NLP. In Proceedings of the 36th International Conference on Machine Learning, volume 97 of Proceedings of Machine Learning Research, pages 2790-2799.
- PMLR.
- Naman Jain and Mayank Singh. 2021. Tweetpap: A dataset to study the social media discourse of scien- tific papers. In 2021 ACM/IEEE Joint Conference on Digital Libraries (JCDL), pages 328-329. · DOI
- Carolyn E Lipscomb. 2000. Medical subject headings (mesh). Bulletin of the Medical Library Association, 88(3):265.
- Shengchao Liu, Yingyu Liang, and Anthony Gitter. 2019a. Loss-balanced task weighting to reduce neg- ative transfer in multi-task learning. Proceedings of the AAAI Conference on Artificial Intelligence, 33(01):9977-9978. · DOI
- Xiang Liu, Torsten Suel, and Nasir Memon. 2014. A robust model for paper reviewer assignment. In Proceedings of the 8th ACM Conference on Recom- mender Systems, RecSys '14, page 25-32, New York, NY, USA. Association for Computing Machinery. · DOI
- Xiaodong Liu, Pengcheng He, Weizhu Chen, and Jian- feng Gao. 2019b. Multi-task deep neural networks for natural language understanding. In Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics, pages 4487-4496, Flo- rence, Italy. Association for Computational Linguis- tics. · DOI
- Ilya Loshchilov and Frank Hutter. 2019. Decoupled weight decay regularization. In International Confer- ence on Learning Representations (ICLR).
- David Mimno and Andrew McCallum. 2007. Expertise modeling for matching papers with reviewers. In Proceedings of the 13th ACM SIGKDD International Conference on Knowledge Discovery and Data Min- ing, KDD '07, page 500-509, New York, NY, USA. Association for Computing Machinery. · DOI
- Sheshera Mysore, Arman Cohan, and Tom Hope. 2022. Multi-vector models with textual guidance for fine- grained scientific document similarity. In Proceed- ings of the 2022 Conference of the North American Chapter of the Association for Computational Lin- guistics: Human Language Technologies, Seattle, United States. Association for Computational Lin- guistics. · DOI
- Sheshera Mysore, Tim O'Gorman, Andrew McCallum, and Hamed Zamani. 2021. Csfcube-a test collec- tion of computer science research articles for faceted query by example. In Thirty-fifth Conference on Neu- ral Information Processing Systems (NeurIPS).
- Arvind Neelakantan, Tao Xu, Raul Puri, Alec Rad- ford, Jesse Michael Han, Jerry Tworek, Qiming Yuan, Nikolas A. Tezak, Jong Wook Kim, Chris Hallacy, Johannes Heidecke, Pranav Shyam, Boris Power, Tyna Eloundou Nekoul, Girish Sastry, Gretchen Krueger, David P. Schnurr, Felipe Petroski Such, Kenny Sai-Kin Hsu, Madeleine Thompson, Tabarak Khan, Toki Sherbakov, Joanne Jang, Peter Welinder, and Lilian Weng. 2022. Text and code embeddings by contrastive pre-training. ArXiv, abs/2201.10005. · arXiv
- Malte Ostendorff, Till Blume, Terry Ruas, Bela Gipp, and Georg Rehm. 2022a. Specialized document em- beddings for aspect-based similarity of research pa- pers. In Proceedings of the 22nd ACM/IEEE Joint Conference on Digital Libraries, JCDL '22, New York, NY, USA. Association for Computing Machin- ery. · DOI
- Malte Ostendorff, Nils Rethmeier, Isabelle Augenstein, Bela Gipp, and Georg Rehm. 2022b. Neighborhood Contrastive Learning for Scientific Document Rep- resentations with Citation Embeddings. In The 2022 Conference on Empirical Methods in Natural Lan- guage Processing (EMNLP 2022), Abu Dhabi. Asso- ciation for Computational Linguistics. 7-11 Decem- ber 2022. Accepted for publication. · DOI
- Vishakh Padmakumar, Leonard Lausen, Miguel Balles- teros, Sheng Zha, He He, and George Karypis. 2022. Exploring the role of task transferability in large- scale multi-task learning. In Proceedings of the 2022 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, pages 2542-2550, Seattle, United States. Association for Computational Lin- guistics. · DOI
- Vikram Shyam, Lauren Friend, Brian Whiteaker, Nicholas Bense, Jonathan Dowdall, Bishoy Bok- tor, Manju Johny, Isaias Reyes, Angeera Naser, Nikhitha Sakhamuri, Victoria Kravets, Alexandra Calvin, Kaylee Gabus, Delonte Goodman, Herbert Schilling, Calvin Robinson, Robert Omar Reid II, and Colleen Unsworth. 2019. Petal (periodic table of life) and physiomimetics. Designs, 3(3). · DOI
- Kaitao Song, Xu Tan, Tao Qin, Jianfeng Lu, and Tie- Yan Liu. 2020. Mpnet: Masked and permuted pre- training for language understanding. arXiv preprint arXiv:2004.09297. · arXiv
- Asa Cooper Stickland and Iain Murray. 2019. BERT and PALs: Projected attention layers for efficient adaptation in multi-task learning. In Proceedings of the 36th International Conference on Machine Learn- ing, volume 97 of Proceedings of Machine Learning Research, pages 5986-5995.
- PMLR.
- Shivashankar Subramanian, Daniel King, Doug Downey, and Sergey Feldman. 2021. S2AND: A Benchmark and Evaluation System for Author Name Disambiguation. In JCDL '21: Proceedings of the ACM/IEEE Joint Conference on Digital Libraries in 2021, JCDL '21, New York, NY, USA. Association for Computing Machinery.
- Yi Tay, Mostafa Dehghani, Vinh Quang Tran, Xavier García, Dara Bahri, Tal Schuster, Huaixiu Zheng, Neil Houlsby, and Donald Metzler. 2022. Unifying language learning paradigms. ArXiv, abs/2205.05131. · arXiv
- Amalie Trewartha, Nicholas Walker, Haoyan Huo, Sanghoon Lee, Kevin Cruse, John Dagdelen, Alexan- der Dunn, Kristin A. Persson, Gerbrand Ceder, and Anubhav Jain. 2022. Quantifying the advantage of domain-specific pre-training on named entity recognition tasks in materials science. Patterns, 3(4):100488. · DOI
- Marco Valenzuela, Vu A. Ha, and Oren Etzioni. 2015. Identifying meaningful citations. In AAAI Workshop: Scholarly Big Data.
- Christophe Van Gysel and Maarten de Rijke. 2018. Pytrec_eval: An extremely fast python interface to trec_eval. In The 41st International ACM SIGIR Con- ference on Research and Development in Information Retrieval, SIGIR '18, page 873-876, New York, NY, USA. Association for Computing Machinery. · DOI
- Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N. Gomez, Łukasz Kaiser, and Illia Polosukhin. 2017. Attention is all you need. In Proceedings of the 31st International Conference on Neural Information Processing Sys- tems, NeurIPS'17, page 6000-6010, Red Hook, NY, USA.
- Ellen Voorhees, Tasmeer Alam, Steven Bedrick, Dina Demner-Fushman, William R. Hersh, Kyle Lo, Kirk Roberts, Ian Soboroff, and Lucy Lu Wang. 2021. Trec-covid: Constructing a pandemic information retrieval test collection. SIGIR Forum, 54(1). · DOI
- Alex Wang, Yada Pruksachatkun, Nikita Nangia, Aman- preet Singh, Julian Michael, Felix Hill, Omer Levy, and Samuel Bowman. 2019. Superglue: A stickier benchmark for general-purpose language understand- ing systems. In Advances in Neural Information Processing Systems, volume 32.
- Kuansan Wang, Iris Shen, Charles Huang, Chieh-Han Wu, Yuxiao Dong, and Anshul Kanakia. 2020a. Mi- crosoft academic graph: when experts are not enough. Quantitative Science Studies, 1(1):396-413. · DOI
- Liang Wang, Nan Yang, Xiaolong Huang, Binxing Jiao, Linjun Yang, Daxin Jiang, Rangan Majumder, and Furu Wei. 2022. Text embeddings by weakly- supervised contrastive pre-training. arXiv preprint arXiv:2212.03533. · arXiv
- Lucy Lu Wang, Kyle Lo, Yoganand Chandrasekhar, Russell Reas, Jiangjiang Yang, Doug Burdick, Darrin Eide, Kathryn Funk, Yannis Katsis, Rodney Michael Kinney, Yunyao Li, Ziyang Liu, William Merrill, Paul Mooney, Dewey A. Murdick, Devvret Rishi, Jerry Sheehan, Zhihong Shen, Brandon Stilson, Alex D. Wade, Kuansan Wang, Nancy Xin Ru Wang, Christopher Wilhelm, Boya Xie, Douglas M. Ray- mond, Daniel S. Weld, Oren Etzioni, and Sebastian Kohlmeier. 2020b. CORD-19: The COVID-19 open research dataset. In Proceedings of the 1st Work- shop on NLP for COVID-19 at ACL 2020, Online. Association for Computational Linguistics.
- Peng Xu, Xinchi Chen, Xiaofei Ma, Zhiheng Huang, and Bing Xiang. 2021. Contrastive document rep- resentation learning with graph attention networks. In Findings of the Association for Computational Linguistics: EMNLP 2021, pages 3874-3884, Punta Cana, Dominican Republic. Association for Compu- tational Linguistics. · DOI
- Michihiro Yasunaga, Jure Leskovec, and Percy Liang. 2022. LinkBERT: Pretraining language models with document links. In Proceedings of the 60th Annual Meeting of the Association for Computational Lin- guistics (Volume 1: Long Papers), pages 8003-8016, Dublin, Ireland. Association for Computational Lin- guistics. · DOI
- Qinyuan Ye, Bill Yuchen Lin, and Xiang Ren. 2021. CrossFit: A few-shot learning challenge for cross- task generalization in NLP. In Proceedings of the 2021 Conference on Empirical Methods in Natural Language Processing, pages 7163-7189, Online and Punta Cana, Dominican Republic. Association for Computational Linguistics. · DOI
- Shunyu Zhang, Yaobo Liang, Ming Gong, Daxin Jiang, and Nan Duan. 2022. Multi-view document repre- sentation learning for open-domain dense retrieval. In Proceedings of the 60th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers), pages 5990-6000, Dublin, Ireland. Association for Computational Linguistics. · DOI
- Yue Zhao, Ajay Anand, and Gaurav Sharma. 2022. Re- viewer recommendations using document vector em- beddings and a publisher database: Implementation and evaluation. IEEE Access, 10:21798-21811. · DOI
Cited by
Sorted by citations
Artificial intelligence tools expand scientists' impact but contract science's focus
Hao, Q., Xu, F., Li, Y., & Evans, J. (2026) · Nature · doi:10.1038/s41586-025-09922-y · Cited by 117
The Semantic Scholar Open Data Platform
Kinney, R., Anastasiades, C., Authur, R., Beltagy, I., Bragg, J., Buraczynski, A., Cachola, I., Candra, S., Chandrasekhar, Y., Cohan, A., et al. (2023) · arXiv · doi:10.48550/arxiv.2301.10140 · Cited by 64
Self-citationThe rise of large language models and the direction and impact of US federal research funding
Qian, Y., Wen, Z., Furnas, A. C., Bai, Y., Shao, E., & Wang, D. (2026) · Proceedings of the National Academy of Sciences · doi:10.1073/pnas.2601439123 · Cited by 5
ARIES: A Corpus of Scientific Paper Edits Made in Response to Peer Reviews
D’Arcy, M., Ross, A., Bransom, E., Kuehl, B., Bragg, J., Hope, T., & Downey, D. (2024) · Proceedings of the 62nd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) · doi:10.18653/v1/2024.acl-long.377 · Cited by 4
Self-citationARIES: A Corpus of Scientific Paper Edits Made in Response to Peer Reviews
D'Arcy, M., Ross, A., Bransom, E., Kuehl, B., Bragg, J., Hope, T., & Downey, D. (2023) · arXiv · doi:10.48550/arxiv.2306.12587 · Cited by 1
Self-citation
Metadata
- Authors
- Singh, A., D’Arcy, M., Cohan, A., Downey, D., & Feldman, S.
- Venue
- Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing
- Published
- 2023
- Pages
- 5548-5566
- Cited by
- 67
- References
- 10
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
How to cite
Cite CoChat for the checks on this page, and the paper for its own findings.
- This page
- CoChat. (2026). Citation check: SciRepEval: A Multi-Format Benchmark for Scientific Document Representations. https://app.cochat.ai/papers/10.18653/v1/2023.emnlp-main.338
- The paper
- Singh, A., D’Arcy, M., Cohan, A., Downey, D., & Feldman, S. (2023). SciRepEval: A Multi-Format Benchmark for Scientific Document Representations. Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing. https://doi.org/10.18653/v1/2023.emnlp-main.338
