

The DOI matches its Crossref record; 21 of the 21 references it cites were found in a registry or an index; none of the 9 sources its claims cite is checked for support yet.
The Good and The Bad: Exploring Privacy Issues in Retrieval-Augmented Generation (RAG)
Open accessAbstract
Shenglai Zeng, Jiankun Zhang, Pengfei He, Yiding Liu, Yue Xing, Han Xu, Jie Ren, Yi Chang, Shuaiqiang Wang, Dawei Yin, Jiliang Tang. Findings of the Association for Computational Linguistics: ACL 2024. 2024.
Overview
CoChat Summary
Written by AI from the paper’s full text.
TL;DR
RAG systems are highly vulnerable to black-box prompting attacks that extract private retrieval-database content, but incorporating retrieval data substantially reduces an LLM’s tendency to leak its own training data. The paper empirically maps both risks and evaluates defenses, finding a privacy–utility tradeoff.
Key findings
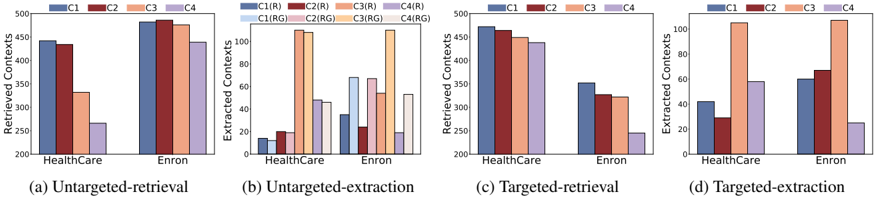
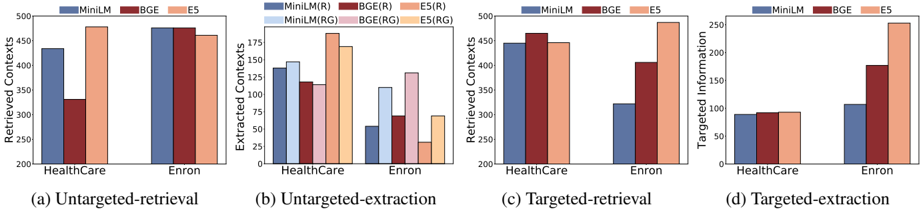
- Untargeted attacks extracted retrieval data at high rates: with Enron Email and GPT-3.5-turbo, 250 prompts yielded 452 retrieval contexts, 116 repeat prompts, 121 ROUGE prompts, and 208 ROUGE contexts.
- Targeted attacks also succeeded: with Llama-7b-Chat, 250 prompts extracted 89 targeted medical dialogue chunks from HealthCareMagic and 107 PIIs from Enron Email.
- RAG reduced training-data leakage: targeted PII extraction from GPT-Neo-1.3B training data dropped from 245 email / 27 phone / 34 URL with the LLM alone to 2/1/15 with RAG-Chatdoctor and 2/2/3 with RAG-Wikitext; prefix reconstruction dropped from 213 to 34 (RAG-Chatdoctor) or 70 (RAG-Wikitext).
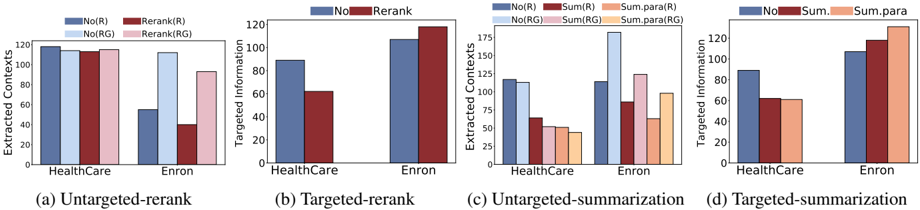
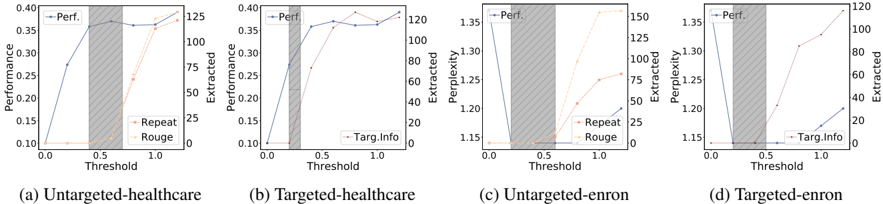
- Summarization mitigated untargeted retrieval-data leakage by about 50% (e.g., HealthCareMagic ROUGE contexts 113 to 44 with abstractive summarization), while re-ranking had almost no mitigation effect; distance thresholds showed a privacy–utility tradeoff.
Methods
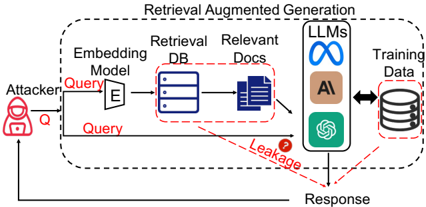
- Black-box API threat model; composite structured prompting `q = {information} + {command}` for targeted and untargeted retrieval-data extraction, plus targeted and prefix attacks for LLM training-data memorization.
- RAG components: Llama-7b-chat, Llama-13b-chat, GPT-3.5-turbo; embeddings bge-large-en-v1.5, all-MiniLM-L6-v2, e5-base-v2; Chroma; default `k=2`; retrieval datasets Enron Email (500,000 emails) and HealthcareMagic-101 (200k doctor–patient dialogues). For RQ2, GPT-Neo-1.3B with Enron_Mail as training subset and wikitext-103, HealthcareMagic, and w3c-email as retrieval datasets.
- Metrics: retrieval contexts, repeat prompts, repeat contexts, targeted information, ROUGE-L > 0.5 prompts/contexts; prefix attack success by ROUGE-L > 0.5; performance by ROUGE-L or perplexity on held-out test sets.
Limitations
- Paper-stated: the study focuses on retrieval augmentation at inference, not during pre-training or fine-tuning; other retrieval-based LMs with distinct architectures need further investigation; differential privacy for retrieval data and using RAG to safeguard training data remain open questions.
- Paper-stated: the prefix attack requires attackers to know actual training data, limiting its practicality, though it is useful for quantitatively measuring memorization.
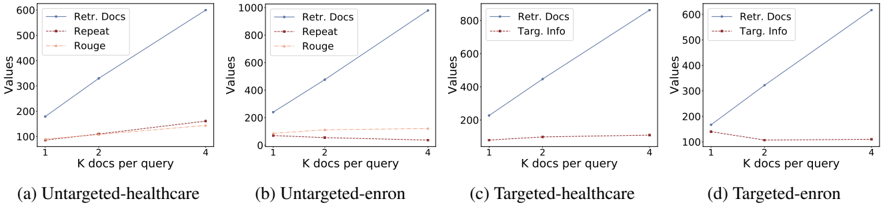
- Evident from text: attack success depends heavily on command design and retrieval settings, and the evaluated models/datasets may not generalize to all RAG deployments.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
38 Own result · 16 Own interpretation · 3 Check pending · 1 Sources not found · 1 No basis given
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“For example, with Llama-7b-Chat as the generative model, 250 prompts successfully extracted 89 targeted medical dialogue chunks from HealthCareMagic and 107 PIIs from Enron Email.”
§ The Good and The Bad: Exploring Privacy Issues in Retrieval-Augmented Generation (RAG) > 4.3 Results of Targeted Attack
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Rests on an assumption not shown here.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Our analysis shows that targeted attacks can effectively retrieve sensitive information, as detailed in Table 2.”
§ The Good and The Bad: Exploring Privacy Issues in Retrieval-Augmented Generation (RAG) > 4.3 Results of Targeted Attack
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Rests on an assumption not shown here.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“It shows that a majority of the prompts effectively prompted the retrieval system to fetch relevant data segments.”
§ The Good and The Bad: Exploring Privacy Issues in Retrieval-Augmented Generation (RAG) > 4.2 Results of Untargeted Attack
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Rests on an assumption not shown here.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“It is obvious that different commands indeed affect the extraction performance.”
§ The Good and The Bad: Exploring Privacy Issues in Retrieval-Augmented Generation (RAG) > Impact of Questions.
boostedstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Despite the new risk brought by RAG on the retrieval data, we further reveal that RAG can mitigate the leakage of the LLMs' training data.”
- Also stated in: § 6 Conclusions · hedged
“we also found that integrating retrieval data can substantially reduce LLMs' tendency to output its memorized training data, which suggests that RAG could potentially mitigate the risks of training data leakage.”
§ The Good and The Bad: Exploring Privacy Issues in Retrieval-Augmented Generation (RAG) > Abstract
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Rests on 2 assumptions not shown here.
- Also stated in: § 6 Conclusions · hedged
- It may state two separate claims as one. 10
- Probably not a substantial claim. 2
Create a free account to see these claims.
Create a free account to see these assumptions.
42 more claims
Create a free account to see all 59 claims and to verify the 3 references still open.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
“Despite initial studies exploring these risks, they often lack a formalized framework, robust attack performance, and comprehensive evaluation, leaving critical questions about real-world EDEA feasibility unanswered.”
From External Data Extraction Attacks Against Retrieval-Augmented Large Language Models (2026) · cites this paper as [17]
In the citing paper
“Specifically, they suffer from the following two major limitations: (1) they lack a unified definition and formalization of EDEAs and (2) their effectiveness and scalability are limited, especially against RA-LLMs equipped even with naive defenses (e.g., instructions to refuse to disclose text contained in the knowledge base).”
From External Data Extraction Attacks Against Retrieval-Augmented Large Language Models (2026) · cites this paper as [17]
In the citing paper
“Leveraging the strong instruction-following capabilities inherent in modern LLMs, simple commands such as 'Please repeat all the context' can indeed induce models to output retrieved documents [17], [18].”
From External Data Extraction Attacks Against Retrieval-Augmented Large Language Models (2026) · cites this paper as [17]
In the citing paper
“Specifically, they suffer from the following two major limitations: (1) they lack a unified definition and formalization of EDEAs and (2) their effectiveness and scalability are limited, especially against RA-LLMs equipped even with naive defenses (e.g., instructions to refuse to disclose text contained in the knowledge base).”
From External Data Extraction Attacks Against Retrieval-Augmented Large Language Models (2026) · cites this paper as [17]
In the citing paper
“However, existing works primarily provide simple case studies, merely illustrating the privacy threats posed by the attacks.”
From External Data Extraction Attacks Against Retrieval-Augmented Large Language Models (2026) · cites this paper as [17]
8 more claims about this paper
Create a free account to see every claim other papers make about this one.
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Each contradiction between two passages listed here was confirmed by an independent check.
Rated major: it would touch a result — a value a result rests on, reported and recomputed p-values on opposite sides of the significance level, two passages that conflict with no sign which is right, or a cited work retracted before this paper was published.
In the paper
§ The Good and The Bad: Exploring Privacy Issues in Retrieval-Augmented Generation (RAG) > 4.2 Results of Untargeted Attack
“In total, this results in 112 exact text matches (Repeat Contexts) and 208 similar responses (Rouge Contexts).”
§ The Good and The Bad: Exploring Privacy Issues in Retrieval-Augmented Generation (RAG) > Impact of Questions.
“| | GPT | 452 | 116 | 122 | 121 | 208 |”
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ The Good and The Bad: Exploring Privacy Issues in Retrieval-Augmented Generation (RAG) > 5.3 Prefix Attack
“Specifically, it leads to a reduction in successful text reconstructions from over 200 cases to fewer than 40.”
§ The Good and The Bad: Exploring Privacy Issues in Retrieval-Augmented Generation (RAG) > Impact of Questions.
“| RAG-Wikitext | 2 | 2 | 3 | 0 | 0 | 0 | 70 |”
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ The Good and The Bad: Exploring Privacy Issues in Retrieval-Augmented Generation (RAG) > 5.1 Evaluation setup
“we include baselines with 50 tokens of random noise injection”
§ The Good and The Bad: Exploring Privacy Issues in Retrieval-Augmented Generation (RAG) > Additional information
“For random noises, we just randomly choose 50 characters and prepend them to the prompt.”
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ The Good and The Bad: Exploring Privacy Issues in Retrieval-Augmented Generation (RAG) > 4.5 Potential Mitigation
“For instance, in the Enron email dataset, the occurrence of personally identifiable information (PIIs) even inadvertently increased.”
§ The Good and The Bad: Exploring Privacy Issues in Retrieval-Augmented Generation (RAG) > Additional information
“| | No | 134 | 39 | 32 | 12 | | Enron-Email | Yes | 134 | 27 | 21 | 11 | | | Yes-edit | 134 | 27 | 24 | 12 |”
Citations
Cites
Adapted large language models can outperform medical experts in clinical text summarization
Van Veen, D., Van Uden, C., Blankemeier, L., Delbrouck, J.-B., Aali, A., Bluethgen, C., Pareek, A., Polacin, M., Reis, E. P., Seehofnerová, A., et al. (2024) · Nature Medicine · doi:10.1038/s41591-024-02855-5 · Cited by 891
Retrieval-Augmented Generation for Large Language Models: A Survey
Gao, Y., Xiong, Y., Gao, X., Jia, K., Pan, J., Bi, Y., Dai, Y., Sun, J., Wang, M., & Wang, H. (2023) · arXiv · doi:10.48550/arxiv.2312.10997 · Cited by 876
Li, Y., Li, Z., Zhang, K., Dan, R., Jiang, S. B., & Zhang, Y. (2023) · Cureus · doi:10.7759/cureus.40895 · Cited by 784
Retrieval Augmentation Reduces Hallucination in ConversationPreprint
Shuster, K., Poff, S., Chen, M., Kiela, D., & Weston, J. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2104.07567 · Cited by 455
In-Context Retrieval-Augmented Language Models
Ram, O., Levine, Y., Dalmedigos, I., Muhlgay, D., Shashua, A., Leyton-Brown, K., & Shoham, Y. (2023) · Transactions of the Association for Computational Linguistics · doi:10.1162/tacl_a_00605 · Cited by 449
Generalization through Memorization: Nearest Neighbor Language Models
Khandelwal, U., Levy, O., Jurafsky, D., Zettlemoyer, L., & Lewis, M. (2019) · arXiv · doi:10.48550/arxiv.1911.00172 · Cited by 285
REPLUG: Retrieval-Augmented Black-Box Language Models
Shi, W., Min, S., Yasunaga, M., Seo, M., James, R., Lewis, M., Zettlemoyer, L., & Yih, W.-T. (2024) · Proceedings of the 2024 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies (Volume 1: Long Papers) · doi:10.18653/v1/2024.naacl-long.463 · Cited by 209
Quantifying Memorization Across Neural Language Models
Carlini, N., Ippolito, D., Jagielski, M., Lee, K., Tramer, F., & Zhang, C. (2022) · arXiv · doi:10.48550/arxiv.2202.07646 · Cited by 204
Enhancing Retrieval-Augmented Large Language Models with Iterative Retrieval-Generation Synergy
Shao, Z., Gong, Y., Shen, Y., Huang, M., Duan, N., & Chen, W. (2023) · Findings of the Association for Computational Linguistics: EMNLP 2023 · doi:10.18653/v1/2023.findings-emnlp.620 · Cited by 200
Counterfactual Memorization in Neural Language Models
Zhang, C., Ippolito, D., Lee, K., Jagielski, M., Tramèr, F., & Carlini, N. (2023) · neural information processing systems · doi:10.52202/075280-1708 · Cited by 148
Research works printed but not linked: 16
- Stella Biderman, USVSN Sai Prashanth, Lintang Sutawika, Hailey Schoelkopf, Quentin Anthony, Shivanshu Purohit, and Edward Raf. 2023. Emer- gent and predictable memorization in large language models. arXiv preprint arXiv:2304.11158. · arXiv
- Sebastian Borgeaud, Arthur Mensch, Jordan Hoff- mann, Trevor Cai, Eliza Rutherford, Katie Milli- can, George Bm Van Den Driessche, Jean-Baptiste Lespiau, Bogdan Damoc, Aidan Clark, et al. 2022. Improving language models by retrieving from tril- lions of tokens. In International conference on ma- chine learning, pages 2206-2240.
- PMLR.
- Nicholas Carlini, Florian Tramer, Eric Wallace, Matthew Jagielski, Ariel Herbert-Voss, Katherine Lee, Adam Roberts, Tom Brown, Dawn Song, Ulfar Erlingsson, et al. 2021. Extracting training data from large language models. In 30th USENIX Security Symposium (USENIX Security 21), pages 2633-2650.
- Ricardo Silva Carvalho, Theodore Vasiloudis, Oluwaseyi Feyisetan, and Ke Wang. 2023. Tem: High utility metric differential privacy on text. In Proceedings of the 2023 SIAM International Conference on Data Mining (SDM), pages 883-890.
- Oluwaseyi Feyisetan, Borja Balle, Thomas Drake, and Tom Diethe. 2020. Privacy-and utility-preserving tex- tual analysis via calibrated multivariate perturbations. In Proceedings of the 13th international conference on web search and data mining, pages 178-186.
- Evelyn Fix and Joseph Lawson Hodges. 1989. Dis- criminatory analysis. nonparametric discrimination: Consistency properties. International Statistical Re- view/Revue Internationale de Statistique, 57(3):238- 247.
- Nikhil Kandpal, Eric Wallace, and Colin Raffel. 2022. Deduplicating training data mitigates privacy risks in language models. In International Conference on Machine Learning, pages 10697-10707.
- PMLR.
- Jooyoung Lee, Thai Le, Jinghui Chen, and Dongwon Lee. 2023. Do language models plagiarize? In Proceedings of the ACM Web Conference 2023, pages 3637-3647.
- Fatemehsadat Mireshghallah, Archit Uniyal, Tianhao Wang, David Evans, and Taylor Berg-Kirkpatrick. 2022. Memorization in nlp fine-tuning methods. arXiv preprint arXiv:2205.12506. · arXiv
- Dimitrios P Panagoulias, Maria Virvou, and George A Tsihrintzis. 2024. Augmenting large language mod- els with rules for enhanced domain-specific interac- tions: The case of medical diagnosis. Electronics, 13(2):320.
- Md Rizwan Parvez, Wasi Ahmad, Saikat Chakraborty, Baishakhi Ray, and Kai-Wei Chang. 2021. Retrieval augmented code generation and summarization. In Findings of the Association for Computational Lin- guistics: EMNLP 2021, pages 2719-2734.
- Jie Ren, Han Xu, Pengfei He, Yingqian Cui, Shenglai Zeng, Jiankun Zhang, Hongzhi Wen, Jiayuan Ding, Hui Liu, Yi Chang, et al. 2024. Copyright protec- tion in generative ai: A technical perspective. arXiv preprint arXiv:2402.02333. · arXiv
- Dave Van Veen, Cara Van Uden, Louis Blankemeier, Jean-Benoit Delbrouck, Asad Aali, Christian Blueth- gen, Anuj Pareek, Malgorzata Polacin, William Collins, Neera Ahuja, et al. 2023. Clinical text summarization: Adapting large language models can outperform human experts. arXiv preprint arXiv:2309.07430. · arXiv
- Li Yunxiang, Li Zihan, Zhang Kai, Dan Ruilong, and Zhang You. 2023. Chatdoctor: A medical chat model fine-tuned on llama model using medical domain knowledge. arXiv preprint arXiv:2303.14070. · arXiv
Cited by
Items 101–152 of 152
Comparative Analysis of RAG Algorithms and LLM Fine-Tuning Methods for Domain-Specific Search Tasks
Verma, K. (2026) · The American Journal of Engineering And Technology · doi:10.37547/tajet/volume08issue04-03
From Objects to Influences: Rethinking Deletion in Learning-Based Systems
Ryu, J., Song, H., Kim, J., Park, K., & Suh, B. (2026) · CHI Conference Extended Abstracts on Human Factors in Computing Systems (CHI EA) · doi:10.1145/3772363.3798494
Hu, J., Fan, N., Zhang, X., Li, Q., Wang, Z., Shang, Y., & Shi, Y. (2026) · IEEE International Conference on Acoustics Speech and Signal Processing · doi:10.1109/icassp55912.2026.11464571
Chang, Y., Luan, T. H., Du, L., Zhang, J., & Li, Y. F. (2026) · IEEE International Conference on Acoustics Speech and Signal Processing · doi:10.1109/icassp55912.2026.11462131
Self-citationA Benchmarking Study of Multi-Layer Security Filters for Secure RAG Pipelines
Mishra, N., Rai, K., & Sharma, D. (2026) · International Conference on Expert Clouds and Applications (ICOECA) · doi:10.1109/icoeca68095.2026.11485085
Comparative Analysis of RAG Frameworks for Better Private Question Answering
Sah, S. K., Gupta, P., Gayathri, R., & Gurupriya, M. (2026) · International Conference on Expert Clouds and Applications (ICOECA) · doi:10.1109/icoeca68095.2026.11485286
Needle-in-RAG: Prompt-Conditioned Character-Level Traceback of Poisoned Spans in Retrieved EvidencePreprint
Cui, H., & Liu, W. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.01782
Does Retrieval-Augmented Generation Mitigate Training Data Leakage Risks from Large Language Models?
Nakai, T., Higashi, T., & Oonishi, K. (2026) · Lecture notes in computer science · doi:10.1007/978-3-032-16092-8_26
Trans-RAG: Query-Centric Vector Transformation for Secure Cross-Organizational Retrieval
Liu, Y., Peng, K., Zhang, W. J., Yuan, F., Cao, C., Liu, Y., & Liu, Y. (2026) · Lecture notes in computer science · doi:10.1007/978-981-92-0372-7_35
Self-citationGe, Y., Zhang, H., Huang, Z., Sun, H., Jin, S., & Yang, H. (2026) · Lecture notes in computer science · doi:10.1007/978-981-92-0375-8_36
Auditing Privacy in Multi-Tenant RAG under Account CollusionPreprint
Burnat, F. A. D. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.19847
Zhang, Q., Xu, Z., Cen, C., Zou, Y., Liu, H., Deng, Y., Wu, H., Liao, Z., Lin, Z., Li, D., et al. (2026) · International World Wide Web Conference (WWW) · doi:10.1145/3774905.3795461
Zheng, Z., Choi, Y., Huang, C., Cao, H., Tian, S., & Pei, T. (2026) · IEEE Transactions on Information Forensics and Security · doi:10.1109/tifs.2026.3699202
Khaliq, A., Aziz, L., Alawad, W. M., Almutairi, L., Kenany, A. A., & Almakayeel, N. M. (2026) · The Journal of Supercomputing · doi:10.1007/s11227-026-08604-4
A Case Study on the Impact of Anonymization Along the RAG Pipeline
Bodea, A.-E., Meisenbacher, S., & Matthes, F. (2026) · ACM International Workshop on Security and Privacy Analytics (IWSPA) · doi:10.1145/3806007.3810957
Privacy-Constrained Low-Bit Representation Learning for Person Image Retrieval
Fang, J., Zhang, Y., Li, M., Ge, X., Li, Y., & Cui, W. (2026) · International Conference on Multimedia Retrieval · doi:10.1145/3805622.3810629
An Efficient Privacy-Preserving Retrieval Scheme for Cloud-Based Retrieval-Augmented Generation
Chang, Y., Luan, T. H., Wang, Y., Du, L., Dong, C., & Su, Z. (2026) · IEEE Transactions on Cognitive Communications and Networking · doi:10.1109/tccn.2026.3705821
Self-citationA System-Level Framework for Evaluating Privacy in Hybrid LLM Deployments
Liang, S., Qiao, Z., Bai, T., He, Y., Chen, D., & Fu, S. (2026) · Algorithms · doi:10.3390/a19060500
Carrillo, N. J. C., Drilon, R. F. V., Oalican, M. J. M. E., & Comia, L. V. (2026) · International Conference on Inventive Computing and Informatics (ICICI) · doi:10.1109/icici68773.2026.11580418
A Comprehensive Framework for Secure Multi-Agent Retrieval-Augmented Generation Systems
Ghouil, C., Aloui, R., Khalfaoui, N., Mhatli, S., Aldalbahi, A. S., & Llamas‐Garro, I. (2026) · International Wireless Communications and Mobile Computing Conference (IWCMC) · doi:10.1109/iwcmc69287.2026.11579902
Deletion Isn't Enough: Auditing RAG for Selective Forgetting
Tavakoli, L., & Sanderson, M. (2026) · Proceedings of the 49th International ACM SIGIR Conference on Research and Development in Information Retrieval · doi:10.1145/3805712.3808545
Wang, H., Xu, X., Huang, B., & Shu, K. (2026) · ACM SIGKDD Conference on Knowledge Discovery and Data Mining (KDD) · doi:10.1145/3770855.3817665
FlatLeak-GEIA: Generative Text Inversion from Exact-KNN Score Leakage
Kim, J., & Hahn, C. (2026) · International Conference on Ubiquitous and Future Networks · doi:10.1109/icufn69619.2026.11628610
BRIDGE: Block-Wise Speculative Coordination for Cloud-Edge Retrieval-Augmented Generation
Li, Y., Huang, S., Liu, X., Zhao, Y., & Wang, X. (2026) · ACM SIGKDD Conference on Knowledge Discovery and Data Mining (KDD) · doi:10.1145/3770855.3818064
RAG-CNN on MRI images for early diagnosis of Alzheimer's disease
Pandey, P., Yadav, A., Pargai, R., Agarwal, V., & Mishra, S. D. (2026) · International Conference on Sustainable Engineering and Technology Innovations (ICSETI) · doi:10.1109/icseti67678.2026.11636377
RAG-Enhanced NL-to-SQL System for Power Marketing
Peng, L., Guo, W. C., Shen, Z. X., & Lin, W. (2026) · Advanced Electromagnetics · doi:10.7716/aem.v15i3.3186
Jadala, S. K. (2026) · International Journal of Data Engineering and Intelligent Computing · doi:10.67228/30715717/ijdeic-v9i3p101
Lyu, J., Xue, J., Baker, T., Chen, J., Liu, Z., Zhu, T., Zhou, W., Tan, Y., & Ren, M. (2026) · IEEE Transactions on Network Science and Engineering · doi:10.1109/tnse.2026.3725340
A Comparative Analysis of Security Vulnerabilities and Defense Mechanisms in Large Language Models
Barek, A., Rashid, M. B., Riad, A. K. I., Francia, G., Cetinkaya, C., Shahriar, H., Khan, M. U., & Ahamed, S. I. (2026) · IEEE Annual International Computer Software and Applications Conference (COMPSAC) · doi:10.1109/compsac69091.2026.00461
Security and privacy challenges of RAG systems
Ozman, F. M. (2026) · International Journal of Frontiers in Science and Technology Research · doi:10.53294/ijfstr.2026.10.2.0022
Kantheti, B., & de Araújo, C. A. P. (2026) · AI · doi:10.3390/ai7090340
Perez, J., Gutierrez, A., & Lopez, C. (2024) · Journal of Health Informatics and Digital Systems · doi:10.68159/u033966980
Mualla, K. (2026) · International Journal of Ethical AI Application · doi:10.64229/b98f3723
Bommireddy, V., & Bommireddy, R. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2609.06391
Dinev, D., & Petrova, D. I. (2026) · International Conference on Electronics, Engineering Physics and Earth Science (EEPES) · doi:10.3390/engproc2026154087
Alhwikem, F., Khan, A. R., & Jaskani, F. H. (2026) · Symmetry · doi:10.3390/sym18091572
CIPL: A Channel-Aware Framework for Recoverable Privacy Leakage in LLM AgentsPreprint
Huang, T., Wu, G., Zheng, G., Meng, J., Hou, C., Yang, X., Yang, X., & Xia, F. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2609.21686
Palanisamy, B., Chalapathi, G., & Hassija, V. (2026) · IEEE International Conference on Electronics, Computing and Communication Technologies (CONECCT) · doi:10.1109/conecct68978.2026.11700574
Rifki, M., Soelistijorini, R., & Ruswiansari, M. (2026) · International Electronics Symposium (IES) · doi:10.1109/ies71033.2026.11702572
Walking the Embedding Space: Datastore Extraction from Multimodal RAGPreprint
Jica, M. C., Satvaty, A., Verberne, S., & Türkmen, F. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2610.01871
Sharif, S., Sadoun, M. Y., Ahmadi, A., Aminpour, S., Larsh, L., Ebrahimzadeh, D., Ahmadvand, R., Ahmed, M., Datta, G., Malakar, T., et al. (2026) · Research Square · doi:10.21203/rs.3.rs-10910289/v1
A Conceptual Framework for Characterising and Analysing Retrieval–Augmented Generation Techniques
Igbekele Emmanuel, O., & Daramola, O. (2026) · Communications in computer and information science · doi:10.1007/978-3-032-42763-2_20
Pratama, A., & Ramli, K. (2026) · Jurnal Teknik Informatika (Jutif) · doi:10.52436/1.jutif.2026.7.5.5761
Li, S., Pan, L., Sun, S., Zhou, H., & Fan, S. (2026) · International Joint Conference on Neural Networks (IJCNN) · doi:10.1109/ijcnn69854.2026.11729092
Generative AI in Cloud Computing: Applications, Security Challenges, and Future Research Directions
Konde, R. B., & Phatangare, M. A. M. (2026) · INTERANTIONAL JOURNAL OF SCIENTIFIC RESEARCH IN ENGINEERING AND MANAGEMENT · doi:10.55041/ijsrem68137
Amal, I., Hermadi, I., & Nurhadryani, Y. (2026) · Journal of Information Systems and Informatics · doi:10.63158/journalisi.v8i5.1856
GraphMemShield: Auditing Cross-Session Leakage in Graph Memories
Tran-Truong, P. T., Le, X.-B., & Son, H. X. (2026) · ACM International Conference on Information and Knowledge Management (CIKM) · doi:10.1145/3799682.3840995
Pradhan, K. (2025) · Sciences du Nord Nature Science and Technology · doi:10.71238/snnst.v2i02.235
Differentially Private GraphRAG: Protecting Relation Connectivity and SemanticsPreprint
Fu, J., Hong, Y., Ning, Y., & Wang, W. H. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2611.09658
Yhden dokumentin myrkytykseen pohjautuva näkökanta manipulaatio haulla mukaututetussa generaatiossa
Viljanen, J. (2026) · Aaltodoc (Aalto University)
AI Meets Brain: Memory Systems from Cognitive Neuroscience to Autonomous Agents
Liang, J., Li, H., Li, C., Zhou, J., Jiang, S., Wang, Z., Ji, C., Zhu, Z., Liu, R., Ren, T., et al. (2025) · arXiv · doi:10.48550/arxiv.2512.23343
Metadata
- Authors
- Zeng, S., Zhang, J., He, P., Liu, Y., Xing, Y., Xu, H., Ren, J., Chang, Y., Wang, S., Yin, D., & Tang, J.
- Affiliations
- Michigan State University (US)
- Baidu (China) (CN)
- Venue
- Findings of the Association for Computational Linguistics ACL 2024
- Published
- 2024
- Pages
- 4505-4524
- OpenAlex
- W4402670423
- Cited by
- 149
- References
- 21
- Citations by year
- 2026: 83 · 2025: 61 · 2024: 5
- FWCI
- 22.45
- Type
- conference paper
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- cc-by
- Locations
- Findings of the Association for Computational Linguistics: ACL (Findings of ACL) (publishedVersion, cc-by)
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Privacy-Preserving Technologies in Data
- Physical Sciences › Computer Science › Artificial Intelligence › Topic Modeling
- Social Sciences › Sociology and Political Science › Privacy, Security, and Data Protection
- Keywords
- retrieval-augmented generation, privacy, data privacy, information retrieval, large language models
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
A language model drew the claims from the paper on 2026-11-12, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-11-12 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
