

The DOI matches its Crossref record; 105 of the 127 references it cites were found in a registry or an index.
Two Tales of Persona in LLMs: A Survey of Role-Playing and Personalization
Open accessAbstract
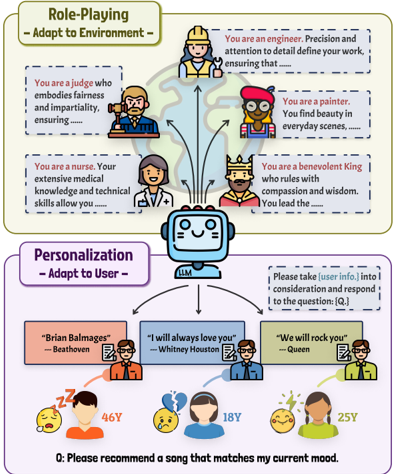
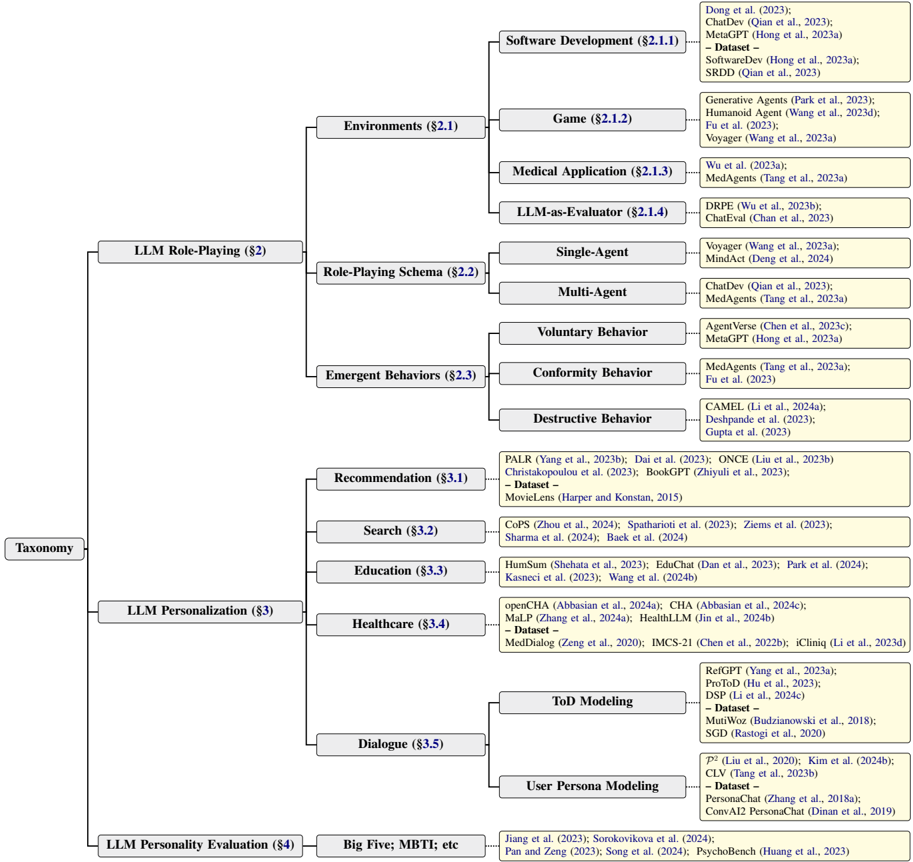
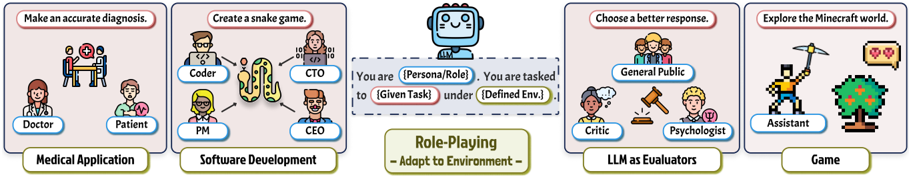
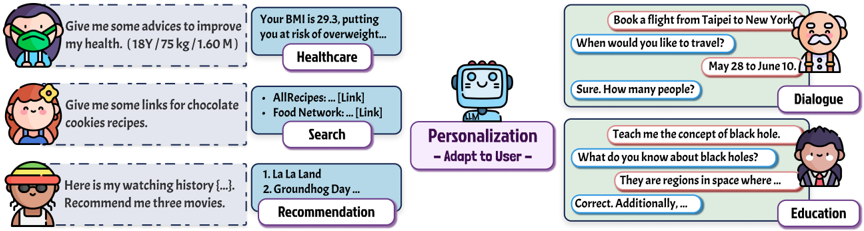
The concept of persona, originally adopted in dialogue literature, has re-surged as a promising framework for tailoring large language models (LLMs) to specific context (e.g., personalized search, LLM-as-a-judge).However, the growing research on leveraging persona in LLMs is relatively disorganized and lacks a systematic taxonomy.To close the gap, we present a comprehensive survey to categorize the current state of the field.We identify two lines of research, namely (1) LLM Role-Playing, where personas are assigned to LLMs, and (2) LLM Personalization, where LLMs take care of user personas.Additionally, we introduce existing methods for LLM personality evaluation.To the best of our knowledge, we present the first survey for role-playing and personalization in LLMs under the unified view of persona.We continuously maintain a paper collection to foster future endeavors.1 * Equal contribution. 1 https://github.com/MiuLab/PersonaLLM-Survey
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“However, collecting substantial annotations for training a personalized system for long-term use is hard (Tseng et al., 2024).”
From In Prospect and Retrospect: Reflective Memory Management for Long-term Personalized Dialogue Agents (2025) · cites this paper as Tseng et al., 2024
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“yet their inherent statelessness poses a significant challenge for maintaining coherent, personalized conversations over time (Chen et al., 2024; Li et al., 2024b; Tseng et al., 2024)”
From In Prospect and Retrospect: Reflective Memory Management for Long-term Personalized Dialogue Agents (2025) · cites this paper as Tseng et al., 2024
Experimental — accuracy not yet measured
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
The publisher hasn’t deposited this paper’s reference list.
Research works printed but not linked: 17
- Tom DeMarco and Tim Lister. 2013. Peopleware: pro- ductive projects and teams. Addison-Wesley.
- Ameet Deshpande, EunJeong Hwang, Vishvak Mura- hari, Joon Sung Park, Diyi Yang, Ashish Sabharwal, Karthik Narasimhan, and Ashwin Kalyan, editors. 2024. Proceedings of the 1st Workshop on Person- alization of Generative AI Systems (PERSONALIZE 2024). Association for Computational Linguistics, St. Julians, Malta.
- Mihail Eric, Rahul Goel, Shachi Paul, Abhishek Sethi, Sanchit Agarwal, Shuyang Gao, Adarsh Kumar, Anuj Goyal, Peter Ku, and Dilek Hakkani-Tur. 2020. Mul- tiWOZ 2.1: A consolidated multi-domain dialogue dataset with state corrections and state tracking base- lines. In Proceedings of the Twelfth Language Re- sources and Evaluation Conference, pages 422-428, Marseille, France. European Language Resources Association. 19
- Jun Hu, Wenwen Xia, Xiaolu Zhang, Chilin Fu, We- ichang Wu, Zhaoxin Huan, Ang Li, Zuoli Tang, and Jun Zhou. 2024. Enhancing sequential recommenda- tion via llm-based semantic embedding learning. In Companion Proceedings of the ACM on Web Confer- ence 2024, pages 103-111.
- Daniil Huryn, William M. Hutsell, and Jinho D. Choi. 2022. Automatic generation of large-scale multi-turn dialogues from Reddit. In Proceedings of the 29th International Conference on Computational Linguis- tics, pages 3360-3373, Gyeongju, Republic of Korea. International Committee on Computational Linguis- tics.
- Guohao Li, Hasan Hammoud, Hani Itani, Dmitrii Khizbullin, and Bernard Ghanem. 2024a. Camel: Communicative agents for" mind" exploration of large language model society. Advances in Neural Information Processing Systems, 36. 2, 5, 8
- Lei Li, Yongfeng Zhang, and Li Chen. 2023a. Person- alized prompt learning for explainable recommen- dation. ACM Transactions on Information Systems, 41(4):1-26. 5, 18, 19
- Yanran Li, Hui Su, Xiaoyu Shen, Wenjie Li, Ziqiang Cao, and Shuzi Niu. 2017. DailyDialog: A manually labelled multi-turn dialogue dataset. In Proceedings of the Eighth International Joint Conference on Nat- ural Language Processing (Volume 1: Long Papers), pages 986-995, Taipei, Taiwan. Asian Federation of Natural Language Processing. 19
- Zekun Li, Baolin Peng, Pengcheng He, Michel Galley, Jianfeng Gao, and Xifeng Yan. 2024c. Guiding large language models via directional stimulus prompting. Advances in Neural Information Processing Systems, 36. 2, 7
- Jianmo Ni, Jiacheng Li, and Julian McAuley. 2019. Jus- tifying recommendations using distantly-labeled re- views and fine-grained aspects. In Proceedings of the 2019 conference on empirical methods in natural language processing and the 9th international joint conference on natural language processing (EMNLP- IJCNLP), pages 188-197. 18, 19
- M Swift and J Allen. 2010. Towards a personal health management assistant. Journal of biomedical infor- matics, 43(5):S13-S16.
- Ning Wu, Ming Gong, Linjun Shou, Shining Liang, and Daxin Jiang. 2023b. Large language models are diverse role-players for summarization evaluation. In CCF International Conference on Natural Language Processing and Chinese Computing, pages 695-707. Springer. 2, 4
- Xuhai Xu, Bingsheng Yao, Yuanzhe Dong, Saadia Gabriel, Hong Yu, James Hendler, Marzyeh Ghas- semi, Anind K Dey, and Dakuo Wang. 2024. Mental- llm: Leveraging large language models for mental health prediction via online text data. Proceedings of the ACM on Interactive, Mobile, Wearable and Ubiquitous Technologies, 8(1):1-32.
- Shunyu Yao, Jeffrey Zhao, Dian Yu, Nan Du, Izhak Shafran, Karthik R Narasimhan, and Yuan Cao. 2022b. React: Synergizing reasoning and acting in language models. In The Eleventh International Conference on Learning Representations. 3
- Saizheng Zhang, Emily Dinan, Jack Urbanek, Arthur Szlam, Douwe Kiela, and Jason Weston. 2018a. Per- sonalizing dialogue agents: I have a dog, do you have pets too? In Proceedings of the 56th Annual Meeting of the Association for Computational Linguistics (Vol- ume 1: Long Papers), pages 2204-2213, Melbourne, Australia. Association for Computational Linguistics. 2, 20 · DOI · Paper page
- Wanjun Zhong, Lianghong Guo, Qiqi Gao, He Ye, and Yanlin Wang. 2024. Memorybank: Enhancing large language models with long-term memory. Proceed- ings of the AAAI Conference on Artificial Intelligence, 38(17):19724-19731. · DOI · Paper page
- USER:] That is all I need to know. Thanks, goodbye. [SYSTEM:] Thank you so much for Cambridge TownInfo center. Have a great day! Table 5: An example of ToD modeling from the MultiWOZ dataset (Zang et al., 2020).
Cited by
Sorted by citations
Limitations of the LLM-as-a-Judge Approach for Evaluating LLM Outputs in Expert Knowledge Tasks
Szymanski, A., Ziems, N., Eicher-Miller, H. A., Li, T. J.-J., Jiang, M., & Metoyer, R. A. (2025) · Proceedings of the 30th International Conference on Intelligent User Interfaces · doi:10.1145/3708359.3712091 · Cited by 77
PersonaCraft: Leveraging language models for data-driven persona development
Jung, S., Salminen, J. O., Aldous, K. K., & Jansen, B. J. J. (2025) · International Journal of Human-Computer Studies · doi:10.1016/j.ijhcs.2025.103445 · Cited by 56
The Impact of Prompt Programming on Function-Level Code Generation
Khojah, R., Neto, F. G. D. O., Mohamad, M., & Leitner, P. (2025) · IEEE Transactions on Software Engineering · doi:10.1109/tse.2025.3587794 · Cited by 59
Principles and Guidelines for the Use of LLM Judges
Dietz, L., Zendel, O., Bailey, P., Clarke, C. L. A., Cotterill, E., Dalton, J., Hasibi, F., Sanderson, M., & Craswell, N. (2025) · ACM SIGIR International Conference on Theory of Information Retrieval (ICTIR) · doi:10.1145/3731120.3744588 · Cited by 50
Creating and Evaluating Personas Using Generative AI: A Scoping Review of 81 Articles
Amin, D., Salminen, J. O., Ahmed, F., Tervola, S. M. H., Sethi, S., & Jansen, B. J. J. (2026) · CHI Conference on Human Factors in Computing Systems · doi:10.1145/3772318.3790608 · Cited by 36
A survey on pragmatic processing techniques
Mao, R., Ge, M., Han, S., Wei, L., He, K., Zhu, L., & Cambria, E. (2024) · Information Fusion · doi:10.1016/j.inffus.2024.102712 · Cited by 24
Promptware Engineering: Software Engineering for Prompt-Enabled Systems
Chen, Z., Wang, C., Sun, W., Liu, X., Zhang, J. M., & Liu, Y. (2026) · ACM Transactions on Software Engineering and Methodology · doi:10.1145/3796535 · Cited by 41
Towards lifelong dialogue agents via timeline-based memory management
Ong, K. T.-I., Kim, N., Gwak, M., Chae, H., Kwon, T., Jo, Y., Hwang, S.-W., Lee, D., & Yeo, J. (2025) · Proceedings of the 2025 Conference of the Nations of the Americas Chapter of the Association for Computational Linguistics: Human Language Technologies (Volume 1: Long Papers) · doi:10.18653/v1/2025.naacl-long.435 · Cited by 18
Lutz, M., Sen, I., Ahnert, G., Rogers, E., & Strohmaier, M. (2025) · Findings of the Association for Computational Linguistics: EMNLP (Findings of EMNLP) · doi:10.18653/v1/2025.findings-emnlp.1261 · Cited by 18
In Prospect and Retrospect: Reflective Memory Management for Long-term Personalized Dialogue Agents
Tan, Z., Yan, J., Hsu, I.-H., Han, R., Wang, Z., Le, L., Song, Y., Chen, Y., Palangi, H., Lee, G., et al. (2025) · Proceedings of the 63rd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) · doi:10.18653/v1/2025.acl-long.413 · Cited by 16
Self-citationLarge Language Models Empowered Personalized Web Agents
Cai, H., Li, Y., Wang, W., Zhu, F., Shen, X., Li, W., & Chua, T.-S. (2025) · Proceedings of the ACM on Web Conference 2025 · doi:10.1145/3696410.3714842 · Cited by 15
Personal Large Language Model Agents: A Case Study on Tailored Travel Planning
Singh, H., Verma, N., Wang, Y., Bharadwaj, M., Fashandi, H., Ferreira, K., & Chul, L. E. (2024) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2024.emnlp-industry.37 · Cited by 18
ProCyon: A multimodal foundation model for protein phenotypesPreprint
Queen, O., Huang, Y., Calef, R., Giunchiglia, V., Chen, T., Dasoulas, G., Tai, L., Abbadessa, G., Howell, O., Li, M. M., et al. (2024) · bioRxiv (Cold Spring Harbor Laboratory) · doi:10.1101/2024.12.10.627665 · Cited by 14
Self-citationSimTube: Simulating Audience Feedback on Videos using Generative AI and User Personas
Hung, Y., Huang, Y.-C., Su, T.-Y., Lin, Y.-T. R., Cheng, L.-P., Wang, B. K., & Sun, S.-H. (2025) · ACM International Conference on Intelligent User Interfaces (IUI) · doi:10.1145/3708359.3712146 · Cited by 18
Self-citationDaCosta, B. (2025) · Heritage · doi:10.3390/heritage8090387 · Cited by 11
Towards a LLM-based intelligent system for detecting propaganda within textual content
Gaeta, A., Loia, V., Lorusso, A., Orciuoli, F., & Pascuzzo, A. (2025) · Computers & Electrical Engineering · doi:10.1016/j.compeleceng.2025.110765 · Cited by 11
Revisiting Prompt Engineering: A Comprehensive Evaluation for LLM-based Personalized Recommendation
Kusano, G., Akimoto, K., & Takeoka, K. (2025) · ACM Conference on Recommender Systems (RecSys) · doi:10.1145/3705328.3748159 · Cited by 10
Kim, Y. S., Moon, H. S., Lee, S., & Lee, T. Y. (2025) · Proceedings of the ACM on Human-Computer Interaction · doi:10.1145/3757534 · Cited by 12
Semantic Commit: Helping Users Update Intent Specifications for AI Memory at Scale
Vaithilingam, P., Kim, M. G., Acosta-Parenteau, F.-C., Lee, D. W., Mhedhbi, A., Glassman, E. L., & Arawjo, I. (2025) · ACM Symposium on User Interface Software and Technology (UIST) · doi:10.1145/3746059.3747778 · Cited by 23
Cinema Multiverse Lounge: Enhancing Film Appreciation via Multi-Agent Conversations
Ryu, J., Kim, K., Heo, D., Song, H., Oh, C., & Suh, B. (2025) · CHI Conference on Human Factors in Computing Systems · doi:10.1145/3706598.3713641 · Cited by 11
Exploring Safety-Utility Trade-Offs in Personalized Language Models
Vijjini, A. R., Chowdhury, S. B. R., & Chaturvedi, S. (2025) · Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies (NAACL-HLT) · doi:10.18653/v1/2025.naacl-long.565 · Cited by 19
Large Language Models as Psychological Simulators: A Methodological Guide
Lin, Z. (2026) · Advances in Methods and Practices in Psychological Science · doi:10.1177/25152459251410153 · Cited by 17
Mixture-of-Personas Language Models for Population Simulation
Bui, N., Nguyen, H. T., Kumar, S., Theodore, J., Qiu, W., Nguyen, V. A., & Ying, R. (2025) · Findings of the Association for Computational Linguistics: ACL (Findings of ACL) · doi:10.18653/v1/2025.findings-acl.1271 · Cited by 20
Understanding Human-AI Misalignment in LLM-Based Job-Seeking Support for Neurodivergent Users
Hall, K., Ma, M., Zhang, X., Swain, V. D., & Kim, J. G. (2025) · International ACM SIGACCESS Conference on Computers and Accessibility (ASSETS) · doi:10.1145/3663547.3746361 · Cited by 8
A LLM-based agent for the construction of typhoon knowledge graphs
Huang, Y., Xia, Y., Tao, R., Jiao, D., Min, X., Zheng, J., Jiang, Y., Wu, W., & Du, P. (2026) · Environmental Modelling & Software · doi:10.1016/j.envsoft.2026.106856 · Cited by 8
Self-citationAligning LLM with Humans for Travel Choices: A Persona-Based Embedding Learning Approach
Liu, T., Li, M., & Yin, Y. (2026) · Transportation Science · doi:10.1287/trsc.2025.0330 · Cited by 17
Can LLM Agents Maintain a Persona in Discourse?
Bhandari, P., Fay, N., Wise, M. J., Datta, A., Meek, S., Naseem, U., & Nasim, M. (2025) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2025.emnlp-main.1487 · Cited by 7
Multi-Agent Simulator Drives Language Models for Legal Intensive Interaction
Yue, S., Huang, T., Jia, Z., Wang, S., Liu, S., Song, Y., Huang, X., & Wei, Z. (2025) · Findings of the Association for Computational Linguistics: NAACL · doi:10.18653/v1/2025.findings-naacl.365 · Cited by 11
Leveraging Large Language Models for Institutional Portfolio Management: Persona-Based Ensembles
Abe, Y., Matsuo, S., Kondo, R., & Hisano, R. (2024) · IEEE International Conference on Big Data (BigData) · doi:10.1109/bigdata62323.2024.10825362 · Cited by 8
Kargupta, P., Agarwal, I., August, T., & Han, J. (2025) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2025.acl-long.1422 · Cited by 12
Conversational Recommender Systems Using Generative Models (Gen-CRS): A Literature Review
Wagne, A., Kolb, T. E., Banerjee, A., Nazary, F., Neidhardt, J., & Deldjoo, Y. (2026) · ACM Transactions on Recommender Systems · doi:10.1145/3828551 · Cited by 8
Act-LLM: A whole-process chain for character-centric role-playing with large language models
Han, X., Zhao, W., Guan, Z., & Peng, J. (2025) · Expert Systems with Applications · doi:10.1016/j.eswa.2025.129024 · Cited by 5
Never Start from Scratch: Expediting On-Device LLM Personalization via Explainable Model Selection
Wang, H., Yang, B., Yin, X., & Gao, W. (2025) · International Conference on Mobile Systems, Applications, and Services · doi:10.1145/3711875.3729132 · Cited by 9
TAKAGI, H., Moriya, S., Sato, T., Nagao, M., & Higuchi, K. (2025) · ACM International Conference on Intelligent User Interfaces (IUI) · doi:10.1145/3708359.3712119 · Cited by 6
Attention Speaks Volumes: Localizing and Mitigating Bias in Language Models
Adiga, R., Nushi, B., & Chandrasekaran, V. (2025) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2025.acl-long.1281 · Cited by 10
Whitmore, S., Harrington, C., & Pritchard, E. (2024) · doi:10.31219/osf.io/cvdzu · Cited by 5
Kaur, A., Aird, A., Borman, H., Nicastro, A., Leontjeva, A., Pizzato, L. A. S., & Jermyn, D. (2025) · ACM Conference on User Modeling, Adaptation and Personalization (UMAP) · doi:10.1145/3699682.3728339 · Cited by 4
Zhang, Y., He, Y., & Zhou, D. (2025) · Findings of the Association for Computational Linguistics: ACL (Findings of ACL) · doi:10.18653/v1/2025.findings-acl.787 · Cited by 4
How to Protect Yourself from 5G Radiation? Investigating LLM Responses to Implicit Misinformation
Guo, R., Xu, W., & Ritter, A. (2025) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2025.emnlp-main.1468 · Cited by 4
Sebastian, J. L., Moon, J.-M., & Camburn, E. M. (2025) · AERA Open · doi:10.1177/23328584251389621 · Cited by 4
VITAL: A New Dataset for Benchmarking Pluralistic Alignment in Healthcare
Shetty, A., Beheshti, A., Dras, M., & Naseem, U. (2025) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2025.acl-long.1119 · Cited by 11
de Oliveira, E. A. M., Cintra, L. M. D. F., Barbosa, G. H. W., Sousa, R. T., & Filho, A. R. G. (2025) · IEEE International Conference on Artificial Intelligence and eXtended and Virtual Reality (AIxVR) · doi:10.1109/aixvr63409.2025.00049 · Cited by 3
Reporting Guidelines for Large Language Models in Human–Robot Interaction
Matuszek, C., Williams, T., DePalma, N., Mead, R., Wen, R., Schneiders, E., Kennington, C., & Bezabih, A. M. (2025) · ACM Transactions on Human-Robot Interaction · doi:10.1145/3777552 · Cited by 5
Language proficiency assessment of autistic children using large language models
Qin, S., Liu, M., Wei, T., & Liu, Q. (2025) · Expert Systems with Applications · doi:10.1016/j.eswa.2025.129712 · Cited by 3
Agentic Recommender Systems: A Systematic Literature Review
Portugal, I. D. S., Alencar, P., & Cowan, D. D. (2026) · IEEE Transactions on Software Engineering · doi:10.1109/tse.2026.3657900 · Cited by 3
Li, M., Chen, H., Xiao, Y., Chen, J., Jiao, H., & Zhou, T. (2026) · Findings of the Association for Computational Linguistics: ACL (Findings of ACL) · doi:10.18653/v1/2026.findings-acl.1270 · Cited by 13
Reasoning Does Not Necessarily Improve Role-Playing Ability
Feng, X., Dou, L., & Kong, L. (2025) · Findings of the Association for Computational Linguistics: ACL (Findings of ACL) · doi:10.18653/v1/2025.findings-acl.537 · Cited by 3
Economic analysis of AI personalisation under product competition and data externality
Xu, B., Lu, Q., Li, H., & Yan, X. (2025) · International Journal of Production Research · doi:10.1080/00207543.2025.2534443 · Cited by 3
Investigating the Personality Consistency in Quantized Role-Playing Dialogue Agents
Wang, Y., Fashandi, H., & Ferreira, K. (2024) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2024.emnlp-industry.19 · Cited by 3
Sun, S., Lee, E., Baek, S. Y., Hwang, S., Lee, W., Nan, D., Jansen, B. J. J., & Kim, J. H. (2024) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2024.emnlp-main.609 · Cited by 3
En-join: Speculative LLM Play for Energy Community Engagement and Sustainability Awareness
Sachser, L., Isaza-Giraldo, A., Jiskrová, A., Cesário, V., Campos, P., Pereira, L., & Bala, P. (2025) · Designing Interactive Systems Conference · doi:10.1145/3715668.3735600 · Cited by 2
PersonaGen: A Persona-Driven Open-Ended Machine-Generated Text Dataset
Gugliotta, C., Cava, L. L., & Tagarelli, A. (2025) · ACM International Conference on Information and Knowledge Management (CIKM) · doi:10.1145/3746252.3761611 · Cited by 2
Pet-Bench: Benchmarking the Abilities of Large Language Models as E-Pets in Social Network Services
Guo, H., Xie, Z., Cao, S., Wang, B., Liu, W., Ye, Z., Li, Z., Liu, Z., & Lu, W. (2025) · ACM International Conference on Information and Knowledge Management (CIKM) · doi:10.1145/3746252.3761605 · Cited by 3
Toward Truly Intelligent Autonomous Systems: A Taxonomy of LLM Integration for Everyday Automation
Jung, M., Hempel, T., Al-Tawil, B., Yang, Q., Wachsmuth, S., & Al-Hamadi, A. K. (2025) · Communications in computer and information science · doi:10.1007/978-3-032-00986-9_6 · Cited by 2
H2HTalk: Evaluating Large Language Models as Emotional Companion
Wang, B., Wu, Y., Guo, H., & Li, Z. (2025) · Lecture notes in computer science · doi:10.1007/978-981-95-3343-5_35 · Cited by 3
How to Train Your Text-to-Image Model: Evaluating Design Choices for Synthetic Training Captions
Brack, M., Katakol, S., Friedrich, F., Schramowski, P., Ravi, H., Kersting, K., & Kale, A. (2025) · 2025 IEEE/CVF International Conference on Computer Vision Workshops (ICCVW) · doi:10.1109/iccvw69036.2025.00711 · Cited by 5
Mousavi, R., Kitchens, B., Oliver, A. G., & Abbasi, A. (2026) · Information Systems Research · doi:10.1287/isre.2024.1143 · Cited by 3
DEEPER Insight into Your User: Directed Persona Refinement for Dynamic Persona Modeling
Chen, A., Du, C., Chen, J., Xu, J., Zhang, Y., Yuan, S., Chen, Z., Li, L., & Xiao, Y. (2025) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2025.acl-long.1177 · Cited by 2
Persona Adaptable Strategies Make Large Language Models Tractable
Hattab, G., Anžel, A., Dubey, A., Ezekannagha, C., Yang, Z., & İlgen, B. (2024) · International Conference on Natural Language Processing and Information Retrieval (NLPIR) · doi:10.1145/3711542.3711581 · Cited by 2
Closing the Feedback Loop in Text2Vis: Refining Visualization with Vision-Language Models
Shi, S., Ren, T., Zhu, G., Feng, G., & Hu, J. C. (2025) · ACM International Conference on Multimedia (ACM MM) · doi:10.1145/3746027.3755862 · Cited by 3
Jang, S., Jeong, C., Kim, J., & Kahng, H. (2025) · Electronics · doi:10.3390/electronics14244919 · Cited by 1
BEE: Belief-Value-Aligned, Explainable, and Extensible Cognitive Framework for Conversational Agents
Yang, C., Groß, M. H., & Wampfler, R. (2025) · ACM International Conference on Intelligent Virtual Agents (IVA) · doi:10.1145/3717511.3747067 · Cited by 1
Mixture of Semantic and Spatial Experts for Explainable Traffic Prediction
Hu, Y., Li, S., Xia, D., Zhou, Z., Zhang, W., Li, H., Zhang, X., & Wang, S. (2025) · ACM International Conference on Information and Knowledge Management (CIKM) · doi:10.1145/3746252.3761412 · Cited by 1
Shhh! Your proxy is speaking: real persona social AI and the appropriation of likeness
Loewith, C. (2025) · AI & Society · doi:10.1007/s00146-025-02735-7 · Cited by 1
Zhou, Y., Chen, K., Gao, W., & Chen, C. (2026) · Journal of Engineering Design · doi:10.1080/09544828.2026.2639927 · Cited by 1
GRAVITY: A Framework for Personalized Text Generation via Profile-Grounded Synthetic Preferences
Dey, P., Rosa, D., Zheng, W., Barcklow, D., Zhao, J., & Ferrara, E. (2026) · Conference of the European Chapter of the Association for Computational Linguistics · doi:10.18653/v1/2026.eacl-long.348 · Cited by 1
Chircu, A. M., Czarnecki, C., Neumüller, T., Sebrak, S., Sultanow, E., & Winzer, F. (2026) · Hawaii International Conference on System Sciences (HICSS) · doi:10.24251/hicss.2026.519 · Cited by 1
Adavi, K. A. K., Ghosh, P., Banks, R., Sarkar, A., & Lindley, S. E. (2026) · Annual Symposium on Human-Computer Interaction for Work (CHIWORK) · doi:10.1145/3808045.3808058 · Cited by 1
Facet-Level Persona Control by Trait-Activated Routing with Contrastive SAE for Role-Playing LLMs
Tang, W., Wan, Z., Komamizu, T., & Ide, I. (2026) · Lecture notes in computer science · doi:10.1007/978-981-92-1947-6_33 · Cited by 2
HAG: Hierarchical Demographic Tree-based Agent Generation for Topic-Adaptive Simulation
Chen, R., Wu, T., Xu, B., Luo, J., Xu, X., & Shen, H. (2026) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2026.acl-long.1187 · Cited by 2
The Pragmatic Persona: Discovering LLM Persona Through Bridging Inference
Yang, J., Ryu, J., Ma, M., Pham, T. X., & Kim, J. (2026) · Lecture notes in computer science · doi:10.1007/978-3-032-31438-3_6 · Cited by 1
From Generic Intelligence to Personalized AI: A Tutorial on Foundations of LLM Personalization
Wang, R., Zeng, Q., Wang, X., Ye, Y., Sun, L., Li, J., & Yu, P. S. (2026) · ACM SIGKDD Conference on Knowledge Discovery and Data Mining (KDD) · doi:10.1145/3770855.3816457 · Cited by 1
The Gutenberg Test Part 1: Building a Creative AI Agent
Pozharev, T. (2024) · Artificial Societies · doi:10.18254/s207751800033493-1 · Cited by 1
Meta-evaluating the Effects of Social Preferences on NPC-evaluators in an Energy Community Game
Isaza-Giraldo, A., Bala, P., Jiskrová, A., Sachser, L., Campos, P., & Pereira, L. (2025) · CHI Conference Extended Abstracts on Human Factors in Computing Systems (CHI EA) · doi:10.1145/3706599.3720218 · Cited by 1
WITHDRAWNPreprint
(2024) · doi:10.31234/osf.io/gu9yq · Cited by 1
Personalizing Language Models for Generative TargetingPreprint
Yin, M., Gao, R., & Cong, Z. (2025) · SSRN Electronic Journal · doi:10.2139/ssrn.5329729 · Cited by 1
CLDassist: LLM-assisted CLD constructionPreprint
Waaijers, M., Rosenbusch, H., Lissa, C. J. V., Roefs, A., & Borsboom, D. (2025) · doi:10.31234/osf.io/gu9yq_v2 · Cited by 1
Harada, Y. (2026) · Qeios · doi:10.32388/be0zbc.3 · Cited by 1
In Prospect and Retrospect: Reflective Memory Management for Long-term Personalized Dialogue Agents
Tan, Z., Yan, J., Hsu, I.-H., Han, R., Wang, Z., Le, L. T., Song, Y., Chen, Y., Palangi, H., Lee, G., et al. (2025) · arXiv · Cited by 54
Self-citationCaring Without Feeling: Affective Dynamics as the Control Layer of Human-AI Agent Collaboration
Xu, J., Wu, X., Zhang, Z., Xu, Y., Yang, Y., Zhu, J., Xiao, L., Wu, W., & He, L. (2026) · arXiv · doi:10.48550/arxiv.2606.18259
Evaluation of character creation of large language models
Wang, Y., An, Y., Zhou, Y., Yao, C., Sun, X., & Sun, W. (2025) · Advances in Engineering Innovation · doi:10.54254/2977-3903/2025.20514
Plate, D. (2025) · International Journal of Emerging and Disruptive Innovation in Education VISIONARIUM · doi:10.62608/2831-3550.1033
Visionarium, July 2025, Full Issue
(2025) · International Journal of Emerging and Disruptive Innovation in Education VISIONARIUM · doi:10.62608/2831-3550.1035
Jang, D., Ahn, Y., & Shin, H. (2025) · Findings of the Association for Computational Linguistics: ACL (Findings of ACL) · doi:10.18653/v1/2025.findings-acl.1132
Liu, W., An, S., Lu, J., Wu, M., Li, T., Wang, X., Lv, C., Zheng, X., Yin, D., Sun, X., et al. (2025) · Findings of the Association for Computational Linguistics: ACL (Findings of ACL) · doi:10.18653/v1/2025.findings-acl.311 · Cited by 1
A Generalizable Rhetorical Strategy Annotation Model Using LLM-based Debate Simulation and Labelling
Ji, S., Hashemi, F., Chen, J., Pan, J., Ma, W., Zhang, H., Pan, S., Cheng, M. T., Mohole, S., Hassanpour, S., et al. (2025) · Findings of the Association for Computational Linguistics: EMNLP (Findings of EMNLP) · doi:10.18653/v1/2025.findings-emnlp.1117
MPTA: MultiTask Personalization Assessment
Tehenan, M., Chamoun, E., & Vlachos, A. (2025) · Findings of the Association for Computational Linguistics: EMNLP (Findings of EMNLP) · doi:10.18653/v1/2025.findings-emnlp.640
Improving Personality Alignment in Role-Playing Dialogue Agents for Small LLMs
Wang, Y., Fashandi, H., & Ferreira, K. (2025) · International Joint Conference on Neural Networks (IJCNN) · doi:10.1109/ijcnn64981.2025.11227883
Role-Playing in Vision-Language Models: A Comprehensive Evaluation of Image Description Performance
Niu, Z., Chang, X., Wang, B., Cheng, X., Li, G., & Li, L. (2025) · International Joint Conference on Neural Networks (IJCNN) · doi:10.1109/ijcnn64981.2025.11228995
Lou, J., Zhang, C., Zhang, X., & Wu, K. (2025) · ACM SIGSAC Conference on Computer and Communications Security (CCS) · doi:10.1145/3719027.3765223
BPMN-Based Business Process Collaboration Modeling Using Large Language Models
Kumarasinghe, A., & Kirikova, M. (2025) · Lecture notes in business information processing · doi:10.1007/978-3-032-12063-2_9
Javadi, V. S., Abedin, Z. U., & Flek, L. (2025) · Workshop on Perspectivist Approaches to NLP (NLPerspectives) · doi:10.18653/v1/2025.nlperspectives-1.2
Трофимчук, В. Т., & Кугуракова, В. В. (2025) · Russian Digital Libraries Journal · doi:10.26907/1562-5419-2025-28-4-957-986
Pluri-perspectivism in Human-Robot Co-creativity with Older Adults
Bossema, M., Saunders, R., Plaat, A., & Allouch, S. B. (2025) · Lecture notes in computer science · doi:10.1007/978-981-95-2382-5_23
Psychologically-Aware Retrieval-Augmented Generation for Coherent Role-Playing in LLMs
Xu, W. B., Shao, P., Zhao, S., Song, S., Yan, T., & Wang, C. (2026) · Lecture notes in computer science · doi:10.1007/978-981-95-5699-1_30
Hu, Y., Wang, Y., Watanabe, B., Gao, M., Qin, Z., Shi, K., Zhang, Z., Shambanna, S., Xue, Z., Zou, T., et al. (2026) · Research Square · doi:10.21203/rs.3.rs-8588902/v1
Hu, H., Yang, X., Wang, J., Zhang, Q., Tang, M., Song, C., Shang, Y., He, C., & Li, W. (2026) · doi:10.36227/techrxiv.177083699.99572896/v1
The Behavioral Fabric of LLM-Powered GUI Agents: Human Values and Interaction Outcomes
Gebreegziabher, S. A., Yang, Y., Chiang, C., Yoo, H., Chen, C., Do, H. J., Ashktorab, Z., Geyer, W., Gómez-Zará, D., & Li, T. J.-J. (2026) · ACM International Conference on Intelligent User Interfaces (IUI) · doi:10.1145/3742413.3789219 · Cited by 5
Trofimchuk, V. T., & Кугуракова, В. В. (2025) · Automatic Documentation and Mathematical Linguistics · doi:10.3103/s0005105525701298
Metadata
- Authors
- Tseng, Y.-M., Huang, Y.-C., Hsiao, T.-Y., Chen, W.-L., Huang, C.-W., Meng, Y., & Chen, Y.-N.
- Affiliations
- National Taiwan University (TW)
- Venue
- Findings of the Association for Computational Linguistics: EMNLP 2024
- Published
- 2024
- Pages
- 16612-16631
- OpenAlex
- W4404781205
- Cited by
- 87
- References
- 0
- Citations by year
- 2026: 47 · 2025: 35 · 2024: 5
- FWCI
- 25.12
- Type
- conference paper
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- cc-by
- Locations
- Findings of the Association for Computational Linguistics: EMNLP (Findings of EMNLP) (publishedVersion, cc-by)
- arXiv (Cornell University) (submittedVersion, cc-by-sa)
- arXiv (Cornell University)
- Funders
- National Taiwan University (113L900902, 113L900903)
- National Science and Technology Council
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Speech and dialogue systems
- Physical Sciences › Computer Science › Artificial Intelligence › Topic Modeling
- Physical Sciences › Computer Science › Human-Computer Interaction › Persona Design and Applications
- Keywords
- personas, large language models, LLM personalization, personality assessment, personalized search, LLM-as-a-judge
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
