

The DOI matches its Crossref record; 105 of the 127 references it cites were found in a registry or an index.
Two Tales of Persona in LLMs: A Survey of Role-Playing and Personalization
Open accessAbstract
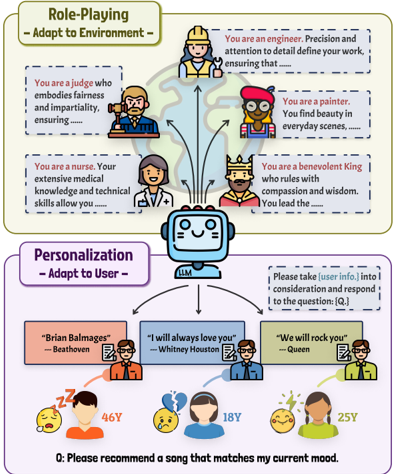
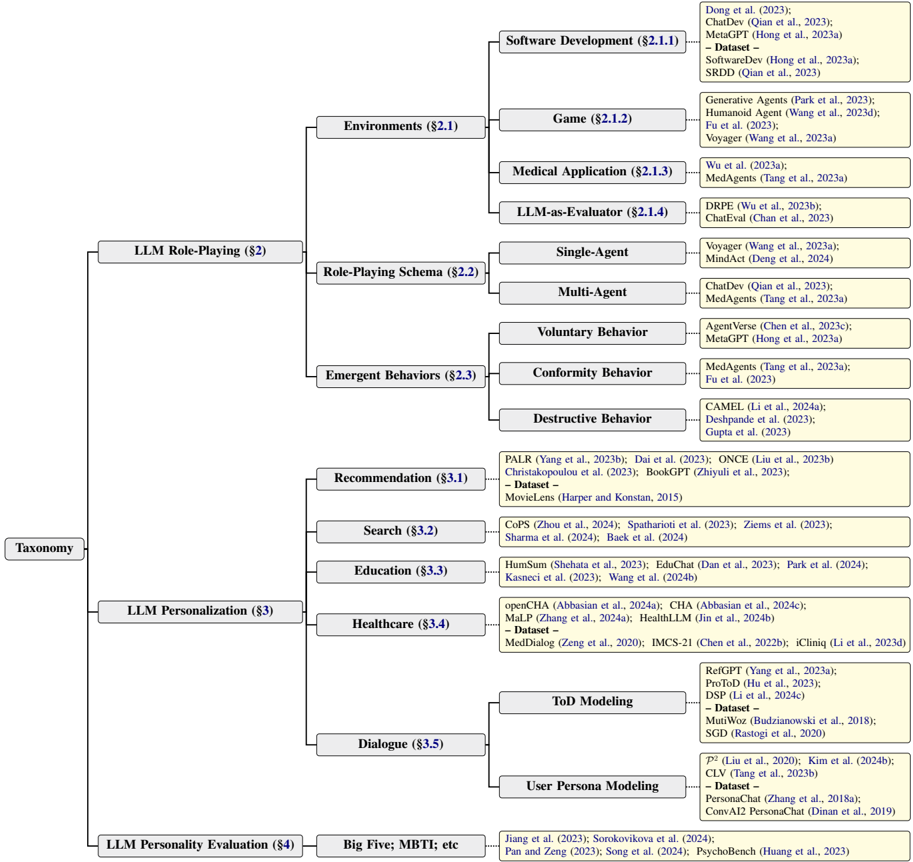
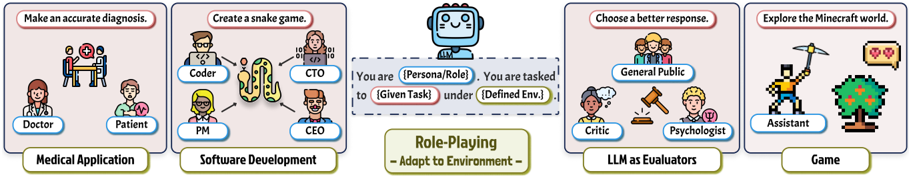
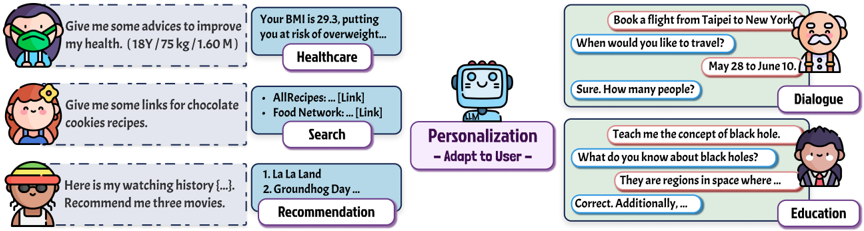
The concept of persona, originally adopted in dialogue literature, has re-surged as a promising framework for tailoring large language models (LLMs) to specific context (e.g., personalized search, LLM-as-a-judge).However, the growing research on leveraging persona in LLMs is relatively disorganized and lacks a systematic taxonomy.To close the gap, we present a comprehensive survey to categorize the current state of the field.We identify two lines of research, namely (1) LLM Role-Playing, where personas are assigned to LLMs, and (2) LLM Personalization, where LLMs take care of user personas.Additionally, we introduce existing methods for LLM personality evaluation.To the best of our knowledge, we present the first survey for role-playing and personalization in LLMs under the unified view of persona.We continuously maintain a paper collection to foster future endeavors.1 * Equal contribution. 1 https://github.com/MiuLab/PersonaLLM-Survey
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“However, collecting substantial annotations for training a personalized system for long-term use is hard (Tseng et al., 2024).”
From In Prospect and Retrospect: Reflective Memory Management for Long-term Personalized Dialogue Agents (2025) · cites this paper as Tseng et al., 2024
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“yet their inherent statelessness poses a significant challenge for maintaining coherent, personalized conversations over time (Chen et al., 2024; Li et al., 2024b; Tseng et al., 2024)”
From In Prospect and Retrospect: Reflective Memory Management for Long-term Personalized Dialogue Agents (2025) · cites this paper as Tseng et al., 2024
Experimental — accuracy not yet measured
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
The publisher hasn’t deposited this paper’s reference list.
Research works printed but not linked: 17
- Tom DeMarco and Tim Lister. 2013. Peopleware: pro- ductive projects and teams. Addison-Wesley.
- Ameet Deshpande, EunJeong Hwang, Vishvak Mura- hari, Joon Sung Park, Diyi Yang, Ashish Sabharwal, Karthik Narasimhan, and Ashwin Kalyan, editors. 2024. Proceedings of the 1st Workshop on Person- alization of Generative AI Systems (PERSONALIZE 2024). Association for Computational Linguistics, St. Julians, Malta.
- Mihail Eric, Rahul Goel, Shachi Paul, Abhishek Sethi, Sanchit Agarwal, Shuyang Gao, Adarsh Kumar, Anuj Goyal, Peter Ku, and Dilek Hakkani-Tur. 2020. Mul- tiWOZ 2.1: A consolidated multi-domain dialogue dataset with state corrections and state tracking base- lines. In Proceedings of the Twelfth Language Re- sources and Evaluation Conference, pages 422-428, Marseille, France. European Language Resources Association. 19
- Jun Hu, Wenwen Xia, Xiaolu Zhang, Chilin Fu, We- ichang Wu, Zhaoxin Huan, Ang Li, Zuoli Tang, and Jun Zhou. 2024. Enhancing sequential recommenda- tion via llm-based semantic embedding learning. In Companion Proceedings of the ACM on Web Confer- ence 2024, pages 103-111.
- Daniil Huryn, William M. Hutsell, and Jinho D. Choi. 2022. Automatic generation of large-scale multi-turn dialogues from Reddit. In Proceedings of the 29th International Conference on Computational Linguis- tics, pages 3360-3373, Gyeongju, Republic of Korea. International Committee on Computational Linguis- tics.
- Guohao Li, Hasan Hammoud, Hani Itani, Dmitrii Khizbullin, and Bernard Ghanem. 2024a. Camel: Communicative agents for" mind" exploration of large language model society. Advances in Neural Information Processing Systems, 36. 2, 5, 8
- Lei Li, Yongfeng Zhang, and Li Chen. 2023a. Person- alized prompt learning for explainable recommen- dation. ACM Transactions on Information Systems, 41(4):1-26. 5, 18, 19
- Yanran Li, Hui Su, Xiaoyu Shen, Wenjie Li, Ziqiang Cao, and Shuzi Niu. 2017. DailyDialog: A manually labelled multi-turn dialogue dataset. In Proceedings of the Eighth International Joint Conference on Nat- ural Language Processing (Volume 1: Long Papers), pages 986-995, Taipei, Taiwan. Asian Federation of Natural Language Processing. 19
- Zekun Li, Baolin Peng, Pengcheng He, Michel Galley, Jianfeng Gao, and Xifeng Yan. 2024c. Guiding large language models via directional stimulus prompting. Advances in Neural Information Processing Systems, 36. 2, 7
- Jianmo Ni, Jiacheng Li, and Julian McAuley. 2019. Jus- tifying recommendations using distantly-labeled re- views and fine-grained aspects. In Proceedings of the 2019 conference on empirical methods in natural language processing and the 9th international joint conference on natural language processing (EMNLP- IJCNLP), pages 188-197. 18, 19
- M Swift and J Allen. 2010. Towards a personal health management assistant. Journal of biomedical infor- matics, 43(5):S13-S16.
- Ning Wu, Ming Gong, Linjun Shou, Shining Liang, and Daxin Jiang. 2023b. Large language models are diverse role-players for summarization evaluation. In CCF International Conference on Natural Language Processing and Chinese Computing, pages 695-707. Springer. 2, 4
- Xuhai Xu, Bingsheng Yao, Yuanzhe Dong, Saadia Gabriel, Hong Yu, James Hendler, Marzyeh Ghas- semi, Anind K Dey, and Dakuo Wang. 2024. Mental- llm: Leveraging large language models for mental health prediction via online text data. Proceedings of the ACM on Interactive, Mobile, Wearable and Ubiquitous Technologies, 8(1):1-32.
- Shunyu Yao, Jeffrey Zhao, Dian Yu, Nan Du, Izhak Shafran, Karthik R Narasimhan, and Yuan Cao. 2022b. React: Synergizing reasoning and acting in language models. In The Eleventh International Conference on Learning Representations. 3
- Saizheng Zhang, Emily Dinan, Jack Urbanek, Arthur Szlam, Douwe Kiela, and Jason Weston. 2018a. Per- sonalizing dialogue agents: I have a dog, do you have pets too? In Proceedings of the 56th Annual Meeting of the Association for Computational Linguistics (Vol- ume 1: Long Papers), pages 2204-2213, Melbourne, Australia. Association for Computational Linguistics. 2, 20 · DOI · Paper page
- Wanjun Zhong, Lianghong Guo, Qiqi Gao, He Ye, and Yanlin Wang. 2024. Memorybank: Enhancing large language models with long-term memory. Proceed- ings of the AAAI Conference on Artificial Intelligence, 38(17):19724-19731. · DOI · Paper page
- USER:] That is all I need to know. Thanks, goodbye. [SYSTEM:] Thank you so much for Cambridge TownInfo center. Have a great day! Table 5: An example of ToD modeling from the MultiWOZ dataset (Zang et al., 2020).
Cited by
Sorted by citations
Items 101–148 of 148
PARAN: Persona-Augmented Review ANswering System on Food Delivery Review Dataset
Park, M., Yun, J., & Kim, B. (2025) · IEEE ... International Conference on Data Mining workshops · doi:10.1109/icdmw69685.2025.00075
Specialized Information Retrieval with Improved Reliability via LLM Finetuning
Robotin, G. C., & Slăvescu, R. R. (2025) · IEEE International Conference on Intelligent Computer Communication and Processing (ICCP) · doi:10.1109/iccp68926.2025.11427155
Effective and Efficient Role-Playing LLM Agent via Pruning Knowledge
Ding, Y. (2026) · Lecture notes in computer science · doi:10.1007/978-981-95-7144-4_33
From Simulation to Strategy: Automating Personalized Interaction Planning for Conversational Agents
Chang, W.-Y., Huang, T., Chen, C.-D., & Chen, Y.-N. (2025) · IEEE Workshop on Automatic Speech Recognition and Understanding (ASRU) · doi:10.1109/asru65441.2025.11434776
Self-citationShirahama, N., Yoshimoto, Y., Nakaya, N., & Watanabe, S. (2026) · Mathematics · doi:10.3390/math14071224
What if I Were?: Synthetic Lived Experience based on Generative Models
Lee, S.-K., Jeong, H., Oh, S. W., Lim, J., Noh, K. J., Chung, S., & Jung, G. (2026) · CHI Conference Extended Abstracts on Human Factors in Computing Systems (CHI EA) · doi:10.1145/3772363.3798417
Maruyama, K., & Besold, T. R. (2026) · CHI Conference on Human Factors in Computing Systems · doi:10.1145/3772318.3791402
More Isn't Always Better: Balancing Decision Accuracy and Conformity Pressures in Multi-AI Advice
Tsuchiya, Y., & Baba, Y. (2026) · CHI Conference on Human Factors in Computing Systems · doi:10.1145/3772318.3791648 · Cited by 1
Gui, X., Xia, D., Colley, M., Li, Y., Chauhan, V., Anubhav, A., Zhou, Z., Javanmardi, E., Seo, S. H., Chang, C.-M., et al. (2026) · CHI Conference on Human Factors in Computing Systems · doi:10.1145/3772318.3790537
A Unified Framework for Spatially-Aware Embodied Agents in XR
Shin, J., Shin, D., Lee, E., Kim, H., & Lee, S. (2026) · IEEE Conference on Virtual Reality and 3D User Interfaces Abstracts and Workshops (VRW) · doi:10.1109/vrw70859.2026.00182
Leite, G. S., Milfont, P. B., Maia, M. D. L., & Gomes, M. V. (2026) · Lecture notes in networks and systems · doi:10.1007/978-3-032-22236-7_10
FBLayout: Optimizing Memory Layout for Efficient LLM Finetuning on Mobile GPUs
Tam, K., Niu, W., Bao, Y., Ouyang, X., Xu, C., & Li, L. (2026) · International Conference on Mobile Systems, Applications, and Services · doi:10.1145/3745756.3809214
Verification-Gated Persona State Transitions for Memory-Augmented Language Agents
Li, F., Li, J. M., Ma, S., & Liu, Y. (2026) · Symmetry · doi:10.3390/sym18061037 · Cited by 1
Ju, J., Seo, J., Jang, J., Lee, D., & Park, H. (2026) · IEEE Pacific Visualization Conference (PacificVis) · doi:10.1109/pacificvis68791.2026.00019
Kobayashi, M., Goto, A., & Himuro, A. (2026) · BMC Psychology · doi:10.1186/s40359-026-05067-3
MENTOR: Mitigating Identity Drift in Dynamic Role-Playing via Dual-Chain Structured Memory
Zhuoning, Z., Gao, X., & Shi, H. (2026) · Findings of the Association for Computational Linguistics: ACL (Findings of ACL) · doi:10.18653/v1/2026.findings-acl.1046
Wu, J., Zhao, J., Huangxinrong, Zhang, C., & Wu, X. (2026) · Findings of the Association for Computational Linguistics: ACL (Findings of ACL) · doi:10.18653/v1/2026.findings-acl.205
From Coarse to Fine: Self-Adaptive Hierarchical Planning for LLM Agents
Tan, H., Zhang, Z., Ma, C., Liu, T., Dai, Q., & Chen, X. (2026) · Findings of the Association for Computational Linguistics: ACL (Findings of ACL) · doi:10.18653/v1/2026.findings-acl.77
ChatAnime: Towards User-Centered Emotional Support in LLM-based Virtual Character Chat
Qiu, L., Pu, S. X., Feng, Y., Gao, W., & He, T. (2026) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2026.acl-long.2179
Wang, C.-C., Liu, F.-C., Xie, J., Lai, C.-M., & Lin, C.-S. (2026) · Education and Information Technologies · doi:10.1007/s10639-026-14086-x
Character History in the Context Design of LLM-Based AI
Matsumoto, T. (2026) · Lecture notes in computer science · doi:10.1007/978-3-032-30038-6_26
UWU Benchmarks: Assessing LLM Performance in k-Shot Prompted Role-Play of Unknown Characters
Rosario, E. N., & Ong, E. (2026) · Lecture notes in networks and systems · doi:10.1007/978-3-032-20897-2_41
All too perfect: bias and aspiration in persona generation with LLMs
Corrêa, N. K., Mallmann, R., Kaczér, D., Mai, F., Ilievska, A., & Mönig, J. M. (2026) · Artificial Intelligence Review · doi:10.1007/s10462-026-11641-3
Hu, Y., Wang, Y., Watanabe, B., Gao, M., Qin, Z., Shi, K., Zhang, Z., Shambanna, S., Xue, Z., Zou, T., et al. (2026) · doi:10.2196/preprints.106505
Persona-as-Configuration: Generative Stakeholder Reporting for Agricultural Floods
Larsen, O. A., Santilli, T., Daghero, F., & Moghaddam, M. T. (2026) · Lecture notes in computer science · doi:10.1007/978-3-032-39143-8_12
Recommendation of Rendezvous Point by Role-playing Generated by LLM
HAMASAKI, H., Kubo, M., Hiroshi, S. A. T. O., & YAMAGUCHI, A. (2026) · Transactions of the Society of Instrument and Control Engineers · doi:10.9746/sicetr.62.249
PersonaEcho: A Personalized Voice Companion
Chen, X., & Liu, Y. (2026) · International Conference on Artificial Intelligence, Big Data and Algorithms (CAIBDA) · doi:10.1109/caibda70336.2026.11621105
Kou, Y., Zhu, D., Sun, W., Zhang, K., Min, X., & Zhai, G. (2026) · International Conference on Quality of Multimedia Experience (QoMEX) · doi:10.1109/qomex69967.2026.11618388
DREAM: LLM-based Dynamic Role-playing via Event-Aware Memory Graph
Xiao, Z., Li, M., Wang, X., Li, L., Shui, L., Ji, M., & Cai, B. (2026) · ACM SIGKDD Conference on Knowledge Discovery and Data Mining (KDD) · doi:10.1145/3770855.3818027
CoPersona: Collaborative Persona Graphs for Robust LLM Personalization
Zhang, Y. P., Wang, L., Madhu, H., Bui, N., Roznyatovskiy, W., & Ying, R. (2026) · ACM SIGKDD Conference on Knowledge Discovery and Data Mining (KDD) · doi:10.1145/3770855.3817892
EchoPersona – A Persona-Faithful Conversational AI System using RAG and LLMs
Saritha, S. L., Kondaveeti, S., Prathyusha, N., Paul, N. A., Loshitha, K. S., & Shameel, S. (2026) · IEEE Global Symposium on Emerging and Communication Technologies (GSEACT) · doi:10.1109/gseact68539.2026.11620147
Persona-Guided LLM Adaptation for Culturally Personalized Diabetes Prevention MCQs
Fan, J., Fensore, C. M., Shtulman, J., Pai, R., Shoaib, D. M., Shah, M. K., & Ho, J. C. (2026) · IEEE International Conference on Healthcare Informatics (ICHI) · doi:10.1109/ichi69079.2026.00125
SEEK-Policy: a data-driven cross-modal retrieval framework for climate policy recommendation
Poopradubsil, T., Chen, S., Latcharote, P., & Thaipisutikul, T. (2026) · PeerJ Computer Science · doi:10.7717/peerj-cs.4054
Baldwin, A. J., Movahedi, M., & Choi, J. (2026) · ASCE Construction Research Congress (CRC) · doi:10.1061/9780784487006.071
Sauka, K., Situmeang, F., & Kackovic, M. (2026) · International Conference on Computer Communication and the Internet (ICCCI) · doi:10.1109/iccci70321.2026.11666502
Zhang, P., Liu, C., & Wu, Z. (2026) · Journal of Consumer Behaviour · doi:10.1002/cb.70243
The Impact Square: Four Levers of Human Responsibility from Conversational to Agentic AIPreprint
Roth, M. (2026) · SSRN Electronic Journal · doi:10.2139/ssrn.7408718
Lin, Y., & Xiao, N. (2026) · Spatial Cognition and Computation · doi:10.1080/13875868.2026.2730164
Personalized Alignment of Large Language Models
Woźniak, S., Koptyra, B., Gurgul, J., Kocoń, J., & Kazienko, P. (2026) · Lecture notes in computer science · doi:10.1007/978-3-032-36868-3_26
Evaluating User Perception and Experience of Persona-Driven LLM-Powered Social Robots
Jafari, G., Rasouli, S., Hutchings, N., Christian, L. W. T., Thompson, B., & Dautenhahn, K. (2026) · IEEE RO-MAN · doi:10.1109/ro-man72286.2026.11714602
Sasson, O., Apartsin, A., & Aperstein, Y. (2026) · Education Sciences · doi:10.3390/educsci16101752 · Cited by 1
Marques, F. P. R., de Miranda, L. C., & de Miranda, E. E. C. (2026) · Simpósio Brasileiro de Jogos e Entretenimento Digital (SBGames) · doi:10.5753/sbgames.2026.25640
Li, C., Xiao, X., Xiao, Y., Xu, Z., Li, X., Luan, Y., Wei, J., Yang, Y., & Zhang, C. (2026) · Findings of the Association for Computational Linguistics: EMNLP (Findings of EMNLP) · doi:10.18653/2026.findings-emnlp.625
Which way does time fly in artificial intelligence?Preprint
Uchikawa, N., & Sasaki, K. (2026) · Research Square · doi:10.21203/rs.3.rs-11533262/v1
Comparative Evaluation of LLM-Based Configurations for a RAG Student Counseling Chatbot
Nazah, V. Z., Pramudita, R., Alfian, A. N., Safitri, N., Solikin, & Muis, S. (2026) · International Conference on Creative Communication and Innovative Technology (ICCIT) · doi:10.1109/iccit70127.2026.11749211
Wilde, L. R. A. (2026) · De Gruyter eBooks · doi:10.1515/9783112249581-003
AI Characters and/or/as Roleplaying Agents
Thon, J.-N. (2026) · De Gruyter eBooks · doi:10.1515/9783112249581-002
Metadata
- Authors
- Tseng, Y.-M., Huang, Y.-C., Hsiao, T.-Y., Chen, W.-L., Huang, C.-W., Meng, Y., & Chen, Y.-N.
- Affiliations
- National Taiwan University (TW)
- Venue
- Findings of the Association for Computational Linguistics: EMNLP 2024
- Published
- 2024
- Pages
- 16612-16631
- OpenAlex
- W4404781205
- Cited by
- 87
- References
- 0
- Citations by year
- 2026: 47 · 2025: 35 · 2024: 5
- FWCI
- 25.12
- Type
- conference paper
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- cc-by
- Locations
- Findings of the Association for Computational Linguistics: EMNLP (Findings of EMNLP) (publishedVersion, cc-by)
- arXiv (Cornell University) (submittedVersion, cc-by-sa)
- arXiv (Cornell University)
- Funders
- National Taiwan University (113L900902, 113L900903)
- National Science and Technology Council
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Speech and dialogue systems
- Physical Sciences › Computer Science › Artificial Intelligence › Topic Modeling
- Physical Sciences › Computer Science › Human-Computer Interaction › Persona Design and Applications
- Keywords
- personas, large language models, LLM personalization, personality assessment, personalized search, LLM-as-a-judge
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
