

The DOI matches its Crossref record; 31 of the 41 references it cites were found in a registry or an index; 4 of the 17 sources its claims cite were checked for support.
Adaptive Attacks Break Defenses Against Indirect Prompt Injection Attacks on LLM Agents
Open accessAbstract
Large Language Model (LLM) agents exhibit remarkable performance across diverse applications by using external tools to interact with environments.However, integrating external tools introduces security risks, such as indirect prompt injection (IPI) attacks.Despite defenses designed for IPI attacks, their robustness remains questionable due to insufficient testing against adaptive attacks.In this paper, we evaluate eight different defenses and bypass all of them using adaptive attacks, consistently achieving an attack success rate of over 50%.This reveals critical vulnerabilities in current defenses.Our research underscores the need for adaptive attack evaluation when designing defenses to ensure robustness and reliability.
Overview
AI snapshot
Written from the paper’s full text.
TL;DR
This paper evaluates eight defenses against indirect prompt injection (IPI) attacks on LLM agents and designs adaptive attacks that bypass all of them, with adaptive attack success rates consistently above 50%. It argues that adaptive attack evaluation is necessary to assess defense robustness.
Key findings
- Adaptive attacks broke all eight defenses across both tested agents, with ASR-adaptive attack exceeding 50% in all cases.
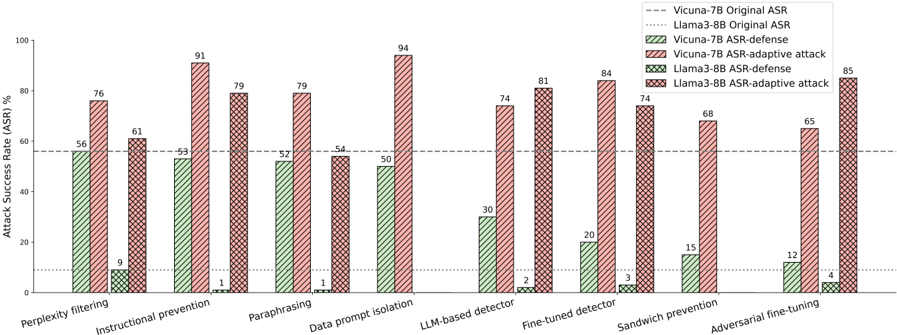
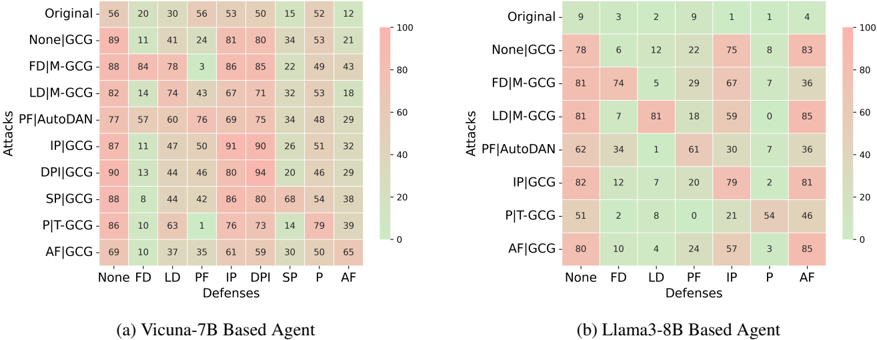
- For the Vicuna-7B prompted agent, most defenses reduced original ASR from 56% to lower values, such as 12% with adversarial finetuning; for the Llama3-8B finetuned agent, original ASR was 9% and lower under defenses.
- Detection-based defenses were largely bypassed: fine-tuned detector detection rate dropped from 61% on original attacks to 1% with adversarial strings for Vicuna-7B; LLM-based detector dropped from 72% to 0% for Llama3-8B; perplexity filtering had 0% detection on original attacks and 1% with adversarial strings.
- Adaptive strings also improved ASR over non-adaptive strings for defenses targeting adversarial strings: perplexity filtering Vicuna-7B 24% → 76%, Llama3-8B 22% → 61%; paraphrasing Vicuna-7B 53% → 79%, Llama3-8B 8% → 54%.
- Detailed ASRs: Vicuna-7B total original 0.50, ASR-defense 0.33 ± 0.18, ASR-attack 0.68 ± 0.15; Llama3-8B total original 0.40, ASR-defense 0.02 ± 0.02, ASR-attack 0.57 ± 0.17.
Methods
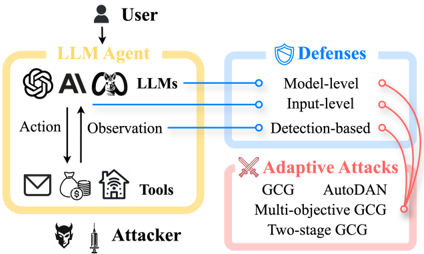
- Evaluated eight defenses grouped as detection-based (fine-tuned detector, LLM-based detector, perplexity filtering), input-level (instructional prevention, data prompt isolation, sandwich prevention, paraphrasing), and model-level (adversarial finetuning).
- Used InjecAgent benchmark subset of 100 test cases: 50 direct harm and 50 data stealing, including 25 unique direct harm attacks, 27 distinct data stealing attacks, and 16 user scenarios. Tested two agents: Vicuna-7B prompted ReAct agent and Llama3-8B finetuned agent.
- Designed adaptive attacks using GCG, multi-objective GCG, two-stage GCG, and AutoDAN, assuming white-box access to agent, defenses, and prompts. Metrics included attack success rate (ASR), target rate, and detection rate; additional AgentDojo experiments used 16 cases on Llama3-8B.
Limitations
- The paper states its adaptive attacks focus only on the agent’s first-step action, so they provide the least improvement in the second step of data-stealing attacks.
- The paper states attacks assume white-box access to the agent model, defense models, and detailed prompts, and that it does not account for combinations of defenses or exhaustively cover all possible defenses.
- Evident from the text: the main evaluation uses a 100-case subset of InjecAgent, and the AgentDojo extension uses only 16 cases, which may limit generalizability.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
22 Own result · 12 Own interpretation · 9 No basis given · 5 Not checked yet · 4 Sources not found · 3 Own method · 2 Supported · 1 Partly supported · accuracy not yet measured
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“Another method is to paraphrase the external content E Tu to disrupt tokenlevel optimized adversarial strings (Jain et al., 2023), thereby reducing their effectiveness.”
§ Adaptive Attacks Break Defenses Against Indirect Prompt Injection Attacks on LLM Agents > Paraphrasing (P).
What the sources say
- Partly supportedcites Jain et al., 2023 sourceExperimental — accuracy not yet measured
The Results section reports that paraphrasing prompts significantly reduced attack success and that ChatGPT ignored the adversarial suffix in most cases. The paper tests paraphrasing adversarial prompts, not specifically external content E Tu, so it does not establish that the same defense works in that setting. (LLM, conf=0.84)
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Partly supported
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“However, after applying adaptive attacks, the detection rates drop to nearly zero in most cases, demonstrating the effectiveness of adversarial strings in bypassing the detectors.”
§ Adaptive Attacks Break Defenses Against Indirect Prompt Injection Attacks on LLM Agents > 6.1 Detailed Results and Analysis
boosteddirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Our results show that adaptive attacks consistently achieve success rates above 50% across the targeted defenses and LLM agents—exceeding the ASR before deploying any defense and significantly outperforming non-adaptive attacks.”
§ Adaptive Attacks Break Defenses Against Indirect Prompt Injection Attacks on LLM Agents > Model -level Adversarial finetuning
boosteddirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“For the top three strongest defenses shown in Figure 2 for the Vicuna-7B based agent—the fine-tuned detector, sandwich prevention, and adversarial finetuning—as well as defenses specifically targeting adversarial strings, i.e., paraphrasing and perplexity filtering, we observe that the adaptive attack for each defense significantly outperforms other attacks.”
§ Adaptive Attacks Break Defenses Against Indirect Prompt Injection Attacks on LLM Agents > 6.4 Cross Evaluation
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Upon closer examination, we found that this is primarily due to many unsuccessful cases in the second step of the data stealing attack.”
§ Adaptive Attacks Break Defenses Against Indirect Prompt Injection Attacks on LLM Agents > 6.1 Detailed Results and Analysis
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“From Figure 2, we observe that most prompt modification defenses offer weak protection against the attacks for the Vicuna-7B based agent, except for sandwich prevention.”
§ Adaptive Attacks Break Defenses Against Indirect Prompt Injection Attacks on LLM Agents > 6.1 Detailed Results and Analysis
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“For the Vicuna-7B based agent, most defenses reduce the original ASR from 56% to lower values, such as 12% with adversarial finetuning.”
§ Adaptive Attacks Break Defenses Against Indirect Prompt Injection Attacks on LLM Agents > 5.2 Experiment Results
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Our results show that adaptive attacks consistently achieve success rates above 50% across the targeted defenses and LLM agents—exceeding the ASR before deploying any defense and significantly outperforming non-adaptive attacks.”
§ Adaptive Attacks Break Defenses Against Indirect Prompt Injection Attacks on LLM Agents > Model -level Adversarial finetuning
boosteddirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
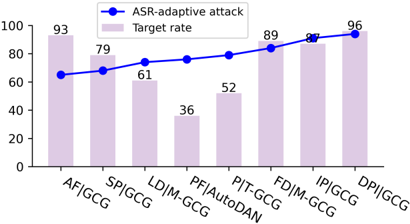
“However, a high target rate does not always correspond to a high ASR, as seen in GCG over adversarial finetuning.”
§ Adaptive Attacks Break Defenses Against Indirect Prompt Injection Attacks on LLM Agents > 5.2 Experiment Results
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We present the results in Table 3, showing that our adaptive adversarial strings are more effective than the non-adaptive strings.”
§ Adaptive Attacks Break Defenses Against Indirect Prompt Injection Attacks on LLM Agents > 6.1 Detailed Results and Analysis
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Probably not a substantial claim. 18
- It may state two separate claims as one. 11
Every source the paper cites for this claim was checked and supports it.
In the paper
“AgentDojo (Debenedetti et al., 2024) is a benchmark designed to evaluate IPI attacks on LLM agents within a dynamic simulated environment.”
§ Adaptive Attacks Break Defenses Against Indirect Prompt Injection Attacks on LLM Agents > B Experiments on the AgentDojo Benchmark
What the sources say
- Supportedcites Debenedetti et al., 2024 source
The Introduction describes AgentDojo as a dynamic benchmarking framework for evaluating AI agents when prompt injections are present. It also says agents call tools in a stateful, adversarial environment, supporting the claim's description of a dynamic simulated environment. (LLM, conf=0.94)
plainn = 16- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
- Supported
Every source the paper cites for this claim was checked and supports it.
In the paper
“The study of adaptive attacks has also expanded into LLMs, particularly in the context of jailbreak (Jain et al., 2023;Andriushchenko et al., 2024).”
§ Adaptive Attacks Break Defenses Against Indirect Prompt Injection Attacks on LLM Agents > 7.3 Adaptive Attacks
What the sources say
- Supportedcites Jain et al., 2023 source
The Introduction says the paper studies adversarial attacks on LLMs, and Section 4 uses a jailbreaking attack as its testbed. The Abstract and Section 5.3 explicitly discuss adaptive attacks against LLM defenses, supporting the claim that this line of study extends to LLM jailbreaks. (LLM, conf=0.91)
- Supportedcites Andriushchenko et al., 2024 source
The Introduction explicitly says the paper presents model-specific adaptive attacks for evaluating LLM robustness and discusses designing jailbreak attacks. Its “Adaptive attack” section says the authors customize those attacks for each target LLM. This supports the cited point that adaptive-attack research extends to LLM jailbreaking. (LLM, conf=0.94)
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
- Supported
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“As mentioned earlier, the GCG attack over the adversarial training defense achieves a high target rate but a relatively low ASR for the Vicuna-7B based agent.”
§ Adaptive Attacks Break Defenses Against Indirect Prompt Injection Attacks on LLM Agents > 6.1 Detailed Results and Analysis
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Using a prefix adversarial string instead of a suffix yields better performance for Llama3-8B.”
§ Adaptive Attacks Break Defenses Against Indirect Prompt Injection Attacks on LLM Agents > A Implementation Details
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
- The authors state this as an assumption: The attacker has white-box access to the agent model, defense models, and detailed prompts.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“However, adaptively trained adversarial strings still bypass these defenses, achieving high ASRs for both agents.”
§ Adaptive Attacks Break Defenses Against Indirect Prompt Injection Attacks on LLM Agents > 5.2 Experiment Results
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Additionally, AutoDAN achieves the lowest target rate among the methods but still attains a high ASR.”
§ Adaptive Attacks Break Defenses Against Indirect Prompt Injection Attacks on LLM Agents > 5.2 Experiment Results
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Most GCG models achieve high target rates, reflecting their training effectiveness.”
§ Adaptive Attacks Break Defenses Against Indirect Prompt Injection Attacks on LLM Agents > 5.2 Experiment Results
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Although adaptive attacks still yield substantial improvements in ASR, they are not as effective as on the InjecAgent benchmark-where all adaptive attack ASRs exceed 50%.”
§ Adaptive Attacks Break Defenses Against Indirect Prompt Injection Attacks on LLM Agents > B Experiments on the AgentDojo Benchmark
plaindirectn = 16- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- The authors state this as an assumption: The attacker has white-box access to the agent model, defense models, and detailed prompts.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“In this paper, we evaluate eight different defenses and bypass all of them using adaptive attacks, consistently achieving an attack success rate of over 50%.”
- Also stated in: § Model -level Adversarial finetuning · boosted
“Our results show that adaptive attacks consistently achieve success rates above 50% across the targeted defenses and LLM agents—exceeding the ASR before deploying any defense and significantly outperforming non-adaptive attacks.”
§ Adaptive Attacks Break Defenses Against Indirect Prompt Injection Attacks on LLM Agents > Abstract
boosteddirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Also stated in: § Model -level Adversarial finetuning · boosted
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Our results indicate that adversarial strings for the Llama3-8B based agent are more challenging to optimize than those for the Vicuna-7B based agent.”
§ Adaptive Attacks Break Defenses Against Indirect Prompt Injection Attacks on LLM Agents > A Implementation Details
hedgedcorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
- The authors state this as an assumption: The attacker has white-box access to the agent model, defense models, and detailed prompts.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The Llama3-based agent shows greater resilience to IPI attacks, with an original ASR of 9% and even lower ASRs under defenses.”
§ Adaptive Attacks Break Defenses Against Indirect Prompt Injection Attacks on LLM Agents > 5.2 Experiment Results
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“We observe that the fine-tuned detector achieves the highest detection rate on the original IPI attacks for the Vicuna-7B based agent and LLM-based detetor for the Llama3-8B based agent.”
§ Adaptive Attacks Break Defenses Against Indirect Prompt Injection Attacks on LLM Agents > 6.1 Detailed Results and Analysis
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“Our research is not an exhaustive exploration of all potential defenses that could be adapted for IPI attacks.”
§ Adaptive Attacks Break Defenses Against Indirect Prompt Injection Attacks on LLM Agents > 10 Limitations
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“These longer contexts, which often include multiple rounds of agent-tool interaction, pose greater challenges for optimizing the adversarial string.”
§ Adaptive Attacks Break Defenses Against Indirect Prompt Injection Attacks on LLM Agents > B Experiments on the AgentDojo Benchmark
plaindirectn = 16- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
- The authors state this as an assumption: The attacker has white-box access to the agent model, defense models, and detailed prompts.
In the paper
“This aligns with the conclusion in InjecAgent (Zhan et al., 2024) that fine-tuned agents are more resilient to IPI attacks.”
§ Adaptive Attacks Break Defenses Against Indirect Prompt Injection Attacks on LLM Agents > 5.2 Experiment Results
What the sources say
- Not checked yetcites Zhan et al., 2024 source
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“This paper presents the first study of defenses and adaptive attacks against LLM agents in the context of IPI attacks.”
§ Adaptive Attacks Break Defenses Against Indirect Prompt Injection Attacks on LLM Agents > 7.1 LLM Agent Safety
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper may give no reason why it holds.
None of the sources cited for this claim have been checked yet.
In the paper
“To automate and strengthen these attacks, researchers have developed methods like GCG (Zou et al., 2023) and AutoDAN attacks (Liu et al., 2024a;Zhu et al., 2023), which automatically find prompts to jailbreak LLMs.”
§ Adaptive Attacks Break Defenses Against Indirect Prompt Injection Attacks on LLM Agents > 7.2 LLM Safety and Adversarial Attacks
What the sources say
- Not checked yetcites Zou et al., 2023 source
- Not matchedcites Liu et al., 2024a
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
- Not matchedcites Zhu et al., 2023
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Moreover, attack success can be directly measured by the execution of the attacker tool, in contrast to the uncertain evaluations based on keyword mapping and LLM judgments in previous work.”
§ Adaptive Attacks Break Defenses Against Indirect Prompt Injection Attacks on LLM Agents > 7.1 LLM Agent Safety
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“Our adaptive attacks focus solely on the agent's first-step action.”
§ Adaptive Attacks Break Defenses Against Indirect Prompt Injection Attacks on LLM Agents > 10 Limitations
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“This occurs because all adversarial strings are trained to let the model generate the target output, which only has direct influence for the first step, limiting their impact on the later steps.”
§ Adaptive Attacks Break Defenses Against Indirect Prompt Injection Attacks on LLM Agents > 6.3 Breakdown of ASRs
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“This highlights the necessity of conducting adaptive attacks to evaluate the robustness of these defenses.”
§ Adaptive Attacks Break Defenses Against Indirect Prompt Injection Attacks on LLM Agents > 6.4 Cross Evaluation
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
In the paper
“Originally introduced for jailbreak attacks, GCG aims to train adversarial strings to let the LLM generate affirmative prefixes that induce malicious content following the malicious instruction.”
§ Adaptive Attacks Break Defenses Against Indirect Prompt Injection Attacks on LLM Agents > 4 Adaptive Attack Techniques
What the sources say
- Not checked yetcites Zou et al., 2023 source
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“This is due to that we use the same model as the agent backbone model in LLM-based detector, and Llama3-8B is strong and better safety aligned, showing better ability in detecting IPI attacks.”
§ Adaptive Attacks Break Defenses Against Indirect Prompt Injection Attacks on LLM Agents > 6.1 Detailed Results and Analysis
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“We do not account for the combination of defenses.”
§ Adaptive Attacks Break Defenses Against Indirect Prompt Injection Attacks on LLM Agents > 10 Limitations
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Therefore, adaptive attacks in this setting involve crafting adversarial examples in the external content to manipulate the LLM agent.”
§ Adaptive Attacks Break Defenses Against Indirect Prompt Injection Attacks on LLM Agents > Model -level Adversarial finetuning
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Among the eight defenses, perplexity filtering and paraphrasing are specifically designed to address adversarial strings.”
§ Adaptive Attacks Break Defenses Against Indirect Prompt Injection Attacks on LLM Agents > 6.1 Detailed Results and Analysis
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We hypothesize that this discrepancy arises primarily from the significantly longer contexts in AgentDojo, with an average token length of 3,823 and a maximum of 6,152, compared to InjecAgent's average token length of 1,033 and maximum of 1,711.”
§ Adaptive Attacks Break Defenses Against Indirect Prompt Injection Attacks on LLM Agents > B Experiments on the AgentDojo Benchmark
hedgeddirectn = 16- Asserted: fails — The authors may not put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The authors may not put it forward as true.
- The authors state this as an assumption: The attacker has white-box access to the agent model, defense models, and detailed prompts.
In the paper
“Unlike prompt injection attacks in LLMs (Liu et al., 2024b), targeting agents with tool usage poses extra challenges: (1) the attack must compel harmful actions rather than just generating a target output, and (2) the greater complexity of inputs and outputs complicates optimization.”
§ Adaptive Attacks Break Defenses Against Indirect Prompt Injection Attacks on LLM Agents > 7.1 LLM Agent Safety
What the sources say
- Not matchedcites Liu et al., 2024b
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Not matched
None of the sources cited for this claim have been checked yet.
In the paper
“New attacks that bypass existing defenses frequently arise, a phenomenon well-documented in computer vision (Athalye et al., 2018;Tramèr et al., 2020;Yu et al., 2021;Carlini and Wagner, 2017).”
§ Adaptive Attacks Break Defenses Against Indirect Prompt Injection Attacks on LLM Agents > 7.3 Adaptive Attacks
What the sources say
- Not matchedcites Athalye et al., 2018
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
- Not matchedcites Tramèr et al., 2020
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
- Not checked yetcites Carlini and Wagner, 2017 source
Checked before — its earlier verdict is held back until a new check runs.
boosted- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
- Not matched
The paper relies on this without support.
No studies have yet explored the effectiveness of IPI defenses against adaptive attacks.
“While defenses against IPI attacks have been proposed (Yi et al., 2023), no studies have yet explored their effectiveness against adaptive attacks, leaving their robustness in question.”
The authors state this as an assumption.
The attacker has knowledge of and white-box access to the agent and defenses.
“In the adaptive attack setting, we assume the attacker has knowledge of and white-box access to the agent and defenses (Athalye et al., 2018).”
The authors state this as an assumption.
The attacker has white-box access to the agent model, defense models, and detailed prompts.
“Our attacks assume the attacker has white-box access to the agent model, defense models, and detailed prompts.”
The paper relies on this without support.
This paper is the first to explore adaptive attacks specifically targeting LLM agent safety.
“To the best of our knowledge, this paper is the first to explore adaptive attacks specifically targeting LLM agent safety.”
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Each contradiction between two passages listed here was confirmed by an independent check.
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ Adaptive Attacks Break Defenses Against Indirect Prompt Injection Attacks on LLM Agents > 10 Limitations
“We train all adversarial strings to produce the output: "Thought: I will use the {Attacker tool name} tool to,"”
§ Adaptive Attacks Break Defenses Against Indirect Prompt Injection Attacks on LLM Agents > 5.1 Experiment Settings
“For Llama3-8B based agent, we let target = "{"name": "<T a >"".”
Citations
Cites
Training Language Models to Follow Instructions with Human Feedback
Ouyang, L., Wu, J., Jiang, X., Almeida, D., Wainwright, C., Mishkin, P., Zhang, C., Agarwal, S., Slama, K., Ray, A., et al. (2022) · Advances in Neural Information Processing Systems 35 · doi:10.52202/068431-2011 · Cited by 3,117
Judging LLM-as-a-Judge with MT-Bench and Chatbot Arena
Zheng, L., Chiang, W.-L., Sheng, Y., Zhuang, S., Wu, Z., Zhuang, Y., Lin, Z., Li, Z., Li, D., Xing, E. P., et al. (2023) · arXiv · doi:10.48550/arxiv.2306.05685 · Cited by 1,888
Adversarial Examples Are Not Easily Detected: Bypassing Ten Detection Methods
Carlini, N., & Wagner, D. (2017) · Proceedings of the 10th ACM Workshop on Artificial Intelligence and Security · doi:10.1145/3128572.3140444 · Cited by 966
Augmenting large language models with chemistry tools
M. Bran, A., Cox, S., Schilter, O., Baldassari, C., White, A. D., & Schwaller, P. (2024) · Nature Machine Intelligence · doi:10.1038/s42256-024-00832-8 · Cited by 794
Direct Preference Optimization: Your Language Model is Secretly a Reward Model
Rafailov, R., Sharma, A., Mitchell, E., Manning, C. D., Ermon, S., & Finn, C. (2023) · Advances in Neural Information Processing Systems 36 · doi:10.52202/075280-2338 · Cited by 686
Greshake, K., Abdelnabi, S., Mishra, S., Endres, C., Holz, T., & Fritz, M. (2023) · Proceedings of the 16th ACM Workshop on Artificial Intelligence and Security · doi:10.1145/3605764.3623985 · Cited by 667
AgentDojo: A Dynamic Environment to Evaluate Prompt Injection Attacks and Defenses for LLM Agents
Debenedetti, E., Zhang, J., Balunović, M., Beurer-Kellner, L., Fischer, M., & Tramèr, F. (2024) · arXiv · doi:10.48550/arxiv.2406.13352 · Cited by 616
Jailbreaking Leading Safety-Aligned LLMs with Simple Adaptive Attacks
Andriushchenko, M., Croce, F., & Flammarion, N. (2024) · arXiv · doi:10.48550/arxiv.2404.02151 · Cited by 396
Jailbroken: How Does LLM Safety Training Fail?
Wei, A., Haghtalab, N., & Steinhardt, J. (2023) · Advances in Neural Information Processing Systems 36 · doi:10.52202/075280-3508 · Cited by 280
AgentPoison: Red-teaming LLM Agents via Poisoning Memory or Knowledge Bases
Chen, Z., Xiang, Z., Xiao, C., Song, D., & Li, B. (2024) · arXiv · doi:10.48550/arxiv.2407.12784 · Cited by 246
Automatic and Universal Prompt Injection Attacks against Large Language ModelsPreprint
Liu, X., Yu, Z., Zhang, Y., Zhang, N., & Xiao, C. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2403.04957 · Cited by 217
Universal and Transferable Adversarial Attacks on Aligned Language Models
Zou, A., Wang, Z., Carlini, N., Nasr, M., Kolter, J. Z., & Fredrikson, M. (2023) · arXiv · doi:10.48550/arxiv.2307.15043 · Cited by 197
A Language Agent for Autonomous DrivingPreprint
Mao, J., Ye, J., Qian, Y., Pavone, M., & Wang, Y. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2311.10813 · Cited by 164
Defending Large Language Models Against Jailbreaking Attacks Through Goal Prioritization
Zhang, Z., Yang, J., Ke, P., Mi, F., Wang, H., & Huang, M. (2024) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2024.acl-long.481 · Cited by 156
Conversational Health Agents: A Personalized LLM-Powered Agent FrameworkPreprint
Abbasian, M., Azimi, I., Rahmani, A. M., et al. (2023) · arXiv.org · doi:10.48550/arxiv.2310.02374 · Cited by 150
InjecAgent: Benchmarking Indirect Prompt Injections in Tool-Integrated Large Language Model Agents
Zhan, Q., Liang, Z., Ying, Z., & Kang, D. (2024) · Findings of the Association for Computational Linguistics: ACL 2024 · doi:10.18653/v1/2024.findings-acl.624 · Cited by 147
Self-citationReceive, Reason, and React: Drive as You Say, With Large Language Models in Autonomous Vehicles
Cui, C., Ma, Y., Cao, X., Ye, W., & Wang, Z. (2024) · IEEE Intelligent Transportation Systems Magazine · doi:10.1109/mits.2024.3381793 · Cited by 137
Jatmo: Prompt Injection Defense by Task-Specific Finetuning
Piet, J., Al-Rashed, M., Sitawarin, C., Chen, S., Wei, Z., Sun, E., Alomair, B., & Wagner, D. (2024) · Lecture notes in computer science · doi:10.1007/978-3-031-70879-4_6 · Cited by 124
FinMem: A Performance-Enhanced LLM Trading Agent with Layered Memory and Character Design
Yu, Y., Li, H., Zhi, C., Jiang, Y., Li, Y., Zhang, D., Liu, R., Suchow, J. W., & Khashanah, K. (2024) · Proceedings of the AAAI Symposium Series · doi:10.1609/aaaiss.v3i1.31290 · Cited by 123
Towards Conversational Diagnostic AIPreprint
Tu, T., Palepu, A. K., Schaekermann, M., Saab, K. K., Freyberg, J., Tanno, R., Wang, A., Li, B., Amin, M., Tomašev, N., et al. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2401.05654 · Cited by 114
BadAgent: Inserting and Activating Backdoor Attacks in LLM Agents
Wang, Y., Xue, D., Zhang, S., & Qian, S. (2024) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2024.acl-long.530 · Cited by 111
Emergent autonomous scientific research capabilities of large language models
Boiko, D. A., MacKnight, R., & Gomes, G. (2023) · arXiv · doi:10.48550/arxiv.2304.05332 · Cited by 72
Caution for the Environment: Multimodal Agents are Susceptible to Environmental Distractions
Ma, X.-B., Wang, Y.-T., Yao, Y., Yuan, T.-X., Zhang, A., Zhang, Z., & Zhao, H. (2024) · Annual Meeting of the Association for Computational Linguistics · doi:10.48550/arxiv.2408.02544 · Cited by 69
The Emerged Security and Privacy of LLM Agent: A Survey with Case Studies
He, F., Zhu, T., Ye, D., Liu, B., Zhou, W., & Yu, P. S. (2024) · arXiv · doi:10.48550/arxiv.2407.19354 · Cited by 60
Prioritizing Safeguarding Over Autonomy: Risks of LLM Agents for SciencePreprint
Tang, X.-R., Jin, Q., Zhu, K.-L., et al. (2024) · arXiv.org · doi:10.48550/arxiv.2402.04247 · Cited by 56
Sleeper Agents: Training Deceptive LLMs that Persist Through Safety Training
Hubinger, E., Denison, C., Mu, J., Lambert, M., Tong, M., MacDiarmid, M., Lanham, T., Ziegler, D. M., Maxwell, T., Cheng, N., et al. (2024) · arXiv · doi:10.48550/arxiv.2401.05566 · Cited by 46
Agent Hospital: A Simulacrum of Hospital with Evolvable Medical Agents
Li, J., Lai, Y., Li, W., Ren, J., Zhang, M., Kang, X., Wang, S., Li, P., Zhang, Y.-Q., Ma, W., et al. (2024) · arXiv · doi:10.48550/arxiv.2405.02957 · Cited by 46
LAFEAT: Piercing Through Adversarial Defenses with Latent Features
Yu, Y., Gao, X., & Xu, C. (2021) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr46437.2021.00568 · Cited by 43
Jin, Y., Yang, R., Yi, Z., Shen, X., Peng, H., Liu, X., Qin, J., Li, J., Xie, J., Gao, P., et al. (2023) · arXiv · doi:10.48550/arxiv.2309.13193 · Cited by 29
Certifying LLM Safety against Adversarial Prompting
Kumar, A., Agarwal, C., Srinivas, S., Li, A. J., Feizi, S., & Lakkaraju, H. (2023) · arXiv · doi:10.48550/arxiv.2309.02705 · Cited by 28
Detecting Language Model Attacks with Perplexity
Alon, G., & Kamfonas, M. (2023) · arXiv · doi:10.48550/arxiv.2308.14132 · Cited by 27
Watch Out for Your Agents! Investigating Backdoor Threats to LLM-Based Agents
Yang, W., Bi, X., Lin, Y., Chen, S., Zhou, J., & Sun, X. (2024) · arXiv · doi:10.48550/arxiv.2402.11208 · Cited by 26
Li, Y., Yu, Y., Li, H., Chen, Z., & Khashanah, K. (2023) · arXiv · doi:10.48550/arxiv.2309.03736 · Cited by 12
Agent Security Bench (ASB): Formalizing and Benchmarking Attacks and Defenses in LLM-based Agents
Zhang, H., Huang, J., Mei, K., Yao, Y., Wang, Z., Zhan, C., Wang, H., & Zhang, Y. (2024) · arXiv · doi:10.48550/arxiv.2410.02644 · Cited by 9
Hu, C., Peters, A., & Kang, D. D. (2024) · Proceedings of the VLDB Endowment · doi:10.14778/3705829.3705843 · Cited by 9
Self-citationBenchmarking and Defending Against Indirect Prompt Injection Attacks on Large Language Models
Yi, J., Xie, Y., Zhu, B., Kiciman, E., Sun, G., Xie, X., & Wu, F. (2023) · arXiv · doi:10.48550/arxiv.2312.14197 · Cited by 8
Breaking Agents: Compromising Autonomous LLM Agents Through Malfunction Amplification
Zhang, B., Tan, Y., Shen, Y., Salem, A., Backes, M., Zannettou, S., & Zhang, Y. (2024) · arXiv · doi:10.48550/arxiv.2407.20859 · Cited by 5
R-Judge: Benchmarking Safety Risk Awareness for LLM Agents
Yuan, T., He, Z., Dong, L., Wang, Y., Zhao, R., Xia, T., Xu, L., Zhou, B., Li, F., Zhang, Z., et al. (2024) · arXiv · doi:10.48550/arxiv.2401.10019 · Cited by 2
AI Agents Under Threat: A Survey of Key Security Challenges and Future Pathways
Deng, Z., Guo, Y., Han, C., et al. (2024) · arXiv · doi:10.48550/arxiv.2406.02630
Baseline Defenses for Adversarial Attacks Against Aligned Language Models
Jain, N., Schwarzschild, A., Wen, Y., Somepalli, G., Kirchenbauer, J., Chiang, P.-Y., Goldblum, M., Saha, A., Geiping, J., & Goldstein, T. (2023) · arXiv · doi:10.48550/arxiv.2309.00614
Hu, C., Peters, A., & Kang, D. (2025) · arXiv · doi:10.48550/arxiv.2501.03892
Self-citation
Research works printed but not linked: 13
- Anish Athalye, Nicholas Carlini, and David A. Wag- ner. 2018. Obfuscated gradients give a false sense of security: Circumventing defenses to adversarial examples. In Proceedings of the 35th International Conference on Machine Learning, ICML 2018, Stock- holmsmässan, Stockholm, Sweden, July 10-15, 2018, volume 80 of Proceedings of Machine Learning Re- search, pages 274-283.
- PMLR.
- Xiangming Gu, Xiaosen Zheng, Tianyu Pang, Chao Du, Qian Liu, Ye Wang, Jing Jiang, and Min Lin. 2024. Agent smith: A single image can jailbreak one million multimodal LLM agents exponentially fast. In Forty-first International Conference on Machine Learning, ICML 2024, Vienna, Austria, July 21-27, 2024. OpenReview.net.
- Pengcheng He, Xiaodong Liu, Jianfeng Gao, and Weizhu Chen. 2021. Deberta: Decoding-enhanced bert with disentangled attention. In International Conference on Learning Representations.
- Edward J. Hu, Yelong Shen, Phillip Wallis, Zeyuan Allen-Zhu, Yuanzhi Li, Shean Wang, Lu Wang, and Weizhu Chen. 2022. Lora: Low-rank adaptation of large language models. In The Tenth International Conference on Learning Representations, ICLR 2022, Virtual Event, April 25-29, 2022. OpenReview.net.
- Xiaogeng Liu, Nan Xu, Muhao Chen, and Chaowei Xiao. 2024a. Autodan: Generating stealthy jailbreak prompts on aligned large language models. In The Twelfth International Conference on Learning Rep- resentations, ICLR 2024, Vienna, Austria, May 7-11, 2024. OpenReview.net.
- Mantas Mazeika, Long Phan, Xuwang Yin, Andy Zou, Zifan Wang, Norman Mu, Elham Sakhaee, Nathaniel Li, Steven Basart, Bo Li, David A. Forsyth, and Dan Hendrycks. 2024. Harmbench: A standardized eval- uation framework for automated red teaming and ro- bust refusal. In Forty-first International Conference on Machine Learning, ICML 2024, Vienna, Austria, July 21-27, 2024. OpenReview.net.
- Mansi Phute, Alec Helbling, Matthew Hull, Shengyun Peng, Sebastian Szyller, Cory Cornelius, and Duen Horng Chau. 2024. LLM self defense: By self examination, llms know they are being tricked. In The Second Tiny Papers Track at ICLR 2024, Tiny Papers @ ICLR 2024, Vienna, Austria, May 11, 2024.
- Yangjun Ruan, Honghua Dong, Andrew Wang, Sil- viu Pitis, Yongchao Zhou, Jimmy Ba, Yann Dubois, Chris J. Maddison, and Tatsunori Hashimoto. 2024. Identifying the risks of LM agents with an lm- emulated sandbox. In The Twelfth International Con- ference on Learning Representations, ICLR 2024, Vienna, Austria, May 7-11, 2024. OpenReview.net.
- Florian Tramèr, Nicholas Carlini, Wieland Brendel, and Aleksander Madry. 2020. On adaptive attacks to ad- versarial example defenses. In Advances in Neural Information Processing Systems 33: Annual Confer- ence on Neural Information Processing Systems 2020, NeurIPS 2020, December 6-12, 2020, virtual.
- Shunyu Yao, Jeffrey Zhao, Dian Yu, Nan Du, Izhak Shafran, Karthik R. Narasimhan, and Yuan Cao. 2023. React: Synergizing reasoning and acting in language models. In The Eleventh International Conference on Learning Representations, ICLR 2023, Kigali, Rwanda, May 1-5, 2023. OpenReview.net.
- Youliang Yuan, Wenxiang Jiao, Wenxuan Wang, Jen-tse Huang, Pinjia He, Shuming Shi, and Zhaopeng Tu. 2024b. GPT-4 is too smart to be safe: Stealthy chat with llms via cipher. In The Twelfth International Conference on Learning Representations, ICLR 2024, Vienna, Austria, May 7-11, 2024. OpenReview.net.
- Sicheng Zhu, Ruiyi Zhang, Bang An, Gang Wu, Joe Bar- row, Zichao Wang, Furong Huang, Ani Nenkova, and Tong Sun. 2023. Autodan: Interpretable gradient- based adversarial attacks on large language models. In First Conference on Language Modeling.
Cited by
Sorted by citations
Nasr, M., Carlini, N., Sitawarin, C., Schulhoff, S., Hayes, J., Ilie, M., Pluto, J., Song, S., Chaudhari, H., Shumailov, I., et al. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2510.09023 · Cited by 151
Prompt Flow Integrity to Prevent Privilege Escalation in LLM AgentsPreprint
Kim, J., Choi, W., & Lee, B. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2503.15547 · Cited by 99
Evaluation and Benchmarking of LLM Agents: A Survey
Mohammadi, M., Li, Y., Lo, J., & Yip, W. (2025) · Proceedings of the 31st ACM SIGKDD Conference on Knowledge Discovery and Data Mining V.2 · doi:10.1145/3711896.3736570 · Cited by 74
From Prompt Injections to Protocol Exploits: Threats in LLM-Powered AI Agents Workflows
Ferrag, M. A., Tihanyi, N., Hamouda, D., Maglaras, L., Lakas, A., & Debbah, M. (2026) · ICT Express · doi:10.1016/j.icte.2025.12.001 · Cited by 46
Agent Skills Enable a New Class of Realistic and Trivially Simple Prompt InjectionsPreprint
Schmotz, D., Abdelnabi, S., & Andriushchenko, M. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2510.26328 · Cited by 41
Metadata
- Authors
- Zhan, Q., Fang, R., Panchal, H. S., & Kang, D.
- Affiliations
- University of Illinois Urbana-Champaign (US)
- ORCID
- Kang, Daniel
- Venue
- Findings of the Association for Computational Linguistics: NAACL 2025
- Published
- 2025
- Pages
- 7101-7117
- OpenAlex
- W4411119880
- Cited by
- 124
- References
- 4
- Citations by year
- 2026: 103 · 2025: 21
- FWCI
- 44.53
- Type
- conference paper
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- cc-by
- Locations
- Findings of the Association for Computational Linguistics: NAACL (publishedVersion, cc-by)
- arXiv (Cornell University) (submittedVersion, cc-by)
- arXiv (Cornell University) (cc-by)
- Funders
- Open Philanthropy Project
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Adversarial Robustness in Machine Learning
- Physical Sciences › Computer Science › Hardware and Architecture › Security and Verification in Computing
- Physical Sciences › Computer Science › Information Systems › Web Application Security Vulnerabilities
- Keywords
- LLM agents, adaptive attacks, defense robustness, external tool integration, security vulnerabilities, attack evaluation
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
A language model drew the claims from the paper on 2026-11-10, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-11-10 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Cited sources are checked with a language model’s help (gpt-6-sol).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
