

The DOI matches its Crossref record; 32 of the 32 references it cites were found in a registry or an index; 3 of the 11 sources its claims cite were checked for support.
ATOM: AdapTive and OptiMized dynamic temporal knowledge graph construction using LLMs
Open accessAbstract
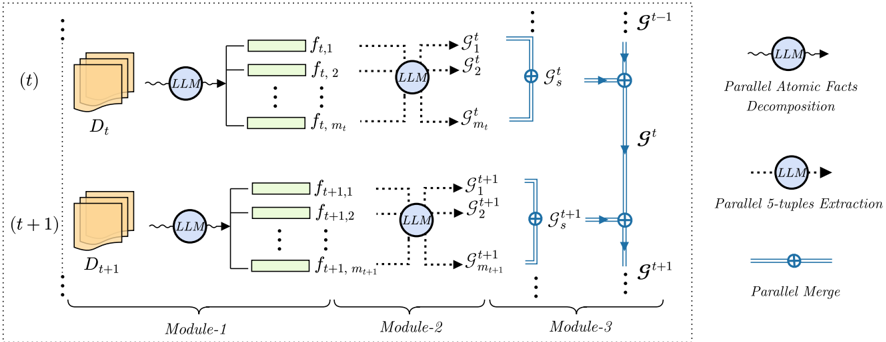
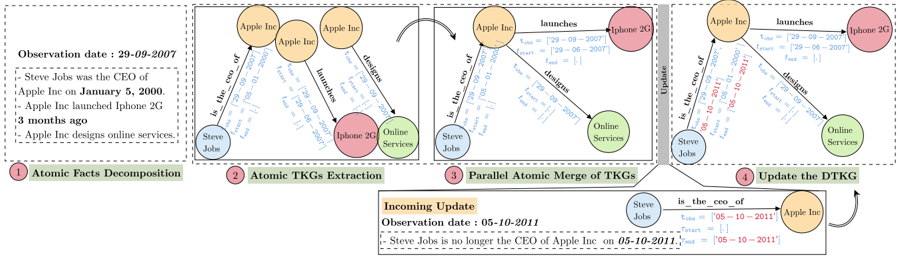
In today's rapidly expanding data landscape, knowledge extraction from unstructured text is vital for real-time analytics, temporal inference, and dynamic memory frameworks.However, traditional static knowledge graph (KG) construction often overlooks the dynamic and time-sensitive nature of real-world data, limiting adaptability to continuous changes.Moreover, recent zero-or few-shot approaches that avoid domain-specific fine-tuning or reliance on prebuilt ontologies often suffer from instability across multiple runs, as well as incomplete coverage of key facts.To address these challenges, we introduce ATOM 1 (AdapTive and OptiMized), a few-shot and scalable approach that builds and continuously updates Temporal Knowledge Graphs (TKGs) from unstructured texts.ATOM splits input documents into minimal, self-contained "atomic" facts, improving extraction exhaustivity and stability.Then, it constructs atomic TKGs from these facts, employing a dual-time modeling that distinguishes between when information is observed and when it is valid.The resulting atomic TKGs are subsequently merged in parallel.Empirical evaluations demonstrate that ATOM achieves ∼ 18% higher exhaustivity, ∼ 33% better stability, and over 90% latency reduction compared to baseline methods, demonstrating a strong scalability potential for dynamic TKG construction.
Overview
CoChat Summary
TL;DR
ATOM is a few-shot, parallel approach that decomposes unstructured text into atomic facts, extracts temporal 5-tuples into atomic TKGs, and merges them with dual-time modeling to build and update dynamic temporal knowledge graphs. On a COVID-19 NYT subset, it reports higher exhaustivity and stability and large latency reductions over baselines.
Key findings
- On 2020-COVID-NYT, atomic-fact extraction improved factual recall \(R_f\) by ∼31% (0.405 ± 0.150 for lead paragraphs vs. 0.720 ± 0.143 for atomic facts) and factual-temporal recall \(R_{f,t}\) by ∼18% (0.176 ± 0.123 vs. 0.354 ± 0.165); \(F_{1,f}\) rose from 0.504 to 0.638 and \(F_{1,f,t}\) from 0.220 to 0.313. Precision was lower for atomic facts: \(P_f\) 0.667 → 0.572 and \(P_{f,t}\) 0.292 → 0.281, described as a marginal ∼1% decrease in factual-temporal precision.
- Stability across reruns was higher for atomic facts (Run 2: 0.552 ± 0.124; Run 3: 0.534 ± 0.12) than for lead paragraphs (Run 2: 0.212 ± 0.181; Run 3: 0.218 ± 0.195), a gain of ∼33%.
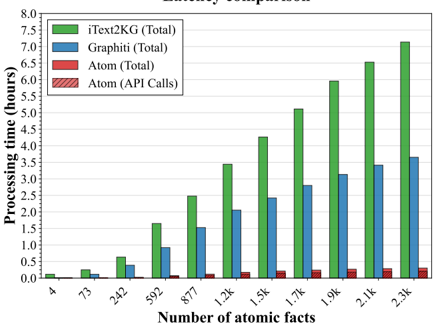
- ATOM reduced latency by 93.8% compared with Graphiti and 95.3% compared with iText2KG; its Module-3 merge accounted for only 13% of total latency.
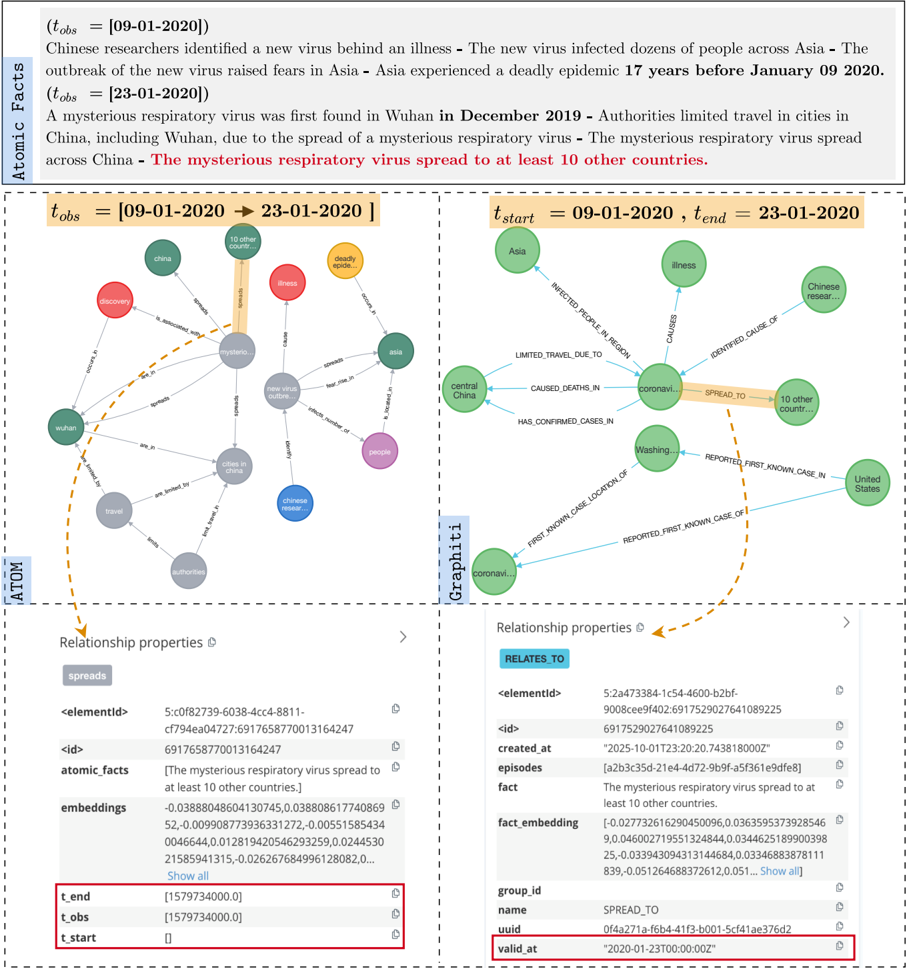
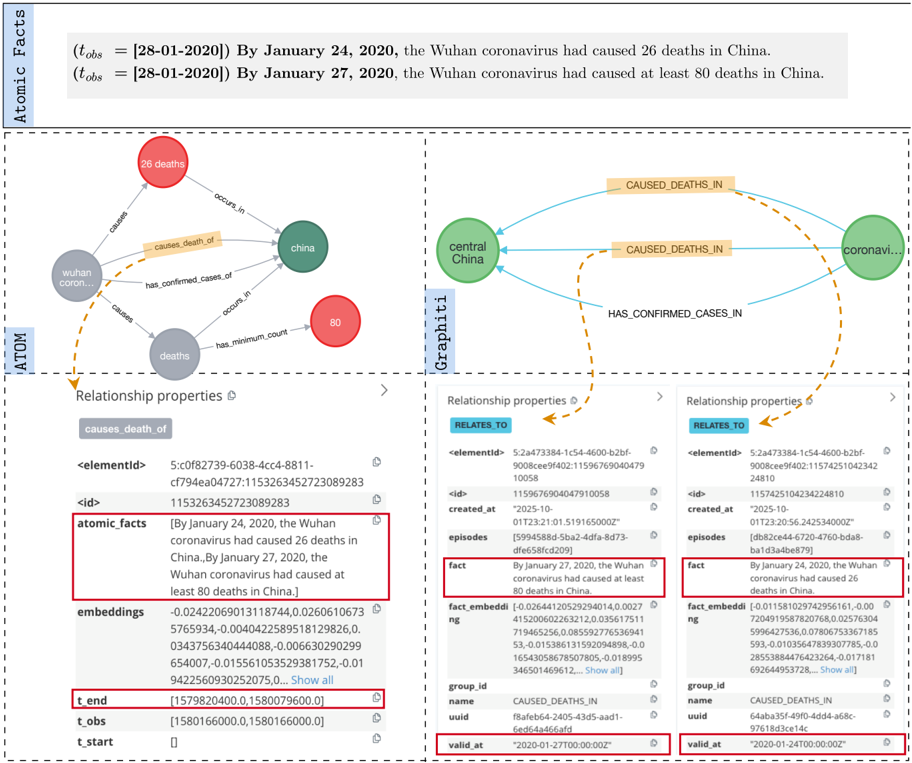
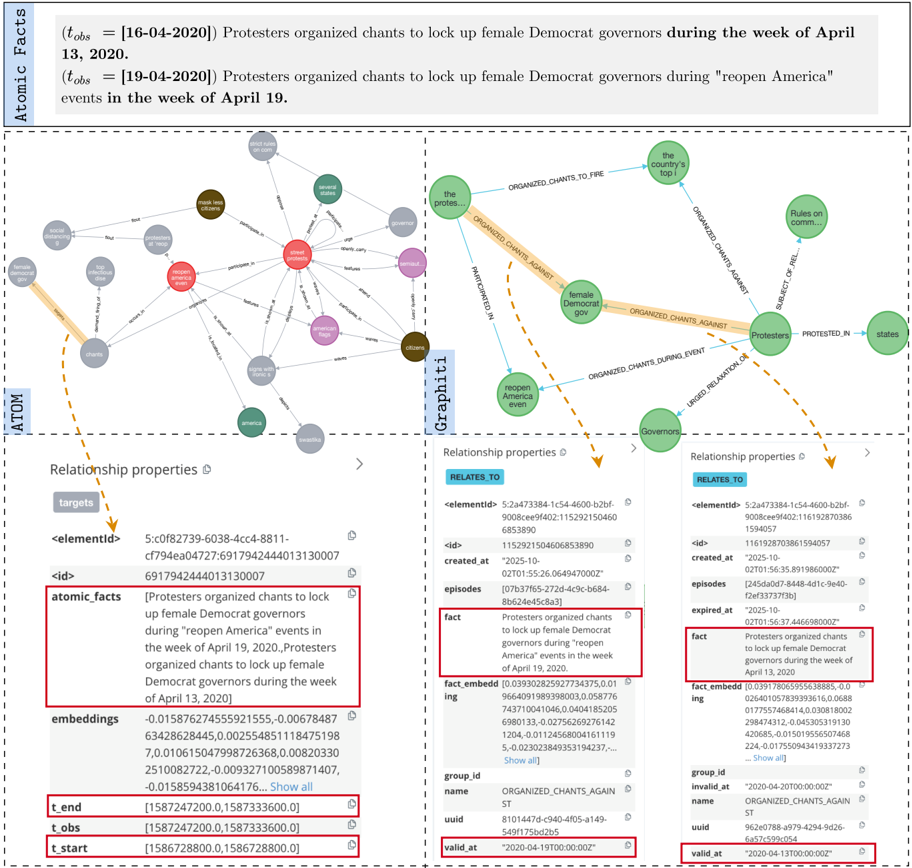
- On DTKG construction, ATOM achieved entity-resolution \(F_1\) 0.994 and relation-resolution \(F_1\) 1, versus Graphiti (0.959, 0.902) and iText2KG (0.977, 0.989); temporal resolution was compared qualitatively, with ATOM extending validity periods and avoiding Graphiti’s treatment of observation time as \(t_{start}\).
Methods
- ATOM decomposes documents into minimal, self-contained atomic facts, extracts 5-tuples in parallel to form atomic TKGs, then merges them via a parallel binary merge algorithm. Entity resolution uses exact name/label matches then cosine similarity with \(\theta_E = 0.8\); relation resolution uses \(\theta_R = 0.7\); temporal resolution merges observation and validity time sets. Dual-time modeling separates observation time from validity start/end, and merging avoids LLM calls.
- Evaluation used the 2020-COVID-NYT subset of the NYT News dynamic and temporal dataset: 1,076 articles, 274 grouped by publication date, average 206 ± 156 tokens per group, date range 2020-01-09 to 2020-12-30; 4,223 atomic facts (2,037 with validity time, 2,186 without), 7,210 5-tuples, 4,223 atomic TKGs, and ∼2 5-tuples per atomic TKG. The subset was enriched with human-verified atomic facts and 5-tuples; publication dates were used as observation dates.
- Models/settings: claude-sonnet-4-2025-01-31 for atomic fact decomposition, gpt-4.1-2025-04-14 for 5-tuple extraction, temperature 0, text-embedding-large-3 embeddings; baselines were Graphiti and iText2KG. Metrics included factual and factual-temporal recall, precision, and \(F_1\); stability via Jaccard similarity across runs; wall-clock latency; entity/relation resolution precision, recall, and \(F_1\); and qualitative temporal resolution.
Limitations
- Stated: atomic fact decomposition can propagate errors—the LLM may generate inferred facts not present in the source, increasing hallucination, and may fail to assign temporal information, lowering factual-temporal precision. Distance-metric merging can occasionally merge semantically distinct but highly similar named entities (e.g., gpt-5:model and gpt-3.5:model). ATOM also costs more than direct extraction due to the added decomposition step and increased output tokens.
- Evident from the text: evaluation is limited to one news subset (2020-COVID-NYT) and uses lead paragraphs rather than full articles; temporal resolution is evaluated qualitatively, with quantitative evaluation listed as future work; stability improves but remains imperfect (atomic-fact Jaccard ∼0.55); and the approach relies on proprietary LLM APIs and thresholds estimated from prior work or generated pairs.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
3 Valid · 4 Not valid · 8 Not checked · 53 Own results and interpretations
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“While DocRed (Yao et al., 2019) is a standard benchmark for relation extraction, it is largely unsuitable for temporal analysis owing to documented labeling inconsistencies (Tan et al., 2022).”
§ ATOM: AdapTive and OptiMized dynamic temporal knowledge graph construction using LLMs > 4.2 Datasets and baseline methods
What the sources say
- Partly supportedcites Tan et al., 2022 sourceExperimental — accuracy not yet measured
Our copy does document labelling problems in DocRED: Section 2.2 (Problem of Incomplete Annotation) attributes the incompleteness to the recommend-revise construction plus 'logical inconsistency' in inverse relations, Section 3.2 quantifies it ('approximately 64.6% of all triples are missing in the original DocRED dataset'), Appendix E names the two types of logical inconsistency, and Appendix B documents coreferential annotation errors. However, no passage in our copy states or implies that DocRED is unsuitable for TEMPORAL analysis specifically; the only temporal-flavoured material (date of birth/death examples in Appendix D, 'slippery slope' error type) concerns model prediction errors and errors in Huang et al. (2022)'s From Scratch set, not DocRED's usability for temporal work. So the 'documented labeling inconsistencies' half is supported and the 'largely unsuitable for temporal analysis' conclusion is the citing authors' own inference, not this source's claim. (LLM, conf=0.72)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Partly supported
Every source the paper cites for this claim was checked and supports it.
In the paper
“static KGs, rarely or never updated, struggle to remain relevant and accurate (Jiang et al., 2023).”
§ ATOM: AdapTive and OptiMized dynamic temporal knowledge graph construction using LLMs > 1 Introduction
What the sources say
- Supportedcites Jiang et al., 2023 source
The Introduction (Sec. 1) states that 'static KGs (SKGs) where triples are never updated or updated very infrequently, are limited due to the timeliness of the knowledge they hold,' which matches the claim's 'rarely or never updated' and its currency/relevance shortfall. Sec. 2.1 reinforces it: SKG examples such as Kinship, HowNet, WordNet and Freebase 'are not updated after creation'/'have no longer been updated for a long time' and 'are not suitable for applications that require up-to-date information,' while Sec. 2.2 presents DKG updates as 'guaranteeing the timeliness of knowledge' and notes a DKG no longer updated 'degenerates into an SKG.' The source expresses the shortfall as lost timeliness/currency rather than using the word 'accuracy', but that is the same content — stale facts about a changing world — so the paraphrase is supported. (LLM, conf=0.85)
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Supported
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“This decomposition addresses a fundamental limitation of LLMs: the “forgetting effect” where models prioritize salient information in longer contexts while omitting key relationships, leading to incomplete knowledge extraction (Liu et al., 2024).”
§ ATOM: AdapTive and OptiMized dynamic temporal knowledge graph construction using LLMs > 3.2.1 Module-1: Atomic fact decomposition
What the sources say
- Partly supportedcites Liu et al., 2024 sourceExperimental — accuracy not yet measured
Our copy supports the general point that current LLMs use long contexts poorly: the Abstract and §1/§2.3 report a U-shaped performance curve with primacy and recency biases, degraded accuracy when relevant information sits in the middle, and models that 'cannot effectively reason over their entire context window' (also §5's reader saturation before retriever recall). But the specific content attributed here is absent: the paper never calls this a 'forgetting effect' (its own framing, §6.3, is the psychological serial-position effect), never says models 'prioritize salient information' — its manipulated variable is position, not salience — and it studies single-item retrieval (one answer document, one key-value pair), not the omission of 'key relationships' or 'incomplete knowledge extraction', terms that appear nowhere in our copy. So the long-context weakness is supported while the mechanism and the knowledge-extraction framing are not. (LLM, conf=0.72)
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Partly supported
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Rerunning the same prompt multiple times leads to variations in output.”
§ ATOM: AdapTive and OptiMized dynamic temporal knowledge graph construction using LLMs > 4.4 TKG stability
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
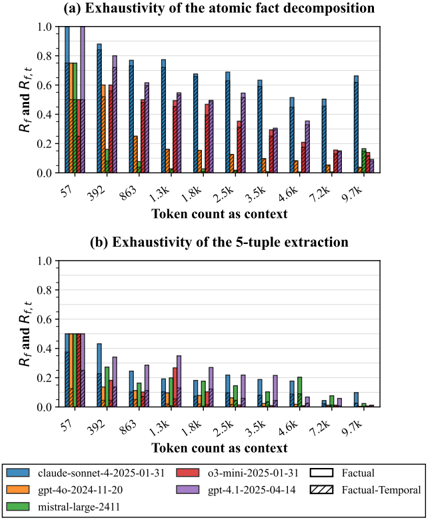
“we empirically determine the optimal chunk size at < 400 tokens to keep the exhaustivity > 0.8.”
§ ATOM: AdapTive and OptiMized dynamic temporal knowledge graph construction using LLMs > 4.3 Exhaustivity deterioration in longer contexts
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
21 more claims
Create a free account to see all 68 claims and to verify the 7 references still open.
- Probably not a substantial claim. 21
- It may state two separate claims as one. 29
Citations
Cites
Lost in the Middle: How Language Models Use Long Contexts
Liu, N. F., Lin, K., Hewitt, J., Paranjape, A., Bevilacqua, M., Petroni, F., & Liang, P. (2024) · Transactions of the Association for Computational Linguistics · doi:10.1162/tacl_a_00638 · Cited by 1,612
The rise and potential of large language model based agents: a survey
Xi, Z., Chen, W., Guo, X., He, W., Ding, Y., Hong, B., Zhang, M., Wang, J., Jin, S., Zhou, E., et al. (2025) · Science China Information Sciences · doi:10.1007/s11432-024-4222-0 · Cited by 970
DocRED: A Large-Scale Document-Level Relation Extraction Dataset
Yao, Y., Ye, D., Li, P., Han, X., Lin, Y., Liu, Z., Liu, Z., Huang, L., Zhou, J., & Sun, M. (2019) · Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics · doi:10.18653/v1/p19-1074 · Cited by 550
Large Language Models on Graphs: A Comprehensive Survey
Jin, B., Liu, G., Han, C., Jiang, M., Ji, H., & Han, J. (2024) · IEEE Transactions on Knowledge and Data Engineering · doi:10.1109/tkde.2024.3469578 · Cited by 428
A Comprehensive Survey on Automatic Knowledge Graph Construction
Zhong, L., Wu, J., Li, Q., Peng, H., & Wu, X. (2024) · ACM Computing Surveys · doi:10.1145/3618295 · Cited by 382
Non-Determinism of "Deterministic" LLM SettingsPreprint
Atil, B., Aykent, S., Chittams, A., Fu, L., Passonneau, R. J., Radcliffe, E., Rajagopal, G. R., Sloan, A., Tudrej, T., Ture, F., et al. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2408.04667 · Cited by 367
Named Entity Extraction for Knowledge Graphs: A Literature Overview
Al-Moslmi, T., Gallofre Ocana, M., L. Opdahl, A., & Veres, C. (2020) · IEEE Access · doi:10.1109/access.2020.2973928 · Cited by 229
LLM-TIKG: Threat intelligence knowledge graph construction utilizing large language model
Hu, Y., Zou, F., Han, J., Sun, X., & Wang, Y. (2024) · Computers & Security · doi:10.1016/j.cose.2024.103999 · Cited by 217
Revisiting DocRED - Addressing the False Negative Problem in Relation Extraction
Tan, Q., Xu, L., Bing, L., Ng, H. T., & Aljunied, S. M. (2022) · Proceedings of the 2022 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/2022.emnlp-main.580 · Cited by 207
From local to global: a graph rag approach to query-focused summarization
Edge, D., Trinh, H., Cheng, N., Bradley, J., Chao, A., Mody, A., Truitt, S., Metropolitansky, D., Ness, R. O., & Larson, J. (2024) · arXiv · doi:10.48550/arxiv.2404.16130 · Cited by 159
AttacKG+: Boosting attack graph construction with Large Language Models
Zhang, Y., Du, T., Ma, Y., Wang, X., Xie, Y., Yang, G., Lu, Y., & Chang, E. (2024) · Computers & Security · doi:10.1016/j.cose.2024.104220 · Cited by 110
Dense X Retrieval: What Retrieval Granularity Should We Use?
Chen, T., Wang, H., Chen, S., Yu, W., Ma, K., Zhao, X., Zhang, H., & Yu, D. (2024) · Proceedings of the 2024 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/2024.emnlp-main.845 · Cited by 74
A Survey on Temporal Knowledge Graph: Representation Learning and Applications
Cai, L., Mao, X., Zhou, Y., Long, Z., Wu, C., & Lan, M. (2024) · arXiv · doi:10.48550/arxiv.2403.04782 · Cited by 68
LLM-empowered knowledge graph construction: A surveyPreprint
Bian, H. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2510.20345 · Cited by 68
iText2KG: Incremental Knowledge Graphs Construction Using Large Language Models
Lairgi, Y., Moncla, L., Cazabet, R., Benabdeslem, K., & Cl'eau, P. (2024) · WISE · doi:10.48550/arxiv.2409.03284 · Cited by 44
Self-citationOn the Evolution of Knowledge Graphs: A Survey and Perspective
Jiang, X., Xu, C., Shen, Y., Sun, X., Tang, L., Wang, S., Chen, Z., Wang, Y., & Guo, J. (2023) · arXiv · doi:10.48550/arxiv.2310.04835 · Cited by 42
Question-Based Retrieval using Atomic Units for Enterprise RAG
Raina, V., & Gales, M. (2024) · Fact Extraction and VERification Workshop (FEVER) · doi:10.18653/v1/2024.fever-1.25 · Cited by 41
iText2KG: Incremental Knowledge Graphs Construction Using Large Language Models
Lairgi, Y., Moncla, L., Cazabet, R., Benabdeslem, K., & Cléau, P. (2025) · Lecture Notes in Computer Science · doi:10.1007/978-981-96-0573-6_16 · Cited by 31
Self-citationOccam’s Razor for Big Data? On Detecting Quality in Large Unstructured Datasets
Dresp, B., Ekseth, O. K., Fesl, J., Gohshi, S., Kurz, M., & Sehring, H.-W. (2019) · Applied Sciences · doi:10.3390/app9153065 · Cited by 27
Potential for the use of large unstructured data resources by public innovation support institutions
Cetera, W., Gogołek, W., Żołnierski, A., & Jaruga, D. (2022) · Journal Of Big Data · doi:10.1186/s40537-022-00610-6 · Cited by 21
Retrieval Augmented Generation for Dynamic Graph Modeling
Wu, Y., Liao, L., & Fang, Y. (2025) · International ACM SIGIR Conference on Research and Development in Information Retrieval (SIGIR) · doi:10.1145/3726302.3729958 · Cited by 13
Scalable and Domain-General Abstractive Proposition Segmentation
Hosseini, M. J., Gao, Y., Baumgärtner, T., Fabrikant, A., & Amplayo, R. K. (2024) · Findings of the Association for Computational Linguistics: EMNLP (Findings of EMNLP) · doi:10.18653/v1/2024.findings-emnlp.517 · Cited by 11
Zep: A Temporal Knowledge Graph Architecture for Agent Memory
Rasmussen, P., Paliychuk, P., Beauvais, T., Ryan, J., & Chalef, D. (2025) · arXiv · doi:10.48550/arxiv.2501.13956 · Cited by 9
Kabal, O., Harzallah, M., Guillet, F., & Ichise, R. (2024) · Procedia Computer Science · doi:10.1016/j.procs.2024.09.436 · Cited by 9
AriGraph: Learning Knowledge Graph World Models with Episodic Memory for LLM Agents
Anokhin, P., Semenov, N., Sorokin, A., Evseev, D., Kravchenko, A., Burtsev, M., & Burnaev, E. (2024) · arXiv · doi:10.48550/arxiv.2407.04363 · Cited by 8
Towards Probabilistic Bitemporal Knowledge Graphs
Chekol, M. W., & Stuckenschmidt, H. (2018) · International World Wide Web Conference (WWW) · doi:10.1145/3184558.3191637 · Cited by 6
A Temporal Knowledge Graph Generation Dataset Supervised Distantly by Large Language Models
Zhu, J., Fu, Y., Zhou, J., & Chen, D. (2025) · Scientific Data · doi:10.1038/s41597-025-05062-0 · Cited by 5
Bi-VAKs: Bi-Temporal Versioning Approach for Knowledge Graphs
Meijer, L. (2022) · Research Repository (Delft University of Technology) · Cited by 4
Scientific Discovery by Machine Intelligence: A New Avenue for Drug ResearchPreprint
Trugenberger, C. A. (2015) · arXiv (Cornell University) · doi:10.48550/arxiv.1506.07116 · Cited by 2
Iterative Zero-Shot LLM Prompting for Knowledge Graph Construction
Carta, S., Giuliani, A., Piano, L., Podda, A. S., Pompianu, L., & Tiddia, S. G. (2023) · arXiv · doi:10.48550/arxiv.2307.01128
Retrieval Augmented Generation for Dynamic Graph Modeling
Wu, Y., Liao, L., & Fang, Y. (2024) · arXiv · doi:10.48550/arxiv.2408.14523
AttacKG+:Boosting Attack Knowledge Graph Construction with Large Language Models
Zhang, Y., Du, T., Ma, Y., Wang, X., Xie, Y., Yang, G., Lu, Y., & Chang, E.-C. (2024) · arXiv · doi:10.48550/arxiv.2405.04753
Cited by
TACTIC-KG: Toward Small Agent Teams for Cyber Threat Intelligence Knowledge Graph Construction
Bouchiha, M. A., & Blanc, G. (2026) · Lecture notes in computer science · doi:10.1007/978-3-032-38692-2_24 · Cited by 3
Kato, M. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2606.20041 · Cited by 1
Hammoud, M. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2607.21327 · Cited by 1
C-Unseen: Weak Signal Detection in Dynamic Temporal Knowledge Graphs via LLM ReasoningPreprint
Lairgi, Y., Moncla, L., Benabdeslem, K., Cazabet, R., & Cléau, P. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2608.26870
Self-citationTemporal-Aware Person-Job Matching via LLM-Extracted Knowledge Graphs and Graph Convolution
Liu, M., Gong, H., Lin, X., Song, X., Zhu, R., & Pan, L. (2026) · International Conference on Big Data and Information Analytics (BigDIA) · doi:10.1109/bigdia71496.2026.11684658
Metadata
- Authors
- Lairgi, Y., Moncla, L., Benabdeslem, K., Cazabet, R., & Cléau, P.
- Affiliations
- Lyon 1 Université (FR)
- Venue
- Findings of the Association for Computational Linguistics: EACL 2026
- Published
- 2026
- Pages
- 950-966
- OpenAlex
- W7140084193
- Cited by
- 7
- References
- 29
- Citations by year
- 2026: 7
- FWCI
- 6.53
- Type
- conference paper
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- cc-by
- Locations
- Findings of the Association for Computational Linguistics: EACL (publishedVersion, cc-by)
- HAL (submittedVersion)
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Topic Modeling
- Physical Sciences › Computer Science › Artificial Intelligence › Advanced Graph Neural Networks
- Physical Sciences › Computer Science › Artificial Intelligence › Semantic Web and Ontologies
- Keywords
- temporal knowledge graphs, knowledge graph construction, few-shot learning, large language models, atomic facts, knowledge graph updating
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
The claim verdicts this report counts are experimental: their accuracy is not yet measured.
A language model drew the claims from the paper on 2026-11-18, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-11-18 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Cited sources are checked with a language model’s help (qwen3.8-omni-flash).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
