

Rationalizing Neural Predictions
Open accessThe DOI matches its Crossref record; 35 of the 35 references it cites were found in a registry or an index.
Abstract
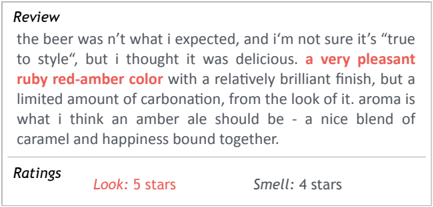
Prediction without justification has limited applicability.As a remedy, we learn to extract pieces of input text as justifications -rationales -that are tailored to be short and coherent, yet sufficient for making the same prediction.Our approach combines two modular components, generator and encoder, which are trained to operate well together.The generator specifies a distribution over text fragments as candidate rationales and these are passed through the encoder for prediction.Rationales are never given during training.Instead, the model is regularized by desiderata for rationales.We evaluate the approach on multi-aspect sentiment analysis against manually annotated test cases.Our approach outperforms attention-based baseline by a significant margin.We also successfully illustrate the method on the question retrieval task. 1
Overview
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Integrity signals
Registry
Cites
Statistics
Figures


Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The check wasn’t confident either way, so it gives no verdict — never disputed.
In the citing paper
“A lot of work has also been done on argumentation and dialog games [6, 11, 51, 53] but the focus in these areas is generally the logical structure of the framework to express and to relate arguments or the protocol to exchange arguments.”
From Beyond explainability: justifiability and contestability of algorithmic decision systems (2022) · cites this paper as [53]
Experimental — accuracy not yet measuredIn the citing paper
“This model can achieve competitive accuracy while having built-in interpretability because the prediction is made exclusively based on rationales.”
From Human-AI Collaboration via Conditional Delegation: A Case Study of Content Moderation (2022) · cites this paper as [52]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
"Why Should I Trust You?": Explaining the Predictions of Any Classifier
Ribeiro, M. T., Singh, S., & Guestrin, C. (2016) · Proceedings of the 22nd ACM SIGKDD International Conference on Knowledge Discovery and Data Mining · doi:10.1145/2939672.2939778 · Cited by 17,555
Neural Machine Translation by Jointly Learning to Align and Translate
Bahdanau, D., Cho, K., & Bengio, Y. (2014) · arXiv · doi:10.48550/arxiv.1409.0473 · Cited by 16,213 · cited 2×
“Attention based models offer another lens to the inner workings of neural models (Bahdanau et al., 2015; Cheng et al., 2016; Martins and Astudillo, 2016; Chen et al., 2015; Xu and Saenko, 2015; Yang et al., 2015).”
BackgroundConvolutional Neural Networks for Sentence Classification
Kim, Y. (2014) · Proceedings of the 2014 Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.3115/v1/d14-1181 · Cited by 14,831
Show, Attend and Tell: Neural Image Caption Generation with Visual Attention
Xu, K., Ba, J., Kiros, R., Cho, K., Courville, A., Salakhutdinov, R., Zemel, R., & Bengio, Y. (2015) · arXiv · doi:10.48550/arxiv.1502.03044 · Cited by 8,248
Bag of Tricks for Efficient Text Classification
Joulin, A., Grave, E., Bojanowski, P., & Mikolov, T. (2017) · Proceedings of the 15th Conference of the European Chapter of the Association for Computational Linguistics: Volume 2, Short Papers · doi:10.18653/v1/e17-2068 · Cited by 4,545
Bag of Tricks for Efficient Text Classification
Joulin, A., Grave, E., Bojanowski, P., & Mikolov, T. (2016) · arXiv · doi:10.48550/arxiv.1607.01759 · Cited by 4,542
A Convolutional Neural Network for Modelling Sentences
Kalchbrenner, N., Grefenstette, E., & Blunsom, P. (2014) · Proceedings of the 52nd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) · doi:10.3115/v1/p14-1062 · Cited by 3,601 · cited 1×
“For instance, we could use a convolutional network (Kim, 2014; Kalchbrenner et al., 2014), deep averaging network (Iyyer et al.”
MethodA Neural Attention Model for Abstractive Sentence Summarization
Rush, A. M., Chopra, S., & Weston, J. (2015) · Proceedings of the 2015 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/d15-1044 · Cited by 2,656
Recurrent Models of Visual Attention
Mnih, V., Heess, N., Graves, A., & Kavukcuoglu, K. (2014) · arXiv (Cornell University) · doi:10.48550/arxiv.1406.6247 · Cited by 2,568 · cited 1×
“space of possible rationales in terms of their interaction with the encoder. We could also apply variance reduction techniques to increase stability of stochastic training (cf. (Weaver and Tao, 2001; Mnih et al., 2014; Ba et al., 2015; Xu et al., 2015)). 7 Acknowledgments We thank Prof. Julian McAuley for sharing the…”
MethodTeaching Machines to Read and Comprehend
Hermann, K. M., Kočiský, T., Grefenstette, E., Espeholt, L., Kay, W., Suleyman, M., & Blunsom, P. (2015) · arXiv (Cornell University) · doi:10.48550/arxiv.1506.03340 · Cited by 2,521
Research works printed but not linked: 6
- [6]6. Cicero dos Santos, Luciano Barbosa, Dasha Bogdanova, and Bianca Zadrozny. 2015. Learning hybrid rep- resentations to retrieve semantically equivalent ques- tions. In Proceedings of the 53rd Annual Meeting of the Association for Computational Linguistics and the 7th International Joint Conference on Natural Lan- guage Processing (Volume 2: Short Papers), pages 694-699, Beijing, China, July. Association for Com- putational Linguistics.
- [7]7. Manaal Faruqui, Jesse Dodge, Sujay K. Jauhar, Chris Dyer, Eduard Hovy, and Noah A. Smith. 2015a. Retrofitting word vectors to semantic lexicons. In Pro- ceedings of NAACL.
- [9]9. Aurélie Herbelot and Eva Maria Vecchi. 2015. Build- ing a shared world: mapping distributional to model- theoretic semantic spaces. In Proceedings of the 2015 Conference on Empirical Methods in Natural Lan- guage Processing. Association for Computational Lin- guistics.
- [12]12. Mohit Iyyer, Varun Manjunatha, Jordan Boyd-Graber, and Hal Daumé III. 2015. Deep unordered compo- sition rivals syntactic methods for text classification. In Proceedings of the 53rd Annual Meeting of the As- sociation for Computational Linguistics and the 7th International Joint Conference on Natural Language Processing (Volume 1: Long Papers).
- [27]27. Tim Rocktäschel, Edward Grefenstette, Karl Moritz Her- mann, Tomáš Kočiskỳ, and Phil Blunsom. 2016. Rea- soning about entailment with neural attention. In In- ternational Conference on Learning Representations.
- [29]29. Sebastian Thrun. 1995. Extracting rules from artifi- cial neural networks with distributed representations. In Advances in neural information processing systems (NIPS).
Cited by
Items 801–900 of 900
Detecting Fake or Deceptive Opinions
Liu, B. (2020) · Cambridge University Press eBooks · doi:10.1017/9781108639286.013
Liu, B. (2020) · Cambridge University Press eBooks · doi:10.1017/9781108639286.007 · Cited by 1
Robot Consciousness: Physics and Metaphysics Here and AbroadPreprint
Ripley, S. B. (2020) · doi:10.36227/techrxiv.12902687
Robot ConsciousnessPreprint
Ripley, S. B. (2020) · PsyArXiv (OSF Preprints) · doi:10.31234/osf.io/q7jrb
Liu, B. (2020) · Cambridge University Press eBooks · doi:10.1017/9781108639286.018
Exploiting auto-encoders for explaining black-box classifiers
Guidotti, R. (2022) · Intelligenza Artificiale · doi:10.3233/ia-220139
“We plan to refine its neighborhood generation exploiting the approaches presented in [36, 39].”
Monte Carlo Tree Search for Interpreting Stress in Natural Language
Swanson, K., Hsu, J., & Süzgün, M. (2022) · Workshop on Language Technology for Equality, Diversity, Inclusion (LT-EDI) · doi:10.18653/v1/2022.ltedi-1.12
Measuring the misinformation ecosystem: audiences, platforms, and storytellers
Jiang, S. (2021) · Digital Repository Service (Northeastern University) · doi:10.17760/d20412317 · Cited by 2
Linear Order in Language: an Error-Driven Learning Account
Hoppe, D. B. (2022) · University of Groningen research database (University of Groningen / Centre for Information Technology) · doi:10.33612/diss.238906691 · Cited by 6
Self-Supervised Text Style Transfer with Rationale Prediction and Pretrained Transformers
Sinclair, N., & Buys, J. (2022) · Communications in computer and information science · doi:10.1007/978-3-031-22321-1_20
The model thinks what?! Interpreting deep NLP models with rationales and influence
Jain, S. (2022) · Digital Repository Service (Northeastern University) · doi:10.17760/d20467212
A novel explainable structure for text classification
Chen, L., Li, Y., Zhang, H., & Shunping, W. (2022) · European Conference on Natural Language Processing and Information Retrieval (ECNLPIR) · doi:10.1109/ecnlpir57021.2022.00028 · Cited by 1
“Others are methods of models jointly trained, like [12].”
MethodDistributed Model Interpretation for Vertical Federated Learning with Feature Discrepancy
Xing, R., Zheng, Z., Li, Q., Wu, F., & Chen, G. (2023) · International Workshop on Quality of Service · doi:10.1109/iwqos57198.2023.10188708 · Cited by 1
“Current model interpretation methods are basically centralized [8]–[17], which would raise new issues if we regard each client’s local model as an isolated model to explain in VFL.”
BackgroundMethodExplanation Graph Generation via Generative Pre-training over Synthetic Graphs
Cui, H., Li, S., Zhang, Y., & Shi, Q. (2023) · Findings of the Association for Computational Linguistics: ACL (Findings of ACL) · doi:10.18653/v1/2023.findings-acl.629 · Cited by 2
Easy to Decide, Hard to Agree: Reducing Disagreements Between Saliency Methods
Jukić, J., Tutek, M., & Šnajder, J. (2023) · Findings of the Association for Computational Linguistics: ACL (Findings of ACL) · doi:10.18653/v1/2023.findings-acl.582 · Cited by 2
R2F: A General Retrieval, Reading and Fusion Framework for Document-level Natural Language Inference
Wang, H., Cao, Y., Li, Y., Huang, Z., Wang, K., & Shao, J. (2022) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2022.emnlp-main.204
Explanations for Graph Neural Networks via Layer Analysis
Li, Q., Kang, X., Li, W., & Liang, D. (2023) · Atlantis Highlights in Intelligent Systems/Atlantis highlights in intelligent systems · doi:10.2991/978-94-6463-222-4_43
Unsupervised Text Style Transfer with Deep Generative ModelsPreprint
Jiang, Z., Zhang, Y., Ju, Y., & Liu, K. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2308.16584
“…the specialization above, the total loss becomes: : Learning to infill the content prototype is almost identical to the definition of the rationale (Lei et al., 2016; Bastings et al., 2019; De Cao et al., 2020) except for the contiguity loss, where the first and second terms refer to fidelity and…”
BackgroundFrom Intermediate Representations to Explanations: Exploring Hierarchical Structures in NLP
Babiker, H. K. B., Kim, M., & Goebel, R. G. (2023) · Frontiers in artificial intelligence and applications · doi:10.3233/faia230266 · Cited by 4
Deep Learning Architecture for Processing Cyber-Physical Data in the Electric Grid.
Calzada, D., Hossain‐McKenzie, S., & Mao, Z. (2022) · doi:10.2172/2001933
Dialogue Generation with Skeleton Extraction and Causal Intervention
Wan, Z. (2023) · International Conference on Pattern Recognition and Artificial Intelligence (PRAI) · doi:10.1109/prai59366.2023.10332043
“In the text classification task, [18] trains the model to select short and continuous text fragments from long texts as the rationale for predicting.”
MethodInterpretability of Deep Neural Models
Sikdar, S., & Bhattacharya, P. (2023) · Studies in computational intelligence · doi:10.1007/978-981-99-7184-8_8
Towards Explainability in Automated Medical Code Prediction from Clinical Records
Kanimozhi, U., Francis, S., Sun, W., & Moens, M. (2024) · Lecture notes in networks and systems · doi:10.1007/978-3-031-47718-8_40 · Cited by 1
Expliquer et justifier les systèmes de décisions algorithmiques
Henin, C. (2021) · theses.fr (ABES) · doi:10.70675/efcb0438z603ez41bbza904zfff3ef397cbb · Cited by 6
Diagnostics-Guided Explanation Generation
Atanasova, P. (2024) · Springer eBooks · doi:10.1007/978-3-031-51518-7_8
Explainable Evidence-Based Veracity Assessment of Textual Claim
Shankar, A., Kulathuramaiyer, N., Abdullah, J., & Pakkirisamy, M. (2024) · Journal of Computer Science · doi:10.3844/jcssp.2024.1009.1019
“Lastly, the adjustment of our model's hard mask attention threshold is driven by the reinforce optimization method, in line with Lei et al .”
MethodGuzman, E. M., Schlegel, V., & Batista-Navarro, R. (2024) · Workshop on NLP for Positive Impact (NLP4PI) · doi:10.18653/v1/2024.nlp4pi-1.8
Fast Evidence Extraction for Grounded Language Model Outputs
Mani, P., Liang, D., & Lipton, Z. C. (2024) · Fact Extraction and VERification Workshop (FEVER) · doi:10.18653/v1/2024.fever-1.24 · Cited by 1
“…on top of a source document (e.g. summarization, dialogue and translation) (Touvron et al., 2023; Bubeck et al., 2023; Widyassari et al., 2022; Rafailov et al., 2023; Liang et al., 2023) are well suited for LLMs (Krishna et al., 2021; Lehman et al., 2019; Lei et al., 2016; Asan et al., 2020).”
BackgroundTowards Explainable Medical Machine Reading Comprehension With Rationale Generation
Li, D., He, S., Hu, B., & Chen, Q. (2025) · IEEE Transactions on Audio Speech and Language Processing · doi:10.1109/taslpro.2025.3555105 · Cited by 1
“…the label first, then generating the explanation with the label and original inputs [21]; 3) generating explanations first and then using the generated explanations to predict the labels [23], [30]; 4) predicting the label and generating the corresponding explanation jointly [20], [24], [67], [68].”
Honjo, Y., Zhang, J., & Zhang, W. (2024) · IEEE/WIC/ACM International Conference on Web Intelligence and Intelligent Agent Technology (WI-IAT) · doi:10.1109/wi-iat62293.2024.00045
“In several natural language processing studies, rationales are defined as parts of the input text that support model predictions [26] [27] [28].”
Unsupervised Fact-Checking via Recursively Verifying Presuppositions
Lyu, X., Zhao, R., Li, J., Liang, B., Yang, M., Gui, L., & Xu, R. (2025) · IEEE Transactions on Audio Speech and Language Processing · doi:10.1109/taslpro.2025.3572768 · Cited by 1
“Authorized licensed use limited to the terms of the We focus on producing justifications for fact-checking [11], [12], [13], [14], [15], [16].”
Faraj, B. K., & Lakizadeh, A. (2025) · International Journal of Computational and Experimental Science and Engineering · doi:10.22399/ijcesen.2551
“…used for network structures and what replaces the max–pooling layer in CNNs is a convolution layer with an improved step size to solve the problem of accuracy loss during the training process Thus, it has certain enlightenment in developing more effective CNN-based DDIs prediction models [66, 67].”
FedRNL: Federated Rationalization with Soft Parameter Sharing
Kong, L., Jiang, J., Wang, H., Wu, L., & Li, R. (2025) · Lecture notes in computer science · doi:10.1007/978-3-032-05981-9_21
Gao, S., Wang, G., & Li, X. (2025) · International Conference on Computer Communication and Artificial Intelligence (CCAI) · doi:10.1109/ccai65422.2025.11189588
Bollikonda, M. (2025) · Preprints.org · doi:10.20944/preprints202511.0008.v1
Think-to-Detect: Rationale-Driven Vision–Language Anomaly Detection
Abdalla, M. I., Kasem, M. S., Mahmoud, M., Senussi, M. F., Abdallah, A., & Kang, H. (2025) · Mathematics · doi:10.3390/math13243920 · Cited by 3
Effective and Efficient Learning at Scale
Yu, W. (2020) · Figshare · doi:10.1184/r1/11898309
Inverse Reinforcement Learning: A Microeconomics-Based Approach
Pattanayak, K. (2023) · eCommons (Cornell University) · doi:10.7298/4s2r-mz87
Efficient and Explainable Neural Ranking
Leonhardt, L. J. (2023) · Institutional Repository of Leibniz Universität Hannover (Leibniz Universität Hannover) · doi:10.15488/15769 · Cited by 1
Developing and Comparing Machine Reasoning Models to Humans in NLP Tasks
Ghasemi Madani, M. R. (2024) · AMS Degree Thesis (University of Bologna) · Cited by 1
Diseño de un modelo explicativo basado en ontologías aplicado a un chatbot conversacional
Arteaga Meléndez, D. M. (2023) · renati · Cited by 3
Towards reliability and interactive debugging for large language models
Paranjape, B. (2024) · ResearchWorks at the University of Washington (University of Washington) · Cited by 17
Towards Human-Centered NLP Systems: Trustworthiness, Cognition, and Social Good
He, Z. (2024) · eScholarship (California Digital Library)
Teimert, E. (2024) · KTH Publication Database DiVA (KTH Royal Institute of Technology)
Ayodele, O. O. (2024) · UUM Electronic Theses and Dissertation [eTheses] (Northern University of Malaysia)
Bönte, B. (2024) · KTH Publication Database DiVA (KTH Royal Institute of Technology)
Interpretable Natural Language Processing with Applications to Information Extraction
Tang, Z., & Tang, Z. (2022) · UA Campus Repository (The University of Arizona)
Opening the Black Box: Empowering Machine Learning Models with Explanations
Setzu, M. (2022) · Electronic Theses and Dissertations Repository (University of Pisa)
Understanding and Improving Language Models Through a Data-Centric Lens
Albalak, A. (2024) · eScholarship (California Digital Library)
Capturing and leveraging opinions in microblogs through generative methods
Bilal, I. M. (2026) · Warwick Research Archive Portal (University of Warwick) · doi:10.82444/warw.33897238
Consumer Online Search Behavior: An Empirical Analysis
Prompijit, A. (2021) · eScholarship (California Digital Library) · Cited by 1
Sparse & Interpretable Graph Attention Networks
Naber, T. (2023) · Research Repository (Delft University of Technology) · Cited by 2
Interpretable and Automated Bias Detection for AI in Healthcare
Alexiev, C. (2024) · DSpace@MIT (Massachusetts Institute of Technology) · Cited by 2
Towards Bridging and Governing Decentralized Communities
Saldías-Fuentes, B. (2025) · DSpace@MIT (Massachusetts Institute of Technology) · Cited by 2
Jiang, X., Cheng, Y., Li, B., Yuan, Y., & Wang, G. (2025) · Knowledge-Based Systems · doi:10.1016/j.knosys.2025.114754
Domingues, L. E. R. (2024) · LA Referencia (Red Federada de Repositorios Institucionales de Publicaciones Científicas)
dos PRAZERES, P. J. N. B. (2023) · LA Referencia (Red Federada de Repositorios Institucionales de Publicaciones Científicas)
Learn from A Rationalist: Distilling Intermediate Interpretable RationalesPreprint
Dai, J., & Goebel, R. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2601.22531
“Following the original design by Lei et al. (2016), the rationale extraction framework has two neural components, a generator and a predictor, to separately perform rationale generation and classification tasks.”
InfluentialBringing NLP Explainability to Critical Sectors: A Case Study on NOTAMs in Aviation
Mussot, V., Hoofd, F., Jourdan, F., & Poché, A. (2026) · HAL · doi:10.82331/erts.2026.40 · Cited by 1
ChatXplain: Interpretable Explanations for Intelligent Assistants via Modular Rationale and Saliency
GUDIPATI, S. K., MISHRA, N. A., Mohammed, A. R., AKKISETTI, S. R., ANKAM, G., & PONUGOTI, S. (2026) · IEEE International Conference on AI in Cybersecurity (ICAIC) · doi:10.1109/icaic67076.2026.11395713
“[6].”
InfluentialExplaining Clinical Outcome Predictions with Compositional Rationale Extraction Model
Gao, W., Grossman, R., & Chen, Y. (2025) · IEEE International Conference on Big Data (BigData) · doi:10.1109/bigdata66926.2025.11400757
Let’s Decipher the Origin: Towards Multimodal Aspect-Based Explainable Complaints in Finance
Das, S., Deo, A., Dasari, H. V., Saha, S., & Maurya, A. (2026) · IEEE Transactions on Computational Social Systems · doi:10.1109/tcss.2025.3623387
Neural Transfer Learning for Domain Adaptation in Natural Language Processing
Meftah, S. (2021) · theses.fr (ABES) · doi:10.70675/9111562bzfa37z4fd8zae6bz2e8ae8d5d403 · Cited by 2
Analysis and control of online interactions through neural natural language processing
Laugier, L. (2022) · theses.fr (ABES) · doi:10.70675/4743aa15z209az4addz8f29z95150aa230b8 · Cited by 2
Transfer learning for abusive language detection
Bose, T. (2023) · theses.fr (ABES) · doi:10.70675/6b663c61zb592z4422zbc5fza68cbc285104 · Cited by 1
Modèles prédictifs & raisonnement avec les explications
Boumazouza, R. (2022) · theses.fr (ABES) · doi:10.70675/e74c615fz12cbz4425z8bc7z8f651a87f9d8 · Cited by 1
A Neural-Symbolic learning framework to produce interpretable predictions for image classification
Bennetot, A. (2022) · theses.fr (ABES) · doi:10.70675/2b59f598z2028z49afz8a20z29b21f19f394 · Cited by 1
Nguyen, D. H. (2024) · theses.fr (ABES) · doi:10.70675/97b1b150zc009z4f96z9ec6z2790870387a0
Atienza, N. (2025) · theses.fr (ABES) · doi:10.70675/81053b26z6d53z4f04zacc2zb3dd0156bba4 · Cited by 1
DocEviTrace: Faithful Explainability Through Verifiable Evidence Localization in Long Documents
Thakkar, K., Chatterjee, M., Balasubramanian, R., Jootoo, A., & Ugrani, R. (2026) · International Research Conference on Smart Computing and Systems Engineering (SCSE) · doi:10.1109/scse70081.2026.11499856
“Baselines include post-hoc attribution (LIME [1], SHAP [16], Integrated Gradients [17]), supervised rationales [6], ERASER-style select-then-predict [7], and a long-context reader (Longformer/BigBird) with attention maps as explanations [8], [9].”
Structure-aware neural generation of text from SQL queries
Yang, J., Zhang, D., Xu, J., Miao, J., Zhang, S., Chen, X., Gao, X., Lv, X., Zhang, Z., & Kang, R. (2026) · Fuzzy Optimization and Decision Making · doi:10.1007/s10700-026-09478-0
Wu, T., Su, Q., Yu, J., Liang, B., & Huang, M. (2026) · Findings of the Association for Computational Linguistics: ACL (Findings of ACL) · doi:10.18653/v1/2026.findings-acl.1025
Rethinking the Rationalization: A Two-Step Decomposition for Graph Rationalization
Xia, R., & Yue, L. (2026) · International Conference on Computer Supported Cooperative Work in Design (CSCWD) · doi:10.1109/cscwd68734.2026.11582241
“To address this issue, interpretable graph learning has gained growing interest [7], [8], with graph rationalization [9], [10] aiming to extract compact and representative subgraphs, known as rationales, that support model predictions.”
You Only Forward Once: Prediction and Rationalization in a Single Forward Pass
Wei, X. B., Jiang, H., Duan, J., Wang, J., & Qu, Z. (2026) · Big Data Mining and Analytics · doi:10.26599/bdma.2025.9020084
Visible Reasoning: User-Facing Decision Transparency for Generative AI Systems
Anbalagan, S. K., Nie, X., Kommalapati, A., Kanamarlapudi, V. K., Radhakrishnan, S., Zhao, X., & Mohan, U. (2026) · Lecture notes in computer science · doi:10.1007/978-3-032-30849-8_1
T-RLHF: Trustworthy Reinforcement Learning from Human Feedback for Decision-Centric NLP
Tripathi, K. K., & Tripathi, S. (2026) · International Conference on Computational Intelligence and Communication Networks (CICN) · doi:10.1109/cicn70047.2026.11594401
“While Chain-of-Thought Prompting [14] [15] has been shown to help improve performance, it is not designed to enforce a causal relationship between the justification for a model's prediction and the prediction itself.”
Federated Rationale Extraction with Information Competition
Cheng, X., Xia, R., & Yue, L. (2026) · Lecture notes in computer science · doi:10.1007/978-981-92-2862-1_5
Xbot: a GPT-based chatbot with transparent and empathetic behaviour
Caroprese, L., Zumpano, E., Aracne, M., & Ruga, T. (2026) · Discover Artificial Intelligence · doi:10.1007/s44163-026-01653-x
Tang, R., Yang, W., Zhang, P., Shi, Y., Zhang, S., He, H., & Jin, L. (2026) · ACM International Conference on Multimedia (ACM MM) · doi:10.48550/arxiv.2607.27902
“This definition presents a critical optimization challenge: patch informativeness is a latent attribute lacking explicit ranking, making it difficult for supervised learning (SL) to identify the most discriminative evidence [18].”
ProgNet: Program-Grounded Evidence Composition for Interpretable Graph Classification
Jeon, M., Park, S., & Jang, J.-G. (2026) · ACM SIGKDD Conference on Knowledge Discovery and Data Mining (KDD) · doi:10.1145/3770855.3817844
Interpretable financial fraud detection via conditional fusion of multimodal financial data
Yue, W., Zhu, G., Chen, Y., Sun, J., Miao, J., Vukovic, D. B., & Cao, J. (2026) · Engineering Applications of Artificial Intelligence · doi:10.1016/j.engappai.2026.115840
REMEDy: a dataset for rationale extraction and span-based moderation of dialogue prompts
Piano, L., Battistin, C., den Abeele, J. V., & Pompianu, L. (2026) · Neural Computing and Applications · doi:10.1007/s00521-026-12381-9
“Subsequent studies introduced automatic rationale generation [15] and encoder–generator architectures capable of producing intrinsic rationales without supervision [16 ].”
Yoo, J., Kim, B., Yang, Y., & Jang, H. (2026) · IEEE Access · doi:10.1109/access.2026.3725783
“…studies, simple label signals cannot explain the causal reasoning process and therefore carry a risk of overfitting, whereas reasoning rationales can function as richer supervisory signals that improve the reliability of decision boundaries even in data-scarce environments [17], [18], [19].”
GRACE: Gradient-Regulated Approach for Consistent Explanations
Basu, S. (2026) · Lecture notes in computer science · doi:10.1007/978-3-032-36039-7_33
Evidence-Consistent Generative Detection under Scenario-Level Distribution Shift
Kim, S., & Bak, J. (2026) · ACM International Conference on Information and Knowledge Management (CIKM) · doi:10.1145/3799682.3840763 · Cited by 1
Accountable NLP for Evidence-Grounded Decision Briefings: A Critical Review and Evaluation Framework
Moon, J. (2026) · Computers, materials & continua/Computers, materials & continua (Print) · doi:10.32604/cmc.2026.089115
Beyond One-Way Pipelines: Bidirectional Cooperation for Self-explaining RationalizationPreprint
Deng, Z., Zheng, L., Gao, W., Yuan, W., Liu, D., & Liu, W. (2026) · SSRN Electronic Journal · doi:10.2139/ssrn.7380313
Hybrid Adversarial Training Guided by Saliency for Robust Sentiment Classification
Chen, C., Lin, S., Huang, Z., Chen, Z., & Liao, X. (2026) · Lecture notes in computer science · doi:10.1007/978-3-032-37673-2_4
Jiang, J., Yu, D., Li, C., Wang, D., Nishizaki, H., & Leow, C. S. (2026) · Lecture notes in computer science · doi:10.1007/978-3-032-37670-1_11
Enhancing Model Explainability and Performance via Attention-Guided Gradient Restriction
Nguyen, H.-C., Lê, H., & Nguyen, T. (2026) · Lecture notes in computer science · doi:10.1007/978-3-032-37676-3_6
Aleb, N. (2026) · International journal of intelligent engineering and systems · doi:10.22266/ijies2026.1031.11
GLoC-EHR: Evidence-Cited Clinical Reasoning over Global Context and Local EHR EventsPreprint
Shin, C., & Kim, K. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2610.01076
“…and the response’s evidence bullets, with the reasoning prose removed and both EHR memories switched off, as in select-then-predict rationales (Lei et al., 2016; Jain et al., 2020); it asks whether the cited findings are informative about the outcome, and it is a loss rather than a reward…”
Sudhandradevi, P., & Bhuvaneswari, V. (2025) · TPM Testing, psychometrics, methodology in applied psychology
ARBITRA: Robust Document-Level ATT&CK Extraction via Multi-Expert ArgumentationPreprint
Jin, Y., & Shin, S. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2610.39433
Beyond Correlation: Deploying Causal AI to Attribute E-Commerce Sales Loss at Scale
Nayak, D., Kumar, M., Goel, H., & Kaveri, S. R. (2026) · ACM International Conference on Information and Knowledge Management (CIKM) · doi:10.1145/3799682.3840136
CST: Lightweight Risk Triage with Source-Grounded Evidence for Web DiscussionsPreprint
Wang, Z., Gao, Y., Feng, Y., Pan, R., Zhao, B., Chen, Z., & Li, N. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2611.01710
SelfCite: Self-Supervised Alignment for Context Attribution in Large Language Models
Chuang, Y.-S., Cohen-Wang, B., Shen, S. Z., Wu, Z., Xu, H., Lin, X. V., Glass, J., Li, S.-W., & Yih, W.-T. (2025) · arXiv · doi:10.48550/arxiv.2502.09604
“Drawing inspiration from model interpretability techniques (Lei et al., 2016; Cohen-Wang et al., 2024), SelfCite leverages the inherent capabilities of LLMs to provide feedback through context ablation —a process to evaluate the necessity and sufficiency of a citation.”
Metadata
- Authors
- Lei, T., Barzilay, R., & Jaakkola, T.
- Affiliations
- MIT Computer Science and Artificial Intelligence Laboratory (US)
- Venue
- Proceedings of the 2016 Conference on Empirical Methods in Natural Language Processing
- Published
- 2016
- Pages
- 107-117
- OpenAlex
- W2440159969
- Cited by
- 777
- References
- 27
- Citations by year
- 2026: 27 · 2025: 33 · 2024: 39 · 2023: 88 · 2022: 92 · 2021: 138 · 2020: 126 · 2019: 101 · 2018: 78 · 2017: 39 · 2016: 4
- FWCI
- 39.87
- Type
- conference paper
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- cc-by
- Locations
- Conference on Empirical Methods in Natural Language Processing (EMNLP) (publishedVersion, cc-by)
- arXiv (Cornell University) (submittedVersion)
- DSpace@MIT (Massachusetts Institute of Technology) (submittedVersion, cc-by-nc-sa)
- arXiv (Cornell University)
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Explainable Artificial Intelligence (XAI)
- Physical Sciences › Computer Science › Artificial Intelligence › Sentiment Analysis and Opinion Mining
- Physical Sciences › Computer Science › Artificial Intelligence › Topic Modeling
- Keywords
- explanation generation, question retrieval, model regularization
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
