

Sparse Communication for Distributed Gradient Descent
Open accessThe DOI matches its Crossref record; 3 of the 3 references it cites were found in a registry or an index.
Abstract
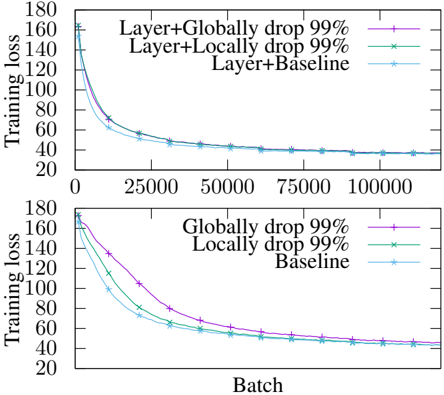
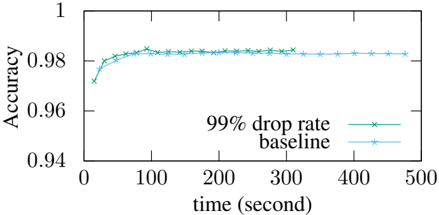
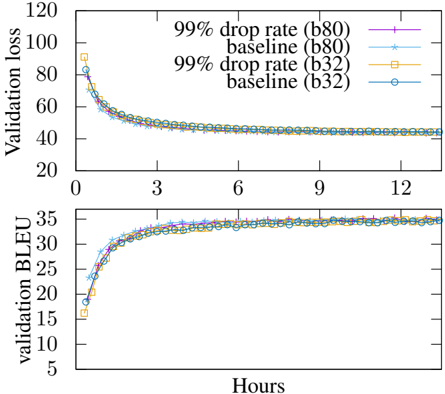
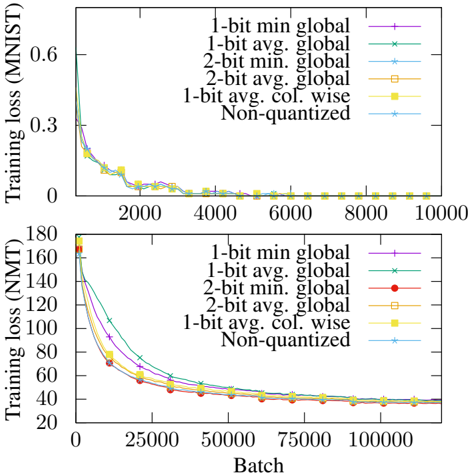
We make distributed stochastic gradient descent faster by exchanging sparse updates instead of dense updates.Gradient updates are positively skewed as most updates are near zero, so we map the 99% smallest updates (by absolute value) to zero then exchange sparse matrices.This method can be combined with quantization to further improve the compression.We explore different configurations and apply them to neural machine translation and MNIST image classification tasks.Most configurations work on MNIST, whereas different configurations reduce convergence rate on the more complex translation task.Our experiments show that we can achieve up to 49% speed up on MNIST and 22% on NMT without damaging the final accuracy or BLEU.
Overview
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
“Sparsification, on the other hand, proposes to only communicate the informative elements of the gradient or model vectors among nodes [128], [129].”
From Edge artificial intelligence for 6g: vision, enabling technologies, and applications (2022) · cites this paper as [129]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
The publisher hasn’t deposited this paper’s reference list.
Research works printed but not linked: 15
- Tolu Alabi, Jeffrey D Blanchard, Bradley Gordon, and Russel Steinbach. 2012. Fast k-selection algorithms for graphics processing units. Journal of Experi- mental Algorithmics (JEA) 17:4-2.
- Dan Alistarh, Jerry Li, Ryota Tomioka, and Milan Vojnovic. 2016. QSGD: randomized quan- tization for communication-optimal stochas- tic gradient descent. CoRR abs/1610.02132. http://arxiv.org/abs/1610.02132. · arXiv
- Trishul M Chilimbi, Yutaka Suzue, Johnson Apacible, and Karthik Kalyanaraman. 2014. Project adam: Building an efficient and scalable deep learning training system. In OSDI. volume 14, pages 571- 582.
- Jeffrey Dean, Greg Corrado, Rajat Monga, Kai Chen, Matthieu Devin, Mark Mao, Andrew Senior, Paul Tucker, Ke Yang, Quoc V Le, et al. 2012. Large scale distributed deep networks. In Advances in neural information processing systems. pages 1223- 1231.
- Nikoli Dryden, Sam Ade Jacobs, Tim Moon, and Brian Van Essen. 2016. Communication quantization for data-parallel training of deep neural networks. In Proceedings of the Workshop on Machine Learn- ing in High Performance Computing Environments. IEEE Press, pages 1-8.
- Marcin Junczys-Dowmunt, Tomasz Dwojak, and Hieu Hoang. 2016. Is neural machine translation ready for deployment? A case study on 30 translation directions. In Program of the 13th International Workshop on Spoken Language Translation (IWSLT 2016).
- Yann LeCun, Léon Bottou, Yoshua Bengio, and Patrick Haffner. 1998. Gradient-based learning applied to document recognition. Proceedings of the IEEE 86(11):2278-2324.
- J. Lei Ba, J. R. Kiros, and G. E. Hinton. 2016. Layer Normalization. ArXiv e-prints .
- Ramón P Ñeco and Mikel L Forcada. 1996. Beyond mealy machines: Learning translators with recurrent neural networks. In Proceedings of the 1996 Inter- national Neural Network Society Annual Meeting. San Diego, California, USA.
- Kishore Papineni, Salim Roukos, Todd Ward, and Wei- Jing Zhu. 2002. BLEU: A method for automatic evalution of machine translation. In Proceedings 40th Annual Meeting of the Association for Com- putational Linguistics. Philadelphia, PA, pages 311- 318.
- Rajat Raina, Anand Madhavan, and Andrew Y Ng. 2009. Large-scale deep unsupervised learning using graphics processors. In Proceedings of the 26th an- nual international conference on machine learning. ACM, pages 873-880.
- Frank Seide, Hao Fu, Jasha Droppo, Gang Li, and Dong Yu. 2014. 1-bit stochastic gradi- ent descent and application to data-parallel distributed training of speech DNNs. In Interspeech. https://www.microsoft.com/en- us/research/publication/1-bit-stochastic-gradient- descent-and-application-to-data-parallel- distributed-training-of-speech-dnns/.
- Rico Sennrich, Barry Haddow, and Alexandra Birch. 2016. Edinburgh neural machine translation sys- tems for WMT 16. In Proceedings of the ACL 2016 First Conference on Machine Translation (WMT16).
- Martin Zinkevich, Markus Weimer, Lihong Li, and Alex J Smola. 2010. Parallelized stochastic gradient descent. In Advances in neural information process- ing systems. pages 2595-2603.
- Daniel Zwillinger and Stephen Kokoska. 1999. CRC standard probability and statistics tables and formu- lae. CRC Press.
Cited by
Robust and Communication-Efficient Federated Learning From Non-i.i.d. Data
Sattler, F., Wiedemann, S., Muller, K.-R., & Samek, W. (2020) · IEEE Transactions on Neural Networks and Learning Systems · doi:10.1109/tnnls.2019.2944481 · Cited by 1,725
Edge artificial intelligence for 6g: vision, enabling technologies, and applications
Letaief, K. B., Shi, Y., Lu, J., & Lu, J. (2022) · IEEE Journal on Selected Areas in Communications · doi:10.1109/jsac.2021.3126076 · Cited by 829
“Sparsification, on the other hand, proposes to only communicate the informative elements of the gradient or model vectors among nodes [128], [129].”
BackgroundBroadband Analog Aggregation for Low-Latency Federated Edge Learning
Zhu, G., Wang, Y., & Huang, K. (2020) · IEEE Transactions on Wireless Communications · doi:10.1109/twc.2019.2946245 · Cited by 761
Demystifying Parallel and Distributed Deep Learning: An In-depth Concurrency Analysis
Ben-Nun, T., & Hoefler, T. (2020) · ACM Computing Surveys · doi:10.1145/3320060 · Cited by 577
Scheduling Policies for Federated Learning in Wireless Networks
Yang, H. H., Liu, Z., Quek, T. Q. S., & Poor, H. V. (2020) · IEEE Transactions on Communications · doi:10.1109/tcomm.2019.2944169 · Cited by 640
Federated Learning Over Wireless Fading Channels
Amiri, M. M., & Gunduz, D. (2020) · IEEE Transactions on Wireless Communications · doi:10.1109/twc.2020.2974748 · Cited by 625
Distributed Learning in Wireless Networks: Recent Progress and Future Challenges
Chen, M., Gunduz, D., Huang, K., Saad, W., Bennis, M., Feljan, A. V., & Poor, H. V. (2021) · IEEE Journal on Selected Areas in Communications · doi:10.1109/jsac.2021.3118346 · Cited by 548
Machine Learning at the Wireless Edge: Distributed Stochastic Gradient Descent Over-the-Air
Mohammadi Amiri, M., & Gunduz, D. (2020) · IEEE Transactions on Signal Processing · doi:10.1109/tsp.2020.2981904 · Cited by 548
Vertical Federated Learning: Concepts, Advances, and Challenges
Liu, Y., Kang, Y., Zou, T., Pu, Y., He, Y., Ye, X., Ouyang, Y., Zhang, Y.-Q., & Yang, Q. (2024) · IEEE Transactions on Knowledge and Data Engineering · doi:10.1109/tkde.2024.3352628 · Cited by 378
Xu, J., & Wang, H. (2021) · IEEE Transactions on Wireless Communications · doi:10.1109/twc.2020.3031503 · Cited by 466
Asynchronous federated learning on heterogeneous devices: A survey
Xu, C., Qu, Y., Xiang, Y., & Gao, L. (2023) · Computer Science Review · doi:10.1016/j.cosrev.2023.100595 · Cited by 335
The Convergence of Sparsified Gradient MethodsPreprint
Alistarh, D., Hoefler, T., Johansson, M., Khirirat, S., Konstantinov, N., & Renggli, C. (2018) · arXiv (Cornell University) · doi:10.48550/arxiv.1809.10505 · Cited by 525
A generic communication scheduler for distributed DNN training acceleration
Peng, Y., Zhu, Y., Chen, Y., Bao, Y., Yi, B., Lan, C., Wu, C., & Guo, C. (2019) · Proceedings of the 27th ACM Symposium on Operating Systems Principles · doi:10.1145/3341301.3359642 · Cited by 321
Multi-Armed Bandit-Based Client Scheduling for Federated Learning
Xia, W., Quek, T. Q. S., Guo, K., Wen, W., Yang, H. H., & Zhu, H. (2020) · IEEE Transactions on Wireless Communications · doi:10.1109/twc.2020.3008091 · Cited by 313
A survey of federated learning for edge computing: Research problems and solutions
Xia, Q., Ye, W., Tao, Z., Wu, J., & Li, Q. (2021) · High-Confidence Computing · doi:10.1016/j.hcc.2021.100008 · Cited by 279
UVeQFed: Universal Vector Quantization for Federated Learning
Shlezinger, N., Chen, M., Eldar, Y. C., Poor, H. V., & Cui, S. (2021) · IEEE Transactions on Signal Processing · doi:10.1109/tsp.2020.3046971 · Cited by 275
ATOMO: Communication-efficient Learning via Atomic Sparsification
Wang, H., Sievert, S., Charles, Z., Liu, S., Wright, S. J., & Papailiopoulos, D. (2018) · arXiv (Cornell University) · doi:10.48550/arxiv.1806.04090 · Cited by 189
Qsparse-local-SGD: Distributed SGD with quantization, sparsification, and local computations
Basu, D., Data, D., Karakus, C., & Diggavi, S. N. (2020) · IEEE Journal on Selected Areas in Information Theory · doi:10.1109/jsait.2020.2985917 · Cited by 256
“, k < 1%, has been proposed [2, 4, 20, 30, 32], combined with error compensation to ensure that all co-ordinates do get eventually updated as needed.”
BackgroundSparse Binary Compression: Towards Distributed Deep Learning with minimal Communication
Sattler, F., Wiedemann, S., Muller, K.-R., & Samek, W. (2019) · 2019 International Joint Conference on Neural Networks (IJCNN) · doi:10.1109/ijcnn.2019.8852172 · Cited by 240
Over-the-Air Federated Learning From Heterogeneous Data
Sery, T., Shlezinger, N., Cohen, K., & Eldar, Y. (2021) · IEEE Transactions on Signal Processing · doi:10.1109/tsp.2021.3090323 · Cited by 219
Baccour, E., Mhaisen, N., Abdellatif, A. A., Erbad, A., Mohamed, A., Hamdi, M., & Guizani, M. (2022) · IEEE Communications Surveys & Tutorials · doi:10.1109/comst.2022.3200740 · Cited by 186
Gunduz, D., de Kerret, P., Sidiropoulos, N. D., Gesbert, D., Murthy, C. R., & van der Schaar, M. (2019) · IEEE Journal on Selected Areas in Communications · doi:10.1109/jsac.2019.2933969 · Cited by 214
Ternary Compression for Communication-Efficient Federated Learning
Xu, J., Du, W., Jin, Y., He, W., & Cheng, R. (2020) · IEEE Transactions on Neural Networks and Learning Systems · doi:10.1109/tnnls.2020.3041185 · Cited by 255
Adaptive Gradient Sparsification for Efficient Federated Learning: An Online Learning Approach
Han, P., Wang, S., & Leung, K. K. (2020) · 2020 IEEE 40th International Conference on Distributed Computing Systems (ICDCS) · doi:10.1109/icdcs47774.2020.00026 · Cited by 181
Hu, S., Chen, X., Ni, W., Hossain, E., & Wang, X. (2021) · IEEE Communications Surveys & Tutorials · doi:10.1109/comst.2021.3086014 · Cited by 178
Membership Inference Attacks and Defenses in Federated Learning: A Survey
Bai, L., Hu, H., Ye, Q., Li, H., Wang, L., & Xu, J. (2024) · ACM Computing Surveys · doi:10.1145/3704633 · Cited by 243
FedOpt: Towards Communication Efficiency and Privacy Preservation in Federated Learning
Asad, M., Moustafa, A., & Ito, T. (2020) · Applied Sciences · doi:10.3390/app10082864 · Cited by 174
Hermes: an efficient federated learning framework for heterogeneous mobile clients
Li, A., Sun, J., Li, P., Pu, Y., Li, H., & Chen, Y. (2021) · Proceedings of the 27th Annual International Conference on Mobile Computing and Networking · doi:10.1145/3447993.3483278 · Cited by 168
A Distributed Synchronous SGD Algorithm with Global Top-k Sparsification for Low Bandwidth Networks
Shi, S., Wang, Q., Zhao, K., Tang, Z., Wang, Y., Huang, X., & Chu, X. (2019) · 2019 IEEE 39th International Conference on Distributed Computing Systems (ICDCS) · doi:10.1109/icdcs.2019.00220 · Cited by 161
Learning Rate Optimization for Federated Learning Exploiting Over-the-Air Computation
Xu, C., Liu, S., Yang, Z., Huang, Y., & Wong, K.-K. (2021) · IEEE Journal on Selected Areas in Communications · doi:10.1109/jsac.2021.3118402 · Cited by 159
Privacy-Preserving Aggregation in Federated Learning: A Survey
Liu, Z., Guo, J., Yang, W., Fan, J., Lam, K., & Zhao, J. (2022) · IEEE Transactions on Big Data · doi:10.1109/tbdata.2022.3190835 · Cited by 260
Characterizing Impacts of Heterogeneity in Federated Learning upon Large-Scale Smartphone Data
Yang, C., Wang, Q., Xu, M., Chen, Z., Bian, K., Liu, Y., & Liu, X. (2021) · Proceedings of the Web Conference 2021 · doi:10.1145/3442381.3449851 · Cited by 135
Privacy-Preserving Asynchronous Federated Learning Mechanism for Edge Network Computing
Lu, X., Liao, Y., Lio, P., & Hui, P. (2020) · IEEE Access · doi:10.1109/access.2020.2978082 · Cited by 159
Gradient Statistics Aware Power Control for Over-the-Air Federated Learning
Zhang, N., & Tao, M. (2021) · IEEE Transactions on Wireless Communications · doi:10.1109/twc.2021.3065748 · Cited by 153
CFD: Communication-Efficient Federated Distillation via Soft-Label Quantization and Delta Coding
Sattler, F., Marbán, A., Rischke, R., & Samek, W. (2021) · IEEE Transactions on Network Science and Engineering · doi:10.1109/tnse.2021.3081748 · Cited by 175
Robust Federated Learning With Noisy Communication
Ang, F., Chen, L., Zhao, N., Chen, Y., Wang, W., & Yu, F. R. (2020) · IEEE Transactions on Communications · doi:10.1109/tcomm.2020.2979149 · Cited by 144
Cui, L., Su, X., Ming, Z., Chen, Z., Yang, S., Zhou, Y., & Xiao, W. (2022) · IEEE Internet of Things Journal · doi:10.1109/jiot.2020.3014370 · Cited by 146
FedSel: Federated SGD Under Local Differential Privacy with Top-k Dimension Selection
Liu, R., Cao, Y., Yoshikawa, M., & Chen, H. (2020) · Lecture notes in computer science · doi:10.1007/978-3-030-59410-7_33 · Cited by 182
Communication-efficient distributed learning: An overview
Cao, X., Başar, T., Diggavi, S., Eldar, Y. C., Letaief, K. B., Poor, H. V., & Zhang, J. (2023) · IEEE Journal on Selected Areas in Communications · doi:10.1109/jsac.2023.3242710 · Cited by 139
“Motivated by this observation, in [122], the authors proposed to map 99% of the gradient entries to zero and only transmit the rest.”
BackgroundMethodLi, A., Sun, J., Zeng, X., Zhang, M., Li, H., & Chen, Y. (2021) · Proceedings of the 19th ACM Conference on Embedded Networked Sensor Systems · doi:10.1145/3485730.3485929 · Cited by 139
A Survey on Approximate Edge AI for Energy Efficient Autonomous Driving Services
Katare, D., Perino, D., Nurmi, J., Warnier, M., Janssen, M., & Ding, A. Y. (2023) · IEEE Communications Surveys & Tutorials · doi:10.1109/comst.2023.3302474 · Cited by 155
Qian, B., Su, J., Wen, Z., Jha, D. N., Li, Y., Guan, Y., Puthal, D., James, P., Yang, R., Zomaya, A. Y., et al. (2021) · ACM Computing Surveys · doi:10.1145/3398020 · Cited by 132
Priority-based Parameter Propagation for Distributed DNN TrainingPreprint
Jayarajan, A., Wei, J., Gibson, G. A., Fedorova, A., & Pekhimenko, G. G. (2019) · arXiv (Cornell University) · doi:10.48550/arxiv.1905.03960 · Cited by 203
Adaptive Control of Local Updating and Model Compression for Efficient Federated Learning
Xu, Y., Liao, Y., Xu, H., Ma, Z., Wang, L., & Liu, J. (2022) · IEEE Transactions on Mobile Computing · doi:10.1109/tmc.2022.3186936 · Cited by 141
SparCML: high-performance sparse communication for machine learning
Renggli, C., Ashkboos, S., Aghagolzadeh, M., Alistarh, D., & Hoefler, T. (2019) · Proceedings of the International Conference for High Performance Computing, Networking, Storage and Analysis · doi:10.1145/3295500.3356222 · Cited by 101
Federated Learning with Quantization Constraints
Shlezinger, N., Chen, M., Eldar, Y. C., Poor, H. V., & Cui, S. (2020) · ICASSP 2020 - 2020 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP) · doi:10.1109/icassp40776.2020.9054168 · Cited by 115
Communication-Efficient Federated Learning Based on Compressed Sensing
Li, C., Li, G., & Varshney, P. K. (2021) · IEEE Internet of Things Journal · doi:10.1109/jiot.2021.3073112 · Cited by 133
Decentralised Learning in Federated Deployment Environments: A System-Level Survey
Bellavista, P., Foschini, L., & Mora, A. (2022) · ACM Computing Surveys · doi:10.1145/3429252 · Cited by 99
Machine Learning at the Wireless Edge: Distributed Stochastic Gradient Descent Over-the-Air
Amiri, M. M., & Gunduz, D. (2019) · 2019 IEEE International Symposium on Information Theory (ISIT) · doi:10.1109/isit.2019.8849334 · Cited by 109
Edge AI for Internet of Energy: Challenges and perspectives
Himeur, Y., Sayed, A. N., Alsalemi, A., Bensaali, F., & Amira, A. (2023) · Internet of Things · doi:10.1016/j.iot.2023.101035 · Cited by 130
Communication-Efficient Federated Learning with Adaptive Quantization
Mao, Y., Zhao, Z., Yan, G., Liu, Y., Lan, T., Song, L., & Ding, W. (2022) · ACM Transactions on Intelligent Systems and Technology · doi:10.1145/3510587 · Cited by 126
Lazily Aggregated Quantized Gradient Innovation for Communication-Efficient Federated Learning
Sun, J., Chen, T., Giannakis, G. B., Yang, Q., & Yang, Z. (2022) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2020.3033286 · Cited by 102
GradientFlow: Optimizing Network Performance for Large-Scale Distributed DNN Training
Sun, P., Wen, Y., Han, R., Feng, W., & Yan, S. (2019) · IEEE Transactions on Big Data · doi:10.1109/tbdata.2019.2957478 · Cited by 109
Accelerating Decentralized Federated Learning in Heterogeneous Edge Computing
Wang, L., Xu, Y., Xu, H., Chen, M., & Huang, L. (2022) · IEEE Transactions on Mobile Computing · doi:10.1109/tmc.2022.3178378 · Cited by 125
A Survey on Error-Bounded Lossy Compression for Scientific Datasets
Di, S., Liu, J., Zhao, K., Liang, X., Underwood, R., Zhang, Z., Shah, M., Huang, Y., Huang, J., Yu, X., et al. (2025) · ACM Computing Surveys · doi:10.1145/3733104 · Cited by 121
Towards efficient communications in federated learning: A contemporary survey
Zhao, Z., Mao, Y., Liu, Y., Song, L., Ouyang, Y., Chen, X., & Ding, W. (2023) · Journal of the Franklin Institute · doi:10.1016/j.jfranklin.2022.12.053 · Cited by 121
Toward Communication-Efficient Federated Learning in the Internet of Things With Edge Computing
Sun, H., Li, S., Yu, F. R., Qi, Q., Wang, J., & Liao, J. (2020) · IEEE Internet of Things Journal · doi:10.1109/jiot.2020.2994596 · Cited by 95
“In the training process, the absolute values of gradients are positively skewed: most are near zero [44].”
AI on the edge: a comprehensive review
Su, W., Li, L., Liu, F., He, M., & Liang, X. (2022) · Artificial Intelligence Review · doi:10.1007/s10462-022-10141-4 · Cited by 105
Communication-Efficient Federated Learning via Quantized Compressed Sensing
Oh, Y., Lee, N., Jeon, Y., & Poor, H. V. (2022) · IEEE Transactions on Wireless Communications · doi:10.1109/twc.2022.3201207 · Cited by 96
Training Neural Networks with Fixed Sparse MasksPreprint
Sung, Y.-L., Nair, V., & Raffel, C. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2111.09839 · Cited by 151
SPARQ-SGD: Event-Triggered and Compressed Communication in Decentralized Optimization
Singh, N., Data, D., George, J., & Diggavi, S. N. (2022) · IEEE Transactions on Automatic Control · doi:10.1109/tac.2022.3145576 · Cited by 93
Towards Accurate Post-Training Quantization for Vision Transformer
Ding, Y., Qin, H., Yan, Q., Chai, Z., Liu, J., Wei, X., & Liu, X. (2022) · Proceedings of the 30th ACM International Conference on Multimedia · doi:10.1145/3503161.3547826 · Cited by 79
“by [1, 37, 45, 48] that pruning the gradients close to zero in the backward propagation has a tiny impact on weight-updating.”
BackgroundLearned Gradient Compression for Distributed Deep Learning
Abrahamyan, L., Chen, Y., Bekoulis, G., & Deligiannis, N. (2021) · IEEE Transactions on Neural Networks and Learning Systems · doi:10.1109/tnnls.2021.3084806 · Cited by 98
FEDZIP: A Compression Framework for Communication-Efficient Federated LearningPreprint
Malekijoo, A., Fadaeieslam, M. J., Malekijou, H., Homayounfar, M., Alizadeh-Shabdiz, F., & Rawassizadeh, R. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2102.01593 · Cited by 90
Joint Optimization of Communications and Federated Learning Over the Air
Fan, X., Wang, Y., Huo, Y., & Tian, Z. (2021) · IEEE Transactions on Wireless Communications · doi:10.1109/twc.2021.3130111 · Cited by 86
Deng, Y., Lyu, F., Xia, T., Zhou, Y., Zhang, Y., Ren, J., & Yang, Y. (2024) · IEEE/ACM Transactions on Networking · doi:10.1109/tnet.2024.3363916 · Cited by 97
A Convergence Analysis of Distributed SGD with Communication-Efficient Gradient Sparsification
Shi, S., Zhao, K., Wang, Q., Tang, Z., & Chu, X. (2019) · International Joint Conference on Artificial Intelligence · doi:10.24963/ijcai.2019/473 · Cited by 90
Adaptive Hierarchical Federated Learning Over Wireless Networks
Xu, B., Xia, W., Wen, W., Liu, P., Zhao, H., & Zhu, H. (2021) · IEEE Transactions on Vehicular Technology · doi:10.1109/tvt.2021.3135541 · Cited by 81
GRACE: A Compressed Communication Framework for Distributed Machine Learning
Xu, H., Ho, C.-Y., Abdelmoniem, A. M., Dutta, A., Bergou, E. H., Karatsenidis, K., Canini, M., & Kalnis, P. (2021) · IEEE International Conference on Distributed Computing Systems (ICDCS) · doi:10.1109/icdcs51616.2021.00060 · Cited by 111
Evaluating the Communication Efficiency in Federated Learning Algorithms
Asad, M., Moustafa, A., Ito, T., & Aslam, M. (2021) · 2021 IEEE 24th International Conference on Computer Supported Cooperative Work in Design (CSCWD) · doi:10.1109/cscwd49262.2021.9437738 · Cited by 59
Liu, H., He, F., & Cao, G. (2023) · IEEE Conference on Computer Communications (INFOCOM) · doi:10.1109/infocom53939.2023.10228970 · Cited by 89
Philippenko, C., & Dieuleveut, A. (2020) · arXiv (Cornell University) · doi:10.48550/arxiv.2006.14591 · Cited by 79
Communication optimization strategies for distributed deep neural network training: A survey
Ouyang, S., Dong, D., Xu, Y., & Xiao, L. (2020) · Journal of Parallel and Distributed Computing · doi:10.1016/j.jpdc.2020.11.005 · Cited by 88
Computation Scheduling for Distributed Machine Learning With Straggling Workers
Amiri, M. M., & Gunduz, D. (2019) · IEEE Transactions on Signal Processing · doi:10.1109/tsp.2019.2952051 · Cited by 65
SHARE: Shaping Data Distribution at Edge for Communication-Efficient Hierarchical Federated Learning
Deng, Y., Lyu, F., Ren, J., Zhang, Y., Zhou, Y., Zhang, Y., & Yang, Y. (2021) · IEEE International Conference on Distributed Computing Systems (ICDCS) · doi:10.1109/icdcs51616.2021.00012 · Cited by 86
Joint Privacy Enhancement and Quantization in Federated Learning
Lang, N., Sofer, E., Shaked, T., & Shlezinger, N. (2023) · IEEE Transactions on Signal Processing · doi:10.1109/tsp.2023.3244092 · Cited by 97
Communication-Efficient Distributed Deep Learning with Merged Gradient Sparsification on GPUs
Shi, S., Wang, Q., Chu, X., Li, B., Qin, Y., Liu, R., & Zhao, X. (2020) · IEEE Conference on Computer Communications (INFOCOM) · doi:10.1109/infocom41043.2020.9155269 · Cited by 88
A Hitchhiker’s Guide On Distributed Training Of Deep Neural Networks
Chahal, K., Grover, M. S., Dey, K., & Shah, R. R. (2019) · Journal of Parallel and Distributed Computing · doi:10.1016/j.jpdc.2019.10.004 · Cited by 76
1-Bit Compressive Sensing for Efficient Federated Learning Over the Air
Fan, X., Wang, Y., Huo, Y., & Tian, Z. (2022) · IEEE Transactions on Wireless Communications · doi:10.1109/twc.2022.3209190 · Cited by 80
Preemptive All-reduce Scheduling for Expediting Distributed DNN Training
Bao, Y., Peng, Y., Chen, Y., & Wu, C. (2020) · IEEE Conference on Computer Communications (INFOCOM) · doi:10.1109/infocom41043.2020.9155446 · Cited by 87
Bandwidth Allocation for Multiple Federated Learning Services in Wireless Edge Networks
Xu, J., Wang, H., & Chen, L. (2021) · IEEE Transactions on Wireless Communications · doi:10.1109/twc.2021.3113346 · Cited by 79
On-Board Federated Learning for Satellite Clusters With Inter-Satellite Links
Razmi, N., Matthiesen, B., Dekorsy, A., & Popovski, P. (2024) · IEEE Transactions on Communications · doi:10.1109/tcomm.2024.3356429 · Cited by 68
Network-Aware Optimization of Distributed Learning for Fog Computing
Wang, S., Ruan, Y., Tu, Y., Wagle, S., Brinton, C. G., & Joe‐Wong, C. (2021) · IEEE/ACM Transactions on Networking · doi:10.1109/tnet.2021.3075432 · Cited by 73
Defending Batch-Level Label Inference and Replacement Attacks in Vertical Federated Learning
Zou, T., Liu, Y., Kang, Y., Liu, W., He, Y., Yi, Z., Yang, Q., & Zhang, Y.-Q. (2022) · IEEE Transactions on Big Data · doi:10.1109/tbdata.2022.3192121 · Cited by 112
Near-optimal sparse allreduce for distributed deep learning
Li, S., & Hoefler, T. (2022) · ACM SIGPLAN Symposium on Principles and Practice of Parallel Programming · doi:10.1145/3503221.3508399 · Cited by 86
Joint Parameter-and-Bandwidth Allocation for Improving the Efficiency of Partitioned Edge Learning
Wen, D., Bennis, M., & Huang, K. (2020) · IEEE Transactions on Wireless Communications · doi:10.1109/twc.2020.3021177 · Cited by 64
Linear Convergence in Federated Learning: Tackling Client Heterogeneity and Sparse GradientsPreprint
Mitra, A., Jaafar, R. H., Pappas, G. J., & Hassani, H. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2102.07053 · Cited by 203
Communication-Efficient Federated Learning With Binary Neural Networks
Yang, Y., Zhang, Z., & Yang, Q. (2021) · IEEE Journal on Selected Areas in Communications · doi:10.1109/jsac.2021.3118415 · Cited by 69
Heterogeneity-Aware Federated Learning with Adaptive Client Selection and Gradient Compression
Jiang, Z., Xu, Y., Xu, H., Wang, Z., & Qian, C. (2023) · IEEE Conference on Computer Communications (INFOCOM) · doi:10.1109/infocom53939.2023.10229029 · Cited by 77
Time-Correlated Sparsification for Communication-Efficient Federated Learning
Özfatura, E., Özfatura, K., & Gündüz, D. (2021) · IEEE International Symposium on Information Theory (ISIT) · doi:10.1109/isit45174.2021.9518221 · Cited by 80
Ji, Y., & Chen, L. (2022) · IEEE Internet of Things Journal · doi:10.1109/jiot.2022.3213650 · Cited by 69
On the Convergence of Communication-Efficient Local SGD for Federated Learning
Gao, H., Xu, A. P., & Huang, H. (2021) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v35i9.16920 · Cited by 70
Eiffel : Efficient and Fair Scheduling in Adaptive Federated Learning
Sultana, A., Haque, M. M., Chen, L., Xu, F., & Yuan, X. (2022) · IEEE Transactions on Parallel and Distributed Systems · doi:10.1109/tpds.2022.3187365 · Cited by 70
GRID: Gradient Routing With In-Network Aggregation for Distributed Training
Fang, J., Zhao, G., Xu, H., Wu, C., & Yu, Z. (2023) · IEEE/ACM Transactions on Networking · doi:10.1109/tnet.2023.3244794 · Cited by 63
E2-Train: Training State-of-the-art CNNs with Over 80% Energy SavingsPreprint
Wang, Y., Jiang, Z., Chen, X., Xu, P., Zhao, Y. K., Lin, Y., & Wang, Z. (2019) · arXiv (Cornell University) · doi:10.48550/arxiv.1910.13349 · Cited by 69
Over-the-Air Machine Learning at the Wireless Edge
Amiri, M. M., & Gündüz, D. (2019) · 2019 IEEE 20th International Workshop on Signal Processing Advances in Wireless Communications (SPAWC) · doi:10.1109/spawc.2019.8815402 · Cited by 60
Stochastic distributed learning with gradient quantization and double-variance reduction
Horváth, S., Kovalev, D. A., Mishchenko, K., Richtárik, P., & Stich, S. U. (2022) · Optimization methods & software · doi:10.1080/10556788.2022.2117355 · Cited by 78
Advancements in Federated Learning: Models, Methods, and Privacy
Chen, H., Wang, H., Long, Q., Jin, D., & Li, Y. (2025) · ACM Computing Surveys · doi:10.1145/3664650 · Cited by 44
SQuARM-SGD: Communication-Efficient Momentum SGD for Decentralized Optimization
Singh, N., Data, D., George, J., & Diggavi, S. N. (2021) · IEEE International Symposium on Information Theory (ISIT) · doi:10.1109/isit45174.2021.9517986 · Cited by 57
GGS: General Gradient Sparsification for Federated Learning in Edge Computing
Li, S., Qi, Q., Wang, J., Sun, H., Li, Y., & Yu, F. R. (2020) · International Conference on Communications · doi:10.1109/icc40277.2020.9148987 · Cited by 66
Metadata
- Authors
- Aji, A. F., & Heafield, K.
- Affiliations
- University of Edinburgh (GB)
- ORCID
- Heafield, Kenneth
- Venue
- Proceedings of the 2017 Conference on Empirical Methods in Natural Language Processing
- Published
- 2017
- Pages
- 440-445
- OpenAlex
- W2606891064
- Cited by
- 585
- References
- 0
- Citations by year
- 2026: 57 · 2025: 89 · 2024: 104 · 2023: 88 · 2022: 79 · 2021: 83 · 2020: 54 · 2019: 24 · 2018: 7
- FWCI
- 10.60
- Type
- conference paper
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- cc-by
- Locations
- Conference on Empirical Methods in Natural Language Processing (EMNLP) (publishedVersion, cc-by)
- arXiv (Cornell University) (submittedVersion)
- Edinburgh Research Explorer (University of Edinburgh) (submittedVersion, cc-by)
- arXiv (Cornell University)
- Funders
- Nvidia
- Alan Turing Institute
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Stochastic Gradient Optimization Techniques
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Advanced Neural Network Applications
- Physical Sciences › Computer Science › Hardware and Architecture › Parallel Computing and Optimization Techniques
- Keywords
- sparse communication, distributed gradient descent, stochastic gradient descent, gradient compression, quantization, neural machine translation, convergence rate, communication efficiency
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
