

Sparse Communication for Distributed Gradient Descent
Open accessThe DOI matches its Crossref record; 2 of the 2 references it cites were found in a registry or an index.
Abstract
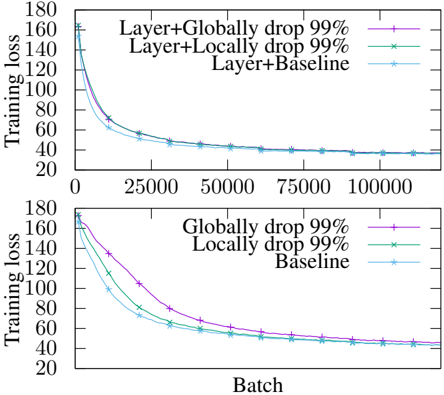
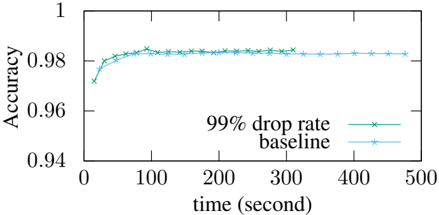
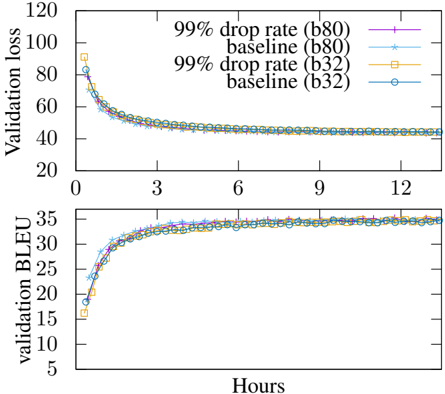
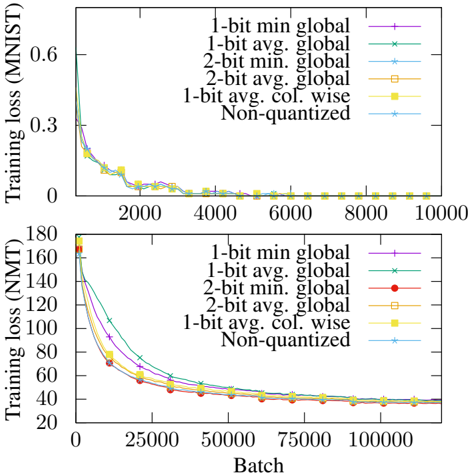
We make distributed stochastic gradient descent faster by exchanging sparse updates instead of dense updates.Gradient updates are positively skewed as most updates are near zero, so we map the 99% smallest updates (by absolute value) to zero then exchange sparse matrices.This method can be combined with quantization to further improve the compression.We explore different configurations and apply them to neural machine translation and MNIST image classification tasks.Most configurations work on MNIST, whereas different configurations reduce convergence rate on the more complex translation task.Our experiments show that we can achieve up to 49% speed up on MNIST and 22% on NMT without damaging the final accuracy or BLEU.
Overview
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
“Sparsification, on the other hand, proposes to only communicate the informative elements of the gradient or model vectors among nodes [128], [129].”
From Edge artificial intelligence for 6g: vision, enabling technologies, and applications (2022) · cites this paper as [129]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
The publisher hasn’t deposited this paper’s reference list.
Research works printed but not linked: 16
- Tolu Alabi, Jeffrey D Blanchard, Bradley Gordon, and Russel Steinbach. 2012. Fast k-selection algorithms for graphics processing units. Journal of Experi- mental Algorithmics (JEA) 17:4-2.
- Dan Alistarh, Jerry Li, Ryota Tomioka, and Milan Vojnovic. 2016. QSGD: randomized quan- tization for communication-optimal stochas- tic gradient descent. CoRR abs/1610.02132. http://arxiv.org/abs/1610.02132. · arXiv
- Trishul M Chilimbi, Yutaka Suzue, Johnson Apacible, and Karthik Kalyanaraman. 2014. Project adam: Building an efficient and scalable deep learning training system. In OSDI. volume 14, pages 571- 582.
- Jeffrey Dean, Greg Corrado, Rajat Monga, Kai Chen, Matthieu Devin, Mark Mao, Andrew Senior, Paul Tucker, Ke Yang, Quoc V Le, et al. 2012. Large scale distributed deep networks. In Advances in neural information processing systems. pages 1223- 1231.
- Nikoli Dryden, Sam Ade Jacobs, Tim Moon, and Brian Van Essen. 2016. Communication quantization for data-parallel training of deep neural networks. In Proceedings of the Workshop on Machine Learn- ing in High Performance Computing Environments. IEEE Press, pages 1-8.
- Marcin Junczys-Dowmunt, Tomasz Dwojak, and Hieu Hoang. 2016. Is neural machine translation ready for deployment? A case study on 30 translation directions. In Program of the 13th International Workshop on Spoken Language Translation (IWSLT 2016).
- Yann LeCun, Léon Bottou, Yoshua Bengio, and Patrick Haffner. 1998. Gradient-based learning applied to document recognition. Proceedings of the IEEE 86(11):2278-2324.
- J. Lei Ba, J. R. Kiros, and G. E. Hinton. 2016. Layer Normalization. ArXiv e-prints .
- Ramón P Ñeco and Mikel L Forcada. 1996. Beyond mealy machines: Learning translators with recurrent neural networks. In Proceedings of the 1996 Inter- national Neural Network Society Annual Meeting. San Diego, California, USA.
- Kishore Papineni, Salim Roukos, Todd Ward, and Wei- Jing Zhu. 2002. BLEU: A method for automatic evalution of machine translation. In Proceedings 40th Annual Meeting of the Association for Com- putational Linguistics. Philadelphia, PA, pages 311- 318.
- Rajat Raina, Anand Madhavan, and Andrew Y Ng. 2009. Large-scale deep unsupervised learning using graphics processors. In Proceedings of the 26th an- nual international conference on machine learning. ACM, pages 873-880.
- Benjamin Recht, Christopher Re, Stephen Wright, and Feng Niu. 2011. Hogwild: A lock-free approach to parallelizing stochastic gradient de- scent. In J. Shawe-Taylor, R. S. Zemel, P. L. Bartlett, F. Pereira, and K. Q. Weinberger, editors, Advances in Neural Information Processing Sys- tems 24, Curran Associates, Inc., pages 693-701. http://papers.nips.cc/paper/4390-hogwild-a-lock- free-approach-to-parallelizing-stochastic-gradient- descent.pdf.
- Frank Seide, Hao Fu, Jasha Droppo, Gang Li, and Dong Yu. 2014. 1-bit stochastic gradi- ent descent and application to data-parallel distributed training of speech DNNs. In Interspeech. https://www.microsoft.com/en- us/research/publication/1-bit-stochastic-gradient- descent-and-application-to-data-parallel- distributed-training-of-speech-dnns/.
- Rico Sennrich, Barry Haddow, and Alexandra Birch. 2016. Edinburgh neural machine translation sys- tems for WMT 16. In Proceedings of the ACL 2016 First Conference on Machine Translation (WMT16).
- Martin Zinkevich, Markus Weimer, Lihong Li, and Alex J Smola. 2010. Parallelized stochastic gradient descent. In Advances in neural information process- ing systems. pages 2595-2603.
- Daniel Zwillinger and Stephen Kokoska. 1999. CRC standard probability and statistics tables and formu- lae. CRC Press.
Cited by
Items 401–500 of 783
Communication Efficient Distributed Newton Method with Fast Convergence Rates
Liu, C., Chen, L., Luo, L., & Lui, J. C. S. (2023) · ACM SIGKDD Conference on Knowledge Discovery and Data Mining (KDD) · doi:10.1145/3580305.3599280 · Cited by 6
Lu, Q., Liu, W., Han, J., & Guo, J. (2018) · Lecture notes in computer science · doi:10.1007/978-3-030-04167-0_10 · Cited by 10
M22: A Communication-Efficient Algorithm for Federated Learning Inspired by Rate-Distortion
Liu, Y., Rini, S., Salehkalaibar, S., & Chen, J. (2023) · IEEE Transactions on Communications · doi:10.1109/tcomm.2023.3327778 · Cited by 6
Distributed Optimization for Over-Parameterized LearningPreprint
Zhang, C., & Li, Q. (2019) · arXiv (Cornell University) · doi:10.48550/arxiv.1906.06205 · Cited by 6
Advancing Privacy-Preserving AI: A Survey on Federated Learning and Its ApplicationsPreprint
Nowell, E., & Gallus, S. (2025) · Preprints.org · doi:10.20944/preprints202501.0685.v1 · Cited by 6
Robust Distributed Swarm Learning for Intelligent IoT
Fan, X., Wang, Y., Huo, Y., & Tian, Z. (2023) · International Conference on Communications · doi:10.1109/icc45041.2023.10278708 · Cited by 5
Beyond Federated Learning for IoT: Efficient Split Learning With Caching and Model Customization
Chawla, M., Gupta, G. R., Gaddam, S., & Wadhwa, M. (2024) · IEEE Internet of Things Journal · doi:10.1109/jiot.2024.3424660 · Cited by 11
Huang, H. M., Xiao, D., Wang, M., Liang, J., Li, M., Chen, L., & Liu, Y. (2025) · Computer Networks · doi:10.1016/j.comnet.2025.111043 · Cited by 6
Tan, J., Zhang, Z., Guo, K., Chang, T., & Quek, T. Q. S. (2025) · IEEE Transactions on Mobile Computing · doi:10.1109/tmc.2025.3627679 · Cited by 6
Improving energy efficiency and scalable computing in Federated Learning
Shahid, A., Ahmad, J., Shafi, I., Arshad, M., Khurshaid, T., Rehman, H. M. R. U., & Ashraf, I. (2025) · Cluster Computing · doi:10.1007/s10586-025-05802-2 · Cited by 5
Find a Scapegoat: Poisoning Membership Inference Attack and Defense to Federated Learning
Mo, W., Li, Z., Fang, M., & Fang, M. (2025) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv51701.2025.00378 · Cited by 8
Distributed Optimization Under Information Constraints: A Survey
Liu, S., Hua, Y., Han, Q., & Xie, L. (2026) · IEEE Transactions on Industrial Informatics · doi:10.1109/tii.2025.3645932 · Cited by 7
Biased Federated Learning Under Wireless Heterogeneity
Abrar, M. F. U., & Michelusi, N. (2026) · IEEE Transactions on Wireless Communications · doi:10.1109/twc.2026.3678173 · Cited by 7
MAC Aware Quantization for Distributed Gradient Descent
Chang, W.-T., & Tandon, R. (2020) · Globecom · doi:10.1109/globecom42002.2020.9322254 · Cited by 7
Communication-Efficient Coded Distributed Multi - Task Learning
Tang, H., Hu, H., Yuan, K., & Wu, Y. (2021) · Globecom · doi:10.1109/globecom46510.2021.9685246 · Cited by 6
Approximate Wireless Communication for Federated Learning
Ma, X., Sun, H., Hu, R. Q., & Qian, Y. (2023) · ACM Workshop on Wireless Security and Machine Learning (WiseML) · doi:10.1145/3586209.3591399 · Cited by 5
Hierarchically Federated Learning in Wireless Networks: D2D Consensus and Inter-Cell Aggregation
Zhang, J., Chen, L., Chen, Y., Chen, X., & Wei, G. (2024) · IEEE Transactions on Machine Learning in Communications and Networking · doi:10.1109/tmlcn.2024.3385355 · Cited by 5
Efficient Federated Learning With Channel Status Awareness and Devices’ Personal Touch
Yu, L., & Ji, T. (2024) · IEEE Transactions on Mobile Computing · doi:10.1109/tmc.2024.3403754 · Cited by 5
Chen, X., Wang, A., Deng, X., & Gui, J. (2024) · IEEE Internet of Things Journal · doi:10.1109/jiot.2024.3462722 · Cited by 6
Privacy Preserving Conversion Modeling in Data Clean Room
Li, K., Chen, X., Leng, L., Xu, J., Sun, J., & Rezaei, B. (2024) · ACM Conference on Recommender Systems (RecSys) · doi:10.1145/3640457.3688054 · Cited by 5
Hierarchical Federated Learning in Inland Waterways via Dataset Distillation and Resource Allocation
Zhao, J., Li, B., Yang, T., & Liu, J. (2024) · IEEE Transactions on Vehicular Technology · doi:10.1109/tvt.2024.3497219 · Cited by 7
Communication-efficient distributed learning with Local Immediate Error Compensation
Cheng, Y., Shen, L., Xu, L., Qian, X., Wu, S., Zhou, Y., Zhang, T., Tao, D., & Chen, E. (2025) · Neural Networks · doi:10.1016/j.neunet.2025.107471 · Cited by 7
Over-the-air Learning Rate Optimization for Federated Learning
Xu, C., Liu, S., Huang, Y., Huang, C., & Zhang, Z. (2021) · IEEE International Conference on Communications workshops · doi:10.1109/iccworkshops50388.2021.9473663 · Cited by 6
A Federated Learning Method Based on Blockchain and Cluster Training
Li, Y., Yan, Y., Liu, Z., Yin, C., Zhang, J., & Zhang, Z. (2023) · Electronics · doi:10.3390/electronics12194014 · Cited by 7
AggTree: A Routing Tree With In-Network Aggregation for Distributed Training
Nie, J., & Wu, W. (2023) · IEEE International Performance, Computing, and Communications Conference · doi:10.1109/ipccc59175.2023.10253874 · Cited by 5
GQFedWAvg: Optimization-Based Quantized Federated Learning in General Edge Computing Systems
Li, Y., Cui, Y., & Lau, V. K. N. (2023) · IEEE Transactions on Wireless Communications · doi:10.1109/twc.2023.3335302 · Cited by 7
Wu, D., Yang, W., Deng, C., Zou, X., Li, S., & Xia, W. (2023) · IEEE International Conference on Computer Design: VLSI in Computers and Processors (ICCD) · doi:10.1109/iccd58817.2023.00096 · Cited by 7
Indirect Stochastic Gradient Quantization and Its Application in Distributed Deep Learning
Abdi, A., & Fekri, F. (2020) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v34i04.5707 · Cited by 5
Efficient Communication Scheduling for Parameter Synchronization of DML in Data Center Networks
Li, S., Qin, Y., Jiang, Z., & Yang, W. (2021) · IEEE Transactions on Network Science and Engineering · doi:10.1109/tnse.2021.3068155 · Cited by 7
Channel-Adaptive Quantization for Wireless Federated Learning
Lin, X., Liu, Y., & Chen, F. (2021) · IEEE/CIC International Conference on Communications in China (ICCC) · doi:10.1109/iccc52777.2021.9580257 · Cited by 6
Adaptive synchronous strategy for distributed machine learning
Tan, M., Liu, W., Luo, J., Chen, H., & Guo, Z. (2022) · International Journal of Intelligent Systems · doi:10.1002/int.23060 · Cited by 5
OptQuant: Distributed training of neural networks with optimized quantization mechanisms
Li, H., Zheng, S., Chen, W., Ma, Z.-M., & Liu, T. (2019) · Neurocomputing · doi:10.1016/j.neucom.2019.02.049 · Cited by 6
Adaptive Periodic Averaging: A Practical Approach to Reducing Communication in Distributed LearningPreprint
Jiang, P., & Agrawal, G. (2020) · arXiv (Cornell University) · doi:10.48550/arxiv.2007.06134 · Cited by 5
MARINA-P: Superior Performance in Non-smooth Federated Optimization with Adaptive StepsizesPreprint
Sokolov, I., & Richtárik, P. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2412.17082 · Cited by 5
Trajectory-Aware Information Matching for Multi-Step Gradient Inversion in Federated LearningPreprint
Xia, L., Yu, J., Liu, Z., Huang, S., Tang, W., & Liu, X. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2509.22082 · Cited by 5
Abdellatif, A. A., Mhaisen, N., Mohamed, A., Erbad, A., Guizani, M., Dawy, Z., & Nasreddine, W. (2022) · Future Generation Computer Systems · doi:10.1016/j.future.2021.10.016 · Cited by 4
FedMQ+: Towards efficient heterogeneous federated learning with multi-grained quantization
Mei, C., Wang, H., Yuan, Y., Lǚ, J., Cai, X., Yu, D., & Zhao, M. (2025) · Journal of Systems Architecture · doi:10.1016/j.sysarc.2025.103460 · Cited by 4
Wang, J., Liang, B., Dong, M., Boudreau, G., & Afana, A. (2025) · IEEE Transactions on Networking · doi:10.1109/ton.2025.3583308 · Cited by 4
Ming, Z., Hu, Y., Zheng, X., Zhou, W., & Feng, D. (2025) · ACM International Symposium on High-Performance Parallel and Distributed Computing (HPDC) · doi:10.1145/3731545.3731581 · Cited by 4
Gupta, A., Ritwik, & Chaurasiya, V. K. (2025) · IEEE Transactions on Green Communications and Networking · doi:10.1109/tgcn.2025.3624654 · Cited by 6
GRACE-FL: Green Resource-Aware Communication-Efficient Federated Learning
Thakur, D., Guzzo, A., Fortino, G., & Das, S. K. (2025) · IEEE Transactions on Artificial Intelligence · doi:10.1109/tai.2025.3636489 · Cited by 6
TFD-Video: Threshold-Aware Federated Deepfake Detection for Video Forensics
Al-Fehani, M., Albaseer, A. M., & Al-Kuwari, S. (2026) · IEEE Access · doi:10.1109/access.2026.3660914 · Cited by 4
Adaptive Step-Size Methods for Compressed SGD With Memory Feedback
Subramaniam, A. M., Magesh, A., & Veeravalli, V. V. (2024) · IEEE Transactions on Signal Processing · doi:10.1109/tsp.2024.3385577 · Cited by 4
Song, J., Luo, J., Lu, R., Xie, S., Chen, B., & Wang, Z. (2024) · Lecture notes in computer science · doi:10.1007/978-3-031-69583-4_14 · Cited by 6
Lightweight Decentralized Federated Learning Framework for Heterogeneous Edge Systems
Yang, C., Wang, J., Ding, Y., Li, C., Liang, H., & Liu, Z. (2024) · IEEE International Conference on Web Services (ICWS) · doi:10.1109/icws62655.2024.00035 · Cited by 4
Novel Gradient Sparsification Algorithm via Bayesian Inference
Bereyhi, A., Liang, B., Boudreau, G., & Afana, A. (2024) · Machine learning for signal processing ... · doi:10.1109/mlsp58920.2024.10734719 · Cited by 7
Pan, K., Gong, M., Feng, K., & Li, H. (2024) · IEEE Internet of Things Journal · doi:10.1109/jiot.2024.3508804 · Cited by 4
Zheng, S., Zhang, L., Dong, Y., Li, X., Wang, X., & Chen, X. (2025) · IEEE Internet of Things Journal · doi:10.1109/jiot.2025.3591626 · Cited by 5
FedEFsz: Fair Cross-Silo Federated Learning System With Error-Bounded Lossy Compression
Zhang, Z., Di, S., Liu, B., Ji, Z., Li, G., Lu, X., Zhou, A. C., Alharthi, K. A., & Cao, J. (2025) · IEEE Transactions on Parallel and Distributed Systems · doi:10.1109/tpds.2025.3593896 · Cited by 7
Trustworthiness of Stochastic Gradient Descent in Distributed Learning
Li, H., Wu, C., Chadli, M., Mammar, S., & Bouvry, P. (2025) · European Control Conference (ECC) · doi:10.23919/ecc65951.2025.11187286 · Cited by 4
Adaptive Step-Size Methods for Compressed SGD
Subramaniam, A. M., Magesh, A., & Veeravalli, V. V. (2023) · IEEE International Conference on Acoustics Speech and Signal Processing · doi:10.1109/icassp49357.2023.10096611 · Cited by 4
Qiao, J., Shen, S., Chen, S., Zhang, X., Lan, T., Cheng, X., & Yu, D. (2024) · IEEE/ACM Transactions on Networking · doi:10.1109/tnet.2024.3438462 · Cited by 4
Ni, Y. (2025) · Theoretical and Natural Science · doi:10.54254/2753-8818/2025.19943 · Cited by 4
Zou, T., Liu, Y., Ye, X., Ouyang, Y., & Zhang, Y.-Q. (2024) · IEEE International Conference on Big Data (BigData) · doi:10.1109/bigdata62323.2024.10825545 · Cited by 6
Tsouvalas, V., Mohammadi, S., Balador, A., Özçelebi, T., Flammini, F., & Meratnia, N. (2025) · Pervasive and Mobile Computing · doi:10.1016/j.pmcj.2025.102021 · Cited by 7
PFFLoRA: Personalized Fourier LoRA Fine-Tuning of Federated Large Language Models
Li, K., Lu, Z., & Yu, S. (2024) · IEEE International Conference on Frontiers Technology of Information and Computer (ICFTIC) · doi:10.1109/icftic64248.2024.10912848 · Cited by 4
Convergence-Aware Neural Network Training
Oh, H., Yu, Y., Ryu, G., Ahn, G., Jeong, Y., Park, Y., & Seo, J. (2020) · ACM/IEEE Design Automation Conference (DAC) · doi:10.1109/dac18072.2020.9218518 · Cited by 4
HGC: Hybrid Gradient Compression in Distributed Deep Learning
Hu, K., Wu, C., & Zhu, E. (2021) · Communications in computer and information science · doi:10.1007/978-3-030-78615-1_2 · Cited by 5
Federated Optimization Based on Compression and Event-triggered Communication
Gao, H., Wang, L., Zhu, J., Zhang, M., & Wu, Q. (2021) · Youth Academic Annual Conference of Chinese Association of Automation (YAC) · doi:10.1109/yac53711.2021.9486477 · Cited by 4
Compressing Gradients by Exploiting Temporal Correlation in Momentum-SGD
Adikari, T. B., & Draper, S. C. (2021) · IEEE Journal on Selected Areas in Information Theory · doi:10.1109/jsait.2021.3103494 · Cited by 6
FWC: Fitting Weight Compression Method for Reducing Communication Traffic for Federated Learning
Jiang, H., Yan, K., Huang, C., Li, Q., & Xiao, S. (2022) · IEEE Symposium on Reliable Distributed Systems (SRDS) · doi:10.1109/srds55811.2022.00025 · Cited by 4
Su, J., Wang, X., Chen, X., & Cheng, R. (2023) · IEEE International Workshop on Signal Processing Advances in Wireless Communications (SPAWC) · doi:10.1109/spawc53906.2023.10304559 · Cited by 4
Robust Federated Learning Under Worst-Case Model
Ang, F., Chen, L., & Wang, W. (2020) · IEEE Wireless Communications and Networking Conference · doi:10.1109/wcnc45663.2020.9120713 · Cited by 4
Huo, Z., & Huang, H. (2019) · arXiv (Cornell University) · doi:10.48550/arxiv.1910.04235 · Cited by 4
Distributed Sparse SGD with Majority VotingPreprint
Özfatura, K., Özfatura, E., & Gündüz, D. (2020) · arXiv (Cornell University) · doi:10.48550/arxiv.2011.06495 · Cited by 4
Linear Regression over Networks with Communication Guarantees
Gatsis, K. (2021) · Oxford University Research Archive (ORA) (University of Oxford) · doi:10.48550/arxiv.2103.04140 · Cited by 4
Linear Stochastic Bandits over a Bit-Constrained ChannelPreprint
Mitra, A., Hassani, H., & Pappas, G. J. (2022) · arXiv (Cornell University) · doi:10.48550/arxiv.2203.01198 · Cited by 4
Yan, Y., Chen, J., Chen, P., Cui, X., Lu, S., & Xu, Y. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2302.14252 · Cited by 12
Pre-Pruning and Gradient-Dropping Improve Differentially Private Image ClassificationPreprint
Adamczewski, K., He, Y., & Park, M. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2306.11754 · Cited by 4
Federated Fine-Tuning of Foundation Models via Probabilistic MaskingPreprint
Tsouvalas, V., Asano, Y. M., & Saeed, A. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2311.17299 · Cited by 4
QLESS: A Quantized Approach for Data Valuation and Selection in Large Language Model Fine-TuningPreprint
Ananta, M., Adilazuarda, M. F., Zuhri, Z. M. K., Purwarianti, A., & Aji, A. F. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2502.01703 · Cited by 4
Self-citationSingh, S., & Kumar, S. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2502.07634 · Cited by 5
Xie, W., Wang, Z., Ma, J., Li, D., & Li, Y. (2024) · IEEE Transactions on Geoscience and Remote Sensing · doi:10.1109/tgrs.2024.3394501 · Cited by 5
Sparse Incremental Aggregation in Satellite Federated Learning
Razmi, N., Mukherjee, S., Matthiesen, B., Dekorsy, A., & Popovski, P. (2025) · International ITG Conference on Systems, Communications and Coding (SCC) · doi:10.1109/ieeeconf62907.2025.10949091 · Cited by 3
Guan, F., Hou, X., Wang, X., Wang, J., Du, J., & Ren, Y. (2025) · International Conference on Communications · doi:10.1109/icc52391.2025.11161857 · Cited by 3
FedSTEP: Asynchronous and Staleness-Aware Personalization for Efficient Federated Learning
Yan, G., Li, J., & Du, W. (2025) · ACM International Conference on Information and Knowledge Management (CIKM) · doi:10.1145/3746252.3761166 · Cited by 4
Yao, C., Liu, F., Hu, Y., Liu, Z., Zheng, X., & Zhou, W. (2025) · International Conference for High Performance Computing, Networking, Storage and Analysis (SC) · doi:10.1145/3712285.3759891 · Cited by 7
Communication-Efficient Federated Learning for Edge Computing With Gradient Leakage Defense
Yang, X., Cui, H., Dai, F., Xie, B., He, Y., & Guizani, M. (2025) · IEEE Journal on Selected Areas in Communications · doi:10.1109/jsac.2025.3638286 · Cited by 3
Johnson, F., Elugbadebo, O., Olugbenga, O., Victor, A. F., & Folashade, A. A. (2025) · Artificial Intelligence and Applications · doi:10.47852/bonviewaia52026275 · Cited by 5
γ-FedHT: Stepsize-Aware Hard-Threshold Gradient Compression in Federated Learning
Lu, R., Jiang, Y., Zhang, J., Li, C., Zhu, Y., Chen, B., & Wang, Z. (2025) · IEEE Conference on Computer Communications (INFOCOM) · doi:10.1109/infocom55648.2025.11044558 · Cited by 3
Zhou, S., Wang, Y., Wang, L., Chen, L., & Wang, Y. B. (2025) · IEEE Transactions on Industrial Informatics · doi:10.1109/tii.2025.3641285 · Cited by 3
A Layer-Based Sparsification Method For Distributed DNN Training
Hu, Y., Ye, Q., Zhang, Z., & Lv, J. (2022) · IEEE International Conference on High Performance Computing and Communications; IEEE International Conference on Smart City; IEEE International Conference on Data Science and Systems (HPCC/SmartCity/DSS) · doi:10.1109/hpcc-dss-smartcity-dependsys57074.2022.00209 · Cited by 3
FedTM: Memory and Communication Efficient Federated Learning with Tsetlin Machine
How, S. S. Q., Chauhan, J., Merrett, G. V., & Hare, J. S. (2023) · International Symposium on the Tsetlin Machine (ISTM) · doi:10.1109/istm58889.2023.10454982 · Cited by 6
Liu, Y., Chang, S., & Liu, Y. (2024) · IEEE Transactions on Big Data · doi:10.1109/tbdata.2024.3403393 · Cited by 4
FedBF16-Dynamic: Communication-Efficient Federated Learning with Adaptive Transmission
Tseng, F., & Huang, Y.-H. (2024) · IEEE Conference on Computer Communications Workshops (INFOCOM WKSHPS) · doi:10.1109/infocomwkshps61880.2024.10620860 · Cited by 3
Wang, J., Dong, M., Liang, B., Boudreau, G., & Afana, A. (2025) · IEEE Transactions on Networking · doi:10.1109/ton.2025.3530460 · Cited by 4
Pan, H., Cui, P., Li, Z., Jia, R., Zhang, P., Zhang, L., Yang, Y., Wu, J., Lauren, M., & Xie, G. (2024) · IEEE International Conference on Network Protocols (ICNP) · doi:10.1109/icnp61940.2024.10858501 · Cited by 3
E-3SFC: Communication-Efficient Federated Learning With Double-Way Features Synthesizing
Zhou, Y., Tian, Y., Shi, M., Li, Y., Sun, Y., Ye, Q., & Lv, J. (2025) · IEEE Transactions on Neural Networks and Learning Systems · doi:10.1109/tnnls.2025.3539869 · Cited by 7
CGGL: A client-side generative gradient leakage attack with double diffusion prior
Pu, B., Liu, Z., Wu, L., Xu, K., Liang, B., He, Z., Ma, B., & Zhao, L. (2025) · Information Fusion · doi:10.1016/j.inffus.2025.103292 · Cited by 3
TS-Inverse: A Gradient Inversion Attack Tailored for Federated Time Series Forecasting Models
Meijer, C., Huang, J., Sharma, S., Lazovik, E., & Chen, L. Y. (2025) · IEEE Conference on Secure and Trustworthy Machine Learning (SaTML) · doi:10.1109/satml64287.2025.00014 · Cited by 5
DictPFL: Efficient and Private Federated Learning on Encrypted Gradients
Xue, J., Kumar, M., Shang, Y., Gao, S., Ning, R., Zheng, M., Jiang, X., & Lou, Q. (2025) · neural information processing systems · doi:10.52202/085713-4001 · Cited by 6
O(1) Communication for Distributed SGD through Two-Level Gradient Averaging
Bhattacharya, S., Yu, W., Chowdhury, F. T., & Mohror, K. (2021) · IEEE International Conference on Cluster Computing (CLUSTER) · doi:10.1109/cluster48925.2021.00054 · Cited by 3
Communication-efficient Federated Learning via Quantized Clipped SGD
Jia, N., Qu, Z., & Ye, B. (2021) · Lecture notes in computer science · doi:10.1007/978-3-030-85928-2_44 · Cited by 3
Migrating Models: A Decentralized View on Federated Learning
Kiss, P. T., & Horváth, T. (2021) · Communications in computer and information science · doi:10.1007/978-3-030-93736-2_15 · Cited by 4
Efficient DNN training based on backpropagation parallelization
Xiao, D., Yang, C., & Wu, W. (2022) · Computing · doi:10.1007/s00607-022-01094-1 · Cited by 3
Layer-wise Top-$k$ Gradient Sparsification for Distributed Deep Learning
Li, G. (2023) · International Conference on Neural Networks, Information and Communication Engineering (NNICE) · doi:10.1109/nnice58320.2023.10105718 · Cited by 3
Federated Learning Scheme Based on Gradient Compression and Local Differential Privacy
Zhao, L., Hu, S., & Shi, Z. (2023) · IEEE International Conference on Control, Electronics and Computer Technology (ICCECT) · doi:10.1109/iccect57938.2023.10140219 · Cited by 3
Research on Transformer Fault Diagnosis Method Based on Deep Learning Algorithm Optimization
Fan, Y. (2023) · International Conference on Electronics and Devices, Computational Science (ICEDCS) · doi:10.1109/icedcs60513.2023.00056 · Cited by 3
Two-Stage Adaptive Gradient Quantization in Federated Learning
Chen, L., Wu, Z., & Ji, Y. (2023) · IEEE International Conference on Network Infrastructure and Digital Content (IC-NIDC) · doi:10.1109/ic-nidc59918.2023.10390881 · Cited by 3
DISCO: Distributed Inference with Sparse Communications
Qin, M., Sun, C., Hofmann, J. A., & Vučinić, D. (2024) · IEEE Winter Conference on Applications of Computer Vision · doi:10.1109/wacv57701.2024.00242 · Cited by 6
Metadata
- Authors
- Aji, A. F., & Heafield, K.
- Affiliations
- University of Edinburgh (GB)
- ORCID
- Heafield, Kenneth
- Venue
- Proceedings of the 2017 Conference on Empirical Methods in Natural Language Processing
- Published
- 2017
- Pages
- 440-445
- OpenAlex
- W2606891064
- Cited by
- 585
- References
- 0
- Citations by year
- 2026: 57 · 2025: 89 · 2024: 104 · 2023: 88 · 2022: 79 · 2021: 83 · 2020: 54 · 2019: 24 · 2018: 7
- FWCI
- 10.60
- Type
- conference paper
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- cc-by
- Locations
- Conference on Empirical Methods in Natural Language Processing (EMNLP) (publishedVersion, cc-by)
- arXiv (Cornell University) (submittedVersion)
- Edinburgh Research Explorer (University of Edinburgh) (submittedVersion, cc-by)
- arXiv (Cornell University)
- Funders
- Nvidia
- Alan Turing Institute
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Stochastic Gradient Optimization Techniques
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Advanced Neural Network Applications
- Physical Sciences › Computer Science › Hardware and Architecture › Parallel Computing and Optimization Techniques
- Keywords
- sparse communication, distributed gradient descent, stochastic gradient descent, gradient compression, quantization, neural machine translation, convergence rate, communication efficiency
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
