

The DOI matches its Crossref record; 45 of the 45 references it cites were found in a registry or an index.
Towards a Better Metric for Evaluating Question Generation Systems
Open accessAbstract
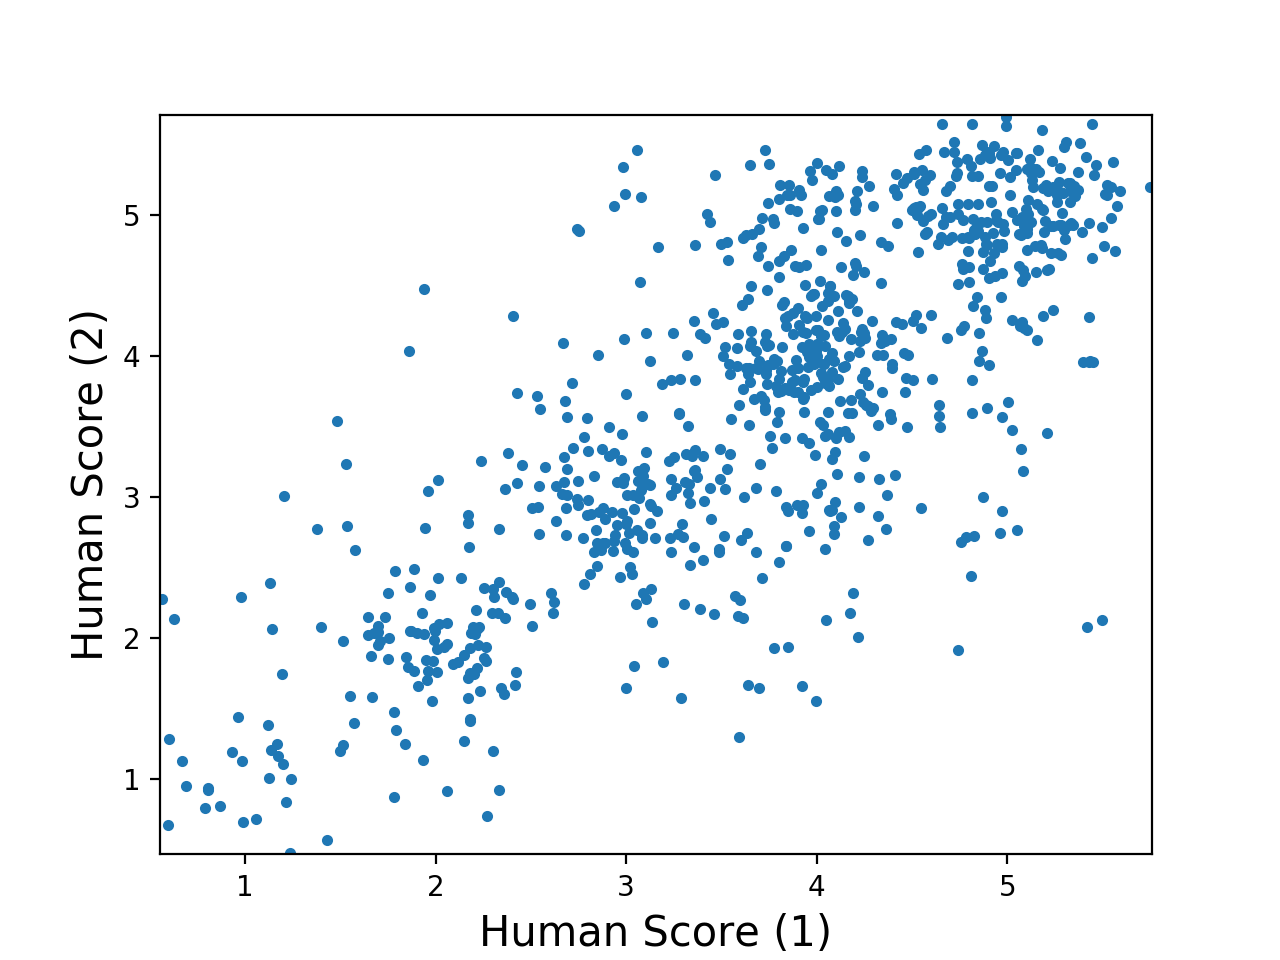
There has always been criticism for using ngram based similarity metrics, such as BLEU, NIST, etc, for evaluating the performance of NLG systems.However, these metrics continue to remain popular and are recently being used for evaluating the performance of systems which automatically generate questions from documents, knowledge graphs, images, etc.Given the rising interest in such automatic question generation (AQG) systems, it is important to objectively examine whether these metrics are suitable for this task.In particular, it is important to verify whether such metrics used for evaluating AQG systems focus on answerability of the generated question by preferring questions which contain all relevant information such as question type (Wh-types), entities, relations, etc.In this work, we show that current automatic evaluation metrics based on n-gram similarity do not always correlate well with human judgments about answerability of a question.To alleviate this problem and as a first step towards better evaluation metrics for AQG, we introduce a scoring function to capture answerability and show that when this scoring function is integrated with existing metrics, they correlate significantly better with human judgments.The scripts and data developed as a part of this work are made publicly available.1
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The cited source doesn’t support the claim as written.
In the citing paper
“1) focusing only on specific dimensions like answerability;”
From QGEval: Benchmarking Multi-dimensional Evaluation for Question Generation (2024) · cites this paper as Nema and Khapra, 2018
Checked by a reasoning model — may be wrong.
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Automatic evaluation of QG is still dominated by reference-based metrics such as BLEU (Papineni et al., 2002) and Q-Metric”
From QGEval: Benchmarking Multi-dimensional Evaluation for Question Generation (2024) · cites this paper as Nema and Khapra, 2018
Experimental — accuracy not yet measuredThe cited source says what the claim attributes to it.
In the citing paper
“Q-BLEU is a variant of BLEU with a higher weight for matching entities and has higher correlation with human judgment for question generation than standard metrics.”
From Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks (2020) · cites this paper as [42]
In the citing paper
“One notable contribution is made in [105], where the authors first use the answerability of a question through human evaluation to modify the existing automatic evaluation metrics to include the influence of relevant words, question types, function words, and named entities.”
From Automatic question generation: a review of methodologies, datasets, evaluation metrics, and applications (2023) · cites this paper as [105]
In the citing paper
“They further proved that their proposed metrics had a better correlation with the human evaluation scores.”
From Automatic question generation: a review of methodologies, datasets, evaluation metrics, and applications (2023) · cites this paper as [105]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
BLEU: a method for automatic evaluation of machine translation
Papineni, K., Roukos, S., Ward, T., & Zhu, W.-J. (2001) · Proceedings of the 40th Annual Meeting on Association for Computational Linguistics - ACL '02 · doi:10.3115/1073083.1073135 · Cited by 21,344
Interrater reliability: The kappa statistic
McHugh, M. L. (2012) · Biochemia Medica · doi:10.11613/bm.2012.031 · Cited by 19,877
(2004) · Cited by 9,718
Weighted kappa: nominal scale agreement provision for scaled disagreement or partial credit
Cohen, J. (1968) · Psychological Bulletin · doi:10.1037/h0026256 · Cited by 8,736
SQuAD: 100,000+ Questions for Machine Comprehension of Text
Rajpurkar, P., Zhang, J., Lopyrev, K., & Liang, P. (2016) · Proceedings of the 2016 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/d16-1264 · Cited by 6,208
VQA: Visual Question Answering
Antol, S., Agrawal, A., Lu, J., Mitchell, M., Batra, D., Zitnick, C. L., & Parikh, D. (2015) · 2015 IEEE International Conference on Computer Vision (ICCV) · doi:10.1109/iccv.2015.279 · Cited by 4,487
Loper, E., & Bird, S. (2002) · doi:10.3115/1118108.1118117 · Cited by 3,323
MS MARCO: A Human Generated MAchine Reading COmprehension Dataset
Bajaj, P., Campos, D., Craswell, N., Deng, L., Gao, J., Liu, X., Majumder, R., McNamara, A., Mitra, B., Nguyen, T., et al. (2016) · arXiv · doi:10.48550/arxiv.1611.09268 · Cited by 2,473
NLTK: The Natural Language ToolkitPreprint
Loper, E., & Bird, S. (2002) · arXiv (Cornell University) · doi:10.48550/arxiv.cs/0205028 · Cited by 1,893
CLEVR: A Diagnostic Dataset for Compositional Language and Elementary Visual Reasoning
Johnson, J., Hariharan, B., van der Maaten, L., Fei-Fei, L., Zitnick, C. L., & Girshick, R. (2017) · 2017 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2017.215 · Cited by 1,781
Research works printed but not linked: 3
- Stanislaw Antol, Aishwarya Agrawal, Jiasen Lu, Mar- garet Mitchell, Dhruv Batra, C. Lawrence Zitnick, and Devi Parikh. 2015. VQA: Visual Question An- swering. In International Conference on Computer Vision (ICCV).
- Alexander H. Miller, Adam Fisch, Jesse Dodge, Amir- Hossein Karimi, Antoine Bordes, and Jason We- ston. 2016. Key-value memory networks for directly reading documents. In EMNLP. The Association for Computational Linguistics, pages 1400-1409.
- Ananthakrishnan R, Pushpak Bhattacharyya, M Sasikumar, and Ritesh M Shah. 2007. Some issues in automatic evaluation of english-hindi mt: More blues for bleu. In International Conference on Natural Language Processing.
Cited by
Sorted by citations
Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks
Lewis, P., Perez, E., Piktus, A., Petroni, F., Karpukhin, V., Goyal, N., Küttler, H., Lewis, M., Yih, W.-T., Rocktäschel, T., et al. (2020) · arXiv · doi:10.48550/arxiv.2005.11401 · Cited by 3,101
A Survey of Evaluation Metrics Used for NLG Systems
Sai, A. B., Mohankumar, A. K., & Khapra, M. M. (2023) · ACM Computing Surveys · doi:10.1145/3485766 · Cited by 235
Self-citationHandling Divergent Reference Texts when Evaluating Table-to-Text Generation
Dhingra, B., Faruqui, M., Parikh, A., Chang, M.-W., Das, D., & Cohen, W. (2019) · Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics · doi:10.18653/v1/p19-1483 · Cited by 150
Mulla, N., & Gharpure, P. (2023) · Progress in Artificial Intelligence · doi:10.1007/s13748-023-00295-9 · Cited by 132
MCQGen: A Large Language Model-Driven MCQ Generator for Personalized Learning
Hang, C. N., Tan, C. W., & Yu, P.-D. (2024) · IEEE Access · doi:10.1109/access.2024.3420709 · Cited by 130
Metadata
- Authors
- Nema, P., & Khapra, M. M.
- Affiliations
- Indian Institute of Technology Madras (IN)
- ORCID
- Khapra, Mitesh M.
- Venue
- Proceedings of the 2018 Conference on Empirical Methods in Natural Language Processing
- Published
- 2018
- Pages
- 3950-3959
- OpenAlex
- W2888812214
- Cited by
- 106
- References
- 43
- Citations by year
- 2026: 4 · 2025: 6 · 2024: 18 · 2023: 18 · 2022: 19 · 2021: 18 · 2020: 11 · 2019: 12
- FWCI
- 4.19
- Type
- conference paper
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- cc-by
- Locations
- Conference on Empirical Methods in Natural Language Processing (EMNLP) (publishedVersion, cc-by)
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Natural Language Processing Techniques
- Physical Sciences › Computer Science › Artificial Intelligence › Topic Modeling
- Physical Sciences › Computer Science › Artificial Intelligence › Speech and dialogue systems
- Keywords
- automatic question generation, evaluation metrics, n-gram similarity, BLEU, NIST, answerability, scoring functions, human judgment correlation, natural language generation evaluation
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
