

The DOI matches its Crossref record; 39 of the 42 references it cites were found in a registry or an index.
SemEval-2018 Task 1: Affect in Tweets
Open accessAbstract
We present the SemEval-2018 Task 1: Affect in Tweets, which includes an array of subtasks on inferring the affectual state of a person from their tweet.For each task, we created labeled data from English, Arabic, and Spanish tweets.The individual tasks are: 1. emotion intensity regression, 2. emotion intensity ordinal classification, 3. valence (sentiment) regression, 4. valence ordinal classification, and 5. emotion classification.Seventy-five teams (about 200 team members) participated in the shared task.We summarize the methods, resources, and tools used by the participating teams, with a focus on the techniques and resources that are particularly useful.We also analyze systems for consistent bias towards a particular race or gender.The data is made freely available to further improve our understanding of how people convey emotions through language.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
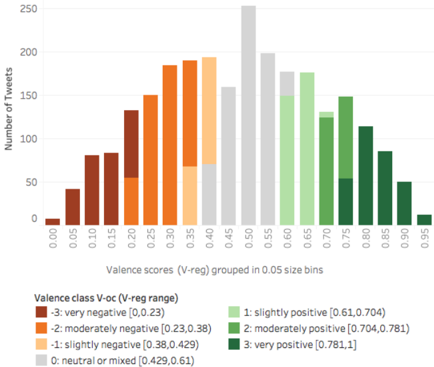
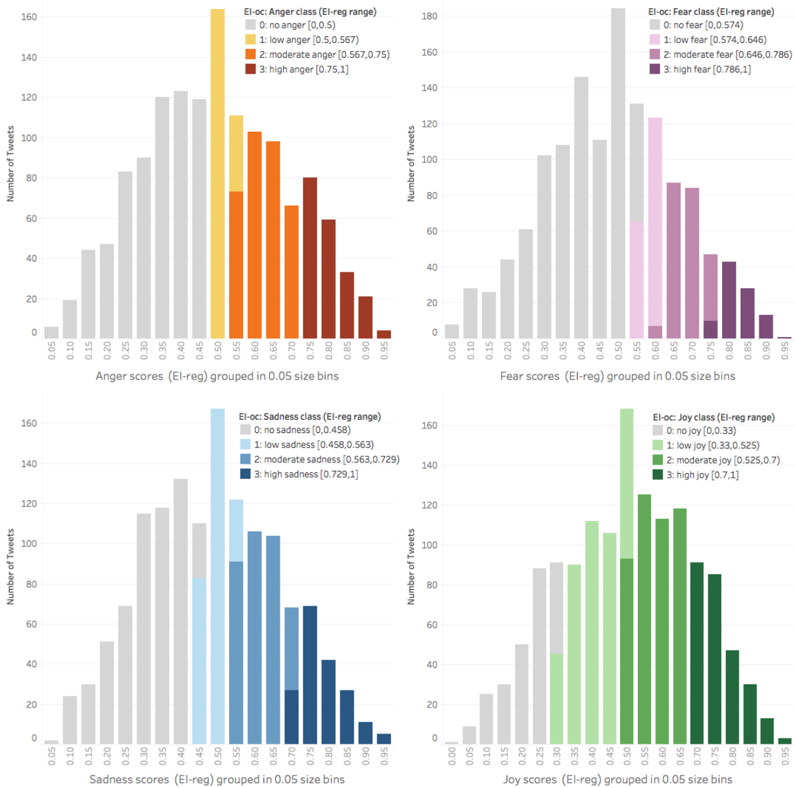
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“However, most existing models for MLEC do not capture emotion-specific associations that can be useful for the classification of emotions [7], [9], [10].”
From Emotion Classification With Visibility Graphs (2025) · cites this paper as [9]
Experimental — accuracy not yet measured
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
LeCun, Y., Bengio, Y., & Hinton, G. (2015) · Nature · doi:10.1038/nature14539 · Cited by 84,126
Russell, J. A. (1980) · Journal of Personality and Social Psychology · doi:10.1037/h0077714 · Cited by 16,334
An argument for basic emotions
Ekman, P. (1992) · Cognition and Emotion · doi:10.1080/02699939208411068 · Cited by 9,646
Mining and summarizing customer reviews
Hu, M., & Liu, B. (2004) · Proceedings of the tenth ACM SIGKDD international conference on Knowledge discovery and data mining · doi:10.1145/1014052.1014073 · Cited by 7,793
Core affect and the psychological construction of emotion.
Russell, J. A. (2003) · Psychological Review · doi:10.1037/0033-295x.110.1.145 · Cited by 6,113
CROWDSOURCING A WORD–EMOTION ASSOCIATION LEXICON
Mohammad, S. M., & Turney, P. D. (2012) · Computational Intelligence · doi:10.1111/j.1467-8640.2012.00460.x · Cited by 2,901
Self-citationFrijda, N. H. (1988) · American Psychologist · doi:10.1037//0003-066x.43.5.349 · Cited by 2,724
Fair prediction with disparate impact: a study of bias in recidivism prediction instruments
Chouldechova, A. (2017) · Big Data · doi:10.1089/big.2016.0047 · Cited by 2,159
The theory of the estimation of test reliability
Kuder, G. F., & Richardson, M. W. (1937) · Psychometrika · doi:10.1007/bf02288391 · Cited by 1,953
Man is to Computer Programmer as Woman is to Homemaker? Debiasing Word Embeddings
Bolukbasi, T., Chang, K.-W., Zou, J., Saligrama, V., & Kalai, A. (2016) · arXiv · doi:10.48550/arxiv.1607.06520 · Cited by 1,615
Research works printed but not linked: 1
- W Parrot. 2001. Emotions in Social Psychology. Psy- chology Press.
Cited by
Sorted by citations
Transformer models for text-based emotion detection: a review of BERT-based approaches
Acheampong, F. A., Nunoo‐Mensah, H., & Chen, W. (2021) · Artificial Intelligence Review · doi:10.1007/s10462-021-09958-2 · Cited by 720
Obtaining Reliable Human Ratings of Valence, Arousal, and Dominance for 20,000 English Words
Mohammad, S. M. (2018) · Annual Meeting of the Association for Computational Linguistics · doi:10.18653/v1/p18-1017 · Cited by 703
Self-citationARBERT & MARBERT: Deep Bidirectional Transformers for Arabic
Abdul-Mageed, M., Elmadany, A., & Nagoudi, E. M. B. (2021) · Annual Meeting of the Association for Computational Linguistics · doi:10.18653/v1/2021.acl-long.551 · Cited by 459
Examining Gender and Race Bias in Two Hundred Sentiment Analysis Systems
Kiritchenko, S., & Mohammad, S. (2018) · Proceedings of the Seventh Joint Conference on Lexical and Computational Semantics · doi:10.18653/v1/s18-2005 · Cited by 384
Self-citationGarcia, K., & Berton, L. (2020) · Applied Soft Computing · doi:10.1016/j.asoc.2020.107057 · Cited by 390
Metadata
- Authors
- Mohammad, S., Bravo-Marquez, F., Salameh, M., & Kiritchenko, S.
- Affiliations
- Carnegie Mellon University Qatar (QA)
- National Research Council Canada (CA)
- Venue
- Proceedings of The 12th International Workshop on Semantic Evaluation
- Published
- 2018
- Pages
- 1-17
- OpenAlex
- W2805744755
- Cited by
- 746
- References
- 42
- Citations by year
- 2026: 49 · 2025: 64 · 2024: 85 · 2023: 104 · 2022: 98 · 2021: 107 · 2020: 87 · 2019: 81 · 2018: 70
- FWCI
- 35.21
- Type
- conference paper
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- cc-by
- Locations
- International Workshop on Semantic Evaluation (SemEval) (publishedVersion, cc-by)
- NPARC (submittedVersion, cc-by)
- INFM-OAR (INFN Catania) (submittedVersion, other-oa)
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Sentiment Analysis and Opinion Mining
- Physical Sciences › Computer Science › Artificial Intelligence › Emotion and Mood Recognition
- Social Sciences › Psychology › Social Psychology › Mental Health via Writing
- Keywords
- affective computing, emotion recognition, tweets, social media text, sentiment analysis, emotion classification, shared task, Arabic tweets, Spanish tweets, English-language tweets, algorithmic bias, gender bias, racial bias
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
