

A Comprehensive Study of Activity Recognition Using Accelerometers
Open accessPublished version of a preprint
The DOI matches its Crossref record; 98 of the 99 references it cites were found in a registry or an index, and 1 are not checked yet.
Abstract
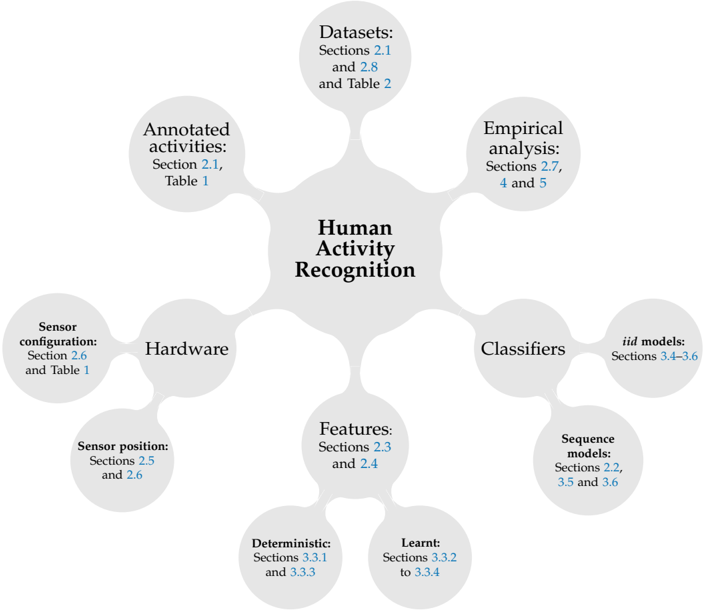
This paper serves as a survey and empirical evaluation of the state-of-the-art in activity recognition methods using accelerometers. The paper is particularly focused on long-term activity recognition in real-world settings. In these environments, data collection is not a trivial matter; thus, there are performance trade-offs between prediction accuracy, which is not the sole system objective, and keeping the maintenance overhead at minimum levels. We examine research that has focused on the selection of activities, the features that are extracted from the accelerometer data, the segmentation of the time-series data, the locations of accelerometers, the selection and configuration trade-offs, the test/retest reliability, and the generalisation performance. Furthermore, we study these questions from an experimental platform and show, somewhat surprisingly, that many disparate experimental configurations yield comparable predictive performance on testing data. Our understanding of these results is that the experimental setup directly and indirectly defines a pathway for context to be delivered to the classifier, and that, in some settings, certain configurations are more optimal than alternatives. We conclude by identifying how the main results of this work can be used in practice, specifically in experimental configurations in challenging experimental conditions.
Overview
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Breiman, L. (2001) · Machine Learning · doi:10.1023/a:1010933404324 · Cited by 133,538
ImageNet classification with deep convolutional neural networks
Krizhevsky, A., Sutskever, I., & Hinton, G. E. (2017) · Communications of the ACM · doi:10.1145/3065386 · Cited by 112,155 · cited 1×
“Convolutional Neural Networks Convolutional Neural Networks (CNNs), also referred to as ConvNets, are a widely used extension of MLPs which have seen great success in computer vision tasks [80].”
BackgroundHochreiter, S., & Schmidhuber, J. (1997) · Neural Computation · doi:10.1162/neco.1997.9.8.1735 · Cited by 102,318 · cited 13×
“Our experiments use LSTM since they have been shown to perform similarly to other methods (e.g., GRU) in many settings [87].”
MethodInfluentialAdam: A Method for Stochastic Optimization
Kingma, D. P., & Ba, J. (2014) · arXiv · doi:10.48550/arxiv.1412.6980 · Cited by 98,946 · cited 1×
“All networks were trained with the Adam optimiser [88] and parameters are tuned to minimise categorical cross entropy.”
MethodLearning Phrase Representations using RNN Encoder–Decoder for Statistical Machine Translation
Cho, K., van Merrienboer, B., Gulcehre, C., Bahdanau, D., Bougares, F., Schwenk, H., & Bengio, Y. (2014) · Proceedings of the 2014 Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.3115/v1/d14-1179 · Cited by 25,545 · cited 2×
“Our experiments use LSTM since they have been shown to perform similarly to other methods (e.g., GRU) in many settings [87].”
MethodPan, S. J., & Yang, Q. (2010) · IEEE Transactions on Knowledge and Data Engineering · doi:10.1109/tkde.2009.191 · Cited by 23,387 · cited 1×
“The introduction of such methods will reduce the risk of overfitting, but Bayesian models can naturally be adapted to hierarchical models which can naturally lead to transfer learning frameworks [96].”
BackgroundAdvances in neural information processing systems 7
Cios, K., & Shields, M. (1997) · Neurocomputing · doi:10.1016/s0925-2312(97)90018-7 · Cited by 22,059
Multilayer feedforward networks are universal approximators
Hornik, K., Stinchcombe, M., & White, H. (1989) · Neural Networks · doi:10.1016/0893-6080(89)90020-8 · Cited by 21,728 · cited 1×
“However, since these models can model arbitrarily complex functions [46] care must be taken to minimise the risk of overfitting.”
BackgroundQuinlan, J. R. (1986) · Machine Learning · doi:10.1007/bf00116251 · Cited by 21,439 · cited 2×
“We note that whilst research has often focused on which ML algorithm performs best for the given dataset, we will assume instead here that virtually any state-of-the-art ML algorithm (e.g., kernel Support Vector Machines (SVMs) [12], Decision Trees [13], Bayesian classifiers [14]) can be made to perform equivalently g…”
BackgroundConditional Random Fields: Probabilistic Models for Segmenting and Labeling Sequence Data
Lafferty, J., McCallum, A., & Pereira, F. C. N. (2001) · ScholarlyCommons (University of Pennsylvania) · Cited by 12,935
Research works printed but not linked: 3
- Shawe-Taylor, J., and Cristianini, N. (2000). Support Vector Machines, Cambridge University Press.
- Goodfellow, I., Bengio, Y., Courville, A., and Bengio, Y. (2016). Deep Learning, MIT Press.
- Tipping, 2001, Sparse Bayesian Learning and the Relevance Vector Machine, J. Mach. Learn. Res., 1, 211
Cited by
Measurement of physical activity in clinical practice using accelerometers
Arvidsson, D., Fridolfsson, J., & Börjesson, M. (2019) · Journal of Internal Medicine · doi:10.1111/joim.12908 · Cited by 239
Self-supervised learning for human activity recognition using 700,000 person-days of wearable data
Yuan, H., Chan, S., Creagh, A. P., Tong, C., Acquah, A., Clifton, D. A., & Doherty, A. (2024) · npj Digital Medicine · doi:10.1038/s41746-024-01062-3 · Cited by 166
“Current human activity recognition (HAR) models typically rely on manual feature engineering (Twomey et al., 2018; Haresamudram et al., 2019) partly due to the very limited size of existing labelled datasets.”
A Comprehensive Study of Activity Recognition Using Accelerometers
Twomey, N., Diethe, T., Fafoutis, X., Elsts, A., McConville, R., Flach, P., & Craddock, I. (2018) · doi:10.20944/preprints201803.0147.v1 · Cited by 143
Self-citationHARTH: A Human Activity Recognition Dataset for Machine Learning
Logacjov, A., Bach, K., Kongsvold, A., Bårdstu, H. B., & Mork, P. J. (2021) · Sensors · doi:10.3390/s21237853 · Cited by 184
“Human activity recognition (HAR) is a field of study that focuses on recognizing specific human physical activities and postures based on sensor data [7,8].”
BackgroundAn IoT-Based Design Using Accelerometers in Animal Behavior Recognition Systems
Tran, D.-N., Nguyen, T. N., Khanh, P. C. P., & Tran, D. (2021) · IEEE Sensors Journal · doi:10.1109/jsen.2021.3051194 · Cited by 142
“Incredibly we got high per-530 formance when classifying feeding (0.914 accuracy, 0.884 sensitivity, and 0.956 PPV) and standing (0.88 accuracy, 0.928 sensitivity, and 0.842 PPV), which was often a limit [4], [5], [22], [24]–[26], [45]–[47].”
BackgroundInfluential
Metadata
- Authors
- Twomey, N., Diethe, T., Fafoutis, X., Elsts, A., McConville, R., Flach, P., & Craddock, I.
- Affiliations
- University of Bristol (GB)
- Corresponding author
- Twomey, Niall
- Diethe, Tom
- Venue
- Informatics
- Publisher
- MDPI AG
- Published
- 2018-05-30
- Volume
- 5
- Issue
- 2
- Pages
- 27
- ISSN
- 2227-9709 (ISSN-L)
- OpenAlex
- W2790414609
- Cited by
- 143
- References
- 95
- Citations by year
- 2026: 1 · 2025: 9 · 2024: 20 · 2023: 10 · 2022: 19 · 2021: 30 · 2020: 24 · 2019: 26 · 2018: 4
- FWCI
- 10.50
- Type
- journal article
- Language
- en
- Open access
- gold
- dx.doi.org
- Licence
- Locations
- Informatics (publishedVersion, cc-by)
- Preprints.org (acceptedVersion, cc-by)
- Explore Bristol Research (publishedVersion, cc-by)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion, cc-by-sa)
- Bristol Research (University of Bristol) (submittedVersion, cc-by)
- Funders
- Horizon 2020 Framework Programme
- Medical Research Council (MC_PC_16029)
- Engineering and Physical Sciences Research Council (EP/K031910/1, H2020)
- Topics
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Context-Aware Activity Recognition Systems
- Health Sciences › Medicine › Public Health, Environmental and Occupational Health › Physical Activity and Health
- Social Sciences › Transportation › Human Mobility and Location-Based Analysis
- Keywords
- activity recognition, accelerometer, wearable sensors, accelerometer placement, time series segmentation, feature extraction, activity selection, test-retest reliability, generalization, field deployment
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
How to cite
Cite CoChat for the checks on this page, and the paper for its own findings.
- This page
- CoChat. (2026). Citation check: A Comprehensive Study of Activity Recognition Using Accelerometers. https://app.cochat.ai/papers/10.3390/informatics5020027
- The paper
- Twomey, N., Diethe, T., Fafoutis, X., Elsts, A., McConville, R., Flach, P., & Craddock, I. (2018). A Comprehensive Study of Activity Recognition Using Accelerometers. Informatics. https://doi.org/10.3390/informatics5020027
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
