

The DOI matches its Crossref record; 72 of the 72 references it cites were found in a registry or an index; 16 of the 20 sources its claims cite were checked for support.
Self-supervised learning for human activity recognition using 700,000 person-days of wearable data
Open accessAbstract
A large-scale study leveraging self-supervised learning on 700,000 person-days of unlabeled accelerometer data from the UK Biobank to build generalized activity recognition models that outperform supervised baselines across eight benchmark datasets with a median relative F1 improvement of 24.4%.
Overview
CoChat Summary
TL;DR
This paper applies multi-task self-supervised learning to 700,000 person-days of unlabelled UK Biobank wrist accelerometer data, then transfers the pre-trained model to eight human activity recognition benchmarks. The resulting models consistently outperform random forest and from-scratch deep learning baselines, with F1 relative improvements of 2.5–130.9% (median 24.4%).
Key findings
- Pre-trained models outperformed both random forest and ResNet trained from scratch on all eight downstream datasets; the largest gains were on small datasets, e.g. MJFF-LR F1 0.755 ± 0.109 vs 0.327 ± 0.103 from scratch (130.9% improvement), ADL 0.829 ± 0.101 vs 0.414 ± 0.179 (100.0%), and Opportunity 0.595 ± 0.085 vs 0.383 ± 0.124 (55.4%).
- The smallest relative improvement was on the largest labelled dataset, Capture-24: F1 0.726 ± 0.093 with self-supervised fine-tuning of all layers vs 0.708 ± 0.094 from scratch (2.5%).
- Fine-tuning all layers was better than fine-tuning only the fully connected layers after the Conv layers, and self-supervised pre-training on UK Biobank generally outperformed supervised pre-training on Rowlands or Capture-24 in the transfer-learning comparisons.
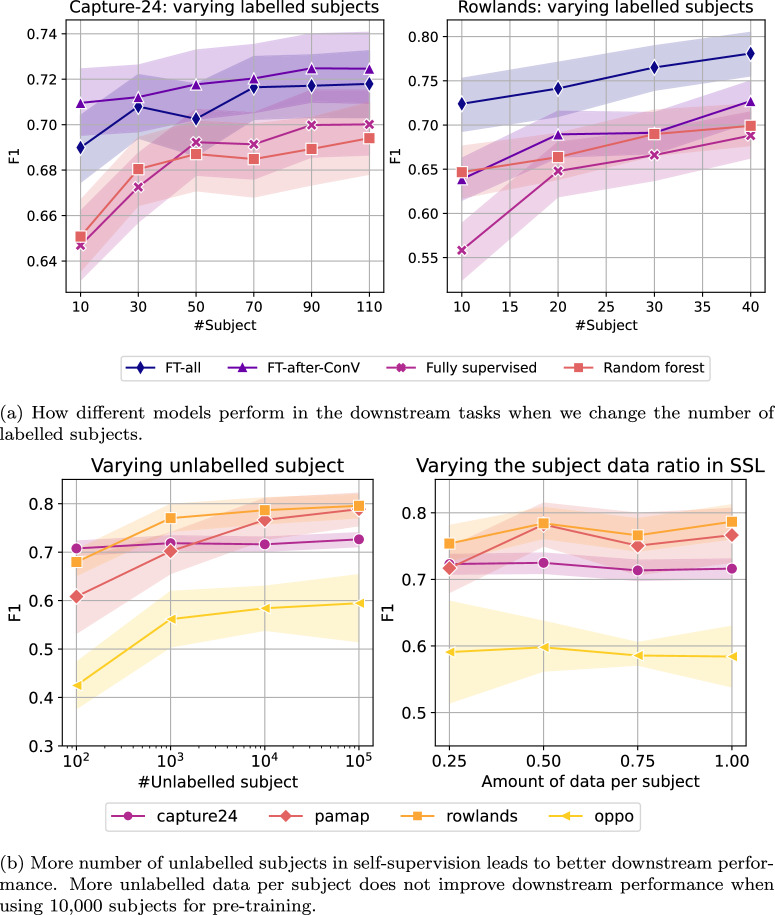
- Downstream performance increased roughly linearly with the number of unlabelled pre-training subjects on a log scale, and reducing data per subject from 100% to 25% did not degrade F1 by more than 10%.
Methods
- Multi-task self-supervised pre-training used unlabelled UK Biobank wrist accelerometer data (~100,000 participants, 7 days, >700,000 person-days), resampled to 30 Hz with 10-second windows. The network was an 18-layer 1D ResNet-V2 with 10M parameters and a 1024-dimensional feature vector; pretext tasks were arrow of time, permutation, and time warping, with weighted sampling by signal standard deviation. Training used Adam with learning rate 1e-3, four Tesla V100-SXM2 GPUs, and about 420 GPU hours for ~20 epochs.
- Evaluation used eight external labelled datasets varying in size (600–600,000 samples), activity classes (4–18), devices (5 brands), placements (4 configurations), and populations. Models were fine-tuned either all layers or only FC layers and compared against random forest and from-scratch ResNet; held-one-subject-out cross-validation was used for datasets with <10 subjects, and five-fold subject-wise cross-validation for datasets with ≥10 subjects, with a 7:1:2 train/validation/test split and early stopping patience of five.
- Ablations varied labelled downstream subjects and unlabelled pre-training participants (100 to 100,000) and data per subject (0.25–1); representation analyses used UMAP projections and layer-wise relevance propagation.
Limitations
- The paper states that the pre-training data (UK Biobank) consists mostly of Caucasians from the UK, due to a current lack of raw accelerometer datasets from different regions of the world. It also notes future work should consider multimodal wearable data, more recent self-supervised approaches, and that Autoencoder and contrastive learning attempts did not yield high-quality representations on UK Biobank, suspected to be due to free-living vs lab-based data differences.
- Evident from the text: evaluation is limited to wrist-worn accelerometer data and eight benchmark datasets, with no external validation in non-UK or non-Caucasian populations. The paper also reports that many open benchmark datasets used lacked suitable licensing or consent information, and small datasets had activity classes removed if not performed by all subjects.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures



Verification
Claims the paper makes
7 Valid · 3 Not valid · 1 Not checked · 55 Own results and interpretations
At least one cited source doesn’t support this claim or points to a different paper, and none confirmed it — see the verdicts below.
In the paper
“The scale of UK Biobank is several orders of magnitude greater than the largest datasets used by the current state-of-the-art such as the Fenland data9 (n = 160,000).”
§ Self-supervised learning for human activity recognition using 700,000 person-days of wearable data > Discussion
What the sources say
- Disputedcites [9] Lindsay, T. et al. Descriptive epidemiology of physical activity energy expenditure in UK adults (the Fenland study). Int. J. Behav. Nutr. Phys. Activity 16, 1–13 (2019). sourceExperimental — accuracy not yet measured
The Methods (Study population) state that the Fenland Study enrolled 12,435 participants, not 160,000. The Results further report that 12,002 met the sensing criteria for this analysis. The paper does not provide a UK Biobank comparison, so it cannot establish the claimed difference in scale. (LLM, conf=0.90)
Checked by a reasoning model — may be wrong.
plainn = 160,000- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Disputed
The cited sources that could be checked couldn’t confirm or dispute this claim.
In the paper
“We attempted to use Autoencoder and contrastive learning for pre-training. However, we could not obtain high-quality representation using the UK Biobank43.”
§ Self-supervised learning for human activity recognition using 700,000 person-days of wearable data > Discussion
What the sources say
- Could not verifycites [43] Tang, C. I. et al. SelfHAR: Improving Human Activity Recognition through Self-training with Unlabeled Data. Proc. ACM Interact. Mob. Wearable Ubiquitous Technol. 5, 30 (2021). sourceExperimental — accuracy not yet measured
The Experimental Protocols (§4.1.8) describe the Fenland Study, and the Results (§5.1.1) name MobiAct and HHAR as unlabeled datasets; neither passage addresses UK Biobank. Searches for UK Biobank, autoencoder and contrastive pre-training found no passage reporting the claimed failure to obtain a high-quality representation. The citing authors describe their own attempt, which this source cannot verify. (LLM, conf=0.76)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Could not verify
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Furthermore, if the number of participants is fixed at 10,000 in pre-training, the data ratio included per subject did not significantly influence the downstream performance.”
§ Self-supervised learning for human activity recognition using 700,000 person-days of wearable data > Results > Ablation studies
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Nonetheless, with self-supervised pre-training, the median relative F1 improvement was 18.4% when compared to the same network trained from scratch and 8.5% when compared to the random forest model.”
§ Self-supervised learning for human activity recognition using 700,000 person-days of wearable data > Results > Downstream performance—human activity recognition
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We also found that the downstream human activity recognition performance appeared to increase linearly with respect to the number of unlabelled subjects on a log scale (Fig. 3b, left).”
§ Self-supervised learning for human activity recognition using 700,000 person-days of wearable data > Results > Ablation studies
hedgedstates an association- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
39 more claims
Create a free account to see all 66 claims and to verify the 1 reference still open.
- It may state two separate claims as one. 13
- Probably not a substantial claim. 14
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Owing to the relative ease of data collection using wearables, there are now large repositories of datasets, e.g., UK Biobank [212], Capture-24 [21,198], and Fenland [145], but crucially, without annotations.”
From Past, Present, and Future of Sensor-based Human Activity Recognition Using Wearables: A Surveying Tutorial on a Still Challenging Task (2025) · cites this paper as [212]
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“However, the gap between HAR-FM and the other foundation model candidates like UniMTS and YUAN-SSL suggests that incorporating larger datasets (evidenced by the gaps between baseline YUAN-SSL (capture24) and YUAN-SSL w10 ) and more fine-grained activity descriptions (evidenced by the significant performance of UniMTS) could lead to significant performance improvements.”
From Towards Customizable Foundation Models for Human Activity Recognition with Wearable Devices (2025) · cites this paper as [62]
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Secondly, in the zero-and few-shot experiments, Yuan et al. [62] and Zhang et al. [65] demonstrates either larger volume or more precise annotations could contribute to the model performance”
From Towards Customizable Foundation Models for Human Activity Recognition with Wearable Devices (2025) · cites this paper as [62]
Experimental — accuracy not yet measuredThe cited source says what the claim attributes to it.
In the citing paper
“Its superior performance against HAR-FM and YUAN-SSL [62] that are pretrained with data from wrist only, suggests the benefits in integrating all placement-wise models.”
From Towards Customizable Foundation Models for Human Activity Recognition with Wearable Devices (2025) · cites this paper as [62]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Each contradiction between two passages listed here was confirmed by an independent check.
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ Self-supervised learning for human activity recognition using 700,000 person-days of wearable data > Methods > Evaluation—human activity recognition
“In terms of unlabelled data, we experimented with pre-training that had 100 to 100,0000 participants with one order of magnitude increment.”
§ Self-supervised learning for human activity recognition using 700,000 person-days of wearable data > Methods > Datasets
“Our multi-task self-supervised training relied on the unlabelledUK Biobank dataset, which contains roughly 700,000 person-days of free-living activity data (>100,000 participants, 7 days of wear).”
Citations
Cites
Adam: A Method for Stochastic Optimization
Kingma, D. P., & Ba, J. (2014) · arXiv · doi:10.48550/arxiv.1412.6980 · Cited by 98,946
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2018) · arXiv · doi:10.48550/arxiv.1810.04805 · Cited by 73,173
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2019) · Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers) · doi:10.18653/v1/n19-1423 · Cited by 54,325
Efficient Estimation of Word Representations in Vector Space
Mikolov, T., Chen, K., Corrado, G., & Dean, J. (2013) · arXiv · doi:10.48550/arxiv.1301.3781 · Cited by 26,568
Language Models are Few-Shot Learners
Brown, T. B., Mann, B., Ryder, N., Subbiah, M., Kaplan, J., Dhariwal, P., Neelakantan, A., Shyam, P., Sastry, G., Askell, A., et al. (2020) · arXiv · doi:10.48550/arxiv.2005.14165 · Cited by 23,372
Momentum Contrast for Unsupervised Visual Representation Learning
He, K., Fan, H., Wu, Y., Xie, S., & Girshick, R. (2020) · 2020 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr42600.2020.00975 · Cited by 13,347 · cited 1×
“…(SSL) methods to leverage unlabelled data in a similar manner as language models (Mikolov et al., 2013; Devlin et al., 2018; Radford et al., 2018, 2019) and vision models (Doersch et al., 2015; Zhang et al., 2016; Noroozi and Favaro, 2016; Wei et al., 2018; He et al., 2020; Chen et al., 2020).”
Identity mappings in deep residual networks
He, K., Zhang, X., Ren, S., & Sun, J. (2016) · Lecture Notes in Computer Science · doi:10.1007/978-3-319-46493-0_38 · Cited by 10,741 · cited 2×
“We adapted a ResNet-V2 with 18 layers and 1D convolutions (He et al., 2016) for the main trunk (feature extractor), totalling 10M parameters.”
Identity Mappings in Deep Residual Networks
He, K., Zhang, X., Ren, S., & Sun, J. (2016) · arXiv · doi:10.48550/arxiv.1603.05027 · Cited by 10,665 · cited 2×
“We adapted a ResNet-V2 with 18 layers and 1D convolutions (He et al., 2016) for the main trunk (feature extractor), totalling 10M parameters.”
UMAP: Uniform Manifold Approximation and Projection
McInnes, L., Healy, J., Saul, N., & Großberger, L. (2018) · Journal of Open Source Software · doi:10.21105/joss.00861 · Cited by 9,826 · cited 1×
“Cluster analysis We used UMAP (McInnes et al., 2018) with default parameters for low-dimensional projections for visualization.”
UMAP: Uniform Manifold Approximation and Projection for Dimension Reduction
McInnes, L., Healy, J., & Melville, J. (2018) · arXiv · doi:10.48550/arxiv.1802.03426 · Cited by 7,101
Research works printed but not linked: 3
- Chen, T., Kornblith, S., Norouzi, M. & Hinton, G. A simple framework for contrastive learning of visual representations. In International Conference on Machine Learning, 1597–1607 (PMLR, 2020).
- Radford, A. et al. Language models are unsupervised multitask learners. OpenAI Blog 1, 9 (2019).
- Haresamudram, H., Essa, I. & Plötz, T. Contrastive Predictive Coding for Human Activity Recognition. Proc. ACM Interact. Mob. Wearable Ubiquitous Technol. 5, 26 (2021). · DOI · Paper page
Cited by
Creagh, A. P., Hamy, V., Yuan, H., Mertes, G., Tomlinson, R., Chen, W.-H., Williams, R., Llop, C., Yee, C., Duh, M. S., et al. (2024) · npj Digital Medicine · doi:10.1038/s41746-024-01013-y · Cited by 64
Self-citationCreagh, A. P., Hamy, V., Yuan, H., Mertes, G., Tomlinson, R., Chen, W.-H., Williams, R., Llop, C., Yee, C., Duh, M. S., et al. (2022) · doi:10.1101/2022.11.18.22282305 · Cited by 64
Self-citationChan, S., Hang, Y., Tong, C., Acquah, A., Schonfeldt, A., Gershuny, J., & Doherty, A. (2024) · Scientific Data · doi:10.1038/s41597-024-03960-3 · Cited by 61
“Our existing benchmark incorporates common methods used for HAR, future work could also benefit from leveraging more recent modeling techniques using DeepConvLSTM 40,41 , transformers 42 , and self-supervised learning 43–46 .”
Self-citationYuan, H., Plekhanova, T., Walmsley, R., Reynolds, A. C., Maddison, K. J., Bucan, M., Gehrman, P., Rowlands, A., Ray, D. W., Bennett, D., et al. (2024) · npj Digital Medicine · doi:10.1038/s41746-024-01065-0 · Cited by 40
“See Supplementary Section 1.3.1 for the full speci fi cation of the analysis.”
BackgroundInfluentialSelf-citationA Comprehensive Survey on Wearable Computing for Mental and Physical Health Monitoring
Elfouly, T., & Alouani, A. T. (2025) · Electronics · doi:10.3390/electronics14173443 · Cited by 71
“[17] [18] This bipolar disorder management using wearable technologies”.”
Metadata
- Authors
- Yuan, H., Chan, S., Creagh, A. P., Tong, C., Acquah, A., Clifton, D. A., & Doherty, A.
- Affiliations
- University of Oxford (GB)
- Corresponding author
- Doherty, Aiden
- Venue
- npj Digital Medicine
- Published
- 2024-04-12
- Volume
- 7
- Issue
- 1
- Pages
- 91-91
- ISSN
- 2398-6352 (ISSN-L)
- PMC
- PMC11015005
- OpenAlex
- W4394757986
- Cited by
- 166
- References
- 56
- Citations by year
- 2026: 78 · 2025: 57 · 2024: 26
- FWCI
- 22.43
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Licence
- cc-by
- creativecommons.org/licenses/by/4.0 (tdm)
- creativecommons.org/licenses/by/4.0 (vor)
- Locations
- npj Digital Medicine (publishedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- arXiv (Cornell University) (submittedVersion)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion, cc-by-sa)
- arXiv (Cornell University) (cc-by)
- Funders
- Wellcome Trust ([223100/Z/21/Z])
- British Heart Foundation
- Novo Nordisk
- GlaxoSmithKline
- DH | National Institute for Health Research
- Topics
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Context-Aware Activity Recognition Systems
- Health Sciences › Medicine › Public Health, Environmental and Occupational Health › Physical Activity and Health
- Physical Sciences › Computer Science › Artificial Intelligence › Domain Adaptation and Few-Shot Learning
- Keywords
- human activity recognition, self-supervised learning, wearable accelerometers, UK Biobank, physical activity monitoring, unlabeled data, pre-trained models, cross-dataset generalization, sensors, limited labeled data
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
The claim verdicts this report counts are experimental: their accuracy is not yet measured.
A language model drew the claims from the paper on 2026-10-10, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-10-10 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Cited sources are checked with a language model’s help (gpt-6-sol).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
How to cite
Cite CoChat for the checks on this page, and the paper for its own findings.
- This page
- CoChat. (2026). Citation check: Self-supervised learning for human activity recognition using 700,000 person-days of wearable data. https://app.cochat.ai/papers/10.1038/s41746-024-01062-3
- The paper
- Yuan, H., Chan, S., Creagh, A. P., Tong, C., Acquah, A., Clifton, D. A., & Doherty, A. (2024). Self-supervised learning for human activity recognition using 700,000 person-days of wearable data. npj Digital Medicine. https://doi.org/10.1038/s41746-024-01062-3
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
