

The DOI matches its Crossref record; 21 of the 23 references it cites were found in a registry or an index, and 2 are not checked yet; none of the 20 sources its claims cite is checked for support yet.
Geographic Variation in LLM DOI Fabrication: Cross-Country Analysis of Citation Accuracy Across Four Large Language Models
Open accessAbstract
This study evaluates digital object identifier (DOI) hallucination in large language model (LLM)-generated scholarly citations, with a focus on systematic geographic disparities. To conduct this study, we systematically evaluated four LLMs (GPT-4o-mini, Claude-3-haiku, Gemini-2.0-flash-lite, and DeepSeek V3) using standardized information behavior prompts across ten countries with diverse income levels. The models generated 3451 citations, which we validated using the CrossRef API. The results showed that DOI hallucination follows systematic patterns influenced by model choice, geographic context, and publication recency. Hallucination rates exceeded 80% in lower-income countries and increased sharply for publications from the 2020s across all regions. Fabricated citations—citations that appear structurally complete but contain invalid DOIs—were especially prevalent in countries such as India and Bangladesh. Model-specific factors showed the strongest association with hallucination, followed by income level and publication period. These findings raise concerns about the epistemic reliability of LLM-generated scholarly references and underscore the need for region-aware training, real-time DOI validation, and robust verification protocols in academic contexts.
Checked 2026-11-13 · 2 references not checked yet
Overview
CoChat Summary
TL;DR
This study evaluates DOI hallucination in citations generated by four LLMs across ten countries and finds systematic geographic disparities, with higher fabrication rates in lower-income contexts and for recent publications. Model choice showed the strongest association with hallucination, followed by country income level and publication period.
Key findings
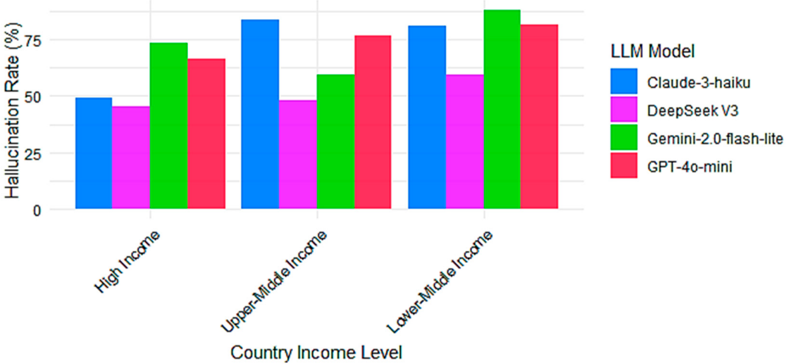
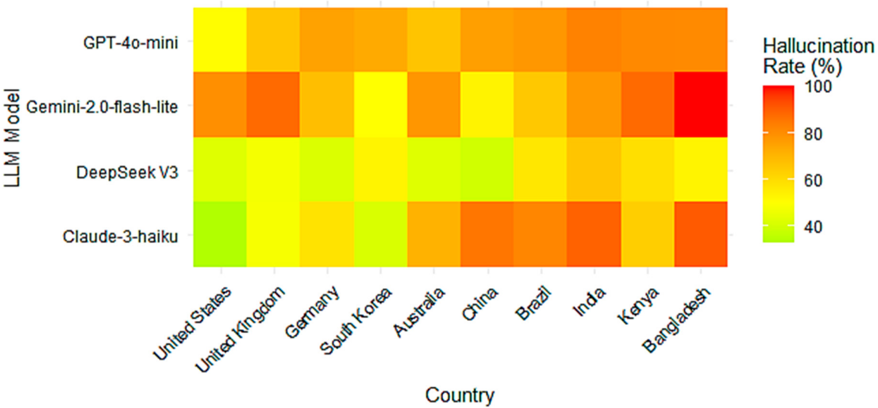
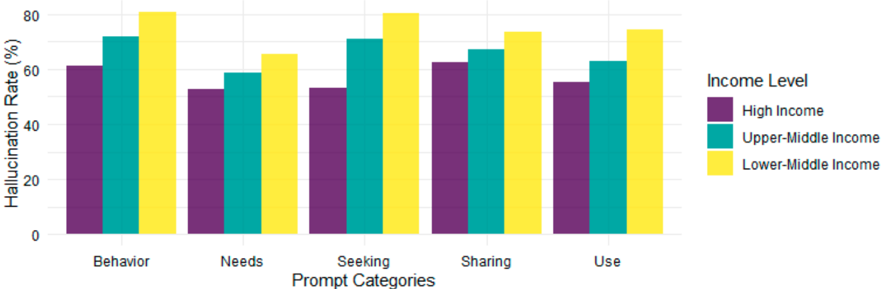
- Across 3451 generated citations validated via CrossRef, DOI hallucination increased as income level decreased; rates exceeded 80% in lower-income countries, and Gemini-2.0-flash-lite approached 100% hallucination for Bangladesh.
- Model-specific factors had the strongest association with DOI hallucination (Cramér’s V = 0.203), followed by country income level (V = 0.162) and geographic bias (V = 0.189); publication period was also significant (Kruskal-Wallis H = 161.74).
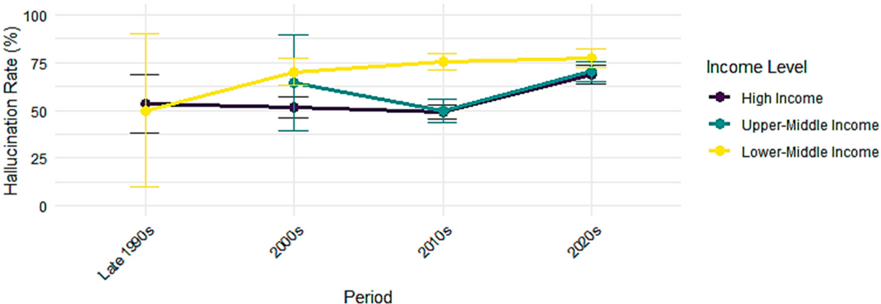
- Hallucination rates rose sharply for publications from the 2020s: high- and upper-middle-income countries increased from roughly 45–55% in earlier periods to 65–75%, while lower-middle-income countries rose from around 70% to 80%.
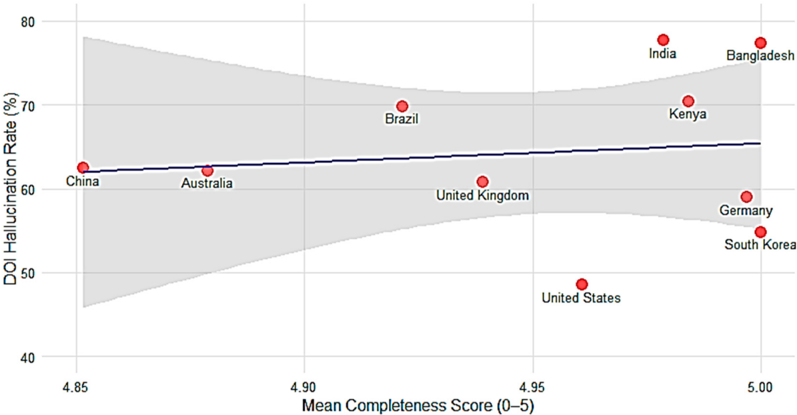
- Citation completeness clustered between 4.85–5.0, but India and Bangladesh showed both near-5.0 completeness and hallucination rates exceeding 80%, while the UK and South Korea had high completeness with lower hallucination rates around 48% and 50%.
Methods
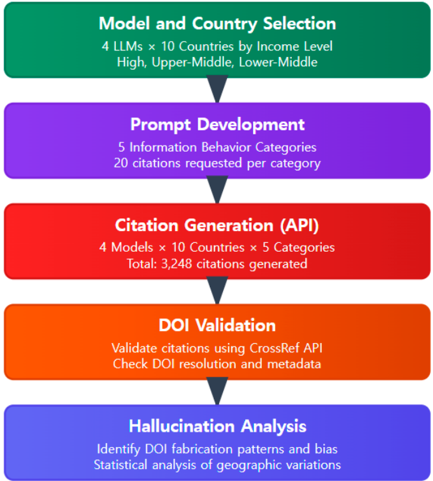
- Controlled experimental design using GPT-4o-mini, Claude-3-haiku, Gemini-2.0-flash-lite, and DeepSeek V3, all configured with temperature 0.2 and a 2000-token limit; ten countries were purposively sampled by World Bank FY2024 income classification.
- Standardized system prompt plus five user prompts targeting information behavior categories (seeking, use, sharing, needs, general behavior), each requesting 20 real citations with valid DOIs in tab-delimited format; 195 experimental conditions were examined (10 countries × 5 prompts × 4 models, with OpenAI having 45 conditions due to technical constraints).
- DOIs were validated with the CrossRef REST API; HTTP 200 with complete bibliographic metadata was classified as valid, while error responses or missing metadata were classified as hallucinated. Analysis used Fisher’s exact tests with Monte Carlo simulation (2000 iterations), Kruskal-Wallis tests, Spearman correlations, and effect sizes including Cramér’s V.
Limitations
- The paper states that causal mechanisms cannot be established due to proprietary training data, restricting conclusions to systematic associations.
- The paper states that DOI validation focused only on resolution success and geographic relevance, not whether valid DOIs matched cited content, likely underestimating citation fabrication; it also notes exclusion of low-income countries, inclusion of only three lower-middle-income countries versus seven upper-middle- and high-income countries, fixed model versions and time period, restriction to information behavior research in LIS, and operationalization of hallucination solely as DOI resolution failure.
- Evident from the text: the study’s own sampling bias toward better-resourced contexts and narrow DOI-only validation mean the reported geographic disparities are likely conservative, as the authors also state.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
0 Valid · 3 Not valid · 17 Not checked · 116 Own results and interpretations
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“GPT-4o-mini shows consistently high hallucination rates even in highincome countries such as the United States and Germany, indicating a model-wide tendency to hallucinate regardless of national information infrastructure.”
§ Geographic Variation in LLM DOI Fabrication: Cross-Country Analysis of Citation Accuracy Across Four Large Language Models > 4.2. Geographic and Country-Specific Variations
hedged- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper states — it cites no source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Overall, hallucination rates increase as income levels decrease.”
§ Geographic Variation in LLM DOI Fabrication: Cross-Country Analysis of Citation Accuracy Across Four Large Language Models > 4.1. DOI Hallucination Patterns by Model and Income Level
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Country income level was significantly associated with both DOI hallucination (V = 0.162) and geographic bias (V = 0.189)”
§ Geographic Variation in LLM DOI Fabrication: Cross-Country Analysis of Citation Accuracy Across Four Large Language Models > 4.6. Statistical Analysis of DOI Validity
plainstates an association- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“This shortfall did not vary by country (p = 1.000,V = 0.042) or prompt type (p = 1.000,V = 0.011)”
§ Geographic Variation in LLM DOI Fabrication: Cross-Country Analysis of Citation Accuracy Across Four Large Language Models > 4.6. Statistical Analysis of DOI Validity
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“In contrast, DeepSeek V3 and Gemini-2.0-flash-litedisplay greater variation in performance.”
§ Geographic Variation in LLM DOI Fabrication: Cross-Country Analysis of Citation Accuracy Across Four Large Language Models > 4.2. Geographic and Country-Specific Variations
plainstates an association- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
65 more claims
Create a free account to see all 136 claims and to verify the 8 references still open.
- It may state two separate claims as one. 47
- Probably not a substantial claim. 31
- The quote only partly states this claim. 2
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
“Bridges (2024) observed that ChatGPT-4 produced only 52 correct DOIs (31.5%) out of 145 clinical references.”
§ Geographic Variation in LLM DOI Fabrication: Cross-Country Analysis of Citation Accuracy Across Four Large Language Models > 2. Literature Review
Reported 31.5 · recomputed 35.862069
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
“Of the 4000 requested citations, only 3451 were received, representing a 13.7 percent shortfall.”
§ Geographic Variation in LLM DOI Fabrication: Cross-Country Analysis of Citation Accuracy Across Four Large Language Models > 4.6. Statistical Analysis of DOI Validity
Reported 4000 · recomputed 3900
Citations
Cites
What do citation counts measure? A review of studies on citing behavior
Bornmann, L., & Daniel, H. (2008) · Journal of Documentation · doi:10.1108/00220410810844150 · Cited by 1,607 · cited 1×
“Citations are fundamental to academic research, serving to validate claims and link new studies to established knowledge (Bornmann & Daniel, 2008; Hyland, 1999).”
Academic attribution: citation and the construction of disciplinary knowledge
Hyland, K. (1999) · Applied Linguistics · doi:10.1093/applin/20.3.341 · Cited by 907
Citation bias favoring statistically significant studies was present in medical research
Jannot, A.-S., Agoritsas, T., Gayet-Ageron, A., & Perneger, T. V. (2013) · Journal of Clinical Epidemiology · doi:10.1016/j.jclinepi.2012.09.015 · Cited by 193
Crossref: The sustainable source of community-owned scholarly metadata
Hendricks, G., Tkaczyk, D., Lin, J., & Feeney, P. (2020) · Quantitative Science Studies · doi:10.1162/qss_a_00022 · Cited by 175
Artificial intelligence-assisted academic writing: recommendations for ethical use
Cheng, A., Calhoun, A., & Reedy, G. (2025) · Advances in Simulation · doi:10.1186/s41077-025-00350-6 · Cited by 140
Daquino, M., Peroni, S., Shotton, D. M., Colavizza, G., Ghavimi, B., Lauscher, A., Mayr, P., Romanello, M., & Zumstein, P. (2020) · Lecture notes in computer science · doi:10.1007/978-3-030-62466-8_28 · Cited by 76
Mugaanyi, J., Cai, L., Cheng, S., Lu, C., & Huang, J. (2024) · Journal of Medical Internet Research · doi:10.2196/52935 · Cited by 74
Goodhart’s law and performance indicators in higher education
Elton, L. (2004) · Evaluation & Research in Education · doi:10.1080/09500790408668312 · Cited by 50
Frosolini, A., Catarzi, L., Benedetti, S., Latini, L., Chisci, G., Franz, L., Gennaro, P., & Gabriele, G. (2024) · Diagnostics · doi:10.3390/diagnostics14080839 · Cited by 41
Using ChatGPT for method development and green chemistry education in upper-level laboratory courses
Ruff, E. F., Franz, J. L., & West, J. K. (2024) · Journal of Chemical Education · doi:10.1021/acs.jchemed.4c00193 · Cited by 40
Research works printed but not linked: 2
- Chavarro, D., Alperin, J. P., and Willinsky, J. (2025). A caminho da indexação universal: OpenAlex e open journal systems. SciELO, preprints.
- Gathama, 2025, Accuracy of references in the kenya eye health journal volume 1 number 1, Kenya Eye Health Journal, 2, 12
Cited by
The ethics of using artificial intelligence in writing medical research papers
Yu, S., & Hwang, H. (2025) · Kosin Medical Journal · doi:10.7180/kmj.25.141 · Cited by 2
Unmediated AI-Assisted Scholarly Citations
Szeider, S. H. (2025) · Open Conference Proceedings · doi:10.52825/ocp.v8i.3161 · Cited by 1
Chen, C. K., Liang, S.-H., & Wang, T. (2026) · Scientometrics · doi:10.1007/s11192-026-05727-6 · Cited by 1
Tosi, D., Mauriello, E. C., & Utzeri, A. (2026) · Research Square · doi:10.21203/rs.3.rs-10539555/v1
Domingo, J. L. (2026) · Qeios · doi:10.32388/9aob4v
Metadata
- Authors
- Kim, E., Kipchumba, F., & Min, S.
- Affiliations
- Keimyung University (KR)
- Corresponding author
- Kim, Eungi
- ORCID
- Venue
- Publications
- Publisher
- MDPI AG
- Published
- 2025-10-01
- Volume
- 13
- Issue
- 4
- Pages
- 49
- ISSN
- 2304-6775 (ISSN-L)
- OpenAlex
- W4414704550
- Semantic Scholar
- e76294bd53b3974b891ed1e292fef9e61b780908
- Cited by
- 7
- References
- 21
- Citations by year
- 2026: 5 · 2025: 2
- FWCI
- 7.78
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Licence
- Locations
- Publications (publishedVersion, cc-by)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion, cc-by-sa)
- Funders
- Bisa Research Grant of Keimyung University (20240535)
- Topics
- Social Sciences › Library and Information Sciences › scientometrics and bibliometrics research
- Social Sciences › Education › Academic integrity and plagiarism
- Social Sciences › Library and Information Sciences › Academic Writing and Publishing
- Keywords
- large language models, citation hallucination, scientific citations, regional variation, country income level, citation accuracy, GPT-4o-mini, DeepSeek-V3, epistemic reliability
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
A language model drew the claims from the paper on 2026-11-13, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-11-13 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
