

The DOI matches its Crossref record; 35 of the 35 references it cites were found in a registry or an index.
A Transformer-Based Neural Network for Gait Prediction in Lower Limb Exoskeleton Robots Using Plantar Force
Open accessAbstract
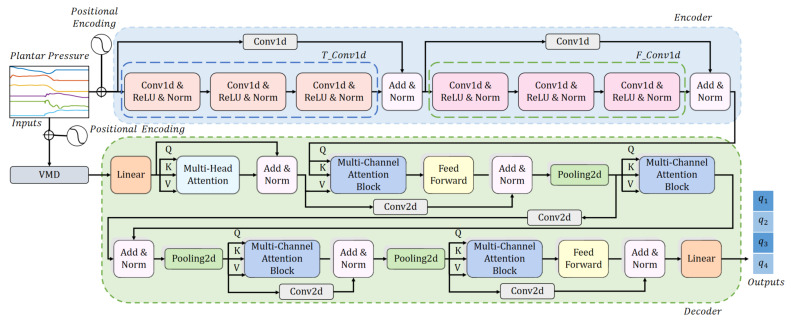
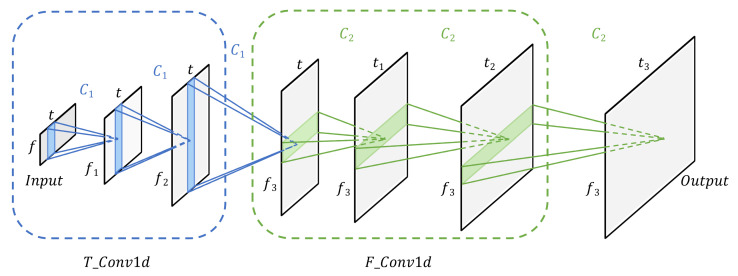
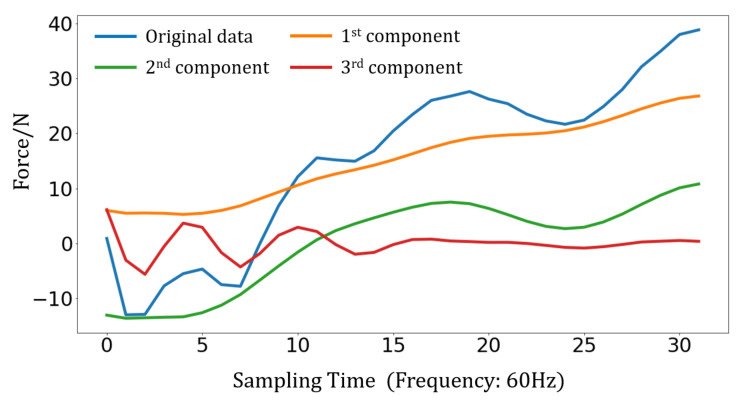
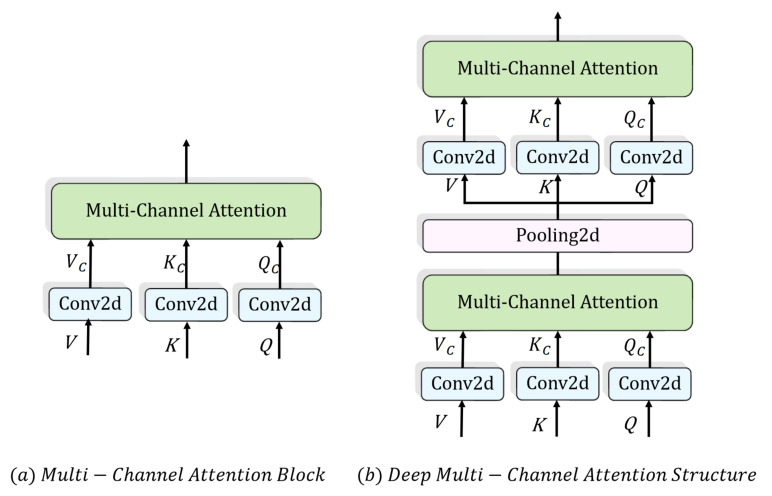
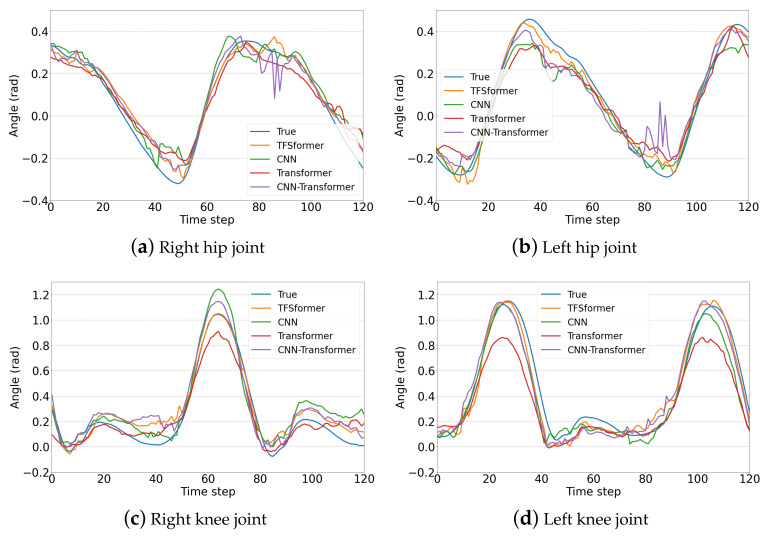
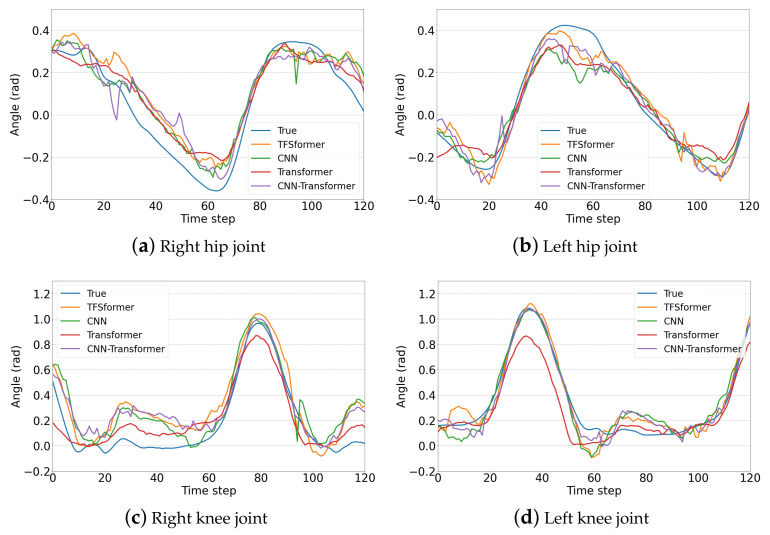
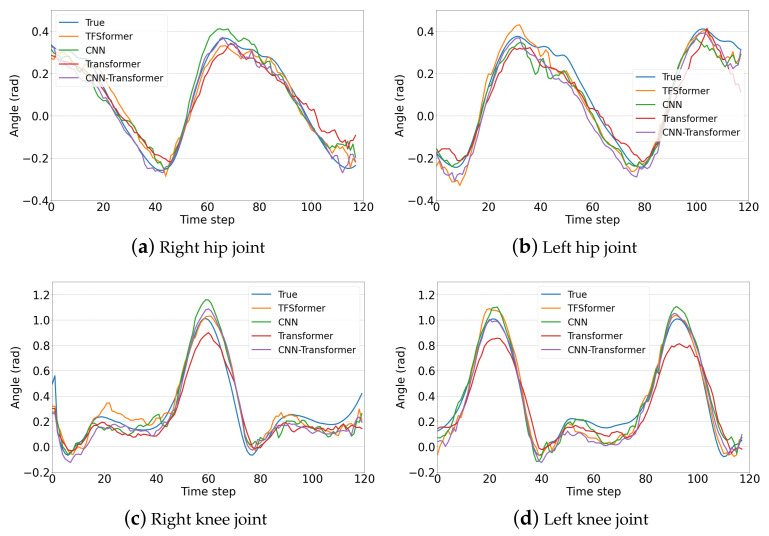
Lower limb exoskeleton robots have shown significant research value due to their capabilities of providing assistance to wearers and improving physical motion functions. As a type of robotic technology, wearable robots are directly in contact with the wearer’s limbs during operation, necessitating a high level of human–robot collaboration to ensure safety and efficacy. Furthermore, gait prediction for the wearer, which helps to compensate for sensor delays and provide references for controller design, is crucial for improving the the human–robot collaboration capability. For gait prediction, the plantar force intrinsically reflects crucial gait patterns regardless of individual differences. To be exact, the plantar force encompasses a doubled three-axis force, which varies over time concerning the two feet, which also reflects the gait patterns indistinctly. In this paper, we developed a transformer-based neural network (TFSformer) comprising convolution and variational mode decomposition (VMD) to predict bilateral hip and knee joint angles utilizing the plantar pressure. Given the distinct information contained in the temporal and the force-space dimensions of plantar pressure, the encoder uses 1D convolution to obtain the integrated features in the two dimensions. As for the decoder, it utilizes a multi-channel attention mechanism to simultaneously focus on both dimensions and a deep multi-channel attention structure to reduce the computational and memory consumption. Furthermore, VMD is applied to networks to better distinguish the trends and changes in data. The model is trained and tested on a self-constructed dataset that consists of data from 35 volunteers. The experimental results show that FTSformer reduces the mean absolute error (MAE) up to 10.83%, 15.04% and 8.05% and the mean squared error (MSE) by 20.40%, 29.90% and 12.60% compared to the CNN model, the transformer model and the CNN transformer model, respectively.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
“| Transformer | Global modeling via self-attention | Adaptive multimodal fusion, strong | Cross-user intent transfer learning, multi-sensor |”
From Recent advances in intelligent wearable systems: from multiscale biomechanical features towards human motion intent prediction (2026) · cites this paper as [152]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Jakubův, J., Chvalovský, K., Goertzel, Z., et al. (2023) · DROPS (Schloss Dagstuhl – Leibniz Center for Informatics) · doi:10.4230/lipics.itp.2023.19 · Cited by 76,648
Variational Mode Decomposition
Dragomiretskiy, K., & Zosso, D. (2014) · IEEE Transactions on Signal Processing · doi:10.1109/tsp.2013.2288675 · Cited by 9,184
Informer: Beyond Efficient Transformer for Long Sequence Time-Series Forecasting
Zhou, H., Zhang, S., Peng, J., Zhang, S., Li, J., Xiong, H., & Zhang, W. (2021) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v35i12.17325 · Cited by 7,752
A Survey of Convolutional Neural Networks: Analysis, Applications, and Prospects
Li, Z., Liu, F., Yang, W., Peng, S., & Zhou, J. (2022) · IEEE Transactions on Neural Networks and Learning Systems · doi:10.1109/tnnls.2021.3084827 · Cited by 5,273 · cited 1×
“Convolutional neural networks (CNNs) are powerful in feature extraction, especially for data with a grid structure [17–21].”
BackgroundFEDformer: Frequency Enhanced Decomposed Transformer for Long-term Series ForecastingPreprint
Zhou, T., Ma, Z., Wen, Q., Wang, X., Sun, L., & Jin, R. (2022) · International Conference on Machine Learning · doi:10.48550/arxiv.2201.12740 · Cited by 3,946
Temporal Fusion Transformers for interpretable multi-horizon time series forecasting
Lim, B., Arık, S. Ö., Loeff, N., & Pfister, T. (2021) · International Journal of Forecasting · doi:10.1016/j.ijforecast.2021.03.012 · Cited by 3,291
Box, G. E. P., & Pierce, D. A. (1970) · Journal of the American Statistical Association · doi:10.2307/2284333 · Cited by 3,212
Taylor, S. J., & Letham, B. (2017) · The American Statistician · doi:10.1080/00031305.2017.1380080 · Cited by 2,904
Language Modeling with Gated Convolutional NetworksPreprint
Dauphin, Y., Fan, A., Auli, M., & Grangier, D. (2016) · arXiv (Cornell University) · doi:10.48550/arxiv.1612.08083 · Cited by 1,765
Recurrent Neural Networks for Time Series Forecasting: Current status and future directions
Hewamalage, H., Bergmeir, C., & Bandara, K. (2021) · International Journal of Forecasting · doi:10.1016/j.ijforecast.2020.06.008 · Cited by 1,371
Research works printed but not linked: 4
- Stadler, K., Altenburger, R., Schmidhauser, E., Scherly, D., Ortiz, J., Toxiri, S., Mateos, L., and Masood, J. (2016). Advances in Cooperative Robotics, World Scientific.
- Borovykh, A., Bohte, S., and Oosterlee, C.W. (2017). Conditional time series forecasting with convolutional neural networks. arXiv.
- Vaswani, 2017, Attention is all you need, Adv. Neural Inf. Process. Syst., 30, 6000
- Wu, 2021, Autoformer: Decomposition transformers with auto-correlation for long-term series forecasting, Adv. Neural Inf. Process. Syst., 34, 22419
Cited by
Sorted by citations
Deep Learning Approaches for Enhanced Lower-Limb Exoskeleton Control: A Review
Belal, M., Alsheikh, N., Aljarah, A., & Hussain, I. (2024) · IEEE Access · doi:10.1109/access.2024.3414175 · Cited by 42
Chen, S., Peng, C., Yang, B., Lin, J., Zhou, L., Jiang, Z., Liu, Z., Liu, Y., & Tang, L. (2026) · npj Artificial Intelligence · doi:10.1038/s44387-026-00083-5 · Cited by 9
Metadata
- Authors
- Ren, J., Wang, A., Li, H., Yue, X., & Meng, L.
- Affiliations
- Zhongyuan University of Technology (CN)
- Ritsumeikan University (JP)
- Corresponding author
- Wang, Aihui
- Venue
- Sensors
- Publisher
- MDPI AG
- Published
- 2023-07-20
- Volume
- 23
- Issue
- 14
- Pages
- 6547
- ISSN
- 1424-8220 (ISSN-L)
- PMC
- PMC10384092
- OpenAlex
- W4384931412
- Cited by
- 34
- References
- 35
- Citations by year
- 2026: 11 · 2025: 13 · 2024: 9 · 2023: 1
- FWCI
- 2.69
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Licence
- Locations
- Sensors (publishedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion, cc-by-sa)
- Funders
- National Natural Science Foundation of China (62073297)
- Topics
- Physical Sciences › Engineering › Biomedical Engineering › Prosthetics and Rehabilitation Robotics
- Physical Sciences › Engineering › Biomedical Engineering › Muscle activation and electromyography studies
- Physical Sciences › Engineering › Biomedical Engineering › Gait Recognition and Analysis
- Keywords
- lower limb exoskeleton, gait prediction, plantar force, plantar pressure, transformer models, variational mode decomposition, hip joint angle, knee joint angle, multi-channel attention, wearable robotics, human-robot collaboration
- MeSH terms
- Exoskeleton Device, Gait, Humans, Robotics, Neural Networks, Computer, Lower Extremity
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
