

The DOI matches its Crossref record; 6 of the 6 references it cites were found in a registry or an index.
FusionVision: A Comprehensive Approach of 3D Object Reconstruction and Segmentation from RGB-D Cameras Using YOLO and Fast Segment Anything
Open accessAbstract
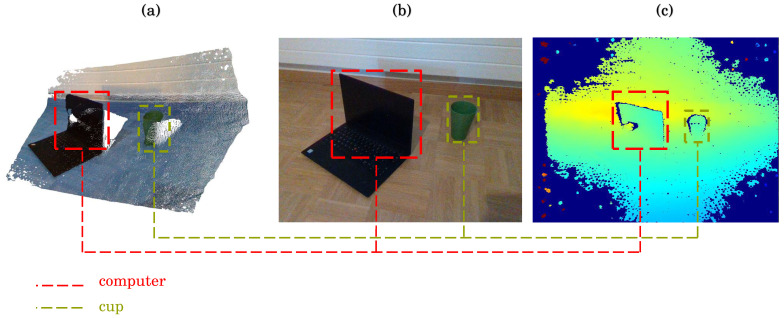
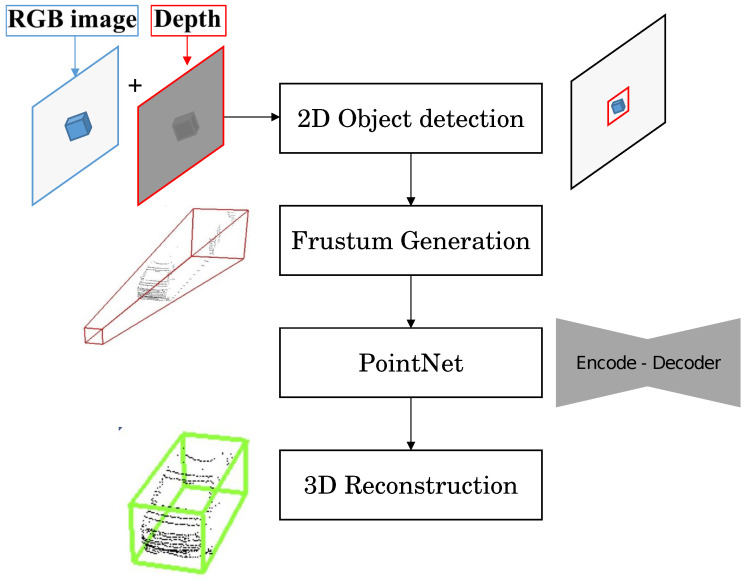
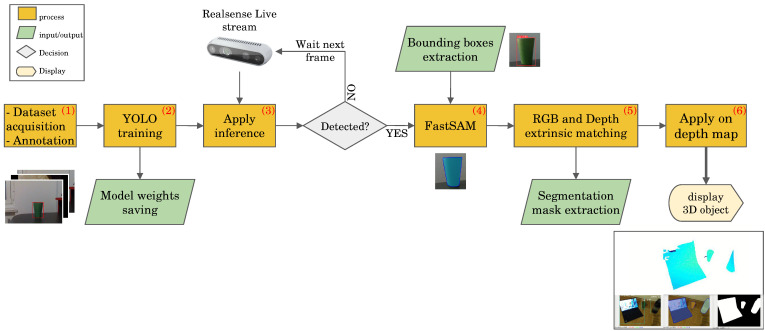
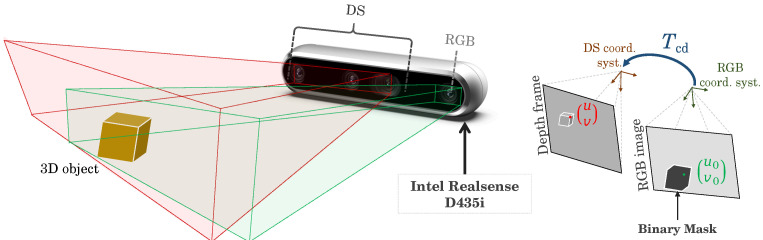
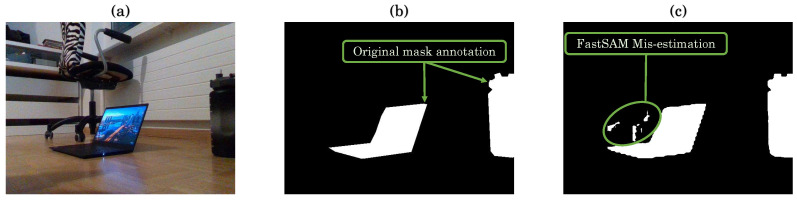
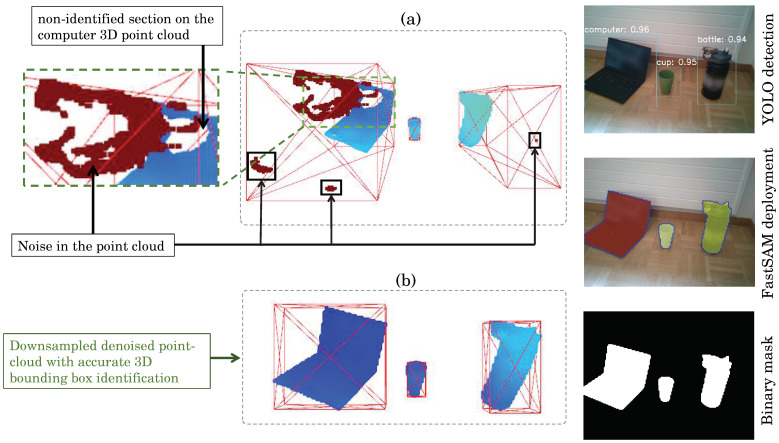
In the realm of computer vision, the integration of advanced techniques into the pre-processing of RGB-D camera inputs poses a significant challenge, given the inherent complexities arising from diverse environmental conditions and varying object appearances. Therefore, this paper introduces FusionVision, an exhaustive pipeline adapted for the robust 3D segmentation of objects in RGB-D imagery. Traditional computer vision systems face limitations in simultaneously capturing precise object boundaries and achieving high-precision object detection on depth maps, as they are mainly proposed for RGB cameras. To address this challenge, FusionVision adopts an integrated approach by merging state-of-the-art object detection techniques, with advanced instance segmentation methods. The integration of these components enables a holistic (unified analysis of information obtained from both color RGB and depth D channels) interpretation of RGB-D data, facilitating the extraction of comprehensive and accurate object information in order to improve post-processes such as object 6D pose estimation, Simultanious Localization and Mapping (SLAM) operations, accurate 3D dataset extraction, etc. The proposed FusionVision pipeline employs YOLO for identifying objects within the RGB image domain. Subsequently, FastSAM, an innovative semantic segmentation model, is applied to delineate object boundaries, yielding refined segmentation masks. The synergy between these components and their integration into 3D scene understanding ensures a cohesive fusion of object detection and segmentation, enhancing overall precision in 3D object segmentation.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The cited source says what the claim attributes to it.
In the citing paper
“Additionally, extending YOLO to handle 3D object detection has become a critical focus area [149,150].”
From The YOLO Framework: A Comprehensive Review of Evolution, Applications, and Benchmarks in Object Detection (2024) · cites this paper as [150]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
U-Net: Convolutional Networks for Biomedical Image Segmentation
Ronneberger, O., Fischer, P., & Brox, T. (2015) · Lecture notes in computer science · doi:10.1007/978-3-319-24574-4_28 · Cited by 99,404
You Only Look Once: Unified, Real-Time Object Detection
Redmon, J., Divvala, S., Girshick, R., & Farhadi, A. (2016) · 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2016.91 · Cited by 53,803
Kirillov, A., Mintun, E., Ravi, N., Mao, H., Rolland, C., Gustafson, L., Xiao, T., Whitehead, S., Berg, A. C., Lo, W.-Y., et al. (2023) · 2023 IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv51070.2023.00371 · Cited by 11,953
Frustum PointNets for 3D Object Detection from RGB-D Data
Qi, C. R., Liu, W., Wu, C., Su, H., & Guibas, L. J. (2018) · 2018 IEEE/CVF Conference on Computer Vision and Pattern Recognition · doi:10.1109/cvpr.2018.00102 · Cited by 2,655
A review: Data pre-processing and data augmentation techniques
Maharana, K., Mondal, S., & Nemade, B. (2022) · Global Transitions Proceedings · doi:10.1016/j.gltp.2022.04.020 · Cited by 1,337
A comprehensive review of object detection with deep learning
Kaur, R., & Singh, S. (2023) · Digital Signal Processing · doi:10.1016/j.dsp.2022.103812 · Cited by 539
Research works printed but not linked: 53
- Liu, 2016, Robotic Online Path Planning on Point Cloud, IEEE Trans. Cybern., 46, 1217, 10.1109/TCYB.2015.2430526 · DOI
- Ding, Z., Sun, Y., Xu, S., Pan, Y., Peng, Y., and Mao, Z. (2023). Recent Advances and Perspectives in Deep Learning Techniques for 3D Point Cloud Data Processing. Robotics, 12. · DOI
- Krawczyk, 2023, Segmentation of 3D Point Cloud Data Representing Full Human Body Geometry: A Review, Pattern Recognit., 139, 109444, 10.1016/j.patcog.2023.109444 · DOI
- Wu, F., Qian, Y., Zheng, H., Zhang, Y., and Zheng, X. (September, January 28). A Novel Neighbor Aggregation Function for Medical Point Cloud Analysis. Proceedings of the Computer Graphics International Conference, Shanghai, China.
- Xie, X., Wei, H., and Yang, Y. (2023). Real-Time LiDAR Point-Cloud Moving Object Segmentation for Autonomous Driving. Sensors, 23. · DOI
- Zhang, Y., Liu, K., Bao, H., Zheng, Y., and Yang, Y. (2023). PMPF: Point-Cloud Multiple-Pixel Fusion-Based 3D Object Detection for Autonomous Driving. Remote Sens., 15. · DOI
- Chiominto, 2023, Extraction of a floor plan from a points cloud: Some metrological considerations, Acta IMEKO, 12, 1
- Zhang, 2023, Applications of data fusion in optical coordinate metrology: A review, Int. J. Adv. Manuf. Technol., 124, 1341, 10.1007/s00170-022-10576-7 · DOI
- Altuntas, C. (2023). Review of Scanning and Pixel Array-Based LiDAR Point-Cloud Measurement Techniques to Capture 3D Shape or Motion. Appl. Sci., 13. · DOI
- Kurtser, 2023, RGB-D datasets for robotic perception in site-specific agricultural operations—A survey, Comput. Electron. Agric., 212, 108035, 10.1016/j.compag.2023.108035 · DOI
- Zhao, 2023, Robust Depth-Aided RGBD-Inertial Odometry for Indoor Localization, Measurement, 209, 112487, 10.1016/j.measurement.2023.112487 · DOI
- Gao, 2023, Deep learning for video object segmentation: A review, Artif. Intell. Rev., 56, 457, 10.1007/s10462-022-10176-7 · DOI
- Hou, 2023, A Survey of Efficient Deep Learning Models for Moving Object Segmentation, APSIPA Trans. Signal Inf. Process., 12, e2, 10.1561/116.00000140 · DOI
- Arkin, 2023, A survey: Object detection methods from CNN to transformer, Multimed. Tools Appl., 82, 21353, 10.1007/s11042-022-13801-3 · DOI
- 2021, Object detection through region proposal based techniques, Mater. Today Proc., 46, 3997, 10.1016/j.matpr.2021.02.533 · DOI
- Liu, W., Anguelov, D., Erhan, D., Szegedy, C., Reed, S.E., Fu, C., and Berg, A.C. (2016, January 11–14). SSD: Single Shot MultiBox Detector. Proceedings of the Computer Vision–ECCV 2016: 14th European Conference, Amsterdam, The Netherlands. · DOI · Paper page
- Wang, 2022, A Comprehensive Review of Modern Object Segmentation Approaches, Found. Trends® Comput. Graph. Vis., 13, 111, 10.1561/0600000097 · DOI
- Liu, 2018, Recent progress in semantic image segmentation, Artif. Intell. Rev., 52, 1089, 10.1007/s10462-018-9641-3 · DOI
- Hafiz, 2020, A survey on instance segmentation: State of the art, Int. J. Multimed. Inf. Retr., 9, 171, 10.1007/s13735-020-00195-x · DOI
- Cong, 2023, A review of convolutional neural network architectures and their optimizations, Artif. Intell. Rev., 56, 1905, 10.1007/s10462-022-10213-5 · DOI
- Luo, Z., Fang, Z., Zheng, S., Wang, Y., and Fu, Y. (2021, January 21–24). NMS-Loss: Learning with Non-Maximum Suppression for Crowded Pedestrian Detection. Proceedings of the 2021 International Conference on Multimedia Retrieval, Taipei, Taiwan. · DOI
- Shao, 2023, Application of U-Net and Optimized Clustering in Medical Image Segmentation: A Review, CMES-Comput. Model. Eng. Sci., 136, 2173
- Zhang, 2023, Modified U-Net for plant diseased leaf image segmentation, Comput. Electron. Agric., 204, 107511, 10.1016/j.compag.2022.107511 · DOI
- Aghdam, E.K., Azad, R., Zarvani, M., and Merhof, D. (2023, January 17–21). Attention swin u-net: Cross-contextual attention mechanism for skin lesion segmentation. Proceedings of the 2023 IEEE 20th International Symposium on Biomedical Imaging (ISBI), Cartagena, Colombia. · DOI
- He, S., Bao, R., Li, J., Stout, J., Bjornerud, A., Grant, P.E., and Ou, Y. (2023). Computer-Vision Benchmark Segment-Anything Model (SAM) in Medical Images: Accuracy in 12 Datasets. arXiv.
- Jiang, P.T., and Yang, Y. (2023). Segment Anything is A Good Pseudo-label Generator for Weakly Supervised Semantic Segmentation. arXiv.
- Osco, 2023, The segment anything model (sam) for remote sensing applications: From zero to one shot, Int. J. Appl. Earth Obs. Geoinf., 124, 103540
- Xu, 2023, The research of a novel WOG-YOLO algorithm for autonomous driving object detection, Sci. Rep., 13, 3699, 10.1038/s41598-023-30409-1 · DOI
- Qureshi, R., Ragab, M.G., Abdulkader, S.J., Alqushaib, A., Sumiea, E.H., and Alhussian, H. (2023). A Comprehensive Systematic Review of YOLO for Medical Object Detection (2018 to 2023), Authorea Preprints. · DOI
- Pan, 2022, Accuracy of RGB-D camera-based and stereophotogrammetric facial scanners: A comparative study, J. Dent., 127, 104302, 10.1016/j.jdent.2022.104302 · DOI
- Yan, S., Yang, J., Käpylä, J., Zheng, F., Leonardis, A., and Kämäräinen, J. (2021, January 11–17). DepthTrack: Unveiling the Power of RGBD Tracking. Proceedings of the IEEE/CVF International Conference on Computer Vision, Montreal, BC, Canada. · DOI
- Tychola, 2022, On 3D Reconstruction Using RGB-D Cameras, Digital, 2, 401, 10.3390/digital2030022 · DOI
- Li, 2022, High-quality indoor scene 3D reconstruction with RGB-D cameras: A brief review, Comput. Vis. Media, 8, 369, 10.1007/s41095-021-0250-8 · DOI
- Linqin, 2017, Dynamic hand gesture recognition using RGB-D data for natural human-computer interaction, J. Intell. Fuzzy Syst., 32, 3495, 10.3233/JIFS-169287 · DOI
- Gao, W., and Miao, P. (2018, January 16–17). RGB-D Camera Assists Virtual Studio through Human Computer Interaction. Proceedings of the 2018 3rd International Conference on Materials Science, Machinery and Energy Engineering (MSMEE 2018), Chennai, India.
- Schwarz, 2018, RGB-D object detection and semantic segmentation for autonomous manipulation in clutter, Int. J. Robot. Res., 37, 437, 10.1177/0278364917713117 · DOI
- Lee, 2016, RGB-D camera based wearable navigation system for the visually impaired, Comput. Vis. Image Underst., 149, 3, 10.1016/j.cviu.2016.03.019 · DOI · Paper page
- Endres, 2013, 3-D mapping with an RGB-D camera, IEEE Trans. Robot., 30, 177, 10.1109/TRO.2013.2279412 · DOI
- Lai, K., Bo, L., Ren, X., and Fox, D. (2013). Consumer Depth Cameras for Computer Vision: Research Topics and Applications, Springer.
- Prankl, J., Aldoma, A., Svejda, A., and Vincze, M. (October, January 28). RGB-D object modelling for object recognition and tracking. Proceedings of the 2015 IEEE/RSJ International Conference on Intelligent robots And Systems (IROS), Hamburg, Germany. · DOI
- Gené-Mola, J., Llorens, J., Rosell-Polo, J.R., Gregorio, E., Arnó, J., Solanelles, F., Martínez-Casasnovas, J.A., and Escolà, A. (2020). Assessing the Performance of RGB-D Sensors for 3D Fruit Crop Canopy Characterization under Different Operating and Lighting Conditions. Sensors, 20. · DOI
- Wang, Y., Xu, S., and Zell, A. (2020, January 22–24). Real-time 3D Object Detection from Point Clouds using an RGB-D Camera. Proceedings of the 9th International Conference on Pattern Recognition Applications and Methods—Volume 1: ICPRAM, INSTICC, Valletta, Malta. · DOI
- Redmon, J., and Farhadi, A. (2018). YOLOv3: An Incremental Improvement. arXiv.
- Lin, T.Y., Maire, M., Belongie, S., Bourdev, L., Girshick, R., Hays, J., Perona, P., Ramanan, D., Zitnick, C.L., and Dollár, P. (2015). Microsoft COCO: Common Objects in Context. arXiv. · DOI · Paper page
- Vissiere, 2022, Optimised calibration of machine vision system for close range photogrammetry based on machine learning, J. King Saud Univ.-Comput. Inf. Sci., 34, 7406
- Paradiso, 2018, A versatile calibration procedure for portable coded aperture gamma cameras and RGB-D sensors, Nucl. Instrum. Methods Phys. Res. Sect. A Accel. Spectrometer Detect. Assoc. Equip., 886, 125, 10.1016/j.nima.2017.12.065 · DOI
- Moreno, C. (2016, January 19–21). A Comparative Study of Filtering Methods for Point Clouds in Real-Time Video Streaming. Proceedings of the World Congress on Engineering and Computer Science, San Francisco, CA, USA.
- Balta, 2018, Fast Statistical Outlier Removal Based Method for Large 3D Point Clouds of Outdoor Environments, IFAC-PapersOnLine, 51, 348, 10.1016/j.ifacol.2018.11.566 · DOI
- Kingma, D.P., and Ba, J. (2017). Adam: A Method for Stochastic Optimization. arXiv.
- Bertels, J., Eelbode, T., Berman, M., Vandermeulen, D., Maes, F., Bisschops, R., and Blaschko, M.B. (2019). Medical Image Computing and Computer Assisted Intervention—MICCAI 2019, Springer International Publishing.
- Jena, R., Zhornyak, L., Doiphode, N., Chaudhari, P., Buch, V., Gee, J., and Shi, J. (2023). Beyond mAP: Towards better evaluation of instance segmentation. arXiv. · DOI
- Gimeno, 2021, Generalizing AUC Optimization to Multiclass Classification for Audio Segmentation With Limited Training Data, IEEE Signal Process. Lett., 28, 1135, 10.1109/LSP.2021.3084501 · DOI
- Hurtado, J.V., and Valada, A. (2024). Semantic Scene Segmentation for Robotics. arXiv.
Cited by
Ali, M. L., & Zhang, Z. (2024) · Computers · doi:10.3390/computers13120336 · Cited by 383
Metadata
- Authors
- El Ghazouali, S., Mhirit, Y., Oukhrid, A., Michelucci, U., & Nouira, H.
- Affiliations
- TOELT LLC, AI Lab, 8406 Winterthur, Switzerland
- Independent Researcher, 75000 Paris, France
- Independent Researcher, 2502 Biel/Bienne, Switzerland
- Laboratoire National de Métrologie et d'Essais (FR)
- Venue
- Sensors
- Publisher
- MDPI AG
- Published
- 2024-04-30
- Volume
- 24
- Issue
- 9
- Pages
- 2889
- ISSN
- 1424-8220 (ISSN-L)
- PMC
- PMC11086350
- OpenAlex
- W4392425776
- Cited by
- 24
- References
- 6
- Citations by year
- 2026: 7 · 2025: 14 · 2024: 3
- FWCI
- 3.36
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Licence
- Locations
- Sensors (publishedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- arXiv (Cornell University) (submittedVersion, cc-by-nc-sa)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion, cc-by-sa)
- arXiv (Cornell University)
- Zenodo (CERN European Organization for Nuclear Research) (cc-by)
- Funders
- EURAMET program (22DIT01-ViDiT, 23IND08-DiVision)
- European Union’s Horizon 2020 research and innovation program (22DIT01-ViDiT, 23IND08-DiVision)
- Topics
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Advanced Neural Network Applications
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Advanced Vision and Imaging
- Physical Sciences › Computer Science › Computer Graphics and Computer-Aided Design › 3D Shape Modeling and Analysis
- Keywords
- 3D object reconstruction, 3D object segmentation, RGB-D camera, YOLO, instance segmentation, object detection, depth images, RGB-D fusion, 6D pose estimation, SLAM, 3D scene understanding
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
How to cite
Cite CoChat for the checks on this page, and the paper for its own findings.
- This page
- CoChat. (2026). Citation check: FusionVision: A Comprehensive Approach of 3D Object Reconstruction and Segmentation from RGB-D Cameras Using YOLO and Fast Segment Anything. https://app.cochat.ai/papers/10.3390/s24092889
- The paper
- El Ghazouali, S., Mhirit, Y., Oukhrid, A., Michelucci, U., & Nouira, H. (2024). FusionVision: A Comprehensive Approach of 3D Object Reconstruction and Segmentation from RGB-D Cameras Using YOLO and Fast Segment Anything. Sensors. https://doi.org/10.3390/s24092889
