

The DOI matches its DataCite record; 49 of the 49 references it cites were found in a registry or an index; 10 of the 38 sources its claims cite were checked for support.
Score-Based Generative Modeling through Stochastic Differential Equations
Open accessAbstract
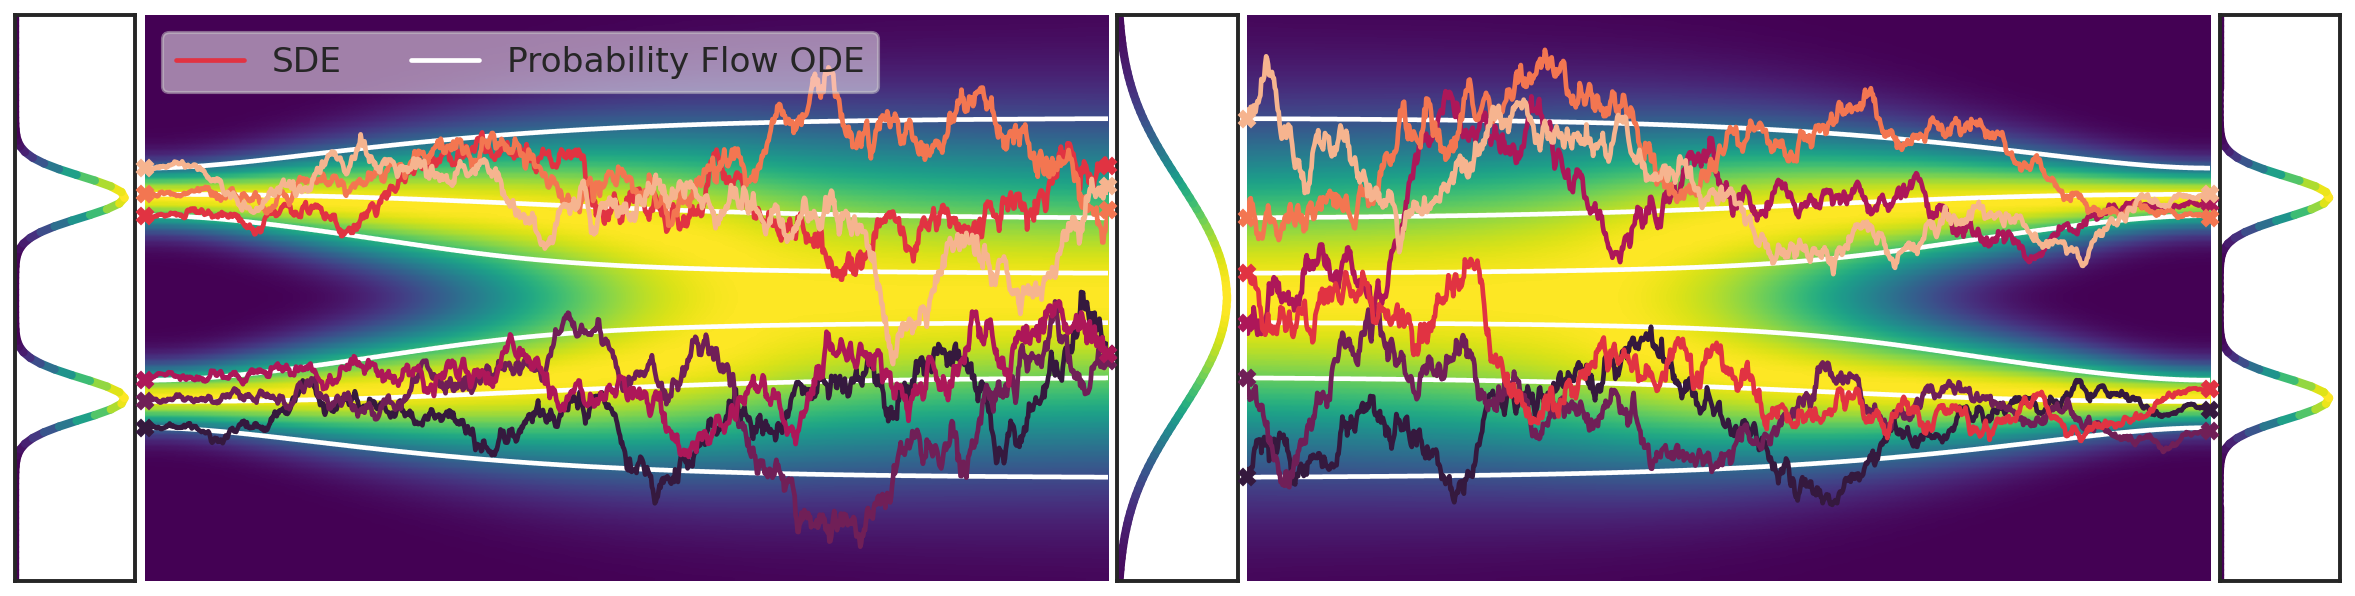
Creating noise from data is easy; creating data from noise is generative modeling. We present a stochastic differential equation (SDE) that smoothly transforms a complex data distribution to a known prior distribution by slowly injecting noise, and a corresponding reverse-time SDE that transforms the prior distribution back into the data distribution by slowly removing the noise. Crucially, the reverse-time SDE depends only on the time-dependent gradient field (\aka, score) of the perturbed data distribution. By leveraging advances in score-based generative modeling, we can accurately estimate these scores with neural networks, and use numerical SDE solvers to generate samples. We show that this framework encapsulates previous approaches in score-based generative modeling and diffusion probabilistic modeling, allowing for new sampling procedures and new modeling capabilities. In particular, we introduce a predictor-corrector framework to correct errors in the evolution of the discretized reverse-time SDE. We also derive an equivalent neural ODE that samples from the same distribution as the SDE, but additionally enables exact likelihood computation, and improved sampling efficiency. In addition, we provide a new way to solve inverse problems with score-based models, as demonstrated with experiments on class-conditional generation, image inpainting, and colorization. Combined with multiple architectural improvements, we achieve record-breaking performance for unconditional image generation on CIFAR-10 with an Inception score of 9.89 and FID of 2.20, a competitive likelihood of 2.99 bits/dim, and demonstrate high fidelity generation of 1024 x 1024 images for the first time from a score-based generative model.
Overview
AI snapshot
Written from the paper’s full text.
TL;DR
The paper introduces a stochastic differential equation framework that unifies score-based generative modeling and diffusion probabilistic modeling by reversing a noising SDE with a learned time-dependent score network. It derives predictor-corrector and probability-flow ODE samplers, enabling exact likelihoods and controllable generation, and reports record CIFAR-10 sample quality and likelihood plus first 1024×1024 score-based samples.
Key findings
- SMLD and DDPM are unified as discretizations of Variance Exploding (VE) and Variance Preserving (VP) SDEs; the reverse-time SDE depends only on the time-dependent score, and a new sub-VP SDE is proposed.
- Predictor-Corrector samplers improve sample quality, while the probability flow ODE enables exact likelihood computation, fast adaptive sampling, latent manipulation, and uniquely identifiable encoding.
- On CIFAR-10, NCSN++ cont. (deep, VE) achieves an Inception score of 9.89 and FID of 2.20 for unconditional generation; DDPM++ cont. (deep, sub-VP) achieves 2.99 bits/dim on uniformly dequantized CIFAR-10.
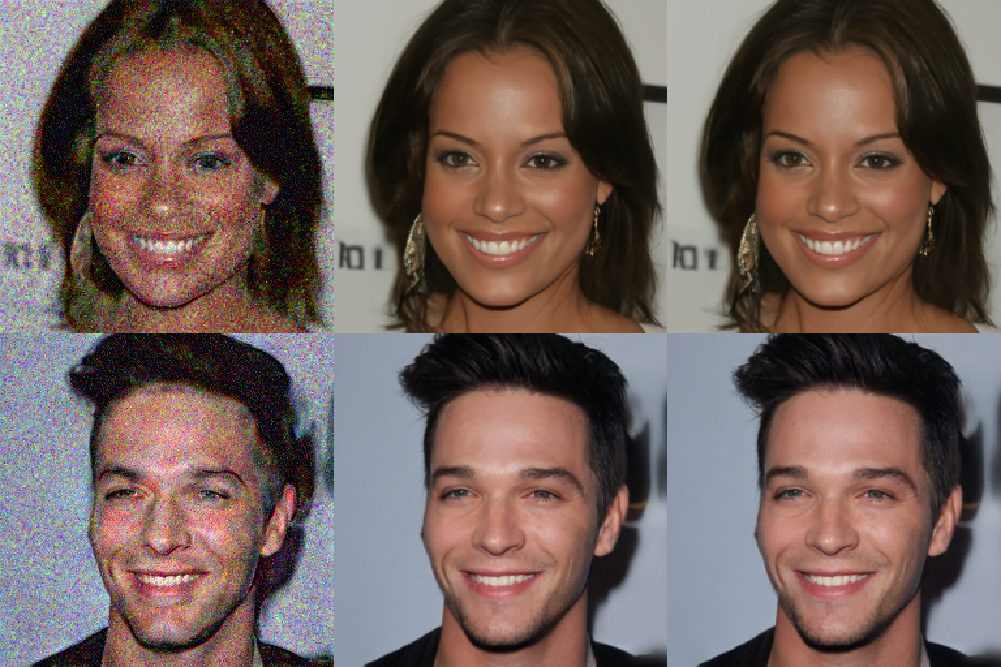
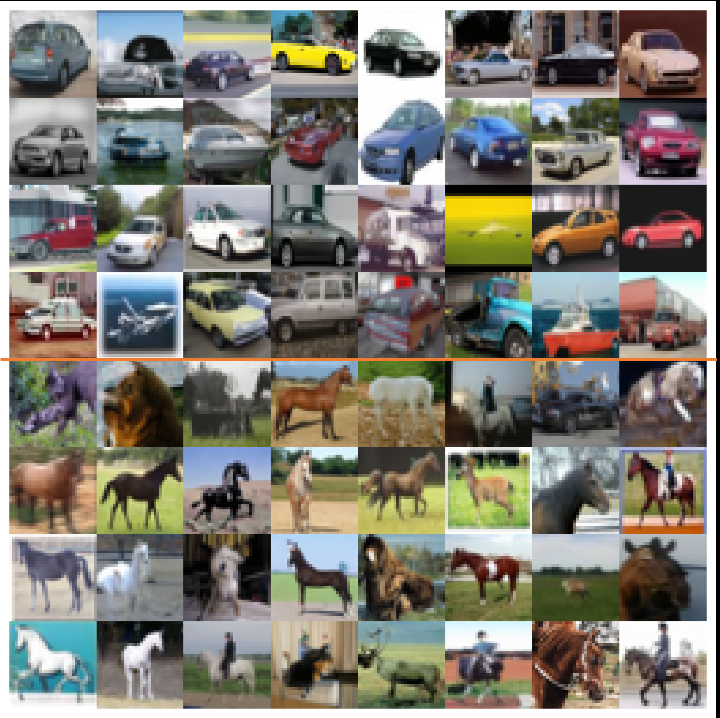
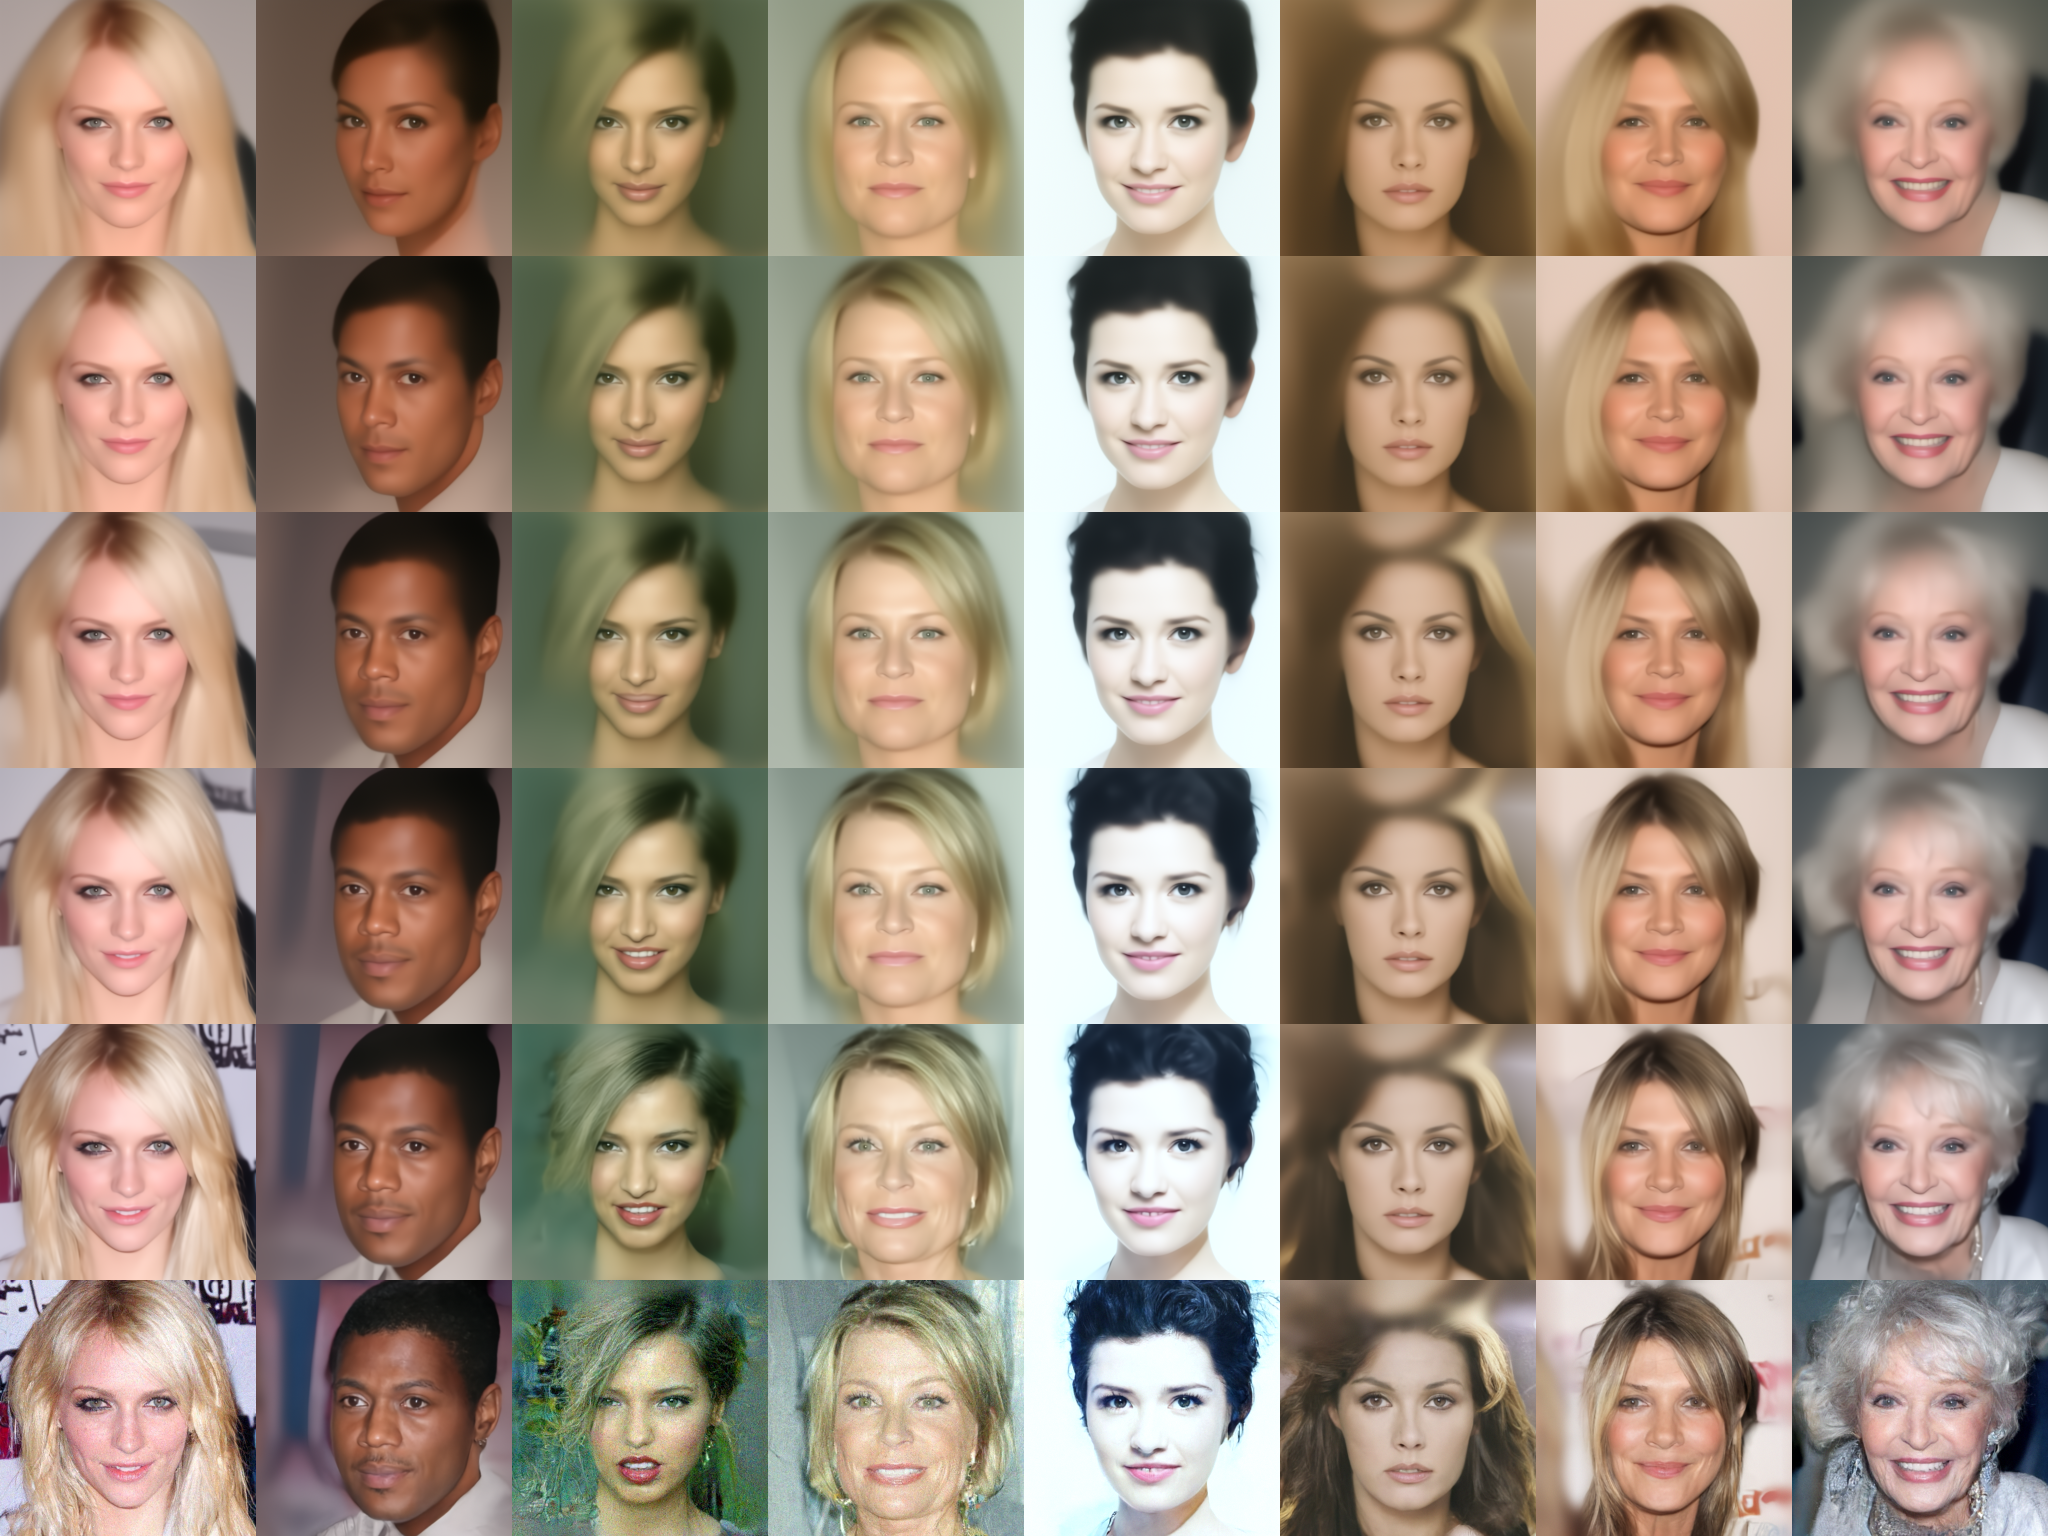
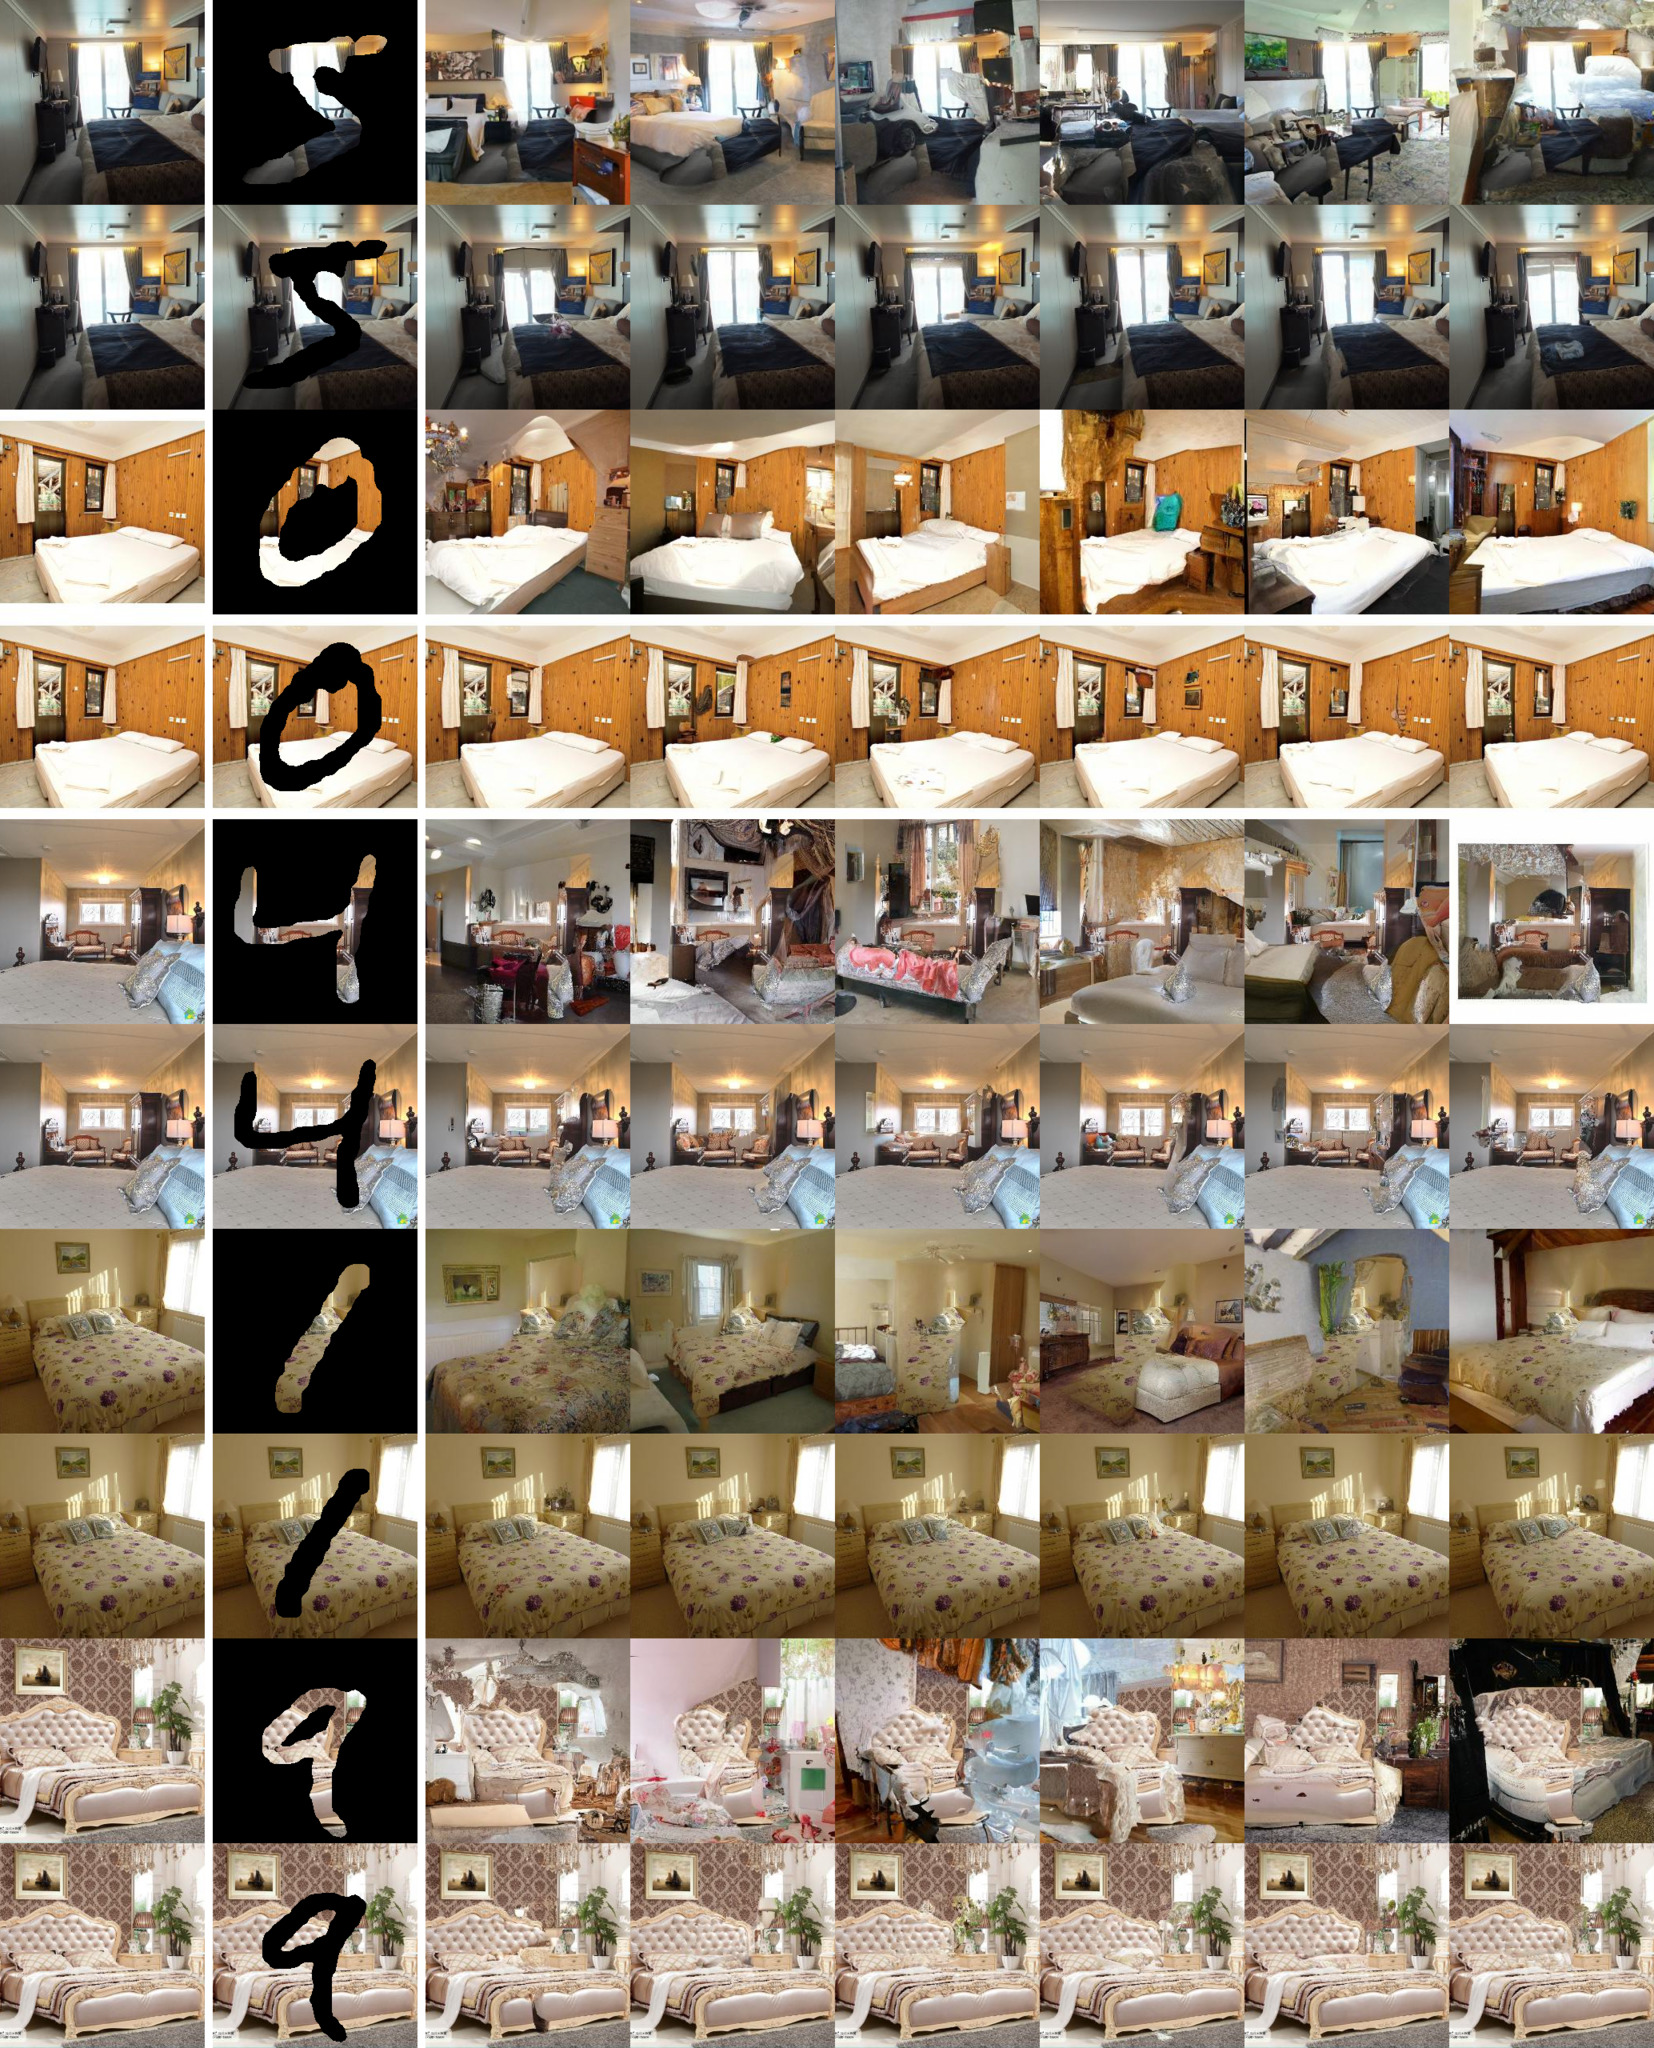
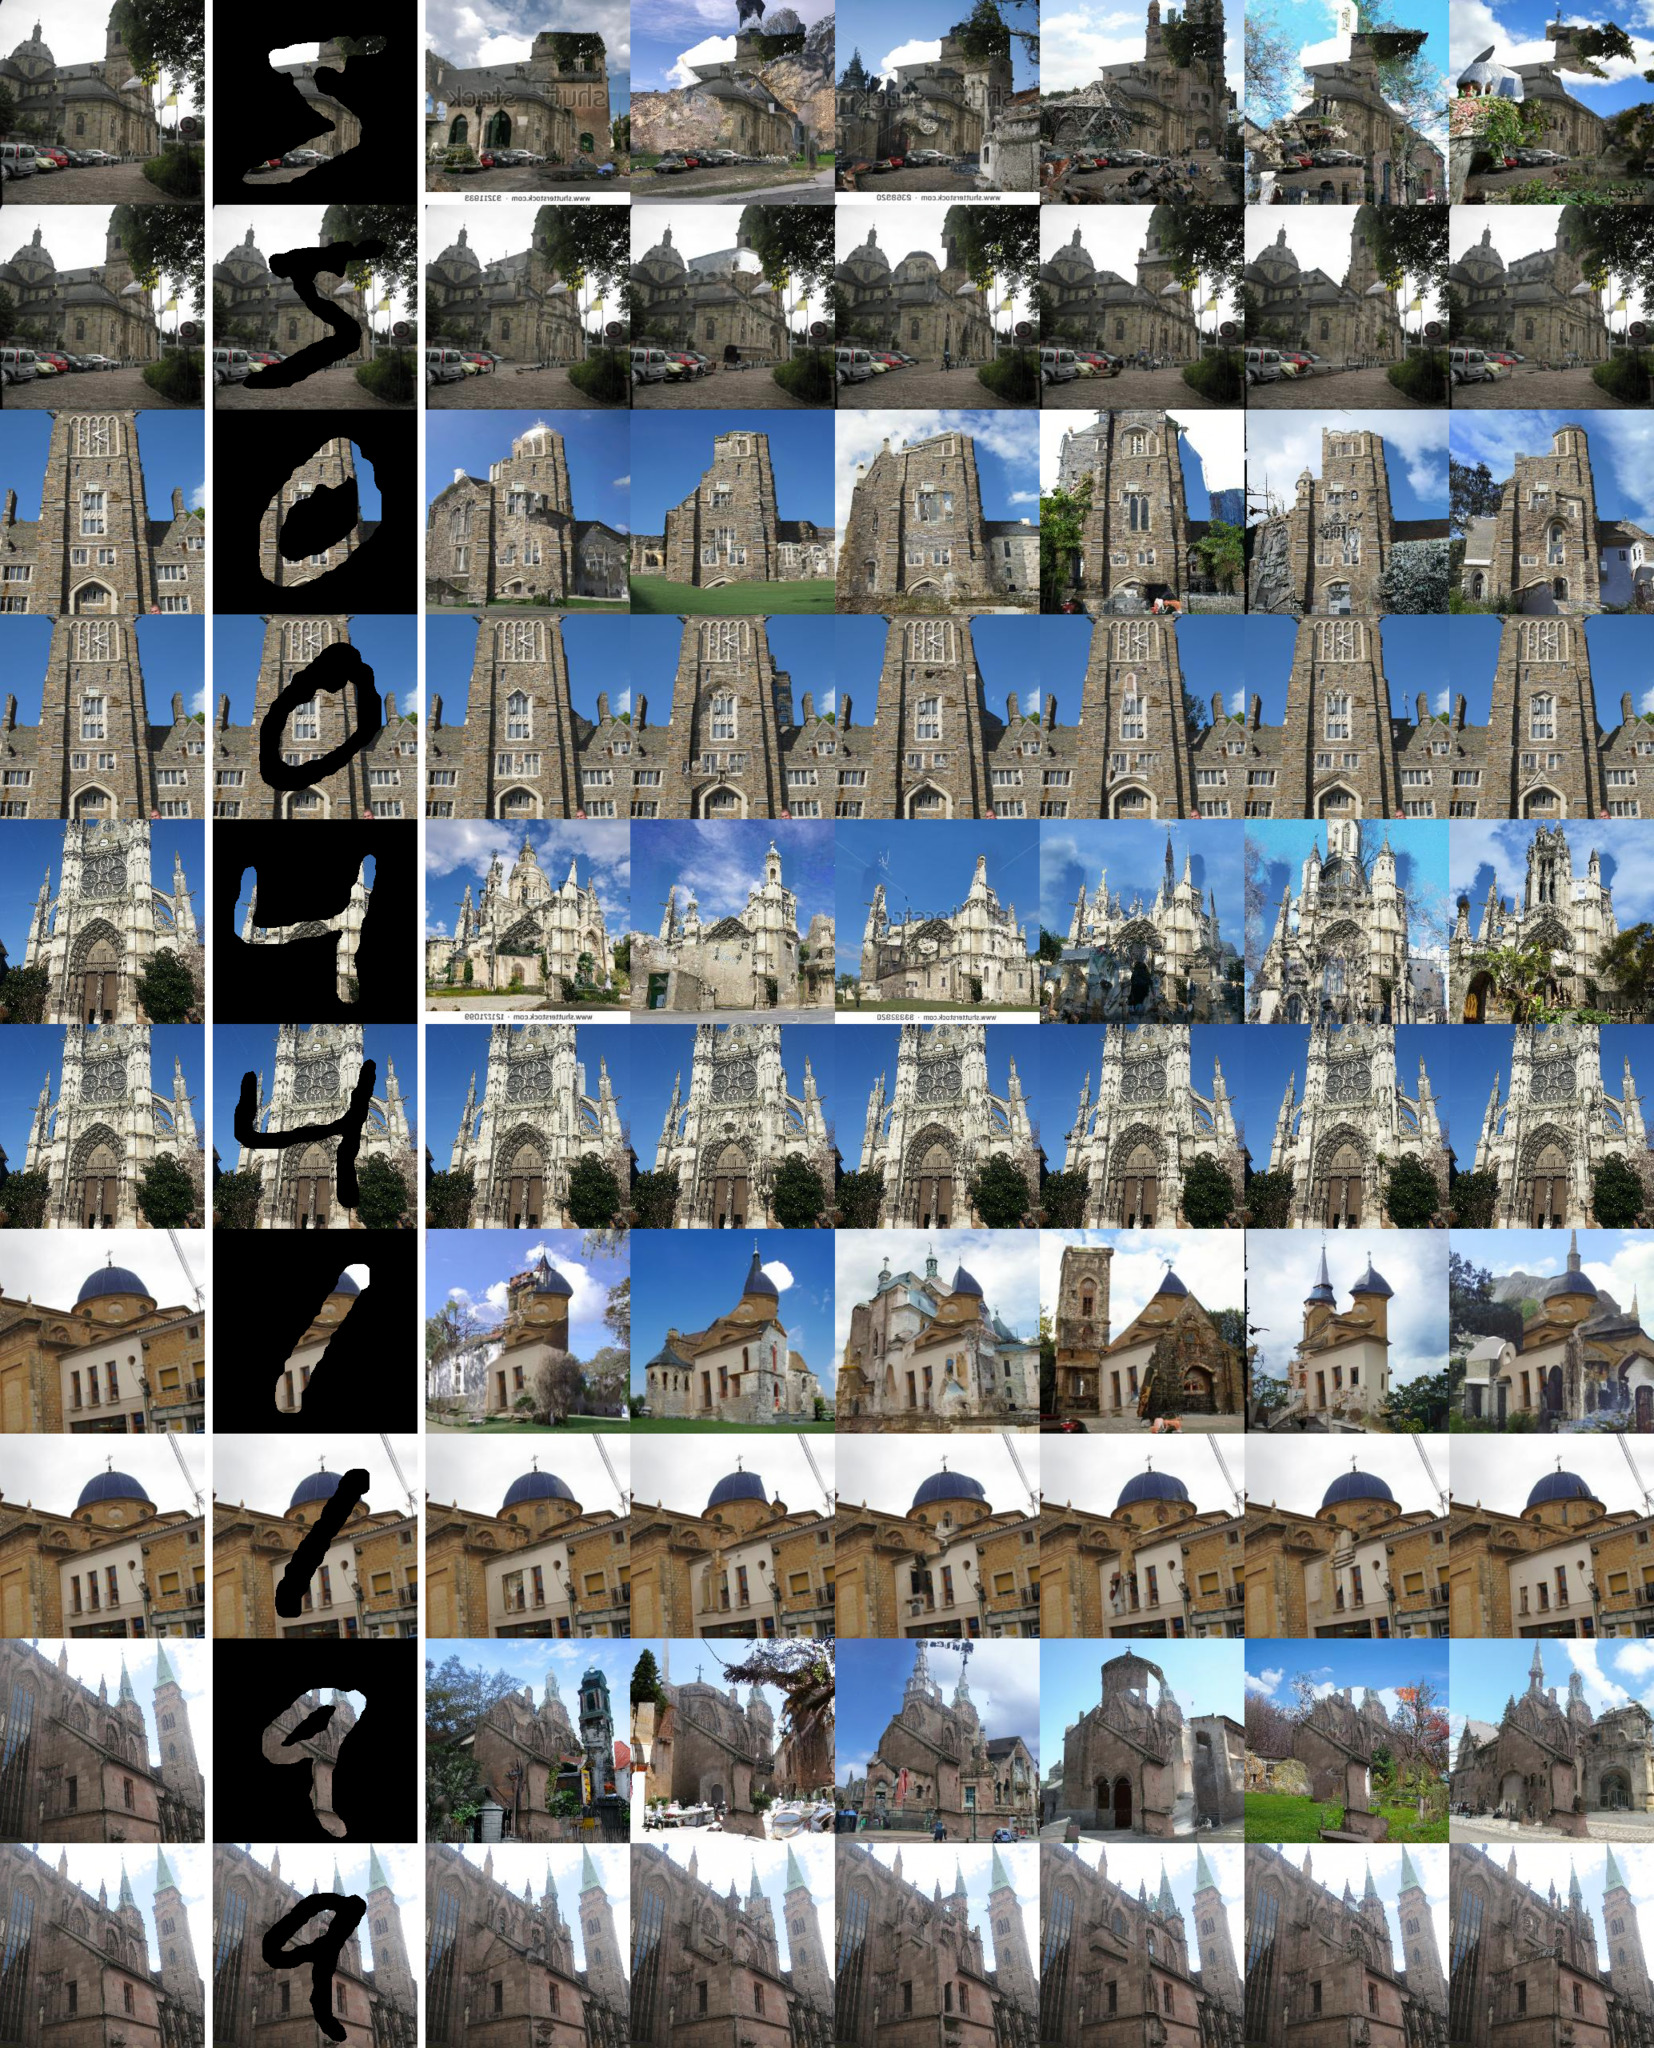
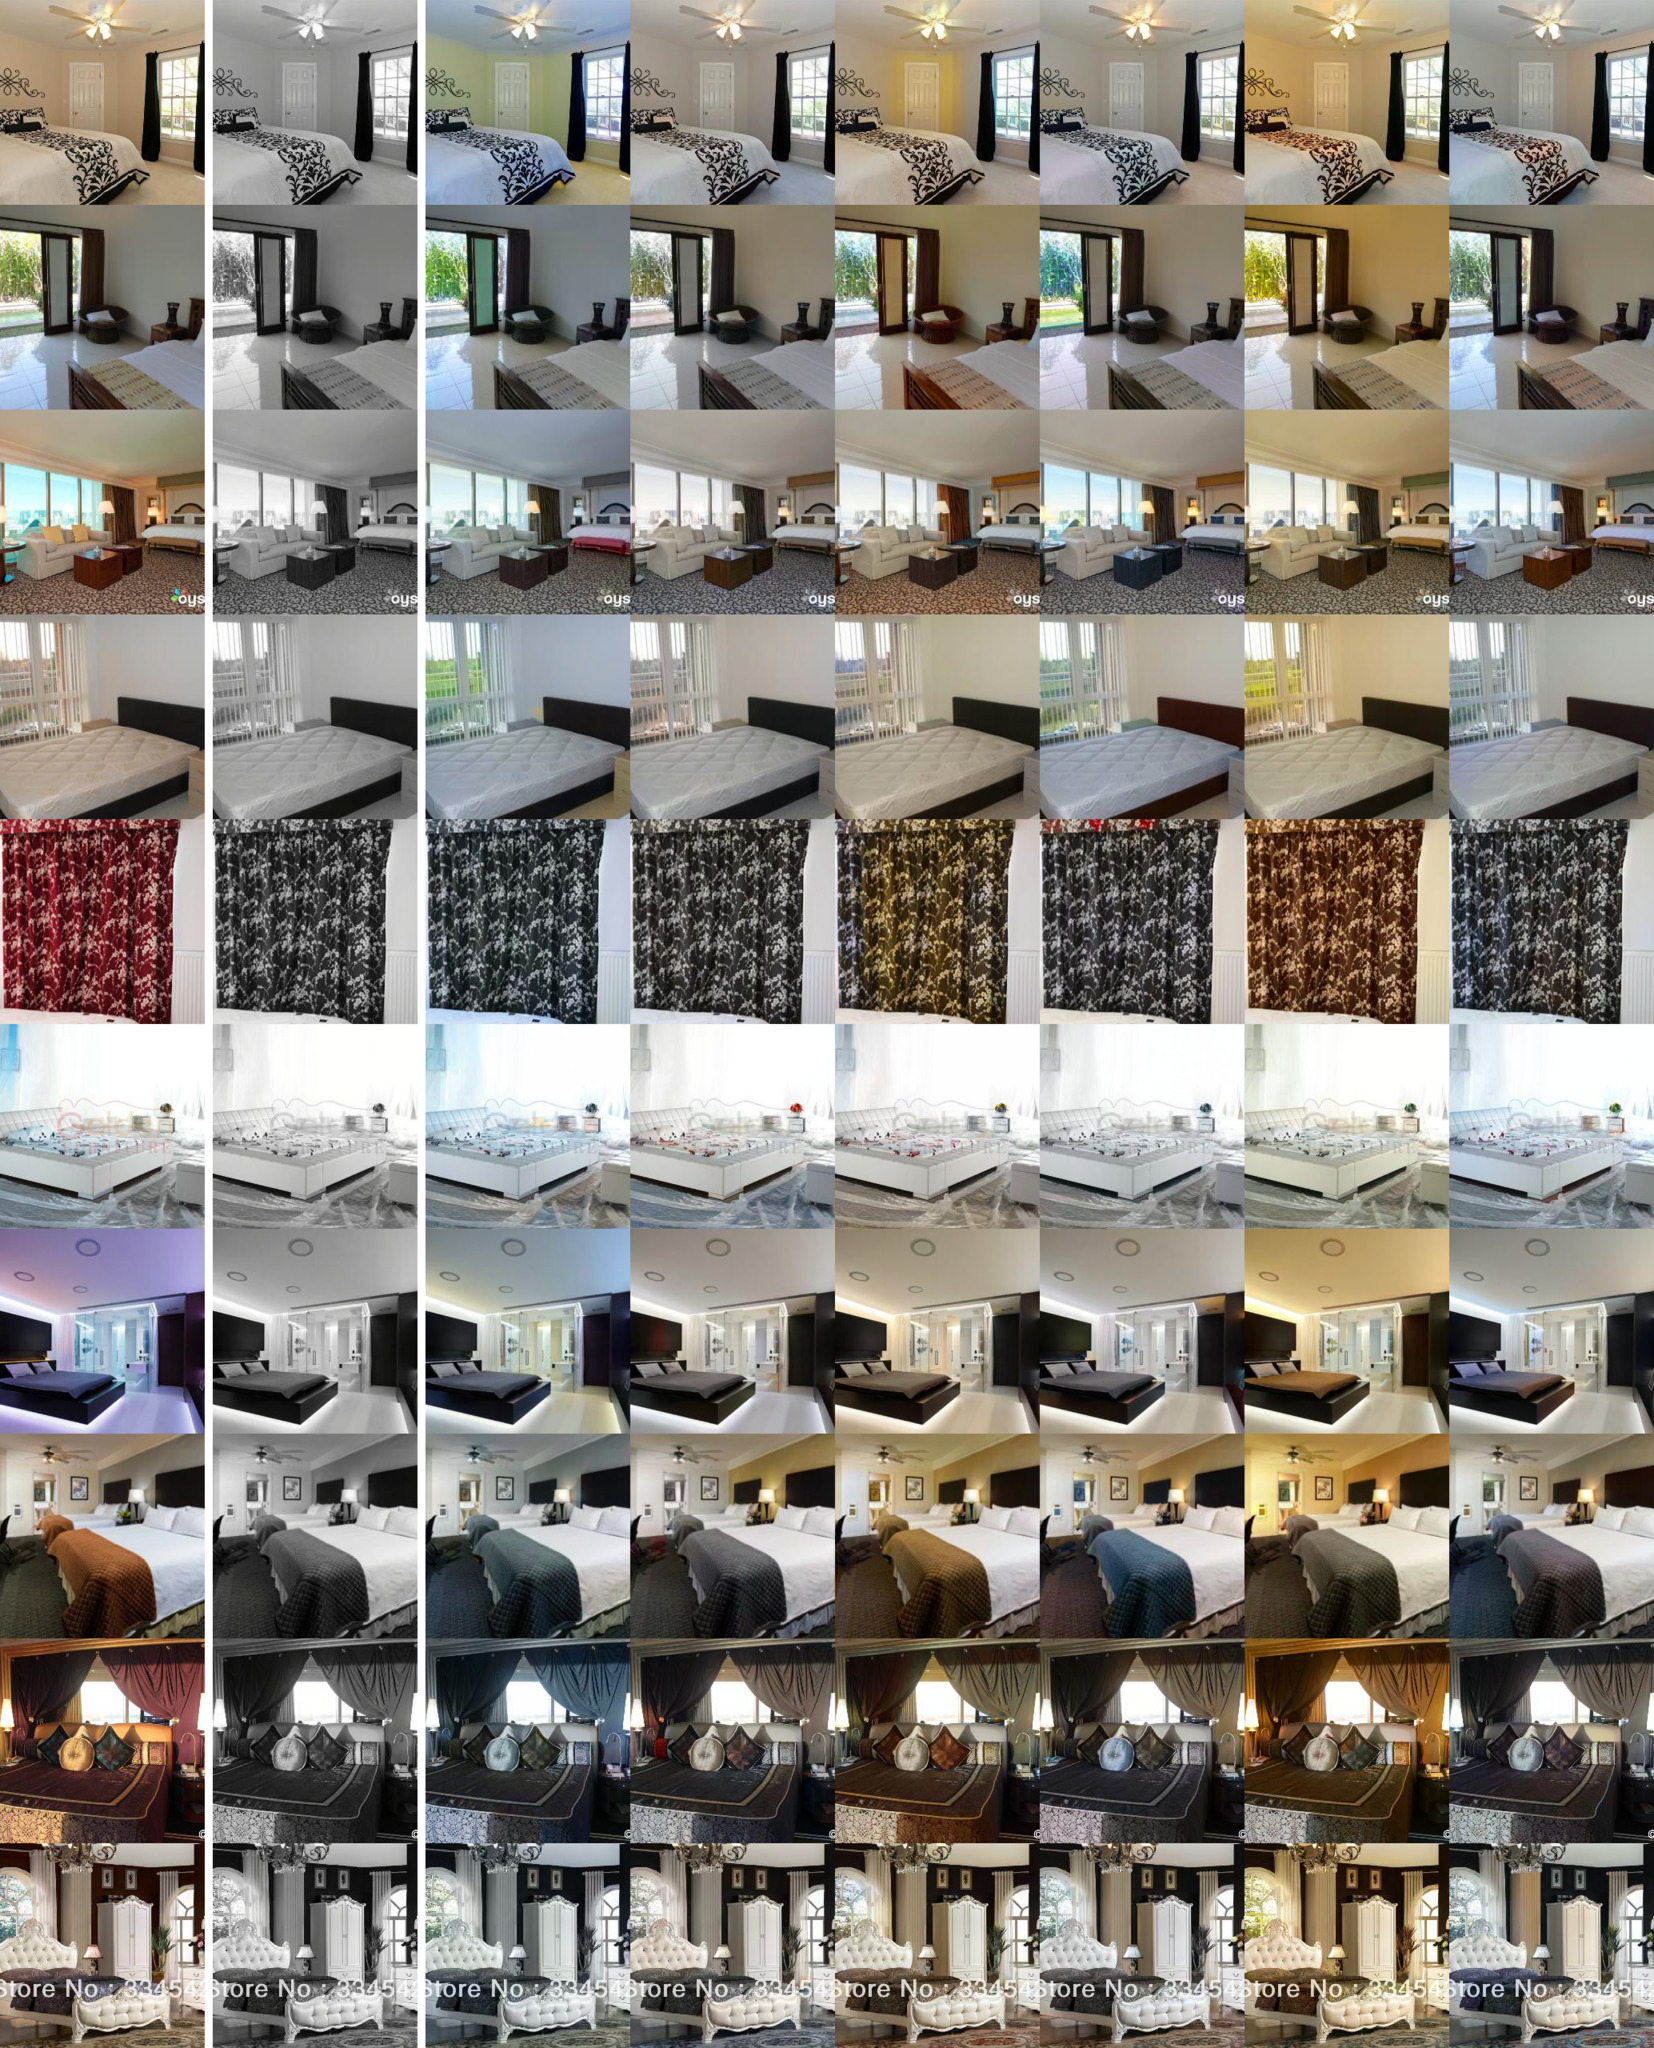
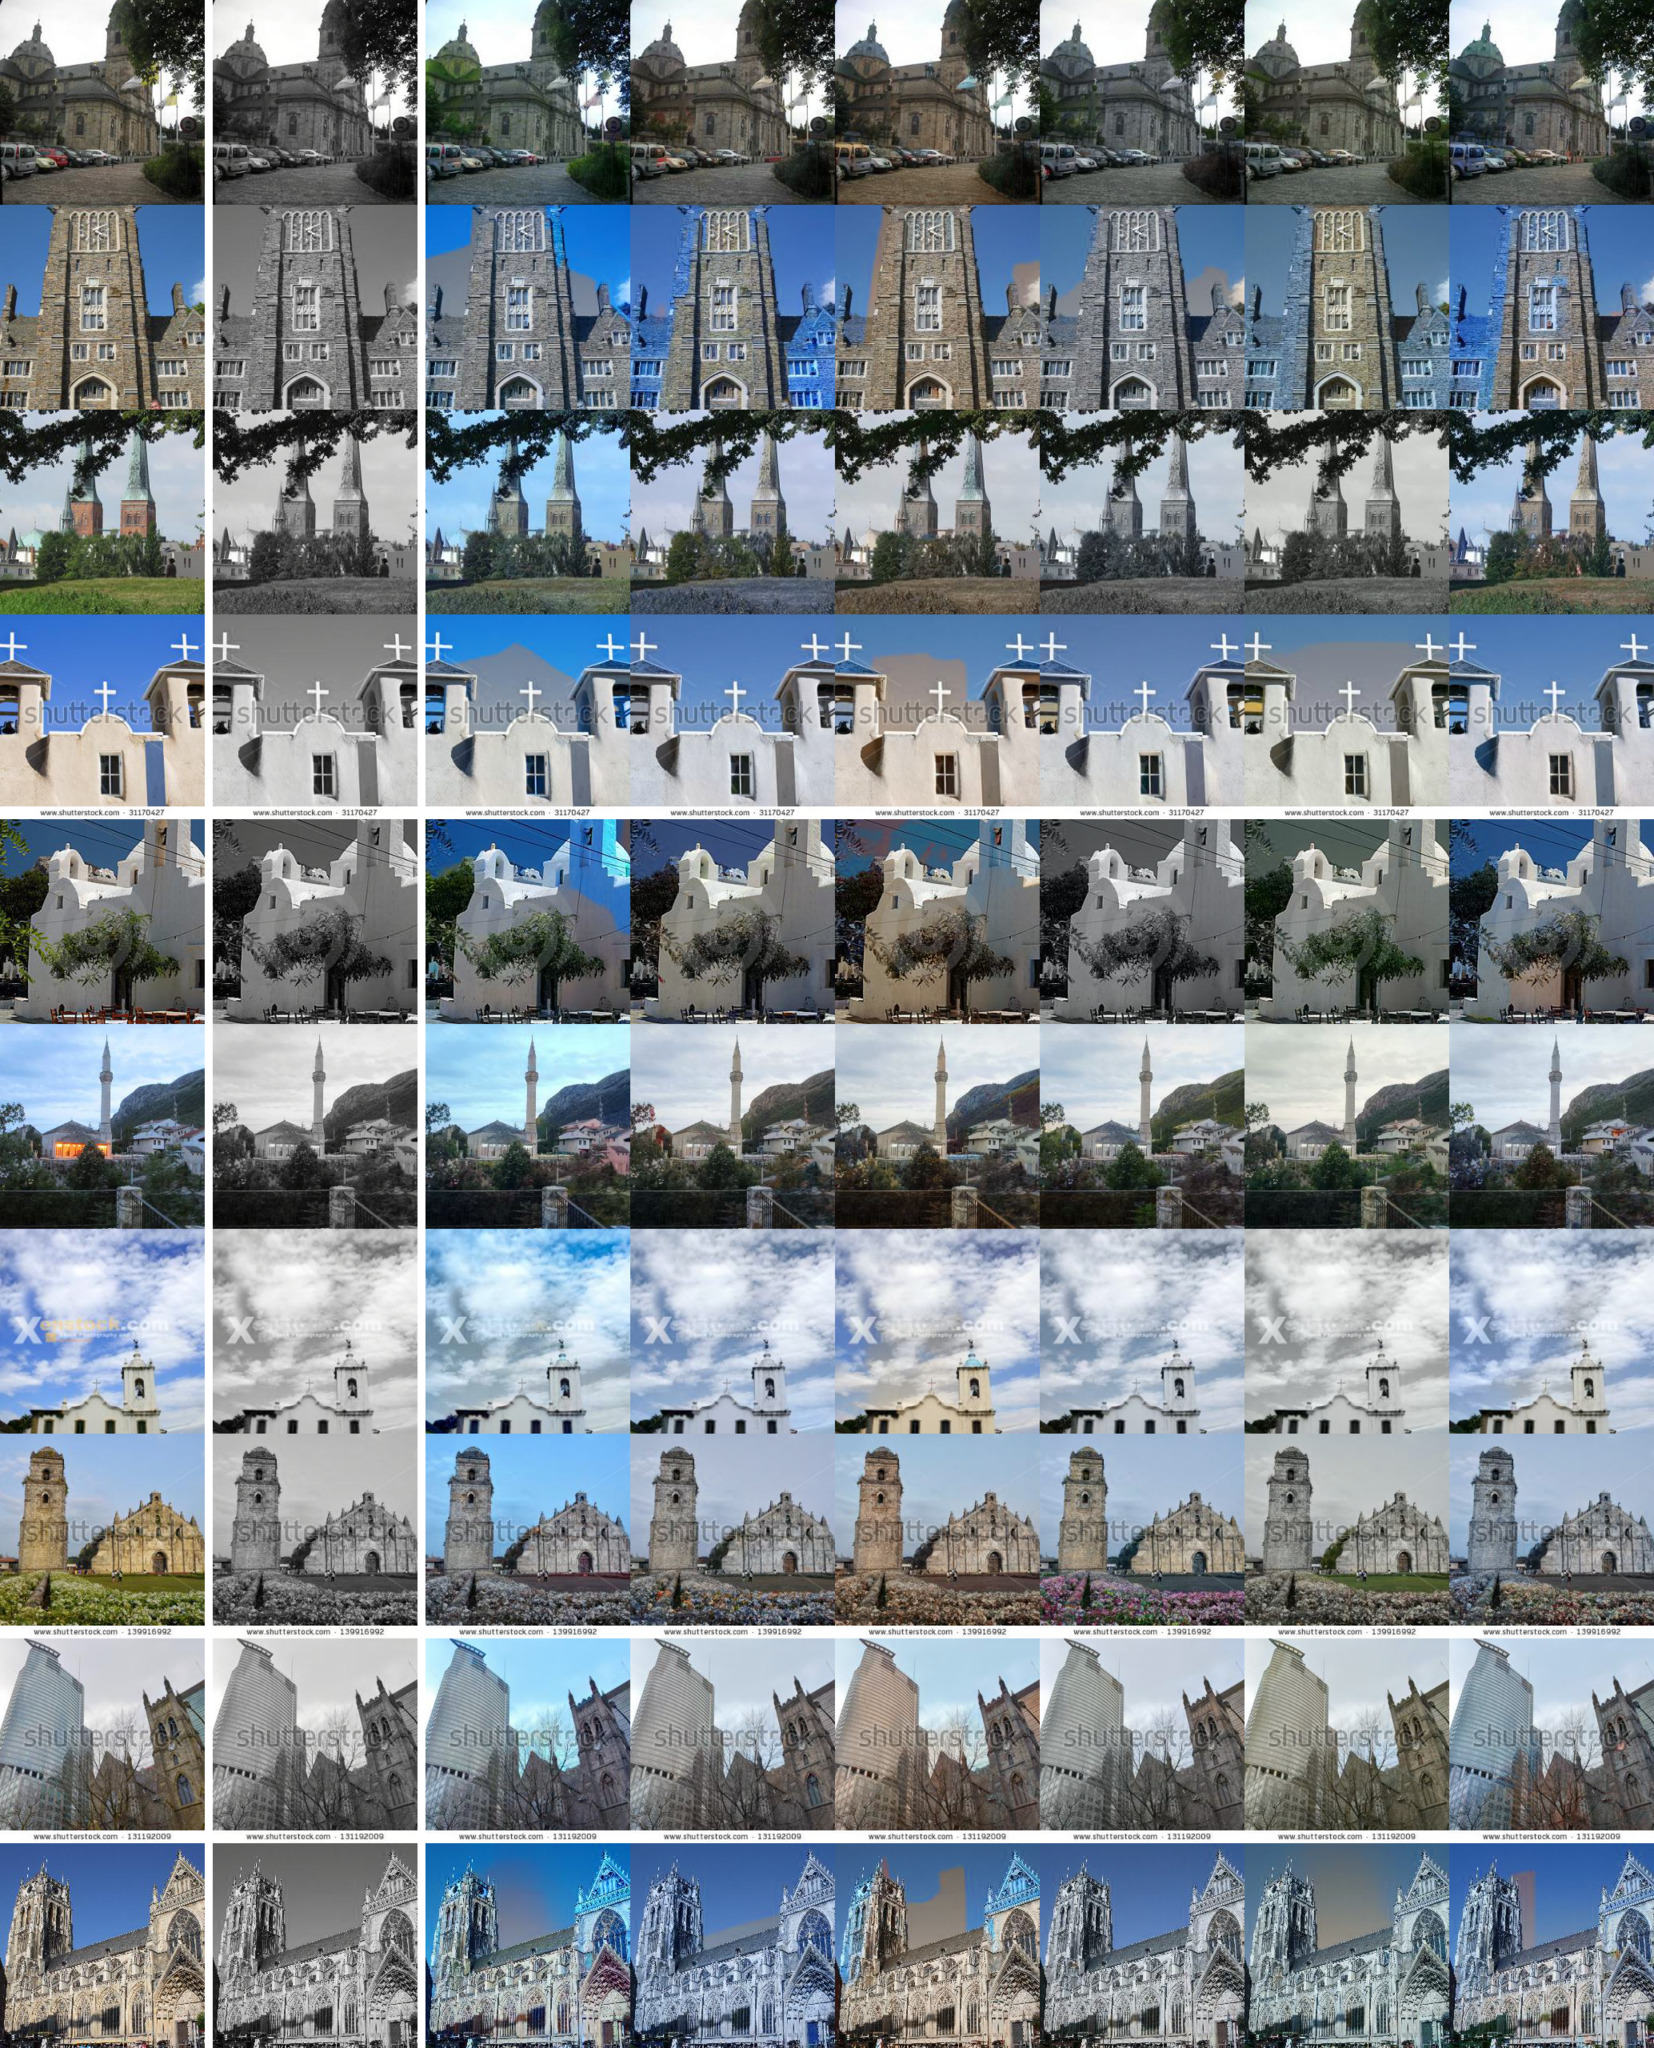
- Controllable generation is demonstrated for class-conditional CIFAR-10, image inpainting and colorization on 256×256 LSUN, and high-fidelity 1024×1024 CelebA-HQ samples from a score-based model.
Methods
- The framework models data corruption as a continuous-time diffusion process `dx = f(x,t)dt + g(t)dw`, derives the reverse-time SDE and probability flow ODE, and trains a time-dependent score model `sθ(x,t)` via denoising score matching; VE, VP, and sub-VP SDEs are instantiated.
- Sampling uses general-purpose SDE solvers, reverse diffusion, ancestral sampling, Predictor-Corrector samplers with Langevin correctors, and probability flow ODE solvers; architecture improvements yield NCSN++ and DDPM++ models.
- Experiments evaluate FID, Inception score, bits/dim negative log-likelihood, and qualitative samples on CIFAR-10, CelebA-HQ 1024×1024, and LSUN 256×256 bedroom/church; class-conditional generation uses a time-dependent classifier.
Limitations
- Stated: sampling remains slower than GANs on the same datasets, and the breadth of available samplers introduces many hyperparameters; future work is needed for automatic selection and tuning.
- Stated/evident: the 1024×1024 samples are not perfect, with visible flaws such as facial symmetry; architecture exploration for VP SDEs was limited to CIFAR-10 due to limited computing resources.
- Evident: likelihood comparisons omit models evaluated with variational dequantization or discrete data except DDPM ELBO values annotated with an asterisk; sample quality and likelihood favor different SDEs (VE better sample quality, VP/sub-VP better likelihood), requiring per-domain experimentation.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
78 Own interpretation · 40 Own result · 14 Sources not found · 14 No basis given · 5 Partly supported · 4 Supported · 4 No full text of the sources · 3 Not checked yet · 2 Own method · 1 Not supported · accuracy not yet measured
At least one cited source doesn’t support this claim or points to a different paper, and none confirmed it — see the verdicts below.
In the paper
“Unlike most current invertible models, our encoding is uniquely identifiable, meaning that with sufficient training data, model capacity, and optimization accuracy, the encoding for an input is uniquely determined by the data distribution (Roeder et al., 2020).”
§ 4 SOLVING THE REVERSE SDE > 4.3 PROBABILITY FLOW AND CONNECTION TO NEURAL ODES
What the sources say
- Disputedcites Roeder et al., 2020 sourceExperimental — accuracy not yet measured
The paper supports an asymptotic identifiability result, but not a uniquely determined encoding. Section 3.2 (p. 4) defines identifiability only up to an invertible linear transformation, and the Introduction (p. 1) describes distinct representation functions learned from the same data distribution. (LLM, conf=0.90)
Checked by a reasoning model — may be wrong.
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Disputed
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“Although DDPM (Ho et al., 2020) was recently reported to achieve higher sample quality than SMLD (Song & Ermon, 2019; 2020), we show that with better architectures and new sampling algorithms allowed by our framework, the latter can catch up”
What the sources say
- Not matchedcites Ho et al., 2020
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
- Not matchedcites Song & Ermon, 2019
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
- Supportedcites Song & Ermon, 2020 source
The Introduction (p. 1) describes improved score-based models and Langevin-dynamics sampling, supporting the citation’s identification of the SMLD line of work. The statement that SMLD can catch up to DDPM is introduced as the citing authors’ own result (“we show”), not attributed to this source; this paper does not establish a DDPM comparison. (LLM, conf=0.82)
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Not matched
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“Crucially, the reverse-time SDE depends only on the time-dependent gradient field (a.k.a., score) of the perturbed data distribution.”
- Also stated in: § 1 INTRODUCTION · plain
“Crucially, this reverse process satisfies a reverse-time SDE (Anderson, 1982), which can be derived from the forward SDE given the score of the marginal probability densities as a function of time.”
What the sources say
- Partly supportedcites Anderson, 1982 sourceExperimental — accuracy not yet measured
The theorem in Section 3 (eqs. 3.11–3.12) makes the reverse-time drift depend on the time-dependent density and its spatial derivative, consistent with the score being relevant. But its formula also includes the forward drift and diffusion coefficient, so the reverse-time SDE does not depend only on the score. The copy provides no page number for this passage. (LLM, conf=0.88)
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Also stated in: § 1 INTRODUCTION · plain
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“When the score function is approximated by the time-dependent score-based model, which is typically a neural network, this is an example of a neural ODE (Chen et al., 2018).”
§ 4 SOLVING THE REVERSE SDE > 4.3 PROBABILITY FLOW AND CONNECTION TO NEURAL ODES
What the sources say
- Partly supportedcites Chen et al., 2018 sourceExperimental — accuracy not yet measured
The Introduction (p. 1) defines a neural ODE as continuous dynamics specified by a neural network, supporting the general classification. Our copy does not discuss score functions or establish that approximating one with a time-dependent score-based model yields an ODE, so it does not support that specific application. (LLM, conf=0.84)
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Partly supported
Every source the paper cites for this claim was checked and supports it.
In the paper
“A remarkable result from Anderson (1982) states that the reverse of a diffusion process is also a diffusion process, running backwards in time and given by the reverse-time SDE:”
§ 3 SCORE-BASED GENERATIVE MODELING WITH SDES > 3.2 GENERATING SAMPLES BY REVERSING THE SDE
What the sources say
- Supportedcites Anderson, 1982 source
The Introduction states that, for a wide variety of diffusion processes, a forward-time representation generates a reverse-time representation. Section 3 defines that representation as a reverse-time stochastic differential equation. The paper notes regularity restrictions, so the result is not stated for every diffusion process. (LLM, conf=0.90)
boosteddirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Supported
Every source the paper cites for this claim was checked and supports it.
In the paper
“As noted by Jolicoeur-Martineau et al. (2020), FIDs can be significantly worse without removing this noise.”
§ 0 100 200 300 > 0.00 0.25 0.50 0.75 1.00
What the sources say
- Supportedcites Jolicoeur-Martineau et al., 2020 source
Section 4 says denoising is critical to the FID score even when its effect is not visible to the human eye. The Section 6.1 ablation study reports an improvement in FID from denoising in every comparison, supporting the claim that leaving the noise in generated samples can substantially worsen FID. (LLM, conf=0.93)
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Supported
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“For both SMLD and DDPM models, the generated samples typically contain small noise that is hard to detect by humans.”
§ 0 100 200 300 > 0.00 0.25 0.50 0.75 1.00
What the sources say
- Partly supportedcites Jolicoeur-Martineau et al., 2020 sourceExperimental — accuracy not yet measured
Section 4 reports that denoising final Langevin samples substantially improves FID even though the change cannot be perceived by the human eye. This supports the claim for the paper’s score-matching/Langevin samples, but not its extension to DDPM samples; Section 6.1 says Ho et al. denoised their final sample. (LLM, conf=0.84)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Partly supported
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“demonstrate high fidelity generation of 1024ˆ 1024 images for the first time from a score-based generative model.”
boosted- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Combined with multiple architectural improvements, we achieve record-breaking performance for unconditional image generation on CIFAR-10 with an Inception score of 9.89 and FID of 2.20”
- Also stated in: § 1 INTRODUCTION · plain
“with better architectures and new sampling algorithms allowed by our framework, the latter can catch up—it achieves new state-of-the-art Inception score (9.89) and FID score (2.20) on CIFAR-10”
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Also stated in: § 1 INTRODUCTION · plain
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“a competitive likelihood of 2.99 bits/dim”
- Also stated in: § 1 INTRODUCTION · plain
“we propose a new SDE under our framework that achieves a likelihood value of 2.99 bits/dim on uniformly dequantized CIFAR-10 images”
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Also stated in: § 1 INTRODUCTION · plain
- It may state two separate claims as one. 40
- Probably not a substantial claim. 25
Every source the paper cites for this claim was checked and supports it.
In the paper
“Crucially, this reverse process satisfies a reverse-time SDE (Anderson, 1982), which can be derived from the forward SDE given the score of the marginal probability densities as a function of time.”
What the sources say
- Supportedcites Anderson, 1982 source
The theorem in Section 3, equations (3.11)–(3.12), constructs a reverse-time SDE from the forward process and gives its drift in terms of the time-dependent marginal density and diffusion coefficients. Section 5, equations (5.6)–(5.7), also derives the reverse-time equation using that density. The density-dependent term is the score term when the diffusion coefficient is independent of the state. (LLM, conf=0.91)
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Supported
Every source the paper cites for this claim was checked and supports it.
In the paper
“The bits/dim values in Table 2 are computed with atol=1e-5 and rtol=1e-5, same as Grathwohl et al. (2018).”
§ 2 log > 0.0 0.2 0.4 0.6 0.8 1.0
What the sources say
- Supportedcites Grathwohl et al. (2018) source
Appendix C (page not provided) says FFJORD set both atol and rtol to the same tolerance and used 10^-5 for most experiments. That supports the cited comparison of solver tolerances; the paper specifies different settings for its tabular experiments. The citing paper’s own Table 2 values cannot be checked against this source. (LLM, conf=0.89)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
- Supported
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“a task that was previously only achievable by some GAN models and VQ-VAE-2 (Razavi et al., 2019).”
What the sources say
- Partly supportedcites Razavi et al., 2019 sourceExperimental — accuracy not yet measured
Section 5.1 (pp. 6–7) reports that VQ-VAE-2 generated 1024 × 1024 face images, but the dataset was FFHQ, not CelebA-HQ. The Related Works section (p. 5) discusses high-resolution GANs and other approaches; it does not establish that only GAN models and VQ-VAE-2 could perform the claimed task. (LLM, conf=0.88)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
- Partly supported
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“In addition, we propose a new SDE under our framework that achieves a likelihood value of 2.99 bits/dim on uniformly dequantized CIFAR-10 images, setting a new record on this task.”
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Our best model for likelihoods, DDPM++ cont. (deep, sub-VP), similarly doubles the network depth and achieves a log-likelihood of 2.99 bits/dim with the continuous objective in Eq. (7).”
§ 100 101 102 103 > 4.4 ARCHITECTURE IMPROVEMENTS
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“although samples across different ε look visually the same to human eyes.”
§ 2 log > 0.0 0.2 0.4 0.6 0.8 1.0
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“As shown in Table 3, VE SDEs typically provide better sample quality than VP/sub-VP SDEs, but we also empirically observe that their likelihoods are worse than VP/sub-VP SDE counterparts.”
§ 100 101 102 103 > 4.4 ARCHITECTURE IMPROVEMENTS
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“For all predictors, adding one corrector step for each predictor step (PC1000) doubles computation but always improves sample quality (against P1000).”
§ 4 SOLVING THE REVERSE SDE > 4.2 PREDICTOR-CORRECTOR SAMPLERS
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
In the paper
“For the same DDPM model in Ho et al. (2020), we obtain better bits/dim than ELBO, since our likelihoods are exact”
§ 4 SOLVING THE REVERSE SDE > 4.3 PROBABILITY FLOW AND CONNECTION TO NEURAL ODES
What the sources say
- Not matchedcites Ho et al. (2020)
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Not matched
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“By switching to the continuous training objective in Eq. (7), and increasing the network depth, we can further improve sample quality for all models.”
§ 100 101 102 103 > 4.4 ARCHITECTURE IMPROVEMENTS
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We observe that our reverse diffusion sampler always outperform ancestral sampling, and corrector-only methods (C2000) perform worse than other competitors (P2000, PC1000) with the same computation”
§ 4 SOLVING THE REVERSE SDE > 4.2 PREDICTOR-CORRECTOR SAMPLERS
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“For sampling, it is important to use an appropriate ε for better Inception scores and FIDs, although samples across different ε look visually the same to human eyes.”
§ 2 log > 0.0 0.2 0.4 0.6 0.8 1.0
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Our best model for sample quality, NCSN++ cont. (deep, VE), doubles the network depth and sets new records for both inception score and FID on unconditional generation for CIFAR-10.”
§ 100 101 102 103 > 4.4 ARCHITECTURE IMPROVEMENTS
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
In the paper
“Using a black-box ODE solver (Dormand & Prince, 1980) not only produces high quality samples (Table 2, details in Appendix D.4), but also allows us to explicitly trade-off accuracy for efficiency. With a larger error tolerance, the number of function evaluations can be reduced by over 90% without affecting the visual quality of samples (Fig. 3).”
What the sources say
- Not checked — no full text of the sourcecites Dormand & Prince, 1980 source
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Our optimal architecture for the VE SDE, named NCSN++, achieves an FID of 2.45 on CIFAR-10 with PC samplers, while our optimal architecture for the VP SDE, called DDPM++, achieves 2.78.”
§ 100 101 102 103 > 4.4 ARCHITECTURE IMPROVEMENTS
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Our endeavor gives rise to new state-of-the-art sample quality on CIFAR-10, new state-of-the-art likelihood on uniformly dequantized CIFAR-10, and enables the first high-fidelity image samples of resolution 1024ˆ 1024 from score-based generative models.”
§ 0 100 200 300 > 3.06 ˘ .03
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We observe that different interpolation methods result in performance differences but maintain the general trend of predictor-corrector methods performing on par or better than predictor-only or corrector-only samplers.”
§ 0 100 200 300 > 3.06 ˘ .03
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The basic NCSN++ model with 4 residual blocks per resolution achieves an FID of 2.45 on CIFAR-10, whereas the basic DDPM++ model achieves an FID of 2.78.”
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“For progressive growing, it is not clear which combination of configurations consistently performs the best, but the results are typically better than when no progressive growing architecture is used.”
hedgedconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The NCSN++ architecture worked decently well for VP SDEs, ranked 4th place over all 144 possible configurations.”
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Its FID score is 2.41, same for both VP and sub-VP SDEs.”
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We can therefore approximate the reverse-time SDE by training a time-dependent neural network to estimate the scores, and then produce samples using numerical SDE solvers.”
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“This enables applications such as class-conditional generation, image inpainting, colorization and other inverse problems, all achievable using a single unconditional score-based model without re-training.”
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We also derive an equivalent neural ODE that samples from the same distribution as the SDE, but additionally enables exact likelihood computation, and improved sampling efficiency.”
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
None of the sources cited for this claim have been checked yet.
In the paper
“we propose two special methods not viable for general SDEs: (i) Predictor-Corrector (PC) samplers that combine numerical SDE solvers with score-based MCMC approaches, such as Langevin MCMC (Parisi, 1981) and HMC (Neal et al., 2011); and (ii) deterministic samplers based on the probability flow ordinary differential equation (ODE).”
What the sources say
- Not checked — no full text of the sourcecites Parisi, 1981 source
- Not matchedcites Neal et al., 2011
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The latter allows for fast adaptive sampling via black-box ODE solvers, flexible data manipulation via latent codes, a uniquely identifiable encoding, and notably, exact likelihood computation.”
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: unclear — It is unclear why the paper says it holds.
It may state two separate claims as one.
None of the sources cited for this claim could be matched to a paper in Crossref, so there is nothing to check it against.
In the paper
“Denoising diffusion probabilistic modeling (DDPM) (Sohl-Dickstein et al., 2015; Ho et al., 2020) trains a sequence of probabilistic models to reverse each step of the noise corruption, using knowledge of the functional form of the reverse distributions to make training tractable.”
What the sources say
- Not matchedcites Sohl-Dickstein et al., 2015
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
- Not matchedcites Ho et al., 2020
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
- Not matched
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The former unifies and improves over existing sampling methods for score-based models.”
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: unclear — It is unclear why the paper says it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We can employ any general-purpose SDE solver to integrate the reverse-time SDE for sampling.”
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper may give no reason why it holds.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“By leveraging advances in score-based generative modeling, we can accurately estimate these scores with neural networks, and use numerical SDE solvers to generate samples.”
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
In the paper
“Score matching with Langevin dynamics (SMLD) (Song & Ermon, 2019) estimates the score (i.e., the gradient of the log probability density with respect to data) at each noise scale, and then uses Langevin dynamics to sample from a sequence of decreasing noise scales during generation.”
What the sources say
- Not matchedcites Song & Ermon, 2019
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
- Not matched
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We can modulate the generation process by conditioning on information not available during training, because the conditional reverse-time SDE can be efficiently estimated from unconditional scores.”
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: unclear — It is unclear why the paper says it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“This process progressively diffuses a data point into random noise, and is given by a prescribed SDE that does not depend on the data and has no trainable parameters.”
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“When the drift and diffusion coefficient of an SDE are not affine, it can be difficult to compute the transition kernel p0tpxptq | xp0qq in closed form.”
plainconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper may give no reason why it holds.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“Therefore, same as the VE SDE, we restrict computation to t P rε, 1s for a small ε ą 0.”
§ 2 log > 0.0 0.2 0.4 0.6 0.8 1.0
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
In the paper
“For example, when using sliced score matching (Song et al., 2019a), our training objective Eq. (7) becomes”
What the sources say
- Not matchedcites Song et al., 2019a
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
- Not matched
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“By integrating Eq. (13), we can encode any datapoint xp0q into a latent space xpT q. Decoding can be achieved by integrating a corresponding ODE for the reverse-time SDE.”
§ 4 SOLVING THE REVERSE SDE > 4.3 PROBABILITY FLOW AND CONNECTION TO NEURAL ODES
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The noise perturbations used in SMLD and DDPM can be regarded as discretizations of two different SDEs.”
- Also stated in: § 3.4 EXAMPLES: VE, VP SDES AND BEYOND · plain
“Therefore, the noise perturbations used in SMLD and DDPM correspond to discretizations of SDEs Eqs. (9) and (11).”
§ 3 SCORE-BASED GENERATIVE MODELING WITH SDES > 3.4 EXAMPLES: VE, VP SDES AND BEYOND
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Also stated in: § 3.4 EXAMPLES: VE, VP SDES AND BEYOND · plain
In the paper
“The SDE has a unique strong solution as long as the coefficients are globally Lipschitz in both state and time (Øksendal, 2003).”
§ 3 SCORE-BASED GENERATIVE MODELING WITH SDES > 3.1 PERTURBING DATA WITH SDES
What the sources say
- Not checked — no full text of the sourcecites Øksendal, 2003 source
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
In the paper
“Leveraging the connection to neural ODEs, we can compute the density defined by Eq. (13) via the instantaneous change of variables formula (Chen et al., 2018). This allows us to compute the exact likelihood on any input data (details in Appendix D.2).”
§ 4 SOLVING THE REVERSE SDE > 4.3 PROBABILITY FLOW AND CONNECTION TO NEURAL ODES
What the sources say
- Not matchedcites Chen et al., 2018
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Not matched
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“As a sanity check for our SDE generalizations to SMLD and DDPM, we compare the perturbation kernels of SDEs and original discrete Markov chains in Fig. 5.”
§ 2 log > 0.0 0.2 0.4 0.6 0.8 1.0
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“In Appendix I.4, we provide a broadly applicable method for obtaining such an estimate without the need of training auxiliary models.”
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Perturbing data with multiple noise scales is key to the success of previous methods.”
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper may give no reason why it holds.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“To overcome this difficulty, we can replace denoising score matching in Eq. (7) with other efficient variants of score matching that do not require computing ∇xptq log p0tpxptq | xp0qq.”
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Our work enables a better understanding of existing approaches, new sampling algorithms, exact likelihood computation, uniquely identifiable encoding, latent code manipulation, and brings new conditional generation abilities to the family of score-based generative models.”
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence. The paper may give no reason why it holds.
In the paper
“Therefore, the original ancestral sampler of Eq. (4) is essentially a different discretization to the same reverse-time SDE. This unifies the sampling method in Ho et al. (2020) as a numerical solver to the reverse-time VP SDE in our continuous framework.”
§ 0 100 200 300 > 0.00 0.25 0.50 0.75 1.00
What the sources say
- Not matchedcites Ho et al., 2020
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Not matched
In the paper
“Therefore, their perturbation kernels p0tpxptq | xp0qq are all Gaussian and can be computed with Eqs. (5.50) and (5.51) in Särkkä & Solin (2019):”
What the sources say
- Not matchedcites Särkkä & Solin (2019)
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Not matched
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Since VE, VP and sub-VP SDEs all have affine drift coefficients, their perturbation kernels p0tpxptq | xp0qq are all Gaussian and can be computed in closed-forms, as discussed in Section 3.3.”
§ 3 SCORE-BASED GENERATIVE MODELING WITH SDES > 3.4 EXAMPLES: VE, VP SDES AND BEYOND
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Our work enables a better understanding of existing approaches, new sampling algorithms, exact likelihood computation, uniquely identifiable encoding, latent code manipulation, and brings new conditional generation abilities to the family of score-based generative models.”
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper may give no reason why it holds.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Additionally, the breadth of samplers one can use when given access to score functions introduces a number of hyper-parameters.”
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. The paper may give no reason why it holds.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We can always simulate the SDE to sample from p0tpxptq | xp0qq, and solve Eq. (19) to train the time-dependent score-based model sθpx, tq.”
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper may give no reason why it holds. It may state two separate claims as one.
In the paper
“Like Eq. (1), Eq. (3) is also a weighted sum of denoising score matching objectives, which implies that the optimal model, sθ˚px̃, iq, matches the score of the perturbed data distribution, ∇x log pαipxq.”
§ 2 BACKGROUND > 2.2 DENOISING DIFFUSION PROBABILISTIC MODELS (DDPM)
What the sources say
- Not matchedcites Ho et al., 2020
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Not matched
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“VE, VP and sub-VP SDEs all have affine drift coefficients.”
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“This is because the discretization strategy of the original DDPM method does not match the variance of the continuous process well when t Ñ 0, which significantly hurts FID scores.”
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: unclear — It is unclear why the paper says it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Colorization is a special case of imputation, except that the known data dimensions are coupled.”
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Because the transformations are all orthogonal matrices, the standard Wiener process wptq will still be a standard Wiener process in the transformed space, allowing us to build an SDE and use the same imputation method in Appendix I.2.”
§ 10 2 10 1 100 101 > 0.577 ´0.816 0
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We can decouple these data dimensions by using an orthogonal linear transformation to map the gray-scale image to a separate channel in a different space, and then perform imputation to complete the other channels before transforming everything back to the original image space.”
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
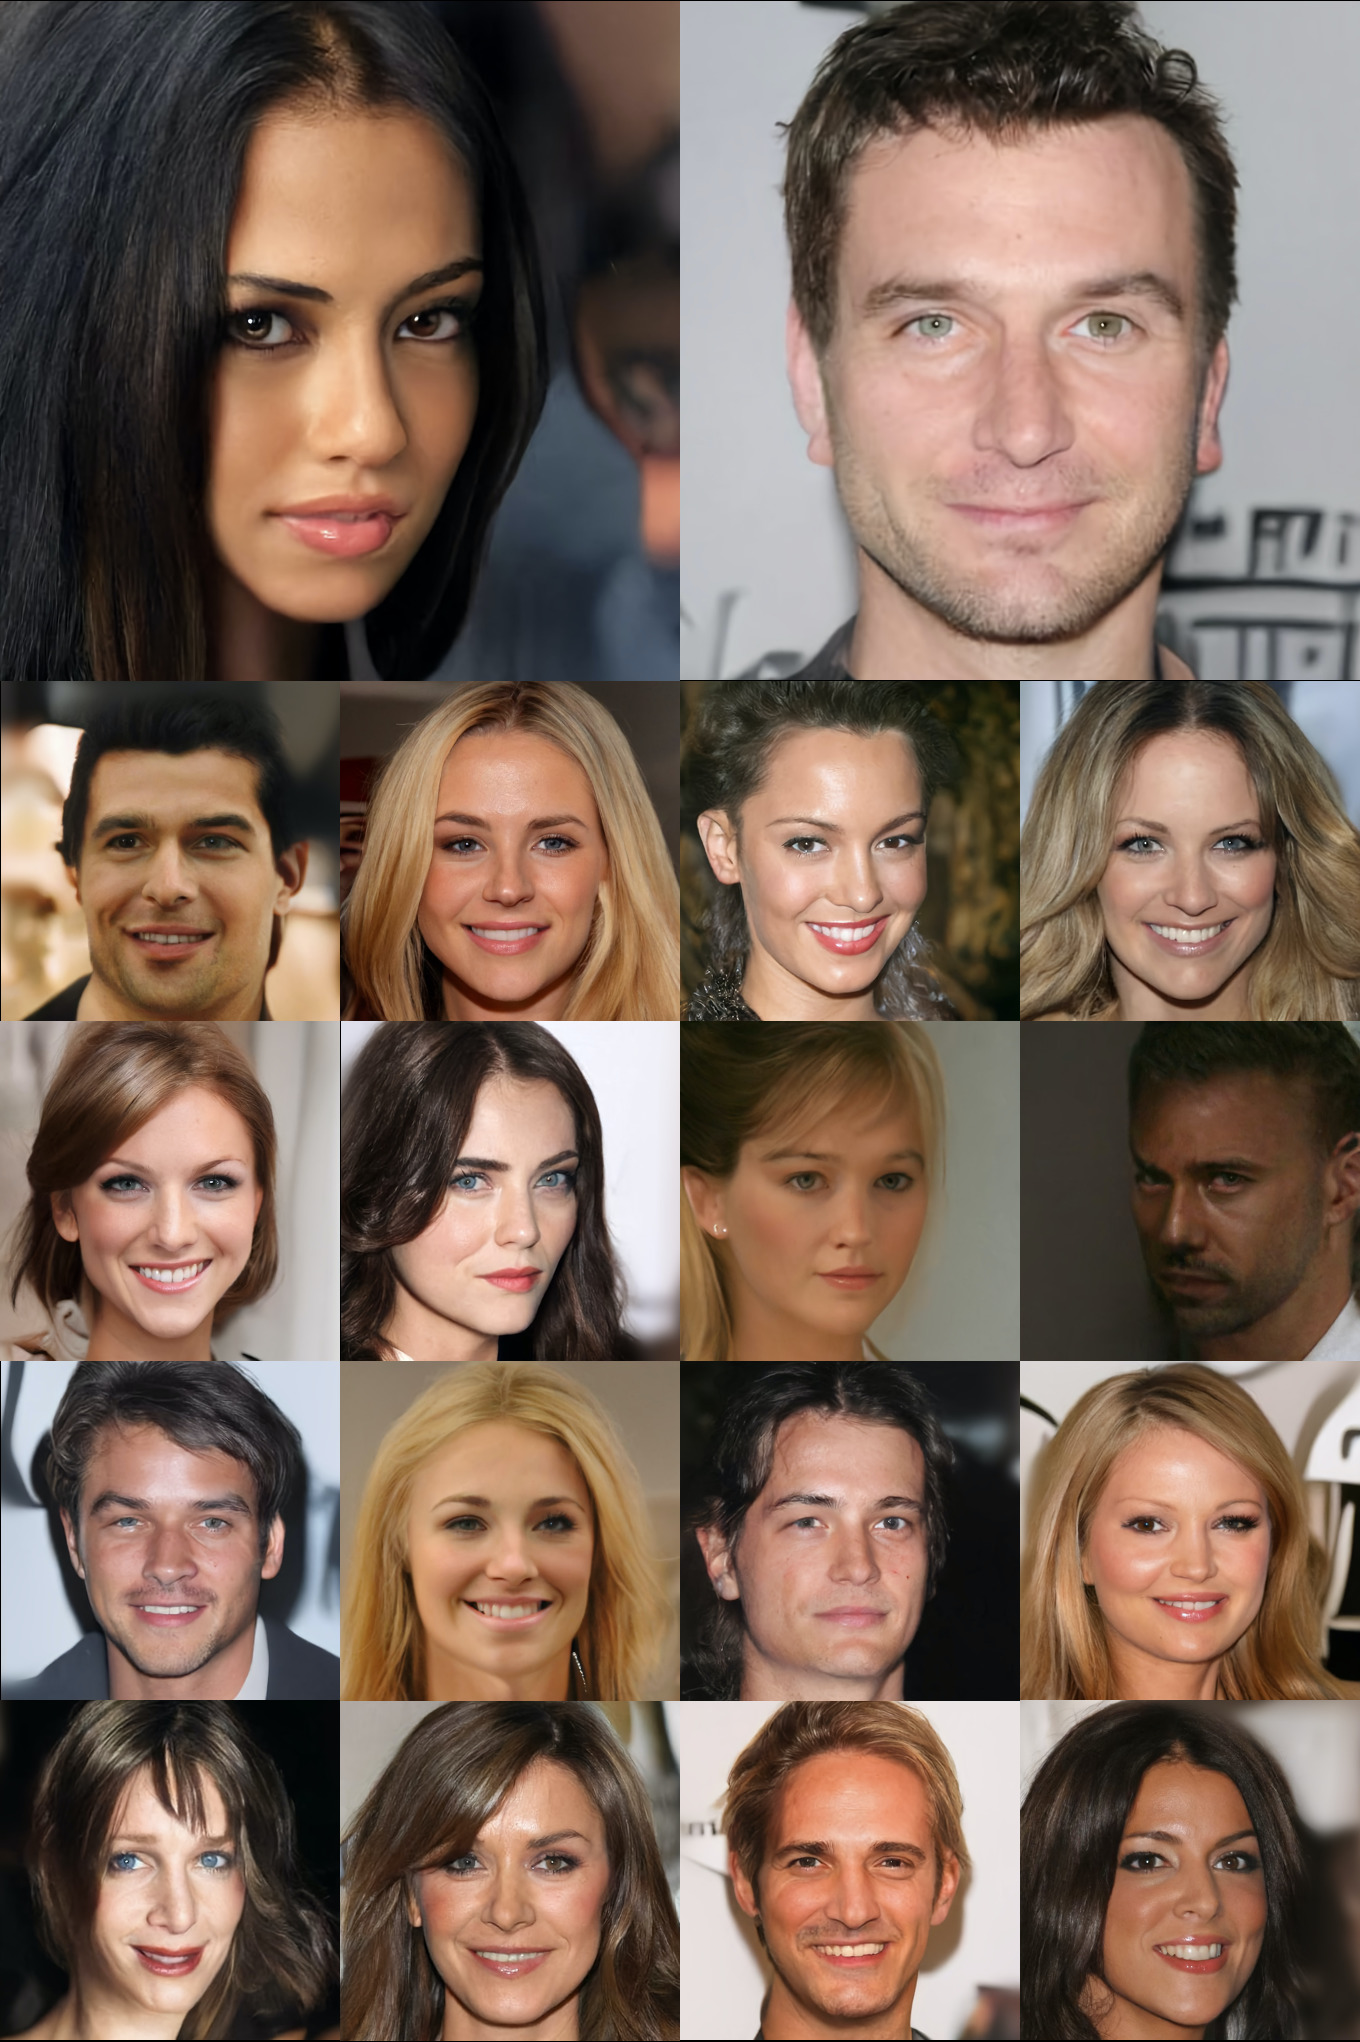
“Although these samples are not perfect (e.g., there are visible flaws on facial symmetry), we believe these results are encouraging and can demonstrate the scalability of our approach.”
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“∇x log ptpxptq | yq”
plain- Asserted: fails — The authors may not put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The authors may not put it forward as true. The paper’s conclusions may not depend on it. The paper may give no reason why it holds.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“All sampling methods we have discussed so far can be applied to the conditional reverse-time SDE for sample generation.”
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Imputation is a special case of conditional sampling.”
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. The paper may give no reason why it holds.
The authors state this as an assumption.
For ease of presentation, the diffusion coefficient is assumed to be a scalar and not to depend on x.
“For ease of presentation we assume the diffusion coefficient is a scalar (instead of a dˆ d matrix) and does not depend on x, but our theory can be generalized to hold in those cases (see Appendix A).”
The authors state this as an assumption.
The discretization schedule of time is fixed beforehand.
“We assume the discretization schedule of time is fixed beforehand, and thus we absorb the dependency on ∆t into the notations of fi and Gi.”
The paper relies on this without support.
In colorization, the known data dimensions are coupled.
“Colorization is a special case of imputation, except that the known data dimensions are coupled.”
The authors state this as an assumption.
p(y(t)|y) is tractable.
“• ppyptq | yq is tractable. We can often derive this distribution from the interaction between the forward process and the SDE, like in the case of image imputation and colorization.”
The authors state this as an assumption.
pt(x(t)|y(t),y) ≈ pt(x(t)|y(t)).
“• ptpxptq | yptq,yq « ptpxptq | yptqq. For small t, yptq is almost the same as y so the approximation holds. For large t, y becomes further away from xptq in the Markov chain, and thus have smaller impact on xptq. Moreover, the approximation error for large t matter less for the final sample, since it is used early in the sampling process.”
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Song et al. [60] found that further changes to the UNet architecture improved performance on the CIFAR-10 [31] and CelebA-64 [34] datasets.”
From Diffusion Models Beat GANs on Image Synthesis (2021) · cites this paper as [60]
Experimental — accuracy not yet measuredThe cited source says what the claim attributes to it.
In the citing paper
“An intriguing feature of diffusion models is that unconditional models can be conditioned at test-time [15, 82, 85].”
From High-Resolution Image Synthesis with Latent Diffusion Models (2022) · cites this paper as [85]
The cited source says what the claim attributes to it.
In the citing paper
“This class of models already holds the state-of-the-art [60] on CIFAR-10 [31]”
From Diffusion Models Beat GANs on Image Synthesis (2021) · cites this paper as [60]
The cited source says what the claim attributes to it.
In the citing paper
“In particular, we can train a classifier pφ(y|xt, t) on noisy images xt, and then use gradients ∇xt log pφ(y|xt, t) to guide the diffusion sampling process towards an arbitrary class label y.”
From Diffusion Models Beat GANs on Image Synthesis (2021) · cites this paper as [60]
The cited source says what the claim attributes to it.
In the citing paper
“Sohl-Dickstein et al. [56] and Song et al. [60] show one way to achieve this, wherein a pre-trained diffusion model can be conditioned using the gradients of a classifier.”
From Diffusion Models Beat GANs on Image Synthesis (2021) · cites this paper as [60]
The cited source says what the claim attributes to it.
In the citing paper
“To this end, we use a score-based conditioning trick adapted from Song et al. [60]”
From Diffusion Models Beat GANs on Image Synthesis (2021) · cites this paper as [60]
The check wasn’t confident either way, so it gives no verdict — never disputed.
In the citing paper
“Continuous visual tokenizers, often including Autoencoder (AE) and Variational Autoencoder (VAE), compress visual data into a continuous latent space where diffusion-based models can be efficiently trained on (Ho et al., 2020; Lipman et al., 2022; Song et al., 2020).”
From Cosmos World Foundation Model Platform for Physical AI (2025) · cites this paper as Song et al., 2020
Experimental — accuracy not yet measured
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Each contradiction between two passages listed here was confirmed by an independent check.
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ 0 100 200 300 > 0.00 0.25 0.50 0.75 1.00
“where sθpxi, iq is to estimate z{σi.”
§ 2 BACKGROUND > 2.1 DENOISING SCORE MATCHING WITH LANGEVIN DYNAMICS (SMLD)
“Given sufficient data and model capacity, the optimal score-based model sθ˚px, σq matches ∇x log pσpxq almost everywhere for σ P tσiuNi"1.”
Citations
Cites
Learning Multiple Layers of Features from Tiny Images
Krizhevsky, A. (2024) · doi:10.57702/zp44cu3g · Cited by 23,889
GAN(Generative Adversarial Nets)
淳司, 柴. (2017) · Journal of Japan Society for Fuzzy Theory and Intelligent Informatics · doi:10.3156/jsoft.29.5_177_2 · Cited by 20,507
A Style-Based Generator Architecture for Generative Adversarial Networks
Karras, T., Laine, S., & Aila, T. (2019) · 2019 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2019.00453 · Cited by 11,714
Deep Learning Face Attributes in the Wild
Liu, Z., Luo, P., Wang, X., & Tang, X. (2015) · 2015 IEEE International Conference on Computer Vision (ICCV) · doi:10.1109/iccv.2015.425 · Cited by 7,747
Zagoruyko, S., & Komodakis, N. (2016) · Procedings of the British Machine Vision Conference 2016 · doi:10.5244/c.30.87 · Cited by 7,244
Analyzing and Improving the Image Quality of StyleGAN
Karras, T., Laine, S., Aittala, M., Hellsten, J., Lehtinen, J., & Aila, T. (2020) · 2020 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr42600.2020.00813 · Cited by 6,332
Numerical solution of stochastic differential equations
Kloeden, P. E. 1., & Platen, E. (2016) · doi:10.5194/gmd-2016-45-rc1 · Cited by 5,119
Large Scale GAN Training for High Fidelity Natural Image Synthesis
Brock, A., Donahue, J., & Simonyan, K. (2018) · arXiv · doi:10.48550/arxiv.1809.11096 · Cited by 3,717
A family of embedded Runge-Kutta formulae
Dormand, J. R., & Prince, P. J. (1980) · Journal of Computational and Applied Mathematics · doi:10.1016/0771-050x(80)90013-3 · Cited by 3,634
Stochastic Differential Equations
Øksendal, B. (2003) · Universitext · doi:10.1007/978-3-642-14394-6_5 · Cited by 3,081
Research works printed but not linked: 6
- Ian Goodfellow, Jean Pouget-Abadie, Mehdi Mirza, Bing Xu, David Warde-Farley, Sherjil Ozair, Aaron Courville, and Yoshua Bengio. Generative adversarial nets. In Advances in neural informa- tion processing systems, pp. 2672–2680, 2014.
- Anirudh Goyal Alias Parth Goyal, Nan Rosemary Ke, Surya Ganguli, and Yoshua Bengio. Variational walkback: Learning a transition operator as a stochastic recurrent net. In Advances in Neural Information Processing Systems, pp. 4392–4402, 2017.
- Jonathan Ho, Xi Chen, Aravind Srinivas, Yan Duan, and Pieter Abbeel. Flow++: Improving flow- based generative models with variational dequantization and architecture design. In International Conference on Machine Learning, pp. 2722–2730, 2019.
- Tero Karras, Timo Aila, Samuli Laine, and Jaakko Lehtinen. Progressive growing of gans for improved quality, stability, and variation. In International Conference on Learning Representations, 2018.
- Durk P Kingma and Prafulla Dhariwal. Glow: Generative flow with invertible 1x1 convolutions. In Advances in Neural Information Processing Systems, pp. 10215–10224, 2018.
- Yang Song, Chenlin Meng, and Stefano Ermon. Mintnet: Building invertible neural networks with masked convolutions. In Advances in Neural Information Processing Systems, pp. 11002–11012, 2019b.
Cited by
Sorted by citations
Items 5,501–5,600 of 6,172
CrossFlowDG: Bridging the Modality Gap with Cross-modal Flow Matching for Domain GeneralizationPreprint
Kritikos, A., Spanos, N., & Voulodimos, A. S. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2604.16892
A Mechanistic Study of Algorithmic Generalization in Diffusion Models on Modular ArithmeticPreprint
Kim, J. H., Park, Y.-H., Østby, M. D., & Gu, J. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2604.17673
Structure-Adaptive Sparse Diffusion in Voxel Space for 3D Medical Image Enhancement
Jiang, H., Li, F., Yu, B., Zhang, Y., Smith, K., Gong, K., & Shao, W. (2026) · Lecture notes in computer science · doi:10.1007/978-3-032-38179-8_49
Long-Text-to-Image Generation via Compositional Prompt DecompositionPreprint
Huang, J.-Y., Lin, T., & Du, Y. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2604.18258
Improving Ear Biometric Recognition Using Conditional WGAN-GP and Transfer Learning
Mohapatra, A., Dutta, S., & Sarangi, P. P. (2026) · Communications in computer and information science · doi:10.1007/978-3-032-16830-6_26
Geometric Decoupling: Diagnosing the Structural Instability of LatentPreprint
Liang, Y., Chen, Z., & Lai, Y.-K. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2604.18804
An Agentic Platform for Drug Repurposing Unified across Molecular, Phenotypic, and Clinical ScalesPreprint
Wang, C., Moussaoui, M. E., Zhang, D., Prabhakaraalva, P., Merzliakov, S., Lu, R. J.-H., Zaman, N., Chakraborty, G., & Huang, K. (2026) · bioRxiv (Cold Spring Harbor Laboratory) · doi:10.64898/2026.04.19.719462
SketchCrafter: Sketch Extraction as a Training‐Free Generative Process
Long, Y., Zheng, C., Xu, C., Yang, R., Liang, J., Xian, C., & He, S. (2026) · Computer Graphics Forum · doi:10.1111/cgf.70484
Classifier-guided discrete diffusion for malware family-conditional graph generation
Lu, C., Park, Y., & Troia, F. D. (2026) · Journal of Computer Virology and Hacking Techniques · doi:10.1007/s11416-026-00680-7
Optimizing Diffusion Priors in Image Reconstruction from a Single ObservationPreprint
Wang, F., & Bouman, K. L. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2604.21066
Su, S., Zha, R., Shi, D., Li, H., & Cheng, X. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2604.21518
Who Defines Fairness? Target-Based Prompting for Demographic Representation in Generative ModelsPreprint
Nizam, M. B., & Davis, J. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2604.21036
ReCAPA: Hierarchical Predictive Correction to Mitigate Cascading Failures
Zeng, X., Sun, Y., Li, H., Liu, S., & Wang, H. (2026) · arXiv (Cornell University)
Statistical Analysis of Markovian Generative ModelingPreprint
Aamari, E., & Stéphanovitch, A. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2604.22712
Multimodal Diffusion to Mutually Enhance Polarized Light and Low Resolution EBSD DataPreprint
Dong, H., Efimov, T., Shah, M. N., Simmons, J., Donegan, S., Graef, M. D., & Chi, Y. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2604.22212
Soria‐Olivas, E., Belda, E. A., Salvador, D. B., Cámara, P. H., Isla, M. A. S.-M., & Belenguer, P. R. (2026) · Studies in computational intelligence · doi:10.1007/978-3-032-15854-3_6
DiSCoQR: Diffusion-Driven Semantic Compression for Robust Image Steganography in Standard QR Codes
Ren, L., & Zhang, D. (2026) · International World Wide Web Conference (WWW) · doi:10.1145/3774904.3792153
Cross-modal flow matching for domain generalization
Kritikos, A. (2026) · DSpace - NTUA (National Technical University of Athens) · doi:10.26240/heal.ntua.32113
Dream-Cubed: Controllable Generative Modeling in Minecraft by Training on Billions of CubesPreprint
Merino, T., Earle, S., 岩井, 龍., Togelius, J., & Cetin, E. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2604.22847
Prabhu, D. F., Park, J., & Gurupur, V. P. (2026) · Applied Sciences · doi:10.3390/app16094262
Learning biophysical models of gene regulation with probability flow matchingPreprint
Maddu, S., Chardès, V., & Shelley, M. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2604.25062
Mpraimakis, A. (2026) · DSpace - NTUA (National Technical University of Athens) · doi:10.26240/heal.ntua.32150
Yang, Y., Meng, F., Fang, H., & Zhang, W. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2604.26348
When Do Diffusion Models learn to Generate Multiple Objects?Preprint
Jeong, Y., Uselis, A., Laina, I., Oh, S. J., & Rohrbach, A. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.00273
GD4: Graph-based Discrete Denoising Diffusion for MIMO DetectionPreprint
Lu, Q., Luan, S., & Chang, X.-W. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.00423
Mean-field path-integral diffusion from samples to interacting agents
Chertkov, M. (2026) · Communications Physics · doi:10.1038/s42005-026-02750-0
Visual Implicit Autoregressive ModelingPreprint
Jiang, P., Luo, J., Lin, L., Huang, Z., & Li, X. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.01220
Cast3: Translating numerical weather prediction principles into data-driven forecastingPreprint
Nai, C., Pan, B., Liang, Y., & Chen, X. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.01599
Rong, G., Chen, C., Wu, X., Gao, H., & Yan, L. (2026) · Research Square · doi:10.21203/rs.3.rs-9303579/v1
Unifying Deep Stochastic Processes for Image EnhancementPreprint
Kozłowski, W., Kuczbański, R., Adamczewski, K., Szczypkowski, K., & Zięba, M. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.01568
Diffusion-based adversarial attacks and defenses on template for visual object tracking
Pang, H., Xiao, G., Liu, C., Jia, J., & Jin, Q. (2026) · Machine Vision and Applications · doi:10.1007/s00138-026-01821-0
Neural-Enhanced Copula Estimation for Robust Blind Source Separation of Images
Elharouri, S., Aadraoui, Y. E., & Ghazdali, A. (2026) · Lecture notes in networks and systems · doi:10.1007/978-3-032-19963-8_18
Fault Diagnosis Under Variable Working Conditions Enhanced by Diffusion Models
Lai, Z., Zhao, G., Luo, L., & Hu, S. J. (2026) · Lecture notes in electrical engineering · doi:10.1007/978-981-95-6366-1_3
Lou, Y., Yu, Y., Ren, S., & Bai, Y. (2026) · Communications in computer and information science · doi:10.1007/978-3-032-22202-2_33
Structured 3D Latents Are Surprisingly Powerful: Unleashing Generalizable Style with 2D DiffusionPreprint
Qiao, Y., Lu, Y., Zhou, Y., Liu, D., Hou, L., Yang, R., Yin, Y., & Ma, J. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.04412
Stage-adaptive audio diffusion modelingPreprint
Zhang, X., & Li, C. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.04547
A Few-Step Generative Model on Cumulative Flow Maps
Li, Z., Chen, D., Sun, Y., & Zhu, B. (2026) · ACM Transactions on Graphics · doi:10.1145/3811380
Autoregressive One-Step Generative Modeling for Dynamical System ForecastingPreprint
Yang, T., & Xiao, X. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.05540
Plug-and-Play Label Map Diffusion for Universal Goal-Oriented NavigationPreprint
Shen, Z., Zeng, Y., Luo, S., Li, T., & Luo, H. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.05960
Conditional Diffusion Under Linear Constraints: Langevin Mixing and Information-Theoretic GuaranteesPreprint
Aghapour, A., Bayraktar, E., & Cohen, A. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.05387
Active Learning for Communication Structure Optimization in LLM-Based Multi-Agent SystemsPreprint
Yang, H., Dong, X., Negruţ, D., & Wu, J.-L. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.05703
Memory Efficient Full-gradient Attacks (MEFA) Framework for Adversarial Defense EvaluationsPreprint
Du, Y., Hill, M., & Cai, H. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.06357
Arena as Offline Reward: Efficient Fine-Grained Preference Optimization for Diffusion ModelsPreprint
Li, Z., Zhao, Y., Zhang, E. Z., Liu, X., Zhang, J., Gu, Q., & Dong, Z. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.06070
Ma, S., Yang, T., Wu, X., & Xiao, X. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.05975
DBMSolver: A Training-free Diffusion Bridge Sampler for High-Quality Image-to-Image TranslationPreprint
Venugopal, S., Mostafavi, M., & Choi, J. H. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.05889
Shi, K., & Zhang, J. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.05865
R 2 DShield: Robust Object Detection in Real-Time via Bayesian Input Shielding
Huai, S., Xie, Z., & Luo, J. (2026) · ACM International Conference on Embedded Networked Sensor Systems · doi:10.1145/3774906.3802755
Pre-stack seismic inversion with plug-and-play diffusion model
Li, S., Li, L., Chen, Z., & Zou, J. X. (2026) · Acta Geophysica · doi:10.1007/s11600-026-01886-5
Style Transfer for High-Fidelity Time Series Augmentation
Nagda, M. K., Ostheimer, P., Arweiler, J., Jungjohann, I., Werner, J., Wagner, D., Muraleedharan, A., Jafari, P., Schmid, J., Jirasek, F., et al. (2026) · Communications in computer and information science · doi:10.1007/978-3-032-19102-1_18
Non-Uniqueness of the Q-based Interpretation of Quantum MechanicsPreprint
Feintzeig, B. H., & DeWitt, W. (2026) · PhilSci-Archive (University of Pittsburgh)
Accurate and Robust Full Waveform Inversion Driven by Poisson Flow Generative Model Priors
Wang, H., Yu, S., & Wang, M. (2026) · Geophysical Prospecting · doi:10.1111/1365-2478.70183
From Synthetic to Real: Toward Identity-Consistent Makeup Transfer with Synthetic and Real DataPreprint
Yu, Y., Wang, J., Shi, J., Tan, Z., Li, H., & Chen, J. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.07861
WA-SAND: Wavelet attention diffusion with spatially adaptive noising for multi-view face generation
Zhong, W., Shichao, H., Lin, W. S., & Zhao, H. (2026) · Neural Networks · doi:10.1016/j.neunet.2026.109048
Adaptive Subspace Projection for Generative PersonalizationPreprint
Nguyen, V.-A., Bui, A. T., Abraham, T., Kim, J., Kaur, A., Omari, R. M., Vu, T.-T., & Phung, D. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.07257
Image semantic compression at extremely low bitrate
Bordin, T. (2025) · theses.fr (ABES) · doi:10.70675/44c0a27ez04c9z4cbcz9f97zfec51619cba8
Towards Photorealistic and Efficient Bokeh Rendering via Diffusion FrameworkPreprint
Shi, L., Zheng, S., Wang, Z., Zhang, H., Chen, J., Li, B., Chen, S., & Jiang, P.-T. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.07429
Wang, Q., Zhou, H., Yu, H., Zhao, J., Zhao, Y., Ye, C., Wang, Z., & Chen, G. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.08202
Predicting 3D structure by latent posterior samplingPreprint
Haider, A., & Rosenbaum, D. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.10830
Abdelhamid, A., Moustafa, H. E.-D., Nafea, H. B., Abdelhay, E. H., Abo-Zahhad, M. M., & El-Ghamry, A. (2026) · Journal of Electronic & Information Systems · doi:10.30564/jeis.v8i1.13224
Elucidating Representation Degradation Problem in Diffusion Model TrainingPreprint
Yao, Z., Li, D., Zhang, Z., Mahee, D., Zhu, F., Zhang, W., He, X., Jin, Y., & Yu, R. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.10790
Muninn: Your Trajectory Diffusion Model But Faster
Puthumanaillam, G., Jiang, H., Hernandez, R., Fuentes, J., Padrão, P., Bobadilla, L., & Ornik, M. (2026) · Robotics: Science and Systems · doi:10.15607/rss.2026.xxii.160
Discrete Langevin-Inspired Posterior SamplingPreprint
Amballa, C., Basu, S., Sampedro, J. V., & Choudhury, R. R. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.09302
A Cold Diffusion Approach for Percussive Dereverberation
Makris, D., Barják, A., & Kaliakatsos-Papakostas, M. A. (2026) · International Joint Conference on Neural Networks (IJCNN) · doi:10.1109/ijcnn69854.2026.11728826
Exploring and Exploiting Stability in Latent Flow MatchingPreprint
Briq, R., Kamp, M., Fried, O., Cohen, S., & Kesselheim, S. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.08398
Wei, Z., Dan, T., & Guorong Wu, A. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.09771
Remix the Timbre: Diffusion-Based Style Transfer Across Polyphonic StemsPreprint
Chen, L., Zhao, J., & Li, S. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.09259
Path-Coupled Bellman Flows for Distributional Reinforcement LearningPreprint
Xu, B., Zou, Q., Yang, S., & Yan, H. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.08253
Learning Unified Representations of Normalcy for Time Series Anomaly DetectionPreprint
Sarker, P., Sarker, S., Murray, N. G., & Tavakkoli, A. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.09685
Huang, Z., & Sun, G. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.12011
On the Approximation Complexity of Matrix Product Operator (MPO) Born MachinesPreprint
Li, C., Tao, Z., Cong, Y., Xu, J., & Zhao, Q. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.11471
RealDiffusion: Physics-informed Attention for Multi-character Storybook GenerationPreprint
Zhao, Q., Chen, J., Tsang, I. W.-H., & Dai, G. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.11927
Generative Diffusion Prior Distillation for Long-Context Knowledge TransferPreprint
Udayangani, N., Nandakishor, K., & Palaniswami, M. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.11414
Generative Modeling of Approximately Periodic Time Series by a Posterior-Weighted Gaussian ProcessPreprint
Reich, E., Messineo, S., & Huber, S. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.13150
Generative Support Realignment for Cross-Domain Offline Reinforcement LearningPreprint
Kim, M., Kim, J., Choi, G., & Han, S. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.13054
Proximal-Based Generative Modeling for Bayesian Inverse ProblemsPreprint
Zhang, B., Wang, Z., & Liu, Y. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.13278
HIR-ALIGN: Enhancing Hyperspectral Image Restoration via Diffusion-Based Data GenerationPreprint
Pang, L., Zhao, H., Zhang, Y., Meng, D., & Cao, X. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.13581
Holistic distributional signatures of F0 dynamics
Iskarous, K., Roessig, S., & Mücke, D. (2026) · Speech prosody · doi:10.21437/speechprosody.2026-95
Training-Free Generative Sampling via Moment-Matched Score SmoothingPreprint
Yao, Z., & Paulin, D. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.14276
Digital twin-based synchronous 4D BIM-driven UAS mission planning using the combined graph approach
Bhadaniya, P., & Gheisari, M. (2026) · Advanced Engineering Informatics · doi:10.1016/j.aei.2026.104814
Privacy Evaluation of Generative Models for Trajectory GenerationPreprint
Bouras, S., Kontopoulos, I., Pugliese, C., Lettich, F., Carlini, E., Kavalionak, H., Renso, C., & Tserpes, K. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.15246
Martingale Neural Operators: Learning Stochastic Marginals via Doob-Meyer FactorizationPreprint
Hidajat, K. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.15806
Accelerating Redshift-Conditioned Galaxy Image Synthesis with One-step Generative ModelingPreprint
Yang, T., Tacchella, S., & Xiao, X. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.17546
Jiang, Z., Fang, J., Ning, B., Li, H., & Liang, Y. (2026) · IEEE Journal of Selected Topics in Signal Processing · doi:10.1109/jstsp.2026.3749773
Divergence-Suppressing Couplings for Rectified FlowPreprint
Min, Y., & Gomes, C. P. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.17733
Awakening the Hydra: Stabilizing Multi-Concept Backdoor Injection in Text-to-Image Diffusion ModelsPreprint
Wang, K., Zhang, J., Zhu, C., Ma, C., & Li, S. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.19698
Han, H., Yeo, S., & Yoo, J. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.19729
SeisDPS-3D: A Diffusion Model-Based Approach for 3D Seismic Data Deconvolution
Liu, D., Yu, H., & Sacchi, M. D. (2026) · Surveys in Geophysics · doi:10.1007/s10712-026-09952-9
Provably Learning Diffusion Models under the Manifold Hypothesis: Collapse and RefinePreprint
Huang, W., Han, A., Bai, M., Zhou, H., Zhang, Q., Suzuki, T., & Fukumizu, K. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.20235
Benchmarking Resilience: Asymmetric Latent Purification Inspired by Generative Diffusion Bottlenecks
Ladgaonkar, B. A., & Padate, R. (2026) · International Journal of Research and Innovation in Applied Science · doi:10.51584/ijrias.2026.110400185
Jia, H., Yin, P., Chen, W., Liang, S., Wang, L., Tian, B., Wang, X., Jia, N., & Yue, Y. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.20780
Wang, Y., Shi, J., Gao, W., Xu, X., Shi, R., & Huang, Y. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.20640
Generative Modeling by Value-Driven TransportPreprint
Moreno-Muñoz, P., Müller, A., & Neu, G. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.22507
Li, J., Santini, T., Clark, C., de Almeida, B., Chu, C., Alkhateeb, S. K., Sajewski, A. N., Berardinelli, J., Jin, H., Campos, T., et al. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.21669
Broken Memories: Detecting and Mitigating Memorization in Diffusion Models with Degraded Generations
Huang, Y., Zhang, M., chen, C., Li, F., Hong, G., You, X., & Yang, M. (2026) · ACM SIGKDD Conference on Knowledge Discovery and Data Mining (KDD) · doi:10.1145/3770855.3817770
Diffuusiomallit ja flow matching offline-mallipohjaisessa optimoinnissa
Eronen, A. (2026) · Aaltodoc (Aalto University)
Guiding Neuro-Symbolic Scenario Generation with Spatio-Temporal Logic
Bonin, L., Giacomarra, F., Bortolussi, L., Deshmukh, J. V., & Cairoli, F. (2026) · Adaptive Agents and Multi-Agents Systems · doi:10.65109/jcra2597
Dong, C., Hurrell, J. W., & Barnes, E. A. (2026) · Machine Learning Earth · doi:10.1088/3049-4753/aeba91
Feng, Y., Li, Y., Lv, W., Zhao, Z., Wang, Y., Chen, W., Chen, B., & Liu, H. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.24402
Metadata
- Authors
- Song, Y., Sohl-Dickstein, J., Kingma, D. P., Kumar, A., Ermon, S., & Poole, B.
- Affiliations
- Stanford University (US)
- Google (United States) (US)
- Venue
- arXiv
- Publisher
- arXiv
- Published
- 2020
- ISSN
- 2331-8422 (ISSN-L)
- arXiv
- 2011.13456
- OpenAlex
- W3110257065
- Semantic Scholar
- 633e2fbfc0b21e959a244100937c5853afca4853
- Cited by
- 1,953
- References
- 48
- Citations by year
- 2026: 51 · 2025: 576 · 2024: 858 · 2023: 385 · 2022: 56 · 2021: 25 · 2020: 1
- Type
- posted content
- Language
- en
- Open access
- green
- arxiv.org
- Locations
- arXiv (Cornell University) (submittedVersion)
- arXiv (Cornell University)
- Topics
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Generative Adversarial Networks and Image Synthesis
- Physical Sciences › Computer Science › Artificial Intelligence › Adversarial Robustness in Machine Learning
- Physical Sciences › Physics and Astronomy › Statistical and Nonlinear Physics › Model Reduction and Neural Networks
- Keywords
- stochastic differential equations, score estimation, diffusion probabilistic models, neural ordinary differential equations, exact likelihood, inverse problems, image generation, image inpainting, image colorization
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
A language model drew the claims from the paper on 2026-11-08, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-11-08 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Cited sources are checked with a language model’s help (gpt-6-sol).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
