

The DOI matches its DataCite record; 16 of the 16 references it cites were found in a registry or an index; 4 of the 7 sources its claims cite were checked for support.
A Theory for Emergence of Complex Skills in Language Models
Open accessAbstract
A major driver of AI products today is the fact that new skills emerge in language models when their parameter set and training corpora are scaled up. This phenomenon is poorly understood, and a mechanistic explanation via mathematical analysis of gradient-based training seems difficult. The current paper takes a different approach, analysing emergence using the famous (and empirical) Scaling Laws of LLMs and a simple statistical framework. Contributions include: (a) A statistical framework that relates cross-entropy loss of LLMs to competence on the basic skills that underlie language tasks. (b) Mathematical analysis showing that the Scaling Laws imply a strong form of inductive bias that allows the pre-trained model to learn very efficiently. We informally call this {\em slingshot generalization} since naively viewed it appears to give competence levels at skills that violate usual generalization theory. (c) A key example of slingshot generalization, that competence at executing tasks involving $k$-tuples of skills emerges essentially at the same scaling and same rate as competence on the elementary skills themselves.
Overview
AI snapshot
Written from the paper’s full text.
TL;DR
The paper proposes a statistical and random-graph theory explaining emergence of complex skills in language models by assuming empirical scaling laws and modeling text as generated from random k-tuples of skills tested by cloze questions. It argues that reductions in excess cross-entropy imply a strong inductive bias, informally called “slingshot generalization,” under which competence on k′-tuples of skills emerges at nearly the same scaling as competence on individual skills.
Key findings
- The framework relates cross-entropy loss to competence: expected cross-entropy loss = entropy + excess entropy. In the Chinchilla scaling law \(L(N,D)=A+B/N^{0.34}+C/D^{0.28}\), the paper identifies \(A=1.61\) as language entropy and the \(B/N^{0.34}+C/D^{0.28}\) terms as excess entropy, with \(B=406.4\), \(C=410.7\).
- Theorem 14 and Corollary 13 imply that if a model with loss \(\delta\) is scaled so its loss becomes \(\delta/k'\), then the performance curve inferred for \(k'\)-tuples of skills using the scaled model is identical to the curve inferred for individual skills on the original model. Since 10× scaling reduces excess entropy by roughly \(10^{0.28}\approx 2\), competence on \(2k'\)-tuples after scaling reaches at least the prior level on \(k'\)-tuples.
- The paper gives an illustrative example: with \(c=10\), \(|S|=10^4\), and \(D=10^{10}\) tokens, a larger model trained on \(10^{13}\) tokens would display proficiency in most 8-tuples of skills, despite \(10^{10}\times 10^8 \ll (10^4)^8\).
- For fixed prediction loss \(\theta\), higher \(k\) (more skills per text-piece, i.e. more complex text) yields better emergence of skills; more frequent skills tend to reach competence faster than less frequent ones.
Methods
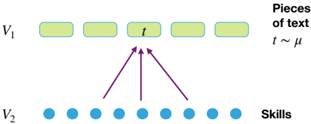
- Theoretical analysis, not empirical training experiments. The paper assumes LLM scaling laws and builds a statistical framework in which text-pieces are generated by an unknown process from random k-tuples of skills, with cloze questions added by an unknown CLOZE process; skills and text-pieces form a bipartite “skill graph.”
- Main analysis uses random graph theory and the probabilistic method to bound the error set \(Y\), deriving performance curves from entropy conditions such as \(H(\theta)+k\theta(H(\beta\alpha)-\beta\alpha\log(1/\alpha)-(1-\beta\alpha)\log(1/(1-\alpha)))<0\). It extends the analysis via a tensorization argument to \(k'\)-tuples of skills and to general measures on skills and text.
- Data or sample: not empirical; the paper uses the Chinchilla scaling law constants and illustrative examples such as the Winograd schema and an appendix chatbot example.
Limitations
- Stated: the theory assumes scaling laws and cannot predict the rate at which loss decrease, and hence emergence, happens within clusters; competence is guaranteed only on text-pieces drawn from the data distribution under usual \(\epsilon\)-\(\delta\) guarantees, and many skills or combinations may not be learnt or may be incorrectly applied on some fraction of the distribution.
- Stated: the theory may underestimate the rate of emergence due to unknown mechanisms, e.g. workings of transformers; it relies on a Cloze Sufficiency Assumption, and multiple-choice cloze questions may not test some skills such as understanding of irony; extensions to generation, dialog, and finer inductive bias are left for future work.
- Evident from the text: there is no empirical validation beyond illustrative examples; the framework relies on artificial cloze questions and distribution shift at test time; it assumes each text-piece requires exactly \(k\) skills drawn iid from an underlying measure, and the skill set, GEN, and CLOZE processes remain unknown.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
41 Own interpretation · 24 No basis given · 3 Partly supported · 2 Sources not found · 2 Own result · 1 Not checked yet · accuracy not yet measured
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“One might thus posit, with some justification from the above-mentioned studies, that the emergence of skills arises from training on related tasks that were implicitly solved while solving next-word prediction in the training dataset.This is indeed our starting point.”
§ A Theory for Emergence of Complex Skills in Language Models > 2 Preliminaries
What the sources say
- Partly supportedcites Wei et al., 2022 sourceExperimental — accuracy not yet measured
Section 5.2 (p. 7) discusses how a language-modeling objective may facilitate downstream behavior, and Section 5.6 (p. 11) proposes investigating links between emergent tasks and similar training data. But the paper calls the cause of emergence an open question; it does not say that skills emerge because related tasks were implicitly solved during next-word prediction. (LLM, conf=0.82)
- Partly supportedcites Srivastava et al., 2022 sourceExperimental — accuracy not yet measured
The Introduction (section 1; page not provided) describes text continuation as a general capability, and section 3.4.2 reports that prerequisite skills can become apparent before a target capability. The paper does not establish the proposed explanation that emerging skills arise because related tasks were implicitly solved during next-word-prediction training. (LLM, conf=0.83)
- Not matchedcites Schaeffer et al., 2023
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
hedgeddirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Partly supported
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“at least 1 -α fraction of skills have at most βθkN 1 /N 2 edges to Y (in other words, at most β times the number of edges a skill would be expected to have to text-pieces in Y ).”
§ A Theory for Emergence of Complex Skills in Language Models > Key Hurdle:
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- The authors state this as an assumption: Each text-piece requires exactly k skills for some k, and this set was drawn by iid sampling from an underlying measure on the set of skills.
- The authors state this as an assumption: The skill-graph has random edges.
- The authors state this as an assumption: In the Section 5 analysis, the test-stream consists of a single degree-k skill cluster, and the skills and text-pieces are uniformly distributed.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“If k ′ > k then the performance curve of θ, k ′ lies below that for k, θ.”
§ A Theory for Emergence of Complex Skills in Language Models > Key Hurdle:
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: unclear — It is unclear why the paper says it holds.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“In the same setting as Theorem 8, for integer k ′ ∈ [2, 1/θ] the conclusion of that theorem holds also for α, β pairs satisfying”
§ A Theory for Emergence of Complex Skills in Language Models > Corollary 11 (tensorization).
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Furthermore, if H(k ′ θ) < k ′ H(θ) the emergence curve from this expression dominates that derived from Theorem 8.”
§ A Theory for Emergence of Complex Skills in Language Models > Corollary 11 (tensorization).
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
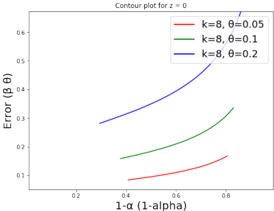
“If θ ′ < θ then the performance curve for θ ′ , k lies below that for θ, k.”
§ A Theory for Emergence of Complex Skills in Language Models > Key Hurdle:
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Theorem 8 shows that for a fixed prediction loss θ, using higher k implies better emergence of skills.”
§ A Theory for Emergence of Complex Skills in Language Models > 6.1 Extending theory to multiple clusters
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Clearly, if the error of the model per average text-piece was δ, then the error per average b-piece is k ′ δ.”
§ A Theory for Emergence of Complex Skills in Language Models > 5.1 The tensorization argument
boosteddirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: unclear — It is unclear why the paper says it holds.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
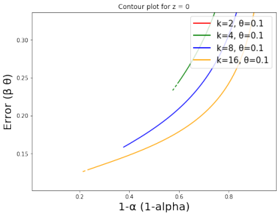
“The emergence curves shift down noticeably (i.e., imply emergence of more skills) as we increase k.”
§ A Theory for Emergence of Complex Skills in Language Models > B.1 Analysis of "General Measure" case in Section 6
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“For example when N, D are increased by a factor of 10 it reduces by roughly (10) 0.28 ≈ 2.”
§ A Theory for Emergence of Complex Skills in Language Models > 2.1 Cross-Entropy, Entropy, and Excess entropy
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Probably not a substantial claim. 19
- It may state two separate claims as one. 19
- The quote only partly states this claim. 1
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“For Chinchilla models Hoffmann et al. [2022] the law is as follows: L(N, D) = A + B N 0.34 + C D 0.28 A = 1.61 B = 406.4 C = 410.7.(2)”
§ A Theory for Emergence of Complex Skills in Language Models > 2 Preliminaries
What the sources say
- Partly supportedcites Hoffmann et al. [2022] sourceExperimental — accuracy not yet measured
Section 3.3 (p. 6) models loss as a function of parameter count and training tokens. Appendix D.2 (p. 25) gives fitted coefficients of 406.4 and 410.7, but reports the constant term as 1.69, not 1.61. The equations and exponents are not decoded in our copy, so it cannot verify the quoted powers. (LLM, conf=0.87)
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
- Partly supported
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“Furthermore, it is known that emergence happens at different rates for different tasks, and is often quickest for tasks where the text is plausibly close to text found in training data Wei et al. [2022].”
§ A Theory for Emergence of Complex Skills in Language Models > 2 Preliminaries
What the sources say
- Partly supportedcites Wei et al. [2022] sourceExperimental — accuracy not yet measured
Appendix A.3 (p. 22) distinguishes tasks that first emerged with LaMDA or GPT-3 from tasks that did not emerge until PaLM, supporting different emergence thresholds across tasks. But §5.6 (p. 11) proposes studying the relationship between emergent tasks and similar training data as future research; it does not establish that tasks resembling training text emerge quickest. (LLM, conf=0.88)
boostedcorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Partly supported
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Theorem 3. If a model's excess entropy at the ith place in text is ϵ then there is a cloze question with binary answer such that the probability that the model answers it incorrectly is at most √ 2ϵ.”
§ A Theory for Emergence of Complex Skills in Language Models > Assumption 2. [Cloze Sufficiency Assumption:]
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper may give no reason why it holds.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“However, the probability of picking the same skill twice scales as O(1/|S|).Since the set of skills S is assumed to be large, the distribution is almost the same as sampling distinct k-tuples of skills.The small difference of O(1/|S|) between the two methods will not affect any of the random graph theory calculations.”
§ A Theory for Emergence of Complex Skills in Language Models > 4.1 Skills: A Statistical View
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“When the list includes harder (or less common) skills, this ability declines.”
§ A Theory for Emergence of Complex Skills in Language Models > Additional information
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. The paper may give no reason why it holds.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“EXPECTED C-E LOSS = ENTROPY + EXCESS ENTROPY (6”
§ A Theory for Emergence of Complex Skills in Language Models > 2.1 Cross-Entropy, Entropy, and Excess entropy
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
- Rests on an assumption: There is a ground-truth human distribution for generating the next word, which assigns probability to the next word given previous words.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Higher values of k greatly improve performance (for k = 2 valid α, β did not exist).”
§ A Theory for Emergence of Complex Skills in Language Models > B.1 Analysis of "General Measure" case in Section 6
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“However, each k ′ -piece is now using a random k ′ k-tuple of skills.Importantly, this set of k ′ k skills consists of iid draws from the skill distribution.”
§ A Theory for Emergence of Complex Skills in Language Models > 5.1 The tensorization argument
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper may give no reason why it holds.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“However, the number of k ′ -tuples of skills scales as the k ′ th power of the number of skills, which is much larger than the size of the training corpus.”
§ A Theory for Emergence of Complex Skills in Language Models > 1.1 Our contributions
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“When each text-piece appears in a single cluster, the analysis of Section ??) continues to apply.”
§ A Theory for Emergence of Complex Skills in Language Models > 6.1 Extending theory to multiple clusters
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. The paper may give no reason why it holds.
- The authors state this as an assumption: Above, a single skill cluster in the language was assumed.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We find that current chatbots, including those in the public domain, can take a list of language skills and produce text illustrating those skills.”
§ A Theory for Emergence of Complex Skills in Language Models > Additional information
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Note that the number of k ′ tuples of skills is around |S| k ′ where S is the set of skills.This quickly leads to paucity of stimulus for some fixed k ′ , specifically, if Dc k ′ ≪ |S| k ′ .”
§ A Theory for Emergence of Complex Skills in Language Models > 4. Learning despite Paucity of stimulus.
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The second and third terms of (2) capture excess entropy, and they decrease polynomially with N and D.”
§ A Theory for Emergence of Complex Skills in Language Models > 2.1 Cross-Entropy, Entropy, and Excess entropy
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: unclear — It is unclear why the paper says it holds.
It may state two separate claims as one.
In the paper
“Cloze questions are multiple choice, which allows testing most language skillsBrown et al. [2020].”
§ A Theory for Emergence of Complex Skills in Language Models > B.1 Analysis of "General Measure" case in Section 6
What the sources say
- Not matchedcites Brown et al. [2020]
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
- Not matched
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Thus at the end of training, locations of errors in the test stream -i.e., the set Y -depend upon the skill-cluster, and since we lack understanding of Y the analysis has to treat it as arbitrary.”
§ A Theory for Emergence of Complex Skills in Language Models > Key Hurdle:
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
In the paper
“Our theory will only rely upon the general form of the equations, specifically, that the dependence is inverse polynomial in N, D. So it applies to other frameworks of training (e.g., overtrained models Muennighoff et al. [2023]) where scaling laws have also been found.”
§ A Theory for Emergence of Complex Skills in Language Models > 2 Preliminaries
What the sources say
- Not matchedcites Muennighoff et al. [2023]
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- The authors state this as an assumption: LLM Scaling Laws, empirical relationships describing reduction in language modeling loss with model scale, hold and are assumed by the theory.
- Not matched
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“But note that there is no way to compute excess entropy using just the corpus.Relationship (6) shows that estimating excess entropy requires knowing the inherent entropy of text, which requires humans in the picture.”
§ A Theory for Emergence of Complex Skills in Language Models > 2.1 Cross-Entropy, Entropy, and Excess entropy
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Since k is the number of skills being used in a single text-piece, it intuitively measures how complex the text is -e.g., a college text would be expected to have higher k than a primary school text.”
§ A Theory for Emergence of Complex Skills in Language Models > 6.1 Extending theory to multiple clusters
hedgedcorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence. The paper may give no reason why it holds. It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Some skills such as understanding of irony don't lend themselves well to cloze-based testing since one of the multiple choices already explains the joke.”
§ A Theory for Emergence of Complex Skills in Language Models > B.1 Analysis of "General Measure" case in Section 6
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“If we think of the k ′ -tuple of skills as a”
§ A Theory for Emergence of Complex Skills in Language Models > 1.1 Our contributions
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
The quote only partly states this claim.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“But one could imagine that the model's basic misunderstanding of the above type could, often, lead to prediction mistakes in neighboring text.”
§ A Theory for Emergence of Complex Skills in Language Models > 3 (Mis)understanding, Excess entropy, and Cloze Questions
hedgedconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper may give no reason why it holds.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“But lacking any mechanistic insight, our theory cannot predict the rate at which loss decrease (and hence emergence) happens within clusters.”
§ A Theory for Emergence of Complex Skills in Language Models > 6.1 Extending theory to multiple clusters
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Under such assumptions the above relationship, which holds in expectation at the word level, should hold fairly precisely at the corpus level.”
§ A Theory for Emergence of Complex Skills in Language Models > 2.1 Cross-Entropy, Entropy, and Excess entropy
hedgedcorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- The authors state this as an assumption: The conditional probabilities p_i and q_i depend only on the previous 10^3 words, and the corpus size M is much bigger than 10^7.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“A key insight (see Figure 2) is that reduction in excess cross entropy loss drives skill acquisition, together with the assumption that normal language -down to short paragraph levelalready utilizes multiple skills, mixed up randomly.”
§ A Theory for Emergence of Complex Skills in Language Models > 8 Conclusions
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper may give no reason why it holds. It may state two separate claims as one.
- The authors state this as an assumption: Normal language, down to short paragraph level, already utilizes multiple skills, mixed up randomly.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Competence is guaranteed only on text-pieces drawn from the data distribution, and governed by usual ϵ-δ) guarantees -many skills as well as combinations of skills may not get learnt, and the ones that do get learnt may incorrectly applied on some fraction of the data distribution.”
§ A Theory for Emergence of Complex Skills in Language Models > 8 Conclusions
hedged- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- The authors state this as an assumption: As the model and data set size tend to infinity in tandem, the model will perfectly learn the language distribution.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“In summary, Definition 7 can be thought of as a lower bound on the model's true”
§ A Theory for Emergence of Complex Skills in Language Models > 4.1 Skills: A Statistical View
plain- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Note that the training corpus did not contain such cloze questions, so this is a simple form of distribution shift at test time.”
§ A Theory for Emergence of Complex Skills in Language Models > 4 Mathematical Framework
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The calculations below only require the total number of skills to be much less than the support size of the distribution of text-in other words, the set of skills can be extremely large.”
§ A Theory for Emergence of Complex Skills in Language Models > 5 Analysis of Emergence (uniform cluster)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The following result guarantees that statistical tasks corresponding to most skills do not assign significant probability to text pieces in Y -in other words, the model has good performance on statistical tasks connected with these skills.”
§ A Theory for Emergence of Complex Skills in Language Models > Key Hurdle:
boosteddirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“If a model is considered to have reasonable performance on individual skills at current scaling, then after further up-scaling of 10x one would see similar reasonable performance on skill-pairs, and scaling up by yet another 10x after that will yield similar reasonable performance on 4-tuples of skills, etc.”
§ A Theory for Emergence of Complex Skills in Language Models > 5.1.1 Emergence for k ′ -tuples of skills
hedgeddirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- The authors state this as an assumption: A Chinchilla-like scaling law holds: 10x up-scaling leads to a factor 2 reduction in excess entropy.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Our analysis allows the set of skills to be almost as large as the training corpus, which implies all individual skills were likely to have been seen during training.”
§ A Theory for Emergence of Complex Skills in Language Models > 1.1 Our contributions
hedgeddirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“This accounting is conservative -it ignores the possibility that a model could have perfect on skills 1 to 4 but still have incorrectly answered the cloze question because of, say, shaky understanding of skill 5.”
§ A Theory for Emergence of Complex Skills in Language Models > 4.1 Skills: A Statistical View
hedged- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Note that as the model is scaled up, θ will go down and the set Y containing erroneous answers on cloze questions will shrink.”
§ A Theory for Emergence of Complex Skills in Language Models > Key Hurdle:
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper may give no reason why it holds. It may state two separate claims as one.
The authors state this as an assumption.
LLM Scaling Laws, empirical relationships describing reduction in language modeling loss with model scale, hold and are assumed by the theory.
“our theory assumes LLM Scaling Laws, which are empirically relationships describing reduction in language modeling loss with model scale.”
The authors state this as an assumption.
There exists a set of ground-truth skills, and text-pieces are generated by an unknown process that takes random tuples of skills and converts them into a text-piece whose comprehension requires those skills.
“The theory assumes there exists a set of ground-truth skills and that text-pieces are generated by an unknown process that takes random tuples of skills and converts them into a text-piece whose comprehension requires those skills.”
The authors state this as an assumption.
Understanding of a text-piece is testable by simple multiple-choice cloze questions inserted by another unknown process into the text at test time.
“The framework assumes that”
The authors state this as an assumption.
The pre-trained model's average multiclass prediction loss on cloze questions closely tracks, within a small multiplicative factor like 1.1, the excess cross-entropy of the model on classical next-word prediction.
“The pre-trained model's average (multiclass) prediction loss on Cloze questions -where the average is taken over the distribution of text pieces-closely tracks (within a small multiplicative factor like 1.1) the excess cross-entropy of the model on classical next-word prediction.”
The authors state this as an assumption.
Language comprehension involves a set of skills.
“First, it is assumed that language comprehension involves a set of skills, though the theory will not need to know a precise list.”
The authors state this as an assumption.
The test distribution is structured as a long unordered list of text-pieces, each with an associated measure.
“We as-sume this test distribution is structured as a long unordered list of text-pieces, each with an associated measure”
The authors state this as an assumption.
The model's comprehension of a text piece is testable via suitable cloze questions analogous to the Winograd example.
“We assume that the model's”
The authors state this as an assumption.
An unknown process CLOZE has been used to add cloze questions to the text pieces at test time.
“Specifically, we assume that an (unknown) process CLOZE has been used to add such cloze questions to the text pieces at test time.”
The authors state this as an assumption.
Each text-piece requires exactly k skills for some k, and this set was drawn by iid sampling from an underlying measure on the set of skills.
“For simplicity we assume that each text-piece requires exactly k skills for some k, and this set was drawn by iid sampling from an underlying measure on the set of skills.”
The authors state this as an assumption.
The skill-graph has random edges.
“The final element of our theory is that the skill-graph has random edges, as made precise in Definition 5.”
The authors state this as an assumption.
If the model incorrectly answered a cloze question, then that loss was incurred in all statistical tasks corresponding to skills in the text-piece.
“However, our method of measuring the loss incurred on these statistical tasks implicitly assumes that if the model incorrectly answered this cloze question (i.e., it assigned significant probability to the wrong answer), then that loss was incurred in all these statistical tasks.”
The authors state this as an assumption.
In the Section 5 analysis, the test-stream consists of a single degree-k skill cluster, and the skills and text-pieces are uniformly distributed.
“This section analyzes a simple setting where the test-stream consists of a single degree-k skill cluster, and the skills are uniformly distributed and so are the text-pieces-in other words, the distributions µ 1 and µ 2 in Definition 5 are uniform.”
The paper relies on this without support.
There is a ground-truth human distribution for generating the next word, which assigns probability to the next word given previous words.
“The conceptual framework underlying cross-entropy loss (1) is that there is a ground-truth (i.e., humans') distribution for generating the next word, which assigns probability p i (w | w 1 w 2 . . .w i ) to the event that the (i + 1)th word is w given that the previous words were w 1 w 2 . . .w i .”
The authors state this as an assumption.
The conditional probabilities p_i and q_i depend only on the previous 10^3 words, and the corpus size M is much bigger than 10^7.
“One can make mild assumptions to the effect that the conditional probabilities p i (), q i () only depend only on (say) the previous 10 3 words, whereas the corpus size M is much bigger, e.g., M ≫ 10 7 .”
The paper relies on this without support.
Every text-piece has an associated set of skills that are required for comprehending it.
“Every text-piece t has an associated set of skills that are required for comprehending it.”
The authors state this as an assumption.
A Chinchilla-like scaling law holds: 10x up-scaling leads to a factor 2 reduction in excess entropy.
“Assume (for simplicity) a Chinchilla-like scaling law that 10x up-scaling leads to factor 2 reduction in excess entropy.”
The authors state this as an assumption.
Normal language, down to short paragraph level, already utilizes multiple skills, mixed up randomly.
“together with the assumption that normal language -down to short paragraph levelalready utilizes multiple skills, mixed up randomly.”
The authors state this as an assumption.
As the model and data set size tend to infinity in tandem, the model will perfectly learn the language distribution.
“Here we're assuming that as the model and data set size tend to infinity in tandem, the model will perfectly learn the language distribution.”
The authors state this as an assumption.
Each piece of text appears in only one cluster, but skills may appear in different clusters.
“We assume each piece of text appears in only one cluster but skills may appear in different clusters.”
The paper relies on this without support.
The measure on text-pieces has the correct marginals: the µ2-measure of all text-pieces containing a skill s is µ1(s).
“Note that the measure on text-pieces has to have the correct marginals e.g., the µ2-measure of all text-pieces containing a skill s is µ1(s).”
The authors state this as an assumption.
All µ(v1) are sufficiently small, and the number of nonempty measure levels is much smaller than N1, so each class has size much larger than N2.
“We assume all µ(v 1 ) are sufficiently small (meaning some large-ish i 0 , class i is empty for i < i 0 ) and the number of nonempty levels is much smaller than N 1 .Thus each class has reasonable size -say, much larger than N 2 , the number of skills-which allows the asymptotic arguments appearing below to hold within each class.”
The authors state this as an assumption.
Above, a single skill cluster in the language was assumed.
“Above we assumed a single skill cluster in the language.”
The paper relies on this without support.
The overall loss is the weighted sum of measure of text in the individual clusters.
“The overall loss is the weighted sum of measure of text in the individual clusters.”
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Each contradiction between two passages listed here was confirmed by an independent check.
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ A Theory for Emergence of Complex Skills in Language Models > 4. Learning despite Paucity of stimulus.
“Then a larger model trained with 10 trillion tokens (10 13 ) -closer to the size of corpora used in training today's models-would display proficiency in most 8-tuples of skills”
§ A Theory for Emergence of Complex Skills in Language Models > 4. Learning despite Paucity of stimulus.
“After scaling by k orders of magnitude (i.e., increasing dataset size to c k ′ D tokens, where in the Chinchilla framework c is around 10) the performance on k ′ -tuples of skills is as good as what the performance was on individual skills before the scaling.”
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ A Theory for Emergence of Complex Skills in Language Models > 4.1 Skills: A Statistical View
“The error rate of the model at the statistical tasks is the expected prediction loss on text-pieces drawn from the above distribution.Since error rate is between 0 and 1, the competence refers to (1error rate).”
§ A Theory for Emergence of Complex Skills in Language Models > 4.1 Skills: A Statistical View
“The prediction loss on the text-piece is the cross-entropy loss on predicting the answers to the cloze questions in it.”
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ A Theory for Emergence of Complex Skills in Language Models > Key Hurdle:
“H(θ) + kθ H(βα) -βα log 1 α -(1 -βα) log( 1 1 -α ) < 0(8)”
§ A Theory for Emergence of Complex Skills in Language Models > B Technical Theorems about Random Bipartite Graphs
“H(θ) + kθ(H(βα) -βα log 1 α -(1 -βα) log( 1 1 -α )) < 0 (11”
Citations
Cites
Scaling Laws for Neural Language Models
Kaplan, J., McCandlish, S., Henighan, T., Brown, T. B., Chess, B., Child, R., Gray, S., Radford, A., Wu, J., & Amodei, D. (2020) · arXiv · doi:10.48550/arxiv.2001.08361 · Cited by 9,550 · cited 1×
“Scaling laws: These empirically-derived expressions describe how test cross entropy loss on held-out data scales (in experiments) with number of model parameters (N) and size of the dataset (D) Cortes et al. [1993], Hestness et al. [2017], Kaplan et al. [2020], Bahri et al. [2021].”
BackgroundOn the Dangers of Stochastic Parrots: Can Language Models Be Too Big? 🦜
Bender, E. M., Gebru, T., McMillan-Major, A., & Shmitchell, S. (2021) · Proceedings of the 2021 ACM Conference on Fairness, Accountability, and Transparency · doi:10.1145/3442188.3445922 · Cited by 6,988
PaLM: Scaling Language Modeling with Pathways
Chowdhery, A., Narang, S., Devlin, J., Bosma, M., Mishra, G., Roberts, A., Barham, P., Chung, H. W., Sutton, C., Gehrmann, S., et al. (2022) · arXiv · doi:10.48550/arxiv.2204.02311 · Cited by 2,590
Emergent Abilities of Large Language Models
Wei, J., Tay, Y., Bommasani, R., Raffel, C., Zoph, B., Borgeaud, S., Yogatama, D., Bosma, M., Zhou, D., Metzler, D., et al. (2022) · arXiv · doi:10.48550/arxiv.2206.07682 · Cited by 1,264
Training Compute-Optimal Large Language Models
Hoffmann, J., Borgeaud, S., Mensch, A., Buchatskaya, E., Cai, T., Rutherford, E., Casas, D. D. L., Hendricks, L. A., Welbl, J., Clark, A., et al. (2022) · Advances in Neural Information Processing Systems 35 · doi:10.52202/068431-2176 · Cited by 932
Training Compute-Optimal Large Language Models
Hoffmann, J., Borgeaud, S., Mensch, A., Buchatskaya, E., Cai, T., Rutherford, E., Casas, D. D. L., Hendricks, L. A., Welbl, J., Clark, A., et al. (2022) · arXiv · doi:10.48550/arxiv.2203.15556 · Cited by 929
Anil, R., Dai, A. M., Firat, O., Johnson, M., Lepikhin, D., Passos, A., Shakeri, S., Taropa, E., Bailey, P., Chen, Z., et al. (2023) · arXiv · doi:10.48550/arxiv.2305.10403 · Cited by 834
Beyond the Imitation Game: Quantifying and extrapolating the capabilities of language models
Srivastava, A., Rastogi, A., Rao, A., Shoeb, A. A. M., Abid, A., Fisch, A., Brown, A. R., Santoro, A., Gupta, A., Garriga-Alonso, A., et al. (2022) · arXiv · doi:10.48550/arxiv.2206.04615 · Cited by 569
Deep Learning Scaling is Predictable, Empirically
Hestness, J., Narang, S., Ardalani, N., Diamos, G., Jun, H., Kianinejad, H., Patwary, M. M. A., Yang, Y., & Zhou, Y. (2017) · arXiv · doi:10.48550/arxiv.1712.00409 · Cited by 427
Predictability and Surprise in Large Generative Models
Ganguli, D., Hernandez, D., Lovitt, L., Askell, A., Bai, Y., Chen, A., Conerly, T., Dassarma, N., Drain, D., Elhage, N., et al. (2022) · 2022 ACM Conference on Fairness Accountability and Transparency · doi:10.1145/3531146.3533229 · Cited by 207
Research works printed but not linked: 11
- N Alon and J Spencer. The Probabilistic Method (4th Ed). Wiley, 2016.
- Yoshua Bengio, Réjean Ducharme, and Pascal Vincent. A neural probabilistic language model. Advances in neural information processing systems, 13, 2000.
- HD Brown. Language Assessment: Principles and Classroom Practice (6th Ed). Pearson Education, 2018.
- Tom Brown, Benjamin Mann, Nick Ryder, Melanie Subbiah, Jared D Kaplan, Prafulla Dhariwal, Arvind Neelakantan, Pranav Shyam, Girish Sastry, Amanda Askell, et al. Language models are few-shot learners. Advances in neural information processing systems, 33:1877-1901, 2020.
- N Chomsky. Language and the problems of knowledge. MIT Press, 1988.
- Corinna Cortes, Lawrence D Jackel, Sara Solla, Vladimir Vapnik, and John Denker. Learning curves: Asymptotic values and rate of convergence. Advances in neural information processing systems, 6, 1993.
- A Hippisley and G Stump. Cambridge Handbook of Morphology. Cambridge University Press, 2017.
- Hector Levesque, Ernest Davis, and Leora Morgenstern. The winograd schema challenge. In Thirteenth international conference on the principles of knowledge representation and reasoning, 2012.
- Nikunj Saunshi, Sadhika Malladi, and Sanjeev Arora. A mathematical exploration of why language models help solve downstream tasks. In ICLR 2021, 2021.
- Mark Steedman. Surface Structure and Interpretation. MIT Press, 1996.
- D Tannen (ed). Framing in Discourse. Oxford University Press, 1994.
Cited by
Sorted by citations
Foundational Challenges in Assuring Alignment and Safety of Large Language ModelsPreprint
Anwar, U., Saparov, A., Ramírez, J. R., Paleka, D., Turpin, M., Hase, P., Lubana, E. S., Jenner, E., Casper, S., Sourbut, O., et al. (2024) · arXiv (Cornell University) · doi:10.3929/ethz-b-000706962 · Cited by 320
Look Before You Leap: An Exploratory Study of Uncertainty Analysis for Large Language Models
Huang, Y., Song, J., Wang, Z., Zhao, S., Chen, H., Juefei-Xu, F., & Ma, L. (2025) · IEEE Transactions on Software Engineering · doi:10.1109/tse.2024.3519464 · Cited by 275
Wisdom of the silicon crowd: LLM ensemble prediction capabilities rival human crowd accuracy
Schoenegger, P., Tuminauskaite, I., Park, P. S., Bastos, R. V. S., & Tetlock, P. E. (2024) · Science Advances · doi:10.1126/sciadv.adp1528 · Cited by 117
Observational Scaling Laws and the Predictability of Langauge Model Performance
Ruan, Y., Maddison, C. J., & Hashimoto, T. (2024) · neural information processing systems · doi:10.52202/079017-0506 · Cited by 94
Emergent Abilities in Large Language Models: A SurveyPreprint
Berti, L., Giorgi, F., & Kasneci, G. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2503.05788 · Cited by 93
QuRating: Selecting High-Quality Data for Training Language ModelsPreprint
Wettig, A., Gupta, A., Malik, S., & Chen, D. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2402.09739 · Cited by 90
A Dynamical Model of Neural Scaling LawsPreprint
Bordelon, B., Atanasov, A., & Pehlevan, C. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2402.01092 · Cited by 80
Scaling and renormalization in high-dimensional regression
Atanasov, A., Zavatone-Veth, J. A., & Pehlevan, C. (2026) · Journal of Statistical Mechanics Theory and Experiment · doi:10.1088/1742-5468/ae4bba · Cited by 65
The Quantization Model of Neural Scaling
Michaud, E. J., Liu, Z., Girit, U., & Tegmark, M. (2023) · arXiv · doi:10.48550/arxiv.2303.13506 · Cited by 57
Advancing Social Intelligence in AI Agents: Technical Challenges and Open Questions
Mathur, L., Liang, P. P., & Morency, L. (2024) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2024.emnlp-main.1143 · Cited by 60
Theoretical limitations of multi-layer Transformer
Chen, L., Peng, B., & Wu, H. (2025) · Annual Symposium on Foundations of Computer Science · doi:10.1109/focs63196.2025.00136 · Cited by 50
AI-Augmented Predictions: LLM Assistants Improve Human Forecasting Accuracy
Schoenegger, P., Park, P. S., Karger, E., Trott, S., & Tetlock, P. E. (2024) · ACM Transactions on Interactive Intelligent Systems · doi:10.1145/3707649 · Cited by 51
Large Language Model Prediction Capabilities: Evidence from a Real-World Forecasting TournamentPreprint
Schoenegger, P., & Park, P. S. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2310.13014 · Cited by 44
AI-Assisted Generation of Difficult Math QuestionsPreprint
Shah, V., Yu, D., Lyu, K., Park, S., Yu, J., He, Y., Ke, N. R., Mozer, M. C., Bengio, Y., Arora, S., et al. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2407.21009 · Cited by 42
Self-citationHow to Protect Copyright Data in Optimization of Large Language Models?
Chu, T., Song, Z., & Yang, C. (2024) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v38i16.29741 · Cited by 41
Skill-Mix: a Flexible and Expandable Family of Evaluations for AI modelsPreprint
Yu, D., Kaur, S., Gupta, A., Brown-Cohen, J., Goyal, A., & Arora, S. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2310.17567 · Cited by 34
Self-citationThe Best Instruction-Tuning Data are Those That Fit
Zhang, D., Dai, Q., & Peng, H. M. (2025) · neural information processing systems · doi:10.52202/085713-4717 · Cited by 33
Compositional Abilities Emerge Multiplicatively: Exploring Diffusion Models on a Synthetic Task
Okawa, M., Lubana, E. S., Dick, R. P., & Tanaka, H. (2023) · neural information processing systems · doi:10.52202/075280-2182 · Cited by 29
Multilingual Blending: LLM Safety Alignment Evaluation with Language MixturePreprint
Song, J., Huang, Y., Zhou, Z., & Ма, Л. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2407.07342 · Cited by 28
Out-of-distribution generalization via composition: A lens through induction heads in Transformers
Song, J., Xu, Z., & Zhong, Y. (2025) · Proceedings of the National Academy of Sciences · doi:10.1073/pnas.2417182122 · Cited by 25
Evans, E. N., Cook, M., Bradshaw, Z. P., & LaBorde, M. L. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2403.14753 · Cited by 24
Compositional Capabilities of Autoregressive Transformers: A Study on Synthetic, Interpretable TasksPreprint
Ramesh, R., Lubana, E. S., Khona, M., Dick, R. P., & Tanaka, H. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2311.12997 · Cited by 23
Emergence in non-neural models: grokking modular arithmetic via average gradient outer productPreprint
Mallinar, N., Beaglehole, D., Zhu, L., Radhakrishnan, A., Pandit, P., & Belkin, M. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2407.20199 · Cited by 23
On Provable Length and Compositional GeneralizationPreprint
Ahuja, K., & Mansouri, A. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2402.04875 · Cited by 22
Towards a theory of how the structure of language is acquired by deep neural networks
Cagnetta, F., & Wyart, M. (2024) · neural information processing systems · doi:10.52202/079017-2645 · Cited by 21
Learning to grok: Emergence of in-context learning and skill composition in modular arithmetic tasks
He, T., Doshi, D., Das, A., & Gromov, A. (2024) · neural information processing systems · doi:10.52202/079017-0422 · Cited by 21
A Tale of Tails: Model Collapse as a Change of Scaling Laws
Dohmatob, E., Feng, Y., Yang, P., Charton, F., & Kempe, J. (2024) · arXiv · doi:10.48550/arxiv.2402.07043 · Cited by 20
A Survey to Recent Progress Towards Understanding In-Context Learning
Mao, H., Liu, G., Ma, Y., Wang, R., Johnson, K., & Tang, J. (2025) · Findings of the Association for Computational Linguistics: NAACL · doi:10.18653/v1/2025.findings-naacl.408 · Cited by 20
Humor Mechanics: Advancing Humor Generation with Multistep ReasoningPreprint
Tikhonov, A., & Shtykovskiy, P. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2405.07280 · Cited by 19
Why Larger Language Models Do In-context Learning Differently?Preprint
Shi, Z., Wei, J., Xu, Z., & Liang, Y. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2405.19592 · Cited by 19
A Percolation Model of Emergence: Analyzing Transformers Trained on a Formal LanguagePreprint
Lubana, E. S., Kawaguchi, K., Dick, R. P., & Tanaka, H. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2408.12578 · Cited by 19
Cui, H., Behrens, F., Krząkała, F., & Zdeborová, L. (2024) · neural information processing systems · doi:10.52202/079017-1146 · Cited by 18
A Survey on Compositional Learning of AI Models: Theoretical and Experimental PracticesPreprint
Sinha, S., Premsri, T., & Kordjamshidi, P. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2406.08787 · Cited by 18
Chen, B., Li, X., Liang, Y., Shi, Z., & Song, Z. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2410.11268 · Cited by 17
Prospects for inconsistency detection using large language models and sheavesPreprint
Huntsman, S., Robinson, M. C., & Huntsman, L. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2401.16713 · Cited by 16
Neural Scaling Laws Rooted in the Data DistributionPreprint
Brill, A. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2412.07942 · Cited by 16
The emergence of sparse attention: impact of data distribution and benefits of repetition
Zucchet, N., D'Angelo, F., Lampinen, A. K., & Chan, S. (2025) · neural information processing systems · doi:10.52202/085713-1179 · Cited by 15
Local Convergence of Approximate Newton Method for Two Layer Nonlinear RegressionPreprint
Li, Z., Song, Z., Wang, Z., & Yin, J. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2311.15390 · Cited by 15
Yan, K., Xu, Y., Du, Z. Z., Yao, X., Wang, Z., Guo, X., & Chen, J. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2504.00509 · Cited by 15
INSTRUCT-SKILLMIX: A POWERFUL PIPELINE FOR LLM INSTRUCTION TUNINGPreprint
Kaur, S., Park, S., Goyal, A., & Arora, S. (2024) · arXiv (Cornell University) · doi:10.13140/rg.2.2.11501.55521 · Cited by 15
Self-citationUnmasking Transformers: A Theoretical Approach to Data Recovery via Attention WeightsPreprint
Deng, Y., Song, Z., Xie, S., & Yang, C. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2310.12462 · Cited by 14
Xu, Z., Shi, Z., & Liang, Y. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2407.15720 · Cited by 14
Physics of Skill LearningPreprint
Liu, Z., Liu, Y., Michaud, E. J., Gore, J., & Tegmark, M. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2501.12391 · Cited by 14
Large Language Model Guided Reinforcement Learning Based Six-Degree-of-Freedom Flight Control
Han, Y., Yang, M., Ren, Y., & Li, W. (2024) · IEEE Access · doi:10.1109/access.2024.3411015 · Cited by 13
Phase Transitions in the Output Distribution of Large Language ModelsPreprint
Arnold, J., Holtorf, F., Schäfer, F., & Lörch, N. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2405.17088 · Cited by 13
Zhang, Y., & Gilpin, W. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2505.11349 · Cited by 14
Can ChatGPT Make Explanatory Inferences? Benchmarks for Abductive Reasoning
Thagard, P. R. (2025) · Synthese Library/Synthese library · doi:10.1007/978-3-031-96684-2_12 · Cited by 12
GPT-Neo for commonsense reasoning -- a theoretical and practical lensPreprint
Kashyap, R., Kashyap, V., & P, N. C. (2022) · arXiv (Cornell University) · doi:10.48550/arxiv.2211.15593 · Cited by 12
Hidden Breakthroughs in Language Model TrainingPreprint
Kangaslahti, S., Rosenfeld, E., & Saphra, N. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2506.15872 · Cited by 12
Optimal scaling laws in learning hierarchical multi-index modelsPreprint
Defilippis, L., Krząkała, F., Loureiro, B., & Maillard, A. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2602.05846 · Cited by 12
Liu, T., Xiao, Y., Luo, X., Xu, H., Zheng, W. J., & Zhao, H. (2024) · Findings of the Association for Computational Linguistics: EMNLP (Findings of EMNLP) · doi:10.18653/v1/2024.findings-emnlp.277 · Cited by 11
What do Language Models Learn and When? The Implicit Curriculum HypothesisPreprint
Liu, E., Sun, K., Li, M., Lee, I., Tjuatja, L., Huang, J.-T., & Neubig, G. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2604.08510 · Cited by 11
Convergence of Two-Layer Regression with Nonlinear UnitsPreprint
Deng, Y., Song, Z., & Xie, S. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2308.08358 · Cited by 10
On the Inductive Bias of Stacking Towards Improving Reasoning
Saunshi, N., Karp, S., Krishnan, S., Miryoosefi, S., Reddi, S. J., & Kumar, S. (2024) · neural information processing systems · doi:10.52202/079017-2282 · Cited by 9
Abedsoltan, A., Zhang, H., Wen, K., Lin, H., Zhang, J., & Belkin, M. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2502.08991 · Cited by 9
Pseudo-perplexity in one fell swoop for protein fitness estimation
Kantroo, P., Wagner, G. P., & Machta, B. B. (2025) · PRX Life · doi:10.1103/zhx7-hcmm · Cited by 8
Large Language Models in Cyberattacks
Лебедь, С. В., Namiot, D., Zubareva, E. V., Хенкин, П. В., Воробьева, А. А., & Свичкарь, Д. А. (2024) · Doklady Mathematics · doi:10.1134/s1064562425700012 · Cited by 8
A Theoretical Insight into Attack and Defense of Gradient Leakage in TransformerPreprint
Li, C., Song, Z., Wang, W., & Yang, C. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2311.13624 · Cited by 8
One Pass Streaming Algorithm for Super Long Token Attention Approximation in Sublinear SpacePreprint
Addanki, R., Li, C., Song, Z., & Yang, C. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2311.14652 · Cited by 8
How Does RL Post-training Induce Skill Composition? A Case Study on CountdownPreprint
Park, S. J., Kaur, S. D., & Arora, S. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2512.01775 · Cited by 8
Self-citationBoncoraglio, F., Erba, V., Troiani, E., Xu, Y., Krząkała, F., & Zdeborová, L. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2509.24914 · Cited by 8
Skill-Targeted Adaptive TrainingPreprint
He, Y., Panigrahi, A., Lin, Y., & Arora, S. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2510.10023 · Cited by 8
Self-citationUniversal One-third Time Scaling in Learning Peaked DistributionsPreprint
Liu, Y., Liu, Z., Pehlevan, C., & Gore, J. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2602.03685 · Cited by 8
Why Larger Models Learn More: Effects of Capacity, Interference, and Rare-Task RetentionPreprint
Huang, J., Wurgaft, D., Bansal, R., Ruis, L., Saphra, N., Alvarez-Melis, D., Lampinen, A. K., Potts, C., & Lubana, E. S. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.29548 · Cited by 8
Multilingual Blending: Large Language Model Safety Alignment Evaluation with Language Mixture
Song, J., Huang, Y., Zhou, Z., & Ma, L. (2025) · Findings of the Association for Computational Linguistics: NAACL · doi:10.18653/v1/2025.findings-naacl.191 · Cited by 7
Neural Thermodynamics: Entropic Forces in Deep and Universal Representation Learning
Ziyin, L., Xu, Y., & Chuang, I. L. (2025) · neural information processing systems · doi:10.52202/085713-1877 · Cited by 7
The Expressibility of Polynomial based Attention Scheme
Song, Z., Wang, C., Xu, G., & Yin, J. (2025) · ACM SIGKDD Conference on Knowledge Discovery and Data Mining (KDD) · doi:10.1145/3711896.3737153 · Cited by 7
Unearthing Skill-Level Insights for Understanding Trade-Offs of Foundation ModelsPreprint
Moayeri, M., Balachandran, V., Chandrasekaran, V., Yousefi, S., Fel, T., Feizi, S., Nushi, B., Joshi, N., & Vineet, V. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2410.13826 · Cited by 7
AgenticDataBench: A Comprehensive Benchmark for Data AgentsPreprint
Sun, Z., Zhong, S., Wen, D., Han, J., Li, G., Yan, Y., Zhang, P., Su, Y. W., Qi, X., Sun, B., et al. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2607.01647 · Cited by 7
Learning Beyond Pattern Matching? Assaying Mathematical Understanding in LLMsPreprint
Guo, S., Didolkar, A., Ke, N. R., Goyal, A., Huszár, F., & Schölkopf, B. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2405.15485 · Cited by 6
Self-citationThe Role of Diversity in In-Context Learning for Large Language ModelsPreprint
Xiao, W., Zhao, H., & Huang, L. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2505.19426 · Cited by 6
Cui, H., Behrens, F., Krząkała, F., & Zdeborová, L. (2025) · Journal of Statistical Mechanics Theory and Experiment · doi:10.1088/1742-5468/ade137 · Cited by 5
Can Models Learn Skill Composition from Examples?
Zhao, H., Kaur, S. D., Yu, D., Goyal, A., & Arora, S. (2024) · neural information processing systems · doi:10.52202/079017-3251 · Cited by 5
Self-citationOko, K., Song, Y., Suzuki, T., & Wu, D. C.-Y. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2406.11828 · Cited by 5
Shattered Compositionality: Counterintuitive Learning Dynamics of Transformers for ArithmeticPreprint
Zhao, X., Sharma, D., Uppaal, R., & Zhong, Y. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2601.22510 · Cited by 5
The Geometry of Alignment Collapse: When Fine-Tuning Breaks SafetyPreprint
Springer, M., Lee, C. P., Metevier, B., Castleman, J., Turbal, B., Jung, H., Shen, Z., & Korolova, A. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2602.15799 · Cited by 5
Neural Scaling Universality: If Exponents Are Fixed, Time to Understand CoefficientsPreprint
Liu, Y., & Gore, J. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2606.25008 · Cited by 5
Ghost Mechanism: An Analytical Model of Abrupt Learning in Recurrent Networks
Dinç, F., Cirakman, E., Kurtkaya, B., Yüksekgönül, M., Jiang, Y., Schnitzer, M. J., & Tanaka, H. (2026) · Physical Review X · doi:10.1103/mjcl-lb4x · Cited by 4
The Information of Large Language Model GeometryPreprint
Tan, Z., Li, C., & Huang, W. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2402.03471 · Cited by 4
Scaling Efficient LLMsPreprint
Kausik, B. N. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2402.14746 · Cited by 4
Analyzing Neural Scaling Laws in Two-Layer Networks with Power-Law Data SpectraPreprint
Worschech, R., & Rosenow, B. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2410.09005 · Cited by 4
Swing-by Dynamics in Concept Learning and Compositional GeneralizationPreprint
Yang, Y., Park, C. F., Lubana, E. S., Okawa, M., Hu, W., & Tanaka, H. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2410.08309 · Cited by 4
Ziemann, I., Matni, N., & Pappas, G. J. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2409.13421 · Cited by 4
Discovering Hierarchical Latent Capabilities of Language Models via Causal Representation LearningPreprint
Jin, J., Syrgkanis, V., Kakade, S. M., & Zhang, H. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2506.10378 · Cited by 4
Towards Compositional Generalization of LLMs via Skill Taxonomy Guided Data SynthesisPreprint
Wei, Y., Du, L., Yu, X., Feng, Y., & Li, A. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2601.03676 · Cited by 4
Circuit Stability Characterizes Language Model Generalization
Sun, A. (2025) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2025.acl-long.442 · Cited by 3
Cortes-Penfield, N. W., & Schwartz, I. S. (2024) · Clinical Infectious Diseases · doi:10.1093/cid/ciae446 · Cited by 3
Skill Path: Unveiling Language Skills from Circuit Graphs
Chen, H., Yang, X., Zhu, J., & Wang, W. (2026) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v40i36.40271 · Cited by 3
Wang, L., Li, H., Hu, L., Cai, J., & Du, Z. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2407.09977 · Cited by 3
A Theoretical Survey on Foundation ModelsPreprint
Fu, S., Chen, Y., Wang, Y., & Tao, D. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2410.11444 · Cited by 3
A non-ergodic framework for understanding emergent capabilities in Large Language ModelsPreprint
Marín, J. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2501.01638 · Cited by 3
Decomposing Complex Visual Comprehension into Atomic Visual Skills for Vision Language ModelsPreprint
Chae, H., Yoon, S., Park, J., Chun, C. Y., Cho, Y., Cai, M., Lee, Y. J., & Ryu, E. K. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2505.20021 · Cited by 3
Higuchi, R., Kawata, R., Nishikawa, N., Oko, K., Yamaguchi, S., Kobayashi, S., Tokui, S., Hayashi, K., Okanohara, D., & Suzuki, T. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2504.17562 · Cited by 3
Observational Scaling Laws and the Predictability of Language Model Performance
Ruan, Y., Maddison, C. J., & Hashimoto, T. (2024) · arXiv · doi:10.48550/arxiv.2405.10938 · Cited by 3
LLM Prompting Methodology and Taxonomy to Benchmark our Engineering Curriculums
Jamieson, P., Bhunia, S., Ricco, G. D., Swanson, B., & Scoy, B. V. (2025) · ASEE Annual Conference & Exposition · doi:10.18260/1-2--56938 · Cited by 2
The Quantum Ecology as an Onto-Epistemological Framework: Toward an Ecological Theory of Sensing
Calzati, S., & Kerckhove, D. C. F. D. (2025) · Digital Society · doi:10.1007/s44206-025-00228-0 · Cited by 2
Zipping the Thought: When and How Compressed Reasoning Data Works in LLM Post-Training
Matsutani, K., Minegishi, G., Kojima, T., Iwasawa, Y., & Matsuo, Y. (2026) · Findings of the Association for Computational Linguistics: EMNLP (Findings of EMNLP) · doi:10.18653/2026.findings-emnlp.984 · Cited by 2
Yan, K., Xu, Y., Du, Z., Yao, X., Wang, Z., Guo, X., & Chen, J. (2025) · International Joint Conference on Natural Language Processing and Conference of the Asia-Pacific Chapter of the Association for Computational Linguistics (IJCNLP-AACL) · doi:10.18653/v1/2025.ijcnlp-long.17 · Cited by 2
Pelican Soup Framework: A Theoretical Framework for Language Model Capabilities
Chiang, T.-R., & Yogatama, D. (2026) · Findings of the Association for Computational Linguistics: EACL · doi:10.18653/v1/2026.findings-eacl.23 · Cited by 2
Understanding Logical Reasoning Ability of Large Language ModelsPreprint
Chan, E. (2024) · SSRN Electronic Journal · doi:10.20944/preprints202408.1712.v1 · Cited by 2
Metadata
- Authors
- Arora, S., & Goyal, A.
- Affiliations
- Princeton University (US)
- Venue
- arXiv
- Publisher
- arXiv
- Published
- 2023
- ISSN
- 2331-8422 (ISSN-L)
- arXiv
- 2307.15936
- OpenAlex
- W4385473649
- Semantic Scholar
- ff6f2b9e56ee0f3f26bcbdc5079678c059fe24e3
- Cited by
- 129
- References
- 9
- Citations by year
- 2026: 30 · 2025: 40 · 2024: 47 · 2023: 11
- Type
- posted content
- Language
- en
- Open access
- green
- arxiv.org
- Licence
- Locations
- arXiv (Cornell University) (submittedVersion, cc-by)
- arXiv (Cornell University) (cc-by)
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Topic Modeling
- Physical Sciences › Computer Science › Artificial Intelligence › Natural Language Processing Techniques
- Physical Sciences › Computer Science › Artificial Intelligence › Domain Adaptation and Few-Shot Learning
- Keywords
- large language models, scaling laws, inductive bias, cross-entropy loss, compositional skills, parameter scaling, generalization theory
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
A language model drew the claims from the paper on 2026-11-08, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-11-08 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Cited sources are checked with a language model’s help (gpt-6-sol).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
