

The DOI matches its Crossref record; 33 of the 33 references it cites were found in a registry or an index.
Knowledge-enhanced visual-language pre-training on chest radiology images
Open accessAbstract
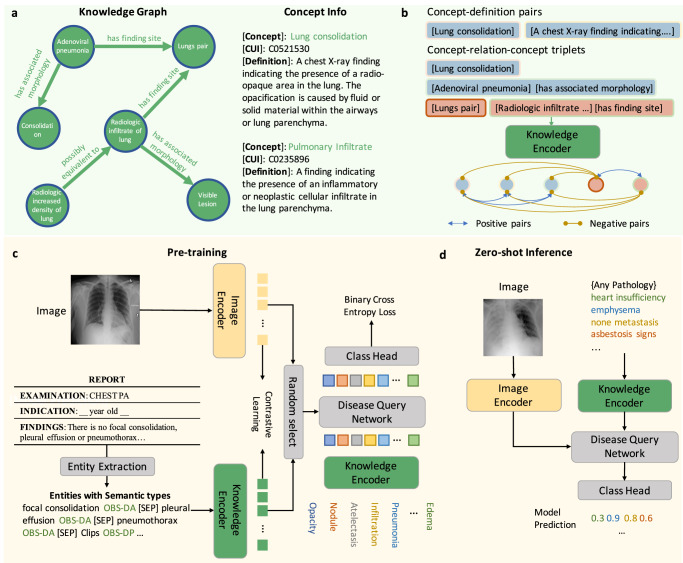
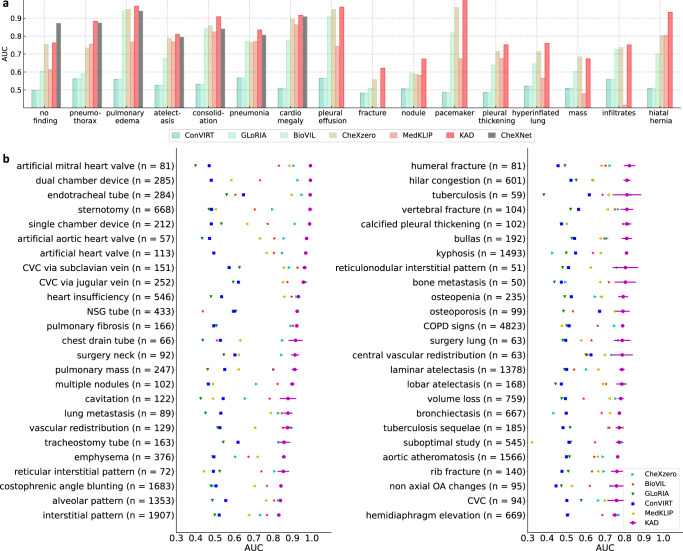
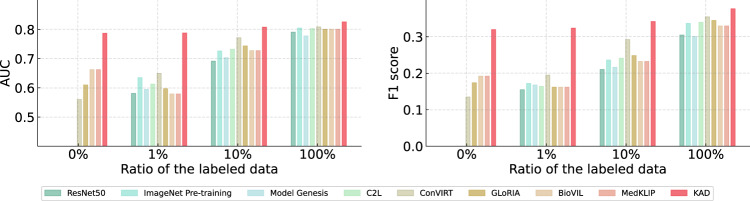
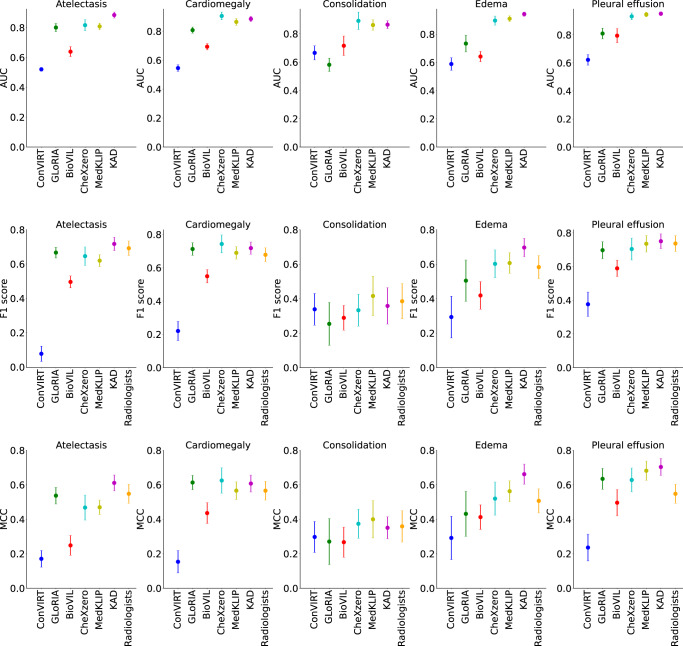
While multi-modal foundation models pre-trained on large-scale data have been successful in natural language understanding and vision recognition, their use in medical domains is still limited due to the fine-grained nature of medical tasks and the high demand for domain knowledge. To address this challenge, we propose an approach called Knowledge-enhanced Auto Diagnosis (KAD) which leverages existing medical domain knowledge to guide vision-language pre-training using paired chest X-rays and radiology reports. We evaluate KAD on four external X-ray datasets and demonstrate that its zero-shot performance is not only comparable to that of fully supervised models but also superior to the average of three expert radiologists for three (out of five) pathologies with statistical significance. Moreover, when few-shot annotation is available, KAD outperforms all existing approaches in fine-tuning settings, demonstrating its potential for application in different clinical scenarios.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“By leveraging encoders pre-trained on large unimodal datasets and occasionally fine-tuning them on the available multimodal data, researchers can achieve robust performance despite the relative scarcity of multimodal data (Wang et al., 2023a; Zhang et al., 2023).”
From Navigating the landscape of multimodal AI in medicine: A scoping review on technical challenges and clinical applications (2025) · cites this paper as Zhang et al., 2023
Experimental — accuracy not yet measured
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Deep Residual Learning for Image Recognition
He, K., Zhang, X., Ren, S., & Sun, J. (2016) · 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2016.90 · Cited by 235,474
Self-citationVaswani, A., Shazeer, N., Parmar, N., Uszkoreit, J., Jones, L., Gomez, A. N., Kaiser, L., & Polosukhin, I. (2017) · arXiv · doi:10.48550/arxiv.1706.03762 · Cited by 120,404
ImageNet: A large-scale hierarchical image database
Deng, J., Dong, W., Socher, R., Li, L.-J., Li, K., & Fei-Fei, L. (2009) · 2009 IEEE Conference on Computer Vision and Pattern Recognition · doi:10.1109/cvpr.2009.5206848 · Cited by 65,333
An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale
Dosovitskiy, A., Beyer, L., Kolesnikov, A., Weissenborn, D., Zhai, X., Unterthiner, T., Dehghani, M., Minderer, M., Heigold, G., Gelly, S., et al. (2020) · arXiv · doi:10.48550/arxiv.2010.11929 · Cited by 47,472
Language Models are Few-Shot Learners
Brown, T. B., Mann, B., Ryder, N., Subbiah, M., Kaplan, J., Dhariwal, P., Neelakantan, A., Shyam, P., Sastry, G., Askell, A., et al. (2020) · arXiv · doi:10.48550/arxiv.2005.14165 · Cited by 23,372
Learning Transferable Visual Models From Natural Language Supervision
Radford, A., Kim, J. W., Hallacy, C., Ramesh, A., Goh, G., Agarwal, S., Sastry, G., Askell, A., Mishkin, P., Clark, J., et al. (2021) · arXiv · doi:10.48550/arxiv.2103.00020 · Cited by 15,293
Wang, X., Peng, Y., Lu, L., Lu, Z., Bagheri, M., & Summers, R. M. (2017) · 2017 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2017.369 · Cited by 4,616
The unified medical language system (UMLS): integrating biomedical terminology
Bodenreider, O. (2004) · Nucleic Acids Research · doi:10.1093/nar/gkh061 · Cited by 4,356
CheXNet: Radiologist-Level Pneumonia Detection on Chest X-Rays with Deep LearningPreprint
Rajpurkar, P., Irvin, J., Zhu, K., Yang, B., Mehta, H., Duan, T., Ding, D. Y., Bagul, A., Langlotz, C. P., Shpanskaya, K. S., et al. (2017) · arXiv (Cornell University) · doi:10.48550/arxiv.1711.05225 · Cited by 4,226
On the Opportunities and Risks of Foundation Models
Bommasani, R., Hudson, D. A., Adeli, E., Altman, R., Arora, S., von Arx, S., Bernstein, M. S., Bohg, J., Bosselut, A., Brunskill, E., et al. (2021) · arXiv · doi:10.48550/arxiv.2108.07258 · Cited by 2,676
Self-citation
Research works printed but not linked: 4
- Devlin, J., Chang, M.-W., Lee, K. & Toutanova, K. Bert: Pre-training of deep bidirectional transformers for language understanding. In Proc. 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, 4171–4186 (ACL, 2019).
- Ma, C., Yang, Y., Wang, Y., Zhang, Y. & Xie, W. Open-vocabulary semantic segmentation with frozen vision-language models. British Machine Vision Conference (2022).
- Zhang, Y., Jiang, H., Miura, Y., Manning, C. D. & Langlotz, C. P. Contrastive learning of medical visual representations from paired images and text. PMLR 182, 2–25. Highest Starred Implementation: https://github.com/edreisMD/ConVIRT-pytorch (2022).
- Loshchilov, I. & Hutter, F. Decoupled weight decay regularization. In Proc. International Conference on Learning Representations (2019).
Cited by
Sorted by citations
Items 101–200 of 207
DWARF: Disease-Weighted Network for Attention Map Refinement
Luo, H., de Mortanges, A. P., Inel, O., & Reyes, M. (2025) · Lecture notes in computer science · doi:10.1007/978-3-031-77610-6_6 · Cited by 4
Xu, Q., Xu, X., Zhou, C., Liu, Z., Huang, F., Li, S., Zhu, L., Bai, Z., Xu, Y., & Hu, W. (2025) · Expert Systems with Applications · doi:10.1016/j.eswa.2025.126585 · Cited by 6
ACE: Anatomically Consistent Embeddings in Composition and Decomposition
Zhou, Z., Luo, H., Taher, M. R. H., Pang, J., Ding, X., Gotway, M. B., & Liang, J. (2025) · IEEE Winter Conference on Applications of Computer Vision · doi:10.1109/wacv61041.2025.00376 · Cited by 3
Trivedi, H., & Gichoya, J. W. (2024) · Radiology Artificial Intelligence · doi:10.1148/ryai.230568 · Cited by 3
Yang, C., Jin, Q., Du, F., Guo, J., & Zhou, Y. (2025) · Complex & Intelligent Systems · doi:10.1007/s40747-024-01717-4 · Cited by 3
A Reality Check of Vision-Language Pre-training in Radiology: Have We Progressed Using Text?
Silva-Rodríguez, J., Dolz, J., & Ayed, I. B. (2025) · Lecture notes in computer science · doi:10.1007/978-3-031-96625-5_20 · Cited by 2
CXR-CML: Improved Zero-Shot Classification of Long-Tailed Multi-label Diseases in Chest X-Rays
Madhipati, R., Bhat, S., Buess, L., & Maier, A. (2025) · Lecture notes in computer science · doi:10.1007/978-3-032-04981-0_12 · Cited by 2
Yi, Q., Nanayakkara, D. S. G., & Li, X. (2025) · Lecture notes in computer science · doi:10.1007/978-3-032-04981-0_34 · Cited by 2
Foundation Model for Medical Imaging: A Comprehensive Review
Jiao, L., Yang, J., Li, R., Liu, F., Liu, X., Chen, P., Guo, Y., Li, L., Shang, R., & Ma, W. (2025) · IEEE Transactions on Artificial Intelligence · doi:10.1109/tai.2025.3618796 · Cited by 4
VTAG: Visual-Textual Association Guided Radiology Reports Generation
Su, Z., Lin, Y., Song, H., Jian, R., Liu, B., & Yang, J. (2025) · IEEE Transactions on Image Processing · doi:10.1109/tip.2025.3623915 · Cited by 2
Recent Progress in Deep Learning for Chest X-Ray Report Generation
Salhi, M., & Akhloufi, M. A. (2026) · BioMedInformatics · doi:10.3390/biomedinformatics6010003 · Cited by 3
Wang, Z., Fang, Y., & Li, Q. (2026) · Journal of Translational Medicine · doi:10.1186/s12967-026-08211-0 · Cited by 3
Overview of State-of-the-Art Learning-Based Classification Methods in Medical Imaging
Nia, N. G., Manwar, R., & Avanaki, K. (2026) · Annals of Biomedical Engineering · doi:10.1007/s10439-026-04241-3 · Cited by 2
Generative AI for healthcare: fundamentals, challenges, and perspectives
Chen, G., Liu, C., Anne, O. G., Tan, M., Xie, Z., Yin, J., Yip, J. W. L., Zhang, W., ZHU, J., & Ooi, B. C. (2026) · Science China Information Sciences · doi:10.1007/s11432-025-4927-2 · Cited by 9
Chest x-ray diagnosis via spatial-channel high-order attention representation learning
Gao, X., Jiang, B., Wang, X., Huang, L., & Tu, Z. (2024) · Physics in Medicine and Biology · doi:10.1088/1361-6560/ad2014 · Cited by 2
Xiao, S., Zhang, Y., Jiang, L., & Wang, Z. (2024) · International Conference on Computational Intelligence and Applications (ICCIA) · doi:10.1109/iccia62557.2024.10719240 · Cited by 2
Self-citationYe, Y., Zhang, J., & Shi, H. (2024) · Lecture notes in computer science · doi:10.1007/978-981-97-8496-7_20 · Cited by 2
On the Interplay of Human-AI Alignment, Fairness, and Performance Trade-Offs in Medical Imaging
Luo, H., Zhou, Z., Shu, S. Z., de Mortanges, A. P., Berke, R., & Reyes, M. (2025) · Lecture notes in computer science · doi:10.1007/978-3-032-05185-1_41 · Cited by 3
Semantic-Aware Hard Negative Mining for Medical Vision-Language Contrastive Pretraining
Li, Y., Cheng, Y., Pan, Y., He, W., Wang, Q., Feng, R., & Zhang, X. (2025) · ACM International Conference on Multimedia (ACM MM) · doi:10.1145/3746027.3754991 · Cited by 2
Self-citationFoundation models in medical image analysis: A systematic review and quantitative analysis
Rajendran, P., Safari, M., He, W., Hu, M., Shah, K. D., Wang, S., Zhou, J., & Yang, X. (2026) · Medical Image Analysis · doi:10.1016/j.media.2026.104293 · Cited by 8
Zhang, T. J., Ma, C., & Wang, Y. (2024) · Electronics · doi:10.3390/electronics13234693 · Cited by 1
Self-citationPRIDE: Pediatric Radiological Image Diagnosis Engine Guided by Medical Domain Knowledge
Zhao, Y., Pang, S., Wang, Z., He, W., Wang, Y., Zhao, R.-W., Feng, R., & Zhang, X. (2024) · IEEE International Conference on Bioinformatics and Biomedicine (BIBM) · doi:10.1109/bibm62325.2024.10822246 · Cited by 1
Self-citationVision-Language Pre-training from Synthetic Data
Liu, C. (2024) · Springer eBooks · doi:10.1007/978-3-031-80965-1_6 · Cited by 1
Debiasing Medical Knowledge for Prompting Universal Model in CT Image Segmentation
Yun, B., Zhao, S., Li, Q., Kot, A. C., & Wang, Y. (2025) · IEEE Transactions on Medical Imaging · doi:10.1109/tmi.2025.3589399 · Cited by 2
Self-citationGao, X., Wang, X., Jiang, B., Wang, X., Tang, J., & Li, C. (2025) · Machine Intelligence Research · doi:10.1007/s11633-024-1530-4 · Cited by 2
Medical Contrastive Learning of Positive and Negative Mentions
Wu, W., Yang, J., Zhu, X., Zhang, X., Liu, Z., Li, M., & Wu, J. Y. (2025) · Lecture notes in computer science · doi:10.1007/978-3-032-05141-7_38 · Cited by 1
Self-citationBaMCo: Balanced Multimodal Contrastive Learning for Knowledge-Driven Medical VQA
Yazıcı, Z. A., & Ekenel, H. K. (2025) · Lecture notes in computer science · doi:10.1007/978-3-032-04981-0_8 · Cited by 1
Park, J., Moon, C., Lee, D., Kim, K., & Hwang, M. (2025) · Lecture notes in computer science · doi:10.1007/978-3-032-04981-0_36 · Cited by 1
Li, Y., Lai, H., Zhou, X., Ming, S., Ma, W., Wei, W., & Zhou, S. K. (2025) · Lecture notes in computer science · doi:10.1007/978-3-032-04981-0_33 · Cited by 2
Zhang, Z., Teng, L., Zhao, N., Liu, Y., Qiu, Z., Weng, Z., Kong, J., Shi, F., & Shen, D. G. (2025) · Lecture notes in computer science · doi:10.1007/978-3-032-05182-0_41 · Cited by 1
Reading Between the Channels: Knowledge-Augmented Medical Time Series Classification
Yuan, X., Wang, W. W., Chen, J., & Hu, X. (2025) · ACM International Conference on Multimedia (ACM MM) · doi:10.1145/3746027.3755824 · Cited by 1
Automated Radiology Report Generation Based on Topic-Keyword Semantic Guidance
Xiao, J., Liu, H., Dong, R., Liu, J., & Yu, H. (2025) · IEEE International Conference on Multimedia and Expo (ICME) · doi:10.1109/icme59968.2025.11209777 · Cited by 1
Transformer-Based Encoder-Decoder Model for Medical Image Captioning with Concept Embedding
Fadhilah, H., & Utama, N. P. (2025) · JURNAL MASYARAKAT INFORMATIKA · doi:10.14710/jmasif.17.1.75082 · Cited by 1
Li, J., Li, Z., Chi, J., & Bi, Z. (2025) · IEEE International Conference on Bioinformatics and Biomedicine (BIBM) · doi:10.1109/bibm66473.2025.11356033 · Cited by 1
HF-VLP: A multimodal vision-language pre-trained model for diagnosing heart failure
Ma, H., Li, D., Zhao, G., Liu, L., Fu, J., Fan, X., Zhang, Z., & Liang, Y. (2026) · Computerized Medical Imaging and Graphics · doi:10.1016/j.compmedimag.2026.102719 · Cited by 1
Zhang, S., Hou, Q., Ding, M., Zhu, Y., Dai, G., Lu, Z., Liu, Z., Chen, B., Li, X., Liu, J., et al. (2026) · Annals of Surgical Oncology · doi:10.1245/s10434-026-19248-2 · Cited by 1
Li, S.-Q., Zhen, C., Li, B., Zhao, J.-G., & Huang, J.-S. (2026) · Expert Systems with Applications · doi:10.1016/j.eswa.2026.131921 · Cited by 1
Knowledge-enhanced AI models for domain-specific application: a survey
Li, X.-Y., Wang, Y., Liang, J., Wang, X., Zhou, P., Zhao, Q., Zhang, Y., & Song, Q. (2026) · Science China Information Sciences · doi:10.1007/s11432-025-4635-0 · Cited by 1
Self-citationMed-ViX-Ray: Enhancing explainable chest X-ray analysis with clinical knowledge graphs
Cieri, M., & Palomba, F. (2026) · Computer Methods and Programs in Biomedicine · doi:10.1016/j.cmpb.2026.109313 · Cited by 1
Meta-Entity Driven Triplet Mining for Aligning Medical Vision-Language Models
Yilmaz, M., Öztürk, Ş., Kara, M., Yavuz, M. T., Gümeler, E., Koç, A., & Çukur, T. (2026) · IEEE Journal of Biomedical and Health Informatics · doi:10.1109/jbhi.2026.3678306 · Cited by 2
Rajaraman, S., Marini, N., Liang, Z., Xue, Z., & Antani, S. (2026) · Journal of Medical Systems · doi:10.1007/s10916-026-02368-3 · Cited by 1
Clinical Knowledge Representation in Data Science
Nguyen, T. A., Su, W., Rajagopalan, A. S., Abdurezak, N., Hewryk, O. S. I., & Romano, J. D. (2026) · Annual Review of Biomedical Data Science · doi:10.1146/annurev-biodatasci-092724-050810 · Cited by 2
brat : Aligned Multi-View Embeddings for Brain MRI Analysis
Kayser, M., Gridnev, M., Wang, W., Bain, M., Rangnekar, A., Chatterjee, A., Petrov, A., Veeraraghavan, H., & Swinburne, N. (2026) · IEEE Winter Conference on Applications of Computer Vision · doi:10.1109/wacv61042.2026.00568 · Cited by 1
Li, J., Liu, C. H., Bai, W., Liu, M., Arcucci, R., Bercea, C. I., & Schnabel, J. A. (2026) · IEEE Winter Conference on Applications of Computer Vision · doi:10.1109/wacv61042.2026.00233 · Cited by 1
Bi-MCQ: Reformulating Vision–Language Alignment for Negation Understanding
Kim, T. H., & Lee, H. G. (2026) · Lecture notes in computer science · doi:10.1007/978-3-032-31397-3_13 · Cited by 1
Elallaf, A., Zhang, Y., Masupalli, Y. P., Yang, J., Lee, Y., Cao, Z., & Liang, G. (2026) · IEEE/CVF Winter Conference on Applications of Computer Vision Workshops (WACVW) · doi:10.1109/wacvw68408.2026.00005 · Cited by 1
Self-citationLi, J., Xiao, L., Qu, X., Du, L., Gong, T., Yu, Y., Li, Y., 谢鹏飞, Chu, G., Li, H., et al. (2026) · Radiology · doi:10.1148/radiol.253579 · Cited by 1
Self-citationKEXNet: A Knowledge-Enhanced Model for Improved Chest X-Ray Lesion Detection
Yan, Q., Duan, J., & Wang, J. (2024) · Big Data Mining and Analytics · doi:10.26599/bdma.2024.9020045 · Cited by 2
Wang, J., Wang, T., Xu, J., Zhang, Z., Wang, H., & Li, H. (2024) · IEEE International Conference on Bioinformatics and Biomedicine (BIBM) · doi:10.1109/bibm62325.2024.10822114 · Cited by 1
Ren, X., Ji, G., Chu, S., Yoshida, S., Zhao, J., Jia, B., & Qiang, Y. (2025) · Journal of X-Ray Science and Technology · doi:10.1177/08953996241296400 · Cited by 2
Knowledge guided relation enhancement for human-object interaction detection
Su, R., Gao, Y., Yu, W., Wu, C., Jiang, X., & Zhou, S. (2025) · Applied Intelligence · doi:10.1007/s10489-025-06279-7 · Cited by 1
Self-citationMedical Transformer With Mix Mask Generation for Thorax Disease Classification
Liu, Z., Wang, Z., & Du, B. (2025) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2025.3543003 · Cited by 1
A Framework for Evaluating the Efficacy of Foundation Embedding Models in HealthcarePreprint
Xu, S. H., Gui, H., Rotemberg, V. M., Wang, T., Chen, Y. T., & Daneshjou, R. (2024) · medRxiv · doi:10.1101/2024.04.17.24305983 · Cited by 1
Ndoro, S., Edwards, S., & McNally, R. (2026) · British Journal of Healthcare Management · doi:10.12968/bjhc.2025.0145 · Cited by 1
Qiao, L., Cheng, L. D., Shu, Y., Luan, X., & Xiao, B. (2024) · IEEE International Conference on Bioinformatics and Biomedicine (BIBM) · doi:10.1109/bibm62325.2024.10822282
Text-Guided Vision Mamba for Alzheimer’s Disease Prediction Using $$ ^{18}$$F-FDG PET
Zhou, D., Chen, Y., Liu, Y., & Jiang, B. (2025) · Lecture notes in computer science · doi:10.1007/978-981-96-2885-8_2
Speech-Driven Medical Emergency Decision-Support Systems in Constrained Environments
Aityan, S. K., Mosaddegh, A., Herrero, R., Gargiulo, C., Lazzaro, R., & Iacovazzo, N. (2025) · Engineering cyber-physical systems and critical infrastructures · doi:10.1007/978-3-031-83149-2_6 · Cited by 1
Medical Visual Question Answering: A Review
Yang, G., Liang, K., Liu, X., Liu, J., & Liu, Y. (2025) · Recent Advances in Computer Science and Communications · doi:10.2174/0126662558373783250404150025
Ghelichkhan, E., & Taşdizen, T. (2025) · IEEE International Symposium on Biomedical Imaging (ISBI) · doi:10.1109/isbi60581.2025.10981290
Wang, C., Pan, C., Meng, C., & Fang, N.-N. (2025) · International Conference on Computing, Networks and Internet of Things (CNIOT) · doi:10.1109/cniot65435.2025.11070476
Zhu, J., & Lü, P. (2025) · Lecture notes in computer science · doi:10.1007/978-3-031-98688-8_14
Knowledge-Enhanced Hyperbolic Language-Image Pretraining for Zero-Shot Learning
Han, L., Qiao, Z., Zhen, X., Gao, J., & Qian, Z. (2025) · Lecture notes in computer science · doi:10.1007/978-3-031-96625-5_14
KECAN: knowledge-enhanced cross-modal alignment network for ophthalmic report generation
Wang, J., Shi, M., Fan, J., Zhang, Y., & Wang, R. (2025) · Multimedia Systems · doi:10.1007/s00530-025-01956-6 · Cited by 1
Self-citationImproving Cross-Modal Consistency in Multimodal Biomedical AI: A Comprehensive Review of Techniques
Basak, A., Choudhury, S. N., & Garai, P. (2025) · International Conference on Computing, Intelligence, and Application (CIACON) · doi:10.1109/ciacon65473.2025.11189769
Zhou, Z., Luo, H., Taher, M. R. H., Pang, J., Ding, X., Gotway, M. B., & Liang, J. (2025) · Lecture notes in computer science · doi:10.1007/978-3-032-07845-2_1
Qiao, L., Gao, S., Shu, Y., Xiao, B., Li, W., & Gao, X. (2025) · ACM International Conference on Multimedia (ACM MM) · doi:10.1145/3746027.3755336
Domain Adaptation in Multimodal Models
Ramakrishnan, R. (2025) · Artificial intelligence · doi:10.5772/intechopen.1011584
Gong, Z., He, L., Zhou, N., Liao, P., Yang, H., Wu, Z., Chen, H., & Zhang, Y. (2025) · International Joint Conference on Neural Networks (IJCNN) · doi:10.1109/ijcnn64981.2025.11228394
Self-citationGao, Y., Zhou, H.-Y., Wang, X., Portaluri, A., Zhang, T., Beets‐Tan, R. G. H., Han, L., Lu, C., Estacio, L., D'Angelo, A. R., et al. (2025) · Radiology Artificial Intelligence · doi:10.1148/ryai.240646 · Cited by 1
Ma, D., Pang, J., Zhou, Z., Gotway, M. B., & Liang, J. (2025) · Lecture notes in computer science · doi:10.1007/978-3-032-07845-2_16
Tan, M., Wu, Q., Zhang, B., Ren, G., Nie, J., Xue, Z., Cao, X., & Shen, D. G. (2025) · Lecture notes in computer science · doi:10.1007/978-3-032-07845-2_8
Chest X-ray foundation models: A survey and future directions
Wang, A., Yang, Z., Rais-Bahrami, S., & Yan, P. (2025) · Meta-Radiology · doi:10.1016/j.metrad.2025.100203 · Cited by 1
Fine-Grained Knowledge-Guided Alignment for Medical Vision-Language Pre-Training
Pan, Y., Cheng, Y., Li, Y., Li, Q., Yuan, R., & Feng, R. (2025) · IEEE International Conference on Bioinformatics and Biomedicine (BIBM) · doi:10.1109/bibm66473.2025.11356422
DeViDe: Faceted Medical Knowledge to Enhance Vision Foundation Model Pretraining for Radiology
Luo, H., Zhou, Z., Hou, M., Royer, C., Reyes, M., Sekuboyina, A., & Menze, B. H. (2025) · IEEE International Conference on Bioinformatics and Biomedicine (BIBM) · doi:10.1109/bibm66473.2025.11357035
Hybrid Explanation-Guided Learning for Transformer-Based Chest X-Ray Diagnosis
Shu, S. Z., Luo, H., Poellinger, A., & Reyes, M. (2026) · Lecture notes in computer science · doi:10.1007/978-3-032-17611-0_4
Unified Supervision for Vision-Language Modeling in 3D Computed Tomography
Lee, H.-C., Liu, Z., Ahmed, H., Kim, S., Huver, S. D., Nath, V., Fayad, Z. A., Deyer, T. W., & Mei, X. (2025) · IEEE International Conference on Computer Vision Workshops · doi:10.1109/iccvw69036.2025.00700
Wang, B., Guo, D., Yang, F., Zhang, H., Teng, P., Tavares, A., & Xu, H. (2026) · Knowledge-Based Systems · doi:10.1016/j.knosys.2026.115672 · Cited by 1
Zhao, Y., Wang, Q. R., Wang, Y., Ruiwei, Z. H. A. O., Feng, R., & Zhang, X. (2026) · Journal of Imaging · doi:10.3390/jimaging12030111
Self-citationKnowledge-Guided and Reinforced Selective State Space Model for radiology report generation
Li, Z., Yang, D., Li, R., & Zhang, J. (2026) · Journal of Biomedical Informatics · doi:10.1016/j.jbi.2026.105011
SCLiP-Polyp: Sentence-level clinical priors for language-guided polyp segmentation
Li, X., Lu, H., Jia, Y., Han, L., & Zhang, D. (2026) · Biomimetic Intelligence and Robotics · doi:10.1016/j.birob.2026.100329
Large‑scale data harmonization of radiology studies via multigranular vision‑language alignment
Li, Z., Wang, Y., Farsiu, S., & Kinahan, P. (2026) · SPIE Medical Imaging: Imaging Informatics for Healthcare, Research, and Applications · doi:10.1117/12.3085934
Self-citationFinetuning medical vision‑language models for interpretable and fine‑grained disease classification
Engelson, S., Ehrhardt, J., & Heinz Handels, A. (2026) · SPIE Medical Imaging: Computer-Aided Diagnosis · doi:10.1117/12.3086032
Knowledge enhancement with cross-modal fusion network for radiological report generation
LIANG, Z., Hou, X., Song, X., & Zhang, Y. (2026) · Multimedia Systems · doi:10.1007/s00530-026-02291-0
Self-citationMRGen: Segmentation Data Engine for Underrepresented MRI Modalities
Wu, H., Zhao, Z., Zhang, Y., Wang, Y., & Xie, W. (2025) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv51701.2025.01851 · Cited by 3
Self-citationCao, W., Zhang, J., Shui, Z., Wang, S., Chen, Z., Li, X., Lü, L., Ye, X., Liang, T., Zhang, Q. H., et al. (2025) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv51701.2025.02139
The Architecture, Capabilities, and Challenges of Vision-Language Models for Healthcare AI
Murali, M. (2026) · Advances in computational intelligence and robotics book series · doi:10.4018/979-8-3373-7315-7.ch006
MedLAMA: Medical lesion-aware multimodal alignment
Xue, Z., Liu, T., Li, X., & Tong, W. (2026) · Neurocomputing · doi:10.1016/j.neucom.2026.134088
Zhao, J., Ding, R., & Liu, M. (2026) · Medical Image Analysis · doi:10.1016/j.media.2026.104143
Qiao, L., Gong, J., Shu, Y., Zhou, L., Xu, X., Li, B., Li, W., & Lei, B. (2026) · IEEE Transactions on Medical Imaging · doi:10.1109/tmi.2026.3700856
Medical Vision-Language Models: Existing Technologies, Clinical Applications and Future Directions
Zou, L., Ma, M., Li, J. B., Chen, H., & Peng, S. (2026) · Sensors · doi:10.3390/s26133998
A unified multi-task framework enables interpretable chest radiograph analysis
Xu, L., Ni, Z., Liu, X., Wang, X., Li, H., & Zhang, S. (2026) · Med · doi:10.1016/j.medj.2026.101223 · Cited by 2
Meng, X., Wang, X., Cai, J., & Ding, L. (2026) · Lecture notes in computer science · doi:10.1007/978-981-92-3394-6_47
Jang, W., Jo, G. Y., Lee, S. Y., Yoon, S. J., Lee, G. Y., Lee, H.-E., Kim, T. H., Baek, J. W., & Kim, J. H. (2026) · Bioengineering · doi:10.3390/bioengineering13080912
Wang, Y., Yang, J., & Zhang, H. (2026) · Fractal and Fractional · doi:10.3390/fractalfract10090597
Self-citationOccurrence-Aware Prototype Graph Learning for Interpretable Multi-Label Disease Diagnosis
Hayat, M., & Aramvith, S. (2026) · IEEE Access · doi:10.1109/access.2026.3728910
Chen, Y., Chen, X., Hu, J., Tan, M., Wang, Y., Nie, L., & Wang, T. (2026) · Talanta · doi:10.1016/j.talanta.2026.130540
Self-citationKhalid, O., Nadeem, S., Farooq, B., & Saeed, H. (2024) · Journal of Artificial Intelligence for Healthcare Systems · doi:10.68159/s049146327
PhenoLIP: Phenotype Guided Medical Vision–Language Pretraining
Liang, C., Wu, C., Zhao, W., Zhang, Y., Wang, Y., & Xie, W. (2026) · Lecture notes in computer science · doi:10.1007/978-3-032-37592-6_7
Self-citationMPDRL: difficulty-aware representation learning with medical priors for vision–language pre-training
Liu, J., Tan, Z., Chen, W., & Liu, X. (2026) · Frontiers in Artificial Intelligence · doi:10.3389/frai.2026.1906686
Yürük, M. A., & Memiş, A. (2026) · World Congress on Medical Physics and Biomedical Engineering, September 7 - 12, 2009, Munich, Germany · doi:10.1007/978-3-032-37739-5_24
Metadata
- Authors
- Zhang, X., Wu, C., Zhang, Y., Xie, W., & Wang, Y.
- Affiliations
- Shanghai Jiao Tong University (CN)
- Corresponding author
- Xie, Weidi
- Wang, Yanfeng
- Venue
- Nature Communications
- Published
- 2023-07-28
- Volume
- 14
- Issue
- 1
- Pages
- 4542-4542
- ISSN
- 2041-1723 (ISSN-L)
- PMC
- PMC10382552
- OpenAlex
- W4385347692
- Cited by
- 207
- References
- 30
- Citations by year
- 2026: 54 · 2025: 104 · 2024: 47 · 2023: 2
- FWCI
- 18.75
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Locations
- Nature Communications (publishedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- arXiv (Cornell University) (submittedVersion)
- RePEc: Research Papers in Economics (submittedVersion)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion, cc-by-sa)
- arXiv (Cornell University)
- Funders
- Science and Technology Commission of Shanghai Municipality (21DZ1100100, 22511106101, BP0719010, 18DZ2270700)
- Topics
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Multimodal Machine Learning Applications
- Health Sciences › Medicine › Health Informatics › Artificial Intelligence in Healthcare and Education
- Health Sciences › Medicine › Radiology, Nuclear Medicine and Imaging › COVID-19 diagnosis using AI
- Keywords
- vision-language pre-training, chest radiography, radiology reports, medical foundation models, few-shot fine-tuning
- MeSH terms
- Radiologists, Humans, Language, Radiography, Radiology, Knowledge
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
