

The DOI matches its Crossref record; 59 of the 59 references it cites were found in a registry or an index.
Collaboration between clinicians and vision–language models in radiology report generation
Open accessPublished version of a preprint
Abstract
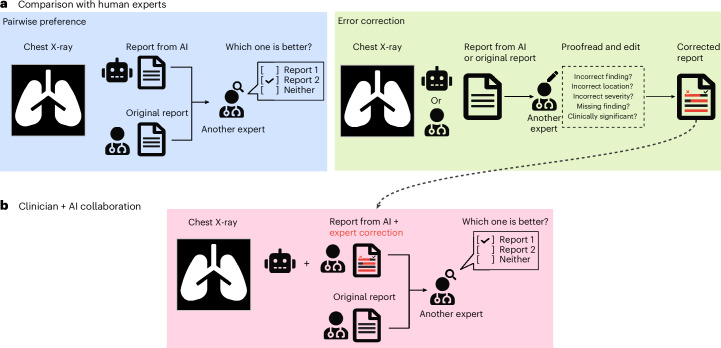
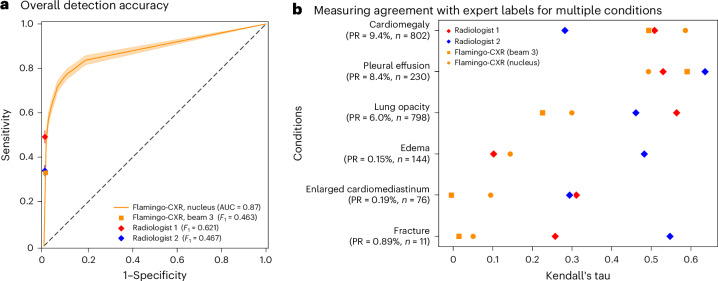
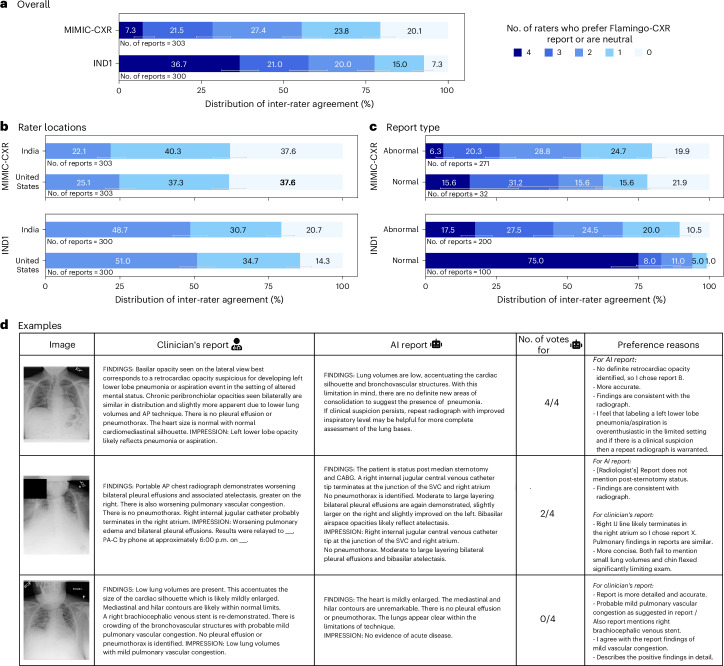
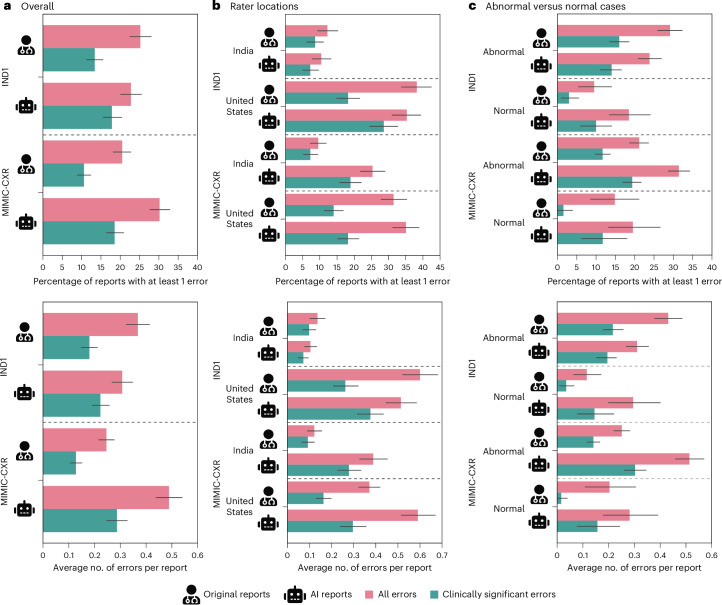
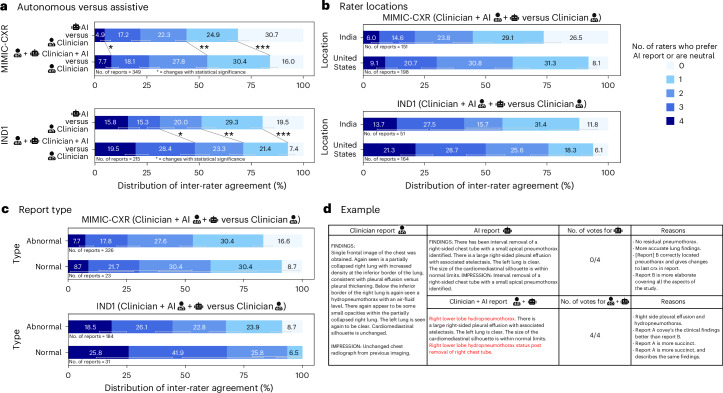
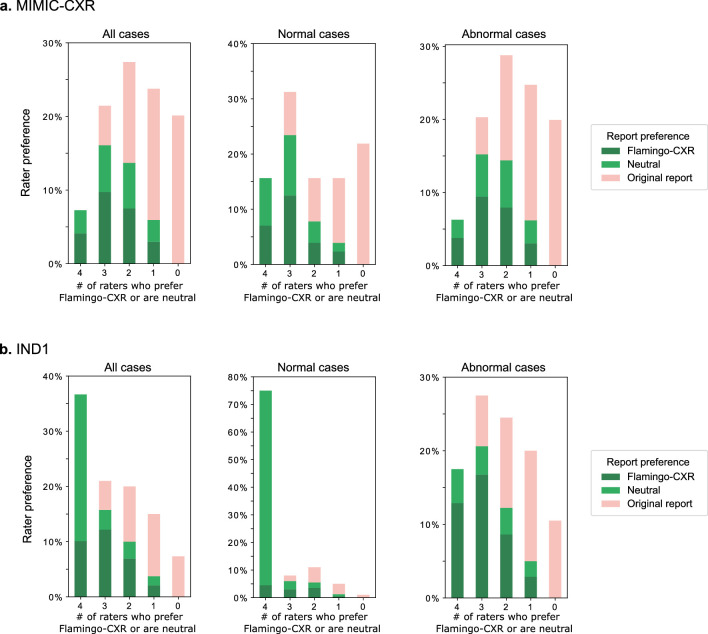
Abstract Radiology reports are an instrumental part of modern medicine, informing key clinical decisions such as diagnosis and treatment. The worldwide shortage of radiologists, however, restricts access to expert care and imposes heavy workloads, contributing to avoidable errors in report delivery. While recent progress in automated report generation with vision-language models offers clear potential to ameliorate this situation, the path toward real-world adoption has been stymied by the challenge of evaluating the clinical quality of AI-generated reports. In this study, we build a state-of-the-art report generation system for chest radiographs, Flamingo-CXR, by fine-tuning a well-known vision-language foundation model on radiology data. To measure the quality of the AI-generated reports, we perform an expert evaluation, that is largest in scale and diversity to date, by engaging a group of 27 certified radiologists in the United States and India to provide detailed assessment of AI-generated and human written reports from an intensive care setting as well as an inpatient setting. We observe a wide distribution of preferences across the panel, ranging from full consensus to dissensus, across clinical settings and regions, with 55.4% of Flamingo-CXR intensive care reports evaluated to be preferable or equivalent to clinician reports, by half or more of the panel, rising to 77.7% for outpatient x-rays overall and to 94% for the subset of cases with no pertinent abnormal findings. For reports that contain errors we develop an assistive setting, the first demonstration of clinician-AI collaboration for radiology report composition, and we observe a synergistic improvement across all clinical settings. Altogether, these nuanced evaluations reveal disparities between the AI system and radiologists, identify areas for potential clinical utility and pave the way toward a collaborative system that enhances clinical accuracy of radiology reporting.
Overview
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
“However, while small language models have shown success in text domains14–16, small multimodal models (SMMs) still have significant performance gaps compared to larger models6,10.”
From A clinically accessible small multimodal radiology model and evaluation metric for chest X-ray findings (2025) · cites this paper as [10]
Citations
Cites
BLEU: a method for automatic evaluation of machine translation
Papineni, K., Roukos, S., Ward, T., & Zhu, W.-J. (2001) · Proceedings of the 40th Annual Meeting on Association for Computational Linguistics - ACL '02 · doi:10.3115/1073083.1073135 · Cited by 21,344
(2004) · Cited by 9,718
2017 IEEE Conference on Computer Vision and Pattern Recognition (CVPR)
(2017) · doi:10.1109/cvpr35066.2017 · Cited by 7,284
Multimodal Machine Learning: A Survey and Taxonomy
Baltrusaitis, T., Ahuja, C., & Morency, L.-P. (2019) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2018.2798607 · Cited by 5,018
CIDEr: Consensus-based image description evaluation
Vedantam, R., Zitnick, C. L., & Parikh, D. (2015) · 2015 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2015.7299087 · Cited by 4,845
A generalization of sampling without replacement from a finite universe
Horvitz, D. G., & Thompson, D. J. (1952) · Journal of the American Statistical Association · doi:10.1080/01621459.1952.10483446 · Cited by 4,293
Large language models encode clinical knowledge
Singhal, K., Azizi, S., Tu, T., Mahdavi, S. S., Wei, J., Chung, H. W., Scales, N., Tanwani, A., Cole-Lewis, H., Pfohl, S., et al. (2023) · Nature · doi:10.1038/s41586-023-06291-2 · Cited by 4,083
Self-citationLarge Language Models Encode Clinical Knowledge
Singhal, K., Azizi, S., Tu, T., Mahdavi, S. S., Wei, J., Chung, H. W., Scales, N., Tanwani, A., Cole-Lewis, H., Pfohl, S., et al. (2022) · arXiv · doi:10.48550/arxiv.2212.13138 · Cited by 4,083
Self-citationMIMIC-CXR, a de-identified publicly available database of chest radiographs with free-text reports
Johnson, A. E. W., Pollard, T. J., Berkowitz, S. J., Greenbaum, N. R., Lungren, M. P., Deng, C.-Y., Mark, R. G., & Horng, S. (2019) · Scientific Data · doi:10.1038/s41597-019-0322-0 · Cited by 1,816
Toward expert-level medical question answering with large language models
Singhal, K., Tu, T., Gottweis, J., Sayres, R., Wulczyn, E., Amin, M., Hou, L., Clark, K., Pfohl, S. R., Cole-Lewis, H., et al. (2025) · Nature Medicine · doi:10.1038/s41591-024-03423-7 · Cited by 1,734
Self-citation
Research works printed but not linked: 5
- Endo, M. et al. Retrieval-based chest X-ray report generation using a pre-trained contrastive language-image model. Proc. Mach. Learn. Res. 158, 209–219 (2021).
- Chen, Z. et al. CheXagent: towards a foundation model for chest X-ray interpretation. In AAAI 2024 Spring Symposium on Clinical Foundation Models (AAAI, 2024).
- Loshchilov, I. & Hutter, F. Fixing weight decay regularization in Adam. Preprint at https://arxiv.org/abs/1711.05101v2 (2018). · arXiv
- Holtzman, A., Buys, J., Du, L., Forbes, M. & Choi, Y. The curious case of neural text degeneration. Preprint at https://arxiv.org/abs/1904.09751 (2019). · arXiv
- Lin, C.-Y. in Text Summarization Branches Out 74–81 (Association for Computational Linguistics, 2004).
Cited by
Sorted by citations
Next-generation agentic AI for transforming healthcare
Karunanayake, N. (2025) · Informatics and Health · doi:10.1016/j.infoh.2025.03.001 · Cited by 165
Multimodal generative AI for medical image interpretation
Rao, V. M., Hla, M., Moor, M., Adithan, S., Kwak, S., Topol, E. J., & Rajpurkar, P. (2025) · Nature · doi:10.1038/s41586-025-08675-y · Cited by 134
A comprehensive survey of large language models and multimodal large language models in medicine
Xiao, H., Zhou, F., Liu, X., Liu, T., Ли, Ж., Liu, X., & Huang, X. (2024) · Information Fusion · doi:10.1016/j.inffus.2024.102888 · Cited by 154
Multimodal Large Language Models in Medical Imaging: Current State and Future Directions
Nam, Y., Kim, D., Kyung, S., Seo, J., Song, J. M., Kwon, J., Kim, J., Jo, W., Park, H. J., Sung, J., et al. (2025) · Korean Journal of Radiology · doi:10.3348/kjr.2025.0599 · Cited by 106
An eyecare foundation model for clinical assistance: a randomized controlled trial
Wu, Y.-L., Qian, B., Li, T., Qin, Y., Guan, Z., Chen, T., Jia, Y., Zhang, P., Zeng, D., Moroi, S. E., et al. (2025) · Nature Medicine · doi:10.1038/s41591-025-03900-7 · Cited by 67
Metadata
- Authors
- Tanno, R., Barrett, D. G. T., Sellergren, A., Ghaisas, S., Dathathri, S., See, A., Welbl, J., Lau, C., Tu, T., Azizi, S., Singhal, K., Schaekermann, M., May, R., Lee, R., Man, S., Mahdavi, S., Ahmed, Z., Matias, Y., Barral, J., Eslami, S. M. A., Belgrave, D., Liu, Y., Kalidindi, S. R., Shetty, S., Natarajan, V., Kohli, P., Huang, P.-S., Karthikesalingam, A., & Ktena, I.
- Affiliations
- Google DeepMind (United Kingdom) (GB)
- Google (United Kingdom) (GB)
- GlaxoSmithKline (United Kingdom) (GB)
- Apollo Hospitals (IN)
- Corresponding author
- Tanno, Ryutaro
- Barrett, David G. T.
- Karthikesalingam, Alan
- ORCID
- Tanno, Ryutaro
- Barrett, David G. T.
- Sellergren, Andrew
- Ghaisas, Sumedh
- Dathathri, Sumanth
- See, Abigail
- Lau, Charles
- Tu, Tao
- Azizi, Shekoofeh
- Singhal, Karan
- Schaekermann, Mike
- Lee, Roy
- Man, SiWai
- Mahdavi, Sara
- Matias, Yossi
- Barral, Joelle
- Eslami, S. M. Ali
- Liu, Yun
- Kalidindi, Sreenivasa Raju
- Shetty, Shravya
- Natarajan, Vivek
- Kohli, Pushmeet
- Huang, Po-Sen
- Karthikesalingam, Alan
- Ktena, Ira
- Venue
- Nature Medicine
- Published
- 2024-11-07
- Volume
- 31
- Issue
- 2
- Pages
- 599-608
- ISSN
- 1078-8956 (ISSN-L)
- 1546-170X
- PMC
- PMC11835717
- OpenAlex
- W4404143589
- Cited by
- 186
- References
- 54
- Citations by year
- 2026: 106 · 2025: 77 · 2024: 2
- FWCI
- 17.30
- Type
- journal article
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- Locations
- Nature Medicine (publishedVersion, cc-by)
- Research Square (acceptedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by-nc-nd)
- PubMed (publishedVersion)
- Funders
- DeepMind
- Topics
- Health Sciences › Medicine › Health Informatics › Artificial Intelligence in Healthcare and Education
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Multimodal Machine Learning Applications
- Health Sciences › Medicine › Radiology, Nuclear Medicine and Imaging › Radiology practices and education
- Keywords
- automated radiology report generation, vision-language models, chest radiograph, clinician-AI collaboration, radiologist workload
- MeSH terms
- Radiologists, Artificial Intelligence, Humans, Radiology, Radiography, Thoracic
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
