

The DOI matches its Crossref record; 21 of the 23 references it cites were found in a registry or an index, and 2 are not checked yet.
Benchmark evaluation of DeepSeek large language models in clinical decision-making
Open accessAbstract
Large language models (LLMs) are increasingly transforming medical applications. However, proprietary models such as GPT-4o face significant barriers to clinical adoption because they cannot be deployed on site within healthcare institutions, making them noncompliant with stringent privacy regulations. Recent advancements in open-source LLMs such as DeepSeek models offer a promising alternative because they allow efficient fine-tuning on local data in hospitals with advanced information technology infrastructure. Here, to demonstrate the clinical utility of DeepSeek-V3 and DeepSeek-R1, we benchmarked their performance on clinical decision support tasks against proprietary LLMs, including GPT-4o and Gemini-2.0 Flash Thinking Experimental. Using 125 patient cases with sufficient statistical power, covering a broad range of frequent and rare diseases, we found that DeepSeek models perform equally well and in some cases better than proprietary LLMs. Our study demonstrates that open-source LLMs can provide a scalable pathway for secure model training enabling real-world medical applications in accordance with data privacy and healthcare regulations.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
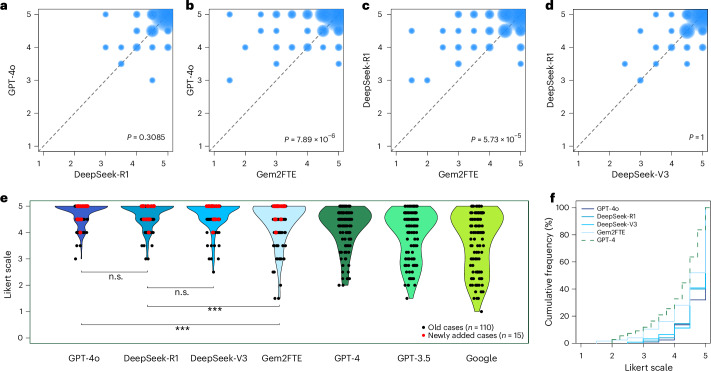
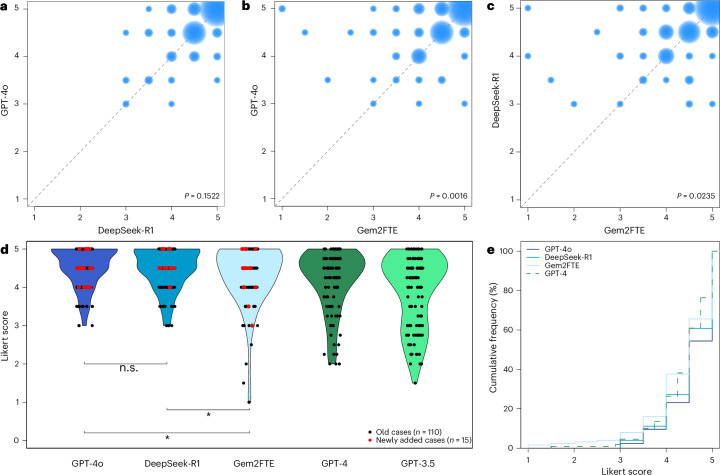
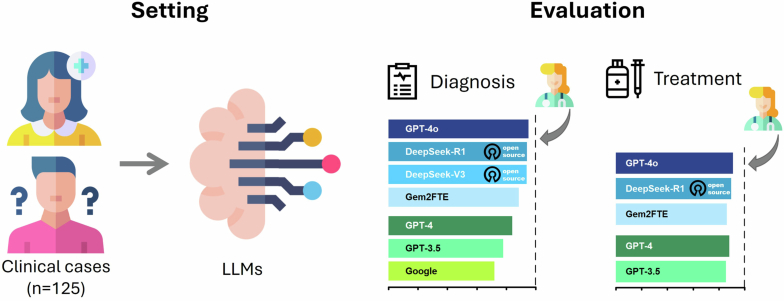
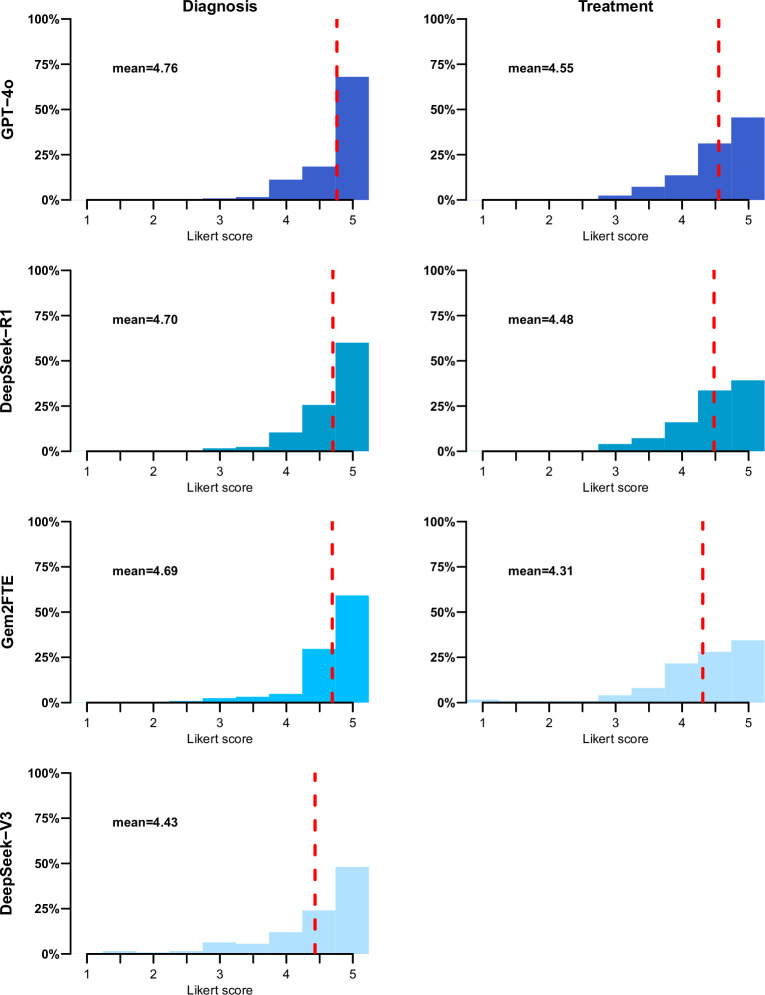
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“However, these frameworks typically focus on narrow clinical scenarios (1–28 datasets), rely on limited data sources or synthetic data, and assess primarily accuracy without comprehensive taxonomy validation or deployment considerations.”
From Holistic evaluation of large language models for medical tasks with MedHELM (2026) · cites this paper as [22]
Experimental — accuracy not yet measured
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
On a Test of Whether one of Two Random Variables is Stochastically Larger than the Other
Mann, H. B., & Whitney, D. R. (1947) · The Annals of Mathematical Statistics · doi:10.1214/aoms/1177730491 · Cited by 14,320
Jin, D., Pan, E., Oufattole, N., Weng, W.-H., Fang, H., & Szolovits, P. (2020) · Applied Sciences · doi:10.48550/arxiv.2009.13081 · Cited by 2,339
Artificial hallucinations in ChatGPT: implications in scientific writing
Alkaissi, H., & McFarlane, S. I. (2023) · Cureus · doi:10.7759/cureus.35179 · Cited by 1,540
Evaluation and mitigation of the limitations of large language models in clinical decision-making
Hager, P., Jungmann, F., Holland, R., Bhagat, K., Hubrecht, I., Knauer, M., Vielhauer, J., Makowski, M., Braren, R., Kaissis, G., et al. (2024) · Nature Medicine · doi:10.1038/s41591-024-03097-1 · Cited by 798
DescTools: Tools for Descriptive Statistics
Signorell, A. (2014) · doi:10.32614/cran.package.desctools · Cited by 723
Jin, D., Pan, E., Oufattole, N., Weng, W.-H., Fang, H., & Szolovits, P. (2021) · Applied Sciences · doi:10.3390/app11146421 · Cited by 718
DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning
DeepSeek-AI, Guo, D., Yang, D., Zhang, H., Song, J., Wang, P., Zhu, Q., Xu, R., Zhang, R., Ma, S., et al. (2025) · arXiv · doi:10.48550/arxiv.2501.12948 · Cited by 538
Medical large language models are vulnerable to data-poisoning attacks
Alber, D. A., Yang, Z., Alyakin, A., Yang, E., Rai, S., Valliani, A. A., Zhang, J., Rosenbaum, G. R., Amend-Thomas, A. K., Kurland, D. B., et al. (2025) · Nature Medicine · doi:10.1038/s41591-024-03445-1 · Cited by 242 · cited 1×
“Concerns regarding data privacy, algorithmic bias and the potential for generating inaccurate or misleading information remain paramount 8–10 .”
Systematic analysis of ChatGPT, Google search and Llama 2 for clinical decision support tasks
Sandmann, S., Riepenhausen, S., Plagwitz, L., & Varghese, J. (2024) · Nature Communications · doi:10.1038/s41467-024-46411-8 · Cited by 228
Self-citationGuidelines for clinical guidelines
Jackson, R., & Feder, G. S. (1998) · BMJ · doi:10.1136/bmj.317.7156.427 · Cited by 206
Research works printed but not linked: 1
- Bonferroni, C. E. Teoria statistica delle classi e calcolo delle probabilita. Pubblicazioni del R. Istituto Super. di Sci. Economiche e Commericiali di Firenze 8, 3–62 (1936).
Cited by
Sorted by citations
Items 101–200 of 231
Applications of DeepSeek in Medicine: Bibliometric Analysis and Scoping Review
Zhang, H., Wang, D., Xu, Y., Han, S., & Wang, G. (2026) · Journal of Medical Internet Research · doi:10.2196/93354 · Cited by 1
Zhang, H., Yan, X., Yang, Y., Jin, L., Yang, P., & Wang, J. (2026) · Journal of Dentistry · doi:10.1016/j.jdent.2026.106853 · Cited by 4
Xie, Y., Liu, J., Zhan, B., et al. (2026) · Journal of Medical Internet Research · doi:10.2196/93890 · Cited by 1
Wu, F., Li, X., Zeng, Y., Tang, Y., Xiao, Z., Yang, S., Wu, K., Liu, S., & Li, A. (2026) · Journal of Medical Internet Research · doi:10.2196/93042 · Cited by 1
Shang, W., Shi, T., Ma, Q., & Kong, G. (2026) · Cell Reports Medicine · doi:10.1016/j.xcrm.2026.102986 · Cited by 1
Wang, X., Tan, R., Wang, B., & Cristea, S. (2025) · bioRxiv (Cold Spring Harbor Laboratory) · doi:10.1101/2025.06.17.659642 · Cited by 2
Balasubramanian, K., O’Connor, D., Gülsuna, B., Srinivasan, V. M., Donoho, D. A., Sader, N., & Graffeo, C. S. (2026) · Journal of Neurological Surgery Reports · doi:10.1055/a-2964-9336
Ma, W., Fong, G., Lai, J., Wu, H., Hue, S. P. Y., Ying, J., The Hong Kong Genome Project, Chu, A. T.-W., & Chung, B. H. Y. (2025) · medRxiv · doi:10.1101/2025.06.03.25328923
The new paradigm for global oncologists in the era of generative AI
Wei, M., Teh, B. S., & Xu, B. (2025) · Intelligent Oncology · doi:10.1016/j.intonc.2025.06.002
Chen, P., Cai, J., Zhou, J., Chen, S., Xu, C., Yuan, L., Dai, X., Chen, X., Wei, Y., Li, X., et al. (2025) · medRxiv · doi:10.1101/2025.06.20.25326623
Mao, Y., Zhang, Y., & Cao, Y. (2025) · The Innovation · doi:10.1016/j.xinn.2025.101009
Automated ICD-O-3 Coding of Real-World Pathology Reports Using Self-Hosted Large Language ModelsPreprint
Arzideh, K., Hosch, R., Turki, A. T., Erilymaz, B., Bahn, M., Schäfer, H., Idrissi-Yaghir, A., Khattab, S., Dada, A., Baba, H. A., et al. (2025) · medRxiv · doi:10.1101/2025.07.23.25332040
Cheng, R., He, S., & Bai, Y. (2025) · International Journal of Surgery · doi:10.1097/js9.0000000000003194
Color-Dp: A Conjugate Low-Rank Optimized Dp Mechanism for Lora Fine-TuningPreprint
Zhang, K., Xu, Y., Lin, W., Tsai, P., Hong, C., & Yuan, X. (2025) · SSRN Electronic Journal · doi:10.2139/ssrn.5390790
DeepSeek-Med-8B: Medical LLM for Chinese Diagnosis and Referral
Li, C., Mao, J., Liu, B., et al. (2025) · International Conference on Computer Information Science and Application Technology (CISAT) · doi:10.1109/cisat66811.2025.11181817
Levita, B., Eminovic, S., Lüdemann, W. M., Schnapauff, D., Schmidt, R., Haack, A.-M., Dell’Orco, A., Nawabi, J., & Penzkofer, T. (2025) · CVIR Endovascular · doi:10.1186/s42155-025-00609-z
Zhang, J., Ma, Y., Zhang, R., Rina, S., & Li, S. (2025) · Research Square · doi:10.21203/rs.3.rs-7713507/v1
Gruenig, A., Kriebel, J., Varghese, J., Herrmann, T., Sandmann, S., & Bruns, C. (2025) · doi:10.2196/preprints.84362
Self-citationTransforming LLMs into Domain Experts: A Case Study of Train Trajectory Evaluation
Yu, Y., Sun, P., Zhao, H., Wang, Q., & Liu, C. (2025) · IEEE International Conference on Intelligent Rail Transportation (ICIRT) · doi:10.1109/icirt66379.2025.11216746
Xu, G., Chen, B., Guo, H., LeBlanc, D., Kusari, A., Yarbasi, E., Ahmed, A., Sun, Z., & Bao, S. (2026) · SAE International Journal of Transportation Safety · doi:10.4271/09-14-01-0033
Shang, L., Chen, Y., Li, R., Zhang, X., Gao, M., Hou, Y., & Zhang, G. K. (2025) · International Journal of Surgery · doi:10.1097/js9.0000000000004062
Manullang, A., Gao, X. W., Viavattene, C., et al. (2025) · Lecture notes in computer science · doi:10.1007/978-3-032-11442-6_39
Maarseveen, T. D., Selani, D., Steinz, N., ten Brinck, R. M., Glas, H. K., Dieren, J. V.-V., Reinders, M. J. T., van den Akker, E. B., & Knevel, R. (2025) · Annals of the Rheumatic Diseases · doi:10.1016/j.ard.2025.11.001 · Cited by 1
Shen, P., Yuan, Y., He, X., & Wang, F. (2025) · Global Medical Education · doi:10.1515/gme-2025-0009
Wu, G., Miao, Y., Fan, S., et al. (2025) · Health care science · doi:10.1002/hcs2.70042
Pathology’s Last Exam: Stress-Testing Diagnostic Reasoning and Safety in Large Language ModelsPreprint
Reitsam, N. G., Gustav, M., Jesinghaus, M., Märkl, B., Foersch, S., & Kather, J. N. (2025) · medRxiv · doi:10.64898/2025.12.11.25342081
江, 予. (2025) · Advances in Education · doi:10.12677/ae.2025.15112125
Pre-consultation Medical Assistant: An LLM-Based Support System for Physicians
Hu, Y., Chen, P., & Shen, Z. (2026) · Lecture notes in computer science · doi:10.1007/978-3-032-13184-3_21
Zhang, X., Shang, L., Hou, S., Li, J., Yang, K., Lai, F., Tian, P., Zheng, Y., Su, G., Xu, T., et al. (2026) · iScience · doi:10.1016/j.isci.2026.114644
沈, 泽. (2026) · Advances in Clinical Medicine · doi:10.12677/acm.2026.161080
Positive sentiments in early academic literature on DeepSeek: a cross-disciplinary mini review
He, Y., Giangan, A., Vu, N., & Watters, C. (2026) · Frontiers in Artificial Intelligence · doi:10.3389/frai.2025.1725853
Lu, Z., Cao, H., Ma, C., et al. (2026) · doi:10.2196/preprints.91016
Gu, S.-Y., Yao, D., Yao, Y., Cen, X., & Yuan, J.-Y. (2026) · BMC Medical Informatics and Decision Making · doi:10.1186/s12911-026-03340-4 · Cited by 1
Yu, Z., Wei, J., Dong, F., Luo, H., Zhang, Z., Fan, J., Ding, H., An, H., Xie, W., & Lu, Y. (2026) · Intelligent Medicine · doi:10.1016/j.imed.2025.12.009
Viculin, I., Vrdoljak, J., Tomić, K., et al. (2026) · doi:10.2196/preprints.91733
Exposing the fragility of LLM reasoning through bias-inducing prompts: evidence from BiasMedQA
Kim, S. H., Ziegelmayer, S., Busch, F., Mertens, C. J., Keicher, M., Adams, L. C., Bressem, K. K., Braren, R., Makowski, M. R., Kirschke, J. S., et al. (2026) · BMJ Digital Health & AI · doi:10.1136/bmjdhai-2025-000189
He, K., Xiao, Q., Chen, W., Jing, L., Wang, Y., Li, S., Yang, D., Xu, H., Pang, K., Xiao, R., et al. (2026) · doi:10.2196/preprints.92852
Ba, Z., He, M., He, H., Fu, Q., Lai, J. Z., Zhang, R., Diao, X., Liu, M., wang, Z., Wang, X., et al. (2026) · medRxiv · doi:10.64898/2026.02.08.26345860
From genomes to precision medicine: 25 years of breakthroughs in genetics and genomics
Hailu, S. G. (2026) · The Nucleus · doi:10.1007/s13237-025-00632-4 · Cited by 1
Xie, Y., Liu, J., Zhan, B., et al. (2026) · doi:10.2196/preprints.93890
Large Language Models in Healthcare: A Meta-Analysis for Clinical Decision-Making
Paikrao, P. D., Bhalke, D. G., Wagh, M., Chougule, S., Chavan, S. S., Deshpande, C., & Sayyad, F. A. (2025) · International Conference on Artificial Intelligence for Computing, Astronomy and Renewable Energy (AICARE) · doi:10.1109/aicare66005.2025.11402661
Zhou, Z. (2026) · Research Square · doi:10.21203/rs.3.rs-9171815/v1
Quantitative Synthesis of Large Language Model Performance in Medical Reasoning Tasks
Paikrao, P. D., Wagh, M., Chavan, S. S., Chougule, S., Wattamwar, R. V., Sayyad, F. A., Bhalke, D. G., & Deshpande, C. (2026) · Biennial International Conference on Nascent Technologies in Engineering (ICNTE) · doi:10.1109/icnte66387.2026.11437404
AI-Assisted Pneumonia Detection, Localisation and Report Generation from Chest X-raysPreprint
Boiardi, F., Lain, A. D., & Posma, J. M. (2026) · medRxiv · doi:10.64898/2026.03.20.26348879
Hany, M., Zidan, M. H. E.-D., Parmar, C. D., Shahmiri, S. S., Altabbaa, H., Shamarka, A. E., Amgad, A., Abdelkhalek, I., Assal, A. A., Abdou, M. E., et al. (2026) · Obesity Surgery · doi:10.1007/s11695-026-08562-z
Guideline Concordance and Safety of AI Chatbots for Circumcision Anesthesia: A Comparative Study
Şahin, A. T., & Yorulmaz, E. M. (2026) · Journal of Contemporary Medicine · doi:10.16899/jcm.1878107
Ibrahim, A. A. A., Htet, H., & Asahi, R. (2026) · Materials & Design · doi:10.1016/j.matdes.2026.115960
Performance of large language models in patient-facing counseling for atrial fibrillation
Cao, J., Wang, R., Zhao, X., et al. (2026) · Asian Journal of Surgery · doi:10.1016/j.asjsur.2026.03.082
Huang, Q., Zhu, W., Mo, H., Huang, B., Liao, Z., Lu, X., & Zhang, H. (2026) · Digital Health · doi:10.1177/20552076261443914
Zhang, Y., Chen, H. Z., Xu, R., Lei, C., Han, D., Li, Y., & Wang, X. (2026) · Scientific Reports · doi:10.1038/s41598-026-44685-0 · Cited by 1
Samaraweera, S., Zhao, L., Echeverría, V., Alfredo, R., Chen, G., Davis, J., Leonny, S., Sevenhuysen, S., Connell, C. J., Gašević, D., et al. (2026) · International Conference on Learning Analytics and Knowledge (LAK) · doi:10.1145/3785022.3785098
Yuan, D., Zhao, X., Wu, Z., et al. (2026) · Visual Neuroscience · doi:10.48130/vns-0026-0016
Xia, P., Wang, Y., Yang, Q., Wang, J., Tong, Y., Zhang, D., Lv, X., Zheng, C., 吳妙音, Li, T., et al. (2026) · Frontiers in Medicine · doi:10.3389/fmed.2026.1758735
He, K., Xiao, Q., Chen, W., Jing, L., Wang, Y., Li, S., Yang, D., Xu, H., Pang, K., Xiao, R., et al. (2026) · Journal of Medical Internet Research · doi:10.2196/92852
Chen, G., Bi, K., Cai, Q., Wang, Z., An, Z., & Fu, W. (2026) · World Journal of Urology · doi:10.1007/s00345-026-06198-3 · Cited by 1
Novelty to necessity: large language models in clinical practice—a call to action for physicians
Beltrani, V., Giannini, O., AbouEzzeddine, O. F., Gruebler, M. R., Mastroleo, F., & Tersalvi, G. (2026) · Internal and Emergency Medicine · doi:10.1007/s11739-026-04393-z
Dynamic Burdens and Dilemmas of Temporary Ileostomy in Rectal Cancer Patients: a qualitative studyPreprint
Ji, H., Zhang, F., & Li, Y. (2026) · Research Square · doi:10.21203/rs.3.rs-9528695/v1
Du, L., Zhong, J., Zheng, S., & Chen, L. (2026) · BMC Medical Informatics and Decision Making · doi:10.1186/s12911-026-03511-3
Zhong, W., Yan, H., Liu, Y., Liu, Y., Yang, K., Gao, H., Yao, Z., Hao, W., Yan, Y., & Yin, C. (2026) · Journal of Medical Internet Research · doi:10.2196/91399
Zhang, Y., Li, R., Shi, H., et al. (2026) · Annals of Surgical Oncology · doi:10.1245/s10434-026-19845-1
Cheng, X., Chen, J., Yang, D., Peng, Y., & Gong, S. (2026) · Digital Health · doi:10.1177/20552076261458159
Sun, Y.-D., Xu, X., Liu, D.-D., Long, Y.-Z., Luo, L., Wu, M.-F., Ou, Y., Zhang, Y.-B., & Cui, Y. (2026) · Aesthetic Plastic Surgery · doi:10.1007/s00266-026-05935-8
Fei, F., 叶璐, Rao, J., Liang, Z., Yang, J., Zou, Y., & Jiang, L. (2026) · Frontiers in Cell and Developmental Biology · doi:10.3389/fcell.2026.1871740 · Cited by 1
Rifat, F. Y., Tabashum, T., Krzak, J. J., Kruger, K. M., Graf, A., Chafetz, R. S., Davids, J. R., Bagley, A. M., Sienko, S. E., Bauer, J., et al. (2026) · doi:10.2196/preprints.103165
Lu, Z., Cao, H., Ma, C., et al. (2026) · JMIR Medical Informatics · doi:10.2196/91016
Development and Deployment of DeepSeek‐Based Applications in Healthcare: A Chinese Perspective
Lv, M., Li, N., Zhang, H., Liu, C., Wu, G., Zhu, Z. G., Zhu, Y., & Gong, M. (2026) · Health care science · doi:10.1002/hcs2.70068
Benchmark evaluation of multi-modal large language models for ophthalmic diagnosis in real world
Huang, S., Chen, J., Wang, J., Zhang, P., Du, W., Yuan, H., Kong, D., Lou, W., Lai, M., & Yang, W. (2026) · Frontiers in Medicine · doi:10.3389/fmed.2026.1842016
Large reasoning models as thinking machines for medicine
Zhou, H.-Y., Rodman, A. M., Liu, P., Rajpurkar, P., Hu, Y., Wong, T. Y., & Topol, E. J. (2026) · Nature Biomedical Engineering · doi:10.1038/s41551-026-01701-y
Latent Confidence Alignment for LLM Self-Assessment
Chen, T. X., Yu, T., Huang, P.-C., Hsu, C., Lin, M.-Y., & Kang, Y. (2026) · IEEE International Conference on Information Reuse and Integration (IRI) · doi:10.1109/iri69576.2026.00024
Zhou, Y., Xiong, W., Liu, H., et al. (2026) · Frontiers in Medicine · doi:10.3389/fmed.2026.1875770
AI-CURA, an automated LLM workflow for high-accuracy genetic variant classification
Ma, W., Fong, G., Lai, J., Wu, H., Hue, S. P. Y., Ying, D., Chen, L., Tang, W., Preusch, C. B., Chu, A. T. W., et al. (2026) · Science Translational Medicine · doi:10.1126/scitranslmed.adz4172 · Cited by 1
Si, Y., Gong, S., Thielscher, M., Bateman, H., Li, B., Chen, S., Wang, D., An, R., Meng, Y., Zhang, H., et al. (2026) · Research Square · doi:10.21203/rs.3.rs-9988886/v1
Zhu, Z., Zhao, Y., Li, L., Wang, X., Zhang, Y., & Zhao, X. (2026) · Health care science · doi:10.1002/hcs2.70085
Fan, L., & Li, Z. (2026) · SAGE Open · doi:10.1177/21582440261420472
Chen, S. H., Wu, X., Ma, Y., Zhang, Y., Zhang, H., & Bian, X. (2026) · Frontiers in Psychology · doi:10.3389/fpsyg.2026.1875736
LAMDA: Large Language Model as Decision Analyst
Hong, Y., Qin, S., & Wang, C. (2026) · Decision Analysis · doi:10.1287/deca.2025.0438
Zhang, P., Nie, X., Mao, H., Zhang, Y., Wang, J., Wang, L., Qin, R., Yang, X., Huang, W., Gao, X., et al. (2026) · Journal of Nanobiotechnology · doi:10.1186/s12951-026-04804-5
Mohammad, M. (2026) · International Conference on Bio-engineering for Smart Technologies (BioSMART) · doi:10.1109/biosmart71257.2026.11598485
Kalinich, M., Luccarelli, J., Maria, J. P. S., Flathers, M., Nguyen, A., Song, S. H., Makhoul, K. G., Criado, M. J. R., Ginapp, C. M., Hill, B., et al. (2026) · medRxiv · doi:10.64898/2026.07.10.26357132
Hussein, M. A., Doshi, R., He, L., & Reynolds, T. L. (2026) · medRxiv · doi:10.64898/2026.07.15.26355314
Accuracy and stability of DeepSeek-R1 and GPT-4o on pediatric questions
Hu, Q., Lei, L., Wang, X., Liu, F. L., & Che, G. (2026) · Digital Health · doi:10.1177/20552076261456893
Shen, J., Yuan, Y., Han, S., et al. (2026) · doi:10.2196/preprints.107462
Li, T., Ma, Z., Wang, B., Fan, N., Wang, A., & Zang, L. (2026) · Journal of Medical Internet Research · doi:10.2196/92931
Performance of DeepSeek V3 and ChatGPT-4o in answering esophageal cancer-related questions
Yang, Q., Yi, J., Gong, A., Li, Y., Feng, Q., Fu, A., Li, J., & Zhan, Y. (2026) · Medicine · doi:10.1097/md.0000000000049896
Wu, Y., Li, H., Su, A., et al. (2026) · JMIR Medical Informatics · doi:10.2196/80580
郑, 立., Lin, Z., Liu, X., Fan, Z., He, Z., Xu, J., & Yin, L. (2026) · Journal of Medical Internet Research · doi:10.2196/98026
Fu, E., Qin, H., Tian, Z., Dong, H., Donghua, Z., Yu, X., & Liu, N. (2026) · Frontiers in Artificial Intelligence · doi:10.3389/frai.2026.1752043
España-Lopera, J. C., Núñez‐Valdéz, E. R., & García-Díaz, V. (2026) · International Conference on Federated Learning and Intelligent Computing Systems (FLICS) · doi:10.1109/flics70075.2026.11621915
Czok, K. H., Schmidt, D. M., Chen, B. P.-H., Kuk, D., Feldman, J., & Cimiano, P. (2026) · JMIR AI · doi:10.2196/92716
Large language models enable consensus-level interpretation in metagenomic diagnosticsPreprint
Steinig, E. J., Krysiak, M., Deo, K., Duncan, A., Prestedge, J., Barr, J. J., Moselen, J. M., Khan, S. F., Fernando, J. A., Savic, I., et al. (2026) · medRxiv · doi:10.64898/2026.07.29.26358751 · Cited by 1
Wu, Z., Tan, Y., Chen, Q., Ye, X., Zhang, Q., Bi, J., & Li, H. (2026) · Anesthesiology and Perioperative Science · doi:10.1007/s44254-026-00176-z
Chen, Z., Jiao, W.-C., Tsang, Y. P., Wu, C. H., & Wang, X.-J. (2026) · Group Decision and Negotiation · doi:10.1007/s10726-026-10017-w
Wu, Z., Xu, H., Feng, F., Zhang, S., Cheng, R., Shi, T., Zhang, S., & Li, Y. (2026) · Journal of Medical Internet Research · doi:10.2196/96587
Zhang, M., Wang, B., Li, R., et al. (2026) · Frontiers in Oncology · doi:10.3389/fonc.2026.1904488
SmartMM: A Domain-Specific Large Language Model for Medical Microbiology
Gong, Y., Ma, R., Wang, X., Li, R., Dong, H., Liu, Y., Peng, X., GUO, Q., & Liu, Y. (2026) · AI · doi:10.3390/ai7080316
Gao, J., Dong, L., & Hu, J. (2026) · doi:10.2196/preprints.109941
Wang, X., Li, K.-L., Hou, S.-M., et al. (2026) · doi:10.1145/3820664.3820708
Zhou, J., Wei, Y., Cai, Q., Chen, B., Edzeafene-Mensah, E., Yang, Y., & Pan, Z. (2026) · Journal of Medical Internet Research · doi:10.2196/94689
Alzoubi, Y. I., & Mishra, A. (2026) · Journal of Responsible Technology · doi:10.1016/j.jrt.2026.100187
Metadata
- Authors
- Sandmann, S., Hegselmann, S., Fujarski, M., Bickmann, L., Wild, B., Eils, R., & Varghese, J.
- Affiliations
- University of Münster (DE)
- Berlin Institute of Health at Charité - Universitätsmedizin Berlin (DE)
- Shanghai Medical College of Fudan University (CN)
- Otto-von-Guericke-Universität Magdeburg (DE)
- Corresponding author
- Eils, Roland
- Venue
- Nature Medicine
- Published
- 2025-04-23
- Volume
- 31
- Issue
- 8
- Pages
- 2546-2549
- ISSN
- 1078-8956 (ISSN-L)
- 1546-170X
- PMC
- PMC12353792
- OpenAlex
- W4409695426
- Cited by
- 233
- References
- 20
- Citations by year
- 2026: 171 · 2025: 62
- FWCI
- 55.69
- Type
- journal article
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- Locations
- Nature Medicine (publishedVersion, cc-by-nc-nd)
- PubMed Central (publishedVersion, cc-by-nc-nd)
- PubMed (publishedVersion)
- Funders
- Deutsche Forschungsgemeinschaft (SFB 1470)
- National Natural Science Foundation of China (W2441025)
- Bundesministerium für Bildung und Forschung (01KX2121)
- Topics
- Health Sciences › Medicine › Health Informatics › Artificial Intelligence in Healthcare and Education
- Physical Sciences › Computer Science › Artificial Intelligence › Machine Learning in Healthcare
- Health Sciences › Health Professions › Health Information Management › Artificial Intelligence in Healthcare
- Keywords
- DeepSeek, open-source large language models, clinical decision support, benchmarking, GPT-4o, Gemini, DeepSeek-V3, DeepSeek-R1, data privacy, rare diseases, clinical adoption
- MeSH terms
- Clinical Decision-Making, Large Language Models, Humans, Benchmarking, Decision Support Systems, Clinical
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
