

The DOI matches its Crossref record; 14 of the 14 references it cites were found in a registry or an index.
Implementing large language models in healthcare while balancing control, collaboration, costs and security
Open accessAbstract
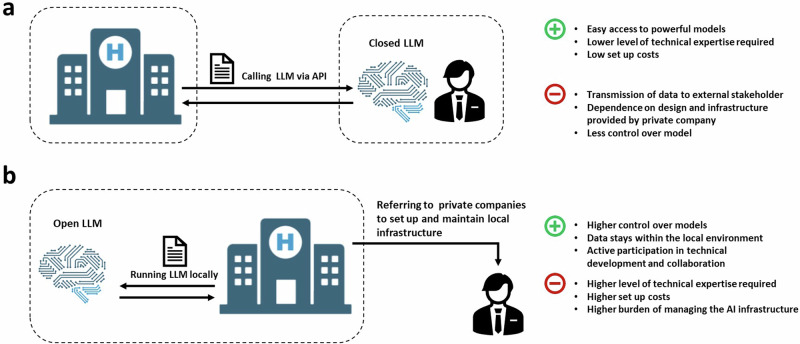
Integrating Large Language Models (LLMs) into healthcare promises substantial advancements but requires careful consideration of technical, ethical, and regulatory challenges. Closed LLMs of private companies offer ease of deployment but pose risks related to data privacy and vendor dependence. Open LLMs deployed on local hardware enable greater model customization but demand resources and technical expertise. Balancing these approaches, with collaboration among clinicians, researchers, and companies is crucial to ensure effective, secure, and ethical implementation.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Deploying large language models (LLMs) in clinical settings is limited by security, reliability, latency, and accessibility concerns that favor smaller, on-device or on-premise models.”
From The economics of accuracy for medical reasoning with large language models (2026) · cites this paper as [3]
Experimental — accuracy not yet measured
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
The future landscape of large language models in medicine
Clusmann, J., Kolbinger, F. R., Muti, H. S., Carrero, Z. I., Eckardt, J.-N., Laleh, N. G., Löffler, C. M. L., Schwarzkopf, S.-C., Unger, M., Veldhuizen, G. P., et al. (2023) · Communications Medicine · doi:10.1038/s43856-023-00370-1 · Cited by 1,045
Using ChatGPT to write patient clinic letters
Ali, S. R., Dobbs, T. D., Hutchings, H. A., & Whitaker, I. S. (2023) · The Lancet Digital Health · doi:10.1016/s2589-7500(23)00048-1 · Cited by 375
Leveraging large language models for decision support in personalized oncology
Benary, M., Wang, X. D., Schmidt, M., Soll, D., Hilfenhaus, G., Nassir, M., Sigler, C., Knödler, M., Keller, U., Beule, D., et al. (2023) · JAMA Network Open · doi:10.1001/jamanetworkopen.2023.43689 · Cited by 306
A critical assessment of using ChatGPT for extracting structured data from clinical notes
Huang, J., Yang, D. M., Rong, R., Nezafati, K., Treager, C., Chi, Z., Wang, S., Cheng, X., Guo, Y., Klesse, L. J., et al. (2024) · npj Digital Medicine · doi:10.1038/s41746-024-01079-8 · Cited by 298
The Role of Large Language Models in Medical Education: Applications and Implications
Safranek, C. W., Sidamon-Eristoff, A. E., Gilson, A., & Chartash, D. (2023) · JMIR Medical Education · doi:10.2196/50945 · Cited by 233
Embracing Large Language Models for Medical Applications: Opportunities and Challenges
Karabacak, M., & Margetis, K. D. (2023) · Cureus · doi:10.7759/cureus.39305 · Cited by 217
Dennstädt, F., Zink, J., Putora, P. M., Hastings, J., & Čihorić, N. (2024) · Systematic Reviews · doi:10.1186/s13643-024-02575-4 · Cited by 191
Self-citationA systematic analysis of failures in protecting personal health data: A scoping review
Pool, J., Akhlaghpour, S., Fatehi, F., & Burton‐Jones, A. (2023) · International Journal of Information Management · doi:10.1016/j.ijinfomgt.2023.102719 · Cited by 181
Hallucinations in Large Multilingual Translation Models
Guerreiro, N. M., Alves, D. M., Waldendorf, J., Haddow, B., Birch, A., Colombo, P., & Martins, A. F. T. (2023) · Transactions of the Association for Computational Linguistics · doi:10.1162/tacl_a_00615 · Cited by 124
Unmasking and quantifying racial bias of large language models in medical report generation
Yang, Y., Liu, X., Jin, Q., Huang, F., & Lu, Z. (2024) · Communications Medicine · doi:10.1038/s43856-024-00601-z · Cited by 105
Research works printed but not linked: 1
- The HIPAA Journal: Managed care of North America hacking incident impacts 8.9 million individuals. http://www.hipaajournal.com/managed-care-of-north-america-hacking-incident-impacts-8-9-million-individuals/.
Cited by
Sorted by citations
The use of large language models in clinical documentation: A scoping review
Woo, B., Cato, K., Cho, H., You, S. B., & Song, J. (2025) · International Journal of Nursing Studies · doi:10.1016/j.ijnurstu.2025.105322 · Cited by 37
An LLM chatbot to facilitate primary-to-specialist care transitions: a randomized controlled trial
Tao, X., Zhou, S., Ding, K., Li, S., Li, Y., Wu, B., Huang, Q., Chen, W., Shen, M., Meng, E., et al. (2026) · Nature Medicine · doi:10.1038/s41591-025-04176-7 · Cited by 40
Pan, G., Chodnekar, V., Roy, A., & Wang, H. (2025) · IEEE International Conference on Big Data (BigData) · doi:10.1109/bigdata66926.2025.11400957 · Cited by 30
Clinical applications of large language models in medicine and surgery: A scoping review
Liang, E. N., Pei, S., Staibano, P., & van der Woerd, B. D. (2025) · Journal of International Medical Research · doi:10.1177/03000605251347556 · Cited by 28
Prompt Engineering for Large Language Models in Interventional Radiology
Dietrich, N. T., Bradbury, N., & Loh, C. (2025) · American Journal of Roentgenology · doi:10.2214/ajr.25.32956 · Cited by 26
Shean, R. S., Shah, T., Pandiarajan, A., Tang, A. C., Bolo, K. A., Nguyen, V., & Xu, B. Y. (2025) · Scientific Reports · doi:10.1038/s41598-025-08601-2 · Cited by 22
Awasthi, R., Bhattad, A., Ramachandran, S. P., Mishra, S. V., Khanna, A. K., Cywiński, J. B., Maheshwari, K. K., Mahapatra, D., DiRosa, I., Cohen, A., et al. (2025) · npj Health Systems · doi:10.1038/s44401-025-00043-2 · Cited by 20
Benchmarking vision-language models for diagnostics in emergency and critical care settings
Kurz, C., Merzhevich, T., Eskofier, B. M., Kather, J. N., & Gmeiner, B. (2025) · npj Digital Medicine · doi:10.1038/s41746-025-01837-2 · Cited by 16
Lee, C., Kumar, S., Vogt, K. A., Munshi, M., Tallapudi, P., Vogt, A., Awad, H., & Khan, W. S. (2025) · Scientific Reports · doi:10.1038/s41598-025-10451-x · Cited by 13
Language models for drug–drug interactions: current applications, pitfalls, and future directions
Meslamani, A. Z. A., & Hajal, A. A. (2025) · Expert Opinion on Drug Metabolism & Toxicology · doi:10.1080/17425255.2025.2551724 · Cited by 13
Tzanis, E., & Klontzas, M. E. (2025) · European Journal of Radiology Artificial Intelligence · doi:10.1016/j.ejrai.2025.100044 · Cited by 17
Dennstädt, F., Windisch, P. Y., Filchenko, I., Zink, J., Putora, P. M., Shaheen, A., Gaio, R., Čihorić, N., Wosny, M., Aeppli, S., et al. (2025) · Oncology · doi:10.1159/000546946 · Cited by 11
Self-citationA community-codesigned LLM-powered chatbot for primary care: a randomized controlled trial
Li, S., Li, Y., Zhou, S., Tao, X., Yu, C., Shen, M., Chen, W., Meng, E., Wu, B., Huang, Q., et al. (2026) · Nature Health · doi:10.1038/s44360-025-00021-w · Cited by 12
Socio-Demographic Modifiers Shape Large Language Models’ Ethical Decisions
Sorin, V., Korfiatis, P. D., Collins, J. D., Apakama, D. U., Omar, M., Glicksberg, B. S., Yeow, M.-E., Brandeland, M. A., Nadkarni, G. N., & Klang, E. (2025) · Journal of Healthcare Informatics Research · doi:10.1007/s41666-025-00211-x · Cited by 11
Sirago, G., Calò, F., Vinci, A., Visci, P., Solarino, B., Dell'Erba, A. S., & Ferorelli, D. (2026) · Journal of Medical Systems · doi:10.1007/s10916-026-02363-8 · Cited by 9
MedReadCtrl: Personalizing medical text generation with readability-controlled instruction learningPreprint
Tran, H., Yao, Z., Jang, W. S., Sultana, S., Chang, A., Zhang, Y., & Hong, Y. (2025) · medRxiv · doi:10.1101/2025.07.09.25331239 · Cited by 12
Papageorgiou, P. S., Christodoulou, R. C., Pitsillos, R., Petrou, V., Vamvouras, G., Kormentza, E. V., Papagelopoulos, P. J., & Georgiou, M. F. (2025) · Applied Sciences · doi:10.3390/app15169005 · Cited by 8
Dennstädt, F., Lerch, L., Schmerder, M., Čihorić, N., Cereghetti, G. M., Gaio, R., Bonél, H., Filchenko, I., Hastings, J., Dammann, F., et al. (2025) · JAMIA Open · doi:10.1093/jamiaopen/ooaf128 · Cited by 7
Self-citationGertz, R. J., Beste, N. C., Dratsch, T., Lennartz, S., Bremm, J., Iuga, A.-I., Bunck, A. C., Laukamp, K. R., Schönfeld, M. H., & Kottlors, J. (2025) · European Radiology · doi:10.1007/s00330-025-11929-y · Cited by 5
Dennstädt, F., Fauser, S., Čihorić, N., Schmerder, M., Lombardo, P., Cereghetti, G. M., von Däniken, S. U., Minder, T., Meyer, J., Chiang, L., et al. (2025) · Journal of Imaging Informatics in Medicine · doi:10.1007/s10278-025-01659-4 · Cited by 5
Self-citationSchönfelder, A., Eberlein-Gonska, M., Hülsken-Giesler, M., Jovy-Klein, F., Kather, J. N., Kohoutek, E., Lennefer, T., Liebert, E., Lipprandt, M., Mathias, R., et al. (2025) · Journal of Medical Internet Research · doi:10.2196/80754 · Cited by 5
Blašković, L., Tanković, N., Lorencin, I., & Šegota, S. B. (2025) · Big Data and Cognitive Computing · doi:10.3390/bdcc9100256 · Cited by 4
Yigamawano, F. K., Odom-Mabey, A. R., Xue, C., Pandey, H. K., & Kolachalama, V. B. (2025) · The Journal of Prevention of Alzheimer s Disease · doi:10.1016/j.tjpad.2025.100396 · Cited by 4
Artificial intelligence-based tools for optimizing surgical research publications
Coronel, B. V., Marescaux, J., & Giménez, M. (2026) · Artificial Intelligence Surgery · doi:10.20517/ais.2025.112 · Cited by 4
Giacobbe, D. R., Ahmad, R., Akıllı, F. M., Ascandari, A., Eyre, D. W., Gallardo‐Pizarro, A., García‐Vidal, C., Lopes, B. S., Lyutsova, E., Rakhimov, R., et al. (2026) · Expert Review of Anti-infective Therapy · doi:10.1080/14787210.2026.2625382 · Cited by 4
Ju, Y.-J., Wang, Y., Lee, S., Liu, C., Lee, M., Hou, C.-Y., Yang, C., & Hsieh, C. (2025) · Medical Teacher · doi:10.1080/0142159x.2025.2532783 · Cited by 3
Zhu, S., Xie, Y., Tang, Y., Zhou, Y., Zhao, R., & Dong, X. (2025) · European Journal of Pediatrics · doi:10.1007/s00431-025-06602-x · Cited by 4
The EU AI Act: implications and compliance guidance for healthcare facilities
Dennstädt, F., Hastings, J., Windisch, P., Jovanovic, A., Marić, T. Ž., Brüningk, S. C., Aebersold, D. M., Knopf, A. C., & Cihoric, N. (2026) · Frontiers in Digital Health · doi:10.3389/fdgth.2026.1808373 · Cited by 5
Self-citationAI agents in clinical practice: an evidence map
Xu, J., Ko, J., & Kvedar, J. C. (2026) · npj Digital Medicine · doi:10.1038/s41746-026-02960-4 · Cited by 3
Leveraging large language models for rare disease named entity recognition
Xi, N. M., Deng, Y., & WANG, L. (2026) · PLOS Digital Health · doi:10.1371/journal.pdig.0001242 · Cited by 3
Steinbuch, S., de Vos‐Hillebrand, L., O'Neill-Dee, C., Wu, I., Steinbuch, H., Kulcsár, Z., Ranjan, A., Verma, A., Landsberg, J., Dietrich, D., et al. (2026) · medRxiv · doi:10.64898/2026.01.23.26344723 · Cited by 3
Chan, J., Hastings, J., Tiernan, G., Paterson, J., Lovell, N. H., Betbeder-Matibet, L., Tung, P. K. M., Pink, S., Lanzeni, D., Donovan, T., et al. (2025) · F1000Research · doi:10.12688/f1000research.169999.1 · Cited by 2
Self-citationBridging guidelines and large language models: a case for retrieval-augmented generation
Alexandrou, M., Mahtani, A. U., & Brilakis, E. S. (2025) · European Heart Journal · doi:10.1093/eurheartj/ehaf546 · Cited by 2
Shickel, B., Ozrazgat‐Baslanti, T., & Bihorac, A. (2025) · Current Opinion in Nephrology & Hypertension · doi:10.1097/mnh.0000000000001112 · Cited by 3
AI-Powered Automation in Healthcare: A Multi-agent Approach with LLM
de Almeida, M. P., Machado, J. M., Sousa, R., & Peixoto, H. (2025) · Communications in computer and information science · doi:10.1007/978-3-032-05925-3_11 · Cited by 2
Jiang, W., Wang, D., Zeng, Y., Huang, J., Xu, C., & Liu, C. (2025) · Journal of Medical Internet Research · doi:10.2196/80770 · Cited by 2
Security Framework for Agentic Home AI in Preventive Healthcare: Cyber Threats Worth Noting
Obeng, C. P., Narasinghe, N. M., Striker, R., & Vazquez, E. A. (2025) · Cyber Awareness and Research Symposium (CARS) · doi:10.1109/cars67163.2025.11337832 · Cited by 2
The role of large language models in emergency care: a comprehensive benchmarking study
Naderi, B., Liu, L., Ghandehari, A., Khoshons, D., Taylor, R. A., Bhavsar, N., Balasubramanian, S., Tanouye, R., Creech, N., Davidson, C., et al. (2026) · npj Artificial Intelligence · doi:10.1038/s44387-026-00078-2 · Cited by 3
NimbleLabs: Accelerating Healthcare AI Development Through Agentic AI
Shimgekar, S. R., Goyal, A., Vassef, S., Saha, K., Poellabauer, C., Vautier, X., Zonooz, P., & Kumar, N. (2025) · IEEE International Conference on Big Data (BigData) · doi:10.1109/bigdata66926.2025.11401464 · Cited by 2
Rethinking healthcare data interoperability in the age of large language models
von Arnim, G., Kohler, S., Hegselmann, S., Marschollek, M., Eils, R., & Wild, B. (2026) · Med · doi:10.1016/j.medj.2026.101146 · Cited by 2
Generative Artificial Intelligence and Large Language Models in Clinical Oncology
Yu, Y., Zhao, Z., Wang, Z., Lin, R., Tan, Y., Chen, Y., Li, T., Baptista‐Hon, D. T., Zhang, X., Wu, C., et al. (2026) · MedComm · doi:10.1002/mco2.70833 · Cited by 2
A roadmap for medical large language models: a review of foundations, applications, and challenges
Sha, Y.-Y., Yu, L., Lin, Z.-H., Kaur, A., Lou, Y., Gornale, S. S., Zhang, T., Wong, L. S., Wang, Z., Yan, Y., et al. (2026) · Military Medical Research · doi:10.1016/j.mmr.2026.100050 · Cited by 3
Umer, F., Mr, S., & Rahman, A. J. (2026) · BDJ Open · doi:10.1038/s41405-026-00462-9 · Cited by 2
Qi, X. S., Wang, Y., Yang, X., Ren, L., Liu, W., Benedict, S., Xiao, Y., Xing, L., & Naqa, I. M. E. (2026) · Medical Physics · doi:10.1002/mp.70616 · Cited by 2
Asano, H., Takaya, D., Hatabu, A., Ohishi, M., Fukuzawa, K., Ikeda, K., & Tian, Y. (2026) · Scientific Reports · doi:10.1038/s41598-026-69686-x · Cited by 2
On-premise medical AI agents for reliable clinical decision-making
Zhang, L., Wölflein, G., Ferber, D., Liang, J., Carrero, Z. I., Wu, X., Vibert, J., Clusmann, J., Möhrmann, L., Möhrmann, E. E., et al. (2026) · Nature Medicine · doi:10.1038/s41591-026-04609-x · Cited by 2
A CDE-based data structure for radiotherapeutic decision-making in breast cancer
Dennstädt, F., Schmalfuss, M., Zink, J., Hastings, J., Gaio, R., Schmerder, M., Putora, P. M., & Čihorić, N. (2025) · BMC Medical Informatics and Decision Making · doi:10.1186/s12911-025-03036-1 · Cited by 2
Self-citationAbrantes, J. (2025) · Cureus · doi:10.7759/cureus.84165 · Cited by 2
Real-World Usage Patterns of Large Language Models in HealthcarePreprint
Unell, A., Kashyap, M., Pfeffer, M. A., & Shah, N. H. (2025) · medRxiv · doi:10.1101/2025.05.02.25326781 · Cited by 2
On the robustness of medical term representations in locally deployable language modelsPreprint
Auger, S. D., Graham, N., & Scott, G. (2026) · medRxiv · doi:10.64898/2026.02.24.26346972 · Cited by 2
A framework for automated extraction and validation of experimental arguments in zeolite synthesis
Yu, Z., He, S., & Du, W. (2026) · Computational Materials Science · doi:10.1016/j.commatsci.2026.114495 · Cited by 1
Aroua, R., Kammoun, I., Louati, M. A., Adjeroh, D., & Duan, T. (2026) · Frontiers in Artificial Intelligence · doi:10.3389/frai.2026.1816692 · Cited by 1
Chow, J., & Patlas, M. N. (2026) · Japanese Journal of Radiology · doi:10.1007/s11604-026-02009-2 · Cited by 1
Chong, A., Lim, C. H., Kim, D., Yun, M., Bom, H.-S. H., & Lee, S. H. (2026) · Nuclear Medicine and Molecular Imaging · doi:10.1007/s13139-026-01029-0 · Cited by 1
Artificial intelligence in oncology: empowering clinicians for responsible integration
Colliver, E., Parisini, E., Arefaine, B., Banerji, C. R. S., Verghese, G. E., & Grigoriadis, A. E. (2026) · ESMO Real World Data and Digital Oncology · doi:10.1016/j.esmorw.2026.100737 · Cited by 1
Yin, J., Wang, W., Wu, L., Li, Z., Wang, W., He, T., Wang, Y., Li, G., Tang, L., Zhao, X., et al. (2026) · Stroke · doi:10.1161/strokeaha.126.055189 · Cited by 2
LLM-gestützte Extraktion klinischer Daten: Potenziale und Herausforderungen
Seidl, P., Szep, M., Breden, S., Charitou, F., Mogler, C., Schüffler, P. J., von Eisenhart‐Rothe, R., Lazic, I., & Hinterwimmer, F. (2025) · Die Orthopädie · doi:10.1007/s00132-025-04754-0 · Cited by 1
SynthEHR-eviction: enhancing eviction SDoH detection with LLM-augmented synthetic EHR data
Yao, Z., Zhao, Y., Mitra, A., Levy, D. A., Druhl, E., Tsai, J., & Yu, H. (2026) · npj Digital Medicine · doi:10.1038/s41746-026-02473-0 · Cited by 1
Petersen, L. A., Beck, M. S., Andersen, M. B., Xu, J. J., & Bruun, F. J. (2026) · Clinical Radiology · doi:10.1016/j.crad.2026.107315 · Cited by 1
Scroggins, J. K., Barcelona, V., Hulchafo, I. I., Harkins, S., Zhang, Z., Scharp, D., Cato, K., Moen, H., Davoudi, A., Tadiello, M., et al. (2026) · Nursing Outlook · doi:10.1016/j.outlook.2026.102757 · Cited by 1
Rahgozar, A., & Mortezaagha, P. (2026) · Artificial Intelligence Review · doi:10.1007/s10462-026-11599-2 · Cited by 1
Fink, M. A., Bischoff, A., Atsiatorme, E., Kremer, A., Kroschke, J., Moll, M., Stein, P., Riebl, V., Leichenich, T., Kauczor, H., et al. (2026) · Insights into Imaging · doi:10.1186/s13244-026-02289-2 · Cited by 1
Chow, N.-H., Chang, H.-C., Chen, H.-K., Lin, C.-Y., Liu, Y.-L., Tseng, P., Shiu, L.-J., Chu, Y.-W., Chung, P., & Chang, K.-P. (2026) · Diagnostics · doi:10.3390/diagnostics16111644 · Cited by 1
Li, J., Guo, J., Pang, P. C., Oliveira, H. G., Ng, B. K., & Tan, T. (2026) · Expert Systems with Applications · doi:10.1016/j.eswa.2026.133419 · Cited by 1
On-premises open-source large language models for privacy-preserving multimodal depression screening
Kwon, S., Kim, Y., Jhon, M., Park, J.-H., Lim, B., Jeon, E., Kim, J.-M., Kim, J.-W., & Lee, H. (2026) · International Journal of Medical Informatics · doi:10.1016/j.ijmedinf.2026.106577 · Cited by 1
ChatGPT and Large Language Models in Contemporary Nursing
Uchmanowicz, I., Aldossary, H. M., Lee, C. S., Figura, M., Jędrzejczyk, M., Maria, M. D., Pucciarelli, G., Molka, E., Straiton, N., & Kołtuniuk, A. (2026) · Journal of Clinical Nursing · doi:10.1111/jocn.70490 · Cited by 2
AI adoption among French oncology pharmacists: A national survey
Wakil, A., Chevrier, R., Tournamille, J., & Pourroy, B. (2026) · Journal of Oncology Pharmacy Practice · doi:10.1177/10781552261485826 · Cited by 1
Small-Sized Reasoning Language Models for Linguistic Screening of Alzheimer’s DiseasePreprint
Addepalli, V. R., Abdalnabi, N., Kummerfeld, E., Hembroff, G. C., Kiselica, A. M., Rao, P. K., & Lee, K. (2026) · medRxiv · doi:10.64898/2025.12.24.25342972 · Cited by 1
Evaluating Locally Deployed Gemma 3 27B on the Taiwanese Pulmologist’s Board ExamPreprint
Chen, C.-H., Chen, C.-W., Hsieh, K.-Y., & Huang, K.-E. (2026) · Research Square · doi:10.21203/rs.3.rs-8477429/v1 · Cited by 1
Cheong, J., Corcoran, C. M., Lewandowski, K. E., Pasternak, O., Kelly, S., Sylvain Bouix, A., Reichenberg, A., Bearden, C. E., Cecchi, G., Baker, J. T., et al. (2026) · Research Square · doi:10.21203/rs.3.rs-8777643/v2 · Cited by 1
Chen, C.-H., Hsieh, K.-Y., Huang, K.-E., & Chen, C.-W. (2026) · Preprints.org · doi:10.20944/preprints202603.0329.v1 · Cited by 1
The economics of accuracy for medical reasoning with large language models
Bhattacharyya, K., & Kamabattula, S. (2026) · PLOS Digital Health · doi:10.1371/journal.pdig.0001182 · Cited by 1
Integrating Large Language Models into Space Radiology: Opportunities and Challenges
Güneş, Y. C., Çamur, E., & Cesur, T. (2025) · Wilderness and Environmental Medicine · doi:10.1177/10806032251337674
TRIPOD+AI ve TRIPOD-LLM Rehberlerine Uyum: Klinik Yapay Zeka Modelleri Nasıl Raporlanmalı?
Varol, B. (2025) · Özgür Yayınları eBooks · doi:10.58830/ozgur.pub780.c3256
SynthEHR-Eviction: Enhancing Eviction SDoH Detection with LLM-Augmented Synthetic EHR DataPreprint
Yao, Z., Zhao, Y., Mitra, A., Levy, D. A., Druhl, E., Tsai, J., & Yu, H. (2025) · medRxiv · doi:10.1101/2025.07.10.25331237
In Reply to Sengul I and Sengul D
Dennstädt, F., Hastings, J., Putora, P. M., Vu, E., Fischer, G. F., Süveg, K., Glatzer, M., Riggenbach, E., Hà, H.-L., & Čihorić, N. (2025) · Advances in Radiation Oncology · doi:10.1016/j.adro.2025.101800
Self-citationA hybrid deployment model for generative artificial intelligence in hospitals
Griot, M., Hemptinne, C., Vanderdonckt, J. M., & Yüksel, D. (2025) · Machine Learning Health · doi:10.1088/3049-477x/addb51 · Cited by 1
Shenoy, E. S., Branch‐Elliman, W., & Wiens, J. (2025) · Clinical Infectious Diseases · doi:10.1093/cid/ciaf371
Chanci, D., Moore, R., Foote, H. P., Goldstein, M. A., Kumar, K. R., Rotta, A. T., Hornik, C. P. V., Burriss‐West, M., Hamilton, M., Stanco, N., et al. (2026) · Scientific Reports · doi:10.1038/s41598-026-57353-0
Junior, V. F. M., Gallani, S., Basovic, L., Alomar, M., You, J. C., Samal, L., Park, E. R., Sylvia, L. G., Banister, G. E., Hadar, P., et al. (2025) · Research Square · doi:10.21203/rs.3.rs-7830207/v1
Domain-Specific Fine-Tuning of PubMedBERT for Neonatal Care Applications
Zahed, T. A., Mishra, B. K., & Fagbola, T. M. (2025) · International Conference on Circuits, Power and Intelligent Systems (CCPIS) · doi:10.1109/ccpis65231.2025.11234243
Prompt engineering experiment on ChatGPT’s ability to recommend orthopedic surgeons
Haupt, M. R., Massillon, D. R., Yang, L., Chen, Y., Natarajan, A., Ward, S. R., & Mackey, T. K. (2026) · International Journal of Medical Informatics · doi:10.1016/j.ijmedinf.2026.106581
O’Regan, P., Butt, F., Carter, L., Graham, D. M., Blanc, A. L., Hoskins, R., Stephenson, L. J., Patil, A., Shabbir, M., Eken, D., et al. (2025) · Frontiers in Digital Health · doi:10.3389/fdgth.2025.1708067
Zafar, S., Qin, W., Chengliang, L., Khan, A. A., Nazir, A., Faisal, M. S., Khalid, F., Vemula, S. S. M., & Khan, A. R. (2025) · doi:10.2196/preprints.88967
Smith, A. B., Brock, J., Jones, H., Solari, F., Anss, R., Kimberley, C., Joyner, C., Yasin, T., Basbous, O., & Poacher, A. T. (2025) · BMJ Open · doi:10.1136/bmjopen-2025-104612
Ethical Hazards of Large Language Models in Primary Care: A Clinician-Focused Update
Lu, M. M., Gillette, J. J., & Heston, T. F. (2025) · IntechOpen eBooks · doi:10.5772/intechopen.1012864
Large Language Models (LLMs) in Medical Error Detection and Correction: A Comprehensive Review
Chandru, R., Kadusabe, P., Qureshi, A. M., Sharma, S., & Kaushik, A. (2025) · Springer eBooks · doi:10.1007/978-3-032-07267-2_6
Digitale Diagnoseunterstützung seltener rheumatologischer Erkrankungen: Evidenz und Perspektiven
Kremer, P., Krusche, M., & Knitza, J. (2026) · rheuma plus · doi:10.1007/s12688-025-00922-4
Cheong, J. (2026) · Research Square · doi:10.21203/rs.3.rs-8777643/v1
Small Language Models for Emergency Departments Decision Support: A Benchmark Study
Wang, Z., Wu, J., Teitge, B. D., Holodinsky, J. K., & Drew, S. (2025) · IEEE Smart World Congress (SWC) · doi:10.1109/swc65939.2025.00239
Asano, H., Tian, Y.-S., Hatabu, A., Ohishi, M., Fukuzawa, K., Takaya, D., & Ikeda, K. (2026) · BMC Research Notes · doi:10.1186/s13104-026-08061-5
Language-dependent variability in large language model performance on pharmaceutical knowledge tasksPreprint
Asano, H., Tian, Y., Hatabu, A., Ohishi, M., Fukuzawa, K., Takaya, D., & Ikeda, K. (2026) · Research Square · doi:10.21203/rs.3.rs-9217016/v1
Luo, J., Ma, J., Qiu, Y., Wang, T., Yang, Y., Qiu, G., Chen, H., Pang, J., & Wang, W. (2026) · npj Digital Medicine · doi:10.1038/s41746-026-02591-9
Artificial Intelligence in Healthcare Cybersecurity
Kuppusamy, P., & Suresh Joseph, K. (2026) · Advances in computational intelligence and robotics book series · doi:10.4018/979-8-3373-2922-2.ch005
From Expectation to Evaluation: Expectation Cues Systematically Bias LLM and Human Judgment
Sun, Y., Dillion, D., Gray, K. J., Lyu, M., Zhang, Z., & Li, F. (2026) · CHI Conference on Human Factors in Computing Systems · doi:10.1145/3772318.3790492 · Cited by 1
Evaluating open-source LLMs for dental EMR generation
Wang, H., Du, W., Yang, B., Liu, M., Xu, C., Zhang, W., Xu, C., He, L., Zhang, W., Yu, Y., et al. (2026) · BMC Oral Health · doi:10.1186/s12903-026-08346-y
Assessing Llm Hallucinations And The Reliability Of Using LLms For Automated Hallucination DetectionPreprint
Cheong, J., Chen, D. S., Leung, W., Chou, C., Corcoran, C. M., Kelly, S., Bearden, C. E., Cecchi, G., Baker, J. T., Kane, J. M., et al. (2026) · Research Square · doi:10.21203/rs.3.rs-9394250/v1
Julio, Y. R., Mangones, A. P., Pérez-García, N. A., Huerta, M., Viloria-Núñez, C., Hernández, F. I., Tovio, J. T., Vega, H. V. R., & Pareja, J. E. D. L. R. (2025) · Latin American Computer Conference (CLEI) · doi:10.1109/clei67442.2025.11420318
Chen, C.-H., Hsieh, K.-Y., Huang, K.-E., & Chen, C.-W. (2026) · doi:10.2196/preprints.98737
PromptFence: A Semantic Guardrail for Healthcare AI to Defend Against Prompt Injection Attacks
Deepak, S., Shukla, V., Shetty, R., Kolhe, A., & Tiwari, M. (2026) · IEEE International Conference on AI Engineering and Innovations (AIEI) · doi:10.1109/aiei69164.2026.11497133
Metadata
- Authors
- Dennstädt, F., Hastings, J., Putora, P. M., Schmerder, M., & Cihoric, N.
- Affiliations
- University of Bern (CH)
- SIB Swiss Institute of Bioinformatics (CH)
- Corresponding author
- Dennstädt, Fabio
- Venue
- npj Digital Medicine
- Published
- 2025-03-06
- Volume
- 8
- Issue
- 1
- Pages
- 143-143
- ISSN
- 2398-6352 (ISSN-L)
- PMC
- PMC11885444
- OpenAlex
- W4408197148
- Cited by
- 144
- References
- 14
- Citations by year
- 2026: 90 · 2025: 54
- FWCI
- 34.42
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Licence
- Locations
- npj Digital Medicine (publishedVersion, cc-by-nc-nd)
- PubMed Central (publishedVersion, cc-by-nc-nd)
- PubMed (publishedVersion)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion, cc-by-sa)
- Open Access CRIS of the University of Bern
- Topics
- Health Sciences › Medicine › Health Informatics › Artificial Intelligence in Healthcare and Education
- Physical Sciences › Computer Science › Artificial Intelligence › Machine Learning in Healthcare
- Physical Sciences › Computer Science › Artificial Intelligence › Ethics and Social Impacts of AI
- Keywords
- large language models, data privacy, open-source LLMs, model customization, AI security, ethical considerations, regulatory challenges, clinician collaboration
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
