

The DOI matches its Crossref record; 14 of the 14 references it cites were found in a registry or an index.
Implementing large language models in healthcare while balancing control, collaboration, costs and security
Open accessAbstract
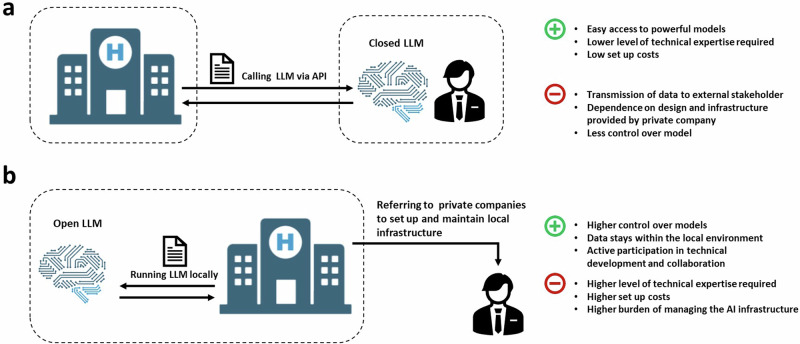
Integrating Large Language Models (LLMs) into healthcare promises substantial advancements but requires careful consideration of technical, ethical, and regulatory challenges. Closed LLMs of private companies offer ease of deployment but pose risks related to data privacy and vendor dependence. Open LLMs deployed on local hardware enable greater model customization but demand resources and technical expertise. Balancing these approaches, with collaboration among clinicians, researchers, and companies is crucial to ensure effective, secure, and ethical implementation.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Deploying large language models (LLMs) in clinical settings is limited by security, reliability, latency, and accessibility concerns that favor smaller, on-device or on-premise models.”
From The economics of accuracy for medical reasoning with large language models (2026) · cites this paper as [3]
Experimental — accuracy not yet measured
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
The future landscape of large language models in medicine
Clusmann, J., Kolbinger, F. R., Muti, H. S., Carrero, Z. I., Eckardt, J.-N., Laleh, N. G., Löffler, C. M. L., Schwarzkopf, S.-C., Unger, M., Veldhuizen, G. P., et al. (2023) · Communications Medicine · doi:10.1038/s43856-023-00370-1 · Cited by 1,045
Using ChatGPT to write patient clinic letters
Ali, S. R., Dobbs, T. D., Hutchings, H. A., & Whitaker, I. S. (2023) · The Lancet Digital Health · doi:10.1016/s2589-7500(23)00048-1 · Cited by 375
Leveraging large language models for decision support in personalized oncology
Benary, M., Wang, X. D., Schmidt, M., Soll, D., Hilfenhaus, G., Nassir, M., Sigler, C., Knödler, M., Keller, U., Beule, D., et al. (2023) · JAMA Network Open · doi:10.1001/jamanetworkopen.2023.43689 · Cited by 306
A critical assessment of using ChatGPT for extracting structured data from clinical notes
Huang, J., Yang, D. M., Rong, R., Nezafati, K., Treager, C., Chi, Z., Wang, S., Cheng, X., Guo, Y., Klesse, L. J., et al. (2024) · npj Digital Medicine · doi:10.1038/s41746-024-01079-8 · Cited by 298
The Role of Large Language Models in Medical Education: Applications and Implications
Safranek, C. W., Sidamon-Eristoff, A. E., Gilson, A., & Chartash, D. (2023) · JMIR Medical Education · doi:10.2196/50945 · Cited by 233
Embracing Large Language Models for Medical Applications: Opportunities and Challenges
Karabacak, M., & Margetis, K. D. (2023) · Cureus · doi:10.7759/cureus.39305 · Cited by 217
Dennstädt, F., Zink, J., Putora, P. M., Hastings, J., & Čihorić, N. (2024) · Systematic Reviews · doi:10.1186/s13643-024-02575-4 · Cited by 191
Self-citationA systematic analysis of failures in protecting personal health data: A scoping review
Pool, J., Akhlaghpour, S., Fatehi, F., & Burton‐Jones, A. (2023) · International Journal of Information Management · doi:10.1016/j.ijinfomgt.2023.102719 · Cited by 181
Hallucinations in Large Multilingual Translation Models
Guerreiro, N. M., Alves, D. M., Waldendorf, J., Haddow, B., Birch, A., Colombo, P., & Martins, A. F. T. (2023) · Transactions of the Association for Computational Linguistics · doi:10.1162/tacl_a_00615 · Cited by 124
Unmasking and quantifying racial bias of large language models in medical report generation
Yang, Y., Liu, X., Jin, Q., Huang, F., & Lu, Z. (2024) · Communications Medicine · doi:10.1038/s43856-024-00601-z · Cited by 105
Research works printed but not linked: 1
- The HIPAA Journal: Managed care of North America hacking incident impacts 8.9 million individuals. http://www.hipaajournal.com/managed-care-of-north-america-hacking-incident-impacts-8-9-million-individuals/.
Cited by
Sorted by citations
Items 101–149 of 149
Retrieval-Augmented Language Models for Checking Safety Consistency in Pharmaceutical Product Labels
Dupont, C., & Martin, J. (2025) · Pharmacophore · doi:10.51847/fzeuaxeluk
Dennstädt, F., Bobnar, T., Handra, A., Putora, P. M., Filchenko, I., Brüningk, S. C., Aebersold, D. M., Čihorić, N., & Shelan, M. (2026) · JCO Clinical Cancer Informatics · doi:10.1200/cci-25-00386
Self-citationReich, C., Leverenz, J., Brand, C., Niemeier, L., Branzei, I., Yıldırım, M., Sedaghat‐Hamedani, F., Amr, A., Frey, N., & Meder, B. (2026) · Frontiers in Digital Health · doi:10.3389/fdgth.2026.1847603
Clinical artificial intelligence applications of vision-language foundation models
Thirunavukarasu, A. J., Li, S. Y., Qin, P., Nie, D., Sanghera, R., Lim, E., Yu, J., & Zhang, L. (2026) · PLOS Digital Health · doi:10.1371/journal.pdig.0001453
Exploring the potential of artificial intelligence and machine learning in orthopaedic surgery
Cohen, L. J. G., Yao, J. J., & Lajam, C. M. (2026) · Bulletin of the Hospital for Joint Diseases/Bulletin of the Hospital for Joint Disease · doi:10.1097/bh9.0000000000000055
Research and Scholarly Methods: Using Artificial Intelligence
Trinkley, K. E., & Maw, A. (2026) · JACCP JOURNAL OF THE AMERICAN COLLEGE OF CLINICAL PHARMACY · doi:10.1002/jac5.70239
Transforming healthcare with large language models: Innovation, integration, and impact
Joshi, G., Ghai, B., Goutam, N., & Joshi, N. (2026) · Elsevier eBooks · doi:10.1016/b978-0-443-44344-2.00010-8
Cao, W., Lloyd, I., Dichmann, M., Halder, N., Thomas, D., Chen, Z., Blomain, E. S., Adejolu, F., Beck, K., Faherty, P., et al. (2026) · International Journal of Radiation Oncology*Biology*Physics · doi:10.1016/j.ijrobp.2026.06.3060
Benchmarking large language models against practicing clinicians on psychopathological assessment
Lenz, E., Naamanka, J., Trabert, W., Bottlender, R., Malchow, B., Meyer‐Lindenberg, A., Gradinger, T., & Schwarz, E. (2026) · npj Digital Medicine · doi:10.1038/s41746-026-02852-7
Patterns of Local and Cloud Llms Usage in Software Development
Andreyeva, D., & Novikovskaya, N. (2026) · Communications in computer and information science · doi:10.1007/978-3-032-30826-9_14
Khan, M. A., Ayub, U., Jajja, S. A., Anjum, M. U., Warraich, K., Jain, P., Oberoi, J. K., Abbas, M. A., Sadiq, M. H., Sarfraz, M. U., et al. (2026) · medRxiv · doi:10.64898/2026.06.26.26356633
Evaluating Open-Weight Large Language Models for a Local Clinical Assistant
Pires, M. J., & Véstias, M. (2026) · International Young Engineers Forum (YEF-ECE) · doi:10.1109/yef-ece70590.2026.11614644
Sablone, S., Costantino, A., Laurenzano, F., Ferretti, G., Croce, E. B., Vaiano, F., & Grassi, S. (2026) · Sci · doi:10.3390/sci8080182
Using Artificial Intelligence to Standardize Naming Conventions in Radiation Therapy
Dennstädt, F. (2026) · JCO Clinical Cancer Informatics · doi:10.1200/cci-26-00169
Self-citationJi, D., Huang, M., & Wang, L. (2026) · Frontiers in Medicine · doi:10.3389/fmed.2026.1913896
Large language model-assisted referral triage automation in a tertiary hospital
Kang, B., Son, M., Jeong, W., Jeong, S. Y., Kim, Y. J., Park, H.-E., Lee, H. K., Chung, M. J., Kim, T., & Yang, K. (2026) · npj Digital Medicine · doi:10.1038/s41746-026-03067-6
Diao, S., Zhao, J., & Liu, X. (2026) · Frontiers in Medicine · doi:10.3389/fmed.2026.1903690
Zhu, J., Huang, X., Shi, J., Chen, S., Chen, D., Gao, Z., Lü, Y., Yang, T., Wang, X., Lin, Y., et al. (2026) · Journal of Medical Internet Research · doi:10.2196/92919
Implementing AI in Neuroradiology
Shanker, R. R. B. J., Shetty, A., & Ginat, D. T. (2026) · Springer eBooks · doi:10.1007/978-3-032-24568-7_2
de Graaf, S., Dieckens, D., & Jarnalo, C. O. M. (2026) · European Journal of Radiology Artificial Intelligence · doi:10.1016/j.ejrai.2026.100125
Katz, A., Paretti, M., Shealy, T., Aruon, A., & Li, N. (2026) · ASEE Annual Conference & Exposition · doi:10.18260/1-2--59021
Nahm, W. J., Yin, E. S., Milam, E. C., & Weed, J. G. (2026) · JMIR Dermatology · doi:10.2196/94764
Artificial Intelligence Chatbot–Driven Detection of Keratoconus From Corneal Tomography
Mihalache, A., Huang, R. S., Nichani, P. A. H., Popovic, M. M., & Chan, C. C. (2026) · Cornea · doi:10.1097/ico.0000000000004279
Pawlik, Ł., & Deniziak, S. R. (2026) · Scientific Reports · doi:10.1038/s41598-026-68883-y
Artificial Intelligence and Bioengineering Approaches for Antimicrobial Resistance Prediction
Frandes, O., Azamfirei, L., Branea, O. E., Frandeș, S. I., & Lazăr, A. E. (2026) · Medicina · doi:10.3390/medicina62091651
Toward continuous quality observability in medicine
Patil, A., Curry, W. T., & Nahed, B. V. (2026) · npj Health Systems · doi:10.1038/s44401-026-00146-4
Posta, M., Figler, A., Dobolyi, Z., & Győrffy, B. (2026) · Journal of Medical Internet Research · doi:10.2196/95780 · Cited by 1
Artificial Intelligence and Sleep
Schneider, L. D., Hernandez, J., & Heneghan, C. (2026) · Neurologic Clinics · doi:10.1016/j.ncl.2026.07.015
Zhang, W., Li, X., Yuan, R., Zhang, Y., Yang, Y., Xu, Y., Zhong, R., Chen, S., Liu, D., Gao, L., et al. (2026) · Digital Health · doi:10.1177/20552076261487079
Kobayashi, Y., Jiang, S. S., Huang, J., Kim, T., Roeder, K., Chen, L., Kobayashi, N. S., Fine, D. H., & Shimizu, E. (2026) · Dentistry Journal · doi:10.3390/dj14090575
Chan, J., Hastings, J., Tiernan, G., Paterson, J., Lovell, N., Betbeder-Matibet, L., Tung, P. K. M., Pink, S., Lanzeni, D., Donovan, T., et al. (2026) · F1000Research · doi:10.12688/f1000research.169999.3
Self-citationFetrati, H., Chan, G., & Orji, R. (2026) · International Journal of Human-Computer Studies · doi:10.1016/j.ijhcs.2026.103944
Jiang, D., Han, X., Xu, K., & Li, C. (2026) · Scientific Reports · doi:10.1038/s41598-026-76600-y
Agentic AI workflows in anatomic pathology: Opportunities and challenges
Ngo, A., Tian, R., Mohammad, A., Weon, J. L., Arvisais‐Anhalt, S., Minor, J., & Youens, K. (2026) · Journal of Pathology Informatics · doi:10.1016/j.jpi.2026.100718
Asadollahi, A. (2026) · Research Square · doi:10.21203/rs.3.rs-10989319/v1
Aligning Editorial Review With the Pace of Language Models: Five Proposals for Oncology Publishing
Cantón, E. D. (2026) · JCO Clinical Cancer Informatics · doi:10.1200/cci-26-00245
Liu, F., Liu, Z., Fei, X., He, J., Xing, J., Li, J., & Chan, P. (2026) · Journal of Medical Systems · doi:10.1007/s10916-026-02459-1
Wójcik, S., Domienik‐Karłowicz, J., & Rulkiewicz, A. (2026) · Frontiers in Digital Health · doi:10.3389/fdgth.2026.1976313
Goyal, R., Liang, J., Kulkarni, M. S., Nguyen, P., Gillipelli, S. R., & Patel, A. (2026) · Global Surgical Education - Journal of the Association for Surgical Education · doi:10.1007/s44186-026-00599-z
Rui, W., Ma, J., Stepanov, V., Bunnell, A., Lan, M., Chen, J., Patel, R. R., Novikov, D. S., Fieremans, E., & Shen, Y. (2026) · medRxiv · doi:10.64898/2026.10.06.26364312
Wang, M., Tang, Y., Yang, Y., Tu, Y., Cao, Z., Ling, R., Sun, K., Ma, J., Zhang, Z., Zhang, R., et al. (2026) · Insights into Imaging · doi:10.1186/s13244-026-02421-2
Locally Deployable Knowledge Graph Question Answering for Judicial Documents
Nie, T., Duan, Q., & Zeng, J. (2026) · International Conference on Artificial Intelligence Technologies and Applications (ICAITA) · doi:10.1109/icaita71179.2026.11737125
Erdoğan, O., Şahin, Y., Şakar, M., & Dağçınar, A. (2026) · doi:10.2196/preprints.114747
Cheng, Y., Wang, R., 洪, 錫., Wang, C., Yin, Y., Wang, J., Liu, X., Yang, L., Yi, L., Zhao, X., et al. (2026) · Diagnostics · doi:10.3390/diagnostics16213502
Nguyen, N. D., Perice, L., Sangal, R. B., Kumar, V., Chu, A. L., & Dash, D. (2026) · medRxiv · doi:10.64898/2026.10.27.26366650
Bang, K. Y., Strachan, D. A., Brummel, G. L., Frick, A., Schwartz, A., Empey, P. E., Chun, E., Rodríguez-Monguió, R., Denton, N. L., Chisholm‐Burns, M. A., et al. (2026) · American Journal of Pharmaceutical Education · doi:10.1016/j.ajpe.2026.102117
Frehywot, S., & Vovides, Y. (2026) · JMIR AI · doi:10.2196/100954
LLM-GAN: Bridging Language and Multi-modal Generation in the Next AI Healthcare Frontier
Bouzidi, W., Salem, Z. N. B., & Meddeb, O. (2026) · Studies in computational intelligence · doi:10.1007/978-3-032-24013-2_2
Metadata
- Authors
- Dennstädt, F., Hastings, J., Putora, P. M., Schmerder, M., & Cihoric, N.
- Affiliations
- University of Bern (CH)
- SIB Swiss Institute of Bioinformatics (CH)
- Corresponding author
- Dennstädt, Fabio
- Venue
- npj Digital Medicine
- Published
- 2025-03-06
- Volume
- 8
- Issue
- 1
- Pages
- 143-143
- ISSN
- 2398-6352 (ISSN-L)
- PMC
- PMC11885444
- OpenAlex
- W4408197148
- Cited by
- 144
- References
- 14
- Citations by year
- 2026: 90 · 2025: 54
- FWCI
- 34.42
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Licence
- Locations
- npj Digital Medicine (publishedVersion, cc-by-nc-nd)
- PubMed Central (publishedVersion, cc-by-nc-nd)
- PubMed (publishedVersion)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion, cc-by-sa)
- Open Access CRIS of the University of Bern
- Topics
- Health Sciences › Medicine › Health Informatics › Artificial Intelligence in Healthcare and Education
- Physical Sciences › Computer Science › Artificial Intelligence › Machine Learning in Healthcare
- Physical Sciences › Computer Science › Artificial Intelligence › Ethics and Social Impacts of AI
- Keywords
- large language models, data privacy, open-source LLMs, model customization, AI security, ethical considerations, regulatory challenges, clinician collaboration
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
