

The DOI matches its Crossref record; 88 of the 88 references it cites were found in a registry or an index.
Moral stereotyping in large language models
Open accessAbstract
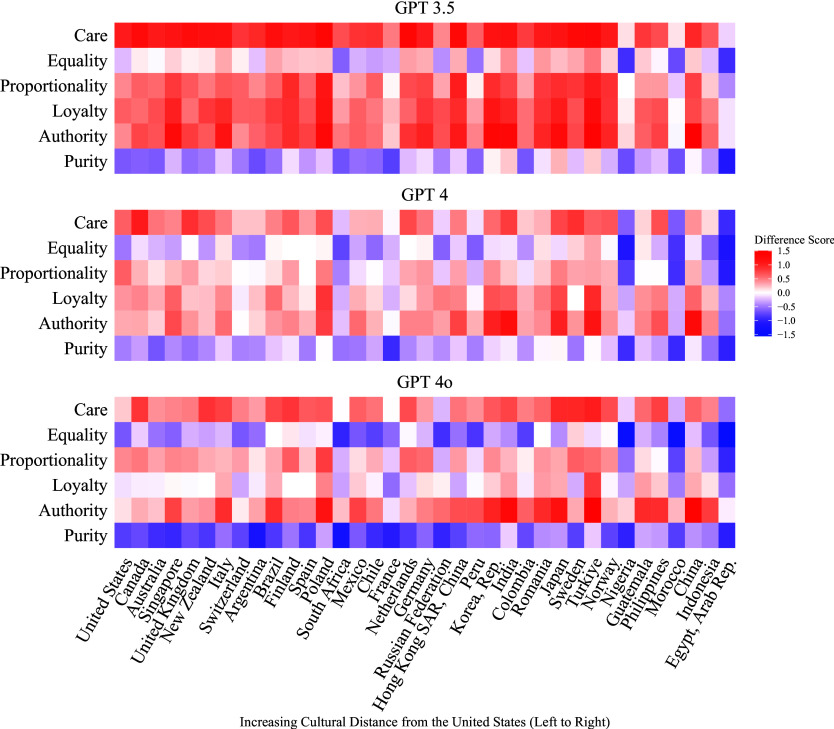
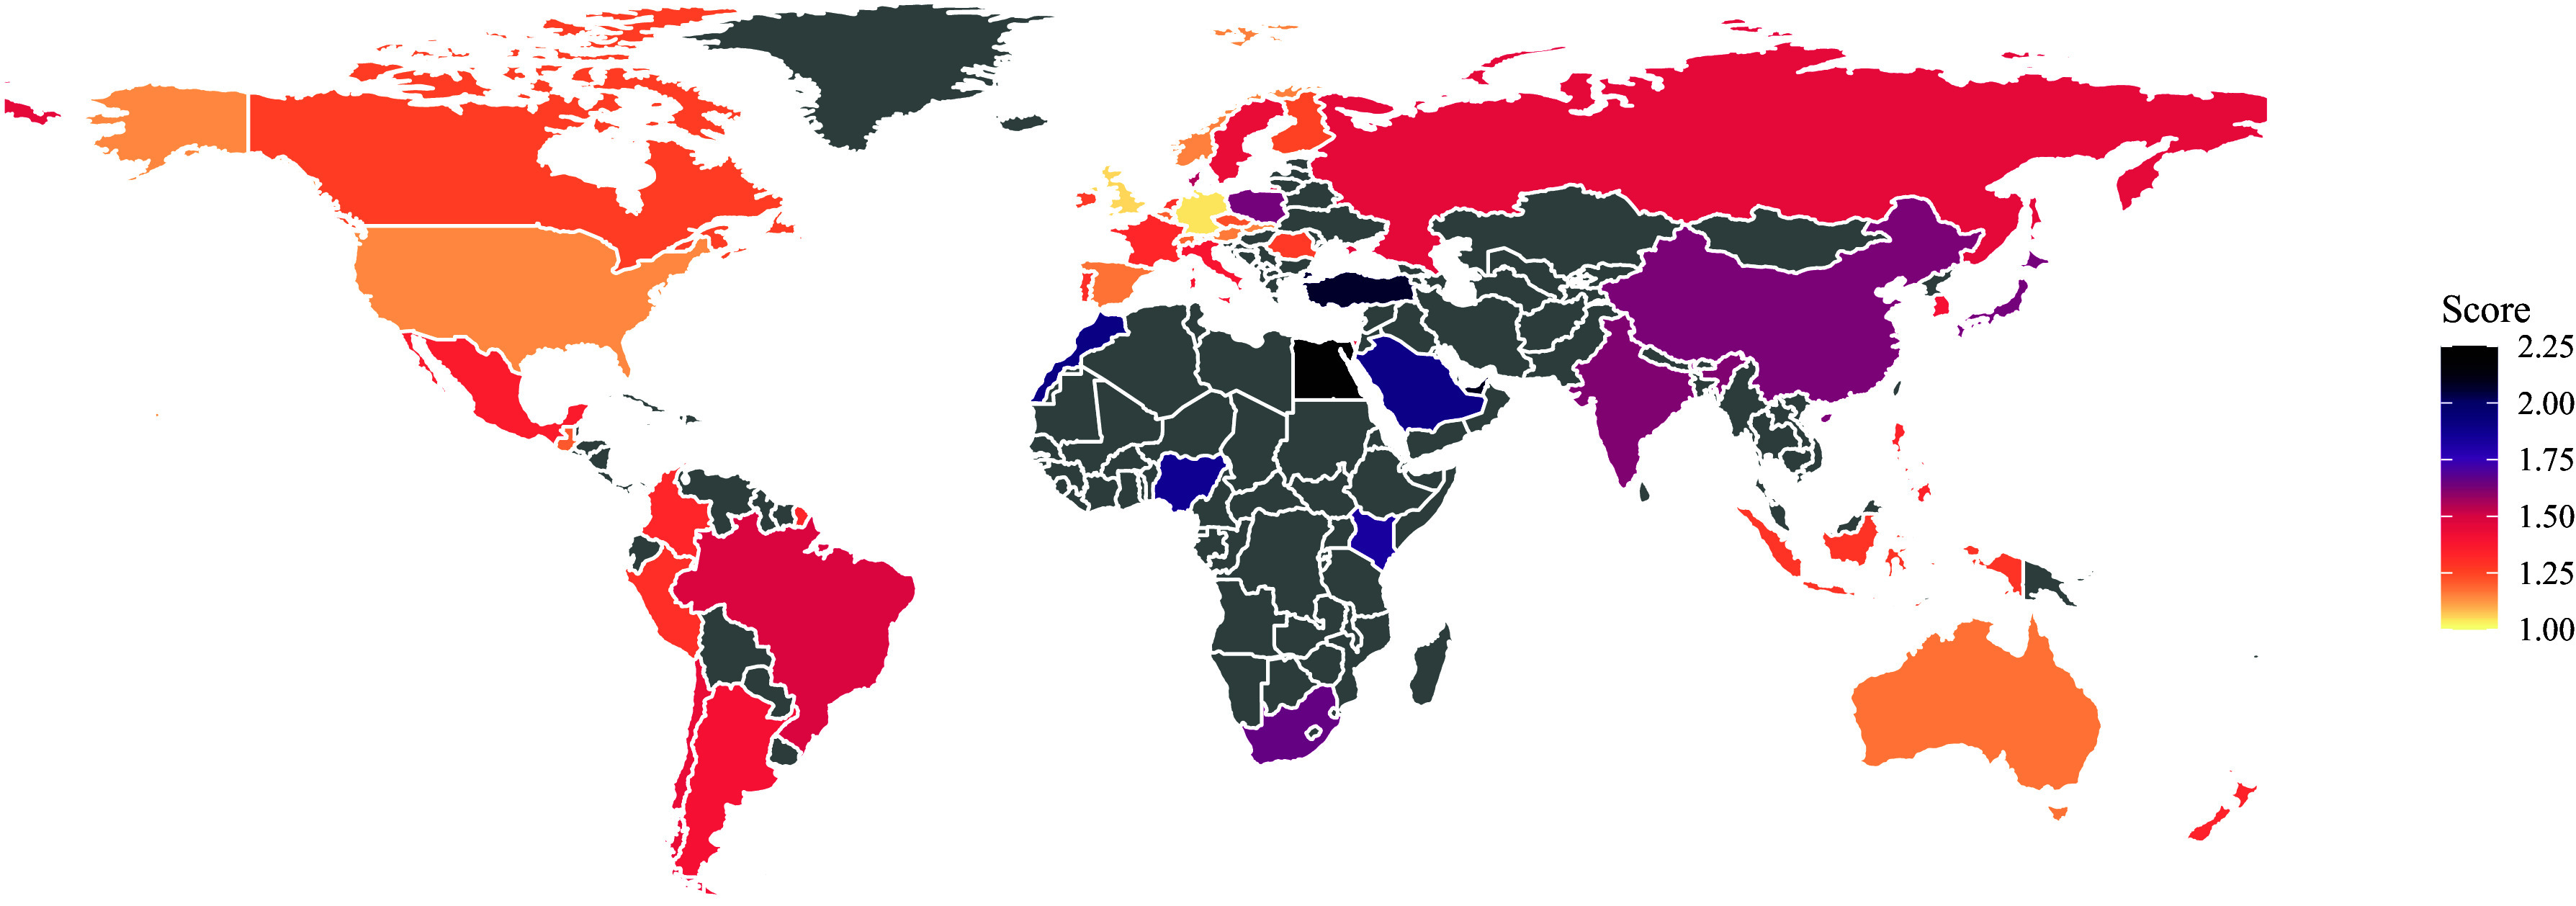
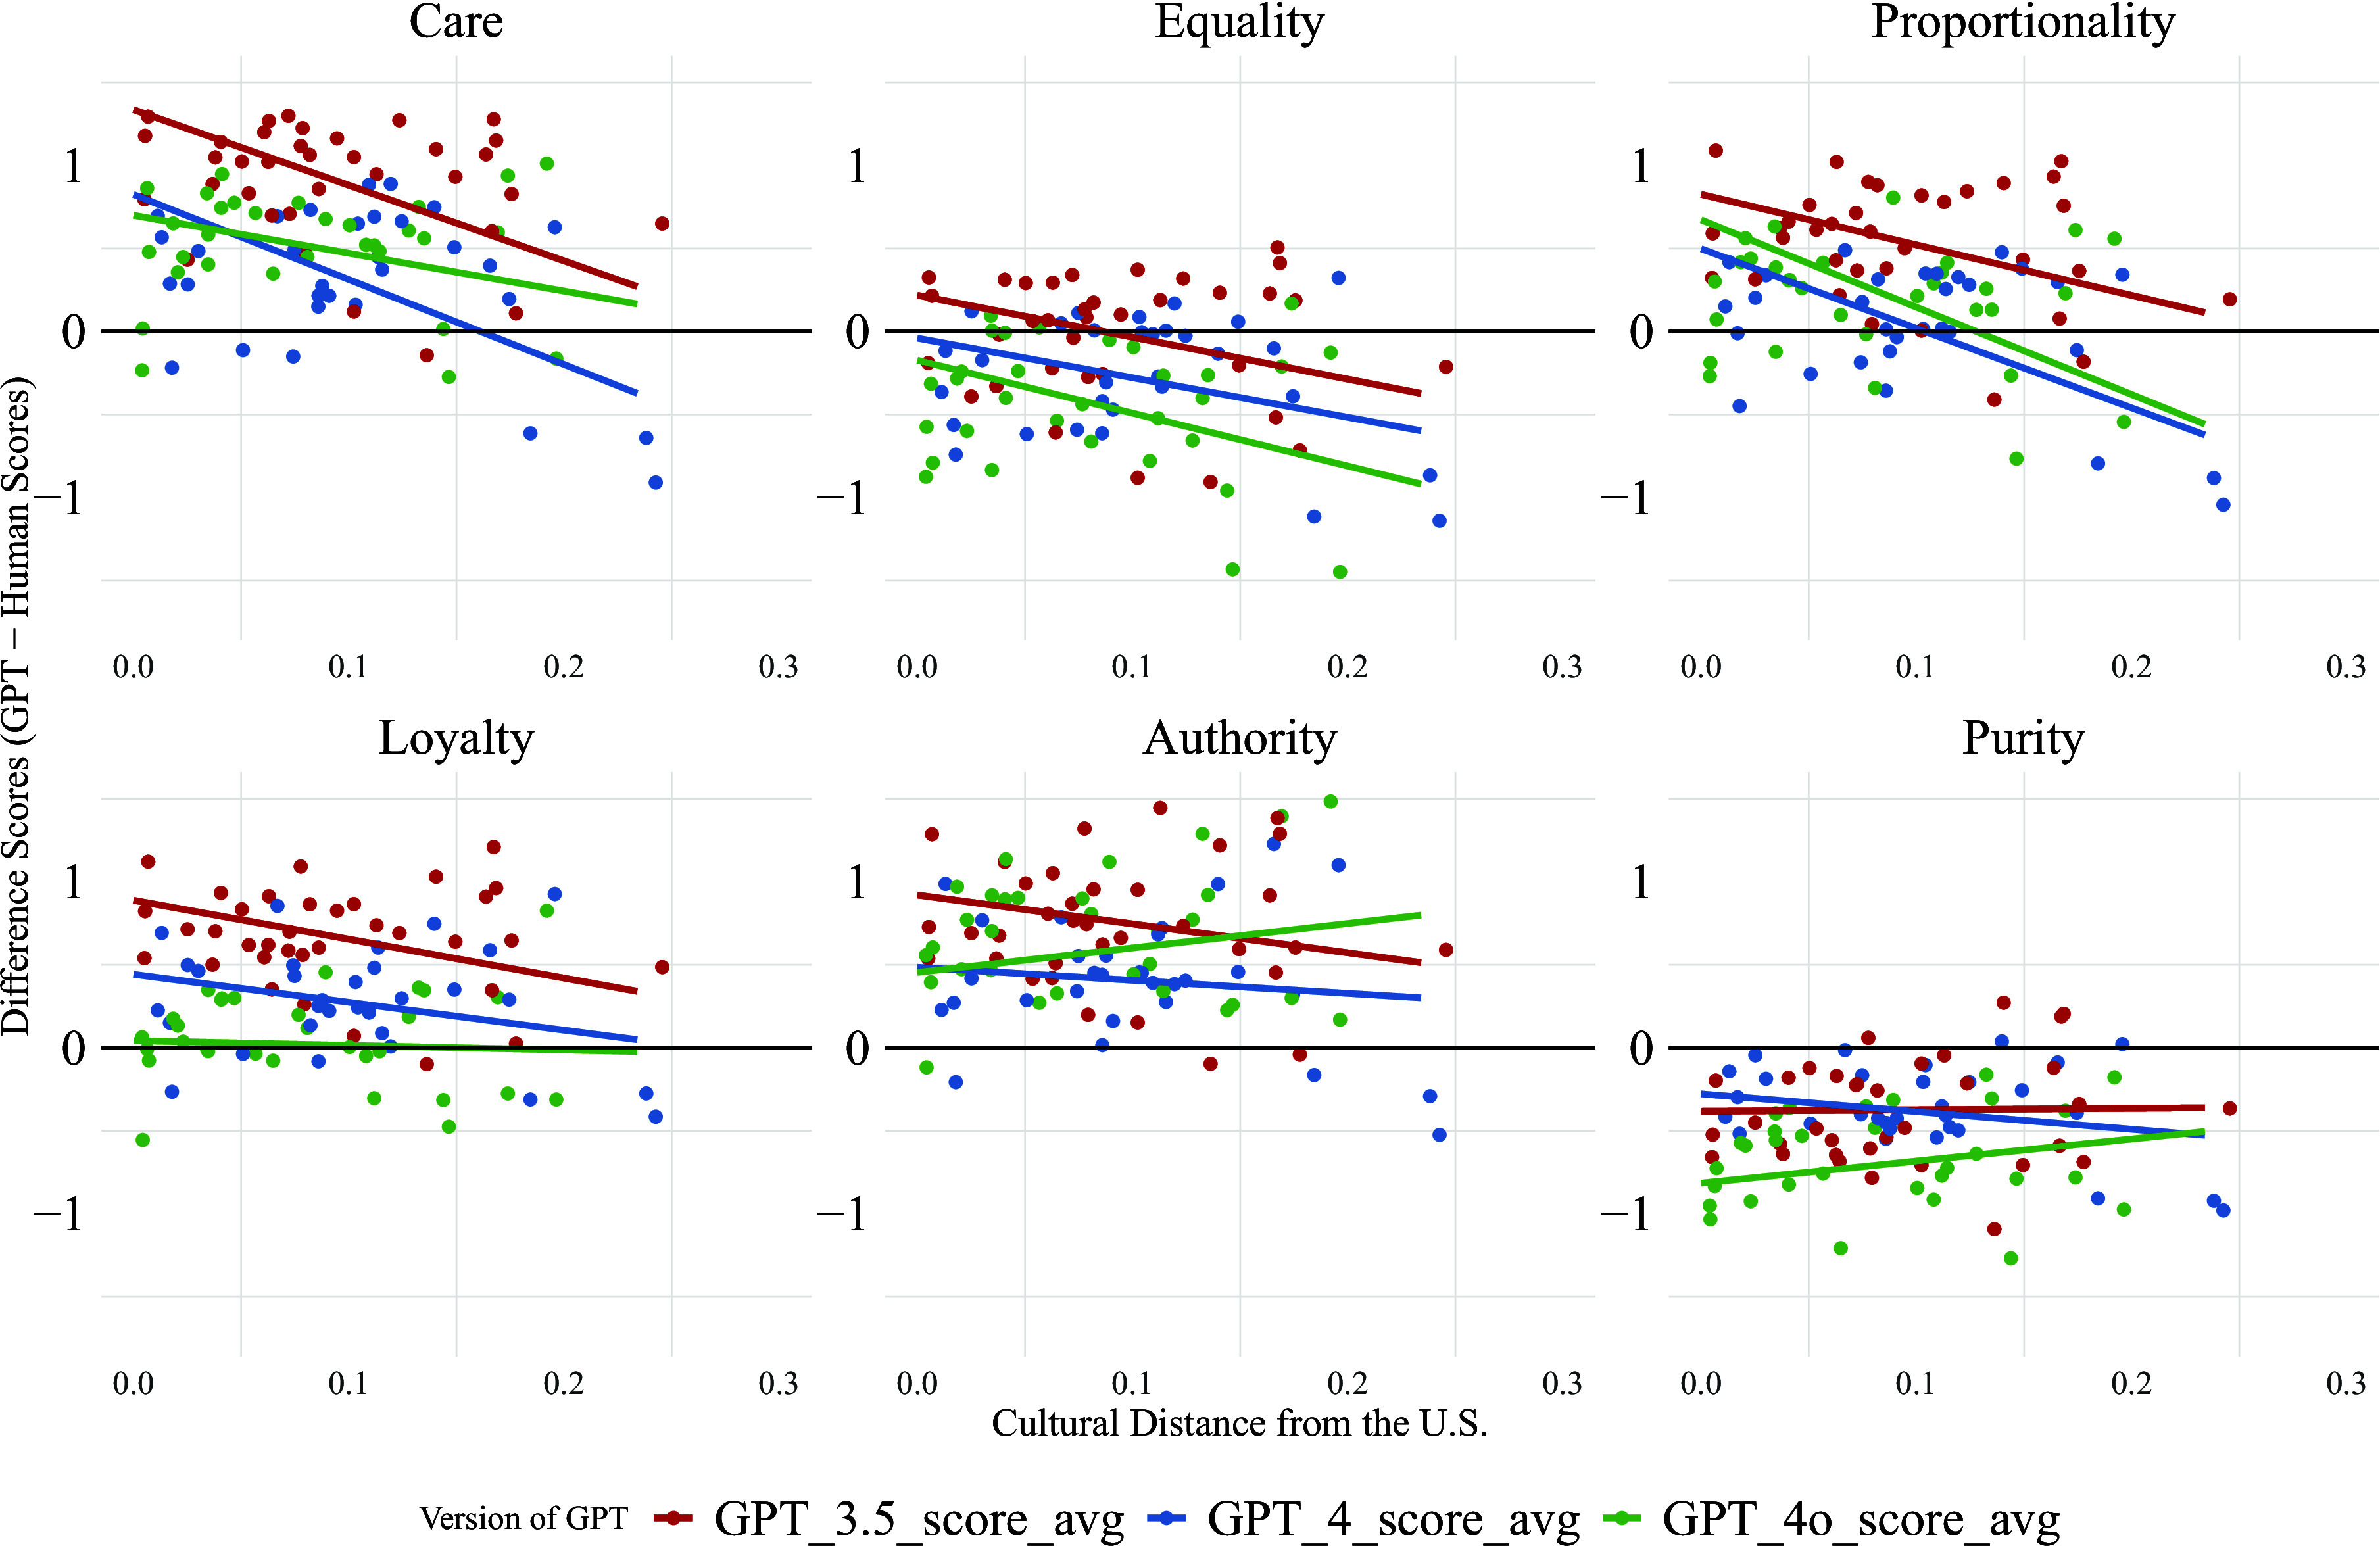
Can Large Language Models (LLMs) accurately estimate various societies’ moral values? Here, we query the perceptions of LLMs regarding the moral norms of the “average” person from 48 nations and compare them to a large-scale ( n = 90 , 802 ) survey of six moral values (Care, Equality, Proportionality, Loyalty, Authority, and Purity) from those populations. Our findings indicate that LLMs poorly capture the moral diversity around the globe, systematically overestimating some moral values (particularly Care) and underestimating others (especially Purity). Notably, examining various versions of Generative Pre-trained Transformer (GPT) shows that these LLMs may overestimate the overall moral concerns of some Western countries (e.g., the United States, Canada, and Australia) while underestimating those of non-Western countries (e.g., Nigeria, Morocco, and Indonesia). Our work demonstrates that LLMs are inaccurate generators of cross-cultural estimations in the moral domain; in other words, they stereotype the moral values of non-Western populations in predictable ways. Our results highlight the ethical and epistemic risks of relying on LLMs to estimate the endorsement of moral values around the globe.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Schwartz, S. H. (1992) · Advances in Experimental Social Psychology · doi:10.1016/s0065-2601(08)60281-6 · Cited by 14,619
The weirdest people in the world?
Henrich, J., Heine, S. J., & Norenzayan, A. (2010) · Behavioral and Brain Sciences · doi:10.1017/s0140525x0999152x · Cited by 12,641
On the Dangers of Stochastic Parrots: Can Language Models Be Too Big? 🦜
Bender, E. M., Gebru, T., McMillan-Major, A., & Shmitchell, S. (2021) · Proceedings of the 2021 ACM Conference on Fairness, Accountability, and Transparency · doi:10.1145/3442188.3445922 · Cited by 6,988 · cited 1×
“As a result, LLMs are likely reflective of a dataset where Western, English texts are overweighted, and thus overrepresented in subsequent outputs (12).”
Liberals and conservatives rely on different sets of moral foundations.
Graham, J., Haidt, J., & Nosek, B. A. (2009) · Journal of Personality and Social Psychology · doi:10.1037/a0015141 · Cited by 4,560
Self-citationThe role of stereotyping in system‐justification and the production of false consciousness
Jost, J. T., & Banaji, M. R. (1994) · British Journal of Social Psychology · doi:10.1111/j.2044-8309.1994.tb01008.x · Cited by 3,608
Cuddy, A. J. C., Fiske, S. T., & Glick, P. (2008) · Advances in experimental social psychology · doi:10.1016/s0065-2601(07)00002-0 · Cited by 2,723
Graham, J., Nosek, B. A., Haidt, J., Iyer, R., Koleva, S., & Ditto, P. H. (2011) · Journal of Personality and Social Psychology · doi:10.1037/a0021847 · Cited by 2,666
Self-citationIntuitive ethics: how innately prepared intuitions generate culturally variable virtues
Haidt, J., & Joseph, C. (2004) · Daedalus · doi:10.1162/0011526042365555 · Cited by 2,079
Hewstone, M., Rubin, M., & Willis, H. (2002) · Annual Review of Psychology · doi:10.1146/annurev.psych.53.100901.135109 · Cited by 2,031
Graham, J., Haidt, J., Koleva, S. P., Motyl, M. S., Iyer, R., Wojcik, S. P., & Ditto, P. H. (2013) · Advances in experimental social psychology · doi:10.1016/b978-0-12-407236-7.00002-4 · Cited by 2,009
Self-citation
Research works printed but not linked: 2
- L. Hewitt A. Ashokkumar I. Ghezae R. Willer Predicting results of social science experiments using large language models. DocSend [Preprint] (2024). https://docsend.com/view/ity6yf2dansesucf. Accessed 20 November 2025.
- 10.1037/a0021847 · DOI · Paper page
Cited by
An, J., Huang, D., Lin, C., & Tai, M. (2025) · PNAS Nexus · doi:10.1093/pnasnexus/pgaf089 · Cited by 58
The cultural stereotype and cultural bias of ChatGPT
Yuan, H., Che, Z., Zhang, Y., Shao, L. H., Yuan, X., Huang, L., Hu, X., Peng, K., & Luo, S. (2025) · Journal of Pacific Rim Psychology · doi:10.1177/18344909251355673 · Cited by 35
AI-Generated Empathy: Opportunities, Limits, and Future Directions
Ong, D. C., Goldenberg, A., Inzlicht, M., & Perry, A. (2026) · Current Directions in Psychological Science · doi:10.1177/09637214261444274 · Cited by 16
Morality across time and space
Atari, M., & Zewail, A. (2025) · European Review of Social Psychology · doi:10.1080/10463283.2025.2500839 · Cited by 10
Self-citationDigital twins are funhouse mirrors: Five systematic distortions
Peng, T., Brucks, M. S., Gui, G., Merlau, D. J., Fan, G. J., Sliman, M. B., Johnson, E. J., Althenayyan, A., Bellezza, S., Donati, D., et al. (2026) · Science Advances · doi:10.1126/sciadv.aeh8260 · Cited by 8
Rethinking Acculturation: Placing Social Interaction at the Center of Cultural Adaptation
Chen, P.-H. A., Chou, F.-C. B., & Wang, T. H. (2025) · Social and Personality Psychology Compass · doi:10.1111/spc3.70099 · Cited by 7
Generative AI Use in Entrepreneurship: An Integrative Review and an Empowerment-Entrapment FrameworkPreprint
Lu, J. G., Zhao, G. G., & Zheng, A. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2604.02567 · Cited by 6
Moral Language and Political Polarisation: An Overview
Wang, S.-Y. N. (2025) · Sociology Compass · doi:10.1111/soc4.70063 · Cited by 2
Gómez‐Corona, C., Otterbring, T., & Jaeger, S. R. (2026) · Food Quality and Preference · doi:10.1016/j.foodqual.2026.106080 · Cited by 2
Persona-prompted LLM agents achieve modest but genuine prediction of human social media reactions
Bojić, L., Felfernig, A., Dinić, B. M., Ilić, V., Rettinger, A., Mevorah, V., & Trilling, D. (2026) · Scientific Reports · doi:10.1038/s41598-026-66277-8 · Cited by 2
Figueroa, A., Osborne, M. R., & Hudson, S. T. J. (2025) · Research in Organizational Behavior · doi:10.1016/j.riob.2025.100227 · Cited by 2
Self-citationFrom Alliance to Nexus: Rethinking Digital Therapeutic Relationships
Cadena, D. B., Walther, J. U., & Brünahl, C. A. (2026) · JMIR Mental Health · doi:10.2196/89378 · Cited by 1
Introduction to Leisure and Artificial Intelligence: Critical Commentaries
Stodolska, M. (2026) · Leisure Sciences · doi:10.1080/01490400.2026.2733704 · Cited by 1
Peng, T., Gui, G., Merlau, D. J., Fan, G. J., Sliman, M. B., Brucks, M. S., Johnson, E., Morwitz, V. G., Althenayyan, A., Bellezza, S., et al. (2025) · SSRN Electronic Journal · doi:10.2139/ssrn.5518418 · Cited by 1
Thakur, A., Murray, T., Rodriguez, P., & Hilbert, M. (2026) · SSRN Electronic Journal · doi:10.2139/ssrn.6083909 · Cited by 1
Atari, M., Seker, F., & Zewail, A. (2026) · Cambridge University Press eBooks · doi:10.1017/9781009639057.008
Self-citationPark, S., Cho, E., Jung, C. Y., Kang, W. C., Kim, T., Park, E., & Song, S. (2025) · Scientific Data · doi:10.1038/s41597-025-06344-3
Psychometric Comparability of LLM-Based Digital TwinsPreprint
Zhang, Y., & Ma, Z. (2026) · SSRN Electronic Journal · doi:10.2139/ssrn.5967255
Potentials and Limitations of Large Language Models in Cross-Cultural Language Understanding
孔, 一. (2026) · Modern Linguistics · doi:10.12677/ml.2026.146511
Synthetic data and digital twins: The hype, the facts, the promise
Toubia, O. (2026) · Current Opinion in Psychology · doi:10.2139/ssrn.7065919
Large language models often prioritize Western moral values, overlooking other cultures
Zewail, A., & Figueroa, A. (2026) · The Conversation · doi:10.64628/aai.tfwp66tdw
Self-citationThe Risks of Sycophantic GenAI in Community Sport and Leisure
Yeomans, C., Nguyen, J., Bowell, P., & Demsar, V. (2026) · Leisure Sciences · doi:10.1080/01490400.2026.2717277
Perry, A., & Cameron, C. D. (2026) · Cambridge University Press eBooks · doi:10.1017/9781009639057.002
Cultural bias or universal traits? Exploring personality-like profiles of large language models
Hang, Y., Soto, C. J., Lignier, B., Ling, Z., Liu, Q., Wang, Y., Zhu, J., He, X., & Wu, W. (2026) · Royal Society Open Science · doi:10.1098/rsos.252491
Locating LLM Expressed Ideology in the Global Distribution of Political AttitudesPreprint
Kaufman, A. R., Ibrahim, H., Omari, A., Rabbani, S., AlDahoul, N., Rahwan, T., & Zaki, Y. (2026) · SSRN Electronic Journal · doi:10.2139/ssrn.7522318
Bojić, L., Stanic, T., Matthes, J., Samala, A. D., Dinić, B. M., & Wang, J. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2609.30563
Who reviews the reviews? When AI encounters academic aesthetics
Qu, C. (2026) · Scottish Geographical Journal · doi:10.1080/14702541.2026.2737673
Lu, J. G., Zhao, G. G., & Zheng, A. (2026) · Strategic Entrepreneurship Journal · doi:10.1002/sej.70050
Akaliyski, P., & Messner, W. (2026) · Journal of International Business Studies · doi:10.1057/s41267-026-00913-3
Metadata
- Authors
- Zewail, A., Figueroa, A., Graham, J., & Atari, M.
- Affiliations
- University of Massachusetts Amherst (US)
- University of California System (US)
- University of Utah (US)
- Corresponding author
- Atari, Mohammad
- Venue
- Proceedings of the National Academy of Sciences
- Publisher
- National Academy of Sciences
- Published
- 2026-03-04
- Volume
- 123
- Issue
- 10
- Pages
- e2519941123-e2519941123
- ISSN
- 0027-8424 (ISSN-L)
- 1091-6490
- PMC
- PMC12974530
- OpenAlex
- W7133518443
- Semantic Scholar
- cf62c036ba481db69ca3896f867f052ad652005d
- Cited by
- 29
- References
- 82
- Citations by year
- 2026: 21
- FWCI
- 29.83
- Type
- journal article
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- Locations
- Proceedings of the National Academy of Sciences (publishedVersion, cc-by-nc-nd)
- PsyArXiv (OSF Preprints) (submittedVersion, cc-by)
- PubMed (publishedVersion)
- PubMed Central (publishedVersion, cc-by-nc-nd)
- Funders
- National Science Foundation (2439846)
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Ethics and Social Impacts of AI
- Life Sciences › Neuroscience › Cognitive Neuroscience › Psychology of Moral and Emotional Judgment
- Social Sciences › Psychology › Social Psychology › Cultural Differences and Values
- Keywords
- large language models, moral values, moral foundations, GPT, cultural bias in AI, Western bias
- MeSH terms
- Large Language Models, Generative Artificial Intelligence, Cross-Cultural Comparison, Humans, Morals, Stereotyping
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
