

The DOI matches its Crossref record; 22 of the 23 references it cites were found in a registry or an index.
Softermax: Hardware/Software Co-Design of an Efficient Softmax for Transformers
Open accessAbstract
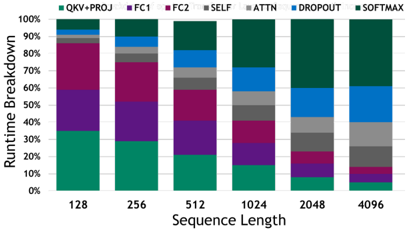
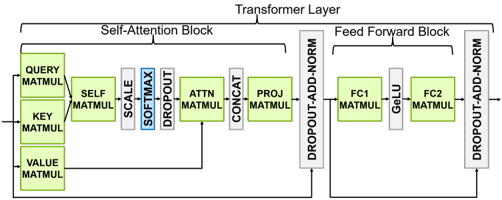
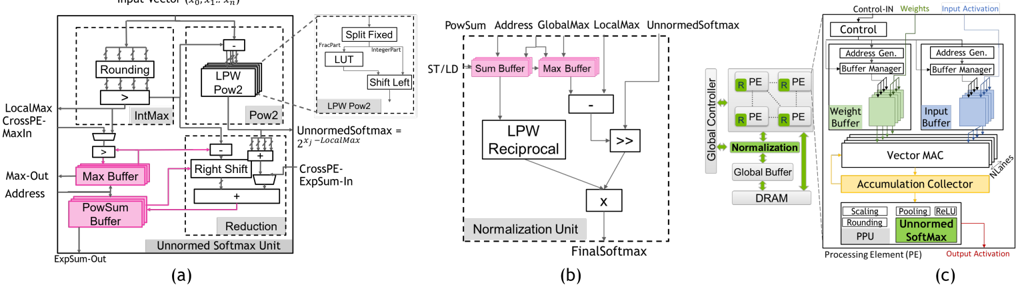
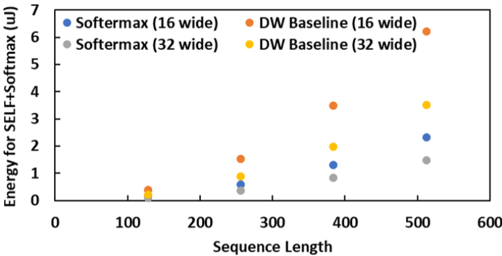
Transformers have transformed the field of natural language processing. Their superior performance is largely attributed to the use of stacked “self-attention” layers, each of which consists of matrix multiplies as well as softmax operations. As a result, unlike other neural networks, the softmax operation accounts for a significant fraction of the total run-time of Transformers. To address this, we propose Softermax, a hardware-friendly softmax design. Softermax consists of base replacement, low-precision softmax computations, and an online normalization calculation. We show Softermax results in 2.35x the energy efficiency at 0.90x the size of a comparable baseline, with negligible impact on network accuracy.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
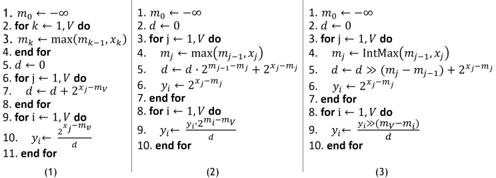
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Non-linear operations like Softmax, LayerNorm, and GELU, though less prevalent, present computational challenges on conventional hardware due to their complexity, potentially restricting the enhancement of end-to-end transformer inference [31].”
From Model Quantization and Hardware Acceleration for Vision Transformers: A Comprehensive Survey (2024) · cites this paper as [31]
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“A large portion of the inference time in ViT models is consumed by floating-point non-linear activations, normalizations, and the associated quantization and dequantization operations [31].”
From Model Quantization and Hardware Acceleration for Vision Transformers: A Comprehensive Survey (2024) · cites this paper as [31]
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“In addition, various approximation methods that hold floating-point arithmetic are presented [36, 50]; while they lower certain computational costs, they cannot meet the demands of integer arithmetic.”
From I-ViT: Integer-only Quantization for Efficient Vision Transformer Inference (2023) · cites this paper as [36]
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Due to the non-linearity, Softmax cannot follow the dyadic arithmetic pipeline discussed above, and the exponential arithmetic in Eq. 11 is typically unsupported by integer-only logic units [36].”
From I-ViT: Integer-only Quantization for Efficient Vision Transformer Inference (2023) · cites this paper as [36]
Experimental — accuracy not yet measured
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Vaswani, A., Shazeer, N., Parmar, N., Uszkoreit, J., Jones, L., Gomez, A. N., Kaiser, L., & Polosukhin, I. (2017) · arXiv · doi:10.48550/arxiv.1706.03762 · Cited by 120,404
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2018) · arXiv · doi:10.48550/arxiv.1810.04805 · Cited by 73,173
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2019) · Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers) · doi:10.18653/v1/n19-1423 · Cited by 54,325
An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale
Dosovitskiy, A., Beyer, L., Kolesnikov, A., Weissenborn, D., Zhai, X., Unterthiner, T., Dehghani, M., Minderer, M., Heigold, G., Gelly, S., et al. (2020) · arXiv · doi:10.48550/arxiv.2010.11929 · Cited by 47,472
Language Models are Few-Shot Learners
Brown, T. B., Mann, B., Ryder, N., Subbiah, M., Kaplan, J., Dhariwal, P., Neelakantan, A., Shyam, P., Sastry, G., Askell, A., et al. (2020) · arXiv · doi:10.48550/arxiv.2005.14165 · Cited by 23,372
DistilBERT, a distilled version of BERT: smaller, faster, cheaper and lighter
Sanh, V., Debut, L., Chaumond, J., & Wolf, T. (2019) · arXiv · doi:10.48550/arxiv.1910.01108 · Cited by 4,653
In-Datacenter Performance Analysis of a Tensor Processing Unit
Jouppi, N. P., Young, C., Patil, N., Patterson, D., Agrawal, G., Bajwa, R., Bates, S., Bhatia, S., Boden, N., Borchers, A., et al. (2017) · Proceedings of the 44th Annual International Symposium on Computer Architecture · doi:10.1145/3079856.3080246 · Cited by 4,537
HuggingFace's Transformers: State-of-the-art Natural Language Processing
Wolf, T., Debut, L., Sanh, V., Chaumond, J., Delangue, C., Moi, A., Cistac, P., Rault, T., Louf, R., Funtowicz, M., et al. (2019) · arXiv · doi:10.48550/arxiv.1910.03771 · Cited by 3,347
In-Datacenter Performance Analysis of a Tensor Processing Unit
Jouppi, N. P., Young, C., Patil, N. P., Patterson, D. A., Agrawal, G., Bajwa, R. S., Bates, S., Bhatia, S., Boden, N., Borchers, A., et al. (2017) · ACM SIGARCH Computer Architecture News · doi:10.1145/3140659.3080246 · Cited by 1,541
Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism
Shoeybi, M., Patwary, M., Puri, R., LeGresley, P., Casper, J., & Catanzaro, B. (2019) · arXiv · doi:10.48550/arxiv.1909.08053 · Cited by 893
Research works printed but not linked: 2
- 2017, Nvidia tesla v100 gpu architecture
- radford, 2019, Language models are unsupervised multitask learners, OpenAIRE blog, 1, 9
Cited by
Sorted by citations
Items 101–149 of 149
Kawamura, T., Masuda, Y., & Ishihara, T. (2025) · International Symposium on Quality Electronic Design (ISQED) · doi:10.1109/isqed65160.2025.11014475 · Cited by 1
An Accurate and Compact Design Integrating Seven Common Nonlinear Functions in Deep Learning
Wu, J. C., Hu, T.-W., Liang, C.-Y., & Huang, J.-D. (2025) · IEEE International Symposium on Circuits and Systems proceedings · doi:10.1109/iscas56072.2025.11043931 · Cited by 1
(2021) · ACM/IEEE Design Automation Conference (DAC) · doi:10.1109/dac18074.2021.9586157
Resource-saving Design Scheme Based on Look-Up Table for Activation Functions
Yuan, S. (2024) · International Conference on Neural Networks, Information and Communication Engineering (NNICE) · doi:10.1109/nnice61279.2024.10498949
Harmonia : A Unified Architecture for Efficient Deep Symbolic Regression
Ma, T., Wen, Y., Song, X., Jin, P., Huang, D., Han, H., Nan, Z., Yu, Z., Peng, S., Zhao, Y., et al. (2024) · IEEE Transactions on Computer-Aided Design of Integrated Circuits and Systems · doi:10.1109/tcad.2024.3443027
Efficient Inference of Transformers on Bare-Metal Devices with RISC-V Vector Processors
Huang, Y.-X., Huang, P., Lu, J., Lin, T., & Chen, T.-F. (2024) · IEEE Interregional NEWCAS Conference (NEWCAS) · doi:10.1109/newcas58973.2024.10666304
On the Design of Novel Attention Mechanism for Enhanced Efficiency of Transformers
Jha, S. K., Jha, S., Ewetz, R., & Velasquez, A. (2024) · ACM/IEEE Design Automation Conference (DAC) · doi:10.1145/3649329.3658253
A Streaming Transformer Accelerator with Efficient On-Chip Normalization
Zhao, N. B., Chen, J., Lv, J., Xie, C., Du, Y., & Du, L. (2024) · IEEE Asia Pacific Conference on Circuits and Systems (APCCAS) · doi:10.1109/apccas62602.2024.10808505
Chung, S., Kim, K., Rho, S., Kim, C., & Chung, K. (2024) · IEEE International Conference on Computer Design: VLSI in Computers and Processors (ICCD) · doi:10.1109/iccd63220.2024.00096
VEGA: Implementing a Versatile and Efficient Deep Learning Processor with Graph-Based ALU
Wang, W., Chen, Y., Huo, G., He, G., & Xu, N. (2024) · IEEE International Conference on Computer Design: VLSI in Computers and Processors (ICCD) · doi:10.1109/iccd63220.2024.00095 · Cited by 1
A High-Performance Approximate Softmax Architecture
Xu, W., Zhou, J., Yang, Y., Wang, L., Zhu, J., Teng, H., Wei, J., & Liu, G. (2024) · doi:10.1109/iccs62517.2024.10846441
Adaptive Decoding for Efficient Automatic Speech Recognition
Ma, X., Liu, P., Zhang, Y., Kou, K., Gao, C., Xiao, T., & Zhu, J. (2025) · IEEE International Conference on Acoustics Speech and Signal Processing · doi:10.1109/icassp49660.2025.10890369
He, L., Wang, Y., Huang, Z., Fan, S., Tang, C., Zhang, S., Lei, L., Yang, H., Liu, Y., & Jia, H. (2025) · IEEE Transactions on Computer-Aided Design of Integrated Circuits and Systems · doi:10.1109/tcad.2025.3561719
Minimizing transformer inference overhead using controlling element on Shenwei AI accelerator
Zhao, Y., Wu, C., Wang, Y., Zhang, L., Zhang, Y., Shen, W., Fan, H., Fang, H., Qin, Y., & Liu, X. (2025) · Frontiers of Information Technology & Electronic Engineering · doi:10.1631/fitee.2400453
GenAI at the Edge: Comprehensive Survey on Empowering Edge DevicesPreprint
Navardi, M., Aalishah, R., Fu, Y., Lin, Y., Li, H., Chen, Y., & Mohsenin, T. (2025) · Qeios · doi:10.1609/aaaiss.v5i1.35586 · Cited by 29
Dash, P., Jiang, A. A., & Dang, D. (2025) · ACM Great Lakes Symposium on VLSI (GLSVLSI) · doi:10.1145/3716368.3735220
MPN-S: An Algorithm-Hardware Co-Designed Architecture for High-Efficiency Softmax Computation
Ma, Y., Wu, D., Du, Y., Wang, X., Si, X., & Chen, C. (2025) · IEEE Transactions on Circuits & Systems II Express Briefs · doi:10.1109/tcsii.2025.3594105
High-Precision Softmax Division without Multipliers or Look-Up Tables
Park, J., & Rhee, C. E. (2025) · International Technical Conference on Circuits/Systems, Computers and Communications (ITC-CSCC) · doi:10.1109/itc-cscc66376.2025.11137704
Softprox: A Post-Finetuning Methodology to Mitigate Softmax Bottlenecks in Transformer Workloads
Parvathy, A. M., Roy, S., Ghosh, S. K., Raha, A., Mathaikutty, D. A., & Raghunathan, A. (2025) · IEEE transactions on circuits and systems for artificial intelligence. · doi:10.1109/tcasai.2025.3628250
Self-citationFPGA-Optimized Transformer Network Accelerator With Efficient Softmax and Sparsity-Aware Gating
Khan, M. I., & Cao, Y. (2025) · IEEE Embedded Systems Letters · doi:10.1109/les.2025.3640022
Kim, D., Sharma, T., Mukherjee, A., Mukherjee, M., & Roy, K. (2025) · International Symposium on Low Power Electronics and Design (ISLPED) · doi:10.1109/islped65674.2025.11261802
Narayanaswami, S. K., Srinivasan, G., & Ravindran, B. (2025) · International Symposium on Low Power Electronics and Design (ISLPED) · doi:10.1109/islped65674.2025.11261772
Integer Quantization of Nonlinear Operations towards Hardware-Friendly ViTs
Sun, T., Ma, T., Liu, J., Li, Z., Li, Q., Wang, Y., Liu, H., & Liu, S. (2025) · IEEE International Conference on Electronics, Circuits and Systems (ICECS) · doi:10.1109/icecs66544.2025.11270824
Du, H., Wen, C., Chen, Z., Zhang, L., Sun, Q. L., Yan, Z., & Zhuo, C. (2025) · IEEE Transactions on Computer-Aided Design of Integrated Circuits and Systems · doi:10.1109/tcad.2025.3642737
Zhao, Z., Li, H., Liu, F., Lu, Y., Wang, Z., Yang, T., Jiang, L., & Guan, H. (2025) · doi:10.1109/iccad66269.2025.11240736 · Cited by 5
Li, Z., Li, Y., Lai, M., Liu, P., Wang, Q., Zhao, Y., Li, H., & Qi, X. (2025) · IEEE International Conference on Computer Design: VLSI in Computers and Processors (ICCD) · doi:10.1109/iccd65941.2025.00020
SUSTAINPHOT: Sustainable Large-Scale AI Training Using Analog Silicon Photonic Accelerators
Dang, D. (2025) · IEEE International Conference on Computer Design: VLSI in Computers and Processors (ICCD) · doi:10.1109/iccd65941.2025.00125
Optimization of SmoothQuant Methods for Large Language Models
Wang, D., Song, H., Liu, Y., & Yin, Z. (2025) · International Conference on Artificial Intelligence and Computer Engineering (ICAICE) · doi:10.1109/icaice68195.2025.11382356
Holla, A., Mukherjee, M., Mukherjee, A., & Roy, K. (2026) · IEEE Journal on Emerging and Selected Topics in Circuits and Systems · doi:10.1109/jetcas.2026.3665635
CLCO-S1: Efficient Softmax1 Architecture of Cross Level Collaborative Optimization for Transformer
Chen, Y., Geng, H., Liu, C., & Du, L. (2025) · IEEE Asia Pacific Conference on Circuits and Systems (APCCAS) · doi:10.1109/apccas67402.2025.11376624
Yue, Z., Xiang, X., Fu, J., Wei, S., Wang, Y., Hu, Y., & Yin, S. (2026) · Digest of technical papers/Digest of technical papers - IEEE International Solid-State Circuits Conference · doi:10.1109/isscc49663.2026.11409075
Lim, S., Kim, J.-H., Moon, S., Cha, J., Seo, D., Kim, J., Lee, H., Lee, J., & Kim, J. (2026) · IEEE Journal of Solid-State Circuits · doi:10.1109/jssc.2026.3663603
A High-Parallelism Softmax Hardware-Software Co-Design for Fast and Efficient LLM Inference
Wen, C., Du, H., He, X., Yan, Z., Sun, Q., & Zhuo, C. (2026) · ACM Transactions on Design Automation of Electronic Systems · doi:10.1145/3801553
Zhang, Q., Fan, Z., Abillama, P., Shoouri, S., Lee, J., Tseng, C.-W., Lee, C., Meng, W., Kim, H.-S., Blaauw, D., et al. (2026) · IEEE Journal of Solid-State Circuits · doi:10.1109/jssc.2026.3669815 · Cited by 1
Low-power AI and signal processing for the edge: tools, techniques, and applications
Badawy, W. M. (2026) · Neural Computing and Applications · doi:10.1007/s00521-026-11936-0
Liu, Y., Zhang, B., Yin, J., Huang, W., Guan, Z., Zhao, W. S., Zhang, D., & Zeng, L. (2026) · IEEE Electron Device Letters · doi:10.1109/led.2026.3691358
Tang, C., Lin, X., Huang, Z., Sun, W., Jia, H., & Liu, Y. (2026) · IEEE Transactions on Circuits and Systems I Regular Papers · doi:10.1109/tcsi.2026.3697149
FLARE: Finetuning ReLU With FIRE for Efficient Long-Context Inference
Moffatt, M., Luo, J., Cheng, H., Wang, Q., Jiang, X., Tao, G., Liu, S., Lei, K., Kielian, G., & Saligane, M. (2026) · Design, Automation, and Test in Europe · doi:10.23919/date69613.2026.11539302
Wang, X., Chen, T., Zhang, X., Liang, S., Yang, Y., Ding, W., & Pan, B. (2026) · IEEE International Symposium on Circuits and Systems proceedings · doi:10.1109/iscas66217.2026.11562939
Neural Quantization-Aware Piecewise Linear Approximation for Nonlinear Functions on FPGA
Zeng, F., Li, C., Li, R., Guan, J., Lai, R., & Zhu, Z. (2026) · IEEE International Symposium on Circuits and Systems proceedings · doi:10.1109/iscas66217.2026.11562458
I/O-Aware PIM Acceleration for Long-Sequence LLM Inference with Hybrid Sparse Attention
Lu, X., Hu, L., Huang, H., Jiang, P., & Sun, X. (2026) · IEEE International Parallel and Distributed Processing Symposium (IPDPS) · doi:10.1109/ipdps65963.2026.00046
A Custom Hardware Accelerator for Softmax Function With Parallel Online Normalization
Shareefa Fairoose, P., & Mishra, A. (2026) · IEEE Transactions on Very Large Scale Integration (VLSI) Systems · doi:10.1109/tvlsi.2026.3706101
Ghabeli, H., & Molahosseini, A. S. (2025) · International Conference on Information and Knowledge Technology (IKT) · doi:10.1109/ikt69652.2025.11626766
A Hierarchical Adaptive Posit-CIM Architecture for Edge Transformer Inference
Liu, X., Liu, C., Wang, J., & Shen, L. (2026) · Lecture notes in computer science · doi:10.1007/978-981-92-4805-6_24
Wei, K., Kusaka, T., & Tanaka, T. (2026) · Electronics · doi:10.3390/electronics15174014
A Multi-Role Unified Buffer Architecture for an On-Device Vision Transformer Accelerator
Park, W., Park, S., & Kim, H. (2026) · IEEE Access · doi:10.1109/access.2026.3734515
FPGA-Based Softmax Approximation: Analytical Cost–Error Modeling and Pareto Optimization
Djellouli, M., Zarei, A., Mahabub, A., Bendaoudi, H., & Vakili, S. (2026) · IEEE Open Journal of Circuits and Systems · doi:10.1109/ojcas.2026.3731578
Bhoyar, D. M. R. (2026) · Advances in computational intelligence and robotics book series · doi:10.4018/979-8-2600-0685-6.ch004
UniNL: Unifying Fragmented Non-Linear Operators for Efficient Edge LLM Inference
Hu, Z. H., Fan, Z., Qin, S., Mu, Y., Li, W., & Ye, X. (2026) · ACM/IEEE Design Automation Conference (DAC) · doi:10.1145/3770743.3806382
Metadata
- Authors
- Stevens, J. R., Venkatesan, R., Dai, S., Khailany, B., & Raghunathan, A.
- Affiliations
- Purdue University West Lafayette (US)
- Nvidia (United Kingdom) (GB)
- Venue
- 2021 58th ACM/IEEE Design Automation Conference (DAC)
- Publisher
- IEEE
- Published
- 2021-12-05
- Pages
- 469-474
- ISSN
- 0738-100X (ISSN-L)
- OpenAlex
- W3137649401
- Cited by
- 148
- References
- 23
- Citations by year
- 2026: 22 · 2025: 68 · 2024: 35 · 2023: 16 · 2022: 5 · 2021: 2
- FWCI
- 4.74
- Type
- conference paper
- Language
- en
- Open access
- green
- arxiv.org
- Licence
- Locations
- ACM/IEEE Design Automation Conference (DAC) (publishedVersion)
- arXiv (Cornell University) (submittedVersion, cc-by-nc-nd)
- arXiv (Cornell University) (submittedVersion)
- arXiv (Cornell University)
- Topics
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Advanced Neural Network Applications
- Physical Sciences › Computer Science › Hardware and Architecture › Parallel Computing and Optimization Techniques
- Physical Sciences › Engineering › Electrical and Electronic Engineering › Low-power high-performance VLSI design
- Keywords
- softmax, transformer models, hardware-software co-design, self-attention, low-precision arithmetic, energy efficiency, neural network acceleration
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
