

MS-TCN++: Multi-Stage Temporal Convolutional Network for Action Segmentation
The DOI matches its Crossref record, with a small difference in title or year; 56 of the 60 references it cites were found in a registry or an index; 4 of the 14 sources its claims cite were checked for support.
Abstract
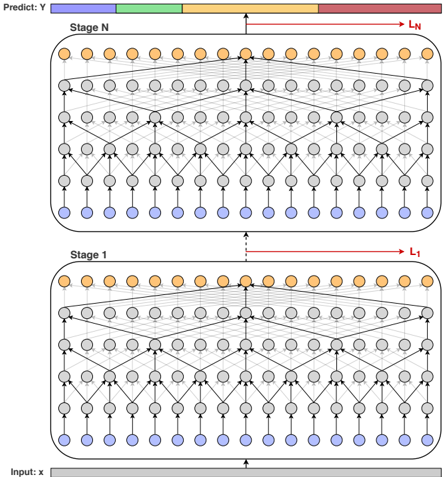
With the success of deep learning in classifying short trimmed videos, more attention has been focused on temporally segmenting and classifying activities in long untrimmed videos. State-of-the-art approaches for action segmentation utilize several layers of temporal convolution and temporal pooling. Despite the capabilities of these approaches in capturing temporal dependencies, their predictions suffer from over-segmentation errors. In this paper, we propose a multi-stage architecture for the temporal action segmentation task that overcomes the limitations of the previous approaches. The first stage generates an initial prediction that is refined by the next ones. In each stage we stack several layers of dilated temporal convolutions covering a large receptive field with few parameters. While this architecture already performs well, lower layers still suffer from a small receptive field. To address this limitation, we propose a dual dilated layer that combines both large and small receptive fields. We further decouple the design of the first stage from the refining stages to address the different requirements of these stages. Extensive evaluation shows the effectiveness of the proposed model in capturing long-range dependencies and recognizing action segments. Our models achieve state-of-the-art results on three datasets: 50Salads, Georgia Tech Egocentric Activities (GTEA), and the Breakfast dataset.
Overview
CoChat Summary
TL;DR
The paper introduces MS-TCN, a multi-stage temporal convolutional network for fully supervised temporal action segmentation that operates at full temporal resolution and refines predictions stage by stage, trained with a combined cross-entropy and truncated-MSE smoothing loss. It reports state-of-the-art results on 50Salads, GTEA, and Breakfast.
Key findings
- The multi-stage architecture substantially outperforms a single-stage TCN of equal parameter count (48 layers) on 50Salads: F1@{10,25,50} of 76.3/74.0/64.5 vs 49.0/46.4/40.2, Edit 67.9 vs 40.7, Acc 80.7 vs 78.0 — a margin of up to 27%.
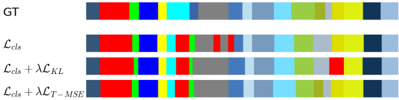
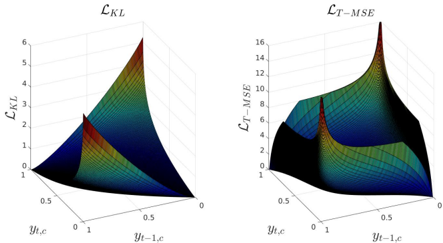
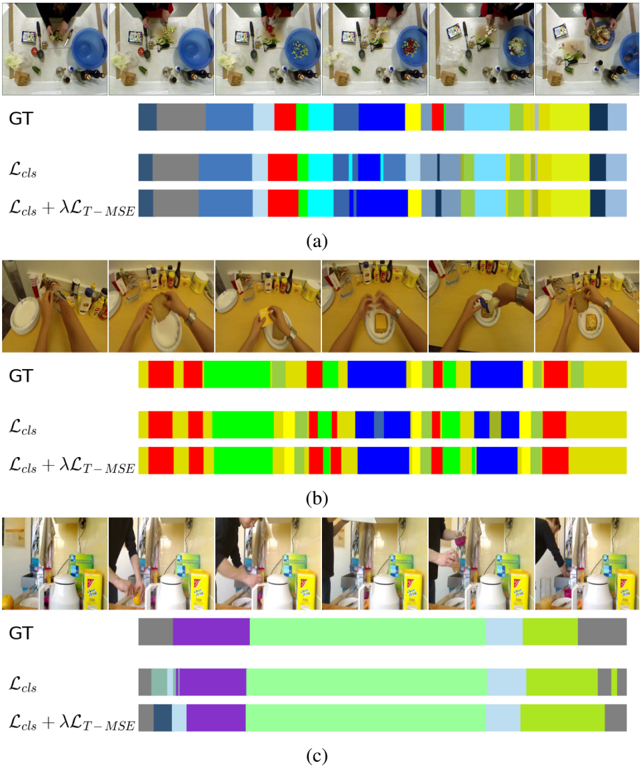
- The proposed smoothing loss improves over cross-entropy alone on 50Salads: L_cls gives F1@{10,25,50} 71.3/69.7/60.7, Edit 64.2, Acc 79.9, while L_cls + λL_T-MSE gives 76.3/74.0/64.5, Edit 67.9, Acc 80.7 (an absolute F1/edit improvement of ~5%); it also beats a KL-divergence smoothing loss (71.9/69.3/60.1, Edit 64.6, Acc 80.2).
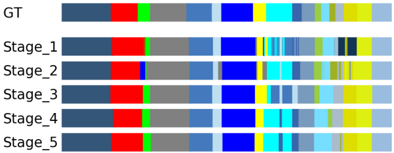
- Four stages is optimal; adding a fifth degrades performance (F1@10 76.4 but F1@25/50 drop to 73.4/63.6 and Acc to 79.5), attributed to over-fitting from more parameters.
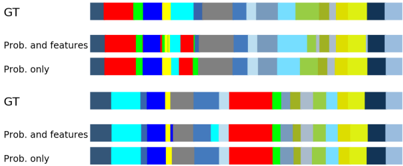
- Concatenating features to the input probabilities of higher stages causes a large drop (F1@10 56.2 vs 76.3, Edit 47.6 vs 67.9, ~20% drop), so only probabilities are passed.
- The model outperforms state-of-the-art methods on all three datasets, with up to 12.6% improvement in frame-wise accuracy on 50Salads; on GTEA with fine-tuning it reaches F1@{10,25,50} 87.5/85.4/74.6, Edit 81.4, Acc 79.2.
Methods
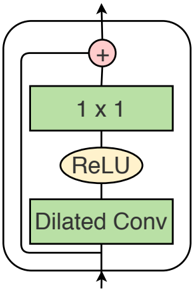
- Architecture: a single-stage TCN of dilated 1D convolutions (kernel size 3, acausal, dilation doubled per layer 1–512, residual connections, no pooling or fully connected layers), stacked into a multi-stage model where each stage refines the previous stage's frame-wise probabilities; implementation uses 4 stages, 10 dilated layers per stage, 64 filters, dropout, Adam with learning rate 0.0005.
- Loss: sum over stages of a per-stage loss combining cross-entropy classification loss and a truncated mean squared error smoothing loss over frame-wise log-probabilities, with τ = 4 and λ = 0.15.
- Data and evaluation: I3D features at 15 fps on 50Salads (50 videos, 17 classes, 5-fold cross-validation), GTEA (28 videos, 11 classes, leave-one-subject-out), and Breakfast (1,712 videos, 48 actions, standard 4 splits); metrics are frame-wise accuracy, segmental edit distance, and segmental F1 at IoU thresholds 10%, 25%, 50%.
Limitations
- Stated: the weakly supervised setting is explicitly out of scope ("the weakly supervised case is beyond the scope of this paper"); performance is slightly worse on longer videos due to the limited receptive field (GTEA ≥1.5 min: F1@10 81.2, Edit 71.8, Acc 75.9 vs <1 min: 89.6, 82.5, 76.6); a fifth stage degrades results, possibly from over-fitting.
- Evident from the text: evaluation is confined to cooking/egocentric activity datasets (50Salads, GTEA, Breakfast), so generalization to other domains is untested; the model is fully supervised and requires frame-level annotations.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
3 Valid · 1 Not valid · 5 Not checked · 71 Own results and interpretations
The sources with a verdict support this claim; the rest weren’t checked yet, have no full text we could read, or their verdicts aren’t rated yet.
In the paper
“Our model achieves state-of-the-art results on three challenging datasets: 50Salads, Georgia Tech Egocentric Activities (GTEA), and the Breakfast dataset.”
- Also stated in: § 1. Introduction · plain
“Our approach achieves state-of-the-art results on three challenging benchmarks for action segmentation: 50Salads [25], Georgia Tech Egocentric Activities (GTEA) [8], and the Breakfast dataset [12].”
What the sources say
- Not checked — no full text of the sourcecites [25] [25] Sebastian Stein and Stephen J McKenna. Combining embedded accelerometers with computer vision for recognizing food preparation activities. In ACM International Joint Conference on Pervasive and Ubiquitous Computing , pages 729-738, 2013. - source
- Supportedcites [8] [8] Alireza Fathi, Xiaofeng Ren, and James M Rehg. Learning to recognize objects in egocentric activities. In IEEE Conference on Computer Vision and Pattern Recognition (CVPR) , pages 3281-3288, 2011. - source
The citation identifies the GTEA dataset, not the citing authors’ own model or its results. Section 5.1 describes the paper’s egocentric daily-activity dataset, and the Conclusion identifies its release as GTEA. No page numbers are available in our copy. (LLM, conf=0.88)
- Not checked — no full text of the sourcecites [12] [12] Hilde Kuehne, Ali Arslan, and Thomas Serre. The language of actions: Recovering the syntax and semantics of goaldirected human activities. In IEEE Conference on Computer Vision and Pattern Recognition (CVPR) , pages 780787, 2014. - source
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Rests on an assumption not shown here.
- Also stated in: § 1. Introduction · plain
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“As shown in the table, all of these models achieve a comparable frame-wise accuracy.”
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Extensive evaluation on three datasets shows the effectiveness of our model in capturing long range dependencies between action classes and producing high quality predictions.”
boosted- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper states — it cites no source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“This architecture is trained using a combination of a classification loss and a proposed smoothing loss that penalizes over-segmentation errors.”
- Also stated in: § 1. Introduction · plain
“we further employ a smoothing loss during training which penalizes over-segmentation errors in the predictions.”
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Also stated in: § 1. Introduction · plain
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“As shown in Table 4, the impact of λ is very small on the performance.”
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
45 more claims
Create a free account to see all 80 claims and every source verdict.
- Probably not a substantial claim. 8
- Borderline: one of the tests for a substantial claim is unclear. 1
- It may state two separate claims as one. 22
Citations
Cites
Deep Residual Learning for Image Recognition
He, K., Zhang, X., Ren, S., & Sun, J. (2016) · 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2016.90 · Cited by 235,474
U-Net: Convolutional Networks for Biomedical Image Segmentation
Ronneberger, O., Fischer, P., & Brox, T. (2015) · Lecture notes in computer science · doi:10.1007/978-3-319-24574-4_28 · Cited by 99,404
Feature Pyramid Networks for Object Detection
Lin, T.-Y., Dollar, P., Girshick, R., He, K., Hariharan, B., & Belongie, S. (2017) · 2017 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2017.106 · Cited by 30,939 · cited 4×
“While the dual dilated layer combines local and global context from the input sequence, there are other techniques in the literature for fusing multi-scale features like feature pyramid networks (FPN) [47].”
BackgroundInfluentialQuo Vadis, Action Recognition? A New Model and the Kinetics Dataset
Carreira, J., & Zisserman, A. (2017) · Computer Vision and Pattern Recognition · doi:10.48550/arxiv.1705.07750 · Cited by 10,485
Quo Vadis, Action Recognition? A New Model and the Kinetics Dataset
Carreira, J., & Zisserman, A. (2017) · 2017 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2017.502 · Cited by 9,570 · cited 7×
“Most of the efforts, however, have been focused on classifying short trimmed videos [1], [2], [3], [4].”
BackgroundMethodInfluentialTwo-Stream Convolutional Networks for Action Recognition in Videos
Simonyan, K., & Zisserman, A. (2014) · arXiv · doi:10.48550/arxiv.1406.2199 · Cited by 6,756 · cited 1×
“Most of the efforts, however, have been focused on classifying short trimmed videos [1], [2], [3], [4].”
BackgroundStacked Hourglass Networks for Human Pose Estimation
Newell, A., Yang, K., & Deng, J. (2016) · Lecture Notes in Computer Science · doi:10.1007/978-3-319-46484-8_29 · Cited by 5,634 · cited 1×
“Stacking several predictors sequentially has shown significant improvements in many tasks like human pose estimation [44], [45], [46].”
BackgroundWaveNet: a generative model for raw audio
Oord, A. V. D., Dieleman, S., Zen, H., Simonyan, K., Vinyals, O., Graves, A., Kalchbrenner, N., Senior, A., & Kavukcuoglu, K. (2016) · arXiv · doi:10.48550/arxiv.1609.03499 · Cited by 4,911
SlowFast Networks for Video Recognition
Feichtenhofer, C., Fan, H., Malik, J., & He, K. (2019) · 2019 IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv.2019.00630 · Cited by 4,007 · cited 1×
“Most of the efforts, however, have been focused on classifying short trimmed videos [1], [2], [3], [4].”
BackgroundRes2Net: A New Multi-Scale Backbone Architecture
Gao, S.-H., Cheng, M.-M., Zhao, K., Zhang, X.-Y., Yang, M.-H., & Torr, P. (2021) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2019.2938758 · Cited by 3,385 · cited 1×
“Multi-scale information is important for speech synthesis [29] and image recognition [30].”
BackgroundSelf-citation
Research works printed but not linked: 1
- [11] Svebor Karaman, Lorenzo Seidenari, and Alberto Del Bimbo. Fast saliency based pooling of fisher encoded dense trajectories. In European Conference on Computer Vision (ECCV), THUMOS Workshop , 2014. -
Cited by
Items 101–200 of 349
Park, M., Oh, S., Jeong, T. T., & Yu, S. (2022) · Diagnostics · doi:10.3390/diagnostics13010107 · Cited by 14
MV-TAL: Mulit-view Temporal Action Localization in Naturalistic Driving
Li, W., Chen, S., Gu, J., Wang, N., Chen, C., & Guo, Y. (2022) · IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops (CVPRW) · doi:10.1109/cvprw56347.2022.00366 · Cited by 9
Video Action Segmentation via Contextually Refined Temporal Keypoints
Jiang, B., Jin, Y., Tan, Z., & Mu, Y. (2023) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv51070.2023.01272 · Cited by 18
Zero-shot prompt-based video encoder for surgical gesture recognition
Rao, M., Qin, Y., Kolouri, S., Wu, J. Y., & Moyer, D. (2024) · International Journal of Computer Assisted Radiology and Surgery · doi:10.1007/s11548-024-03257-1 · Cited by 12
Xu, A., & Zheng, W. (2024) · Computer Vision and Pattern Recognition · doi:10.1109/cvpr52733.2024.01728 · Cited by 20
Language-Assisted Skeleton Action Understanding for Skeleton-Based Temporal Action Segmentation
Ji, H., Chen, B., Xu, X., Ren, W., Wang, Z., & Liu, H. (2024) · Lecture notes in computer science · doi:10.1007/978-3-031-72949-2_23 · Cited by 21
Improving Audio Anomalies Recognition Using Temporal Convolutional Attention Networks
Huang, Q., & Hain, T. (2021) · IEEE International Conference on Acoustics Speech and Signal Processing · doi:10.1109/icassp39728.2021.9414611 · Cited by 16
MCFM: Mutual Cross Fusion Module for Intermediate Fusion-Based Action Segmentation
Ishihara, K., Nakano, G., & Inoshita, T. (2022) · Proceedings - International Conference on Image Processing · doi:10.1109/icip46576.2022.9897444 · Cited by 12
Measurement and prediction of subway resilience under rainfall events: An environment perspective
Gao, W., Lu, Y., Wang, N., Cheng, G., Qiu, Z., & Hu, X. (2024) · Transportation Research Part D Transport and Environment · doi:10.1016/j.trd.2024.104479 · Cited by 15
Ahmed, M., Chen, J., Akpaku, E., & Sosu, R. N. A. (2025) · Computer Networks · doi:10.1016/j.comnet.2025.111147 · Cited by 13
UnweaveNet: Unweaving Activity Stories
Price, W., Vondrick, C., & Damen, D. (2022) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52688.2022.01340 · Cited by 16
Dual-Path Hybrid Attention Network for Monaural Speech Separation
Qiu, W., & Hu, Y. (2022) · IEEE Access · doi:10.1109/access.2022.3193245 · Cited by 10
Combining long and short spatiotemporal reasoning for deep reinforcement learning
Liu, P., Liu, P., & Bai, C. (2024) · Neurocomputing · doi:10.1016/j.neucom.2024.129165 · Cited by 11
DConv-LSTM-Net: A Novel Architecture for Single- and 12-Lead ECG Anomaly Detection
Dissanayake, T., Fernando, T., Denman, S., Sridharan, S., & Fookes, C. (2023) · IEEE Sensors Journal · doi:10.1109/jsen.2023.3300752 · Cited by 8
Reducing the Label Bias for Timestamp Supervised Temporal Action Segmentation
Liu, K., Li, Y., Liu, S., Tan, C., & Shao, Z. (2023) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52729.2023.00629 · Cited by 16
Liu, Y., Zhong, X., Zhai, S., Du, Z., Gao, Z., Huang, Q., Zhang, C. Y., Jiang, B., Pandey, V. K., Han, S., et al. (2023) · Computers in Biology and Medicine · doi:10.1016/j.compbiomed.2023.107672 · Cited by 10
Self-citationLu, Z., Cheng, Z., & Yang, T.-Y. (2020) · Computational Intelligence and Neuroscience · doi:10.1155/2020/8882279 · Cited by 13
Depthwise Separable Temporal Convolutional Network for Action Segmentation
Hampiholi, B., Jarvers, C., Mader, W., & Neumann, H. (2020) · International Conference on 3D Vision (3DV) · doi:10.1109/3dv50981.2020.00073 · Cited by 14
Using open surgery simulation kinematic data for tool and gesture recognition
Goldbraikh, A., Volk, T., Pugh, C. M., & Laufer, S. (2022) · International Journal of Computer Assisted Radiology and Surgery · doi:10.1007/s11548-022-02615-1 · Cited by 16
Sayed, S., Ghoddoosian, R., Trivedi, B., & Athitsos, V. (2023) · IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops (CVPRW) · doi:10.1109/cvprw59228.2023.00315 · Cited by 16
Multi-Stage Learning for Radar Pulse Activity Segmentation
Huang, Z., Pemasiri, A., Denman, S., et al. (2024) · IEEE International Conference on Acoustics Speech and Signal Processing · doi:10.1109/icassp48485.2024.10445810 · Cited by 8
CrossVideo: Self-supervised Cross-modal Contrastive Learning for Point Cloud Video Understanding
Liu, Y., Chen, C., Wang, Z., & Yi, L. (2024) · Proceedings - IEEE International Conference on Robotics and Automation/Proceedings · doi:10.1109/icra57147.2024.10610376 · Cited by 16
Self-citationTwo-Stage Active Learning for Efficient Temporal Action Segmentation
Su, Y., & Elhamifar, E. (2024) · Lecture notes in computer science · doi:10.1007/978-3-031-72970-6_10 · Cited by 15
R-ATCN: continuous human activity recognition using FMCW radar with temporal convolutional networks
Chen, J., Gu, M., & Lin, Z. (2024) · Measurement Science and Technology · doi:10.1088/1361-6501/ad9622 · Cited by 9
Feng, Z., Zhou, T., & Han, T. (2025) · IEEE Journal of Biomedical and Health Informatics · doi:10.1109/jbhi.2025.3546019 · Cited by 12
Multi-modal temporal action segmentation for manufacturing scenarios
Romeo, L., Marani, R., Perri, A. G., & Gall, J. (2025) · Engineering Applications of Artificial Intelligence · doi:10.1016/j.engappai.2025.110320 · Cited by 12
Self-citationShuvo, M. R., Mekala, M. S., & Elyan, E. (2025) · Cognitive Computation · doi:10.1007/s12559-025-10513-2 · Cited by 17
Timestamp-Supervised Action Segmentation from the Perspective of Clustering
Du, D., Li, E., Si, L., Xu, F., & Sun, F. (2023) · International Joint Conference on Artificial Intelligence · doi:10.24963/ijcai.2023/77 · Cited by 13
Action Segmentation Using 2D Skeleton Heatmaps and Multi-Modality Fusion
Hyder, S. W., Usama, M., Zafar, A., Naufil, M., Fateh, F. J., Konin, A., Zia, M. Z., & Tran, Q.-H. (2024) · Proceedings - IEEE International Conference on Robotics and Automation/Proceedings · doi:10.1109/icra57147.2024.10610644 · Cited by 15
Luo, D., Wang, Y., Yue, A., & Xu, H. (2022) · ACM International Conference on Multimedia (ACM MM) · doi:10.1145/3503161.3548067 · Cited by 13
Intra- and Inter-Action Understanding via Temporal Action ParsingPreprint
Shao, D., Zhao, Y., Dai, B., & Lin, D.-H. (2020) · Computer Vision and Pattern Recognition · doi:10.48550/arxiv.2005.10229 · Cited by 119
Lane Change Intention Recognition and Vehicle Status Prediction for Autonomous VehiclesPreprint
Yuan, R., Abdel-Aty, M. A., Gu, X., et al. (2023) · SSRN Electronic Journal · doi:10.2139/ssrn.4511705 · Cited by 8
Diffused Fourier Network for Video Action Segmentation
Jiang, B., & Mu, Y. (2023) · ACM International Conference on Multimedia (ACM MM) · doi:10.1145/3581783.3611842 · Cited by 10
HOI-aware Adaptive Network for Weakly-supervised Action Segmentation
Zhang, R., Wang, S., Duan, Y., Tang, Y., Zhang, Y., & Tan, Y. (2023) · International Joint Conference on Artificial Intelligence · doi:10.24963/ijcai.2023/191 · Cited by 12
Markov Game Video Augmentation for Action Segmentation
Aziere, N., & Todorović, S. (2023) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv51070.2023.01242 · Cited by 9
Random Walks for Temporal Action Segmentation with Timestamp Supervision
Hirsch, R., Cohen, R., Golany, T., Freedman, D., & Rivlin, E. (2024) · IEEE Workshop/Winter Conference on Applications of Computer Vision · doi:10.1109/wacv57701.2024.00648 · Cited by 4
Goldbraikh, A., Shubi, O., Rubin, O., Pugh, C. M., & Laufer, S. (2024) · Pattern Recognition · doi:10.1016/j.patcog.2024.110778 · Cited by 12
Extra-abdominal trocar and instrument detection for enhanced surgical workflow understanding
Jurosch, F., Wagner, L., Jell, A., Islertas, E., Wilhelm, D., & Berlet, M. (2024) · International Journal of Computer Assisted Radiology and Surgery · doi:10.1007/s11548-024-03220-0 · Cited by 7
Sense understanding of text conversation using temporal convolution neural network
Rathor, S., & Agrawal, S. (2022) · Multimedia Tools and Applications · doi:10.1007/s11042-022-12090-0 · Cited by 7
Turning to a Teacher for Timestamp Supervised Temporal Action Segmentation
Zhao, Y., & Song, Y. (2022) · IEEE International Conference on Multimedia and Expo · doi:10.1109/icme52920.2022.9859626 · Cited by 7
Facial Tic Detection in Untrimmed Videos of Tourette Syndrome Patients
Tang, Y., Béjar, B., Essoe, J. K.-Y., Mcguire, J. F., & Vidal, R. (2022) · Proceedings - International Conference on Pattern Recognition/Proceedings/International Conference on Pattern Recognition · doi:10.1109/icpr56361.2022.9956140 · Cited by 9
Mujtaba, G., Khowaja, S. A., Jarwar, M. A., Choi, J., & Ryu, E. (2023) · IEEE Transactions on Big Data · doi:10.1109/tbdata.2023.3338012 · Cited by 7
Quantifying impairment and disease severity using AI models trained on healthy subjects
Yu, B., Kaku, A., Liu, K., Parnandi, A., Fokas, E. E., Venkatesan, A., Pandit, N. G., Ranganath, R., Schambra, H. M., & Fernandez‐Granda, C. (2024) · npj Digital Medicine · doi:10.1038/s41746-024-01173-x · Cited by 10
Alowonou, K. C., & Han, J.-H. (2024) · IEEE Access · doi:10.1109/access.2024.3520172 · Cited by 9
A Comprehensive Survey of Advancement in Lip Reading Models: Techniques and Future Directions
Deshpande, S., Shirsath, K., Pashte, A., Loya, P., Shingade, S., & Sambhe, V. (2025) · IET Image Processing · doi:10.1049/ipr2.70095 · Cited by 10
Action recognition: A comprehensive survey of tasks, methods, and challenges
Heo, S., Moon, J., & Jung, S. K. (2025) · ICT Express · doi:10.1016/j.icte.2025.11.015 · Cited by 12
Multi-Modal Few-Shot Temporal Action Segmentation
Lu, Z., & Elhamifar, E. (2025) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv51701.2025.01309 · Cited by 6
The BRIO-TA Dataset: Understanding Anomalous Assembly Process in Manufacturing
Moriwaki, K., Nakano, G., & Inoshita, T. (2022) · Proceedings - International Conference on Image Processing · doi:10.1109/icip46576.2022.9897369 · Cited by 6
Global–local multi-stage temporal convolutional network for cataract surgery phase recognition
Fang, L., Mou, L., Gu, Y., Hu, Y., Chen, B., Chen, X., Wang, Y., Liu, J., & Zhao, Y. (2022) · BioMedical Engineering OnLine · doi:10.1186/s12938-022-01048-w · Cited by 13
SG-TCN: Semantic Guidance Temporal Convolutional Network for Action Segmentation
Zhang, Y., Ren, K., Zhang, C., & Yan, T. (2022) · International Joint Conference on Neural Networks (IJCNN) · doi:10.1109/ijcnn55064.2022.9891932 · Cited by 8
U-Transformer-based multi-levels refinement for weakly supervised action segmentation
Ke, X., Miao, X., & Guo, W. (2023) · Pattern Recognition · doi:10.1016/j.patcog.2023.110199 · Cited by 7
Chen, W., Fan, H., Jiang, Q., Huang, C., & Yang, Y. (2024) · ACM International Conference on Multimedia (ACM MM) · doi:10.1145/3664647.3680687 · Cited by 5
Li, X., Ban, X., Qiao, H., Yuan, Z., Dai, H., Zhao, Y., Guo, Y., Obaidat, M. S., & Huang, G. Q. (2025) · IEEE/CAA Journal of Automatica Sinica · doi:10.1109/jas.2025.125117 · Cited by 6
Snippet-Aware Transformer With Multiple Action Elements for Skeleton-Based Action Segmentation
Ji, H., Chen, B., Huang, W., Ren, W., Wang, Z., & Liu, H. (2025) · IEEE Transactions on Neural Networks and Learning Systems · doi:10.1109/tnnls.2025.3563025 · Cited by 9
The Object at Hand: Automated Editing for Mixed Reality Video Guidance from Hand-Object Interactions
Lu, Y., & Mayol-Cuevas, W. W. (2021) · Proceedings - International Symposium on Mixed and Augmented Reality, ISMAR · doi:10.1109/ismar52148.2021.00023 · Cited by 7
Efficient Two-Stream Network for Online Video Action Segmentation
Kang, M., Park, R., & Park, H. (2022) · IEEE Access · doi:10.1109/access.2022.3201208 · Cited by 9
Deep-Cogn: Skeleton-based Human Action Recognition for Cognitive Behavior Assessment
Elmi, S., Bell, M. D., & Tan, K. (2022) · IEEE International Conference on Tools with Artificial Intelligence (ICTAI) · doi:10.1109/ictai56018.2022.00107 · Cited by 8
CMS-net: Edge-aware multimodal MRI feature fusion for brain tumor segmentation
Lv, C., Li, B., Wang, X., Cai, P., Yang, B., Jia, X., & Yan, J. (2025) · Image and Vision Computing · doi:10.1016/j.imavis.2025.105481 · Cited by 6
Mao, Z., Das, A., Khan, D. Z., et al. (2025) · International Journal of Computer Assisted Radiology and Surgery · doi:10.1007/s11548-025-03369-2 · Cited by 5
Alharthi, A. S. (2026) · Mathematics · doi:10.3390/math14020230 · Cited by 8
ASQuery: A Query-based Model for Action Segmentation
Gan, Z., Jin, L., Nie, L., Wang, Z., Zhou, L., Li, L., Wang, Z., Li, J., Xing, J., & Zhao, J. C. (2024) · IEEE International Conference on Multimedia and Expo (ICME) · doi:10.1109/icme57554.2024.10687535 · Cited by 5
FineBio: A Fine-Grained Video Dataset of Biological Experiments with Hierarchical Annotation
Yagi, T., Ohashi, M., Huang, Y., Furuta, R., Adachi, S., Mitsuyama, T., & Sato, Y. (2025) · International Journal of Computer Vision · doi:10.1007/s11263-025-02523-2 · Cited by 16
AutoENP: An Auto Rating Pipeline for Expressing Needs via Pointing Protocol
Chen, B., Ren, W., Liu, H., Li, H., Xu, X., Zhou, B., & Xu, Q. (2022) · Proceedings - International Conference on Pattern Recognition/Proceedings/International Conference on Pattern Recognition · doi:10.1109/icpr56361.2022.9956342 · Cited by 8
Depth over RGB: automatic evaluation of open surgery skills using depth camera
Zuckerman, I., Werner, N. E., Kouchly, J., Huston, E., DiMarco, S. M., DiMusto, P. D., & Laufer, S. (2024) · International Journal of Computer Assisted Radiology and Surgery · doi:10.1007/s11548-024-03158-3 · Cited by 6
Optimized RainDNet: an efficient image deraining method with enhanced perceptual quality
Shandilya, D. K., Roy, S., & Singh, N. (2024) · Signal Image and Video Processing · doi:10.1007/s11760-024-03380-1 · Cited by 5
“Despite having a lot fewer parameters than the underlying model, our optimised Multi-stage technique outperforms the original cutting-edge MPRNet [27–29] in terms of PSNR and SSIM, suggesting greater picture restoration quality from a human visual perception standpoint tasks [30, 34–36].”
HierGAT: hierarchical spatial-temporal network with graph and transformer for video HOI detection
Wu, J., Zhang, Y., Kampffmeyer, M., Pan, Y. M., Zhang, C., Sun, S., Chang, H., & Zhao, X. (2024) · Multimedia Systems · doi:10.1007/s00530-024-01604-5 · Cited by 7
Bounded Future MS-TCN++ for Surgical Gesture Recognition
Goldbraikh, A., Avisdris, N., Pugh, C. M., & Laufer, S. (2023) · Lecture notes in computer science · doi:10.1007/978-3-031-25066-8_22 · Cited by 8
StrokeRehab: A Benchmark Dataset for Sub-second Action Identification.
Kaku, A., Liu, K., Parnandi, A., Rajamohan, H. R., Venkataramanan, K., Venkatesan, A., Wirtanen, A., Pandit, N. G., Schambra, H. M., & Fernandez‐Granda, C. (2022) · PubMed · Cited by 12
Pose Refinement Graph Convolutional Network for Skeleton-based Action RecognitionPreprint
Li, S., Yi, J., Farha, Y. A., et al. (2020) · arXiv (Cornell University) · doi:10.48550/arxiv.2010.07367 · Cited by 5
“Although deep learning models are very popular for recognizing activities in videos [1]–[3], these approaches are computationally expensive and cannot be”
BackgroundSelf-citationMulti-shot Temporal Event Localization: a BenchmarkPreprint
Liu, X., Hu, Y. G., Bai, S., Ding, F., Bai, X., & Torr, P. H. S. (2020) · arXiv (Cornell University) · doi:10.48550/arxiv.2012.09434 · Cited by 5
Unsupervised Activity Segmentation by Joint Representation Learning and Online Clustering.Preprint
Kumar, S., Haresh, S., Ahmed, A., Konin, A., Zia, M. Z., & Tran, Q.-H. (2021) · arXiv (Cornell University) · Cited by 5
Hong, D., Li, C., Wen, L., Wang, X., & Zhang, L. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2107.00239 · Cited by 8
Annealing Temporal–Spatial Contrastive Learning for multi-view Online Action Detection
Tan, Y., Xie, L., Jing, S., Fang, S., & Zhang, K. (2024) · Knowledge-Based Systems · doi:10.1016/j.knosys.2024.112523 · Cited by 4
End-to-End Streaming Video Temporal Action Segmentation With Reinforcement Learning
Zhang, J., Wen, W., Liu, S., Huang, G. M., Li, Y., Li, Q., & Feng, L. (2025) · IEEE Transactions on Neural Networks and Learning Systems · doi:10.1109/tnnls.2025.3550910 · Cited by 7
Future-Aware Interaction Network for Motion Forecasting
Li, S., Liu, C., Xu, X., Yeo, S. Y., & Yang, X. (2025) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv51701.2025.00704 · Cited by 12
Self-citationText-Derived Relational Graph-Enhanced Network for Skeleton-Based Action Segmentation
Ji, H., Chen, B., Ren, W., Huang, W., Yang, Z., Wang, Z., & Liu, H. (2025) · IEEE Transactions on Image Processing · doi:10.1109/tip.2025.3624581 · Cited by 5
Hong, S., Hong, S., Jang, J., Keun-young Kim, A., Hyung, W. J., & Choi, M.-K. (2022) · Computer Methods in Biomechanics and Biomedical Engineering Imaging & Visualization · doi:10.1080/21681163.2022.2159533 · Cited by 5
Improving Time Study Methods Using Deep Learning-Based Action Segmentation Models
Gudlin, M., Hegedić, M., Golec, M., & Kolar, D. (2024) · Applied Sciences · doi:10.3390/app14031185 · Cited by 4
TSCL: Timestamp Supervised Contrastive Learning for Action Segmentation
Patsch, C., Wu, Y., Salihu, D., Zakour, M., & Steinbach, E. G. (2024) · IEEE Robotics and Automation Letters · doi:10.1109/lra.2024.3427553 · Cited by 5
Biffi, C., Roffo, G., Salvagnini, P., & Cherubini, A. (2025) · Computer Methods and Programs in Biomedicine · doi:10.1016/j.cmpb.2025.108782 · Cited by 8
MOSCATO: Predicting Multiple Object State Change through Actions
Zameni, P., Shen, Y., & Elhamifar, E. (2025) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv51701.2025.01079 · Cited by 11
Zhang, B., Sturgeon, D., Shankar, A. R., Goel, V. K., Barker, J., Ghanem, A. G., Lee, P., Milecky, M., Stottler, N., & Petculescu, S. (2022) · Computer Methods in Biomechanics and Biomedical Engineering Imaging & Visualization · doi:10.1080/21681163.2022.2152371 · Cited by 5
Frequency Selective Augmentation for Video Representation Learning
Kim, J., Kim, T., Shim, M., Han, D., Wee, D., & Kim, J. (2023) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v37i1.25194 · Cited by 9
InteractNet: Social Interaction Recognition for Semantic-rich Videos
Lyu, Y., Qin, P., Xu, T., Zhu, C., & Chen, E. (2024) · ACM Transactions on Multimedia Computing Communications and Applications · doi:10.1145/3663668 · Cited by 5
SG2VID: Scene Graphs Enable Fine-Grained Control for Video Synthesis
Sivakumar, S. K., Frisch, Y., Ghazaei, G., & Mukhopadhyay, A. (2025) · Lecture notes in computer science · doi:10.1007/978-3-032-05114-1_49 · Cited by 9
Dissanayake, T., Müller, K., & von Lühmann, A. (2025) · IEEE Reviews in Biomedical Engineering · doi:10.1109/rbme.2025.3617858 · Cited by 9
“As per [25], [29], multiple layers, typically up to five, could help to obtain more refined outcomes.”
CLOT: Closed Loop Optimal Transport for Unsupervised Action Segmentation
Bueno-Benito, E., & Dimiccoli, M. (2025) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv51701.2025.00998 · Cited by 3
Timestamp Query Transformer for Temporal Action Segmentation
Wang, T., & Todorović, S. (2026) · IEEE Winter Conference on Applications of Computer Vision · doi:10.1109/wacv61042.2026.00487 · Cited by 3
Multi-level Temporal Relation Graph for Continuous Sign Language Recognition
Guo, J., Xue, W., Guo, L., et al. (2022) · Lecture notes in computer science · doi:10.1007/978-3-031-18913-5_32 · Cited by 3
Blau, A., Schaffer, E., Mishra, N., Miska, N. J., Paninski, L., & Whiteway, M. R. (2024) · Neurons Behavior Data analysis and Theory · doi:10.51628/001c.127770 · Cited by 8
A Multimodal Handover Failure Detection Dataset and Baselines
Thoduka, S., Hochgeschwender, N., Gall, J., et al. (2024) · Proceedings - IEEE International Conference on Robotics and Automation/Proceedings · doi:10.1109/icra57147.2024.10610143 · Cited by 3
Self-citationHe, J., Guo, J., Zhou, L., et al. (2025) · IEEE Transactions on Instrumentation and Measurement · doi:10.1109/tim.2025.3606063 · Cited by 3
Self-citationCross Your Body: a Cognitive Assessment System for Children
Sayed, S., & Athitsos, V. (2021) · Lecture notes in computer science · doi:10.1007/978-3-030-90436-4_8 · Cited by 3
Tencent AVS: A Holistic Ads Video Dataset for Multi-Modal Scene Segmentation
Jiang, J., Li, Z., Xiong, J., Quan, R., Lu, Q., & Liu, W. (2022) · IEEE Access · doi:10.1109/access.2022.3227425 · Cited by 4
“Previous temporal action segmentation methods such as MS-TCN++ [35] commonly utilize a cross-entropy loss for frame-wise classification and a smoothing loss for regularization, respectively.”
MethodInfluentialHu, Y. Y., Hsu, C., Tseng, Y.-H., Lin, C., Chiang, H., Chiang, A., Chang, S., & Chen, S.-J. (2023) · Biomedical Optics Express · doi:10.1364/boe.484154 · Cited by 3
Long, J., Hong, J., Wang, Z., Chen, T., Chen, Y., & Yang, L. (2023) · IEEE International Conference on Bioinformatics and Biomedicine (BIBM) · doi:10.1109/bibm58861.2023.10385579 · Cited by 4
Positive and Negative Set Designs in Contrastive Feature Learning for Temporal Action Segmentation
Chen, Y.-C., & Chu, W.-T. (2024) · IEEE Transactions on Circuits and Systems for Video Technology · doi:10.1109/tcsvt.2024.3417392 · Cited by 4
Romeo, L., Marani, R., Cicirelli, G., & D’Orazio, T. (2024) · International Conference on Control, Decision and Information Technologies (CoDIT) · doi:10.1109/codit62066.2024.10708238 · Cited by 3
Not all samples are equal: Boosting action segmentation via selective incremental learning
Huang, F., Chen, X.-D., Wu, W., & Ma, W. (2025) · Engineering Applications of Artificial Intelligence · doi:10.1016/j.engappai.2025.110334 · Cited by 5
Error Recognition in Procedural Videos Using Generalized Task Graph
Lee, S., & Elhamifar, E. (2025) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv51701.2025.00933 · Cited by 16
Metadata
- Authors
- Li, S., Farha, Y. A., Liu, Y., Cheng, M.-M., & Gall, J.
- Affiliations
- University of Bonn (DE)
- Nankai University (CN)
- University of Bonn, Bonn, Germany
- Venue
- IEEE Transactions on Pattern Analysis and Machine Intelligence
- Published
- 2023-06-01
- Volume
- 45
- Issue
- 6
- Pages
- 6647-6658
- ISSN
- 0162-8828 (ISSN-L)
- 2160-9292
- 1939-3539
- OpenAlex
- W3083550439
- Semantic Scholar
- 2db9d36748bf7058cbe72856021500794f711d37
- Cited by
- 349
- References
- 60
- Citations by year
- 2026: 45 · 2025: 69 · 2024: 74 · 2023: 49
- FWCI
- 15.68
- Type
- journal article
- Language
- en
- Open access
- closed
- Licence
- Locations
- IEEE Transactions on Pattern Analysis and Machine Intelligence (publishedVersion)
- PubMed (publishedVersion)
- Funders
- Deutsche Forschungsgemeinschaft (GA 1927/4-1)
- ERC Starting (677650)
- Topics
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Human Pose and Action Recognition
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Video Surveillance and Tracking Methods
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Advanced Vision and Imaging
- Keywords
- temporal action segmentation, long-range temporal dependencies, over-segmentation, untrimmed video, activity recognition, receptive fields
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
The claim verdicts this report counts are experimental: their accuracy is not yet measured.
A language model drew the claims from the paper on 2026-10-05, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-10-05 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Cited sources are checked with a language model’s help (gpt-6-sol).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
