

MS-TCN++: Multi-Stage Temporal Convolutional Network for Action Segmentation
The DOI matches its Crossref record, with a small difference in title or year; 56 of the 60 references it cites were found in a registry or an index; 4 of the 14 sources its claims cite were checked for support.
Abstract
With the success of deep learning in classifying short trimmed videos, more attention has been focused on temporally segmenting and classifying activities in long untrimmed videos. State-of-the-art approaches for action segmentation utilize several layers of temporal convolution and temporal pooling. Despite the capabilities of these approaches in capturing temporal dependencies, their predictions suffer from over-segmentation errors. In this paper, we propose a multi-stage architecture for the temporal action segmentation task that overcomes the limitations of the previous approaches. The first stage generates an initial prediction that is refined by the next ones. In each stage we stack several layers of dilated temporal convolutions covering a large receptive field with few parameters. While this architecture already performs well, lower layers still suffer from a small receptive field. To address this limitation, we propose a dual dilated layer that combines both large and small receptive fields. We further decouple the design of the first stage from the refining stages to address the different requirements of these stages. Extensive evaluation shows the effectiveness of the proposed model in capturing long-range dependencies and recognizing action segments. Our models achieve state-of-the-art results on three datasets: 50Salads, Georgia Tech Egocentric Activities (GTEA), and the Breakfast dataset.
Overview
CoChat Summary
TL;DR
The paper introduces MS-TCN, a multi-stage temporal convolutional network for fully supervised temporal action segmentation that operates at full temporal resolution and refines predictions stage by stage, trained with a combined cross-entropy and truncated-MSE smoothing loss. It reports state-of-the-art results on 50Salads, GTEA, and Breakfast.
Key findings
- The multi-stage architecture substantially outperforms a single-stage TCN of equal parameter count (48 layers) on 50Salads: F1@{10,25,50} of 76.3/74.0/64.5 vs 49.0/46.4/40.2, Edit 67.9 vs 40.7, Acc 80.7 vs 78.0 — a margin of up to 27%.
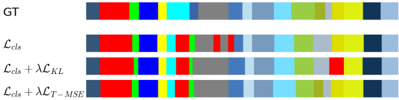
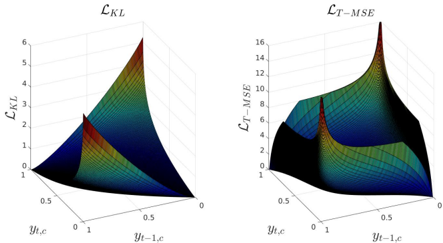
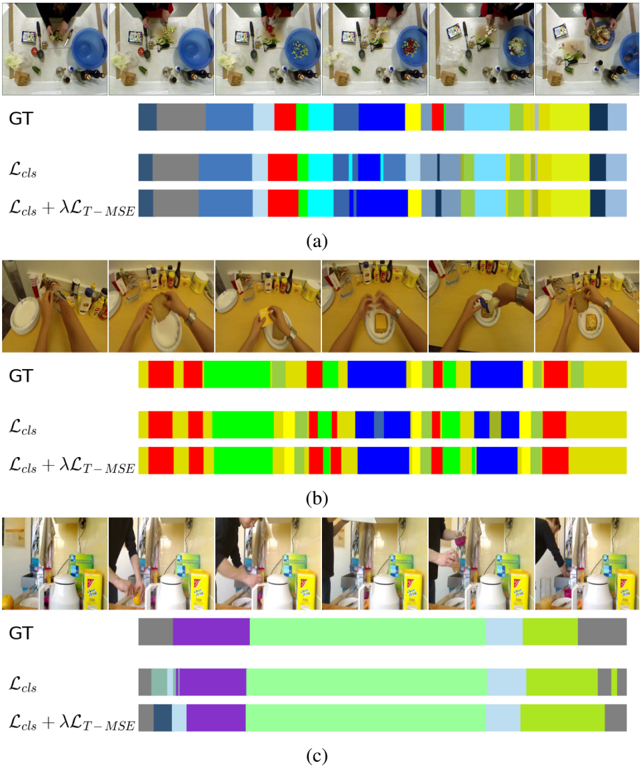
- The proposed smoothing loss improves over cross-entropy alone on 50Salads: L_cls gives F1@{10,25,50} 71.3/69.7/60.7, Edit 64.2, Acc 79.9, while L_cls + λL_T-MSE gives 76.3/74.0/64.5, Edit 67.9, Acc 80.7 (an absolute F1/edit improvement of ~5%); it also beats a KL-divergence smoothing loss (71.9/69.3/60.1, Edit 64.6, Acc 80.2).
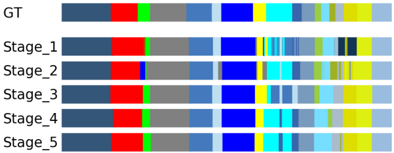
- Four stages is optimal; adding a fifth degrades performance (F1@10 76.4 but F1@25/50 drop to 73.4/63.6 and Acc to 79.5), attributed to over-fitting from more parameters.
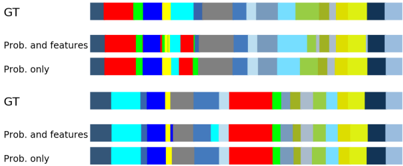
- Concatenating features to the input probabilities of higher stages causes a large drop (F1@10 56.2 vs 76.3, Edit 47.6 vs 67.9, ~20% drop), so only probabilities are passed.
- The model outperforms state-of-the-art methods on all three datasets, with up to 12.6% improvement in frame-wise accuracy on 50Salads; on GTEA with fine-tuning it reaches F1@{10,25,50} 87.5/85.4/74.6, Edit 81.4, Acc 79.2.
Methods
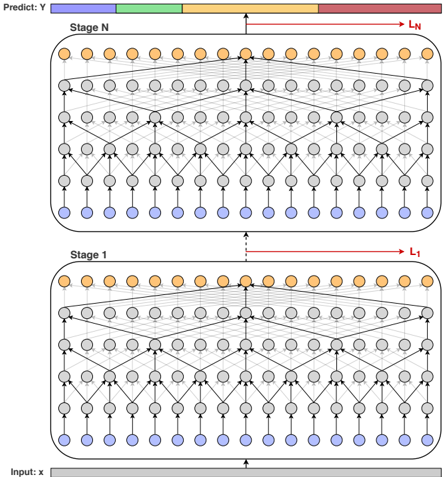
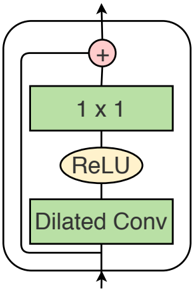
- Architecture: a single-stage TCN of dilated 1D convolutions (kernel size 3, acausal, dilation doubled per layer 1–512, residual connections, no pooling or fully connected layers), stacked into a multi-stage model where each stage refines the previous stage's frame-wise probabilities; implementation uses 4 stages, 10 dilated layers per stage, 64 filters, dropout, Adam with learning rate 0.0005.
- Loss: sum over stages of a per-stage loss combining cross-entropy classification loss and a truncated mean squared error smoothing loss over frame-wise log-probabilities, with τ = 4 and λ = 0.15.
- Data and evaluation: I3D features at 15 fps on 50Salads (50 videos, 17 classes, 5-fold cross-validation), GTEA (28 videos, 11 classes, leave-one-subject-out), and Breakfast (1,712 videos, 48 actions, standard 4 splits); metrics are frame-wise accuracy, segmental edit distance, and segmental F1 at IoU thresholds 10%, 25%, 50%.
Limitations
- Stated: the weakly supervised setting is explicitly out of scope ("the weakly supervised case is beyond the scope of this paper"); performance is slightly worse on longer videos due to the limited receptive field (GTEA ≥1.5 min: F1@10 81.2, Edit 71.8, Acc 75.9 vs <1 min: 89.6, 82.5, 76.6); a fifth stage degrades results, possibly from over-fitting.
- Evident from the text: evaluation is confined to cooking/egocentric activity datasets (50Salads, GTEA, Breakfast), so generalization to other domains is untested; the model is fully supervised and requires frame-level annotations.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
3 Valid · 1 Not valid · 5 Not checked · 71 Own results and interpretations
The sources with a verdict support this claim; the rest weren’t checked yet, have no full text we could read, or their verdicts aren’t rated yet.
In the paper
“Our model achieves state-of-the-art results on three challenging datasets: 50Salads, Georgia Tech Egocentric Activities (GTEA), and the Breakfast dataset.”
- Also stated in: § 1. Introduction · plain
“Our approach achieves state-of-the-art results on three challenging benchmarks for action segmentation: 50Salads [25], Georgia Tech Egocentric Activities (GTEA) [8], and the Breakfast dataset [12].”
What the sources say
- Not checked — no full text of the sourcecites [25] [25] Sebastian Stein and Stephen J McKenna. Combining embedded accelerometers with computer vision for recognizing food preparation activities. In ACM International Joint Conference on Pervasive and Ubiquitous Computing , pages 729-738, 2013. - source
- Supportedcites [8] [8] Alireza Fathi, Xiaofeng Ren, and James M Rehg. Learning to recognize objects in egocentric activities. In IEEE Conference on Computer Vision and Pattern Recognition (CVPR) , pages 3281-3288, 2011. - source
The citation identifies the GTEA dataset, not the citing authors’ own model or its results. Section 5.1 describes the paper’s egocentric daily-activity dataset, and the Conclusion identifies its release as GTEA. No page numbers are available in our copy. (LLM, conf=0.88)
- Not checked — no full text of the sourcecites [12] [12] Hilde Kuehne, Ali Arslan, and Thomas Serre. The language of actions: Recovering the syntax and semantics of goaldirected human activities. In IEEE Conference on Computer Vision and Pattern Recognition (CVPR) , pages 780787, 2014. - source
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Rests on an assumption not shown here.
- Also stated in: § 1. Introduction · plain
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“As shown in the table, all of these models achieve a comparable frame-wise accuracy.”
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Extensive evaluation on three datasets shows the effectiveness of our model in capturing long range dependencies between action classes and producing high quality predictions.”
boosted- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper states — it cites no source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“This architecture is trained using a combination of a classification loss and a proposed smoothing loss that penalizes over-segmentation errors.”
- Also stated in: § 1. Introduction · plain
“we further employ a smoothing loss during training which penalizes over-segmentation errors in the predictions.”
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Also stated in: § 1. Introduction · plain
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“As shown in Table 4, the impact of λ is very small on the performance.”
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
45 more claims
Create a free account to see all 80 claims and every source verdict.
- Probably not a substantial claim. 8
- Borderline: one of the tests for a substantial claim is unclear. 1
- It may state two separate claims as one. 22
Citations
Cites
Deep Residual Learning for Image Recognition
He, K., Zhang, X., Ren, S., & Sun, J. (2016) · 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2016.90 · Cited by 235,474
U-Net: Convolutional Networks for Biomedical Image Segmentation
Ronneberger, O., Fischer, P., & Brox, T. (2015) · Lecture notes in computer science · doi:10.1007/978-3-319-24574-4_28 · Cited by 99,404
Feature Pyramid Networks for Object Detection
Lin, T.-Y., Dollar, P., Girshick, R., He, K., Hariharan, B., & Belongie, S. (2017) · 2017 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2017.106 · Cited by 30,939 · cited 4×
“While the dual dilated layer combines local and global context from the input sequence, there are other techniques in the literature for fusing multi-scale features like feature pyramid networks (FPN) [47].”
BackgroundInfluentialQuo Vadis, Action Recognition? A New Model and the Kinetics Dataset
Carreira, J., & Zisserman, A. (2017) · Computer Vision and Pattern Recognition · doi:10.48550/arxiv.1705.07750 · Cited by 10,485
Quo Vadis, Action Recognition? A New Model and the Kinetics Dataset
Carreira, J., & Zisserman, A. (2017) · 2017 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2017.502 · Cited by 9,570 · cited 7×
“Most of the efforts, however, have been focused on classifying short trimmed videos [1], [2], [3], [4].”
BackgroundMethodInfluentialTwo-Stream Convolutional Networks for Action Recognition in Videos
Simonyan, K., & Zisserman, A. (2014) · arXiv · doi:10.48550/arxiv.1406.2199 · Cited by 6,756 · cited 1×
“Most of the efforts, however, have been focused on classifying short trimmed videos [1], [2], [3], [4].”
BackgroundStacked Hourglass Networks for Human Pose Estimation
Newell, A., Yang, K., & Deng, J. (2016) · Lecture Notes in Computer Science · doi:10.1007/978-3-319-46484-8_29 · Cited by 5,634 · cited 1×
“Stacking several predictors sequentially has shown significant improvements in many tasks like human pose estimation [44], [45], [46].”
BackgroundWaveNet: a generative model for raw audio
Oord, A. V. D., Dieleman, S., Zen, H., Simonyan, K., Vinyals, O., Graves, A., Kalchbrenner, N., Senior, A., & Kavukcuoglu, K. (2016) · arXiv · doi:10.48550/arxiv.1609.03499 · Cited by 4,911
SlowFast Networks for Video Recognition
Feichtenhofer, C., Fan, H., Malik, J., & He, K. (2019) · 2019 IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv.2019.00630 · Cited by 4,007 · cited 1×
“Most of the efforts, however, have been focused on classifying short trimmed videos [1], [2], [3], [4].”
BackgroundRes2Net: A New Multi-Scale Backbone Architecture
Gao, S.-H., Cheng, M.-M., Zhao, K., Zhang, X.-Y., Yang, M.-H., & Torr, P. (2021) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2019.2938758 · Cited by 3,385 · cited 1×
“Multi-scale information is important for speech synthesis [29] and image recognition [30].”
BackgroundSelf-citation
Research works printed but not linked: 1
- [11] Svebor Karaman, Lorenzo Seidenari, and Alberto Del Bimbo. Fast saliency based pooling of fisher encoded dense trajectories. In European Conference on Computer Vision (ECCV), THUMOS Workshop , 2014. -
Cited by
Items 201–300 of 349
Double Attention Network Based on Sparse Sampling
Dong, Z., Li, Y., Sun, Y., Hao, C., Liu, K., Sun, T., & Liu, S. (2022) · IEEE International Conference on Multimedia and Expo (ICME) · doi:10.1109/icme52920.2022.9859819 · Cited by 3
RFNet: A Refinement Network for Semantic Segmentation
Zhu, G., Wang, R., Han, C., Liu, Y., Ding, Y., Liu, M., Liu, L., & Sang, N. (2022) · Proceedings - International Conference on Pattern Recognition/Proceedings/International Conference on Pattern Recognition · doi:10.1109/icpr56361.2022.9956063 · Cited by 4
Self-citationTemporal Relational Modeling with Self-Supervision for Action SegmentationPreprint
Wang, D., Hu, D., Li, X., et al. (2020) · arXiv (Cornell University) · doi:10.48550/arxiv.2012.07508 · Cited by 3
Zayene, M. A., Basly, H., Franco, A., DRIDI, B., & Sayadi, F. E. (2025) · Neurocomputing · doi:10.1016/j.neucom.2025.131215 · Cited by 3
Huo, J., Bian, W., & Chang, C. (2025) · Digital Signal Processing · doi:10.1016/j.dsp.2025.105521 · Cited by 3
Phase-Informed Tool Segmentation for Manual Small-Incision Cataract Surgery
Sachdeva, B., J, N. A. R., Ashraf, T., Müller, S., Schultz, T., Wintergerst, M. W. M., Prasad, S. N., Murali, K., & Jain, M. (2025) · Lecture notes in computer science · doi:10.1007/978-3-032-05114-1_43 · Cited by 9
Improving action segmentation via explicit similarity measurement
Kamel, A., Zhang, W., Li, A., & Zhang, C. (2025) · Engineering Applications of Artificial Intelligence · doi:10.1016/j.engappai.2025.113251 · Cited by 3
Romeo, L., Patruno, C., Cicirelli, G., & D’Orazio, T. (2025) · International Conference on Control, Decision and Information Technologies (CoDIT) · doi:10.1109/codit66093.2025.11321535 · Cited by 4
ST-VA-AR: Learning velocity-aware action representations with mixture of spatiotemporal attention
Wei, J., Yu, B., Li, K., Yang, L., Xiao, D., & Liu, J. (2026) · Pattern Recognition · doi:10.1016/j.patcog.2026.113200 · Cited by 2
End-to-End Action Segmentation Transformer
Wang, T., & Todorović, S. (2025) · IEEE International Conference on Computer Vision Workshops · doi:10.1109/iccvw69036.2025.00313 · Cited by 3
Chen, X.-J., Qin, S.-J., Bai, Z.-C., et al. (2022) · IOP Conference Series: Earth and Environment · doi:10.1088/1755-1315/1101/9/092003 · Cited by 4
“…of these two networks in human motion segmentation and their lightweight models, we applied Multi-Stage Temporal Convolutional Network (MS-TCN++) and Action Segment Refinement Framework (ASRF) to the excavator action segmentation respectively, and compared the performance of the two methods (Li, S.”
MethodPrecise Gymnastic Scoring from TV Playback
Li, Q., Cui, Z., Kitahara, I., & Sagawa, R. (2022) · IEEE Global Conference on Consumer Electronics (GCCE) · doi:10.1109/gcce56475.2022.10014208 · Cited by 2
CEAT: Curvature Feature Extractor Using Action Based Triplet Learning for Action Segmentation
Jang, S., Moon, J.-H., Kim, S. Y., & Sohn, K.-A. (2023) · IEEE Access · doi:10.1109/access.2023.3298960 · Cited by 2
RetinaViT: Efficient Visual Backbone for Online Video Streams
Suzuki, T., & Aoki, Y. (2024) · Sensors · doi:10.3390/s24175457 · Cited by 2
Prompting semantic priors for image restoration
Liu, P., Wang, C., Wan, Y., & Lei, P. (2025) · Computers & Graphics · doi:10.1016/j.cag.2025.104167 · Cited by 2
Context Sensitive Network for weakly-supervised fine-grained temporal action localization
Dong, C., Liu, Q., Wang, Z., Zhang, Y., & Zhao, F. (2025) · Neural Networks · doi:10.1016/j.neunet.2025.107140 · Cited by 3
Srinivas, S., Jayaram, A., Bhavadharani, K., et al. (2024) · National Power Systems Conference · doi:10.1109/npsc61626.2024.10987033 · Cited by 2
Boundary Voting Network for Ambiguity-Aware Timestamp-Supervised Action Segmentation
Zhang, R., Duan, Y., Chen, Y., Hu, W., Cai, C., Wang, S., & Tan, Y. (2025) · IEEE Transactions on Circuits and Systems for Video Technology · doi:10.1109/tcsvt.2025.3571770 · Cited by 5
Watch and learn: leveraging expert knowledge and language for surgical video understanding
Gastager, D., Ghazaei, G., & Patsch, C. (2025) · International Journal of Computer Assisted Radiology and Surgery · doi:10.1007/s11548-025-03472-4 · Cited by 2
FocalFormer: Leveraging focal modulation for efficient action segmentation in egocentric videos
Xi, J., & Liu, S. (2025) · Computers & Graphics · doi:10.1016/j.cag.2025.104381 · Cited by 2
Shuvo, R., Mekala, M. S., & Elyan, E. (2025) · Computer Vision and Image Understanding · doi:10.1016/j.cviu.2025.104521 · Cited by 2
CTDA: Contrastive Temporal Domain Adaptation for Action Segmentation
Han, H., Lu, Z., & Wen, J.-R. (2023) · Lecture notes in computer science · doi:10.1007/978-3-031-27818-1_46 · Cited by 2
SMC-NCA: Semantic-Guided Multi-Level Contrast for Semi-Supervised Temporal Action Segmentation
Zhou, F., Jiang, Z., Zhou, H., & Li, X. (2024) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2024.3452980 · Cited by 7
Sequence-to-Sequence Modeling for Action Identification at High Temporal ResolutionPreprint
Kaku, A., Liu, K., Parnandi, A., Rajamohan, H. R., Venkataramanan, K., Venkatesan, A., Wirtanen, A., Pandit, N. G., Schambra, H. M., & Fernandez‐Granda, C. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2111.02521 · Cited by 5
Dong, J., Chen, T., & Peng, Z. (2026) · Research Square · doi:10.21203/rs.3.rs-8477605/v1 · Cited by 2
Efficient Single Image De-raining Using Multi-scale Depthwise Separable Dilated Convolution
Bi, X., Chen, Z., Li, X., et al. (2021) · International Conference on Computer and Communications (ICCC) · doi:10.1109/iccc54389.2021.9674621 · Cited by 1
Learning Video-Independent Eye Contact Segmentation from In-the-Wild Videos
Wu, T., & Sugano, Y. (2023) · Lecture notes in computer science · doi:10.1007/978-3-031-26316-3_4 · Cited by 1
PoCaPNet: A Novel Approach for Surgical Phase Recognition Using Speech and X-Ray Images
Demir, K. C., Weise, T., May, M. S., Schmid, A., Maier, A., & Yang, S. H. (2023) · Interspeech (USB) · doi:10.21437/interspeech.2023-753 · Cited by 2
GTFP: Network Fault Prediction Based on Graph and Time Series
Li, Z., Ding, J., & Ma, Z. (2023) · International Journal of Software Engineering and Knowledge Engineering · doi:10.1142/s0218194023500560 · Cited by 1
Bidirectional temporal and frame-segment attention for sparse action segmentation of figure skating
Liu, Y., Cheng, X., Li, Y., & Ikenaga, T. (2024) · Computer Vision and Image Understanding · doi:10.1016/j.cviu.2024.104186 · Cited by 3
Self-citationGaussian Sliding Window Smoothing for Human Action Segmentation
Tian, Y., Li, C., Guo, X., et al. (2024) · IEEE International Conference on Sensors, Electronics and Computer Engineering (ICSECE) · doi:10.1109/icsece61636.2024.10729446 · Cited by 1
Cluster Assumption-Guided Timestamp-Supervised Temporal Action Segmentation
Ren, Z., Li, G., Cheng, N., Wu, A., Wang, N., & Gao, X. (2025) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2025.3535331 · Cited by 3
Lee, J., Ahmed, T., Rikakis, T., & Turaga, P. K. (2025) · IEEE/CVF Winter Conference on Applications of Computer Vision Workshops (WACVW) · doi:10.1109/wacvw65960.2025.00008 · Cited by 4
Qu, J., Li, Y., Liu, C., Wang, W., & Weiping, F. (2025) · Computers, materials & continua/Computers, materials & continua (Print) · doi:10.32604/cmc.2025.065895 · Cited by 4
Enhancing Temporal Action Segmentation with Large Language Models
Sasage, R., Qu, J., & Miwa, S. (2025) · IEEE Conference on Industrial Electronics and Applications (ICIEA) · doi:10.1109/iciea65512.2025.11148796 · Cited by 2
Egocentric Online Action Segmentation with Behavior-Centred Feature Augmentation
Han, Z., Jiang, X., Wang, Z., Liu, X., Shen, F., & Xu, X. (2025) · IEEE International Conference on Multimedia and Expo (ICME) · doi:10.1109/icme59968.2025.11208951 · Cited by 1
Probabilistic Embeddings with Causal Constraint for Error Detection in Egocentric Procedural Videos
Hou, T., Li, S., Jiang, X., Wang, Z., Shen, F., & Xu, X. (2025) · IEEE International Conference on Multimedia and Expo (ICME) · doi:10.1109/icme59968.2025.11209124 · Cited by 3
Self-citationMulti-Granularity Query Network With Adaptive Category Feature Embedding for Behavior Recognition
Long, N., Dang, Y., Yang, K., et al. (2025) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2025.3632695 · Cited by 1
ATARS: An Aerial Traffic Atomic Activity Recognition and Temporal Segmentation Dataset
Chen, Z., Wu, H. R., Kung, C.-H., Chen, Y., & Peng, Y. (2025) · IEEE/RSJ International Conference on Intelligent Robots and Systems (IROS) · doi:10.1109/iros60139.2025.11247259 · Cited by 2
Yang, Z., Ji, H., Chen, B., Huang, W., Ren, W., Wang, Z., & Liu, H. (2025) · IEEE Transactions on Circuits and Systems for Video Technology · doi:10.1109/tcsvt.2025.3637737 · Cited by 1
Huang, G.-T., Bai, S., Yang, X., et al. (2025) · Italian National Conference on Sensors · doi:10.3390/s25237229 · Cited by 1
“RNN/LSTM/GRU models excel at capturing long-term dependencies, while TCNs use dilated convolutions to achieve large receptive fields with parallel processing and stable gradients [12,13].”
Enhancing open-surgery gesture recognition using 3D pose estimation
Meiraz, O., Laufer, S., Spector, R., et al. (2026) · International Journal of Computer Assisted Radiology and Surgery · doi:10.1007/s11548-025-03564-1 · Cited by 1
STDLM: A spatio-temporal deep learning method for anomaly detection in in-vehicle CAN networks
Xiong, X., Zhang, J., Wu, Y., et al. (2026) · Journal of Network and Computer Applications · doi:10.1016/j.jnca.2026.104489 · Cited by 1
Gong, L., & Sun, L. (2025) · International Conference on Computational Modeling, Simulation and Data Analysis (CMSDA) · doi:10.1145/3796731.3796775 · Cited by 1
Skeleton Motion Words for Unsupervised Skeleton-Based Temporal Action Segmentation
Gökay, U., Spurio, F., Bach, D. R., & Gall, J. (2025) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv51701.2025.01125 · Cited by 10
Self-citationPaving the Way for Point Cloud Video Representation Learning Using a PDE Model
Huang, Z., Fan, Z., Han, J., & Kittler, J. (2026) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2026.3697828 · Cited by 2
A Temporal Convolutional Network for Weakly Supervised Action Segmentation
Zou, Z., Zou, J., Liu, J., & Sun, S. (2021) · IEEE International Conference on Network Infrastructure and Digital Content (IC-NIDC) · doi:10.1109/ic-nidc54101.2021.9660442 · Cited by 1
Convolutional Transformer with Similarity-based Boundary Prediction for Action Segmentation
Du, D., Su, B., Li, Y., Qi, Z., Si, L., & Shan, Y. (2022) · IEEE International Conference on Tools with Artificial Intelligence (ICTAI) · doi:10.1109/ictai56018.2022.00131 · Cited by 2
A Multiscale Dynamic Temporal Convolution Network For Continuous Dimensional Emotion Recognition
Hu, M. Q., Sun, J., Wang, X., & An, N. (2023) · International Joint Conference on Neural Networks (IJCNN) · doi:10.1109/ijcnn54540.2023.10191861 · Cited by 2
Ma, Z., & Li, K. (2023) · Mathematics · doi:10.3390/math12010057 · Cited by 1
Representation and Boundary Enhancement for Action Segmentation Using Transformer
Chen, S., Wen, C.-X., Cheng, W.-H., & Hua, K. (2024) · IEEE International Conference on Acoustics Speech and Signal Processing · doi:10.1109/icassp48485.2024.10448258 · Cited by 2
SigFormer: Sparse Signal-guided Transformer for Multi-modal Action Segmentation
Liu, Q., Liu, X., Liu, K., Gu, X., & Liu, W. (2024) · ACM Transactions on Multimedia Computing Communications and Applications · doi:10.1145/3657296 · Cited by 3
Body Motion Segmentation via Multilayer Graph Processing for Wearable Sensor Signals
Deng, Q., Zhang, S., & Ding, Z. J. (2024) · IEEE Open Journal of Signal Processing · doi:10.1109/ojsp.2024.3407662 · Cited by 1
Lipreading using Joint Preception Temporal Convolutional Network
Li, X., Tan, Z., Cheng, Z., & Wu, X. (2023) · International Conference on Mobility, Sensing and Networking (MSN) · doi:10.1109/msn60784.2023.00091 · Cited by 1
Hong, J., Long, Y., Luo, Y., Qi, Q., & Long, J. (2024) · IEEE International Conference on Multimedia and Expo (ICME) · doi:10.1109/icme57554.2024.10688242 · Cited by 1
Long-Tail Temporal Action Segmentation with Group-Wise Temporal Logit Adjustment
Pang, Z., Şener, F., Ramasubramanian, S., & Yao, A. (2024) · Lecture notes in computer science · doi:10.1007/978-3-031-73404-5_19 · Cited by 6
2by2: Weakly-Supervised Learning for Global Action Segmentation
Bueno-Benito, E., & Dimiccoli, M. (2024) · Lecture notes in computer science · doi:10.1007/978-3-031-78125-4_26 · Cited by 1
Automated surgical workflow recognition in privacy-preserving depth videos of the operating room
Gerats, B. G. A., Wolterink, J. M., & Broeders, I. A. M. J. (2025) · Surgical Endoscopy · doi:10.1007/s00464-025-12031-6 · Cited by 1
Coarse-to-Fine Loss Based On Viterbi Algorithm for Weakly Supervised Action Segmentation
Sheng, L., Li, C., & Tian, Y. (2021) · 2021 International Conference on Signal Processing and Machine Learning (CONF-SPML) · doi:10.1109/conf-spml54095.2021.00009 · Cited by 2
Temporal Action Segmentation from Timestamp SupervisionPreprint
Li, Z., Farha, Y. A., & Gall, J. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2103.06669 · Cited by 1
Self-citationExploiting Segment-level Semantics for Online Phase Recognition from Surgical VideosPreprint
Ding, X., & Li, X. (2021) · arXiv (Cornell University) · Cited by 1
Yuan, R., Abdel-Aty, M. A., Xiang, Q., et al. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2308.00533 · Cited by 1
Automated movement assessment in stroke rehabilitationPreprint
Ahmed, T., Thopalli, K., Rikakis, T., et al. (2021) · bioRxiv (Cold Spring Harbor Laboratory) · doi:10.1101/2021.06.25.449936
Global2Local: Efficient Structure Search for Video Action SegmentationPreprint
Gao, S., Han, Q., Li, Z., et al. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2101.00910
Self-citationTemporal Action Segmentation with High-level Complex Activity LabelsPreprint
Ding, G., & Yao, A. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2108.06706
Long Short View Feature Decomposition via Contrastive Video Representation LearningPreprint
Behrmann, N., Fayyaz, M., Gall, J., et al. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2109.11593
Self-citationBackground-Click Supervision for Temporal Action LocalizationPreprint
Yang, L., Han, J., Zhao, T., Lin, T., Zhang, D., & Chen, J. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2111.12449
Yu, J., Cheng, Y., Zhao, R.-W., et al. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2111.12374
Singhania, D., Rahaman, R., & Yao, A. (2021) · arXiv (Cornell University)
Pyramid Dilated Attention Network for Action Segmentation
Du, Z., Mei, F., Lai, X., & Wang, Q. (2021) · International Conference on Wireless Communications and Signal Processing (WCSP) · doi:10.1109/wcsp52459.2021.9613432
Supervised Sliding Window Smoothing Loss Function Based on MS-TCN for Video Segmentation
Yang, T. (2021) · Communications in computer and information science · doi:10.1007/978-981-16-8885-0_24
A Hierarchical Bayesian Model for Cyber-Human Assessment of Rehabilitation MovementPreprint
Ahmed, T., Rikakis, T., Zilevu, S., et al. (2022) · medRxiv · doi:10.1101/2022.05.25.22275480
PACE: Predictive and Contrastive Embedding for Unsupervised Action Segmentation
Wang, J., Qin, J., Wang, Y., & Li, A. (2022) · International Joint Conference on Artificial Intelligence · doi:10.24963/ijcai.2022/198
Detection of Change Points in Time Series for Devices Maintenance
Zhou, Q., Liu, L., Zhang, J., & Zheng, Y. (2022) · IEEE Joint International Information Technology and Artificial Intelligence Conference (ITAIC) · doi:10.1109/itaic54216.2022.9836900
Pose Driven Deep Appearance Feature Learning for Action Classification
Sameer, R. H., Rambabu, S., Kishore, P. V. V., Kumar, D. A., & Suneetha, M. (2022) · Lecture notes in networks and systems · doi:10.1007/978-981-19-2535-1_8
Boundary-Match U-Shaped Temporal Convolutional Network for Vulgar Action SegmentationPreprint
Feng, X., Xu, R., He, Y., Qin, F., Toyoura, M., & Peng, Y. K. (2023) · SSRN Electronic Journal · doi:10.2139/ssrn.4576778
Denoised Temporal Relation Network for Temporal Action Segmentation
Ma, Z., & Li, K. (2023) · Lecture notes in computer science · doi:10.1007/978-981-99-8537-1_23
Ma, Z., & Li, K. (2024) · Machine Vision and Applications · doi:10.1007/s00138-023-01505-z
“For a fair comparison, the temporal resolution of 15 frames per second (fps) is applied to all the datasets, same as existing studies [6, 7], and we set λ = 0 .”
InfluentialSmartPerf: Automated Speed Performance Test from Visual Perspective
Li, L., Qiu, L., Li, S., Wang, J., & Zhu, H. (2023) · IEEE International Conference on Software Quality, Reliability and Security Companion (QRS-C) · doi:10.1109/qrs-c60940.2023.00027
Self-citationMS-MH-TCN: Multi-Stage and Multi-Head Temporal Convolutional Network for Action Segmentation
Kang, Z., & Chu, Z. (2024) · Communications in computer and information science · doi:10.1007/978-981-97-0885-7_5
SmallTAL: Real-Time Egocentric Online Temporal Action Localization for the Data-Impoverished
Joyce, E. C., Chen, Y., Neeter, E., & Mordohai, P. (2023) · PRESENCE Virtual and Augmented Reality · doi:10.1162/pres_a_00408
Deep machine learning for biosignal analysis
Dissanayakage, P. T. T. (2024) · Queensland University of Technology · doi:10.5204/thesis.eprints.247177
Improved Sliding Window Smoothing for Video Temporal Action Segmentation and Recognition
Li, C., Tian, Y., Sheng, L., Chen, J., Wang, T., & Wei, X. (2023) · China Automation Congress (CAC) · doi:10.1109/cac59555.2023.10450614
Multi-Branch Network for Video Summarization Integrating Rich Information
He, H., Gao, J., Guoxin, H. A. O., et al. (2024) · Advances in transdisciplinary engineering · doi:10.3233/atde240087
Understanding Human Work Behavior by Action Segmentation Model with Feature Selection
Shimizu, Y., Yamamoto, Y., Nishimura, M., Shiono, Y., Shirasawa, R., Nakano, T., & Aoki, T. (2023) · IEEE Asia-Pacific Conference on Computer Science and Data Engineering (CSDE) · doi:10.1109/csde59766.2023.10487714
Boundary-sensitive denoised temporal reasoning network for video action segmentation
Ma, Z., & Li, K. (2024) · Signal Image and Video Processing · doi:10.1007/s11760-024-03199-w
ASGSA: global semantic-aware network for action segmentation
Bian, Q., Zhang, C., Ren, K., Yue, T., & Zhang, Y. (2024) · Neural Computing and Applications · doi:10.1007/s00521-024-09776-x
Pose-aware video action segmentation
Zhang, M., Liao, C., Li, Q., Zhang, H., & Liu, W. (2024) · Neural Computing and Applications · doi:10.1007/s00521-024-09920-7
Transformer-Based Cascade U-shaped Network for Action Segmentation
Bao, W., Lin, A., Huang, H., Yang, X., & Chen, H. (2024) · International Conference on Image Processing and Media Computing (ICIPMC) · doi:10.1109/icipmc62364.2024.10586708
Prompting Semantic Priors For Image RestorationPreprint
Liu, P., Wang, C., Wan, Y., et al. (2024) · SSRN Electronic Journal · doi:10.2139/ssrn.4903323
Vhoip: Video-Based Human-Object Interaction Recognition with Clip Prior KnowledgePreprint
Baek, D., & Choe, J. (2024) · SSRN Electronic Journal · doi:10.2139/ssrn.4903379
Caseg: Clip-Based Action Segmentation With Learnable Text Prompt
Huang, S., Zhang, H., Xu, Y., Gao, Y., Hu, Y., & Qin, Z. (2024) · Proceedings - International Conference on Image Processing · doi:10.1109/icip51287.2024.10647731
Improving Temporal Action Segmentation and Detection with Hierarchical Task Grammar
Yihui, Q., & Rajan, D. (2024) · Lecture notes in computer science · doi:10.1007/978-3-031-78110-0_13 · Cited by 2
Localization-Aware Multi-Scale Representation Learning for Repetitive Action Counting
Wang, S., Shen, X., Tang, Y., et al. (2024) · IEEE International Conference on Visual Communications and Image Processing (VCIP) · doi:10.1109/vcip63160.2024.10849865 · Cited by 1
Proposal of Ensemble Method for Action Segmentation in Laparoscopic Surgery Videos
HIDAKA, T., Kanta, K. U. B. O., Tanabe, K., et al. (2025) · Journal of Japan Society for Fuzzy Theory and Intelligent Informatics · doi:10.3156/jsoft.37.1_571
Cluster-Refined Optimal Transport for Unsupervised Action Segmentation
Wang, S., Zhang, J., Liu, Y., Li, S., & Feng, L. (2025) · IEEE International Conference on Acoustics Speech and Signal Processing · doi:10.1109/icassp49660.2025.10887693
Self-citationMultiple temporal scale aggregate network for temporal action segmentation
Zheng, Z., Zhou, Y., Chen, Y., Gu, Y., Zhou, J., & Ji, Z. (2025) · Pattern Recognition · doi:10.1016/j.patcog.2025.112165 · Cited by 1
Xiao, W., & Wei, C. (2025) · Preprints.org · doi:10.3390/app15147866
Dong, Y., Jiang, H., Pan, S., & Wang, J.-Z. (2025) · Information Sciences · doi:10.1016/j.ins.2025.122530 · Cited by 2
FACT++: Multi-Stage Hand Keypoint Fusion for Enhanced Egocentric Action Segmentation
Naeem, A., Khan, E., Ahmad, H., et al. (2025) · IEEE International Conference on Computing and Machine Intelligence (ICMI) · doi:10.1109/icmi65310.2025.11141070
Metadata
- Authors
- Li, S., Farha, Y. A., Liu, Y., Cheng, M.-M., & Gall, J.
- Affiliations
- University of Bonn (DE)
- Nankai University (CN)
- University of Bonn, Bonn, Germany
- Venue
- IEEE Transactions on Pattern Analysis and Machine Intelligence
- Published
- 2023-06-01
- Volume
- 45
- Issue
- 6
- Pages
- 6647-6658
- ISSN
- 0162-8828 (ISSN-L)
- 2160-9292
- 1939-3539
- OpenAlex
- W3083550439
- Semantic Scholar
- 2db9d36748bf7058cbe72856021500794f711d37
- Cited by
- 349
- References
- 60
- Citations by year
- 2026: 45 · 2025: 69 · 2024: 74 · 2023: 49
- FWCI
- 15.68
- Type
- journal article
- Language
- en
- Open access
- closed
- Licence
- Locations
- IEEE Transactions on Pattern Analysis and Machine Intelligence (publishedVersion)
- PubMed (publishedVersion)
- Funders
- Deutsche Forschungsgemeinschaft (GA 1927/4-1)
- ERC Starting (677650)
- Topics
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Human Pose and Action Recognition
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Video Surveillance and Tracking Methods
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Advanced Vision and Imaging
- Keywords
- temporal action segmentation, long-range temporal dependencies, over-segmentation, untrimmed video, activity recognition, receptive fields
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
The claim verdicts this report counts are experimental: their accuracy is not yet measured.
A language model drew the claims from the paper on 2026-10-05, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-10-05 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Cited sources are checked with a language model’s help (gpt-6-sol).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
