

Understanding Plagiarism Linguistic Patterns, Textual Features, and Detection Methods
The DOI matches its Crossref record; 150 of the 168 references it cites were found in a registry or an index; 5 of the 73 sources its claims cite were checked for support.
Abstract
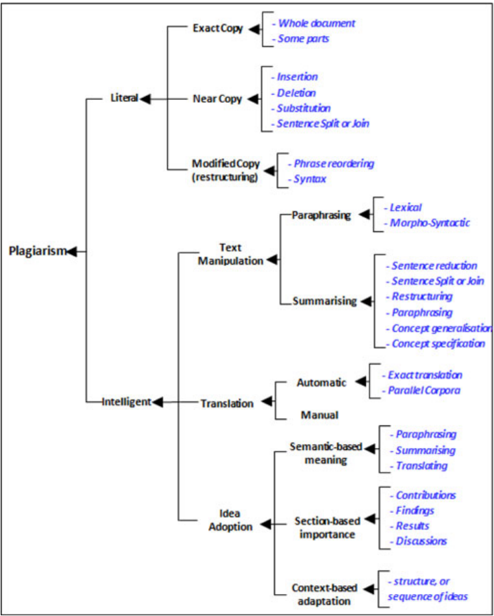
Plagiarism can be of many different natures, ranging from copying texts to adopting ideas, without giving credit to its originator. This paper presents a new taxonomy of plagiarism that highlights differences between literal plagiarism and intelligent plagiarism, from the plagiarist's behavioral point of view. The taxonomy supports deep understanding of different linguistic patterns in committing plagiarism, for example, changing texts into semantically equivalent but with different words and organization, shortening texts with concept generalization and specification, and adopting ideas and important contributions of others. Different textual features that characterize different plagiarism types are discussed. Systematic frameworks and methods of monolingual, extrinsic, intrinsic, and cross-lingual plagiarism detection are surveyed and correlated with plagiarism types, which are listed in the taxonomy. We conduct extensive study of state-of-the-art techniques for plagiarism detection, including character n-gram-based (CNG), vector-based (VEC), syntax-based (SYN), semantic-based (SEM), fuzzy-based (FUZZY), structural-based (STRUC), stylometric-based (STYLE), and cross-lingual techniques (CROSS). Our study corroborates that existing systems for plagiarism detection focus on copying text but fail to detect intelligent plagiarism when ideas are presented in different words.
Overview
CoChat Summary
TL;DR
This survey proposes a taxonomy distinguishing literal from intelligent plagiarism and correlates linguistic patterns, textual features, and detection methods. It finds that existing plagiarism detection systems mainly detect copied text and fail on intelligent plagiarism when ideas are reworded or adopted.
Key findings
- The taxonomy divides plagiarism into literal plagiarism and intelligent plagiarism; intelligent plagiarism includes text manipulation (paraphrasing, summarization), translation, and idea adoption. Idea plagiarism is further categorized into semantic-based meaning, section-based importance, and context-based adaptation.
- Existing systems focus on copying text but fail to detect intelligent plagiarism when ideas are presented in different words; the paper states current antiplagiarism tools “can pinpoint only word-for-word plagiarism and only some instances of it” and do not cater adopting ideas of others.
- Detection methods are categorized as CNG, VEC, SYN, SEM, FUZZY, STRUC, STYLE, and CROSS. CNG, VEC, and SYN are fast but lose semantic information and are unable to detect types other than literal plagiarism; SEM and FUZZY can detect rewording but have received less attention due to semantic representation challenges and time complexity; STYLE methods lack source-document evidence.
- A qualitative study at the University of Technology Malaysia interviewed faculty members with 10–20-year teaching expertise to inform the taxonomy. A cited Arabic fuzzy IR study used a corpus of 4477 source statements and 303 query/suspicious statements, with permission threshold p = 0.825 and variation threshold v = 0.15.
Methods
- Survey/review of state-of-the-art plagiarism detection techniques and frameworks for monolingual, extrinsic, intrinsic, and cross-lingual detection, mapping methods to plagiarism types in the proposed taxonomy.
- Qualitative study at the University of Technology Malaysia: interviews with several faculty members with 10–20-year teaching expertise about student plagiarism practices; the main output was a new taxonomy of plagiarism.
- Conceptual synthesis of textual features—lexical, syntactic, semantic, structural, and stylometric—and detection methods, with examples and reported thresholds from prior work rather than a unified new benchmark.
Limitations
- The paper states that current antiplagiarism tools can pinpoint only word-for-word plagiarism and only some instances of it, and do not cater adopting ideas of others; idea plagiarism is described as a key academic problem needing future research.
- The paper states SEM and FUZZY approaches have received less attention due to the challenge of representing semantics and the time complexity of representative algorithms, making them inefficient and impractical for real-world tools; STYLE methods lack the source-document evidence crucial to a human investigator.
- Evident from the text: the taxonomy is based on a qualitative study at one university plus literature review, and the survey does not report a unified empirical benchmark comparing all surveyed methods.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures




Verification
Claims the paper makes
3 Valid · 21 Not valid · 50 Not checked · 34 Own results and interpretations
The cited sources that could be checked couldn’t confirm or dispute this claim.
In the paper
“Fingerprint [115], [116] and hash-based [117], [118] are common heuristic retrieval models”
What the sources say
- Could not verifycites [115] [115] C. D. Manning, P. Raghavan, and H. Sch¨ utze, 'Web search basics: Near-duplicates and shingling,' in Introduction to Information Retrieval . Cambridge, U.K.: Cambridge Univ. Press, 2008, pp. 437-442. - sourceExperimental — accuracy not yet measured
Our copy of Koroutchev & Cebrián (2006) contains no mention of fingerprinting or hash-based retrieval: searches for 'fingerprint', 'hash/hashing', 'shingling/digest/signature' and 'heuristic retrieval' returned only the Related work (Sec. 2) and Introduction passages. Section 2 instead divides prior parallel-text/bitext work into two classes — structure based (locating pages via search engines, candidate generation by language identification [11], URL-matching [9,10], document-length filtering [12], and structural filtering in STRAND, PTMiner, BITS) and content based (Smith's tsim lexical score [15], and the Resnik–Smith combination [16]) — so it does not speak to the claim's point about fingerprint and hash models being common heuristic retrieval approaches. The paper is not truncated, and it states nothing contrary (it does not deny such methods exist), so the claim can be neither confirmed nor disputed. (LLM, conf=0.68)
- Not checked — no full text of the sourcecites [116] [116] N. Heintze, 'Scalable document fingerprinting,' in Proc. 2nd USENIX Workshop Electron. Commerce , 1996, pp. 191-200. - source
- Not checked — no full text of the sourcecites [117] [117] B. Stein, 'Principles of hash-based text retrieval,' in Proc. 30th Annu. Int. ACM SIGIR , Amsterdam, The Netherlands, 2007, pp. 527-534. - source
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Could not verify
None of the sources cited for this claim have been checked yet.
In the paper
“Approximate string matching and similarity metrics have been widely used in plagiarism detection.”
boosted- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The main output of the qualitative study is a new taxonomy of plagiarism that comprehensively relates different types, as shown in Fig. 2.”
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
None of the sources cited for this claim have been checked yet.
In the paper
“Different plagiarism techniques, which feature the text as character n -gram or word n -gram, use exact string matching.”
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper states — it cites no source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“In all of them, writing style is quantified and/or feature complexity is analyzed.”
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
14 more claims
Create a free account to see all 108 claims and to verify the 3 references still open.
- Probably not a substantial claim. 80
- It may state two separate claims as one. 37
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Each contradiction between two passages listed here was confirmed by an independent check.
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ A. Retrieval Models of Candidate Documents
“x="aaabbbccc" y="aaabbbccd" d(x,y)=8”
§ B. Exhaustive Analysis Methods of Plagiarism Detection
“longest common subsequence (LCS) distance, which allows only insertions and deletions at cost 1.”
Citations
Cites
WordNet: a lexical database for English
Miller, G. A. (1995) · Communications of the ACM · doi:10.1145/219717.219748 · Cited by 14,015
Introduction to information retrieval
(2009) · Choice Reviews Online · doi:10.5860/choice.46-2715 · Cited by 12,278
Introduction to Modern Information Retrieval
Salton, G., & McGill, M. J. (1983) · Virtual Defense Library (Ministerio de Defensa) · Cited by 11,389
Introduction to Information Retrieval
Manning, C. D., Raghavan, P., & Schütze, H. (2008) · doi:10.1017/cbo9780511809071 · Cited by 11,288
Self-Organization and Associative Memory
Kohonen, T. (1989) · Springer Series in Information Sciences · doi:10.1007/978-3-642-88163-3 · Cited by 8,740
Self-Organization and Associative Memory
Kohonen, T. (1988) · Springer Series in Information Sciences · doi:10.1007/978-3-662-00784-6 · Cited by 3,812
A guided tour to approximate string matching
Navarro, G. (2001) · ACM Computing Surveys · doi:10.1145/375360.375365 · Cited by 2,561
A comparison of string distance metrics for name-matching tasks
Cohen, W. W., Ravikumar, P., & Fienberg, S. E. (2003) · International Joint Conference on Artificial Intelligence · Cited by 1,369
A survey of modern authorship attribution methods
Stamatatos, E. (2009) · Journal of the American Society for Information Science and Technology · doi:10.1002/asi.21001 · Cited by 1,176 · cited 7×
“However, an evidence of plagiarism (i.e., providing the source document) is crucial to a human investigator, a disadvantage of STYLE methods.”
BackgroundMethodInfluentialSchleimer, S., S, W. D., & Aiken, A. (2003) · Proceedings of the 2003 ACM SIGMOD International Conference on Management of Data · doi:10.1145/872757.872770 · Cited by 1,099 · cited 1×
“Fingerprint [115], [116] and hash-based [117], [118] are com-”
Sentence similarity based on semantic nets and corpus statistics
Li, Y., McLean, D., Bandar, Z. A., O'Shea, J. D., & Crockett, K. (2006) · IEEE Transactions on Knowledge and Data Engineering · doi:10.1109/tkde.2006.130 · Cited by 819 · cited 7×
“On the other hand, SEM [14], [15] and FUZZY [16]–[19] methods incorporate different semantic features, thesaurus dictionaries , and lexical databases, such as WordNet.”
MethodInfluentialComputational methods in authorship attribution
Koppel, M., Schler, J., & Argamon, S. (2009) · Journal of the American Society for Information Science and Technology · doi:10.1002/asi.20961 · Cited by 528
Zheng, R., Li, J., Chen, H., & Huang, Z. (2006) · Journal of the American Society for Information Science and Technology · doi:10.1002/asi.20316 · Cited by 519
WEBSOM – Self-organizing maps of document collections
Kaski, S., Honkela, T., Lagus, K., & Kohonen, T. (1998) · Neurocomputing · doi:10.1016/s0925-2312(98)00039-3 · Cited by 495
Mining e-mail content for author identification forensics
de Vel, O., Anderson, A., Corney, M., & Mohay, G. (2001) · ACM SIGMOD Record · doi:10.1145/604264.604272 · Cited by 487
Copy detection mechanisms for digital documents
Brin, S., Davis, J., & García-Molina, H. (1995) · Proceedings of the 1995 ACM SIGMOD international conference on Management of data - SIGMOD '95 · doi:10.1145/223784.223855 · Cited by 479
The Evolution of Stylometry in Humanities Scholarship
HOLMES, D. I. (1998) · Literary and Linguistic Computing · doi:10.1093/llc/13.3.111 · Cited by 478
How Variable May a Constant be? Measures of Lexical Richness in Perspective
Tweedie, F. J., & Baayen, R. H. (1998) · Computers and the Humanities · doi:10.1023/a:1001749303137 · Cited by 423
Outside the cave of shadows: using syntactic annotation to enhance authorship attribution
Baayen, H., van Halteren, H., & Tweedie, F. (1996) · Literary and Linguistic Computing · doi:10.1093/llc/11.3.121 · Cited by 388
Introduction to Modern Information Retrieval
(2011) · Library Management · doi:10.1108/01435121111132365 · Cited by 376
Authorship attribution in the wild
Koppel, M., Schler, J., & Argamon, S. (2011) · Language Resources and Evaluation · doi:10.1007/s10579-009-9111-2 · Cited by 306
(1995) · Cited by 296
Cross-language plagiarism detection
Potthast, M., Barrón-Cedeño, A., Stein, B., & Rosso, P. (2011) · Language Resources and Evaluation · doi:10.1007/s10579-009-9114-z · Cited by 286 · cited 3×
“(c) White-box design for cross-lingual plagiarism detection system, inspired by [31]. the white-box design for intrinsic plagiarism detection.”
Background(2006) · Cited by 255
Exploiting Stylistic Idiosyncrasies for Authorship Attribution
Koppel, M., & Schler, J. (2003) · Cited by 247
Scoring, term weighting, and the vector space model
(2008) · Introduction to Information Retrieval · doi:10.1017/cbo9780511809071.007 · Cited by 238
Computer algorithms for plagiarism detection
Parker, A., & Hamblen, J. O. (1989) · IEEE Transactions on Education · doi:10.1109/13.28038 · Cited by 216
An algorithmic approach to the detection and prevention of plagiarism
Ottenstein, K. J. (1976) · ACM SIGCSE Bulletin · doi:10.1145/382222.382462 · Cited by 208 · cited 1×
“Earlier than plagiarism detection in natural languages, code clones and software misuse detection has started since the 1970s by the studies to detect programming code plagiarism in Pascal and C [28], [44]–[47].”
BackgroundStylistic text classification using functional lexical features
Argamon, S., Whitelaw, C., Chase, P., Hota, S. R., Garg, N., & Levitan, S. (2007) · Journal of the American Society for Information Science and Technology · doi:10.1002/asi.20553 · Cited by 203
Detecting Short Passages of Similar Text in Large Document Collections
Lyon, C., Malcolm, J. A., & Dickerson, B. (2001) · University of Hertfordshire Research Archive (University of Hertfordshire) · Cited by 202
Stein, B., Lipka, N., & Prettenhofer, P. (2011) · Language Resources and Evaluation · doi:10.1007/s10579-010-9115-y · Cited by 194
Academic Writing and Plagiarism: A Linguistic Analysis
(2008) · Cited by 194
Linguistic correlates of style: authorship classification with deep linguistic analysis features
Gamon, M. (2004) · Proceedings of the 20th international conference on Computational Linguistics - COLING '04 · doi:10.3115/1220355.1220443 · Cited by 188
Plagiarism in natural and programming languages: an overview of current tools and technologies
Clough, P. D. (2000) · Cited by 186
Intrinsic Plagiarism Detection
Eissen, S. M. Z., & Stein, B. (2006) · Lecture Notes in Computer Science · doi:10.1007/11735106_66 · Cited by 184 · cited 1×
“Many research works have been conducted to tackle the task of intrinsic plagiarism detection [23], [33], [34], [66], [103]–[107].”
BackgroundIntrinsic Plagiarism Detection Using Character n-gram Profiles
Stamatatos, E. (2009) · Cited by 181
Overview of the 1st international competition on plagiarism detection
Potthast, M., Stein, B., Eiselt, A., Barrón‐Cedeño, A., & Rosso, P. (2009) · Cited by 172
CHECK: a document plagiarism detection system
Si, A., Leong, H. V., & Lau, R. W. H. (1997) · Proceedings of the 1997 ACM symposium on Applied computing - SAC '97 · doi:10.1145/331697.335176 · Cited by 169
Developing a corpus of plagiarised short answers
Clough, P. D., & Stevenson, M. (2010) · Language Resources and Evaluation · doi:10.1007/s10579-009-9112-1 · Cited by 167
Computer-based plagiarism detection methods and tools: an overview
Lukashenko, R., Graudina, V., & Grundspenkis, J. (2007) · Proceedings of the 2007 international conference on Computer systems and technologies - CompSysTech '07 · doi:10.1145/1330598.1330642 · Cited by 160
A fuzzy document retrieval system using the keyword connection matrix and a learning method
Ogawa, Y., Morita, T., & Kobayashi, K. (1991) · Fuzzy Sets and Systems · doi:10.1016/0165-0114(91)90210-h · Cited by 152
Style mining of electronic messages for multiple authorship discrimination: first results
Argamon, S., Šarić, M., & Stein, S. S. (2003) · Proceedings of the ninth ACM SIGKDD international conference on Knowledge discovery and data mining · doi:10.1145/956750.956805 · Cited by 140
Author identification: Using text sampling to handle the class imbalance problem
Stamatatos, E. (2007) · Information Processing & Management · doi:10.1016/j.ipm.2007.05.012 · Cited by 137
On Automatic Plagiarism Detection Based on n-Grams Comparison
Barrón‐Cedeño, A., & Rosso, P. (2009) · Lecture notes in computer science · doi:10.1007/978-3-642-00958-7_69 · Cited by 137
Old and new challenges in automatic plagiarism detection
Clough, P. D., & Court, R. (2003) · Cited by 136
An introduction to fuzzy systems
Dubois, D., & Prade, H. M. (1998) · Clinica Chimica Acta · doi:10.1016/s0009-8981(97)00232-5 · Cited by 132
Bouville, M. (2008) · Science and Engineering Ethics · doi:10.1007/s11948-008-9057-6 · Cited by 132 · cited 1×
“Borrowing a few words, but no original ideas, to improve the quality of the English, especially by nonnatives, should not be considered plagiarism [74].”
BackgroundA Wikipedia-Based Multilingual Retrieval Model
Potthast, M., Stein, B., & Anderka, M. (2008) · Springer eBooks · doi:10.1007/978-3-540-78646-7_51 · Cited by 129
Analyzing Writing Styles with Coh-Metrix.
McCarthy, P. M., Lewis, G. A., Dufty, D. F., & McNamara, D. S. (2006) · The Florida AI Research Society · Cited by 126
ENCOPLOT: Pairwise Sequence Matching in Linear Time Applied to Plagiarism Detection ∗
Grozea, C., First, F., Gehl, C., & Popescu, M. (2009) · Publikationsdatenbank der Fraunhofer-Gesellschaft (Fraunhofer-Gesellschaft) · Cited by 124
Copy detection mechanisms for digital documents
Brin, S., Davis, J., & García-Molina, H. (1995) · ACM SIGMOD Record · doi:10.1145/568271.223855 · Cited by 119
A similarity-based probability model for latent semantic indexing
Ding, C. H. Q. (1999) · International ACM SIGIR Conference on Research and Development in Information Retrieval (SIGIR) · doi:10.1145/312624.312652 · Cited by 118
Dubois, D., & Prade, H. M. (1989) · Elsevier eBooks · doi:10.1016/b978-0-12-685242-4.50005-1 · Cited by 113
Intelligent Technologies for Information Analysis
Zhong, N., & Liu, J. (2004) · Springer eBooks · doi:10.1007/978-3-662-07952-2 · Cited by 107
Plagiarism detection using the Levenshtein distance and Smith-Waterman algorithm
Su, Z., Ahn, B.-R., Eom, K.-Y., Kang, M.-K., Kim, J.-P., & Kim, M.-K. (2008) · 2008 3rd International Conference on Innovative Computing Information and Control · doi:10.1109/icicic.2008.422 · Cited by 107 · cited 1×
“[5] combined Levenshtein distance, and simplified Smith-Waterman algorithm for the identification and quantification of local simi-”
MethodStrategies for retrieving plagiarized documents
Stein, B., zu Eissen, S. M., & Potthast, M. (2007) · Proceedings of the 30th annual international ACM SIGIR conference on Research and development in information retrieval · doi:10.1145/1277741.1277928 · Cited by 106
Plagiarism Detection Without Reference Collections
Meyer zu Eissen, S., Stein, B., & Kulig, M. (2007) · Studies in Classification, Data Analysis, and Knowledge Organization · doi:10.1007/978-3-540-70981-7_40 · Cited by 106
Generating, integrating, and activating thesauri for concept-based document retrieval
Chen, H., Lynch, K. J., Basu, K., & Ng, T. D. (1993) · IEEE Expert · doi:10.1109/64.207426 · Cited by 105
External and Intrinsic Plagiarism Detection Using Vector Space Models
Muhr, M., Zechner, M., Kern, R., & Granitzer, M. (2009) · Cited by 98
WordNet: a lexical database for English
Miller, G. A. (1994) · DARPA Workshop on Speech and Natural Language (HLT) · doi:10.3115/1075812.1075938 · Cited by 97
Author verification by linguistic profiling: An exploration of the parameter space
Halteren, H. V. (2007) · ACM Transactions on Speech and Language Processing · doi:10.1145/1187415.1187416 · Cited by 93
Donaldson, J. L., Lancaster, A.-M., & Sposato, P. H. (1981) · Proceedings of the twelfth SIGCSE technical symposium on Computer science education - SIGCSE '81 · doi:10.1145/800037.800955 · Cited by 88
Efficient privacy-preserving similar document detection
Murugesan, M., Jiang, W., Clifton, C., Si, L., & Vaidya, J. S. (2010) · The VLDB Journal · doi:10.1007/s00778-009-0175-9 · Cited by 86
Conceptual clustering in information retrieval
(1998) · doi:10.1109/3477.678640 · Cited by 84
PPChecker: Plagiarism Pattern Checker in Document Copy Detection
Kang, N., Gelbukh, A. F., & Han, S. (2006) · Lecture notes in computer science · doi:10.1007/11846406_83 · Cited by 83
The toolbox for local and global plagiarism detection
Butakov, S., & Scherbinin, V. (2009) · Computers & Education · doi:10.1016/j.compedu.2008.12.001 · Cited by 79
A statistical approach to crosslingual natural language tasks
Pinto, D., Civera, J., Barrón‐Cedeño, A., Juan, A., & Rosso, P. (2009) · Journal of Algorithms · doi:10.1016/j.jalgor.2009.02.005 · Cited by 77
Multilingual Plagiarism Detection
Ceska, Z., Toman, M., & Jezek, K. (2008) · Lecture Notes in Computer Science · doi:10.1007/978-3-540-85776-1_8 · Cited by 72
On cross-lingual plagiarism analysis using a statistical model
Barrón‐Cedeño, A., Rosso, P., Pinto, D., & Juan, A. (2008) · Cited by 70
Multilayer SOM With Tree-Structured Data for Efficient Document Retrieval and Plagiarism Detection
Chow, T. W. S., & Rahman, M. K. M. (2009) · IEEE Transactions on Neural Networks · doi:10.1109/tnn.2009.2023394 · Cited by 67
A plagiarism detection procedure in three steps: Selection, matches and squares
Basile, C., Benedetto, D., Caglioti, E., Cristadoro, G., & Esposti, M. D. (2009) · BOA (University of Milano-Bicocca) · Cited by 63
Using Word Clusters to Detect Similar Web Documents
Koberstein, J., & Ng, Y. (2006) · Lecture notes in computer science · doi:10.1007/11811220_19 · Cited by 62
Corpus and Evaluation Measures for Automatic Plagiarism Detection
Barrón‐Cedeño, A., Potthast, M., Rosso, P., & Stein, B. (2010) · Language Resources and Evaluation Conference (LREC) · doi:10.63317/4kofobrajocn · Cited by 62
SNITCH: a software tool for detecting cut and paste plagiarism
Niezgoda, S., & Way, T. P. (2006) · Proceedings of the 37th SIGCSE technical symposium on Computer science education · doi:10.1145/1121341.1121359 · Cited by 61
Finding Plagiarism by Evaluating Document Similarities
Kasprzak, J., Brandejs, M., & Křipač, M. (2009) · Cited by 61
Sentence-based natural language plagiarism detection
White, D. R., & Joy, M. S. (2004) · Journal on Educational Resources in Computing · doi:10.1145/1086339.1086341 · Cited by 59
(1994) · doi:10.1007/bf01014019 · Cited by 58
Principles of hash-based text retrieval
Stein, B. (2007) · Proceedings of the 30th annual international ACM SIGIR conference on Research and development in information retrieval · doi:10.1145/1277741.1277832 · Cited by 55
Plagiarism analysis, authorship identification, and near-duplicate detection PAN'07
Stein, B., Koppel, M., & Stamatatos, E. (2007) · ACM SIGIR Forum · doi:10.1145/1328964.1328976 · Cited by 55
A Sentence-Based Copy Detection Approach for Web Documents
Yerra, R., & Ng, Y.-K. (2005) · Lecture Notes in Computer Science · doi:10.1007/11539506_70 · Cited by 53 · cited 1×
“Much research has been undertaken to tackle this task [1]–[6], [10], [12], [16]–[19], [21], [26], [29], [61], [77]–[102].”
BackgroundFast Plagiarism Detection System
Mozgovoy, M., Fredriksson, K., White, D., Joy, M., & Sutinen, E. (2005) · Lecture Notes in Computer Science · doi:10.1007/11575832_30 · Cited by 49
Intrinsic Plagiarism Detection using Complexity Analysis
(2009) · Cited by 48
Computer-Based Plagiarism Detection Methods and Tools: an Overview
Lukašenko, R., Šakele, V., & Grundspeņķis, J. (2007) · publication.editionName · Cited by 47
Plagiarism Detection Based on Singular Value Decomposition
Ceska, Z. (2008) · Lecture notes in computer science · doi:10.1007/978-3-540-85287-2_11 · Cited by 47
Tool support for plagiarism detection in text documents
Gruner, S., & Naven, S. (2005) · Proceedings of the 2005 ACM symposium on Applied computing · doi:10.1145/1066677.1066854 · Cited by 45
Carneiro, D. R., Nováis, P., & Neves, J. (2014) · Law, governance and technology series · doi:10.1007/978-3-319-06239-6_7 · Cited by 43
Reducing the Plagiarism Detection Search Space on the Basis of the Kullback-Leibler Distance
Barrón‐Cedeño, A., Rosso, P., & Benedí, J.-M. (2009) · Lecture notes in computer science · doi:10.1007/978-3-642-00382-0_42 · Cited by 43
Plagiarism Detection through Multilevel Text Comparison
Zini, M., Fabbri, M., Moneglia, M., & Panunzi, A. (2006) · International Conference on Automated Production of Cross Media Content for Multi-Channel Distribution · doi:10.1109/axmedis.2006.40 · Cited by 42
Language models for information retrieval
Croft, W. B. (2004) · IEEE International Conference on Data Engineering (ICDE) · doi:10.1109/icde.2003.1260777 · Cited by 42
A tool that detects plagiarism in Pascal programs
Grier, S. (1981) · ACM SIGCSE Bulletin · doi:10.1145/953049.800954 · Cited by 41
Donaldson, J. L., Lancaster, A.-M., & Sposato, P. H. (1981) · ACM SIGCSE Bulletin · doi:10.1145/953049.800955 · Cited by 38
The SCAM Approach to Copy Detection in Digital Libraries
Shivakumar, N., & Garcia-Molina, H. (1995) · D-Lib Magazine · doi:10.1045/november95-shivakumar · Cited by 37
Use of text syntactical structures in detection of document duplicates
Elhadi, M., & Al-Tobi, A. (2008) · 2008 Third International Conference on Digital Information Management · doi:10.1109/icdim.2008.4746719 · Cited by 36
Sorokina, D., Gehrke, J., Warner, S., & Ginsparg, P. (2006) · Sixth International Conference on Data Mining (ICDM'06) · doi:10.1109/icdm.2006.126 · Cited by 36
A New Approach for Cross-Language Plagiarism Analysis
Corezola Pereira, R., Moreira, V. P., & Galante, R. (2010) · Lecture Notes in Computer Science · doi:10.1007/978-3-642-15998-5_4 · Cited by 35 · cited 1×
“Research on crosslingual plagiarism detection has attracted attention in recent few years [20], [27], [31], [36], [38], [108], thus focusing on text similarity computation across languages.”
BackgroundA natural language processing approach to automatic plagiarism detection
Leung, C.-H., & Chan, Y.-Y. (2007) · Conference on Information Technology Education · doi:10.1145/1324302.1324348 · Cited by 34
Schleimer, S., Wilkerson, D. S., & Aiken, A. (2003) · doi:10.1145/872769.872770 · Cited by 34
A Taxonomy of Information Retrieval Models and Tools
(2004) · doi:10.2498/cit.2004.03.01 · Cited by 33
Elhadi, M., & Al-Tobi, A. (2009) · 2009 Fourth International Conference on Computer Sciences and Convergence Information Technology · doi:10.1109/iccit.2009.235 · Cited by 32
Word Length n-Grams for Text Re-use Detection
Barrón‐Cedeño, A., Basile, C., Esposti, M. D., et al. (2010) · Lecture notes in computer science · doi:10.1007/978-3-642-12116-6_58 · Cited by 32
Avoiding plagiarism in academic writing
Anderson, I. (2009) · Nursing Standard · doi:10.7748/ns2009.01.23.18.35.c6739 · Cited by 32
A coarse-to-fine framework to efficiently thwart plagiarism
Zhang, H., & Chow, T. W. S. (2011) · Pattern Recognition · doi:10.1016/j.patcog.2010.08.023 · Cited by 31
Fuzzy information retrieval model revisited
(2009) · doi:10.1016/j.fss.2009.02.012 · Cited by 30
Back-translation: the latest form of plagiarism
Jones, M. (2009) · Research Online (University of Wollongong) · Cited by 30
A flexible multi-layer self-organizing map for generic processing of tree-structured data
Rahman, M. K. M., Yang, W. P., Chow, T. W. S., & Wu, S. (2006) · Pattern Recognition · doi:10.1016/j.patcog.2006.10.010 · Cited by 28
Tambouratzis, G. (2004) · Literary and Linguistic Computing · doi:10.1093/llc/19.2.221 · Cited by 26
Fast and reliable plagiarism detection system
Mozgovoy, M., Karakovskiy, S., & Klyuev, V. (2007) · IEEE Frontiers in Education Conference (FIE) · doi:10.1109/fie.2007.4417860 · Cited by 25
Semantic Sequence Kin: A Method of Document Copy Detection
Bao, J.-P., Shen, J.-Y., Liu, X.-D., Liu, H.-Y., & Zhang, X.-D. (2004) · Lecture Notes in Computer Science · doi:10.1007/978-3-540-24775-3_63 · Cited by 25 · cited 2×
“On the other hand, SEM [14], [15] and FUZZY [16]–[19] methods incorporate different semantic features, thesaurus dictionaries, and lexical databases, such as WordNet.”
BackgroundMethodUsing Microsoft SQL Server platform for plagiarism detection
Shcherbinin, V., & Butakov, S. (2009) · Cited by 24
On the use of fuzzy information retrieval for gauging similarity of Arabic documents
Alzahrani, S. M., & Salim, N. B. (2009) · International Conference on the Applications of Digital Information and Web Technologies (ICADIWT) · doi:10.1109/icadiwt.2009.5273835 · Cited by 23
Self-citationCopy detection in Chinese documents using Ferret
Bao, J. P., Lyon, C., & Lane, P. C. R. (2007) · Language Resources and Evaluation · doi:10.1007/s10579-007-9020-1 · Cited by 19
Probabilistic information retrieval
Manning, C. D., Raghavan, P., & Schütze, H. (2008) · Cambridge University Press eBooks · doi:10.1017/cbo9780511809071.012 · Cited by 19
Matrix decompositions and latent semantic indexing
(2008) · doi:10.1017/cbo9780511809071.019 · Cited by 19
Style mining of electronic messages for multiple authorship discrimination: first results
Argamon, S., Šarić, M., & Stein, S. S. (2003) · Proceedings of the ninth ACM SIGKDD international conference on Knowledge discovery and data mining · doi:10.1145/956804.956805 · Cited by 19
A fast document copy detection model
Bao, J., Shen, J., Liu, H., & Liu, X. (2005) · Soft Computing · doi:10.1007/s00500-005-0463-2 · Cited by 18
LSISOM — A Latent Semantic Indexing Approach to Self-Organizing Maps of Document Collections
Ampazis, N., & Perantonis, S. J. (2004) · Neural Processing Letters · doi:10.1023/b:nepl.0000023449.95030.8f · Cited by 18 · cited 1×
“In [137], LSISOM investigated the use of SOM in clustering a document collection by encoding the LSI of document”
MethodDetecting and tracing plagiarized documents by reconstruction plagiarism-evolution tree
Ryu, C.-K., Kim, H.-J., Ji, S.-H., Woo, G., & Cho, H.-G. (2008) · 2008 8th IEEE International Conference on Computer and Information Technology · doi:10.1109/cit.2008.4594660 · Cited by 16
Tackling the PAN’09 External Plagiarism Detection Corpus with a Desktop Plaigiarism Detector
Malcolm, J. A., & Lane, P. C. R. (2009) · University of Hertfordshire Research Archive (University of Hertfordshire) · Cited by 16
Zaka, B., Kappe, F., & Maurer, H. (2006) · Verlag der Technischen Universität Graz · doi:10.3217/jucs-012-08-1050 · Cited by 16
On Authorship Attribution via Markov Chains and Sequence Kernels
Sanderson, C., & Guenter, S. (2006) · 18th International Conference on Pattern Recognition (ICPR'06) · doi:10.1109/icpr.2006.899 · Cited by 15
Ordinal measures in authorship identification
(2009) · Cited by 14
Extending Web Search for Online Plagiarism Detection
Liu, Y., Zhang, H., Chen, T.-W., & Teng, W. (2007) · IEEE International Conference on Information Reuse and Integration (IRI) · doi:10.1109/iri.2007.4296615 · Cited by 14
Finding Plagiarism Based on Common Semantic Sequence Model
Bao, J., Shen, J., Liu, X., Liu, H., & Zhang, X. (2004) · Lecture notes in computer science · doi:10.1007/978-3-540-27772-9_66 · Cited by 14
Manning, C. D., Raghavan, P., & Schütze, H. (2008) · Cambridge University Press eBooks · doi:10.1017/cbo9780511809071.002 · Cited by 14
Language models for information retrieval
Manning, C. D., Raghavan, P., & Schütze, H. (2008) · Cambridge University Press eBooks · doi:10.1017/cbo9780511809071.013 · Cited by 14
Plagiarism detection in Chinese based on chunk and paragraph weight
Wang, T., Fan, X., & Liu, J. (2008) · International Conference on Machine Learning and Cybernetics · doi:10.1109/icmlc.2008.4620842 · Cited by 13
PAN Plagiarism Corpus 2009 (PAN-PC-09)
(2009) · doi:10.5281/zenodo.3250083 · Cited by 13
Algorithm of the longest commonly consecutive word for Plagiarism detection in text based document
Sediyono, A., & Ku-Mahamud, K. R. (2008) · 2008 Third International Conference on Digital Information Management · doi:10.1109/icdim.2008.4746827 · Cited by 13
PAN Plagiarism Corpus 2009 (PAN-PC-09)
Potthast, M., Stein, B., Eiselt, A., Barrón‐Cedeño, A., & Rosso, P. (2009) · Figshare · doi:10.5281/zenodo.3250082 · Cited by 13
Plagiarism Detection in Large Sets of Press Agency News Articles
Kienreich, W., Granitzer, M., Sabol, V., & Klieber, W. (2006) · 17th International Conference on Database and Expert Systems Applications (DEXA'06) · doi:10.1109/dexa.2006.112 · Cited by 12
On the Number of Search Queries Required for Internet Plagiarism Detection
Butakov, S., & Shcherbinin, V. (2009) · 2009 Ninth IEEE International Conference on Advanced Learning Technologies · doi:10.1109/icalt.2009.78 · Cited by 12
Rahman, M. K. M., & Chow, T. W. S. (2010) · Expert Systems with Applications · doi:10.1016/j.eswa.2009.09.002 · Cited by 11
Intelligent plagiarists are the most dangerous
Stenflo, L. (2004) · Nature · doi:10.1038/427777a · Cited by 10 · cited 1×
“" What is worse are cases where scientists rewrite previous findings in different words, purposely hiding the sources of their ideas " [73].”
BackgroundA Platform Framework for Cross-Lingual Text Relatedness Evaluation and Plagiarism Detection
Lee, C.-H., Wu, C.-H., & Yang, H.-C. (2008) · International Conference on Innovative Computing, Information and Control · doi:10.1109/icicic.2008.76 · Cited by 9
Detecting translations of the same text and data with common source
Koroutchev, K., & Cebrián, M. (2006) · Journal of Statistical Mechanics: Theory and Experiment · doi:10.1088/1742-5468/2006/10/p10009 · Cited by 9 · cited 2×
“stemming, the approach in [6], [12], and [13] reduces the text into a smaller set of syntactical tags, thus making use of most of the content.”
BackgroundTambouratzis, G. (2004) · Literary and Linguistic Computing · doi:10.1093/llc/19.2.197 · Cited by 9
Authors, Genre, and Linguistic Convention
(2007) · Cited by 8
Work in Progress: Developing Arabic Plagiarism Detection Tool for E-Learning Systems
Alzahrani, S. M., Salim, N. B., & Alsofyani, M. M. (2009) · International Association of Computer Science and Information Technology · doi:10.1109/iacsit-sc.2009.22 · Cited by 8
Self-citationAuthor verification by linguistic profiling
(2007) · doi:10.1145/1217098.1217099 · Cited by 7
Document plagiarism detection algorithm using semantic networks
Muftah, A. M., & Jabr, A. (2009) · Cited by 7
Avoiding plagiarism in academic writing.
Anderson, I. (2009) · Nursing Standard · doi:10.7748/ns.23.18.35.s51 · Cited by 7
A word-frequency based method for detecting plagiarism in documents
Lackes, R., Bartels, J., Berndt, E., & Frank, E. (2009) · IEEE International Conference on Information Reuse and Integration (IRI) · doi:10.1109/iri.2009.5211544 · Cited by 6
Soft Computing Pattern Recognition, Data Mining and Web Intelligence
Pal, S. K., Mitra, S., & Mitra, P. (2004) · Springer eBooks · doi:10.1007/978-3-662-07952-2_19 · Cited by 3
Program plagiarism revisited: current issues and approaches
(1988) · doi:10.1145/52964.53020 · Cited by 3
Program plagiarism revisited: current issues and approaches
(1988) · doi:10.1145/52965.53020 · Cited by 2
Sorokina, D., Gehrke, J. E., Warner, S. M., et al. (2007) · doi:10.48550/arxiv.cs/0702012 · Cited by 2
PAN Plagiarism Corpus 2010 (PAN-PC-10)
Potthast, M., Stein, B., Eiselt, A., et al. (2010) · Figshare · doi:10.5281/zenodo.3250122 · Cited by 1
(2010)
Self-citation
Research works printed but not linked: 12
- alzahrani, 2008, Plagiarism detection in Arabic scripts using fuzzy information retrieval, presented at the Student Conf Res Develop
- ceska, 0, The future of copy detection techniques, Proc YRCAS, 5
- palkovskii, 0, Counter plagiarism detection software” and “Counter counter plagiarism detection” methods, Proc SEPLN, 67
- 10.1016/j.esp.2009.01.004 · doi:10.1016/j.esp.2009.01.004
- rao, 2008, Plagiarism, a scourge, Current Sci, 94, 581
- rijsbergen, 1979, Information Retrieval
- balaguer, 0, Putting ourselves in SME's shoes: Automatic detection of plagiarism by the WCopyFind tool, Proc SEPLN, 34
- manning, 2009, Introduction to Information Retrieval, 109
- alzahrani, 2009, Statement-based fuzzy-set IR versus fingerprints matching for plagiarism detection in arabic documents, Proceedings of the Postgraduate Annual Research Seminar, 267
- heintze, 1996, Scalable document fingerprinting, Proc 2nd Usenix Workshop Electron Commerce, 191
- 10.1017/CBO9780511809071 · DOI · Paper page
- manning, 2009, Introduction to Information Retrieval, 403
Cited by
Academic Plagiarism Detection: A Systematic Literature Review
Foltýnek, T., Meuschke, N., & Gipp, B. (2020) · ACM Computing Surveys · doi:10.1145/3345317 · Cited by 238
Surveying Stylometry Techniques and Applications
Neal, T., Sundararajan, K., Fatima, A., Yan, Y., Xiang, Y., & Woodard, D. (2018) · ACM Computing Surveys · doi:10.1145/3132039 · Cited by 222
An improved plagiarism detection scheme based on semantic role labeling
Osman, A. H., Salim, N. B., Binwahlan, M. S., Alteeb, R., & Abuobieda, A. (2012) · Applied Soft Computing · doi:10.1016/j.asoc.2011.12.021 · Cited by 115
Self-citationKauffman, Y., & Young, M. F. (2015) · Computers & Education · doi:10.1016/j.compedu.2014.12.016 · Cited by 101
Pudasaini, S., Miralles-Pechuán, L., Lillis, D., & Llorens Salvador, M. (2025) · Journal of Academic Ethics · doi:10.1007/s10805-024-09576-x · Cited by 70
Metadata
- Authors
- Alzahrani, S. M., Salim, N., & Abraham, A.
- Affiliations
- Taif University (SA)
- University of Technology Malaysia (MY)
- VSB - Technical University of Ostrava (CZ)
- Venue
- IEEE Transactions on Systems, Man, and Cybernetics, Part C (Applications and Reviews)
- Published
- 2012-03
- Volume
- 42
- Issue
- 2
- Pages
- 133-149
- ISSN
- 1094-6977 (ISSN-L)
- 1558-2442
- OpenAlex
- W2147742901
- Cited by
- 299
- References
- 168
- Citations by year
- 2026: 17 · 2025: 8 · 2024: 18 · 2023: 7 · 2022: 12 · 2021: 23 · 2020: 27 · 2019: 30 · 2018: 24 · 2017: 27 · 2016: 26 · 2015: 28 · 2014: 25 · 2013: 15 · 2012: 8
- FWCI
- 43.02
- Type
- journal article
- Language
- en
- Open access
- closed
- Locations
- IEEE Transactions on Systems Man and Cybernetics Part C (Applications and Reviews) (publishedVersion)
- Oxford University Research Archive (ORA) (University of Oxford) (submittedVersion)
- Topics
- Social Sciences › Education › Academic integrity and plagiarism
- Physical Sciences › Computer Science › Artificial Intelligence › Authorship Attribution and Profiling
- Physical Sciences › Computer Science › Information Systems › Software Engineering Research
- Keywords
- plagiarism detection, text features, stylometry, character n-grams
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
The claim verdicts this report counts are experimental: their accuracy is not yet measured.
A language model drew the claims from the paper on 2026-10-10, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-10-10 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Cited sources are checked with a language model’s help (qwen3.8-omni-flash).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
