

The DOI matches its Crossref record; 59 of the 59 references it cites were found in a registry or an index; none of the 30 sources its claims cite is checked for support yet.
‘Just like I thought’: Street‐level bureaucrats trust AI recommendations if they confirm their professional judgment
Open accessAbstract
Artificial Intelligence is increasingly used to support and improve street‐level decision‐making, but empirical evidence on how street‐level bureaucrats' work is affected by AI technologies is scarce. We investigate how AI recommendations affect street‐level bureaucrats' decision‐making and if explainable AI increases trust in such recommendations. We experimentally tested a realistic mock predictive policing system in a sample of Dutch police officers using a 2 × 2 factorial design. We found that police officers trust and follow AI recommendations that are congruent with their intuitive professional judgment. We found no effect of explanations on trust in AI recommendations. We conclude that police officers do not blindly trust AI technologies, but follow AI recommendations that confirm what they already thought. This highlights the potential of street‐level discretion in correcting faulty AI recommendations on the one hand, but, on the other hand, poses serious limits to the hope that fair AI systems can correct human biases.
Overview
CoChat Summary
TL;DR
In a 2×2 vignette experiment with 124 Dutch police officers and 294 observations, officers trusted AI recommendations more when they were congruent with their professional judgment, while explanations did not significantly affect trust. Higher trust was associated with greater likelihood of following the AI recommendation, suggesting confirmation bias rather than automation bias.
Key findings
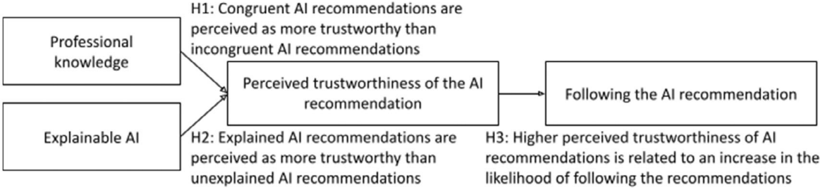
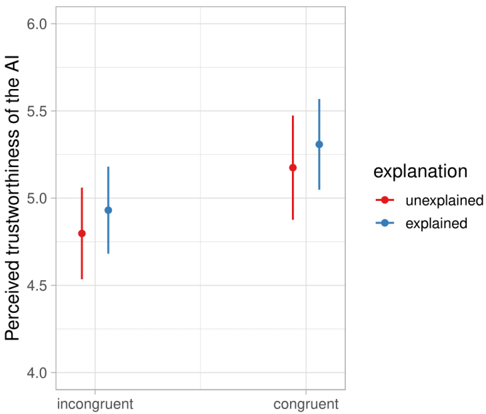
- H1 supported: police officers perceived AI recommendations congruent with their professional knowledge as more trustworthy than incongruent recommendations (β = −.377 [−.622, −.132], p = .003; group means on 1–7 trust scale: incongruent unexplained 4.73, incongruent explained 4.98, congruent unexplained 5.26, congruent explained 5.25).
- H2 not supported: explained versus unexplained AI recommendations had no statistically significant effect on trust (β = −.133 [−.400, .134], p = .328); the interaction between congruence and explanation was also not significant (β = −.259 [−.888, .371], p = .42).
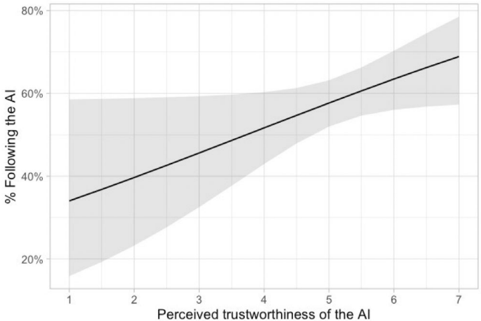
- H3 supported: higher perceived trustworthiness was associated with increased likelihood of following the AI recommendation (β = .243 [.006, .480], p = .045).
- Manipulation checks: congruency check mean 4.65, SD 1.63, t = 5.65, p < .001; explanation-detail check mean 4.49, SD 1.48, t = 3.34, p < .001; mundane realism mean 5.24, SD 1.25.
Methods
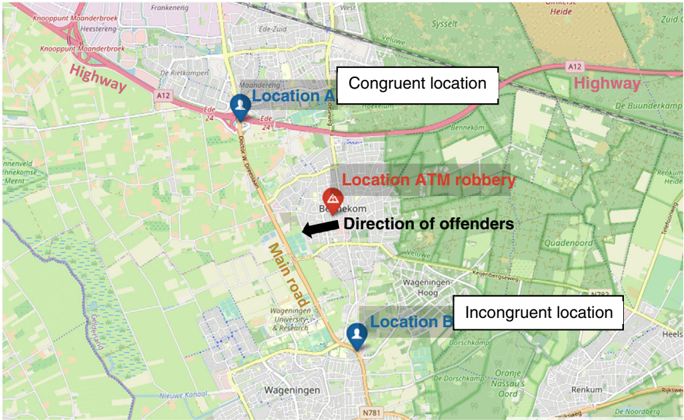
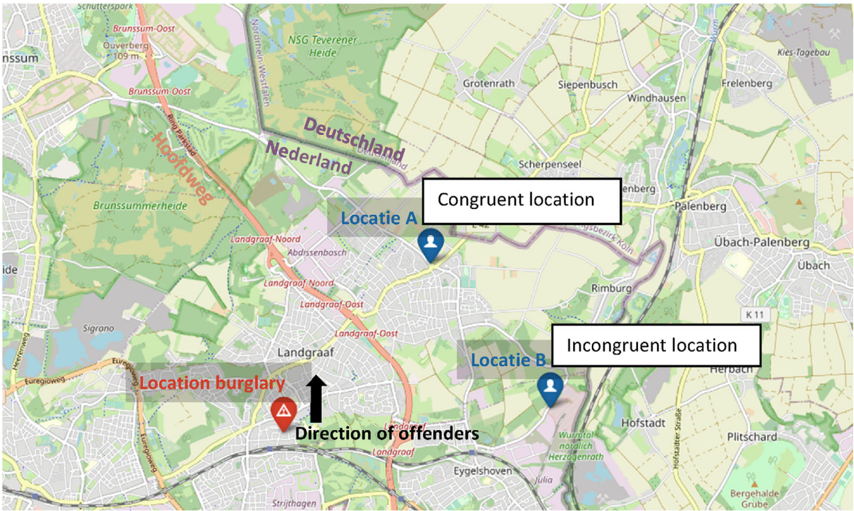
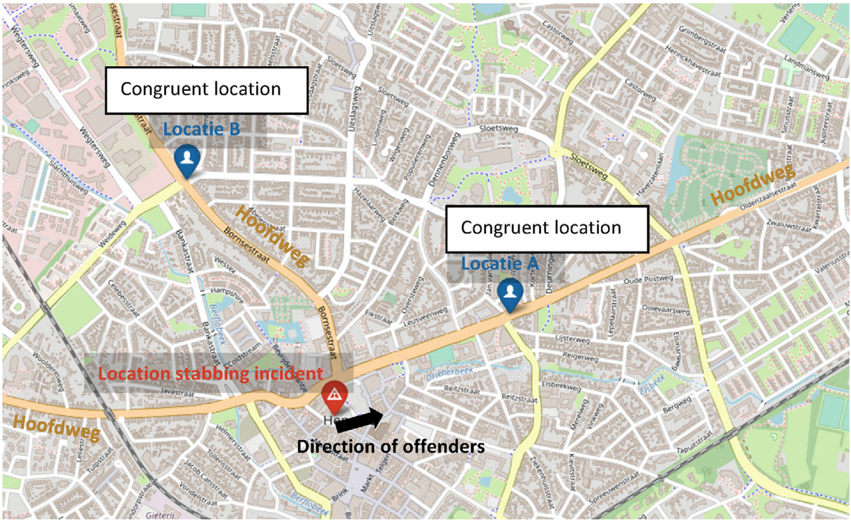
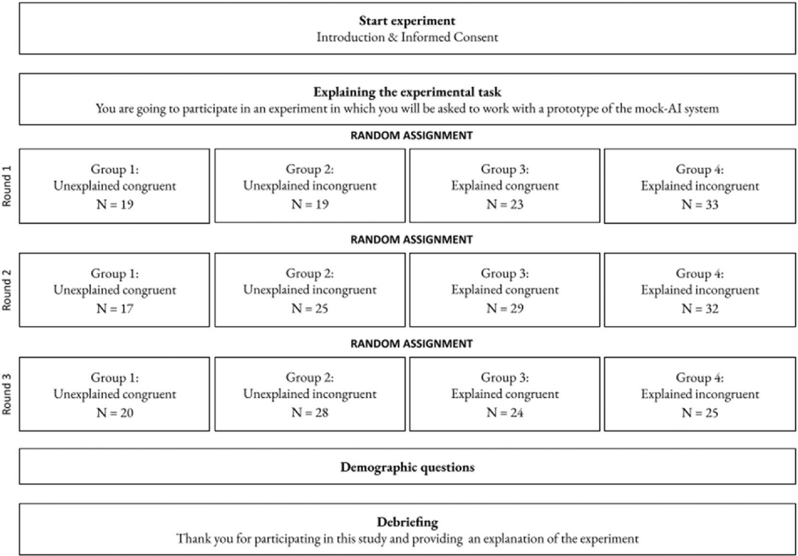
- Design: 2×2 repeated measures factorial vignette experiment with three scenarios (burglary, ATM robbery, stabbing incident); factors were AI recommendation congruent/incongruent with intuitive professional knowledge and explained/unexplained; the mock predictive policing system was based on a system developed by the Dutch police.
- Sample/data: population-based sample of Dutch street-level police officers; survey sent to approximately 400 officers, 152 responded, 28 excluded, final N = 124 officers and 294 vignettes; average age approximately 47.9, 25% female, 93% executive status; data collected May–June 2021.
- Analysis: Generalized Estimating Equations (GEE) using the Geepack package in R to account for repeated measures; trust scale included four items plus a direct trust item (Cronbach’s alpha above .92; factor loadings above .74); follow/override was a dummy variable; robustness checks with two-way ANOVA and logistic regression produced equal results.
Limitations
- The paper states that survey experiments remain artificial despite high mundane realism, and calls for field experiments in “messy” settings where police officers work in teams or under time pressure.
- The paper states that the study focuses on police officers and one type of local XAI; it calls for testing other street-level bureaucrats, other AI systems and organizational contexts, global explanations, and repeated use of reliable AI systems.
- Evident/paper-stated: no attention checks were used, and inclusion required completing at least one scenario, so inattentive responses may remain (the paper frames this as an intent-to-treat effect and external-validity strength); also, there was a small but statistically significant baseline difference in general trust in technology between the congruent unexplained and incongruent unexplained groups (less than 0.6 point on a 1–7 scale), which the authors do not believe substantially affected the findings.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
0 Valid · 0 Not valid · 23 Not checked · 62 Own results and interpretations
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We also explored an interaction between the congruence and explanation manipulations but found no significant effect (β = À.259 [À.888, .371],p = .42).”
§ 'Just like I thought': Street-level bureaucrats trust AI recommendations if they confirm their professional judgment > RESULTS
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“As indicated in Table 2, this manipulation was also successful: police officers perceived the explained AI recommendation to be more detailed than the unexplained AI recommendation.”
§ 'Just like I thought': Street-level bureaucrats trust AI recommendations if they confirm their professional judgment > Manipulation checks
hedgedstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“In contrast, we found no support for H2.While Figure 3 seems to show the existence of some effect of explaining the AI recommendation on how trustworthy the police officers perceived the AI recommendation to be, the GEE demonstrates that this effect was not statistically significant (β = À.133 [À.400, .134],p = .328).”
§ 'Just like I thought': Street-level bureaucrats trust AI recommendations if they confirm their professional judgment > RESULTS
boosted- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“An increase in perceived trustworthiness is statistically significantly related to an increase in the likelihood of police officers following the AI recommendation (β = .243[.006, .480],p = .045).”
§ 'Just like I thought': Street-level bureaucrats trust AI recommendations if they confirm their professional judgment > RESULTS
plainstates an association- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Rests on an assumption not shown here.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We found no effect of explanations on trust in AI recommendations.”
- Also stated in: § What is the effect of AI recommendations and explainable AI on decision-making of street-level police officers? · plain
“Moreover, we found that police officers' trust in AI recommendations is not affected by AI-generated explanations (XAI)”
§ 'Just like I thought': Street-level bureaucrats trust AI recommendations if they confirm their professional judgment > Abstract
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Also stated in: § What is the effect of AI recommendations and explainable AI on decision-making of street-level police officers? · plain
29 more claims
Create a free account to see all 85 claims and to verify the 19 references still open.
- Probably not a substantial claim. 41
- It may state two separate claims as one. 19
- The quote only partly states this claim. 1
Statistics that don’t add up
Each reported p-value recomputed from its test statistic and degrees of freedom.
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
“F(3, 280) = 0.182, p = .14”
§ 'Just like I thought': Street-level bureaucrats trust AI recommendations if they confirm their professional judgment > A PP E N D IX B : SUMMARY OF EXPERIMENTAL SCENARIOS (TRANSLATED FROM DUTCH)
Reported p = .14 · recomputed p = .909
Statistics recomputed
Every reported test result, recomputed from its test statistic and degrees of freedom. A result shows as not adding up only once an independent check has confirmed it.
- Doesn’t add upF(3, 280) = 0.182reported p = .14 · recomputed p = .909
“F(3, 280) = 0.182, p = .14”
- ConsistentF(3, 280) = 0.81reported p = .49 · recomputed p = .489
“F(3, 280) = 0.81, p = .49”
- ConsistentF(3, 280) = 0.53reported p = .66 · recomputed p = .662
“F(3, 280) = 0.53, p = .66”
- ConsistentF(3, 280) = 2.89reported p = .04 · recomputed p = .036
“F(3, 280) = 2.89, p = .04”
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Each contradiction between two passages listed here was confirmed by an independent check.
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ 'Just like I thought': Street-level bureaucrats trust AI recommendations if they confirm their professional judgment > ARTIFICIAL INTELLIGENCE IN STREET-LEVEL BUREAUCRACY
“H1. Street-level bureaucrats perceive AI recommendations that are congruent with their professional judgment as more trustworthy than AI recommendations that are incongruent with their professional judgment.”
§ 'Just like I thought': Street-level bureaucrats trust AI recommendations if they confirm their professional judgment > A PP E N D I X D : DEVIATIONS FROM PRE-ANALYSIS PLAN
“H2 The second hypothesis in the pre-registry (In general, police officers are more likely to trust algorithmic advice that complies with their tacit knowledge than algorithmic advice that conflicts with their tacit knowledge) is rephrased in the article to H2 (Street-level bureaucrats perceive AI recommendations that are congruent with their professional judgment as more trustworthy than AI recommendations that are incongruent with their professional judgment).”
Citations
Cites
Longitudinal data analysis using generalized linear models
LIANG, K.-Y., & ZEGER, S. L. (1986) · Biometrika · doi:10.1093/biomet/73.1.13 · Cited by 18,550
"Why Should I Trust You?": Explaining the Predictions of Any Classifier
Ribeiro, M. T., Singh, S., & Guestrin, C. (2016) · Proceedings of the 22nd ACM SIGKDD International Conference on Knowledge Discovery and Data Mining · doi:10.1145/2939672.2939778 · Cited by 17,555
An integrative model of organizational trust
Mayer, R. C., Davis, J. H., & Schoorman, F. D. (1995) · The Academy of Management Review · doi:10.2307/258792 · Cited by 10,736
The case for motivated reasoning.
Kunda, Z. (1990) · Psychological Bulletin · doi:10.1037/0033-2909.108.3.480 · Cited by 9,022
Street-Level Bureaucracy: Dilemmas of the Individual in Public Services
Lipsky, M. (1981) · Michigan Law Review · doi:10.2307/1288305 · Cited by 8,981
Peeking Inside the Black-Box: A Survey on Explainable Artificial Intelligence (XAI)
Adadi, A., & Berrada, M. (2018) · IEEE Access · doi:10.1109/access.2018.2870052 · Cited by 6,294
Explanation in artificial intelligence: Insights from the social sciences
Miller, T. (2019) · Artificial Intelligence · doi:10.1016/j.artint.2018.07.007 · Cited by 5,302
Motivated Skepticism in the Evaluation of Political Beliefs
Taber, C. S., & Lodge, M. (2006) · American Journal of Political Science · doi:10.1111/j.1540-5907.2006.00214.x · Cited by 4,344
Kim, D. J., Ferrin, D. L., & Rao, H. R. (2008) · Decision Support Systems · doi:10.1016/j.dss.2007.07.001 · Cited by 3,613
How the machine “thinks”: Understanding opacity in machine learning algorithms
Burrell, J. (2016) · Big Data & Society · doi:10.1177/2053951715622512 · Cited by 3,196
Research works printed but not linked: 2
- Kahneman Daniel, 2013, Thinking, Fast and Slow
- O'Neill Cathy, 2016, Weapons of Math Destruction: How Big Data Increases Inequality and Threatens Democracy
Cited by
Managing with Artificial Intelligence: An Integrative Framework
Hillebrand, L., Raisch, S., & Schad, J. (2025) · Academy of Management Annals · doi:10.5465/annals.2022.0072 · Cited by 210
Exploring automation bias in human–AI collaboration: a review and implications for explainable AI
Romeo, G., & Conti, D. (2026) · AI & SOCIETY · doi:10.1007/s00146-025-02422-7 · Cited by 209
“In like manner, the studies by Selten et al. (2023) and Bashkirova and Krpan (2024) found no evidence for AB, emphasizing confirmation bias as a more dominant cognitive mechanism in AI-assisted decision-making.”
Maragno, G., Tangi, L., Gastaldi, L., & Benedetti, M. (2023) · International Journal of Information Management · doi:10.1016/j.ijinfomgt.2023.102686 · Cited by 185
Human-centered evaluation of explainable AI applications: a systematic review
Kim, J., Maathuis, H., & Sent, D. (2024) · Frontiers in Artificial Intelligence · doi:10.3389/frai.2024.1456486 · Cited by 130
Bright, J., Enock, F., Esnaashari, S., Francis, J., Hashem, Y., & Morgan, D. (2025) · Digital Government: Research and Practice · doi:10.1145/3700140 · Cited by 32
Metadata
- Authors
- Selten, F., Robeer, M., & Grimmelikhuijsen, S.
- Affiliations
- Leiden University (NL)
- Utrecht University (NL)
- Corresponding author
- Selten, Friso
- Venue
- Public Administration Review
- Publisher
- Wiley
- Published
- 2023-01-22
- Volume
- 83
- Issue
- 2
- Pages
- 263-278
- ISSN
- 0033-3352 (ISSN-L)
- 1540-6210
- OpenAlex
- W4313590506
- Cited by
- 153
- References
- 58
- Citations by year
- 2026: 73 · 2025: 52 · 2024: 19 · 2023: 8
- FWCI
- 10.53
- Type
- journal article
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- Locations
- Public Administration Review (publishedVersion, cc-by)
- Utrecht University Repository (Utrecht University) (submittedVersion, other-oa)
- Funders
- Nederlandse Organisatie voor Wetenschappelijk Onderzoek (406.DI.19.011)
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Ethics and Social Impacts of AI
- Social Sciences › Political Science and International Relations › Policing Practices and Perceptions
- Social Sciences › Law › Artificial Intelligence in Law
- Keywords
- street-level bureaucracy, artificial intelligence, trust in AI, explainable AI, police decision-making, predictive policing, professional judgment, algorithmic decision support, human-AI interaction, algorithmic fairness, human bias
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
A language model drew the claims from the paper on 2026-11-14, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-11-14 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
