

Self-supervised Human Activity Recognition by Learning to Predict Cross-Dimensional Motion
Open accessThe DOI matches its Crossref record; 34 of the 36 references it cites were found in a registry or an index; 12 of the 25 sources its claims cite were checked for support.
Abstract
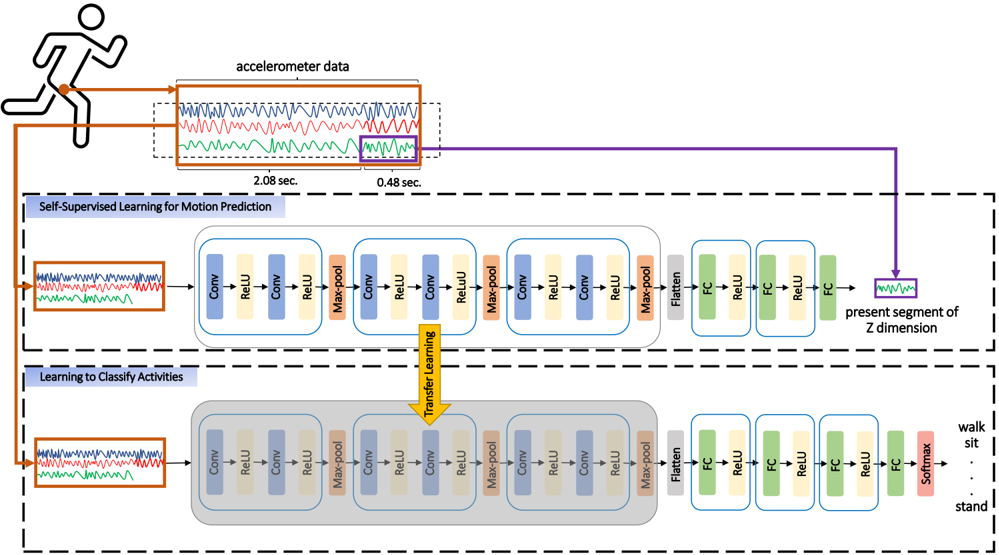
We propose the use of self-supervised learning for human activity recognition with smartphone accelerometer data. Our proposed solution consists of two steps. First, the representations of unlabeled input signals are learned by training a deep convolutional neural network to predict a segment of accelerometer values. Our model exploits a novel scheme to leverage past and present motion in x and y dimensions, as well as past values of the z axis to predict values in the z dimension. This cross-dimensional prediction approach results in effective pretext training with which our model learns to extract strong representations. Next, we freeze the convolution blocks and transfer the weights to our downstream network aimed at human activity recognition. For this task, we add a number of fully connected layers to the end of the frozen network and train the added layers with labeled accelerometer signals to learn to classify human activities. We evaluate the performance of our method on three publicly available human activity datasets: UCI HAR, MotionSense, and HAPT. The results show that our approach outperforms the existing methods and sets new state-of-the-art results.
Overview
CoChat Summary
TL;DR
The paper proposes a self-supervised human activity recognition framework that learns accelerometer representations by predicting future z-axis motion from past/present x and y and past z, then freezes the convolutional blocks and transfers them to a downstream HAR classifier. It reports state-of-the-art results on UCI HAR, MotionSense, and HAPT.
Key findings
- The pretext motion-prediction task achieved \(R^2 = 0.682 \pm 0.062\), which the authors interpret as strongly learned representations.
- On UCI HAR, the self-supervised model reached accuracy \(0.908 \pm 0.036\) and weighted F1 \(0.908 \pm 0.036\); fine-tuning gave accuracy \(0.906 \pm 0.038\) and weighted F1 \(0.906 \pm 0.038\).
- On MotionSense, the self-supervised model reached accuracy \(0.920 \pm 0.022\) and weighted F1 \(0.921 \pm 0.022\); fine-tuning improved accuracy to \(0.933 \pm 0.024\) and weighted F1 to \(0.934 \pm 0.023\).
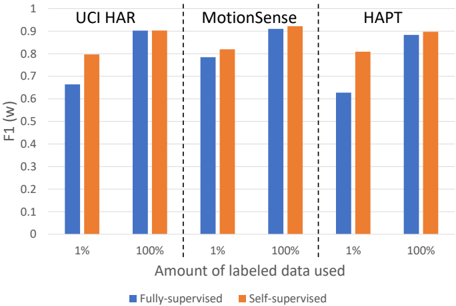
- On HAPT, the self-supervised model reached accuracy \(0.899 \pm 0.034\) and weighted F1 \(0.898 \pm 0.034\); fine-tuning gave accuracy \(0.901 \pm 0.038\) and weighted F1 \(0.900 \pm 0.038\). With only 1% labeled data, the self-supervised model clearly outperformed a fully supervised model of the same architecture, while at 100% labeled data the two were relatively similar.
Methods
- Two-stage design: a deep CNN \(H_{predict}\) is trained with MSE loss to predict a 0.48-second future segment of the z axis from 2.56 seconds of x and y and 2.08 seconds of past z, with 50% overlap between input segments. The convolution blocks are then frozen and transferred to \(H_{HAR}\), which adds fully connected layers and is trained with entropy loss and 20% dropout.
- Data: three public smartphone accelerometer datasets — UCI HAR (30 participants, 6 activities, 50 Hz), MotionSense (24 participants, 6 activities, 50 Hz), and HAPT (30 participants, 12 activities, 50 Hz).
- Evaluation: user-split holdout validation, randomly selecting 20% of participants per dataset for testing and 10% of training data for validation, repeated 5 times so all users appear once in the test set and 4 times in training; results are averaged. Metrics are \(R^2\) for pretext prediction and accuracy plus mean/weighted F1 for HAR.
Limitations
- The paper states future work could use additional datasets for the pretext self-supervised task to improve generalized motion representations, and that CNN-RNN-based methods may better learn temporal dependencies. No explicit limitations section is provided.
- Evident from the text: all downstream evaluations are within individual datasets, and no cross-dataset transfer results are reported despite the claim that the learned features can be used across different datasets.
- Evident from the text: the method uses accelerometer signals only, although the described datasets also contain gyroscope data.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
9 Valid · 1 Not valid · 5 Not checked · 24 Own results and interpretations
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“This is the first time that motion prediction with cross-dimensional learning has been used for self-supervised learning in the context of HAR.”
- Also stated in: § Self-supervised Human Activity Recognition by Learning to Predict Cross-Dimensional Motion · p. 1 · plain
“While motion prediction has been used in the field of computer vision for self-supervised learning [23, 26], our model is novel in that the cross-dimensional aspect results in more effective learning.”
What the sources say
- Partly supportedcites [23] [23] Nitish Srivastava, Elman Mansimov, and Ruslan Salakhudinov. 2015. Unsupervised Learning of Video Representations using LSTMs. In Proceedings of the 32nd International Conference on Machine Learning , Vol. 37. PMLR, 843-852. - sourceExperimental — accuracy not yet measured
Our copy does support the general substance: the LSTM Future Predictor model uses future-frame (motion) prediction as an unsupervised objective (§2.3, p. 4; §1.2, p. 2: 'Another option is to predict the future frames... extrapolate the motion and appearance beyond what has been observed'), and the learned representations are fine-tuned and evaluated for human action recognition on UCF-101/HMDB-51 (§3.3–3.5, pp. 8–11). Two parts attributed to this source are not in it: (1) 'cross-dimensional learning' — §1.2 (p. 2) limits inputs to two kinds, pixel patches or convnet 'percepts', and the decoders reconstruct/predict frames of the same kind, so no cross-representation-space objective is described; (2) the novelty assertion 'this is the first time' — the paper makes no priority claim anywhere, and §1.3 Related Work (p. 2) instead credits earlier unsupervised video-representation work (ICA-based approaches, Le et al. 2011, Memisevic 2013; Memisevic & Hinton 2010, Susskind et al. 2011, extended by Michalski et al. 2014 to longer sequences). (LLM, conf=0.75)
- Not checked — no full text of the sourcecites [26] [26] Jiangliu Wang, Jianbo Jiao, Linchao Bao, Shengfeng He, Yunhui Liu, and Wei Liu. 2019. Self-supervised spatio-temporal representation learning for videos by predicting motion and appearance statistics. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition . IEEE, 4006-4015. - source
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: unclear — It is unclear why the paper says it holds.
- Also stated in: § Self-supervised Human Activity Recognition by Learning to Predict Cross-Dimensional Motion · p. 1 · plain
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“While motion prediction has been used in the field of computer vision for self-supervised learning [23, 26], our model is novel in that the cross-dimensional aspect results in more effective learning.”
- Also stated in: § 2.2 HARwith Self-Supervised Learning · p. 2 · plain
“Our model uses cross-dimensional learning to leverage some axis to predict motion in the other axis, which results in more effective pre-text learning.”
What the sources say
- Partly supportedcites [23] [23] Nitish Srivastava, Elman Mansimov, and Ruslan Salakhudinov. 2015. Unsupervised Learning of Video Representations using LSTMs. In Proceedings of the 32nd International Conference on Machine Learning , Vol. 37. PMLR, 843-852. - sourceExperimental — accuracy not yet measured
Our copy confirms the half of the sentence the citation actually anchors: Srivastava et al. (2015) use future-frame (motion) prediction as an unsupervised/self-supervised objective for video representations (Sec. 1.2, p. 2; Sec. 2.3 'LSTM Future Predictor Model', p. 4), and evaluate it on action recognition (Sec. 3.5, p. 11). Nothing in our copy supports the cross-dimensional part of the paraphrase: the paper's pretext task is standard same-space future prediction (reconstructing/predicting pixel patches or CNN 'percepts' of frames), it defines no 'cross-dimensional' variant, and it makes no comparison showing such a variant learns more effectively than standard motion prediction (Tables 1-2 compare Autoencoder/Future Predictor/Conditional/Composite variants only, pp. 10-11). The 'our model is novel' clause is the citing authors' own contribution, not a finding of this source. (LLM, conf=0.78)
- Not checked — no full text of the sourcecites [26] [26] Jiangliu Wang, Jianbo Jiao, Linchao Bao, Shengfeng He, Yunhui Liu, and Wei Liu. 2019. Self-supervised spatio-temporal representation learning for videos by predicting motion and appearance statistics. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition . IEEE, 4006-4015. - source
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: unclear — It is unclear why the paper says it holds.
- Also stated in: § 2.2 HARwith Self-Supervised Learning · p. 2 · plain
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“Nonetheless, for both UCI HAR and HAPT, our fine-tuned self-supervised models outperform the fine-tuned models proposed by [19] and [20].”
What the sources say
- Partly supportedcites [19] [19] Aaqib Saeed, Tanir Ozcelebi, and Johan Lukkien. 2019. Multi-task self-supervised learning for human activity detection. Proceedings of the ACM on Interactive, Mobile, Wearable and Ubiquitous Technologies 3, 2 (2019), 1-30. - sourceExperimental — accuracy not yet measured
Table 2 (p. 14) identifies Saeed et al.’s fine-tuned self-supervised model, and Section 4.3 (p. 13) reports its evaluation on UCI HAR. Table 1 and Section 4.1 (pp. 8–10) list the evaluated datasets but not HAPT. The source therefore supports identifying a UCI HAR model for comparison, but not a fine-tuned HAPT model; the citing authors’ own performance comparison cannot be established from this source alone. (LLM, conf=0.86)
- Supportedcites [20] [20] Aaqib Saeed, Victor Ungureanu, and Beat Gfeller. 2020. Sense and Learn: SelfSupervision for Omnipresent Sensors. arXiv:2009.13233 [cs.LG] - source
Section 4.3.1 describes fine-tuning the paper’s self-supervised encoder and explicitly discusses results for both HAPT and UCI HAR. The citation identifies this paper’s models as comparators; the citing authors’ assertion that their own models outperform them is not a result attributed to this source. (LLM, conf=0.90)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Rests on an assumption not shown here.
- Partly supported
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“We show that our method outperforms existing self-supervised methods in HAR for UCI HAR, MotionSense, and HAPT datasets.”
What the sources say
- Partly supportedcites [19] [19] Aaqib Saeed, Tanir Ozcelebi, and Johan Lukkien. 2019. Multi-task self-supervised learning for human activity detection. Proceedings of the ACM on Interactive, Mobile, Wearable and Ubiquitous Technologies 3, 2 (2019), 1-30. - sourceExperimental — accuracy not yet measured
Table 1 (p. 10) lists UCI HAR and MotionSense among the evaluated datasets, and the Conclusions (p. 23) report that the proposed self-supervised approach performed significantly better than traditional unsupervised methods such as autoencoders. The paper does not list HAPT or establish that its method outperformed existing self-supervised methods; those parts of the attributed claim are unsupported. (LLM, conf=0.88)
- Not checked — no full text of the sourcecites [8] [8] Harish Haresamudram, Apoorva Beedu, Varun Agrawal, Patrick L. Grady, Irfan Essa, Judy Hoffman, and Thomas Plötz. 2020. Masked reconstruction based selfsupervision for human activity recognition. In Proceedings of the International Symposium on Wearable Computers . Association for Computing Machinery, New York, NY, USA, 45-49. - source
- Partly supportedcites [20] [20] Aaqib Saeed, Victor Ungureanu, and Beat Gfeller. 2020. Sense and Learn: SelfSupervision for Omnipresent Sensors. arXiv:2009.13233 [cs.LG] - sourceExperimental — accuracy not yet measured
Section 4.3.2 reports improved activity-recognition F-scores on UCI HAR, HAPT, and MotionSense, but compares the method with fully supervised models in a low-data setting. The comparison tables in Sections 4.3.3–4.3.4 include some self-supervised baselines, such as autoencoders; they do not establish the broader claim that the method outperforms existing self-supervised methods generally on all three datasets. (LLM, conf=0.79)
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Partly supported
Every source the paper cites for this claim was checked and supports it.
In the paper
“| Saeed et al. [20] (SS) | - | - | 0.863 ± 0.045 |”
What the sources say
- Supportedcites [20] [20] Aaqib Saeed, Victor Ungureanu, and Beat Gfeller. 2020. Sense and Learn: SelfSupervision for Omnipresent Sensors. arXiv:2009.13233 [cs.LG] - source
Table A.8 (section 4.3.4; page unavailable) reports 0.863 ± 0.045 for the Transformations self-supervised method on HAPT under five-fold user-split cross-validation. Section 4.2 states that the paper reports weighted F-scores. (LLM, conf=0.94)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Supported
25 more claims · 2 with their cited sources checked
Create a free account to see all 39 claims and every source verdict.
- It may state two separate claims as one. 5
- The quote only partly states this claim. 2
- Probably not a substantial claim. 6
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Each contradiction between two passages listed here was confirmed by an independent check.
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ 3.2 Implementation Details · p. 3
“The 𝐻 𝑝𝑟𝑒𝑑𝑖𝑐𝑡 kernel size is set to 3 for all the convolution layers.”
§ 3.2 Implementation Details · p. 3
“[ conv , 1 × 2 , 384 ]”
Citations
Cites
(2013) · RECERCAT (Consorci de Serveis Universitaris de Catalunya) · Cited by 1,959
Unsupervised Learning of Video Representations using LSTMs
Srivastava, N., Mansimov, E., & Salakhutdinov, R. (2015) · arXiv · doi:10.48550/arxiv.1502.04681 · Cited by 1,861 · cited 1×
“While motion prediction has been used in the field of computer vision for self-supervised learning [23, 26], our model is novel in that the cross-dimensional aspect results in more effective learning.”
MethodNweke, H. F., Teh, Y. W., Al-garadi, M. A., & Alo, U. R. (2018) · Expert Systems with Applications · doi:10.1016/j.eswa.2018.03.056 · Cited by 930 · cited 1×
“A detailed survey on different deep learning solutions for HAR is available in [14].”
BackgroundLSTM-CNN Architecture for Human Activity Recognition
Xia, K., Huang, J., & Wang, H. (2020) · IEEE Access · doi:10.1109/access.2020.2982225 · Cited by 851 · cited 2×
“Recurrent neural networks (RNN), either alone or accompanying CNNs, have also been widely used for HAR applications [27, 29, 30].”
MethodTransition-Aware Human Activity Recognition Using Smartphones
Reyes-Ortiz, J.-L., Oneto, L., Samà, A., Parra, X., & Anguita, D. (2016) · Neurocomputing · doi:10.1016/j.neucom.2015.07.085 · Cited by 740 · cited 2×
“Three publicly available datasets, UCI HAR [1], MotionSense [13], and HAPT [18] are used to evaluate our model.”
MethodErmes, M., Parkka, J., Mantyjarvi, J., & Korhonen, I. (2008) · IEEE Transactions on Information Technology in Biomedicine · doi:10.1109/titb.2007.899496 · Cited by 707 · cited 1×
“Human activity recognition (HAR) has become a popular field of research due to its wide applications in health [15, 16], personalization of user experience [31], sports [6, 7], and others.”
BackgroundUnsupervised Representation Learning by Sorting Sequences
Lee, H.-Y., Huang, J.-B., Singh, M., & Yang, M.-H. (2017) · 2017 IEEE International Conference on Computer Vision (ICCV) · doi:10.1109/iccv.2017.79 · Cited by 534 · cited 1×
“Self-supervised learning has been previously explored in time-series representation learning applications such as computer vision [10, 12], bio-signal analysis (e.”
Bianchi, V., Bassoli, M., Lombardo, G., Fornacciari, P., Mordonini, M., & De Munari, I. (2019) · IEEE Internet of Things Journal · doi:10.1109/jiot.2019.2920283 · Cited by 466 · cited 3×
“For IMU-based HAR, [19] and [8] have used self-supervised learning.”
MethodSelf-Supervised ECG Representation Learning for Emotion Recognition
Sarkar, P., & Etemad, A. (2022) · IEEE Transactions on Affective Computing · doi:10.1109/taffc.2020.3014842 · Cited by 383 · cited 2×
“Self-supervised learning has been previously explored in time-series representation learning applications such as computer vision [10, 12], bio-signal analysis (e.g. ECG [21, 22] and EEG [3]), speech recognition [17], and others.”
BackgroundSelf-citationMulti-task Self-Supervised Learning for Human Activity Detection
Saeed, A., Ozcelebi, T., & Lukkien, J. (2019) · Proceedings of the ACM on Interactive, Mobile, Wearable and Ubiquitous Technologies · doi:10.1145/3328932 · Cited by 346 · cited 4×
“For IMU-based HAR, [19] and [8] have used self-supervised learning.”
BackgroundMethodInfluentialA Comparative Study on Human Activity Recognition Using Inertial Sensors in a Smartphone
Wang, A., Chen, G., Yang, J., Zhao, S., & Chang, C.-Y. (2016) · IEEE Sensors Journal · doi:10.1109/jsen.2016.2545708 · Cited by 324 · cited 3×
“Moreover, advances in machine learning and deep learning in recent years has resulted in a variety of different solutions being proposed for HAR [19, 25].”
BackgroundMulti-Task Self-Supervised Learning for Robust Speech Recognition
Ravanelli, M., Zhong, J., Pascual, S., Swietojanski, P., Monteiro, J., Trmal, J., & Bengio, Y. (2020) · ICASSP 2020 - 2020 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP) · doi:10.1109/icassp40776.2020.9053569 · Cited by 258 · cited 1×
“ECG [21, 22] and EEG [3]), speech recognition [17], and others.”
BackgroundWang, J., Jiao, J., Bao, L., He, S., Liu, Y., & Liu, W. (2019) · 2019 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2019.00413 · Cited by 210 · cited 1×
“While motion prediction has been used in the field of computer vision for self-supervised learning [23, 26], our model is novel in that the cross-dimensional aspect results in more effective learning.”
MethodProtecting sensory data against sensitive inferences
Malekzadeh, M., Clegg, R. G., Cavallaro, A., & Haddadi, H. (2018) · Spiral (Imperial College London) · Cited by 166
Protecting Sensory Data against Sensitive Inferences
Malekzadeh, M., Clegg, R. G., Cavallaro, A., & Haddadi, H. (2018) · Proceedings of the 1st Workshop on Privacy by Design in Distributed Systems · doi:10.1145/3195258.3195260 · Cited by 154 · cited 2×
“( 2 ) We test our method on three publicly available datasets , UCI HAR [1], MotionSense [13], and HAPT [18].”
MethodHuman activity recognition in pervasive health-care: Supporting efficient remote collaboration
Osmani, V., Balasubramaniam, S., & Botvich, D. (2007) · Journal of Network and Computer Applications · doi:10.1016/j.jnca.2007.11.002 · Cited by 149 · cited 1×
“Human activity recognition (HAR) has become a popular field of research due to its wide applications in health [15, 16], personalization of user experience [31], sports [6, 7], and others.”
BackgroundMasked reconstruction based self-supervision for human activity recognition
Haresamudram, H., Beedu, A., Agrawal, V., Grady, P. L., Essa, I., Hoffman, J., & Plötz, T. (2020) · Proceedings of the 2020 International Symposium on Wearable Computers · doi:10.1145/3410531.3414306 · Cited by 146 · cited 3×
“For IMU-based HAR, [19] and [8] have used self-supervised learning.”
BackgroundMethodSelf-Supervised Learning for ECG-Based Emotion Recognition
Sarkar, P., & Etemad, A. (2020) · ICASSP 2020 - 2020 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP) · doi:10.1109/icassp40776.2020.9053985 · Cited by 146 · cited 2×
“Self-supervised learning has been previously explored in time-series representation learning applications such as computer vision [10, 12], bio-signal analysis (e.g. ECG [21, 22] and EEG [3]), speech recognition [17], and others.”
BackgroundSelf-citationSelfHAR: Improving Human Activity Recognition through Self-training with Unlabeled Data
Tang, C. I., Perez-Pozuelo, I., Spathis, D., Brage, S., Wareham, N., & Mascolo, C. (2021) · Proceedings of the ACM on Interactive, Mobile, Wearable and Ubiquitous Technologies · doi:10.1145/3448112 · Cited by 140 · cited 1×
“In [24], teacher-student selftraining and multi-task self-supervision were combined to perform HAR task, in the context of semi-supervised learning.”
MethodSelf-Supervised Spatiotemporal Feature Learning via Video Rotation Prediction
Jing, L., Yang, X., Liu, J., & Tian, Y. (2018) · arXiv (Cornell University) · doi:10.48550/arxiv.1811.11387 · Cited by 119 · cited 1×
“Self-supervised learning has been previously explored in time-series representation learning applications such as computer vision [10, 12], bio-signal analysis (e.”
Automated daily human activity recognition for video surveillance using neural network
Babiker, M., Khalifa, O. O., Htike, K. K., Hashim, A. H. A., & Zaharadeen, M. (2017) · IEEE International Conference on Smart Instrumentation, Measurement and Applications (ICSIMA) · doi:10.1109/icsima.2017.8312024 · Cited by 110 · cited 1×
“A variety of different data modalities have been used in the past for HAR, for example, vision [2], IMU [11, 28, 30], motion capture [9], and even audio [5], among others.”
BackgroundYao, R., Lin, G., Shi, Q., & Ranasinghe, D. C. (2018) · Pattern Recognition · doi:10.1016/j.patcog.2017.12.024 · Cited by 105 · cited 4×
“A variety of different data modalities have been used in the past for HAR, for example, vision [2], IMU [11, 28, 30], motion capture [9], and even audio [5], among others.”
BackgroundMethodInfluentialSelf-Supervised Representation Learning from Electroencephalography Signals
Banville, H. J., Albuquerque, I., Hyvärinen, A., Moffat, G., Engemann, D. A., & Gramfort, A. (2019) · Machine learning for signal processing ... · doi:10.1109/mlsp.2019.8918693 · Cited by 90
Human Activity Recognition with Smartphone Inertial Sensors Using Bidir-LSTM Networks
Yu, S., & Qin, L. (2018) · International Conference on Mechanical, Control and Computer Engineering (ICMCCE) · doi:10.1109/icmcce.2018.00052 · Cited by 80 · cited 2×
“In [29], a bi-directional LSTM network was used to process both the past and future time-steps of the input signals.”
MethodChahuara, P., Fleury, A., Portet, F., & Vacher, M. (2016) · Journal of Ambient Intelligence and Smart Environments · doi:10.3233/ais-160386 · Cited by 77 · cited 1×
“A variety of different data modalities have been used in the past for HAR, for example, vision [2], IMU [11, 28, 30], motion capture [9], and even audio [5], among others.”
BackgroundHuman activity recognition using neural networks
Oniga, S., & Suto, J. (2014) · Proceedings of the 2014 15th International Carpathian Control Conference (ICCC) · doi:10.1109/carpathiancc.2014.6843636 · Cited by 74 · cited 3×
“While these approaches are generally robust and effective in terms of performance [15], they face a number of challenges and limitations.”
BackgroundSelf-supervised representation learning from electroencephalography signals
Banville, H. J., Albuquerque, I., Hyvärinen, A., Moffat, G., Engemann, D. A., & Gramfort, A. (2019) · HAL · Cited by 71
One-Shot Periodic Activity Recognition Using Convolutional Neural Networks
Ijjina, E. P., & Mohan, C. K. (2014) · International Conference on Machine Learning and Applications · doi:10.1109/icmla.2014.69 · Cited by 70 · cited 1×
“A variety of different data modalities have been used in the past for HAR, for example, vision [2], IMU [11, 28, 30], motion capture [9], and even audio [5], among others.”
BackgroundKeeping Users Engaged through Feature Updates: A Long-Term Study of Using Wearable-Based Exergames
Zhao, Z., Arya, A., Whitehead, A., Chan, G., & Etemad, S. A. (2017) · Proceedings of the 2017 CHI Conference on Human Factors in Computing Systems · doi:10.1145/3025453.3025982 · Cited by 52 · cited 1×
“Human activity recognition (HAR) has become a popular field of research due to its wide applications in health [15, 16], personalization of user experience [31], sports [6, 7], and others.”
BackgroundTeam Activity Recognition in Sports
Direkoğlu, C., & O'Connor, N. E. (2012) · Lecture notes in computer science · doi:10.1007/978-3-642-33786-4_6 · Cited by 37 · cited 1×
“Human activity recognition (HAR) has become a popular field of research due to its wide applications in health [15, 16], personalization of user experience [31], sports [6, 7], and others.”
BackgroundA Multi-Layer Parallel LSTM Network for Human Activity Recognition with Smartphone Sensors
Yu, T., Chen, J., Yan, N., & Liu, X. (2018) · International Conference on Wireless Communications and Signal Processing (WCSP) · doi:10.1109/wcsp.2018.8555945 · Cited by 37 · cited 10×
“Given the ubiquity of IMUs in smartphones and wearables, in our work, we focus on accelerometer-based HAR, which has been explored in recent years using different machine learning and deep learning methods [11, 28, 30].”
BackgroundMethodInfluentialSense and Learn: Self-supervision for omnipresent sensors
Saeed, A., Ungureanu, V., & Gfeller, B. (2021) · Machine Learning with Applications · doi:10.1016/j.mlwa.2021.100152 · Cited by 34 · cited 1×
“Nonetheless, for both UCI HAR and HAPT, our fine-tuned self-supervised models outperform the fine-tuned models proposed by [19] and [20].”
MethodSense and Learn: Self-Supervision for Omnipresent Sensors
Saeed, A., Ungureanu, V., & Gfeller, B. (2020) · arXiv · doi:10.48550/arxiv.2009.13233 · Cited by 34
Kulchyk, J., & Etemad, A. (2019) · Proceedings of IEEE Sensors/Proceedings of IEEE Sensors ... · doi:10.1109/sensors43011.2019.8956668 · Cited by 22 · cited 10×
“Given the ubiquity of IMUs in smartphones and wearables, in our work, we focus on accelerometer-based HAR, which has been explored in recent years using different machine learning and deep learning methods [11, 28, 30].”
BackgroundMethodInfluentialSelf-citationYao, R., Lin, G., Shi, Q., et al. (2017) · arXiv (Cornell University) · doi:10.48550/arxiv.1702.06212 · Cited by 4
Cited by
Logacjov, A., & Bach, K. (2023) · Engineering Applications of Artificial Intelligence · doi:10.1016/j.engappai.2023.107478 · Cited by 41
D’Aniello, G., Gaeta, M., Gravina, R., Li, Q., Rehman, Z. U., & Fortino, G. (2023) · Information Fusion · doi:10.1016/j.inffus.2023.102197 · Cited by 36
Taghanaki, S. R., Rainbow, M. J., & Etemad, A. (2023) · IEEE Transactions on Human-Machine Systems · doi:10.1109/thms.2023.3303438 · Cited by 31
“Selfsupervised learning [10], [13], [14] is one of these techniques which has been proposed to tackle the problem by exploiting auxiliary tasks for pre-training, also referred to as pretext tasks, relying only on the unlabeled data.”
BackgroundMethodInfluentialSelf-citationSelf-supervised Learning for Accelerometer-based Human Activity Recognition: A Survey
Logacjov, A. (2024) · Proceedings of the ACM on Interactive Mobile Wearable and Ubiquitous Technologies · doi:10.1145/3699767 · Cited by 40
Spatial-Temporal Masked Autoencoder for Multi-Device Wearable Human Activity Recognition
Miao, S., Chen, L., & Hu, R. (2023) · Proceedings of the ACM on Interactive, Mobile, Wearable and Ubiquitous Technologies · doi:10.1145/3631415 · Cited by 23
“Masked reconstruction tasks leverage encoders to extract valid features from partially masked input and decoders to recover the complete input by learning the correlation patterns within the data [25, 56, 71].”
BackgroundMethodResultInfluential
Metadata
- Authors
- Rahimi Taghanaki, S., Rainbow, M. J., & Etemad, A.
- Affiliations
- Queen's University, Canada
- Queen's University (CA)
- Venue
- 2021 International Symposium on Wearable Computers
- Publisher
- ACM
- Published
- 2021-09-21
- Pages
- 23-27
- OpenAlex
- W3196399896
- Semantic Scholar
- 85106aafef1b6385cd174c4ff6371ff11b7ea6f8
- Cited by
- 22
- References
- 36
- Citations by year
- 2026: 3 · 2025: 3 · 2024: 7 · 2023: 5 · 2022: 4
- FWCI
- 1.31
- Type
- conference paper
- Language
- en
- Open access
- green
- arxiv.org
- Locations
- International Symposium on Wearable Computers (publishedVersion, public-domain)
- arXiv (Cornell University) (submittedVersion)
- arXiv (Cornell University)
- Topics
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Context-Aware Activity Recognition Systems
- Physical Sciences › Computer Science › Artificial Intelligence › Domain Adaptation and Few-Shot Learning
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Human Pose and Action Recognition
- Keywords
- human activity recognition, self-supervised learning, smartphone accelerometer, transfer learning, unlabeled data, UCI-HAR
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
The claim verdicts this report counts are experimental: their accuracy is not yet measured.
A language model drew the claims from the paper on 2026-10-10, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-10-10 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Cited sources are checked with a language model’s help (qwen3.8-omni-flash and gpt-6-sol).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
