

The DOI matches its Crossref record; 57 of the 57 references it cites were found in a registry or an index; 13 of the 15 sources its claims cite were checked for support.
CodeGeeX: A Pre-Trained Model for Code Generation with Multilingual Benchmarking on HumanEval-X
Open accessAbstract
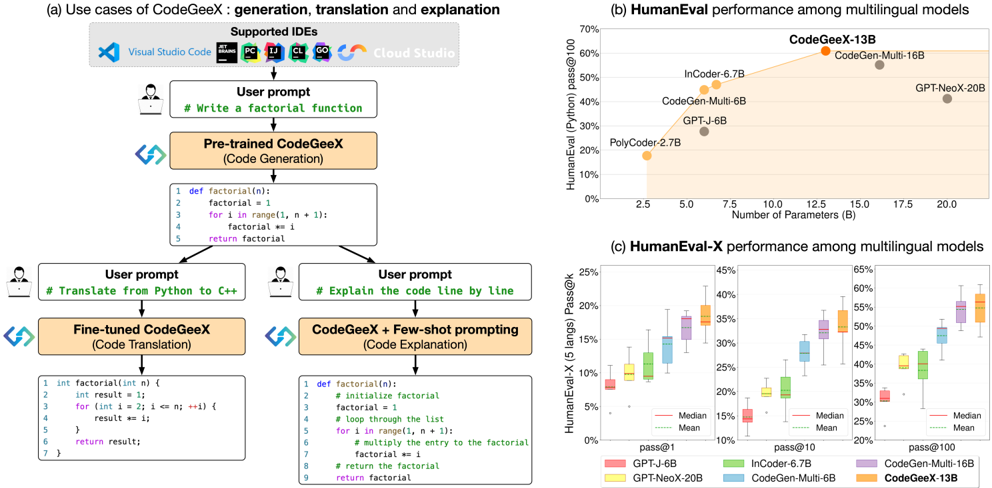
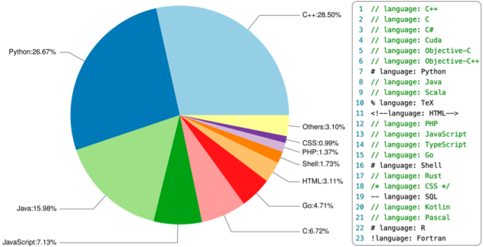
Large pre-trained code generation models, such as OpenAI Codex, can generate syntax-and function-correct code, making the coding of programmers more productive. In this paper, we introduce CodeGeeX, a multilingual model with 13 billion parameters for code generation. CodeGeeX is pre-trained on 850 billion tokens of 23 programming languages as of June 2022. Our extensive experiments suggest that CodeGeeX outperforms multilingual code models of similar scale for both the tasks of code generation and translation on HumanEval-X. Building upon HumanEval (Python only), we develop the HumanEval-X benchmark for evaluating multilingual models by hand-writing the solutions in C++, Java, JavaScript, and Go. In addition, we build CodeGeeX-based extensions on Visual Studio Code, JetBrains, and Cloud Studio, generating 8 billion tokens for tens of thousands of active users per week. Our user study demonstrates that CodeGeeX can help to increase coding efficiency for 83.4% of its users. Finally, CodeGeeX is publicly accessible since Sep. 2022, we open-sourced its code, model weights, API, extensions, and HumanEval-X at https://github.com/THUDM/CodeGeeX.
Overview
CoChat Summary
TL;DR
CodeGeeX is a 13B-parameter multilingual code generation model pre-trained on 850B tokens across 23 programming languages, released with the HumanEval-X benchmark for evaluating code generation and translation in Python, C++, Java, JavaScript, and Go. It reports competitive or best average performance among same-scale multilingual baselines on HumanEval-X and positive user-reported coding-efficiency gains.
Key findings
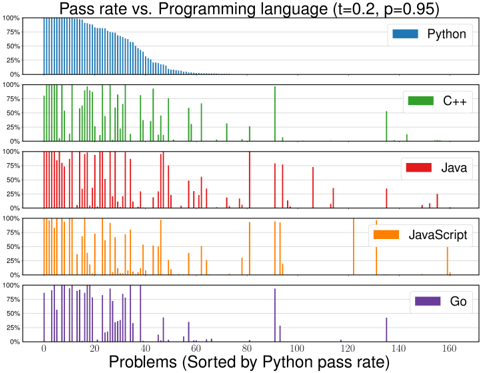
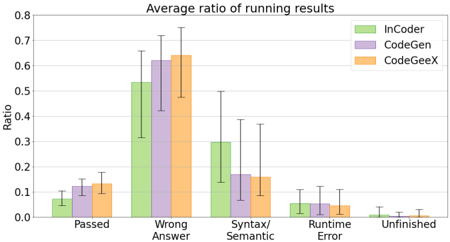
- CodeGeeX achieves the best average performance on HumanEval-X code generation among compared models, with average pass@1 18.40%, pass@10 33.29%, and pass@100 54.76%, slightly better than CodeGen-Multi-16B in all three metrics (0.37%–1.67% improvements).
- On Python HumanEval, CodeGeeX reaches pass@1 22.89%, pass@10 39.57%, and pass@100 60.92%; the paper notes it is second-highest among multilingual code generation models on HumanEval, surpassed by PaLMCoder-540B.
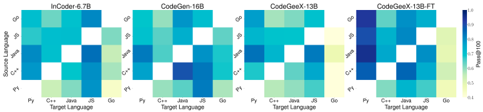
- For cross-lingual code translation, fine-tuned CodeGeeX-13B-FT performs best on pass@100 in 11 of 20 language pairs, while CodeGen-Multi-16B is best on 7.
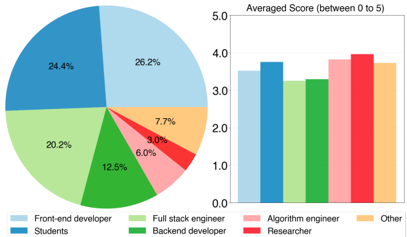
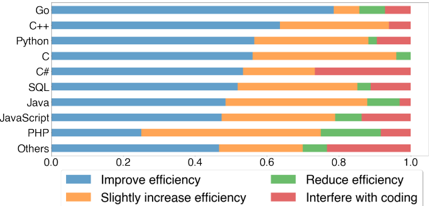
- In a user survey of 168 users, over 83.4% report that CodeGeeX improves or slightly increases coding efficiency; the deployed extensions generate 8 billion tokens per week for tens of thousands of daily active users, averaging 200+ API calls per active user per weekday.
Methods
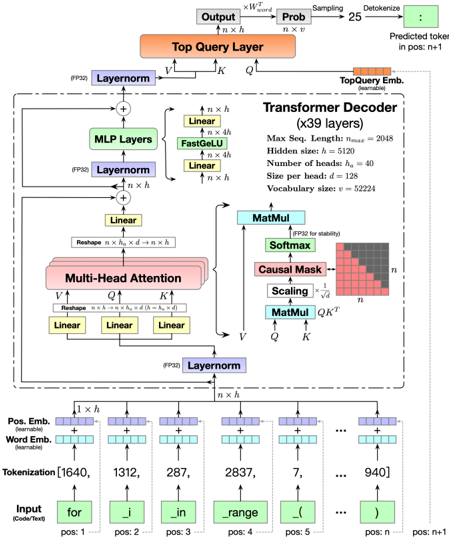
- CodeGeeX is a 39-layer decoder-only transformer with 13B parameters, hidden size 5120, vocabulary size 52,224, maximum sequence length 2048, and a top query layer; it was trained on 850B tokens over 213,000 steps using 1,536 Ascend 910 AI processors, Mindspore v1.7.0, 8-way model parallelism, 192-way data parallelism, and global batch size 3,072.
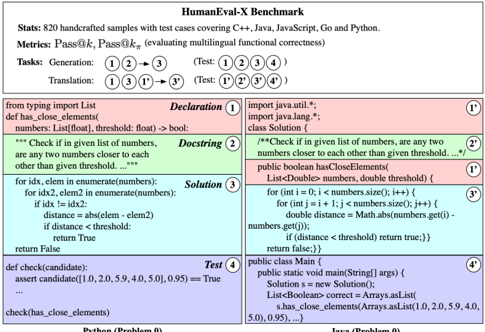
- HumanEval-X was built by manually rewriting the 164 Python HumanEval problems into C++, Java, JavaScript, and Go, yielding 820 problem-solution pairs; it supports code generation and translation across 20 source-target language pairs, evaluated with pass@k using n=200 generations and k ∈ {1, 10, 100}.
- Baselines include GPT-J-6B, GPT-NeoX-20B, InCoder-6.7B, and CodeGen-Multi-6B/16B; additional evaluations cover MBPP, CodeXGLUE code summarization, and XLCoST code translation.
Limitations
- The paper states that it is computationally unaffordable to test different architectural designs for large pre-trained models, and that multilingual models may require larger model capacity to master different languages; it also observes asymmetry in translation performance, suggesting models lack high-level understanding between languages.
- The paper notes language-specific weaknesses: Go is harder to translate into due to strict syntax constraints such as forbidding unused variables/imports, and Ruby is absent from CodeGeeX’s pre-training corpus.
- Evident from the text: the main multilingual evaluation is limited to HumanEval-X and selected benchmarks, and the user-efficiency result comes from a self-reported survey of 168 users rather than a controlled productivity study.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
6 Valid · 3 Not valid · 0 Not checked · 65 Own results and interpretations
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“existing multilingual datasets [18,28,45] use string similarity metrics like BLEU [21] for evaluation rather than really verify the functional correctness of generated code.”
§ CodeGeeX: A Pre-Trained Model for Code Generation with Multilingual Benchmarking on HumanEval-X > 1 INTRODUCTION
What the sources say
- Supportedcites [18] source
Section 3.5 (p. 4) describes a Java–C# code-translation dataset. Section 5.7 (p. 9) lists exact match, BLEU, and CodeBLEU as its evaluation measures, with CodeBLEU as the overall metric, rather than a functional-correctness test. The claim is supported for this dataset; it should not be read as saying BLEU alone is the overall metric. (LLM, conf=0.87)
- Supportedcites [28] source
The citation to this paper is attached to BLEU as an evaluation metric, not to the identification of the multilingual datasets. The Introduction (p. 1) calls BLEU a popular code-synthesis evaluation method based on token overlap, and Related Work (p. 7) says it ignores logical correctness. That supports the attributed distinction between string similarity and verification of functional correctness. (LLM, conf=0.88)
- Supportedcites [45] source
XLCoST evaluates code generation with BLEU and CodeBLEU (Evaluation Metrics and Baselines, p. 6). Its Limitations and Future Work section (p. 7) says evaluation could be improved by using test cases and treats automated test-case generation as future work. CodeBLEU also checks syntax and data flow, but the paper does not report verifying generated code’s functional correctness with tests. (LLM, conf=0.91)
- Not matchedcites [21]
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Supported
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“HumanEval [7]-developed by OpenAI for evaluating Codex-and other benchmarks [2,13,20] only consist of programming problems in a single language”
- Also stated in: § 3.1 HumanEval-X: A Multilingual Benchmark · plain
“However, similar to MBPP [2] and APPS [13], it only consists of handcrafted programming problems in Python, thus cannot be directly applied to systematically evaluate the performance of multilingual code generation.”
§ CodeGeeX: A Pre-Trained Model for Code Generation with Multilingual Benchmarking on HumanEval-X > 1 INTRODUCTION
What the sources say
- Supportedcites [7] source
The Codex and Codex-S Performance section (p. 2) says the authors created a 164-problem dataset to evaluate their model on generating standalone Python functions. Section 2.2 (p. 4) names that dataset HumanEval. The separate citations attached to “other benchmarks” are not judged here. (LLM, conf=0.93)
- Partly supportedcites [2] sourceExperimental — accuracy not yet measured
The Introduction (p. 2) says this paper introduces two Python code-synthesis datasets, and §2.1 (p. 4) describes MBPP as containing Python programs. That supports the single-language claim for this paper’s benchmarks. The Introduction (p. 3) mentions HumanEval but does not establish that it, or every other benchmark in the citing sentence, contains problems in only one language. (LLM, conf=0.84)
- Supportedcites [13] source
The Abstract (p. 1) says APPS evaluates generation of Python code, and the Conclusion (p. 9) calls it a benchmark of 10,000 Python programming problems. This supports the single-language point for APPS, the benchmark identified by this citation; it does not need to establish the language coverage of HumanEval. (LLM, conf=0.92)
- Supportedcites [20] source
Section 3 (p. 4) identifies HumanEval as 164 Python programming problems. Sections 4.1 (p. 6) and 4.2 (p. 7) describe this paper’s own benchmark, MTPB, using Python prompts and execution. The paper therefore supports the single-language characterization for the benchmarks it discusses; it does not establish that every programming benchmark is single-language. (LLM, conf=0.87)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Also stated in: § 3.1 HumanEval-X: A Multilingual Benchmark · plain
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The inference time per token is within 13ms (1.61 seconds / 128 tokens).”
§ CodeGeeX: A Pre-Trained Model for Code Generation with Multilingual Benchmarking on HumanEval-X > 2.4 Fast Inference
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Rests on an assumption not shown here.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Our user survey suggests that 83.4% of users feel the CodeGeeX extensions improve their programming efficiency.”
- Also stated in: § Budget Allocation Strategies. · plain
“There are on average over 83.4% of users think CodeGeeX can improve or slightly increase their coding efficiency, especially for mainstream programming languages like Go, C++, Python, C, C#, etc.”
- Also stated in: § 6 CONCLUSION · plain
“Over 83.4% of users have positive answers.”
§ CodeGeeX: A Pre-Trained Model for Code Generation with Multilingual Benchmarking on HumanEval-X > 1 INTRODUCTION
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Rests on an assumption not shown here.
- Also stated in: § Budget Allocation Strategies. · plain
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
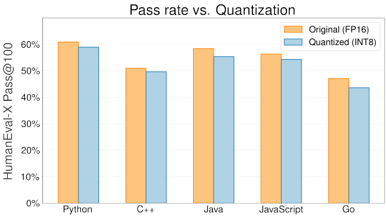
“Importantly, Figure 4 shows that the quantization only slightly affects the performance on the code generation task”
§ CodeGeeX: A Pre-Trained Model for Code Generation with Multilingual Benchmarking on HumanEval-X > 2.4 Fast Inference
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Rests on an assumption not shown here.
24 more claims
Create a free account to see all 74 claims and every source verdict.
- Probably not a substantial claim. 20
- It may state two separate claims as one. 29
- The quote only partly states this claim. 2
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Each contradiction between two passages listed here was confirmed by an independent check.
Rated major: it would touch a result — a value a result rests on, reported and recomputed p-values on opposite sides of the significance level, two passages that conflict with no sign which is right, or a cited work retracted before this paper was published.
In the paper
“The entire pre-training process takes two months on 192 nodes with 1,536 AI processors, during which the model consumes 850B tokens, equivalent to 5+ epochs (213,000 steps).”
§ CodeGeeX: A Pre-Trained Model for Code Generation with Multilingual Benchmarking on HumanEval-X > 2.3 CodeGeeX Training
Reported 850000000000 · recomputed 1340080128000
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ CodeGeeX: A Pre-Trained Model for Code Generation with Multilingual Benchmarking on HumanEval-X > Additional information
“| pass@𝑘𝜋 (𝑘 = 100) | Best Single 33.77% Uniform 36.40% Weighted 36.76% | 42.67% 44.75% 44.97% | 43.95% 43.89% 45.60% | 53.19% 53.47% 53.94%”
§ CodeGeeX: A Pre-Trained Model for Code Generation with Multilingual Benchmarking on HumanEval-X > Additional information
“| | pass@100 32.96% | 42.23% | 40.70% | 53.91% | 60.62% | 58.42% | |”
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ CodeGeeX: A Pre-Trained Model for Code Generation with Multilingual Benchmarking on HumanEval-X > Budget Allocation Strategies.
“Both Uniform and Weighted outperform Best Single by promoting a more diverse generation, which gives a higher chance of solving problems.”
§ CodeGeeX: A Pre-Trained Model for Code Generation with Multilingual Benchmarking on HumanEval-X > Additional information
“| 43.95% 43.89% 45.60% |”
Citations
Cites
Deep Residual Learning for Image Recognition
He, K., Zhang, X., Ren, S., & Sun, J. (2016) · 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2016.90 · Cited by 235,474 · cited 1×
“We use an approximation of GELU (Gaussian Linear Units) operation [14], namely FastGELU, which is more efficient under Ascend 910: Generative Pre-Training Objective.”
MethodVaswani, A., Shazeer, N., Parmar, N., Uszkoreit, J., Jones, L., Gomez, A. N., Kaiser, L., & Polosukhin, I. (2017) · arXiv · doi:10.48550/arxiv.1706.03762 · Cited by 120,404
Adam: A Method for Stochastic Optimization
Kingma, D. P., & Ba, J. (2014) · arXiv · doi:10.48550/arxiv.1412.6980 · Cited by 98,946
Language Models are Few-Shot Learners
Brown, T. B., Mann, B., Ryder, N., Subbiah, M., Kaplan, J., Dhariwal, P., Neelakantan, A., Shyam, P., Sastry, G., Askell, A., et al. (2020) · arXiv · doi:10.48550/arxiv.2005.14165 · Cited by 23,372
BLEU: a method for automatic evaluation of machine translation
Papineni, K., Roukos, S., Ward, T., & Zhu, W.-J. (2001) · Proceedings of the 40th Annual Meeting on Association for Computational Linguistics - ACL '02 · doi:10.3115/1073083.1073135 · Cited by 21,344
Advances in Neural Information Processing Systems 29
Teymur, O., Zygalakis, K., & Calderhead, B. (2016) · Cited by 13,887
Transformers: State-of-the-Art Natural Language Processing
Wolf, T., Debut, L., Sanh, V., Chaumond, J., Delangue, C., Moi, A., Cistac, P., Rault, T., Louf, R., Funtowicz, M., et al. (2020) · Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing: System Demonstrations · doi:10.18653/v1/2020.emnlp-demos.6 · Cited by 8,741
Chain-Of-Thought Prompting Elicits Reasoning in Large Language Models
Wei, J., Wang, X., Schuurmans, D., Bosma, M., Ichter, B., Xia, F., Chi, E., Le, Q. V., & Zhou, D. (2022) · Advances in Neural Information Processing Systems 35 · doi:10.52202/068431-1800 · Cited by 4,505
Gaussian Error Linear Units (GELUs)
Hendrycks, D., & Gimpel, K. (2016) · arXiv · doi:10.48550/arxiv.1606.08415 · Cited by 3,537
HuggingFace's Transformers: State-of-the-art Natural Language Processing
Wolf, T., Debut, L., Sanh, V., Chaumond, J., Delangue, C., Moi, A., Cistac, P., Rault, T., Louf, R., Funtowicz, M., et al. (2019) · arXiv · doi:10.48550/arxiv.1910.03771 · Cited by 3,347
PaLM: Scaling Language Modeling with Pathways
Chowdhery, A., Narang, S., Devlin, J., Bosma, M., Mishra, G., Roberts, A., Barham, P., Chung, H. W., Sutton, C., Gehrmann, S., et al. (2022) · arXiv · doi:10.48550/arxiv.2204.02311 · Cited by 2,590
Proceedings of the 40th Annual Meeting on Association for Computational Linguistics
Isabelle, P. (2002) · Cited by 1,633
Wang, Y., Wang, W., Joty, S., & Hoi, S. C. H. (2021) · arXiv · doi:10.48550/arxiv.2109.00859 · Cited by 1,495
Wang, Y., Wang, W., Joty, S., & Hoi, S. C. H. (2021) · Proceedings of the 2021 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/2021.emnlp-main.685 · Cited by 1,495
Evaluating Large Language Models Trained on Code
Chen, M., Tworek, J., Jun, H., Yuan, Q., Pinto, H. P. D. O., Kaplan, J., Edwards, H., Burda, Y., Joseph, N., Brockman, G., et al. (2021) · arXiv · doi:10.48550/arxiv.2107.03374 · Cited by 1,436
Self-citationCompetition-Level Code Generation with AlphaCode
Li, Y., Choi, D., Chung, J., Kushman, N., Schrittwieser, J., Leblond, R., Eccles, T., Keeling, J., Gimeno, F., Lago, A. D., et al. (2022) · arXiv · doi:10.48550/arxiv.2203.07814 · Cited by 1,043
Self-citationCompetition-level code generation with AlphaCode
Li, Y., Choi, D., Chung, J., Kushman, N., Schrittwieser, J., Leblond, R., Eccles, T., Keeling, J., Gimeno, F., Dal Lago, A., et al. (2022) · Science · doi:10.1126/science.abq1158 · Cited by 1,043
Self-citationUnified Pre-training for Program Understanding and GenerationPreprint
Ahmad, W. U., Chakraborty, S., Ray, B., & Chang, K.-W. (2021) · North American Chapter of the Association for Computational Linguistics · doi:10.48550/arxiv.2103.06333 · Cited by 1,001
Neural Machine Translation of Rare Words with Subword Units
Sennrich, R., Haddow, B., & Birch, A. (2016) · Proceedings of the 54th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) · doi:10.18653/v1/p16-1162 · Cited by 974
Neural Machine Translation of Rare Words with Subword Units
Sennrich, R., Haddow, B., & Birch, A. (2015) · arXiv · doi:10.48550/arxiv.1508.07909 · Cited by 950
(2020) · doi:10.1109/sc41405.2020.00024 · Cited by 928 · cited 1×
“To increase training efficiency, we adopt an 8-way model parallel training together with 192-way data parallel training, with ZeRO2 [27] optimizer enabled to further reduce thememory consumption of optimizer states.”
MethodLaMDA: Language Models for Dialog Applications
Thoppilan, R., De Freitas, D., Hall, J., Shazeer, N., Kulshreshtha, A., Cheng, H.-T., Jin, A., Bos, T., Baker, L., Du, Y., et al. (2022) · arXiv · doi:10.48550/arxiv.2201.08239 · Cited by 778
Self-citationUnified Pre-training for Program Understanding and Generation
Ahmad, W., Chakraborty, S., Ray, B., & Chang, K.-W. (2021) · Proceedings of the 2021 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies · doi:10.18653/v1/2021.naacl-main.211 · Cited by 642
A systematic evaluation of large language models of code
Xu, F. F., Alon, U., Neubig, G., & Hellendoorn, V. J. (2022) · Proceedings of the 6th ACM SIGPLAN International Symposium on Machine Programming · doi:10.1145/3520312.3534862 · Cited by 540
CodeXGLUE: A Machine Learning Benchmark Dataset for Code Understanding and Generation
Lu, S., Guo, D., Ren, S., Huang, J., Svyatkovskiy, A., Blanco, A., Clement, C., Drain, D., Jiang, D., Tang, D., et al. (2021) · arXiv · doi:10.48550/arxiv.2102.04664 · Cited by 536
The Pile: An 800GB Dataset of Diverse Text for Language Modeling
Gao, L., Biderman, S., Black, S., Golding, L., Hoppe, T., Foster, C., Phang, J., He, H., Thite, A., Nabeshima, N., et al. (2021) · arXiv · doi:10.48550/arxiv.2101.00027 · Cited by 492
IntelliCode compose: code generation using transformer
Svyatkovskiy, A., Deng, S. K., Fu, S., & Sundaresan, N. (2020) · Proceedings of the 28th ACM Joint Meeting on European Software Engineering Conference and Symposium on the Foundations of Software Engineering · doi:10.1145/3368089.3417058 · Cited by 474 · cited 1×
“From LISPbased pioneering deductive synthesis approaches [31, 37] tomodern program synthesis systems [23, 30], to end-to-end code generation via deep neural networks [19, 32, 33], tremendous efforts have been made to enable machines to automatically write correct programs as part of the quest to artificial general int…”
BackgroundBa, J. L., Kiros, J., & Hinton, G. E. (2016) · arXiv (Cornell University) · doi:10.48550/arxiv.1607.06450 · Cited by 440
GPT-NeoX-20B: An Open-Source Autoregressive Language Model
Black, S., Biderman, S., Hallahan, E., Anthony, Q., Gao, L., Golding, L., He, H., Leahy, C., McDonell, K., Phang, J., et al. (2022) · Proceedings of BigScience Episode #5 -- Workshop on Challenges & Perspectives in Creating Large Language Models · doi:10.18653/v1/2022.bigscience-1.9 · Cited by 404
Program Synthesis with Large Language Models
Austin, J., Odena, A., Nye, M., Bosma, M., Michalewski, H., Dohan, D., Jiang, E., Cai, C., Terry, M., Le, Q., et al. (2021) · arXiv · doi:10.48550/arxiv.2108.07732 · Cited by 388
CodeGen: An Open Large Language Model for Code with Multi-Turn Program Synthesis
Nijkamp, E., Pang, B., Hayashi, H., Tu, L., Wang, H., Zhou, Y., Savarese, S., & Xiong, C. (2022) · arXiv · doi:10.48550/arxiv.2203.13474 · Cited by 330
Program synthesis by sketching
Bodík, R., & Solar-Lezama, A. (2008) · Cited by 326
GPT-Neo: Large Scale Autoregressive Language Modeling with Mesh-Tensorflow
Black, S., Leo, G., Wang, P., Leahy, C., & Biderman, S. (2021) · Zenodo · doi:10.5281/zenodo.5297715 · Cited by 324
LLM.int8(): 8-Bit Matrix Multiplication for Transformers at Scale
Dettmers, T., Lewis, M., Belkada, Y., & Zettlemoyer, L. (2022) · Advances in Neural Information Processing Systems 35 · doi:10.52202/068431-2198 · Cited by 305
LLM.int8(): 8-bit Matrix Multiplication for Transformers at Scale
Dettmers, T., Lewis, M., Belkada, Y., & Zettlemoyer, L. (2022) · arXiv · doi:10.48550/arxiv.2208.07339 · Cited by 305
GLM-130B: An Open Bilingual Pre-trained Model
Zeng, A., Liu, X., Du, Z., Wang, Z., Lai, H., Ding, M., Yang, Z., Xu, Y., Zheng, W., Xia, X., et al. (2022) · arXiv · doi:10.48550/arxiv.2210.02414 · Cited by 281
Self-citationCodeBERT: A Pre-Trained Model for Programming and Natural Languages
Feng, Z., Guo, D., Tang, D., Duan, N., Feng, X., Gong, M., Shou, L., Qin, B., Liu, T., Jiang, D., et al. (2020) · arXiv · doi:10.48550/arxiv.2002.08155 · Cited by 243
FlashMeta: a framework for inductive program synthesis
Polozov, O., & Gulwani, S. (2015) · Proceedings of the 2015 ACM SIGPLAN International Conference on Object-Oriented Programming, Systems, Languages, and Applications · doi:10.1145/2814270.2814310 · Cited by 225 · cited 1×
“From LISP-based pioneering deductive synthesis approaches [31, 37] to modern program synthesis systems [23, 30], to end-to-end code generation via deep neural networks [19, 32, 33], tremendous efforts have been made to enable machines to automatically write correct programs as part of the quest to…”
MethodA Methodology for LISP Program Construction from Examples
Summers, P. D. (1977) · Journal of the ACM · doi:10.1145/321992.322002 · Cited by 219 · cited 2×
“This problem has been explored since the early days of computer science in the 1960s [31, 37].”
BackgroundMethodCodeBLEU: a Method for Automatic Evaluation of Code Synthesis
Ren, S., Guo, D., Lu, S., Zhou, L., Liu, S., Tang, D., Sundaresan, N., Zhou, M., Blanco, A., & Ma, S. (2020) · arXiv · doi:10.48550/arxiv.2009.10297 · Cited by 214
Productivity Assessment of Neural Code Completion
Ziegler, A., Kalliamvakou, E., Li, X. A., Rice, A., Rifkin, D., Simister, S., Sittampalam, G., & Aftandilian, E. (2022) · Proceedings of the 6th ACM SIGPLAN International Symposium on Machine Programming · doi:10.1145/3520312.3534864 · Cited by 200 · cited 1×
“Research studies [46] also show that 88% of users of GitHub Copilot—a paid service powered by Codex—feel more productive when coding with it.”
BackgroundProductivity Assessment of Neural Code Completion
Ziegler, A., Kalliamvakou, E., Simister, S., Sittampalam, G., Li, A., Rice, A., Rifkin, D., & Aftandilian, E. (2022) · arXiv · doi:10.48550/arxiv.2205.06537 · Cited by 200
InCoder: A Generative Model for Code Infilling and Synthesis
Fried, D., Aghajanyan, A., Lin, J., Wang, S., Wallace, E., Shi, F., Zhong, R., Yih, W.-T., Zettlemoyer, L., & Lewis, M. (2022) · arXiv · doi:10.48550/arxiv.2204.05999 · Cited by 187 · cited 2×
“Second, in addition to code generation and code completion as Codex and others, CodeGeeX supports the tasks of code explanation and code translation between language pairs (Cf. Figure 1 (a)).”
BackgroundMethodInfluentialSelf-citationCoTexT: Multi-task Learning with Code-Text Transformer
Phan, L., Tran, H., Le, D. X., Nguyen, H., Anibal, J., Peltekian, A., & Ye, Y. (2021) · doi:10.18653/v1/2021.nlp4prog-1.5 · Cited by 175
Zeng, W., Ren, X., Su, T., Wang, H., Liao, Y., Wang, Z., Jiang, X., Yang, Z., Wang, K., Zhang, X., et al. (2021) · arXiv · doi:10.48550/arxiv.2104.12369 · Cited by 172 · cited 1×
“As shown in Figure 2, the input of the top query layer replaces the query input 𝑋 𝑖𝑛 by the query Table 1: Large pre-trained language models related to programming languages in the literature.”
BackgroundSelf-citationTreeGen: A Tree-Based Transformer Architecture for Code Generation
Sun, Z., Zhu, Q., Xiong, Y., Sun, Y., Mou, L., & Zhang, L. (2020) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v34i05.6430 · Cited by 167 · cited 1×
“From LISPbased pioneering deductive synthesis approaches [31, 37] tomodern program synthesis systems [23, 30], to end-to-end code generation via deep neural networks [19, 32, 33], tremendous efforts have been made to enable machines to automatically write correct programs as part of the quest to artificial general int…”
BackgroundMeasuring Coding Challenge Competence With APPS
Hendrycks, D., Basart, S., Kadavath, S., Mazeika, M., Arora, A., Guo, E., Burns, C., Puranik, S., He, H., Song, D., et al. (2021) · arXiv · doi:10.48550/arxiv.2105.09938 · Cited by 142
SPoC: Search-based Pseudocode to Code
Kulal, S., Pasupat, P., Chandra, K., Lee, M., Padon, O., Aiken, A., & Liang, P. (2019) · arXiv · doi:10.48550/arxiv.1906.04908 · Cited by 103
FlashMeta: a framework for inductive program synthesis
Polozov, O., & Gulwani, S. (2015) · ACM SIGPLAN Notices · doi:10.1145/2858965.2814310 · Cited by 91
GPT-NeoX-20B: An Open-Source Autoregressive Language Model
Black, S., Biderman, S., Hallahan, E., Anthony, Q., Gao, L., Golding, L., He, H., Leahy, C., McDonell, K., Phang, J., et al. (2022) · arXiv · doi:10.48550/arxiv.2204.06745 · Cited by 67
On End-to-End Program Generation from User Intention by Deep Neural NetworksPreprint
Mou, L., Men, R., Li, G., Zhang, L., & Jin, Z. G. (2015) · arXiv (Cornell University) · doi:10.48550/arxiv.1510.07211 · Cited by 59
Qi, W., Gong, Y., Yan, Y., Xu, C., Yao, B., Zhou, B., Cheng, B., Jiang, D., Chen, J., Zhang, R., et al. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2104.08006 · Cited by 33
A methodology for LISP program construction from examples
Summers, P. D. (1976) · doi:10.1145/800168.811541 · Cited by 28
XLCoST: A Benchmark Dataset for Cross-lingual Code Intelligence
Zhu, M., Jain, A., Suresh, K., Ravindran, R., Tipirneni, S., & Reddy, C. K. (2022) · arXiv · doi:10.48550/arxiv.2206.08474 · Cited by 24
TreeGen: A Tree-Based Transformer Architecture for Code GenerationPreprint
Sun, Z., Zhu, Q., Xiong, Y., et al. (2019) · arXiv (Cornell University) · doi:10.48550/arxiv.1911.09983 · Cited by 18
CoTexT: Multi-task Learning with Code-Text TransformerPreprint
Phan, L., Tran, H., Le, D. X., Nguyen, H., Anibal, J., Peltekian, A., & Ye, Y. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2105.08645 · Cited by 7
OPT: Open Pre-trained Transformer Language Models
Zhang, S., Roller, S., Goyal, N., Artetxe, M., Chen, M., Chen, S., Dewan, C., Diab, M., Li, X., Lin, X. V., et al. (2022) · arXiv · doi:10.48550/arxiv.2205.01068
Research works printed but not linked: 3
- Alec Radford Jeffrey Wu Rewon Child David Luan Dario Amodei Ilya Sutskever etal 2019. Language models are unsupervised multitask learners. OpenAI blog Vol. 1 8 (2019) 9. Alec Radford Jeffrey Wu Rewon Child David Luan Dario Amodei Ilya Sutskever et al. 2019. Language models are unsupervised multitask learners. OpenAI blog Vol. 1 8 (2019) 9.
- Lewis Tunstall , Leandro von Werra , and Thomas Wolf . 2022. Natural language processing with transformers. "O'Reilly Media , Inc .". Lewis Tunstall, Leandro von Werra, and Thomas Wolf. 2022. Natural language processing with transformers. "O'Reilly Media, Inc.".
- Richard J Waldinger and Richard CT Lee . 1969 . PROW: A step toward automatic program writing . In Proceedings of the 1st international joint conference on Artificial intelligence. 241--252 . Richard J Waldinger and Richard CT Lee. 1969. PROW: A step toward automatic program writing. In Proceedings of the 1st international joint conference on Artificial intelligence. 241--252.
Cited by
Large Language Models for Software Engineering: A Systematic Literature Review
Hou, X., Zhao, Y., Liu, Y., Yang, Z., Wang, K., Li, L., Luo, X., Lo, D., Grundy, J., & Wang, H. (2024) · ACM Transactions on Software Engineering and Methodology · doi:10.1145/3695988 · Cited by 1,029
Self-citationLongBench: A Bilingual, Multitask Benchmark for Long Context Understanding
Bai, Y., Lv, X., Zhang, J., Lyu, H., Tang, J., Huang, Z., Du, Z., Liu, X., Zeng, A., Hou, L., et al. (2024) · Proceedings of the 62nd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) · doi:10.18653/v1/2024.acl-long.172 · Cited by 400
Self-citationLost in Translation: A Study of Bugs Introduced by Large Language Models while Translating Code
Pan, R., Ibrahimzada, A. R., Krishna, R., Sankar, D., Wassi, L. P., Merler, M., Sobolev, B., Pavuluri, R., Sinha, S., & Jabbarvand, R. (2024) · Proceedings of the IEEE/ACM 46th International Conference on Software Engineering · doi:10.1145/3597503.3639226 · Cited by 349
A Review of Current Trends, Techniques, and Challenges in Large Language Models (LLMs)
Patil, R., & Gudivada, A. V. (2024) · doi:10.20944/preprints202402.0357.v1 · Cited by 296
A Review of Current Trends, Techniques, and Challenges in Large Language Models (LLMs)
Patil, R., & Gudivada, V. (2024) · Applied Sciences · doi:10.3390/app14052074 · Cited by 290
Metadata
- Authors
- Zheng, Q., Xia, X., Zou, X., Dong, Y., Wang, S., Xue, Y., Shen, L., Wang, Z., Wang, A., Li, Y., Su, T., Yang, Z., & Tang, J.
- Affiliations
- Tsinghua University (CN)
- Zhipu AI (China) (CN)
- Huawei Technologies (China) (CN)
- ORCID
- Venue
- Proceedings of the 29th ACM SIGKDD Conference on Knowledge Discovery and Data Mining
- Publisher
- ACM
- Published
- 2023-08-04
- Pages
- 5673-5684
- OpenAlex
- W4385562549
- Semantic Scholar
- bafe023fb072045dc0cd50316382a61c8dcb9fae
- Cited by
- 563
- References
- 15
- Citations by year
- 2026: 148 · 2025: 205 · 2024: 157 · 2023: 53
- FWCI
- 108.31
- Type
- conference paper
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- Locations
- ACM SIGKDD Conference on Knowledge Discovery and Data Mining (KDD) (publishedVersion, cc-by)
- arXiv (Cornell University) (submittedVersion, cc-by)
- arXiv (Cornell University) (cc-by)
- Funders
- Natural Science Foundation of China (No. 62276148, No. 61836013, No. 61825602)
- Topics
- Physical Sciences › Computer Science › Information Systems › Software Engineering Research
- Physical Sciences › Computer Science › Artificial Intelligence › Topic Modeling
- Physical Sciences › Computer Science › Computer Science Applications › Teaching and Learning Programming
- Keywords
- multilingual code generation, pre-trained code models, program translation, programming language support, Visual Studio Code extension, coding efficiency
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
The claim verdicts this report counts are experimental: their accuracy is not yet measured.
A language model drew the claims from the paper on 2026-10-05, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-10-05 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Cited sources are checked with a language model’s help (gpt-6-sol).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
