

Past, Present, and Future of Sensor-based Human Activity Recognition Using Wearables: A Surveying Tutorial on a Still Challenging Task
Open accessThe DOI matches its Crossref record; 235 of the 236 references it cites were found in a registry or an index; 107 of the 168 sources its claims cite were checked for support.
Abstract
A comprehensive survey and tutorial on sensor-based human activity recognition from heuristic handcrafted feature engineering through deep learning, self-supervised learning, and multimodal foundation models, outlining benchmark datasets, placement challenges, and open problems.
Overview
CoChat Summary
TL;DR
This surveying tutorial reviews sensor-based wearable human activity recognition from handcrafted features through deep learning and self-supervised representation learning to emerging foundational-model approaches. It argues that HAR remains challenging due to signal ambivalence, input variability, information coding mismatch, and scarce labeled data, and provides a hands-on tutorial with code and Motionsense experiments.
Key findings
- The paper identifies four broad HAR challenges: signal ambivalence, variability of the input space, information coding, and lack of labeled training data.
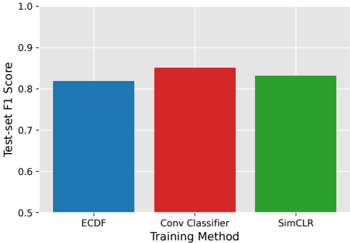
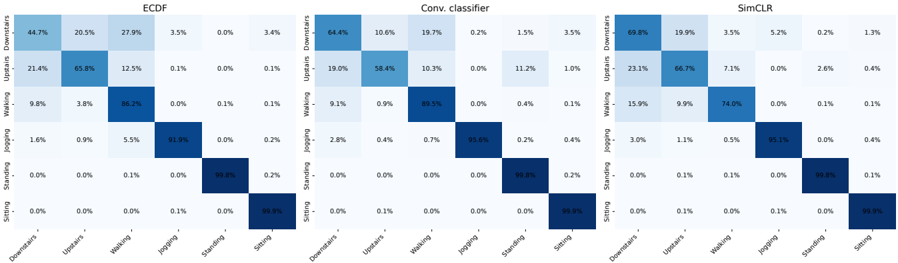
- In the tutorial experiments on Motionsense, the ECDF-RF baseline achieved a test F1-score of 81.84%, the supervised Conv.classifier achieved 85.1%, and SimCLR with frozen pre-trained encoder weights achieved 83.17%.
- Class imbalance is substantial in wearable datasets: the null class comprises approx. 75% of the Opportunity benchmark, >35% of Mobiact is “Standing,” and transitionary activities such as “Sit to stand” comprise <5%.
- The paper concludes there is no “one-size-fits-all” HAR method, but self-supervised representation learning is currently the predominant approach and foundational models may drive a third paradigm shift.
Methods
- Design: a surveying tutorial that reviews the field from the Activity Recognition Chain and handcrafted features to end-to-end deep learning, self-supervised learning, data generation/augmentation, and foundational models.
- Data and tutorial experiments: the hands-on tutorial uses the Motionsense dataset, accelerometer data only, with six locomotion-style activities from 24 participants; splits are 15 train, 4 validation, and 5 test users.
- Main analysis: the tutorial compares distribution-based ECDF features with a Random Forest classifier, a supervised convolutional classifier, and SimCLR self-supervised learning, using mean/unweighted F1-score because it is more resistant to class imbalance.
Limitations
- The paper states that there is no universally applicable HAR method, that large-scale richly annotated datasets are lacking, and that plug-and-play sensor-language models remain unsolved; it also notes that many sensor-language works train and evaluate on different splits of the same dataset, leaving cross-distribution performance unclear.
- The paper states limitations for specific methods: GAN-based generation is dataset- and label-specific, requires substantial labeled data, and can suffer mode collapse; adversarial learning lacks a mechanism to measure generalization quality during training; diffusion models require considerable computational steps; and early simulation approaches often rely on MoCap and exclude gyroscope data.
- Evident from the text: the tutorial uses only accelerometer data to reduce training time and evaluates on Motionsense’s relatively simple locomotion activities; the ECDF-RF result shows 100% train performance versus 81.84% test F1, which the paper itself notes indicates potential overfitting.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures

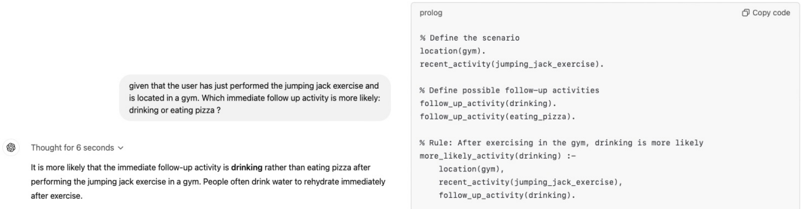
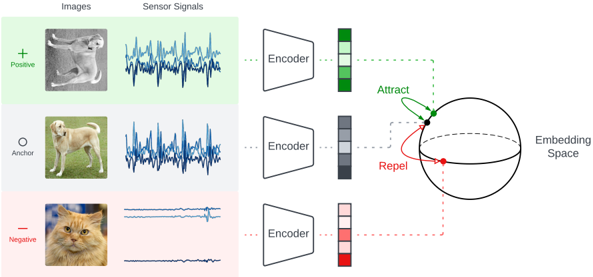
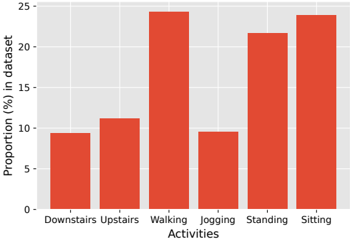
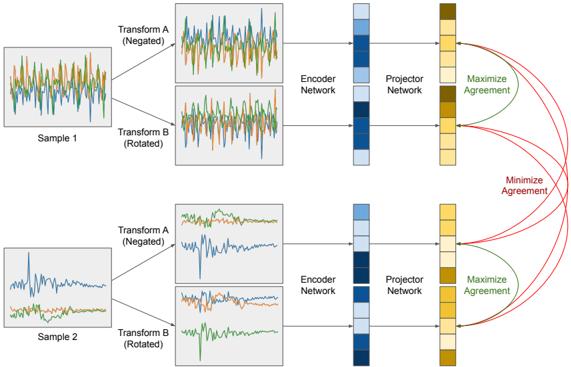
Verification
Claims the paper makes
62 Valid · 7 Not valid · 36 Not checked · 98 Own results and interpretations
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“More recently, the self-attention mechanism introduced in the Transformer paper [194] has also been successfully applied for sensor-based HAR [20,57,58,129].”
§ Past, Present, and Future of Sensor-based Human Activity Recognition Using Wearables: A Surveying Tutorial on a Still Challenging Task > 3.2 End-to-End Learning Based Approaches
What the sources say
- Supportedcites [20] 20. Keyan Cao and Mingrui Wang. 2023. Human behavior recognition based on sparse transformer with channel attention mechanism. Frontiers in Physiology 14 (2023), 1239453. sourceExperimental — accuracy not yet measured
The Abstract describes a Transformer-based model using self-attention for sensor-based HAR and reports strong accuracy on three HAR datasets. Section 3.2 explains that the authors modified the Transformer’s self-attention mechanism for this application. (LLM, conf=0.93)
- Partly supportedcites [57] 57. Wenbin Gao, Lei Zhang, Qi Teng, Jun He, and Hao Wu. 2021. DanHAR: Dual attention network for multimodal human activity recognition using wearable sensors. Applied Soft Computing 111 (2021), 107728. sourceExperimental — accuracy not yet measured
The Conclusion (p. 10) reports improved sensor-based HAR performance using DanHAR’s dual attention mechanism. But the Model section (pp. 3–4) describes channel and temporal attention built with pooling and convolution, not Transformer-style self-attention; that specific part of the claim is unsupported. (LLM, conf=0.88)
- Supportedcites [58] 58. Ziqi Gao, Yuntao Wang, Jianguo Chen, Junliang Xing, Shwetak Patel, Xin Liu, and Yuanchun Shi. 2023. MMTSA: Multi-Modal Temporal Segment Attention Network for Efficient Human Activity Recognition. Proceedings of the ACM on Interactive, Mobile, Wearable and Ubiquitous Technologies 7, 3 (2023), 1-26. source
Section 4.3 (p. 14) links MMTSA’s attention mechanism to Transformer attention and describes its use in multimodal fusion. The Conclusion (p. 23) reports successful HAR results using RGB-camera and IMU sensor data, supporting the claim that Transformer-derived attention has been applied successfully to sensor-based HAR. (LLM, conf=0.88)
- Not checked — no full text of the sourcecites [129] 129. Saif Mahmud, M Tanjid Hasan Tonmoy, Kishor Kumar Bhaumik, AKM Mahbubur Rahman, M Ashraful Amin, Mohammad Shoyaib, Muhammad Asif Hossain Khan, and Amin Ahsan Ali. 2020. Human activity recognition from wearable sensor data using self-attention. In ECAI 2020. IOS Press, 1332-1339. source
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Supported
Every source the paper cites for this claim was checked and supports it.
In the paper
“The intuition here is that the pretext task captures core signal and sensor characteristics under different rotations and placements and levels of noise [166].”
§ Past, Present, and Future of Sensor-based Human Activity Recognition Using Wearables: A Surveying Tutorial on a Still Challenging Task > 4.1.2
What the sources say
- Supportedcites [166] 166. Aaqib Saeed, Tanir Ozcelebi, and Johan Lukkien. 2019. Multi-task self-supervised learning for human activity detection. Proceedings of the ACM on Interactive, Mobile, Wearable and Ubiquitous Technologies 3, 2 (2019), 1-30. source
Section 3.2 (p. 7) says the pretext tasks enable the network to capture core signal characteristics, including sensor behavior under different device placements and robustness against sensor noise. The same section describes a rotation transformation intended to provide sensor-orientation invariance. (LLM, conf=0.94)
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Supported
Every source the paper cites for this claim was checked and supports it.
In the paper
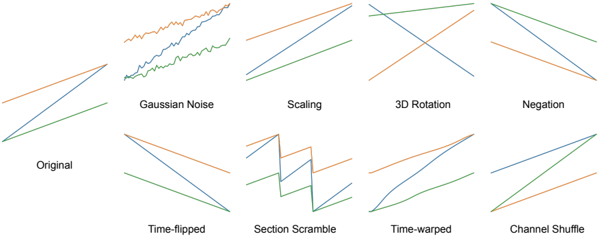
“Since the choice of augmentation function encodes the learning objective and invariance that the model should capture, the original SimCLR framework demonstrates significant performance differences among the choices of augmentation functions [28].”
§ Past, Present, and Future of Sensor-based Human Activity Recognition Using Wearables: A Surveying Tutorial on a Still Challenging Task > SimCLR.
What the sources say
- Supportedcites [28] 28. Ting Chen, Simon Kornblith, Mohammad Norouzi, and Geoffrey Hinton. 2020. A simple framework for contrastive learning of visual representations. In International conference on machine learning. PMLR, 1597-1607. source
Section 3 (p. 3) says data augmentation defines predictive tasks, and Section 3.1 (pp. 4–5) compares different augmentation choices. Table 1 reports SimCLR top-1 accuracy ranging from 59.6% to 64.5% across the tested choices, supporting the claimed performance differences. (LLM, conf=0.93)
boostedstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Supported
Every source the paper cites for this claim was checked and supports it.
In the paper
“One such adaptation effort is the modification of the SimCLR framework for sensor time series by Tang et al. [184].”
§ Past, Present, and Future of Sensor-based Human Activity Recognition Using Wearables: A Surveying Tutorial on a Still Challenging Task > SimCLR.
What the sources say
- Supportedcites [184] 184. Chi Ian Tang, Ignacio Perez-Pozuelo, Dimitris Spathis, and Cecilia Mascolo. 2020. Exploring contrastive learning in human activity recognition for healthcare. arXiv preprint arXiv:2011.11542 (2020). source
The Introduction (p. 2) says the authors adapted SimCLR for wearable-sensor data by replacing image augmentations with transformations designed for sensor time series. The Method section (p. 2) also explicitly describes modifications for HAR. (LLM, conf=0.95)
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Supported
Every source the paper cites for this claim was checked and supports it.
In the paper
“Furthermore, investigations into enhancements of CPC for HAR, as presented by subsequent research [79,82], have yielded fully convolutional architectures that exhibit substantial improvements across diverse datasets and activity types.”
§ Past, Present, and Future of Sensor-based Human Activity Recognition Using Wearables: A Surveying Tutorial on a Still Challenging Task > Contrastive Predictive Coding.
What the sources say
- Supportedcites [79] 79. Harish Haresamudram, Irfan Essa, and Thomas Ploetz. 2024. Towards Learning Discrete Representations via Self-Supervision for Wearables-Based Human Activity Recognition. Sensors 24, 4 (2024), 1238. source
The Background (§2.3) says Enhanced CPC uses a fully convolutional architecture, substantially improves on the original CPC framework, and outperforms other self-supervised methods on four of six target datasets. The Results (§5.1) describe datasets spanning several sensor locations and activity types; the paper does not claim improvement on every dataset or activity. (LLM, conf=0.91)
- Supportedcites [82] 82. Harish Haresamudram, Irfan Essa, and Thomas Plötz. 2023. Investigating enhancements to contrastive predictive coding for human activity recognition. In 2023 IEEE International Conference on Pervasive Computing and Communications (PerCom). IEEE, 232-241. source
The paper’s opening summary says its CPC enhancements produce a fully convolutional architecture and substantial improvements across sensor positions and activities on four of six target datasets. The Conclusion also reports substantial improvements on four of six benchmark datasets. (LLM, conf=0.90)
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Supported
101 more claims · 26 with their cited sources checked
Create a free account to see all 203 claims and to verify the 2 references still open.
- It may state two separate claims as one. 47
- Probably not a substantial claim. 59
- The quote only partly states this claim. 1
- Borderline: one of the tests for a substantial claim is unclear. 1
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“A key challenge is that annotating IMU data is much more labor-intensive and costly than labeling images or text, as it often requires external reference signals and precise temporal alignment [25].”
From COMODO: Cross-Modal Video-to-IMU Distillation for Efficient Egocentric Human Activity Recognition (2026) · cites this paper as [25]
Experimental — accuracy not yet measuredIn the citing paper
“By leveraging unlabeled data samples through proxy objectives, SSL can learn transferable representations that approach and in some cases exceed supervised baselines while using substantially fewer labelled samples for downstream training1.”
From Siamese masked reconstruction with temporal rotation consistency for inertial-based human activity recognition (2026) · cites this paper as [1]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Each contradiction between two passages listed here was confirmed by an independent check.
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ Past, Present, and Future of Sensor-based Human Activity Recognition Using Wearables: A Surveying Tutorial on a Still Challenging Task > B.2.1 Segmentation and Data Loading.
“We perform training for 50 epochs with the Adam optimizer.”
§ Past, Present, and Future of Sensor-based Human Activity Recognition Using Wearables: A Surveying Tutorial on a Still Challenging Task > B.4 Performance Evaluation
“10 optimizer = optim.AdamW(model.parameters(),lr=args['learning_rate'],”
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ Past, Present, and Future of Sensor-based Human Activity Recognition Using Wearables: A Surveying Tutorial on a Still Challenging Task > B.3 HAR with Self-Supervised Learning: SimCLR
“Each block has a 1D convolutional layer, followed by ReLU and dropout with 𝑝 = 0.2.”
§ Past, Present, and Future of Sensor-based Human Activity Recognition Using Wearables: A Surveying Tutorial on a Still Challenging Task > B.3 HAR with Self-Supervised Learning: SimCLR
“1 SimCLR( 5 (relu): ReLU() 6 (dropout): Dropout(p=0.1,inplace=False) 7 ) 8 (conv2)”
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ Past, Present, and Future of Sensor-based Human Activity Recognition Using Wearables: A Surveying Tutorial on a Still Challenging Task > B.2.1 Segmentation and Data Loading.
“Inside each block is a 1D convolutional layer, followed by ReLU activation, and dropout with p=0.2.”
§ Past, Present, and Future of Sensor-based Human Activity Recognition Using Wearables: A Surveying Tutorial on a Still Challenging Task > B.4 Performance Evaluation
“Figure: 245678 2 ( 4 ( 5 ( 6 ( 7 ) 8 ( conv): Conv1d(3, 32, kernel_size=(24,), stride=(1,)) relu): ReLU() dropout): Dropout(p=0.1,inplace=False)”
Citations
Cites
Items 201–236 of 236
Towards Machine Learning with Zero Real-World Data
Kang, C., Jung, H., & Lee, Y. (2019) · WearSys@MobiSys · doi:10.1145/3325424.3329662 · Cited by 14 · cited 1×
“On an abstract level, there is currently a lot of discussion in the AI community about the exact capabilities of such models.”
CROMOSim: A Deep Learning-Based Cross-Modality Inertial Measurement Simulator
Hao, Y., Lou, X., Wang, B., & Zheng, R. (2022) · IEEE Transactions on Mobile Computing · doi:10.1109/tmc.2022.3230370 · Cited by 14
Haresamudram, H., Essa, I., & Plötz, T. (2024) · Sensors · doi:10.3390/s24041238 · Cited by 14
Self-citationSensor Positioning and Data Acquisition for Activity Recognition using Deep Learning
Chung, S., Lim, J., Noh, K. J., Kim, G. G., & Jeong, H. T. (2018) · International Conference on Information and Communication Technology Convergence (ICTC) · doi:10.1109/ictc.2018.8539473 · Cited by 13
MLPs Are All You Need for Human Activity Recognition
Ojiako, K., & Farrahi, K. (2023) · Applied Sciences · doi:10.3390/app132011154 · Cited by 12
Human behavior recognition based on sparse transformer with channel attention mechanism
Cao, K., & Wang, M. (2023) · Frontiers in Physiology · doi:10.3389/fphys.2023.1239453 · Cited by 12
MLPs Are All You Need for Human Activity Recognition
Ojiako, K., & Farrahi, K. (2023) · Applied Sciences · doi:10.20944/preprints202309.0635.v1 · Cited by 12
Fortes Rey, V., Suh, S., & Lukowicz, P. (2022) · Proceedings of the 2022 ACM International Symposium on Wearable Computers · doi:10.1145/3544794.3558464 · Cited by 12 · cited 2×
“This model learns subject-independent embeddings through adversarial learning, capable of generalizing to new subjects.”
Self-citationIMU2CLIP: Multimodal Contrastive Learning for IMU Motion Sensors from Egocentric Videos and Text
Moon, S., Madotto, A., Lin, Z., Dirafzoon, A., Saraf, A., Bearman, A., & Damavandi, B. (2022) · arXiv · doi:10.48550/arxiv.2210.14395 · Cited by 10 · cited 3×
“The idea is to encode such knowledge in the structure of the embedding space which is typically achieved by some version of contrastive or adversarial learning.”
Bello, H., Geißler, D., Suh, S., Zhou, B., & Lukowicz, P. (2024) · Lecture notes in computer science · doi:10.1007/978-3-031-78389-0_14 · Cited by 10
Self-citationHow Much Unlabeled Data is Really Needed for Effective Self-Supervised Human Activity Recognition?
Dhekane, S. G., Haresamudram, H., Thukral, M., & Plötz, T. (2023) · Proceedings of the 2023 International Symposium on Wearable Computers · doi:10.1145/3594738.3611366 · Cited by 9 · cited 1×
“The pre-training data efficiency of self-supervision was evaluated in [41], which found that even a few minutes of unlabeled data with sufficient augmentation can rival using entire dataset for pre-training.”
Self-citation(2024) · doi:10.1109/percomworkshops59983.2024.10503379 · Cited by 9
Self-citationHaresamudram, H., Beedu, A., Rabbi, M., Saha, S., Essa, I., & Ploetz, T. (2025) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v39i1.32004 · Cited by 8
Self-citationZeng, M., Gao, H., Yu, T., Mengshoel, O. J., Helge Langseth, A., Lane, I. R., & Liu, X. (2018) · arXiv (Cornell University) · doi:10.48550/arxiv.1810.04038 · Cited by 7
Smartwatch step counting: impact on daily step-count estimation accuracy
Düking, P., Strahler, J., Forster, A., Wallmann-Sperlich, B., & Sperlich, B. (2024) · Frontiers in Digital Health · doi:10.3389/fdgth.2024.1400369 · Cited by 7
CROMOSim: A Deep Learning-based Cross-modality Inertial Measurement Simulator
Hao, Y., Wang, B., & Zheng, R. (2022) · 2022 2nd International Workshop on Cyber-Physical-Human System Design and Implementation (CPHS) · doi:10.1109/cphs56133.2022.9804560 · Cited by 6 · cited 1×
“For the purpose of this article, we refrain from such discussion, as the aspects of such models that define their potential for sensor-based HAR are largely uncontroversial.”
MMTSA: Multimodal Temporal Segment Attention Network for Efficient Human Activity Recognition
Gao, Z., Wang, Y., Chen, J., Xing, J., Patel, S., Liu, X., & Shi, Y. (2022) · arXiv · doi:10.48550/arxiv.2210.09222 · Cited by 6
TENT: Connect Language Models with IoT Sensors for Zero-Shot Activity RecognitionPreprint
Zhou, Y., Yang, J., Zou, H., et al. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2311.08245 · Cited by 6
Sudershan, B. (2023) · doi:10.1145/3610896 · Cited by 5
Generalized Few-Shot Learning For Wearable Sensor-based Human Activity Recognition
Wijayasingha, L. N., & Stankovic, J. A. (2022) · IEEE International Conference on Pervasive Computing and Communications Workshops (PerCom Workshops) · doi:10.1109/percomworkshops53856.2022.9767306 · Cited by 5
Hiremath, S. K., & Ploetz, T. (2021) · 2021 International Symposium on Wearable Computers · doi:10.1145/3460421.3478825 · Cited by 4
Self-citationSingh, D. P., Ray, L. S. S., Zhou, B., Suh, S., & Lukowicz, P. (2024) · IEEE International Conference on Acoustics Speech and Signal Processing · doi:10.1109/icassp48485.2024.10447226 · Cited by 4 · cited 1×
“Yet, activity recognition goes beyond such “low hanging fruits” and the research community is now attempting more detailed activity assessments such as longitudinal health monitoring [160] including change detection, detailed sports tracking and coaching [100, 106, 124, 166, 212], or quality…”
Self-citationUnsupervised Statistical Feature-Guided Diffusion Model for Sensor-based Human Activity Recognition
Zuo, S., Rey, V. F., Suh, S., Sigg, S., & Lukowicz, P. (2023) · arXiv · doi:10.48550/arxiv.2306.05285 · Cited by 4
Self-citationContextGPT: Infusing LLMs Knowledge into Neuro-Symbolic Activity Recognition Models
Arrotta, L., Bettini, C., Civitarese, G., & Fiori, M. (2024) · arXiv · doi:10.48550/arxiv.2403.06586 · Cited by 3 · cited 1×
“As already described, for a vast majority of possible situations and activities, the model is likely to contain information on most ways to execute them and the associated situational context.”
Yet it moves: Learning from Generic Motions to Generate IMU data from YouTube videos
Rey, V. F., Garewal, K. K., & Lukowicz, P. (2020) · arXiv · doi:10.48550/arxiv.2011.11600 · Cited by 3
Self-citationSensorLLM: Aligning Large Language Models with Motion Sensors for Human Activity RecognitionPreprint
Li, Z., Deldari, S., Chen, L., et al. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2410.10624 · Cited by 1
What Makes Good Contrastive Learning on Small-Scale Wearable-based Tasks?Preprint
Qian, H., Tian, T., & Miao, C. (2022) · arXiv (Cornell University) · doi:10.48550/arxiv.2202.05998
Arithmetic Reasoning with LLM: Prolog Generation & Permutation
Yang, X., Chen, B., & Tam, Y.-C. (2024) · arXiv · doi:10.48550/arxiv.2405.17893 · cited 1×
“However, the scope of such ontologies is also limited, in particular when it comes to covering the entire breadth of less common situations.”
ConvBoost: Boosting ConvNets for Sensor-based Activity Recognition
Shao, S., Guan, Y., Zhai, B., Missier, P., & Plötz, T. (2023) · Newcastle University ePrints (Newcastle Univesity) · doi:10.25405/ncl.34475085
Self-citationEnsembles of deep LSTM Learners for Activity Recognition using Wearables
Guan, Y., & Ploetz, T. (2017) · Newcastle University ePrints (Newcastle Univesity) · doi:10.25405/ncl.34321128
OpenAI, Achiam, J., Adler, S., Agarwal, S., Ahmad, L., Akkaya, I., Aleman, F. L., Almeida, D., Altenschmidt, J., Altman, S., et al. (2023) · arXiv · doi:10.48550/arxiv.2303.08774
Towards LLM-Powered Ambient Sensor Based Multi-Person Human Activity Recognition
Chen, X., Cumin, J., Ramparany, F., et al. (2024) · arXiv · doi:10.48550/arxiv.2407.09529
Evaluating Large Language Models as Virtual Annotators for Time-series Physical Sensing Data
Hota, A., Chatterjee, S., & Chakraborty, S. (2024) · arXiv · doi:10.48550/arxiv.2403.01133
Germini, F., Noronha, N., Debono, V. B., et al. (2021) · doi:10.2196/preprints.30791
Self-supervised Learning for Human Activity Recognition Using 700,000 Person-days of Wearable Data
Yuan, H., Chan, S., Creagh, A. P., Tong, C., Acquah, A., Clifton, D. A., & Doherty, A. (2022) · arXiv · doi:10.48550/arxiv.2206.02909 · cited 1×
“More convolutional architectures have since been evaluated, typically involving deeper networks and residual connections [103, 161, 204].”
Research works printed but not linked: 14
- 10.5555/1622407.1622416 · doi:10.5555/1622407.1622416
- Spyros Gidaris, Andrei Bursuc, Jean-Baptiste Alayrac, Adrià Recasens, Mathilde Caron, Olivier Hénaff, Aäron van den Oord, and Relja Arandjelović. 2021. CVPR 2021 Tutorial on Self-Supervised Representation Learning --- gidariss.github.io. https://gidariss.github.io/self-supervised-learning-cvpr2021/. [Accessed 28-10-2024].
- Ian Goodfellow, Yoshua Bengio, and Aaron Courville. 2016. Deep Learning. MIT Press. http://www.deeplearningbook.org.
- Jonathan Ho, Ajay Jain, and Pieter Abbeel. 2020. Denoising Diffusion Probabilistic Models. In Advances in Neural Information Processing Systems H. Larochelle, M. Ranzato, R. Hadsell, M.F. Balcan, and H. Lin (Eds.), Vol. 33. Curran Associates, Inc., 6840--6851. https://proceedings.neurips.cc/paper_files/paper/2020/file/4c5bcfec8584af0d967f1ab10179ca4b-Paper.pdf
- Yifan Hu. 2023. BSDGAN: Balancing Sensor Data Generative Adversarial Networks for Human Activity Recognition. In 2023 International Joint Conference on Neural Networks (IJCNN). IEEE, 1--8.
- Alex Krizhevsky, Ilya Sutskever, and Geoffrey E Hinton. 2012. Imagenet classification with deep convolutional neural networks. Advances in neural information processing systems 25 (2012).
- Lin Liao, Dieter Fox, and Henry Kautz. 2005. Location-based activity recognition. Advances in neural information processing systems 18 (2005).
- Hiroki Ohashi, M Al-Nasser, Sheraz Ahmed, Takayuki Akiyama, Takuto Sato, Phong Nguyen, Katsuyuki Nakamura, and Andreas Dengel. 2017. Augmenting wearable sensor data with physical constraint for DNN-based human-action recognition. In ICML 2017 times series workshop. 6--11.
- Alec Radford, Jong Wook Kim, Chris Hallacy, Aditya Ramesh, Gabriel Goh, Sandhini Agarwal, Girish Sastry, Amanda Askell, Pamela Mishkin, Jack Clark, et al. 2021. Learning transferable visual models from natural language supervision. In International conference on machine learning. PMLR, 8748--8763.
- Milyun Ni'ma Shoumi and Sozo Inoue. 2024. Leveraging the Large Language Model for Activity Recognition: A Comprehensive Review. International Journal of Activity and Behavior Computing 2024, 2 (2024), 1--27.
- Jiaming Song, Chenlin Meng, and Stefano Ermon. 2021. Denoising Diffusion Implicit Models. In International Conference on Learning Representations. https://openreview.net/forum?id=St1giarCHLP
- Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N Gomez, Łukasz Kaiser, and Illia Polosukhin. 2017. Attention is all you need. Advances in neural information processing systems 30 (2017).
- Minkai Xu, Lantao Yu, Yang Song, Chence Shi, Stefano Ermon, and Jian Tang. 2022. GeoDiff: A Geometric Diffusion Model for Molecular Conformation Generation. In International Conference on Learning Representations. https://openreview.net/forum?id=PzcvxEMzvQC
- Jinsung Yoon, Daniel Jarrett, and Mihaela Van der Schaar. 2019. Time-series generative adversarial networks. Advances in neural information processing systems 32 (2019).
Cited by
Liu, X., Cheng, D., Fu, Z., Zhang, L., Wu, H., & Song, A. (2026) · IEEE Transactions on Mobile Computing · doi:10.1109/tmc.2026.3664424 · Cited by 16
Ayub, M., & El-Alfy, E.-S. M. (2025) · IEEE Access · doi:10.1109/access.2025.3631392 · Cited by 6
“The study [47] surveyed the current state-of-the-art techniques in HAR, identified the challenges, and proposed future research options.”
Ubiquitous Lingering Technologies: What's Left Behind by the Past “Proximate Futures”?
Lu, A. J., & Sun, Y. (2026) · Proceedings of the ACM on Interactive Mobile Wearable and Ubiquitous Technologies · doi:10.1145/3789676 · Cited by 4
Bian, S., Liu, M., Ray, L. S. S., Zhou, B., Guo, B., Yu, Z., Plötz, T., Lukowicz, P., Yuan, S., & Rey, V. F. (2026) · Proceedings of the ACM on Interactive Mobile Wearable and Ubiquitous Technologies · doi:10.1145/3810230 · Cited by 16
Self-citationCOMODO: Cross-Modal Video-to-IMU Distillation for Efficient Egocentric Human Activity Recognition
Chen, B., Wongso, W., Li, Z., Khaokaew, Y., Xue, H., & Salim, F. D. (2026) · Proceedings of the ACM on Interactive, Mobile, Wearable and Ubiquitous Technologies · doi:10.1145/3810218 · Cited by 1
“A key challenge is that annotating IMU data is much more labor-intensive and costly than labeling images or text, as it often requires external reference signals and precise temporal alignment [21].”
Metadata
- Authors
- Haresamudram, H., Tang, C. I., Suh, S., Lukowicz, P., & Plötz, T.
- Affiliations
- Georgia Institute of Technology (US)
- Nokia (United Kingdom) (GB)
- Korea University (KR)
- German Research Centre for Artificial Intelligence (DE)
- Venue
- Proceedings of the ACM on Interactive Mobile Wearable and Ubiquitous Technologies
- Published
- 2025-06-09
- Volume
- 9
- Issue
- 2
- Pages
- 1-44
- ISSN
- 2474-9567 (ISSN-L)
- OpenAlex
- W4411403377
- Semantic Scholar
- 72ad9f2cfb7d3aa3ffbc250be956cd5e05f405e6
- Cited by
- 33
- References
- 156
- Citations by year
- 2026: 26 · 2025: 7
- FWCI
- 11.47
- Type
- journal article
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- cc-by
- Locations
- Proceedings of the ACM on Interactive Mobile Wearable and Ubiquitous Technologies (publishedVersion, cc-by)
- arXiv (Cornell University) (submittedVersion)
- arXiv (Cornell University)
- Funders
- Horizon 2020 Framework Programme (52026 HumanE- AI-Net project)
- NSF (IS2112633)
- Topics
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Context-Aware Activity Recognition Systems
- Health Sciences › Medicine › Public Health, Environmental and Occupational Health › Physical Activity and Health
- Physical Sciences › Engineering › Biomedical Engineering › Gait Recognition and Analysis
- Keywords
- human activity recognition, wearable sensors, sensor-based activity recognition, wearable computing, feature engineering, foundation models, benchmark performance
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
The claim verdicts this report counts are experimental: their accuracy is not yet measured.
A language model drew the claims from the paper on 2026-10-05, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-10-05 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Cited sources are checked with a language model’s help (gpt-6-sol).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
