

LUMEN: Enhancing IoT System Observability with Multi-Agent Large Language Models and Knowledge Graphs
Open accessThe DOI matches its Crossref record; 103 of the 103 references it cites were found in a registry or an index; 1 of the 3 sources its claims cite were checked for support.
Abstract
This paper introduces LUMEN, which combines multi-agent LLMs, knowledge graphs, and heterogeneous databases to enable cognitive digital twins for IoT observability.
Overview
CoChat Summary
TL;DR
LUMEN combines multi-agent LLMs, knowledge graphs, and heterogeneous databases to enable cognitive digital twins for IoT observability. In two industrial case studies it achieved a 67.7% average success rate across queries, with most tasks completed under 60 seconds and at $0.002–$0.05 per run.
Key findings
- Across all evaluated tasks, LUMEN achieved a 67.7% average success rate; seven queries reached 100% success, while three queries produced no correct responses. Failures mostly stemmed from ambiguous queries, missing data schemas, or misinterpretation during complex task decomposition.
- Of 220 total runs, 124 (56%) involved no agent loops; among these, 99 were successful, giving a 79.8% first-attempt correctness rate. Of the 96 runs involving loops, 50 also resulted in correct answers.
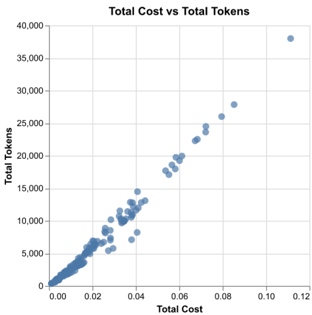
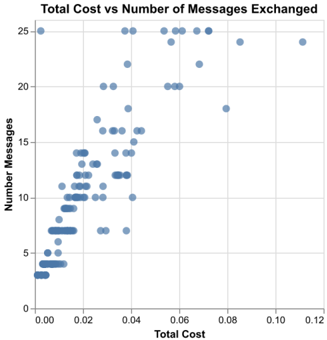
- Most responses were returned within 60 seconds, and task resolution costs ranged from $0.002 to $0.05 per run. The paper reports no clear tradeoff between accuracy and execution time, token usage, or monetary cost; cost was driven primarily by token usage and message exchanges.
- Agent loops averaged 1.10 per query for TaskPlanner, 0.87 for CodeGenerator, 0.80 for FilePathDriver, and 0.25 for GraphExplorer. Q-DS-UC2-3 had over 10 loops per run (116 total) and a 0% success rate; Q-SD-UC1-1 had an average execution time of 470.93 seconds.
Methods
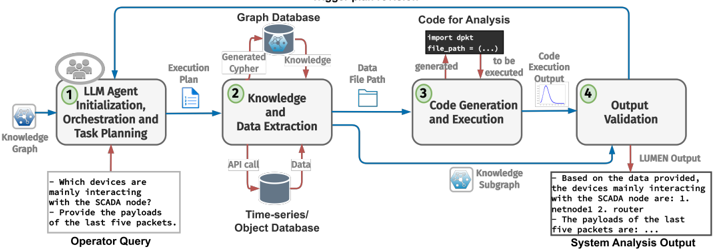
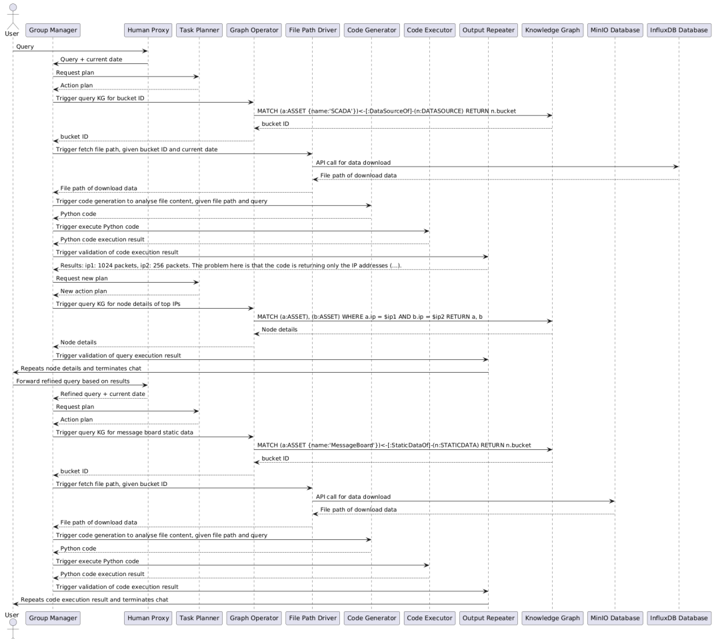
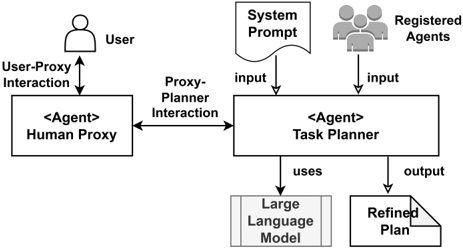
- LUMEN models the IoT system as a knowledge graph in Neo4j, stores static data in MinIO and time-series data in InfluxDB, and uses specialized LLM agents—Human Proxy, Task Planner, Graph Operator, File Path Driver, Code Generator, Code Executor, Output Repeater, and Group Manager—orchestrated via AutoGen.
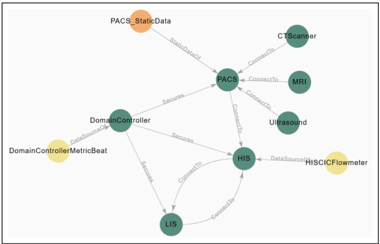
- Evaluation used two industrial use cases: electric vehicle charging station infrastructure (UC1) and healthcare information technology infrastructure (UC2), with data from Metricbeat, OCPPFlowMeter, CICFlowMeter, and network traffic PCAPs, plus knowledge-graph creation and analysis queries.
- Experiments used GPT-4o via API with temperature 0.1, 10 runs per query, and a Docker-based environment on a Windows machine with an 8-core Intel i7-11800H CPU, 32 GB RAM, and an NVIDIA RTX A3000 GPU; metrics included success rate, execution time, token usage, cost, and agent loops.
Limitations
- Stated limitations include scalability for extremely large IoT systems, dependence on knowledge graph accuracy and completeness, energy consumption and sustainability concerns from LLM inference, limited domain-specific explanations for non-expert users, and the need for future probabilistic inference.
- Stated validity threats include internal validity concerns (subjective success/failure classification, LLM stochasticity, prompt sensitivity), external validity concerns (only two industrial scenarios, reliance on GPT-4o/OpenAI API, predefined queries, simulated runtime), construct validity concerns (metrics may overlook user satisfaction or explainability), reliability concerns (stochasticity, proprietary API, prompt sensitivity), and human interaction bias from manual query design, output interpretation, labeling, and metadata supplementation.
- Evident from the text: the evaluation is limited to two use cases and a fixed GPT-4o setup; some queries had 0% success due to ambiguous phrasing or schema-less data; agent loops can add inefficiency without consistently improving success.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures






Verification
Claims the paper makes
1 Valid · 2 Not valid · 0 Not checked · 110 Own results and interpretations
A result the paper states — it cites no source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“These case studies demonstrated that LUMEN effectively automates IoT system analysis through multi-agent collaboration, but its performance highly depends on accurate task decomposition and good code generation abilities.”
- Also stated in: § Our Case Studies. · plain
“but its performance highly depends on accurate task decomposition and good code generation abilities.”
§ LUMEN: Enhancing IoT System Observability with Multi-Agent Large Language Models and Knowledge Graphs > Our Case Studies.
plainstates a causen = 2- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Also stated in: § Our Case Studies. · plain
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The approach is evaluated through two industrial case studies that demonstrate its effectiveness in IoT environments, covering multiple assessment dimensions.”
§ LUMEN: Enhancing IoT System Observability with Multi-Agent Large Language Models and Knowledge Graphs > Our Contributions.
boostedstates a causen = 2- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“One outlier is Q-DS-UC1-1, which has a 20% success rate.”
§ LUMEN: Enhancing IoT System Observability with Multi-Agent Large Language Models and Knowledge Graphs > RQ2: How efficiently do LUMEN agents collaborate to perform semantic reasoning, task decomposition, and dynamic code generation, and to what extent do iterative refinements and error corrections impact execution efficiency?
plainSingle case- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Rests on an assumption not shown here.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“achieving an average success rate of 67.7% across diverse queries”
§ LUMEN: Enhancing IoT System Observability with Multi-Agent Large Language Models and Knowledge Graphs > Our Case Studies.
plainn = 2- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“while maintaining execution times under 60 seconds for most tasks.”
§ LUMEN: Enhancing IoT System Observability with Multi-Agent Large Language Models and Knowledge Graphs > Our Case Studies.
plainn = 2- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
35 more claims
Create a free account to see all 113 claims and every source verdict.
- It may state two separate claims as one. 49
- Probably not a substantial claim. 37
- The quote only partly states this claim. 2
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Each contradiction between two passages listed here was confirmed by an independent check.
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ LUMEN: Enhancing IoT System Observability with Multi-Agent Large Language Models and Knowledge Graphs > 9.1.1 Use Cases.
“We assessed LUMEN in two use cases: (i) electric vehicle charging station infrastructure and (ii) healthcare information technology infrastructure.”
§ LUMEN: Enhancing IoT System Observability with Multi-Agent Large Language Models and Knowledge Graphs > 9.1.1 Use Cases.
“The healthcare system is our third critical infrastructure use case, distinguished by stringent trust, confidentiality requirements, and regulatory compliance.”
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ LUMEN: Enhancing IoT System Observability with Multi-Agent Large Language Models and Knowledge Graphs > 9.2 Results
“To assess timeliness, we measured the execution time for each query by timing all agent interactions.Figure 5 presents the results.”
§ LUMEN: Enhancing IoT System Observability with Multi-Agent Large Language Models and Knowledge Graphs > MERGE (n:ASSET name: 'SCADA') -[:DeployOn]->(m:ASSET name: 'n3') .
“Fig. 5. Agents facilitating the creation and maintenance of the knowledge graph in LUMEN.”
Citations
Cites
Internet of Things (IoT): A vision, architectural elements, and future directions
Gubbi, J., Buyya, R., Marusic, S., & Palaniswami, M. (2013) · Future Generation Computer Systems · doi:10.1016/j.future.2013.01.010 · Cited by 12,293
Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer
Raffel, C., Shazeer, N., Roberts, A., Lee, K., Narang, S., Matena, M., Zhou, Y., Li, W., & Liu, P. J. (2019) · arXiv · doi:10.48550/arxiv.1910.10683 · Cited by 10,929
Digital twin: Enabling technologies, challenges and open research
Fuller, A., Fan, Z., Day, C., & Barlow, C. (2020) · IEEE Access · doi:10.1109/access.2020.2998358 · Cited by 2,965
A Survey on Knowledge Graphs: Representation, Acquisition, and Applications
Ji, S., Pan, S., Cambria, E., Marttinen, P., & Yu, P. S. (2022) · IEEE Transactions on Neural Networks and Learning Systems · doi:10.1109/tnnls.2021.3070843 · Cited by 2,947
MetaGPT: Meta Programming for A Multi-Agent Collaborative Framework
Hong, S., Zhuge, M., Chen, J., Zheng, X., Cheng, Y., Zhang, C., Wang, J., Wang, Z., Yau, S. K. S., Lin, Z., et al. (2023) · arXiv · doi:10.48550/arxiv.2308.00352 · Cited by 2,825
Knowledge Graph Embedding: A Survey of Approaches and Applications
Wang, Q., Mao, Z., Wang, B., & Guo, L. (2017) · IEEE Transactions on Knowledge and Data Engineering · doi:10.1109/tkde.2017.2754499 · Cited by 2,654 · cited 1×
“This transition has unlocked new possibilities where agents with specialized roles coordinate their efforts to achieve common objectives, improving scalability and adaptability.”
A survey on large language model based autonomous agents
Wang, L., Ma, C., Feng, X., Zhang, Z., Yang, H., Zhang, J., Chen, Z., Tang, J., Chen, X., Lin, Y., et al. (2024) · Frontiers of Computer Science · doi:10.1007/s11704-024-40231-1 · Cited by 1,941
A Survey on Large Language Model based Autonomous Agents
Wang, L., Ma, C., Feng, X., Zhang, Z., Yang, H., Zhang, J., Chen, Z., Tang, J., Chen, X., Lin, Y., et al. (2023) · arXiv · doi:10.48550/arxiv.2308.11432 · Cited by 1,925
Hogan, A., Blomqvist, E., Cochez, M., D’amato, C., Melo, G. D., Gutierrez, C., Kirrane, S., Gayo, J. E. L., Navigli, R., Neumaier, S., et al. (2022) · ACM Computing Surveys · doi:10.1145/3447772 · Cited by 1,904 · cited 1×
“A knowledge graph organizes data as nodes (entities) and edges (relationships), enriched with metadata and domain-specific ontologies [17, 19, 20, 27].”
Large Language Model based Multi-Agents: A Survey of Progress and Challenges
Guo, T., Chen, X., Wang, Y., Chang, R., Pei, S., Chawla, N. V., Wiest, O., & Zhang, X. (2024) · arXiv · doi:10.48550/arxiv.2402.01680 · Cited by 1,713
Research works printed but not linked: 9
- AgentGPT. Visited in 2024. AgentGPT: a tool to configure and deploy Autonomous AI agents. Retrieved from https://agentgpt.reworkd.ai/
- Ryan Clancy, Ihab F. Ilyas, and Jimmy Lin. 2019. Scalable knowledge graph construction from text collections. In Proceedings of the 2nd Workshop on Fact Extraction and VERification. 39–46. · DOI
- Meng Ma, Ping Wang, and Chao-Hsien Chu. 2013. Data management for internet of things: Challenges, approaches and opportunities. In Proceedings of the 2013 IEEE International Conference on Green Computing and Communications and IEEE Internet of Things and IEEE Cyber, Physical and Social Computing. IEEE, 1144–1151.
- Igor Melnyk, Pierre Dognin, and Payel Das. 2021. Grapher: Multi-stage knowledge graph construction using pretrained language models. In Proceedings of the NeurIPS 2021 Workshop on Deep Generative Models and Downstream Applications.
- Jindřich Mynarz Kateřina Haniková and Vojtěch Svátek. 2023. Test-driven knowledge graph construction. https://kg-construct.github.io/workshop/2023/resources/paper4.pdf
- Ruwei Pan Hongyu Zhang and Chao Liu. 2025. CodeCoR: An LLM-based self-reflective multi-agent framework for code generation. arXiv:1409.0473. Retrieved from https://arxiv.org/abs/1701.00133 · arXiv
- 10.5555/3692070.3694124 · doi:10.5555/3692070.3694124
- Frank Wawrzik, Rami Dhouib, Khushnood Adil Rafique, and Christoph Grimm. 2023. Hybrid AI approach for knowledge graph construction. In Proceedings of the IJCKG (Workshop/Poster/Demo). 48–63.
- Zhanfang Zhao, Sung-Kook Han, and In-Mi So. 2018. Architecture of knowledge graph construction techniques. International Journal of Pure and Applied Mathematics 118, 19 (2018), 1869–1883.
Cited by
LLMs and IoT: A Comprehensive Survey on Large Language Models and the Internet of Things
Sarhaddi, F., Nguyen, N. T., Zuniga, A., Khan, M., Hui, P., Tarkoma, S., Flores, H., & Nurmi, P. (2026) · IEEE Open Journal of the Communications Society · doi:10.1109/ojcoms.2026.3680064 · Cited by 33
“Agentic AI has been used in various applications such as automated prescriptive maintenance in smart manufacturing [112], distributed IoT automation sys-tem (LLMind 2.0) [113], spatiotemporal urban data analysis (CityGPT) [114], and industrial IoT system enhancement (LUMEN) [115].”
InfluentialEmotionally Adaptive IoT Ecosystems for Neurodivergent Cognitive Regulation
Aarthi, S., & Ravikumar, R. N. (2026) · Advances in computational intelligence and robotics book series · doi:10.4018/979-8-2600-0462-3.ch007
Becattini, M., Biondino, E. G., Vicario, E., & Iera, A. (2026) · IEEE Internet of Things Journal · doi:10.1109/jiot.2026.3716300
Metadata
- Authors
- Nedisan Videsjorden, A., Song, H., Goknil, A., Roman, D., & Soylu, A.
- Affiliations
- SINTEF
- SINTEF (NO)
- Høyskolen Kristiania (NO)
- Venue
- ACM Transactions on Internet of Things
- Published
- 2026-04-21
- Volume
- 7
- Issue
- 2
- Pages
- 1-40
- ISSN
- 2577-6207 (ISSN-L)
- 2691-1914
- OpenAlex
- W4415689625
- Cited by
- 5
- References
- 28
- Citations by year
- 2026: 5
- FWCI
- 5.20
- Type
- journal article
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- cc-by
- Locations
- ACM Transactions on Internet of Things (publishedVersion, cc-by)
- Funders
- HORIZON EUROPE Framework Programme (101095634)
- Topics
- Physical Sciences › Computer Science › Information Systems › Internet of Things and AI
- Physical Sciences › Computer Science › Computer Networks and Communications › IoT and Edge/Fog Computing
- Physical Sciences › Engineering › Industrial and Manufacturing Engineering › Digital Transformation in Industry
- Keywords
- multi-agent large language models, knowledge graphs, cognitive digital twin, heterogeneous databases, time series, semantic reasoning, explainable analytics, LLM agents, Industrial Internet of Things
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
A language model drew the claims from the paper on 2026-10-07, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-10-07 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
