

The DOI matches its Crossref record; 183 of the 183 references it cites were found in a registry or an index.
A survey on missing data in machine learning
Open accessAbstract
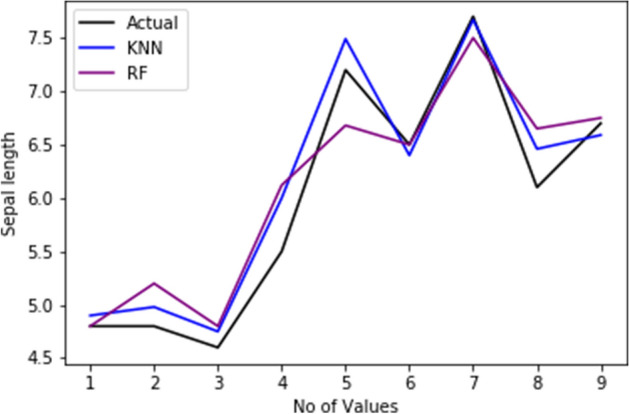
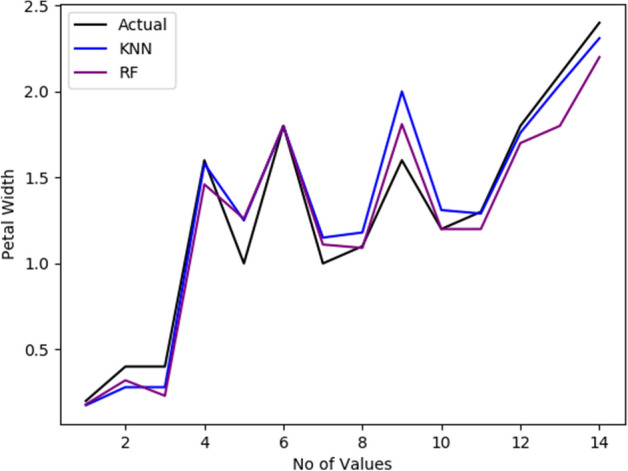
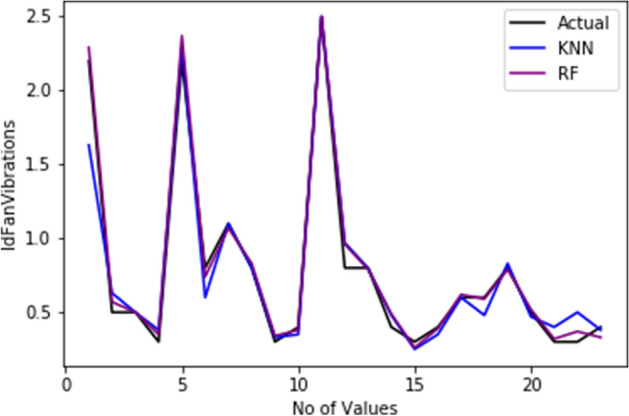
Machine learning has been the corner stone in analysing and extracting information from data and often a problem of missing values is encountered. Missing values occur because of various factors like missing completely at random, missing at random or missing not at random. All these may result from system malfunction during data collection or human error during data pre-processing. Nevertheless, it is important to deal with missing values before analysing data since ignoring or omitting missing values may result in biased or misinformed analysis. In literature there have been several proposals for handling missing values. In this paper, we aggregate some of the literature on missing data particularly focusing on machine learning techniques. We also give insight on how the machine learning approaches work by highlighting the key features of missing values imputation techniques, how they perform, their limitations and the kind of data they are most suitable for. We propose and evaluate two methods, the k nearest neighbor and an iterative imputation method (missForest) based on the random forest algorithm. Evaluation is performed on the Iris and novel power plant fan data with induced missing values at missingness rate of 5% to 20%. We show that both missForest and the k nearest neighbor can successfully handle missing values and offer some possible future research direction.
Overview
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The check wasn’t confident either way, so it gives no verdict — never disputed.
In the citing paper
“Earlier methods described in22–25 disrupt the temporal dependencies, making them unsuitable for predicting events based on sequential data.”
From Comparative analysis of machine learning approaches for heatwave event prediction in India (2025) · cites this paper as [25]
Experimental — accuracy not yet measured
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Breiman, L. (2001) · Machine Learning · doi:10.1023/a:1010933404324 · Cited by 133,538
An introduction to ROC analysis
Fawcett, T. (2006) · Pattern Recognition Letters · doi:10.1016/j.patrec.2005.10.010 · Cited by 21,879
Classification and Regression Trees.
Ryzin, J. V., Breiman, L., Friedman, J. H., Olshen, R. A., & Stone, C. J. (1986) · Journal of the American Statistical Association · doi:10.2307/2288003 · Cited by 20,825
Statistical Analysis With Missing Data
Lahiff, M., Little, R. J. A., & Rubin, D. B. (1989) · Journal of the American Statistical Association · doi:10.2307/2289883 · Cited by 17,265
THE USE OF MULTIPLE MEASUREMENTS IN TAXONOMIC PROBLEMS
FISHER, R. A. (1936) · Annals of Eugenics · doi:10.1111/j.1469-1809.1936.tb02137.x · Cited by 15,227
Classification And Regression Trees
Breiman, L., Friedman, J. H., Olshen, R. A., & Stone, C. J. (2017) · doi:10.1201/9781315139470 · Cited by 11,417
Classification and regression trees
Praagman, J. (1985) · European Journal of Operational Research · doi:10.1016/0377-2217(85)90321-2 · Cited by 10,053
RUBIN, D. B. (1976) · Biometrika · doi:10.1093/biomet/63.3.581 · Cited by 9,925
Chai, T., & Draxler, R. R. (2014) · Geoscientific Model Development · doi:10.5194/gmd-7-1247-2014 · Cited by 8,761 · cited 2×
“However, [144] partially disputed the conclusions and introduced arguments against avoiding RMSE.”
BackgroundText categorization with Support Vector Machines: Learning with many relevant features
Joachims, T. (1998) · Lecture Notes in Computer Science · doi:10.1007/bfb0026683 · Cited by 7,999
Research works printed but not linked: 9
- Suthar B, Patel H, Goswami A. A survey: classification of imputation methods in data mining. Int J Emerg Technol Adv Eng. 2012;2(1):309–12.
- Chen Y-C. Pattern graphs: a graphical approach to nonmonotone missing data. arXiv preprint arXiv:2004.00744. 2020. · arXiv
- Williams R. Missing data Part 1: overview, traditional methods. Notre Dame: University of Notre Dame; 2015.
- Allison PD. Missing data, vol. 136. Thousand Oaks: Sage Publications; 2001.
- Delalleau O, Courville A, Bengio Y. Efficient EM training of gaussian mixtures with missing data. arXiv preprint arXiv:1209.0521. 2012. · arXiv
- Gimpy M. Missing value imputation in multi attribute data set. Int J Comput Sci Inf Technol. 2014;5(4):1–7.
- He Y, Pi D-C. Improving KNN method based on reduced relational grade for microarray missing values imputation. IAENG Int J Comput Sci. 2016;43(3):1–7.
- Gimpy D, Rajan Vohra M. Estimation of missing values using decision tree approach. Int J Comput Sci Inf Technol. 2014;5(4):5216–20.
- Phyu TN. Survey of classification techniques in data mining. In: Proceedings of the international multiconference of engineers and computer scientists, vol. 1. 2009.
Cited by
Validation of biomarkers of aging
Moqri, M., Herzog, C., Poganik, J. R., Ying, K., Justice, J. N., Belsky, D. W., Higgins-Chen, A. T., Chen, B. H., Cohen, A. A., Fuellen, G., et al. (2024) · Nature Medicine · doi:10.1038/s41591-023-02784-9 · Cited by 361
Liu, M., Li, S., Yuan, H., Ong, M. E. H., Ning, Y., Xie, F., Saffari, S. E., Shang, Y., Volovici, V., Chakraborty, B., et al. (2023) · Artificial Intelligence in Medicine · doi:10.1016/j.artmed.2023.102587 · Cited by 219
Prediction of diabetes disease using an ensemble of machine learning multi-classifier models
Abnoosian, K., Farnoosh, R., & Behzadi, M. H. (2023) · BMC Bioinformatics · doi:10.1186/s12859-023-05465-z · Cited by 214
Li, J., Guo, S., Ma, R., He, J., Zhang, X., Rui, D., Ding, Y., Li, Y., Jian, L.-Y., Cheng, J., et al. (2024) · BMC Medical Research Methodology · doi:10.1186/s12874-024-02173-x · Cited by 210
The impact of imputation quality on machine learning classifiers for datasets with missing values
Shadbahr, T., Roberts, M., Stanczuk, J., Gilbey, J., Teare, P., Dittmer, S., Thorpe, M., Viñas, R., Sala, E., Lió, P., et al. (2023) · Communications Medicine · doi:10.1038/s43856-023-00356-z · Cited by 198
Metadata
- Authors
- Emmanuel, T., Maupong, T., Mpoeleng, D., Semong, T., Mphago, B., & Tabona, O.
- Affiliations
- Botswana International University of Science and Technology (BW)
- Corresponding author
- Emmanuel, Tlamelo
- Venue
- Journal of Big Data
- Published
- 2021-10-27
- Volume
- 8
- Issue
- 1
- Pages
- 140-140
- ISSN
- 2196-1115 (ISSN-L)
- PMC
- PMC8549433
- OpenAlex
- W3170657538
- Semantic Scholar
- e2e8ea9bcdb83deb2787ce89db1b51f7ccb1bd1e
- Cited by
- 1,067
- References
- 183
- Citations by year
- 2026: 203 · 2025: 345 · 2024: 284 · 2023: 164 · 2022: 69 · 2021: 2
- FWCI
- 96.80
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Licence
- cc-by
- creativecommons.org/licenses/by/4.0 (tdm)
- creativecommons.org/licenses/by/4.0 (vor)
- Locations
- Journal Of Big Data (publishedVersion, cc-by)
- Europe PMC (PubMed Central) (publishedVersion, other-oa)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion, cc-by-sa)
- Funders
- Botswana International University of Science and Technology
- Topics
- Physical Sciences › Mathematics › Statistics and Probability › Statistical Methods and Bayesian Inference
- Physical Sciences › Computer Science › Artificial Intelligence › Machine Learning and Data Classification
- Physical Sciences › Computer Science › Information Systems › Data Mining and Machine Learning Applications
- Keywords
- missing data, missing completely at random, missing at random, missing not at random, k-nearest neighbors imputation, missForest, random forest, Iris dataset
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
How to cite
Cite CoChat for the checks on this page, and the paper for its own findings.
- This page
- CoChat. (2026). Citation check: A survey on missing data in machine learning. https://app.cochat.ai/papers/10.1186/s40537-021-00516-9
- The paper
- Emmanuel, T., Maupong, T., Mpoeleng, D., Semong, T., Mphago, B., & Tabona, O. (2021). A survey on missing data in machine learning. Journal of Big Data. https://doi.org/10.1186/s40537-021-00516-9
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
