

The DOI matches its Crossref record; 43 of the 44 references it cites were found in a registry or an index; none of the 22 sources its claims cite is checked for support yet.
Adaptive trust calibration for human-AI collaboration
Open accessAbstract
Safety and efficiency of human-AI collaboration often depend on how humans could appropriately calibrate their trust towards the AI agents. Over-trusting the autonomous system sometimes causes serious safety issues. Although many studies focused on the importance of system transparency in keeping proper trust calibration, the research in detecting and mitigating improper trust calibration remains very limited. To fill these research gaps, we propose a method of adaptive trust calibration that consists of a framework for detecting the inappropriate calibration status by monitoring the user's reliance behavior and cognitive cues called "trust calibration cues" to prompt the user to reinitiate trust calibration. We evaluated our framework and four types of trust calibration cues in an online experiment using a drone simulator. A total of 116 participants performed pothole inspection tasks by using the drone's automatic inspection, the reliability of which could fluctuate depending upon the weather conditions. The participants needed to decide whether to rely on automatic inspection or to do the inspection manually. The results showed that adaptively presenting simple cues could significantly promote trust calibration during over-trust.
Overview
AI snapshot
Written from the paper’s full text.
TL;DR
The paper proposes adaptive trust calibration: a behavior-based framework detects over-trust/under-trust and presents “trust calibration cues” (TCCs) only when needed. In an online drone-simulator experiment, adaptively presented TCCs significantly increased manual choices and improved sensitivity d′ during over-trust, whereas continuous reliability information alone did not.
Key findings
- Of 194 online participants, 116 successfully inspected at least 15 checkpoints; they completed 1,740 inspections with a correct rate of 0.74, choosing automatic inspection 1,236 times (0.71) and manual inspection 504 times (0.29).
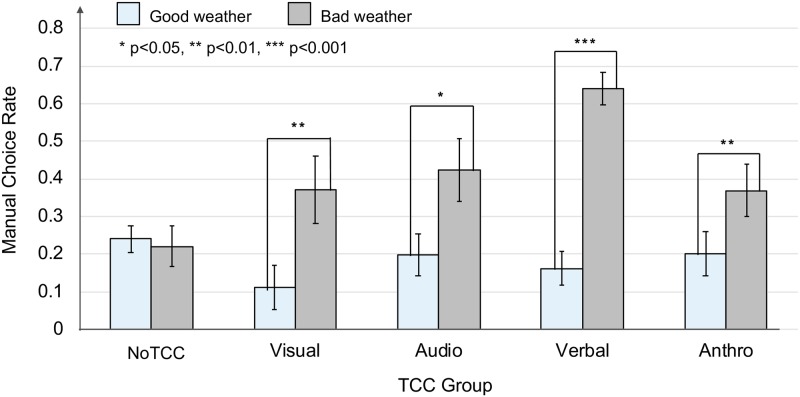
- A two-factor mixed ANOVA found a significant main effect of weather period on manual rates [F(1, 111) = 51.69, p < 0.01] and a significant interaction between TCC group and period [F(4, 111) = 4.86, p < 0.01]. The NoTCC group did not significantly change manual rates between good and bad weather, while all TCC groups did: visual [F(1, 17) = 9.20, p < 0.01], audio [F(1, 21) = 5.54, p = 0.03], verbal [F(1, 28) = 62.9, p < 0.001], and anthropomorphic [F(1, 18) = 8.55, p < 0.01].
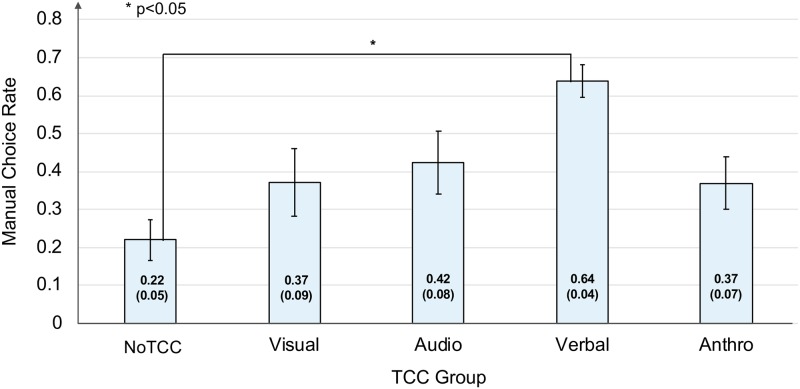
- In bad weather, the verbal TCC group had a significantly higher manual rate than both NoTCC [t(111) = 4.77, adj.p < 0.01] and anthropomorphic TCC [t(111) = 2.74, adj.p = 0.04].
- Sensitivity d′ in bad weather was significantly higher for the verbal group (0.92, SE 0.14) than for NoTCC [t(111) = 2.97, adj.p = 0.04, Cohen’s d = 0.75]; accuracy declined in bad weather but did not differ significantly among groups, though the verbal group had the highest mean accuracy (0.72, SE 0.04).
Methods
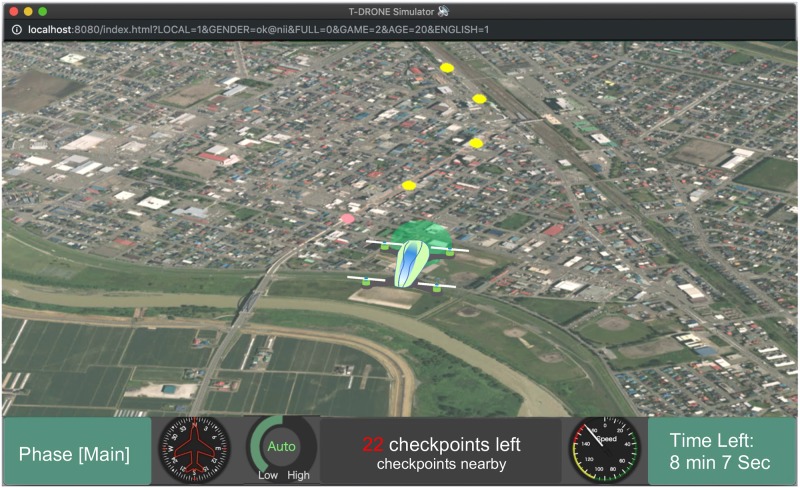
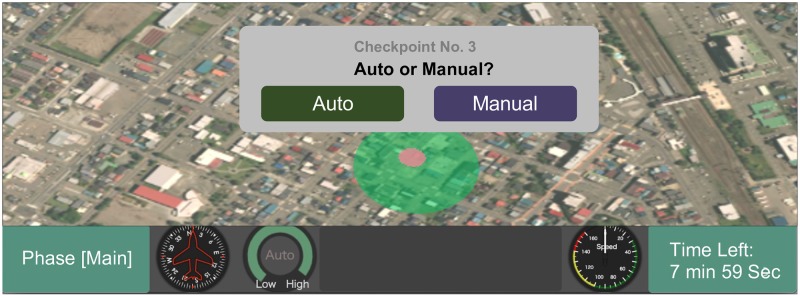
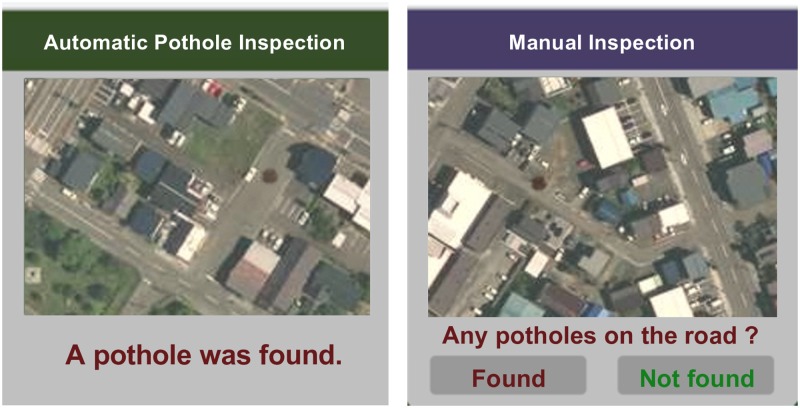
- Online experiment using a 3D drone simulator built with CesiumJS and Bing Map API. Participants performed a pothole inspection task over 30 checkpoints (10 with potholes, 20 without), choosing between automatic inspection and manual inspection; they were randomly assigned to NoTCC, visual, audio, verbal, or anthropomorphic TCC groups.
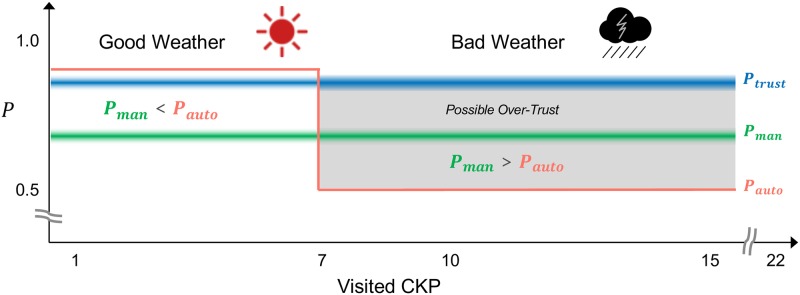
- Automatic inspection reliability Pauto was manipulated: good weather Pauto = 90% and d′ = 1.8; bad weather Pauto = 50% and d′ = 0.1. The framework detected over-trust by observing reliance behavior and comparing Pman and Pauto, then presented a TCC when over-trust was detected.
- Main analyses were two-factor mixed ANOVAs with TCC group as between-subjects and checkpoint period as within-subjects, plus Holm–Bonferroni-adjusted post hoc comparisons and t-tests for Pman.
Limitations
- Stated: the framework focuses only on performance-related factors, ignoring other automation benefits such as faster completion, lighter workload, or fewer risks; it evaluates only an over-trust scenario; it does not guarantee convergence of behavior; and it uses only a pothole inspection/reconnaissance task and four TCC types.
- Stated: correct answers were not shown during the task, and automatic-inspection results were shown only when participants chose automatic inspection, not manual inspection; future work should test combinations of feedback information.
- Evident: attrition was high—78 of 194 participants failed to complete the task within the time limit because they moved the drone away from the checkpoints—so the analyzed sample of 116 may not represent all recruited participants.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
29 Own result · 26 Own interpretation · 11 Not checked yet · 6 Own method · 3 No basis given
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The participants of the group without TCC did not change their behavior when they were in over-trust status, even if the system reliability information was continuously presented.”
§ Adaptive trust calibration for human-AI collaboration > Introduction
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We found that adaptively presented TCCs significantly affected the choice behavior of the participants.”
§ Adaptive trust calibration for human-AI collaboration > Introduction
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“while TCC rates in the anthro. TCC group did not follow the decreasing trend.”
§ Adaptive trust calibration for human-AI collaboration > Results > TCC rates
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“and that Pman in the bad weather period was significantly larger than Pauto = 0.50 [Mean = 0.86, t(200) = 17.79, p < 0.01, Cohen’s d = 1.25].”
§ Adaptive trust calibration for human-AI collaboration > Results > Performance: Sensitivity d′ and accuracy
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- The authors state this as an assumption: Manual accuracy can be used to estimate Pman.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“One-sample t-tests showed that Pman in the good weather period was significantly smaller than Pauto = 0.90 [Mean = 0.81, t(71) = −2.17, p = 0.03, Cohen’s d = 0.26]”
§ Adaptive trust calibration for human-AI collaboration > Results > Performance: Sensitivity d′ and accuracy
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- The authors state this as an assumption: Manual accuracy can be used to estimate Pman.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“A significant interaction was found between the two factors [F(4, 111) = 4.86, p < 0.01, ].”
§ Adaptive trust calibration for human-AI collaboration > Results > Manual rates
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“and the anthro. group (t(111) = 2.74, adj.p = 0.04).”
§ Adaptive trust calibration for human-AI collaboration > Results > Manual rates
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“a Welch’s t-test indicated that there was no significant difference between Pman in the good weather period and in the bad one [t(114) = −1.08, p = 0.28, Cohen’s d = 0.16].”
§ Adaptive trust calibration for human-AI collaboration > Results > Performance: Sensitivity d′ and accuracy
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- The authors state this as an assumption: Manual accuracy can be used to estimate Pman.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“No other differences between the groups were found to be significant.”
- Also stated in: § Effects of TCCs to change the participants’ behavior · plain
“The result, however, showed that its manual choice rate was not significantly larger than the one of NoTCc group.”
§ Adaptive trust calibration for human-AI collaboration > Results > Manual rates
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Also stated in: § Effects of TCCs to change the participants’ behavior · plain
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“TCC rates in the verbal TCC group were higher in the early part of the period and gradually decreased.”
§ Adaptive trust calibration for human-AI collaboration > Results > TCC rates
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Probably not a substantial claim. 16
- It may state two separate claims as one. 16
- The quote only partly states this claim. 1
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The participants did the manual inspection 504 times (the choice rate = 0.29).”
§ Adaptive trust calibration for human-AI collaboration > Results
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“however, the verbal group showed the highest mean value (0.72 (SE 0.04)), and other groups with TCCs also had better accuracy values (0.6 (SE 0.04)) than the NoTCC group.”
§ Adaptive trust calibration for human-AI collaboration > Results > Performance: Sensitivity d′ and accuracy
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The visual and audio TCC groups also showed a similar trend”
§ Adaptive trust calibration for human-AI collaboration > Results > TCC rates
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
The quote only partly states this claim.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“They inspected the total of 1,740 CKPs from the 1st CKP to the 15th CKP, and the results of 1,282 inspections were correct, making the correct answer rate 0.74.”
§ Adaptive trust calibration for human-AI collaboration > Results
plainn = 16- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“In the bad weather period, post-hoc comparisons indicated that the sensitivity d′ of the verbal group, which was the highest (0.92 (SE 0.14) among all the groups, was significantly higher than the sensitivity d′ of the NoTCC group [t(111) = 2.97, adj.p = 0.04, Cohen’s d = 0.75].”
§ Adaptive trust calibration for human-AI collaboration > Results > Performance: Sensitivity d′ and accuracy
hedged- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Automatic inspection was selected 1,236 times (the choice rate = 0.71).”
§ Adaptive trust calibration for human-AI collaboration > Results
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Though there was no statistical difference in accuracy among the groups, all the groups with TCCs also showed better accuracy than the NoTCC group.”
§ Adaptive trust calibration for human-AI collaboration > Discussion > Performance
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“To solve this dilemma that could perpetuate an inappropriate status of trust calibration, a new trigger would be necessary in instances of over-trust or under-trust.”
§ Adaptive trust calibration for human-AI collaboration > Introduction > Our approach: Adaptive trust calibration
hedgeddirect- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence.
In the paper
“Calibration can only occur in response to new evidence that may change the users’ prevailing recognition, while no new evidence can be learned without changing the current behavior first [5].”
§ Adaptive trust calibration for human-AI collaboration > Introduction > Our approach: Adaptive trust calibration
What the sources say
- Not checked yetcites [5] Adams BD, Bruyn LE, Houde S. Trust in automated systems literature review. Defence Research and Development Canada; 2003. Report No. CR-2003-096.
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
In the paper
“Regarding online experiments in general, Crump et al. [32] showed that the data collected online using a web-browser seemed mostly in line with laboratory results, so long as the experiment methods were solid.”
§ Adaptive trust calibration for human-AI collaboration > Materials and methods > Participants
What the sources say
- Not checked yetcites [32] MJC Crump, 2013, Evaluating amazon’s mechanical turk as a tool for experimental behavioral research, PLoS ONE source
hedged- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“This approach is to mitigate over-trust or under-trust, in contrast with the traditional approach of trying to maintain appropriate trust calibration with continuous system transparency.”
§ Adaptive trust calibration for human-AI collaboration > Introduction > Our approach: Adaptive trust calibration
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: unclear — It is unclear why the paper says it holds.
It may state two separate claims as one.
In the paper
“Behaviors might not be observable if there is no interaction; nevertheless, behavioral measures are practical and can easily be used as a basis for modeling and prediction [25].”
§ Adaptive trust calibration for human-AI collaboration > Introduction > Measuring trust
What the sources say
- Not checked yetcites [25] K Drnec, 2016, From trust in automation to decision neuroscience: applying cognitive neuroscience methods to understand and improve interaction decisions involved in human automation interaction, Frontires In Human Neuroscience
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Instead of directly measuring Ptrust or , the first inequalities of (1) and (2) can be estimated by observing the user’s reliance behavior; thus, the trust calibration status can be detected, if the second inequalities of Pman and Pauto can be estimated.”
§ Adaptive trust calibration for human-AI collaboration > Introduction > Our approach: Adaptive trust calibration
hedgedconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“194 participants joined the experiment online.”
§ Adaptive trust calibration for human-AI collaboration > Materials and methods > Participants
plainn = 194- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“As for the successful participants, their ages ranged from 20 to 69 years old (M = 43.25, SD = 14.01), 66 participants were male and 50 were females.”
§ Adaptive trust calibration for human-AI collaboration > Results
plainn = 16- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“28 were in the NoTCC group, 18 in the visual group, 22 in the audio group, 29 in the verbal group, and 19 in the anthro. group.”
§ Adaptive trust calibration for human-AI collaboration > Results
plainn = 16- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“Seventy eight participants unintentionally moved the drone far from the area where the CKPs were located, and they failed to complete the tasks within the time limit.”
§ Adaptive trust calibration for human-AI collaboration > Results
plainn = 78- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“One hundred sixteen participants successfully inspected 15 CKPs or more within the time limit.”
§ Adaptive trust calibration for human-AI collaboration > Results
plainn = 116- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
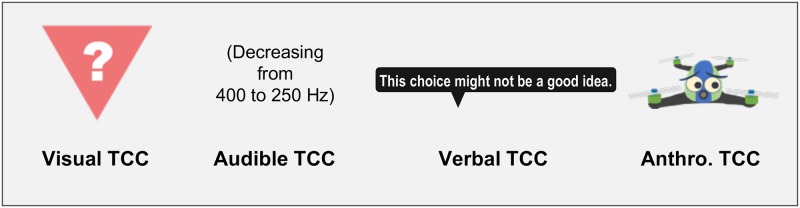
“Participants were randomly assigned to one of five groups with the corresponding TCCs: NoTCC group (without TCCs), visual group (with the visual sign TCC), audio group (with the audio TCC), verbal group (with the verbal TCC), and anthro. group (with the anthropomorphic TCC).”
§ Adaptive trust calibration for human-AI collaboration > Materials and methods > Procedure
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“TCCs were given right after the behavior only if the participants were judged to over-trust, so that it would be easier for the participants to understand the implication of the cues and to move forward in the trust calibration process.”
§ Adaptive trust calibration for human-AI collaboration > Discussion > Adaptive method vs. continuous method
hedgeddirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may state two separate claims as one.
In the paper
“However, automation could be beneficial beyond a better performance, such as for faster task completion, lighter workloads, fewer risks, etc. [3]”
§ Adaptive trust calibration for human-AI collaboration > Discussion > Limitations and future research
What the sources say
- Not checked yetcites [3] R Parasuraman, 1997, Humans and automation: Use, misuse, disuse, abuse, Human Factors source
hedgedconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Previous studies emphasized the importance of the system transparency for proper trust calibration.”
§ Adaptive trust calibration for human-AI collaboration > Conclusion
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper may give no reason why it holds.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“These results indicated that adaptively presenting TCCs promoted appropriate trust calibration leading to the better performance in the bad weather period.”
§ Adaptive trust calibration for human-AI collaboration > Discussion > Performance
hedgeddirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
None of the sources cited for this claim have been checked yet.
In the paper
“It was obvious that the participants recognized these visually impressive TCCs; however, the results suggested that just being salient on the screen was not enough for some of the participants to change their choice behavior [31, 40].”
§ Adaptive trust calibration for human-AI collaboration > Discussion > Effects of TCCs to change the participants’ behavior
What the sources say
- Not checked yetcites [31] KR Laughery, 2014, A three-stage model summarizes product warning and environmental sign research, Safety Science source
- Not checked yetcites [40] VC Conzola, 2001, A Communication—Human Information Processing (C–HIP) approach to warning effectiveness in the workplace, Journal of Risk Research source
hedged- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The proposed method deals with users’ behaviors to choose Auto or Manual and does not guarantee the convergence of the behaviors, which is the result of trust calibration by users.”
§ Adaptive trust calibration for human-AI collaboration > Discussion > Limitations and future research
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
In the paper
“Therefore, trust as the observable and rational choice behavior can be a product of believing that these benefits will outweigh the costs [5].”
§ Adaptive trust calibration for human-AI collaboration > Discussion > Limitations and future research
What the sources say
- Not checked yetcites [5] Adams BD, Bruyn LE, Houde S. Trust in automated systems literature review. Defence Research and Development Canada; 2003. Report No. CR-2003-096.
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The feedback information given for each inspection was very important for the participants to make decisions.”
§ Adaptive trust calibration for human-AI collaboration > Discussion > Limitations and future research
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. The paper may give no reason why it holds.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“The pothole inspection task in the experiment is a remote sensing task, and it would be quite difficult for the system to know the correct answer (ground truth) at the time of each inspection in practical situations because the only information available is the image data and the results of automatic recognition.”
§ Adaptive trust calibration for human-AI collaboration > Discussion > Limitations and future research
hedgeddirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
The authors state this as an assumption.
Pauto fluctuates more widely than Pman under changing weather conditions.
“Therefore, we assumed that Pauto would fluctuate more widely than Pman under changing weather conditions.”
The paper relies on this without support.
Trust is a latent construct and cannot be directly measured; measuring trust experimentally is difficult in general.
“Trust is a latent construct and cannot be directly measured; measuring trust experimentally is difficult in general.”
The paper relies on this without support.
Users often fail to calibrate their trust in the agent and end up in over-trust or under-trust.
“While an agent’s reliability changes for various reasons in an environment, the users often fail to calibrate their trust in the agent and end up in the status called over-trust or under-trust.”
The paper relies on this without support.
Self-report measures are too intrusive to be viable in applied settings.
“Most previous literature used self-report measures such as subjective rating with questionnaires [18] or rating scales [19, 20]; however, self-report measures are too intrusive to be viable in applied settings.”
The paper relies on this without support.
Physiological and neural measures usually require special hardware.
“Although these measures can be used for dynamic tracking of trust, they usually require special hardware.”
The paper relies on this without support.
TCC rates are a valid indicator of over-trust or trust calibration status.
“TCC rates in the verbal TCC group were higher in the early part of the period and gradually decreased. This indicates that over-trust decreased during this period.”
The authors state this as an assumption.
Manual accuracy can be used to estimate Pman.
“The results of the manual accuracy were consistent with our assumption to estimate Pman − Pauto in this experiment.”
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Notwithstanding a clear agenda on the issues that we should explore further, we still have limited evidence-based knowledge of the context, design, and psychological mechanisms that would craft an optimal human–ai team15–17.”
From Experimental evidence of effective human–AI collaboration in medical decision-making (2022) · cites this paper as [16]
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“They also found that giving additional trigger signals was effective in resolving this problem [16].”
From Dynamic Selection of Reliance Calibration Cues With AI Reliance Model (2023) · cites this paper as [16]
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Avoiding misplaced trust in AI results is not essentially a technical challenge (Okamura and Yamada 2020).”
From Keeping the organization in the loop: a socio-technical extension of human-centered artificial intelligence (2023) · cites this paper as Okamura and Yamada 2020
Experimental — accuracy not yet measuredThe cited source says what the claim attributes to it.
In the citing paper
“In their experiment, participants did not change their over-reliance in spite of a reliability indicator being continuously displayed to them.”
From Dynamic Selection of Reliance Calibration Cues With AI Reliance Model (2023) · cites this paper as [16]
The cited source says what the claim attributes to it.
In the citing paper
“Various interventions have been explored to foster trust calibration, such as displaying confidence scores that indicate the likelihood of a model's outputs being correct to end users [124], and designing adaptive monitoring systems that visually prompt users to calibrate their trust when over-trust or under-trust is detected during human-AI collaboration [87]”
From Understanding the Practices, Perceptions, and (Dis)Trust of Generative AI among Instructors: A Mixed-methods Study in the U.S. Higher Education (2025) · cites this paper as [87]
Statistics recomputed
Every reported test result, recomputed from its test statistic and degrees of freedom. A result shows as not adding up only once an independent check has confirmed it.
- ConsistentF(1, 111) = 51.69reported p < .01 · recomputed p < .001
“F(1, 111) = 51.69, p < .01”
- ConsistentF(4, 111) = 4.86reported p < .01 · recomputed p = .001
“F(4, 111) = 4.86, p < .01”
- ConsistentF(1, 17) = 9.2reported p < .01 · recomputed p = .008
“F(1, 17) = 9.20, p < .01”
- ConsistentF(1, 21) = 5.54reported p = .03 · recomputed p = .028
“F(1, 21) = 5.54, p = .03”
- ConsistentF(1, 28) = 62.9reported p < .001 · recomputed p < .001
“F(1, 28) = 62.9, p < .001”
- ConsistentF(1, 18) = 8.55reported p < .01 · recomputed p = .009
“F(1, 18) = 8.55, p < .01”
- Consistentt(114) = -1.08reported p = .28 · recomputed p = .282
“t(114) = −1.08, p = .28”
- Consistentt(71) = -2.17reported p = .03 · recomputed p = .033
“t(71) = −2.17, p = .03”
- Consistentt(200) = 17.79reported p < .01 · recomputed p < .001
“t(200) = 17.79, p < .01”
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Each contradiction between two passages listed here was confirmed by an independent check.
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ Adaptive trust calibration for human-AI collaboration > Results
“TCCs were not presented in the period from the 7th CKP to the 9th CKP”
§ Adaptive trust calibration for human-AI collaboration > Results
“| Visual TCC | 0.78 (0.10) | 0.67 (0.11) | 0.56 (0.12) | 0.67 (0.11) | 0.67 (0.11) | 0.50 (0.12) | 0.56 (0.12) |”
Citations
Cites
ImageNet classification with deep convolutional neural networks
Krizhevsky, A., Sutskever, I., & Hinton, G. E. (2017) · Communications of the ACM · doi:10.1145/3065386 · Cited by 112,155
Trust in Automation: Designing for Appropriate Reliance
Lee, J. D., & See, K. A. (2004) · Human Factors: The Journal of the Human Factors and Ergonomics Society · doi:10.1518/hfes.46.1.50_30392 · Cited by 6,605
Humans and automation: Use, misuse, disuse, abuse
Parasuraman, R., & Riley, V. (1997) · Human Factors: The Journal of the Human Factors and Ergonomics Society · doi:10.1518/001872097778543886 · Cited by 4,554
A model for types and levels of human interaction with automation
Parasuraman, R., Sheridan, T. B., & Wickens, C. D. (2000) · IEEE Transactions on Systems, Man, and Cybernetics - Part A: Systems and Humans · doi:10.1109/3468.844354 · Cited by 4,195 · cited 1×
“A possible explanation for the result could be made by discussing models for the trust process [1, 27, 41].”
BackgroundTrust in Automation: Integrating Empirical Evidence on Factors That Influence Trust
Hoff, K. A., & Bashir, M. (2015) · Human Factors: The Journal of the Human Factors and Ergonomics Society · doi:10.1177/0018720814547570 · Cited by 2,817
Calculation of signal detection theory measures
Stanislaw, H., & Todorov, N. (1999) · Behavior Research Methods, Instruments, & Computers · doi:10.3758/bf03207704 · Cited by 2,673
A Meta-Analysis of Factors Affecting Trust in Human-Robot Interaction
Hancock, P. A., Billings, D. R., Schaefer, K. E., Chen, J. Y. C., de Visser, E. J., & Parasuraman, R. (2011) · Human Factors: The Journal of the Human Factors and Ergonomics Society · doi:10.1177/0018720811417254 · Cited by 2,051 · cited 1×
“[10] examined factors that affect trust by applying meta-analysis methods to existing empirical studies.”
MethodFoundations for an Empirically Determined Scale of Trust in Automated Systems
Jian, J.-Y., Bisantz, A. M., & Drury, C. G. (2000) · International Journal of Cognitive Ergonomics · doi:10.1207/s15327566ijce0401_04 · Cited by 1,799
Evaluating amazon’s mechanical turk as a tool for experimental behavioral research
Crump, M. J. C., McDonnell, J. V., & Gureckis, T. M. (2013) · PLoS ONE · doi:10.1371/journal.pone.0057410 · Cited by 1,617
The mind in the machine: Anthropomorphism increases trust in an autonomous vehicle
Waytz, A., Heafner, J., & Epley, N. (2014) · Journal of Experimental Social Psychology · doi:10.1016/j.jesp.2014.01.005 · Cited by 1,439
Research works printed but not linked: 1
- Adams BD, Bruyn LE, Houde S. Trust in automated systems literature review. Defence Research and Development Canada; 2003. Report No. CR-2003-096.
Cited by
Sorted by citations
Items 201–248 of 248
Satellite Constellations and Artificial Intelligence: An Organizational Challenge For Defense?
Lucas, M. D. (2025) · Revue Défense Nationale · doi:10.3917/rdna.883.0045
Alam, J. U. (2026) · American Journal of Advanced Technology and Engineering Solutions · doi:10.63125/mv67zd78
Ge, C., Wang, X., & Ma, K. (2025) · International Conference on Intelligent Design (ICID) · doi:10.1109/icid67979.2025.11351467
Trust and Risk-aware Human–AI Collaboration Framework in AI-Enabled OT Systems
Akbarzadeh, A., & Spathoulas, G. P. (2025) · IEEE Annual Congress on Artificial Intelligence of Things (AIoT) · doi:10.1109/aiot66900.2025.00067
Triantafyllopoulos, L., Paxinou, E., & Kalles, D. (2026) · Διεθνές Συνέδριο για την Ανοικτή & εξ Αποστάσεως Εκπαίδευση · doi:10.12681/icodl.8542
Cognitive Drones and Human–Artificial Intelligence Trust Calibration Across Industrial Sectors
Alloghani, M. A. (2026) · Springer eBooks · doi:10.1007/978-3-032-15594-8_6
Shao, X., Jiang, W., & Osman, K. N. (2026) · Frontiers in Psychology · doi:10.3389/fpsyg.2026.1821188
Guynup, C., Nguyen, H., Basappa, R., André, K., Yancey, M., Flathmann, C., McNeese, N. J., Toxtli, C., Madathil, K. C., & Gramopadhye, A. K. (2026) · IEEE Conference on Cognitive and Computational Aspects of Situation Management (CogSIMA) · doi:10.1109/cogsima68896.2026.11481227
Golahi, G., Antonio, F., & Annisa, D. N. (2026) · JMIR Medical Education · doi:10.2196/preprints.100828
Organizational Practices and Socio-Technical Design of Human-Centered AI
Herrmann, T. (2026) · Springer eBooks · doi:10.1007/978-981-95-3658-0_66
Face value: How avatar identity shapes epistemic trust in AI-mediated learning
Anthis, Z., & Kyriakidou-Zacharoudiou, A. (2026) · Computers and Education Artificial Intelligence · doi:10.1016/j.caeai.2026.100610 · Cited by 1
Future Directions—Human-AI Collaboration, Adaptive Explanations, and Regulatory Readiness
Mofrad, F. B., & Yousefzamani, M. (2026) · Springer eBooks · doi:10.1007/978-3-032-15088-2_12
Artificial Trust Model for Human-AI Teaming Systems
Maathuis, C. (2026) · IEEE Swiss Conference on Data Science (SDS) · doi:10.1109/sds70563.2026.00009
Crichton, K., Reddy, A., & Ji, J. (2026) · doi:10.51593/20250002
Saoud, L. S., & Qureshi, O. A. (2026) · Communications in computer and information science · doi:10.1007/978-3-032-28819-6_31
Strategic Decision-Making Frameworks With Human-AI Systems
Roos, G. (2026) · Advances in computational intelligence and robotics book series · doi:10.4018/979-8-3373-7036-1.ch004
AI-Augmented Leadership and Digital Decision-Making Models
Roos, G. (2026) · Advances in computational intelligence and robotics book series · doi:10.4018/979-8-2600-2541-3.ch002
Margondai, A., Willox, S., Diaz, A. A., Rader, J., Hani, S., Ezcurra, V., & Mouloua, M. (2026) · Lecture notes in computer science · doi:10.1007/978-3-032-30044-7_7 · Cited by 1
Designing Collaborative Intelligence
Ravikumar, R. N., & Aarthi, S. (2026) · Advances in computational intelligence and robotics book series · doi:10.4018/979-8-3373-8217-3.ch002
Human-AI Interaction in Healthcare - A Manifesto for Improved Usability Evaluation
Oliveira, M., Cruz, C. F., & Matela, N. (2026) · ACM Interactive Health Conference · doi:10.1145/3786579.3804937
Human-Centered Design of LLM-Powered Educational Chatbots: A Study with Secondary Teachers
Reichert, H., Briceno, D., Tabarsi, B. T., & Barnes, T. M. (2026) · Lecture notes in computer science · doi:10.1007/978-3-032-31048-4_32
Wei, C., Su, E., Kalirai, M., Tan, A., Dushniku, P., Jones, B., Kim, Y., & Kuzminykh, A. (2026) · ACM Transactions on Computer-Human Interaction · doi:10.1145/3830401
Too Much, Too Little, Just Right? Towards Dimensions of Trust Calibration in Human–AI Interaction
Börsting, I., & Hesenius, M. (2026) · ACM Conference on Conversational User Interfaces (CUI) · doi:10.1145/3816046.3816283
Ouyang, L., Jahng, J., & Woo, S. (2026) · International Journal of Human-Computer Interaction · doi:10.1080/10447318.2026.2705163
Бойко, А. (2026) · Економіка та суспільство · doi:10.32782/2524-0072/2026-88-5
Wang, S., Yang, W., Wang, R., Ding, Y., & Xu, B. (2026) · Behavioral Sciences · doi:10.3390/bs16081356
Wang, E. J., Berthon, P. R., & John, J. (2026) · Journal of Services Marketing · doi:10.1108/jsm-12-2025-0888
Trust and Cybersecurity Behaviours: A Scoping Review
Melebari, S., Rehman, M. A. U., Bashir, A. K., & Al-Khalidi, M. (2026) · Computers, materials & continua/Computers, materials & continua (Print) · doi:10.32604/cmc.2026.085515
Laviola, F., Palese, B., Kim, S. T., & Cucari, N. (2026) · European Research on Management and Business Economics · doi:10.1016/j.iedeen.2026.100327
Redefining Collaboration: A Framework for Skill Development in K–12 Education
Courey, K. A., Liu, L., Ober, T., & Renfrow-Symon, E. (2026) · ETS Research Report Series · doi:10.64634/pdzqfj39
Mannahali, M., & Malik, A. R. (2026) · Journal of Language Teaching and Research · doi:10.17507/jltr.1705.32
Brassesco, V., Schinca, H., & Schapachnik, F. (2026) · SSRN Electronic Journal · doi:10.2139/ssrn.7404232
Exploring Cognitive Fatigue and Communication Latency in Human-AI Teams: A Preliminary Investigation
Brady, C., Madathil, K. C., & McNeese, N. J. (2026) · Proceedings of the Human Factors and Ergonomics Society Annual Meeting · doi:10.1177/10711813261485919
González-Oliveras, P., Engwall, O., & Majlesi, A. R. (2026) · Frontiers in Robotics and AI · doi:10.3389/frobt.2026.1901093
Exploring Trust Factors in Designing AI-Supported Performance Appraisal System
Harnindito, A., & Sawarni, A. (2026) · European Conference on Cognitive Ergonomics · doi:10.1145/3822301.3822342
Integrating AI Bots into Collaborative Requirements Decision-Making Through Temporal Graph Modeling
Mateos-Aparicio-Ruiz, I., Montealegre-Macias, P., López-Gómez, J. A., Déniz, Ó., & Bueno, G. (2026) · IEEE International Requirements Engineering Conference Workshops (REW) · doi:10.1109/rew72749.2026.00048
Development of a theoretical model for calibrating trust in AI to augment highways safety
Ivvala, P., Bayramova, A., Roberts, C. J., Edwards, D. J., & Rillie, I. (2026) · Smart and Sustainable Built Environment · doi:10.1108/sasbe-05-2026-0485
Elgohr, A. T., Rashad, M., El-Gendy, E. M., Shaaban, W., & Saafan, M. M. (2026) · International Journal of Computational Intelligence Systems · doi:10.1007/s44196-026-01599-z
Daniele, F., Montini, E., Conti, L., Gambardella, L. M., & Pedrazzoli, P. (2026) · IFIP advances in information and communication technology · doi:10.1007/978-3-032-38610-6_3
AI-in-the-human-loop: an operational model for mature human-AI collaboration
Casadei, R., Delnevo, G., Bassi, B., Ceccarini, C., & Mirri, S. (2026) · Journal of Ambient Intelligence and Humanized Computing · doi:10.1007/s12652-026-05135-x
Sulaima, M. F., Jyotsna, A., Herout, L., Gálvez, I. P., Krejcar, O., & Namazi, H. (2026) · Energy Nexus · doi:10.1016/j.nexus.2026.100870
When AI Fails: Hallucination Exposure, Verification, and Critical AI LiteracyPreprint
Nowacki, L., & Wrochna, A. E. (2026) · Research Square · doi:10.2139/ssrn.7583923
Aldalham, M. S. (2026) · Current Psychology · doi:10.1007/s12144-026-10137-1
Biswas, M. I., Talukder, M. S., & Opel, M. I. T. (2026) · Research Square · doi:10.21203/rs.3.rs-10395816/v1
Yang, J., Tang, J., & He, J. (2026) · iScience · doi:10.1016/j.isci.2026.117725
Geopolitical Sustainability of Powering Distributed Artificial Intelligence in Pakistan
Chaudary, B., & Pulli, P. (2026) · Science Technology & Public Policy · doi:10.11648/j.stpp.20261002.13
Li, L. (2026) · International Journal of Interactive Mobile Technologies (iJIM) · doi:10.3991/ijim.v20i20.63554
Mindful Generative AI Use: Development and Validation of a Langerian Mindfulness Scale
Zheng, Y., Lu, Y., Wu, T.-X., & Zeng, X.-L. (2026) · International Journal of Human-Computer Interaction · doi:10.1080/10447318.2026.2752743
Metadata
- Authors
- Okamura, K., & Yamada, S.
- Affiliations
- The Graduate University for Advanced Studies, SOKENDAI (JP)
- National Institute of Informatics (JP)
- Corresponding author
- Okamura, Kazuo
- Venue
- PLOS ONE
- Publisher
- Public Library of Science (PLoS)
- Published
- 2020-02-21
- Volume
- 15
- Issue
- 2
- Pages
- e0229132
- ISSN
- 1932-6203 (ISSN-L)
- PMC
- PMC7034851
- OpenAlex
- W2954555759
- Semantic Scholar
- acc10c9ebf9456d71474d79a61b2f0af3d3b29b2
- Cited by
- 239
- References
- 43
- Citations by year
- 2026: 65 · 2025: 56 · 2024: 46 · 2023: 31 · 2022: 18 · 2021: 16 · 2020: 7
- FWCI
- 19.67
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Licence
- Locations
- PLoS ONE (publishedVersion, cc-by)
- Europe PMC (PubMed Central) (publishedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion, cc-by-sa)
- The Japanese Society for Artificial Intelligence
- Funders
- Japan Society for the Promotion of Science (26118005)
- Topics
- Social Sciences › Human Factors and Ergonomics › Human-Automation Interaction and Safety
- Social Sciences › Psychology › Social Psychology › Social Robot Interaction and HRI
- Physical Sciences › Computer Science › Human-Computer Interaction › Usability and User Interface Design
- Keywords
- trust calibration, human-AI collaboration, cognitive cues, adaptive prompts, system transparency, trust in AI, drone inspection, human-AI decision-making
- MeSH terms
- Adult, Aged, Artificial Intelligence, Calibration, Female, Humans, Male, Man-Machine Systems, Middle Aged, Surveys and Questionnaires, Young Adult
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
A language model drew the claims from the paper on 2026-10-09, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-10-09 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
