

The DOI matches its Crossref record; 64 of the 69 references it cites were found in a registry or an index, and 1 are not checked yet.
When Do You Need Billions of Words of Pretraining Data?
Open accessAbstract
Yian Zhang, Alex Warstadt, Xiaocheng Li, Samuel R. Bowman. Proceedings of the 59th Annual Meeting of the Association for Computational Linguistics and the 11th International Joint Conference on Natural Language Processing (Volume 1: Long Papers). 2021.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The cited source doesn’t support the claim as written.
In the citing paper
“When restricted to developmentally plausible data volumes, language models no longer perform well on benchmarks for human-like syntactic and semantic behavior (van Schijndel et al., 2019;Zhang et al., 2021).”
From Findings of the BabyLM Challenge: Sample-Efficient Pretraining on Developmentally Plausible Corpora (2023) · cites this paper as Zhang et al., 2021
Checked by a reasoning model — may be wrong.
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Training long enough on a large-enough dataset has been shown to be key for the ability of language models to acquire syntactic, semantic, and other world knowledge (Zhang et al., 2021; Wei et al., 2021b; Razeghi et al., 2022).”
From Emergent Abilities of Large Language Models (2022) · cites this paper as Zhang et al., 2021
Experimental — accuracy not yet measured
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2018) · arXiv · doi:10.48550/arxiv.1810.04805 · Cited by 73,173
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2019) · Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers) · doi:10.18653/v1/n19-1423 · Cited by 54,325
Language Models are Few-Shot Learners
Brown, T. B., Mann, B., Ryder, N., Subbiah, M., Kaplan, J., Dhariwal, P., Neelakantan, A., Shyam, P., Sastry, G., Askell, A., et al. (2020) · arXiv · doi:10.48550/arxiv.2005.14165 · Cited by 23,372
RoBERTa: A Robustly Optimized BERT Pretraining Approach
Liu, Y., Ott, M., Goyal, N., Du, J., Joshi, M., Chen, D., Levy, O., Lewis, M., Zettlemoyer, L., & Stoyanov, V. (2019) · arXiv · doi:10.48550/arxiv.1907.11692 · Cited by 16,515
WordNet: a lexical database for English
Miller, G. A. (1995) · Communications of the ACM · doi:10.1145/219717.219748 · Cited by 14,015 · cited 1×
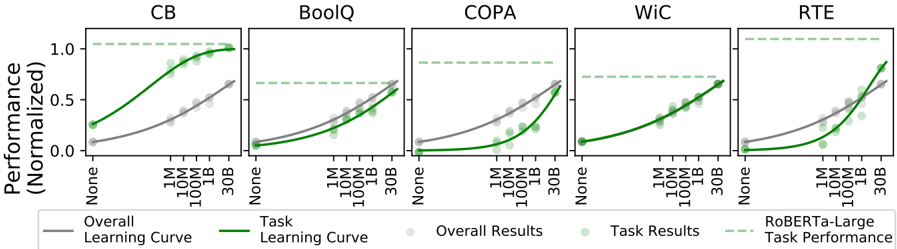
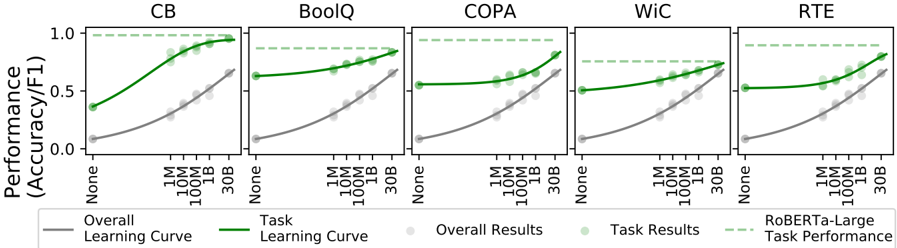
“Miller (1995); Schuler (2005), RTE from Dagan et al. (2006); Bar Haim et al. (2006); Giampiccolo et al. (2007); Bentivogli et al. (2009) Results We plot the results on SuperGLUE in Figure 6.”
BackgroundOn the Dangers of Stochastic Parrots: Can Language Models Be Too Big? 🦜
Bender, E. M., Gebru, T., McMillan-Major, A., & Shmitchell, S. (2021) · Proceedings of the 2021 ACM Conference on Fairness, Accountability, and Transparency · doi:10.1145/3442188.3445922 · Cited by 6,988
SQuAD: 100,000+ Questions for Machine Comprehension of Text
Rajpurkar, P., Zhang, J., Lopyrev, K., & Liang, P. (2016) · Proceedings of the 2016 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/d16-1264 · Cited by 6,208
GLUE: A Multi-Task Benchmark and Analysis Platform for Natural Language Understanding
Wang, A., Singh, A., Michael, J., Hill, F., Levy, O., & Bowman, S. (2018) · Proceedings of the 2018 EMNLP Workshop BlackboxNLP: Analyzing and Interpreting Neural Networks for NLP · doi:10.18653/v1/w18-5446 · Cited by 4,222
Self-citationEnergy and Policy Considerations for Deep Learning in NLP
Strubell, E., Ganesh, A., & McCallum, A. (2019) · Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics · doi:10.18653/v1/p19-1355 · Cited by 3,684
Geurts, B. (1999) · Language · doi:10.2307/417746 · Cited by 2,848
Research works printed but not linked: 7
- Roy Bar Haim, Ido Dagan, Bill Dolan, Lisa Ferro, Danilo Giampiccolo, Bernardo Magnini, and Idan Szpektor. 2006. The second PASCAL recognising textual entailment challenge. In Proceedings of the Second PASCAL Challenges Workshop on Recognis- ing Textual Entailment.
- Luisa Bentivogli, Ido Dagan, Hoa Trang Dang, Danilo Giampiccolo, and Bernardo Magnini. 2009. The fifth PASCAL recognizing textual entailment chal- lenge. In Textual Analysis Conference (TAC).
- Hady Elsahar, Pavlos Vougiouklis, Arslen Remaci, Christophe Gravier, Jonathon Hare, Frederique Laforest, and Elena Simperl. 2018. T-rex: A large scale alignment of natural language with knowledge base triples. In Proceedings of the Eleventh Interna- tional Conference on Language Resources and Eval- uation (LREC-2018).
- Charles Lovering, Rohan Jha, Tal Linzen, and El- lie Pavlick. 2021. Predicting inductive biases of fine-tuned models. In International Conference on Learning Representations.
- Colin Raffel, Noam Shazeer, Adam Roberts, Kather- ine Lee, Sharan Narang, Michael Matena, Yanqi Zhou, Wei Li, and Peter J. Liu. 2020. Exploring the limits of transfer learning with a unified text-to- text transformer. Journal of Machine Learning Re- search, 21(140):1-67.
- Melissa Roemmele, Cosmin Adrian Bejan, and An- drew S. Gordon. 2011. Choice of plausible alterna- tives: An evaluation of commonsense causal reason- ing. In 2011 AAAI Spring Symposium Series.
- Alex Wang and Kyunghyun Cho. 2019. BERT has a mouth, and it must speak: BERT as a Markov random field language model. In Proceedings of the Workshop on Methods for Optimizing and Eval- uating Neural Language Generation, pages 30-36, Minneapolis, Minnesota. Association for Computa- tional Linguistics. · DOI
Cited by
Sorted by citations
Items 101–108 of 108
Evaluating L2 Training Methods in Neural Language Models
Lee, J., & Shin, J. (2024) · 어학연구 · doi:10.30961/lr.2024.60.3.323
CAIRD: Context-Aware Implicit Relation Discovery in Multi-Event ChainsPreprint
Ali, S., & Fang, N. (2025) · Preprints.org · doi:10.20944/preprints202510.2118.v1
Scaling Behavior of Encoder Language Models in Low-Resource Settings
Visser, R., Grobler, T., & Dunaiski, M. (2025) · Communications in computer and information science · doi:10.1007/978-3-032-11733-5_22
Modeling Language and Vision at Human Scales
Fields, C. (2025) · doi:10.18122/td.2405.boisestate
Mou, B., & Lou, R. (2026) · ChemRxiv · doi:10.26434/chemrxiv.15000021/v1
Noor, F. R., Wijaya, R., & Romadhony, A. (2026) · Indonesian Journal on Computing (Indo-JC) · doi:10.21108/indojc.v10i2.9709
Chen, J., Chersoni, E., Marelli, M., & Huang, C. (2026) · Cognitive Science · doi:10.1111/cogs.70194
Exploring Hybrid Pre-training for Automatic Essay Scoring
Carpi, M. M., Silveira, I. C., Mauá, D. D., & Finger, M. (2026) · Simpósio Brasileiro de Tecnologia da Informação e da Linguagem Humana (STIL) · doi:10.5753/stil.2026.26589
Metadata
- Authors
- Zhang, Y., Warstadt, A., Li, X., & Bowman, S. R.
- Affiliations
- New York University (US)
- Venue
- Proceedings of the 59th Annual Meeting of the Association for Computational Linguistics and the 11th International Joint Conference on Natural Language Processing (Volume 1: Long Papers)
- Published
- 2021
- Pages
- 1112-1125
- OpenAlex
- W3176198948
- Cited by
- 85
- References
- 69
- Citations by year
- 2026: 3 · 2025: 7 · 2024: 9 · 2023: 40 · 2022: 16 · 2021: 10
- FWCI
- 8.66
- Type
- conference paper
- Language
- en
- Open access
- gold
- doi.org
- Licence
- cc-by
- Funders
- National Science Foundation (1850208)
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Topic Modeling
- Physical Sciences › Computer Science › Artificial Intelligence › Natural Language Processing Techniques
- Physical Sciences › Computer Science › Artificial Intelligence › Domain Adaptation and Few-Shot Learning
- Keywords
- pre-training, language models, training data requirements
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
