

Multimodal Compact Bilinear Pooling for Visual Question Answering and Visual Grounding
Open accessThe DOI matches its Crossref record; 61 of the 61 references it cites were found in a registry or an index.
Abstract
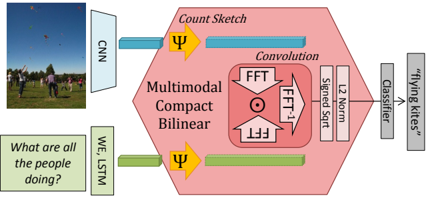
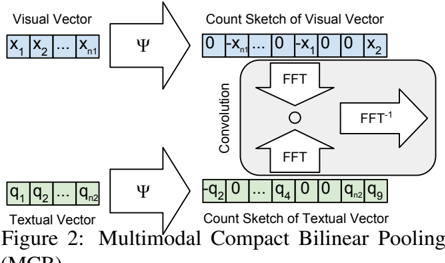
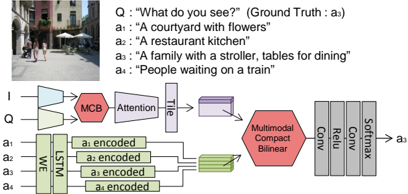
Modeling textual or visual information with vector representations trained from large language or visual datasets has been successfully explored in recent years.However, tasks such as visual question answering require combining these vector representations with each other.Approaches to multimodal pooling include element-wise product or sum, as well as concatenation of the visual and textual representations.We hypothesize that these methods are not as expressive as an outer product of the visual and textual vectors.As the outer product is typically infeasible due to its high dimensionality, we instead propose utilizing Multimodal Compact Bilinear pooling (MCB) to efficiently and expressively combine multimodal features.We extensively evaluate MCB on the visual question answering and grounding tasks.We consistently show the benefit of MCB over ablations without MCB.For visual question answering, we present an architecture which uses MCB twice, once for predicting attention over spatial features and again to combine the attended representation with the question representation.This model outperforms the state-of-the-art on the Visual7W dataset and the VQA challenge.
Overview
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Integrity signals
Registry
Cites
Statistics
Figures





Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The check wasn’t confident either way, so it gives no verdict — never disputed.
In the citing paper
“However, the PJ-X backbone MCB [16] (which is crucial for the answering performance) preceded the publication of the CLEVR dataset.”
From CLEVR-X: A Visual Reasoning Dataset for Natural Language Explanations (2022) · cites this paper as [16]
Experimental — accuracy not yet measured
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Deep Residual Learning for Image Recognition
He, K., Zhang, X., Ren, S., & Sun, J. (2016) · 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2016.90 · Cited by 235,474 · cited 1×
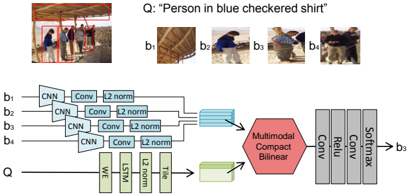
“We replace the concatenation of the visual representation and the encoded phrase in Grounder with MCB to combine both modalities.”
MethodVery Deep Convolutional Networks for Large-Scale Image Recognition
Simonyan, K., & Zisserman, A. (2014) · arXiv · doi:10.48550/arxiv.1409.1556 · Cited by 114,148
Adam: A Method for Stochastic Optimization
Kingma, D. P., & Ba, J. (2014) · arXiv · doi:10.48550/arxiv.1412.6980 · Cited by 98,946
ImageNet: A large-scale hierarchical image database
Deng, J., Dong, W., Socher, R., Li, L.-J., Li, K., & Fei-Fei, L. (2009) · 2009 IEEE Conference on Computer Vision and Pattern Recognition · doi:10.1109/cvpr.2009.5206848 · Cited by 65,333 · cited 2×
“, 2015) that is pretrained on ImageNet data (Deng et al., 2009).”
BackgroundMethodMicrosoft COCO: Common Objects in Context
Lin, T.-Y., Maire, M., Belongie, S., Hays, J., Perona, P., Ramanan, D., Dollár, P., & Zitnick, C. L. (2014) · Lecture Notes in Computer Science · doi:10.1007/978-3-319-10602-1_48 · Cited by 45,460
Glove: Global Vectors for Word Representation
Pennington, J., Socher, R., & Manning, C. (2014) · Proceedings of the 2014 Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.3115/v1/d14-1162 · Cited by 34,071 · cited 1×
“Also, for this model, we concatenated the learned word embedding with pretrained GloVe vectors (Pennington et al., 2014).”
MethodGirshick, R. (2015) · 2015 IEEE International Conference on Computer Vision (ICCV) · doi:10.1109/iccv.2015.169 · Cited by 28,105
Batch Normalization: Accelerating Deep Network Training by Reducing Internal Covariate Shift
Ioffe, S., & Szegedy, C. (2015) · arXiv · doi:10.48550/arxiv.1502.03167 · Cited by 27,818
Sequence to Sequence Learning with Neural Networks
Sutskever, I., Vinyals, O., & Le, Q. V. (2014) · arXiv · doi:10.48550/arxiv.1409.3215 · Cited by 17,766
Show, Attend and Tell: Neural Image Caption Generation with Visual Attention
Xu, K., Ba, J., Kiros, R., Cho, K., Courville, A., Salakhutdinov, R., Zemel, R., & Bengio, Y. (2015) · arXiv · doi:10.48550/arxiv.1502.03044 · Cited by 8,248
Selective Search for Object Recognition
Uijlings, J. R. R., van de Sande, K. E. A., Gevers, T., & Smeulders, A. W. M. (2013) · International Journal of Computer Vision · doi:10.1007/s11263-013-0620-5 · Cited by 5,980
Visual Genome: Connecting Language and Vision Using Crowdsourced Dense Image Annotations
Krishna, R., Zhu, Y., Groth, O., Johnson, J., Hata, K., Kravitz, J., Chen, S., Kalantidis, Y., Li, L.-J., Shamma, D. A., et al. (2017) · International Journal of Computer Vision · doi:10.1007/s11263-016-0981-7 · Cited by 5,107
Deep visual-semantic alignments for generating image descriptions
Karpathy, A., & Fei-Fei, L. (2015) · 2015 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2015.7298932 · Cited by 4,902
VQA: Visual Question Answering
Antol, S., Agrawal, A., Lu, J., Mitchell, M., Batra, D., Zitnick, C. L., & Parikh, D. (2015) · 2015 IEEE International Conference on Computer Vision (ICCV) · doi:10.1109/iccv.2015.279 · Cited by 4,487
DeCAF: A Deep Convolutional Activation Feature for Generic Visual Recognition
Donahue, J., Jia, Y., Vinyals, O., Hoffman, J., Zhang, N., Tzeng, E., & Darrell, T. (2013) · arXiv · doi:10.48550/arxiv.1310.1531 · Cited by 4,019 · cited 2×
“2015), and convolutional neural networks (CNNs) are often used to represent images (Donahue et al., 2013; He et al., 2015).”
BackgroundSelf-citationCanonical Correlation Analysis: An Overview with Application to Learning Methods
Hardoon, D. R., Szedmak, S., & Shawe-Taylor, J. (2004) · Neural Computation · doi:10.1162/0899766042321814 · Cited by 3,202 · cited 2×
“Some of such embeddings are based on Canonical Correlation Analysis (Hardoon et al., 2004) e.g. (Gong et al., 2014; Klein et al., 2015; Plummer et al., 2015), linear models with ranking loss (Frome et al., 2013; Karpathy and Fei-Fei, 2015; Socher et al., 2014; Weston et al., 2011) or non-linear deep learning models (K…”
MethodDeViSE: A Deep Visual-Semantic Embedding Model
Frome, A., Corrado, G. S., Shlens, J., Bengio, S., Dean, J., Ranzato, M., & Mikolov, T. (2013) · neural information processing systems · Cited by 3,134
(2011) · Cited by 2,752
Edge Boxes: Locating Object Proposals from Edges
Zitnick, C. L., & Dollár, P. (2014) · Lecture Notes in Computer Science · doi:10.1007/978-3-319-10602-1_26 · Cited by 2,656
Young, P., Lai, A., Hodosh, M., & Hockenmaier, J. (2014) · Transactions of the Association for Computational Linguistics · doi:10.1162/tacl_a_00166 · Cited by 2,426
Bilinear CNN Models for Fine-Grained Visual Recognition
Lin, T.-Y., RoyChowdhury, A., & Maji, S. (2015) · 2015 IEEE International Conference on Computer Vision (ICCV) · doi:10.1109/iccv.2015.170 · Cited by 2,135 · cited 3×
“Bilinear pooling models (Tenenbaum and Freeman, 2000) have recently been shown to be beneficial for finegrained classification for vision only tasks (Lin et al., 2015).”
BackgroundMethodInfluentialStacked Attention Networks for Image Question Answering
Yang, Z., He, X., Gao, J., Deng, L., & Smola, A. (2016) · 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2016.10 · Cited by 1,998 · cited 4×
“Stacked Attention Networks (Yang et al., 2015) and Spatial Memory Networks (Xu et al., 2015) use LSTMs or extract soft-attention on the image features, but ultimately use element-wise product or element-wise sums to merge modalities.”
BackgroundMethodInfluentialFlickr30k Entities: Collecting Region-to-Phrase Correspondences for Richer Image-to-Sentence Models
Plummer, B. A., Wang, L., Cervantes, C. M., Caicedo, J. C., Hockenmaier, J., & Lazebnik, S. (2015) · 2015 IEEE International Conference on Computer Vision (ICCV) · doi:10.1109/iccv.2015.303 · Cited by 1,444
Finding frequent items in data streams
Charikar, M., Chen, K., & Farach-Colton, M. (2004) · Theoretical Computer Science · doi:10.1016/s0304-3975(03)00400-6 · Cited by 1,278
ReferItGame: Referring to Objects in Photographs of Natural Scenes
Kazemzadeh, S., Ordonez, V., Matten, M., & Berg, T. (2014) · Proceedings of the 2014 Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.3115/v1/d14-1086 · Cited by 1,048
Deep Visual-Semantic Alignments for Generating Image Descriptions
Karpathy, A., & Fei-Fei, L. (2017) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2016.2598339 · Cited by 1,048
Ask Me Anything: Dynamic Memory Networks for Natural Language Processing
Kumar, A., Irsoy, O., Ondruska, P., Iyyer, M., Bradbury, J., Gulrajani, I., Zhong, V., Paulus, R., & Socher, R. (2015) · arXiv · doi:10.48550/arxiv.1506.07285 · Cited by 1,020 · cited 2×
“, 2016) pool image and question with element-wise multiplication and addition, attending to part of image and question with a Episodic Memory Module (Kumar et al., 2015).”
BackgroundAndreas, J., Rohrbach, M., Darrell, T., & Klein, D. (2016) · 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2016.12 · Cited by 908 · cited 3×
“We base our grounding approach on the fully-supervised version of GroundeR (Rohrbach et al., 2016).”
MethodSelf-citationVQA: Visual Question Answering
Agrawal, A., Lu, J., Antol, S., Mitchell, M., Zitnick, C. L., Batra, D., & Parikh, D. (2015) · arXiv (Cornell University) · doi:10.48550/arxiv.1505.00468 · Cited by 900 · cited 5×
“The Visual Question Answering (VQA) real-image dataset (Antol et al., 2015) consists of approximately 200,000 MSCOCO images (Lin et al.”
MethodInfluentialGao, Y., Beijbom, O., Zhang, N., & Darrell, T. (2016) · 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2016.41 · Cited by 871 · cited 5×
“In this paper, we adopt the idea from Gao et al. (2016) which shows how to efficiently compress bilinear pooling for a single modality.”
BackgroundMethodInfluentialSelf-citationSeparating Style and Content with Bilinear Models
Tenenbaum, J. B., & Freeman, W. T. (2000) · Neural Computation · doi:10.1162/089976600300015349 · Cited by 840
Visual7W: Grounded Question Answering in Images
Zhu, Y., Groth, O., Bernstein, M., & Fei-Fei, L. (2016) · 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2016.540 · Cited by 794 · cited 3×
“We use the splits from (Zhu et al., 2016) to train, validate, and test our models.”
MethodInfluentialMultimodal Neural Language Models
Kiros, R., Salakhutdinov, R., & Zemel, R. (2014) · International Conference on Machine Learning · Cited by 789
Grounded Compositional Semantics for Finding and Describing Images with Sentences
Socher, R., Karpathy, A., Le, Q. V., Manning, C. D., & Ng, A. Y. (2014) · Transactions of the Association for Computational Linguistics · doi:10.1162/tacl_a_00177 · Cited by 777 · cited 1×
“, 2015), linear models with ranking loss (Frome et al., 2013; Karpathy and Fei-Fei, 2015; Socher et al., 2014; Weston et al., 2011) or non-linear deep learning models (Kiros et al.”
BackgroundLearning Deep Structure-Preserving Image-Text Embeddings
Wang, L., Li, Y., & Lazebnik, S. (2016) · 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2016.541 · Cited by 760
Ask, Attend and Answer: Exploring Question-Guided Spatial Attention for Visual Question Answering
Xu, H., & Saenko, K. (2016) · Lecture Notes in Computer Science · doi:10.1007/978-3-319-46478-7_28 · Cited by 727 · cited 4×
“Stacked Attention Networks (Yang et al., 2015) and Spatial Memory Networks (Xu et al., 2015) use LSTMs or extract soft-attention on the image features, but ultimately use element-wise product or element-wise sums to merge modalities.”
BackgroundMethodInfluentialWsabie: Scaling up to large vocabulary image annotation
Weston, J., Samy Bengio, A., & Usunier, N. (2011) · Cited by 677
Finding Frequent Items in Data Streams
Charikar, M., Chen, K., & Farach-Colton, M. (2002) · Lecture Notes in Computer Science · doi:10.1007/3-540-45465-9_59 · Cited by 650
Deep Captioning with Multimodal Recurrent Neural Networks (m-RNN)
Mao, J., Xu, W., Yang, Y., Wang, J., Huang, Z., & Yuille, A. (2014) · arXiv (Cornell University) · doi:10.48550/arxiv.1412.6632 · Cited by 620 · cited 2×
“…et al., 2004) e.g. (Gong et al., 2014; Klein et al., 2015; Plummer et al., 2015), linear models with ranking loss (Frome et al., 2013; Karpathy and Fei-Fei, 2015; Socher et al., 2014; Weston et al., 2011) or non-linear deep learning models (Kiros et al., 2014; Mao et al., 2015; Ngiam et al., 2011).”
BackgroundDynamic Memory Networks for Visual and Textual Question Answering
Xiong, C., Merity, S., & Socher, R. (2016) · arXiv (Cornell University) · doi:10.48550/arxiv.1603.01417 · Cited by 603 · cited 2×
“Dynamic Memory Networks (DMN) (Xiong et al., 2016) pool image and question with element-wise multiplication and addition, attending to part of image and question with a Episodic Memory Module (Kumar et al.”
BackgroundVQA: Visual Question Answering: www.visualqa.org
Agrawal, A., Lu, J., Antol, S., Mitchell, M., Zitnick, C. L., Parikh, D., & Batra, D. (2017) · International Journal of Computer Vision · doi:10.1007/s11263-016-0966-6 · Cited by 570 · cited 5×
“The Visual Question Answering (VQA) real-image dataset (Antol et al., 2015) consists of approximately 200,000 MSCOCO images (Lin et al.”
MethodInfluentialNatural Language Object Retrieval
Hu, R., Xu, H., Rohrbach, M., Feng, J., Saenko, K., & Darrell, T. (2016) · 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2016.493 · Cited by 532 · cited 1×
“Similarly, Hu et al. (2016a) concatenate phrase embeddings with visual features at different spatial locations to obtain a segmentation.”
BackgroundSelf-citationLearning to Compose Neural Networks for Question Answering
Andreas, J., Rohrbach, M., Darrell, T., & Klein, D. (2016) · Proceedings of the 2016 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies · doi:10.18653/v1/n16-1181 · Cited by 446 · cited 3×
“We base our grounding approach on the fully-supervised version of GroundeR (Rohrbach et al., 2016).”
MethodSelf-citationSegmentation from Natural Language Expressions
Hu, R., Rohrbach, M., & Darrell, T. (2016) · Lecture Notes in Computer Science · doi:10.1007/978-3-319-46448-0_7 · Cited by 438
Self-citationGrounding of Textual Phrases in Images by Reconstruction
Rohrbach, A., Rohrbach, M., Hu, R., Darrell, T., & Schiele, B. (2016) · Max Planck Digital Library · Cited by 422
Self-citationThe segmented and annotated IAPR TC-12 benchmark
Escalante, H. J., Hernández, C. A., Gonzalez, J. A., López-López, A., Montes, M., Morales, E. F., Enrique Sucar, L., Villaseñor, L., & Grubinger, M. (2010) · Computer Vision and Image Understanding · doi:10.1016/j.cviu.2009.03.008 · Cited by 399
Ask Me Anything: Free-Form Visual Question Answering Based on Knowledge from External Sources
Wu, Q., Wang, P., Shen, C., Dick, A., & Van Den Hengel, A. (2016) · 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2016.500 · Cited by 355
Image Question Answering Using Convolutional Neural Network with Dynamic Parameter Prediction
Noh, H., Seo, P. H., & Han, B. (2016) · 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2016.11 · Cited by 345 · cited 1×
“The MCB is followed by an element-wise signed square-root and L2 normalization.”
MethodFast and scalable polynomial kernels via explicit feature maps
Pham, N., & Pagh, R. (2013) · Proceedings of the 19th ACM SIGKDD international conference on Knowledge discovery and data mining · doi:10.1145/2487575.2487591 · Cited by 306 · cited 1×
“In contrast to Rohrbach et al. (2016), we include a linear embedding of the visual representation and L 2 normalization of both input modalities, instead of batch normalization (Ioffe and Szegedy, 2015), which we found to be beneficial when using MCB for the grounding task.”
MethodThe IAPR Benchmark : A New Evaluation Resource for Visual Information Systems
Grubinger, M. (2006) · RWTH Publications (RWTH Aachen) · Cited by 285
Improving Image-Sentence Embeddings Using Large Weakly Annotated Photo Collections
Gong, Y., Wang, L., Hodosh, M., Hockenmaier, J., & Lazebnik, S. (2014) · Lecture Notes in Computer Science · doi:10.1007/978-3-319-10593-2_35 · Cited by 281
Simple Baseline for Visual Question Answering
Zhou, B., Tian, Y., Sukhbaatar, S., Szlam, A. D., & Fergus, R. (2015) · arXiv (Cornell University) · doi:10.48550/arxiv.1512.02167 · Cited by 254 · cited 3×
“Simpler models such as iBOWIMG baseline (Zhou et al., 2015) use concatenation and fully connected layers to combine the image and question modalities.”
MethodInfluentialVisual Genome: Connecting Language and Vision Using Crowdsourced Dense Image AnnotationsPreprint
Krishna, R., Zhu, Y., Groth, O., et al. (2016) · arXiv (Cornell University) · doi:10.48550/arxiv.1602.07332 · Cited by 248
The New Data and New Challenges in Multimedia Research.Preprint
Thomée, B., Shamma, D. A., Friedland, G. H., Elizalde, B., Ni, K. S., Poland, D., Borth, D., & Li, L.-J. (2015) · arXiv (Cornell University) · Cited by 247
Stacked Attention Networks for Image Question AnsweringPreprint
Yang, Z., He, X., Gao, J., et al. (2015) · arXiv (Cornell University) · doi:10.48550/arxiv.1511.02274 · Cited by 192 · cited 4×
“Stacked Attention Networks (Yang et al., 2015) and Spatial Memory Networks (Xu et al., 2015) use LSTMs or extract soft-attention on the image features, but ultimately use element-wise product or element-wise sums to merge modalities.”
BackgroundMethodInfluentialA Focused Dynamic Attention Model for Visual Question Answering
Ilievski, I., Yan, S., & Feng, J. (2016) · arXiv (Cornell University) · doi:10.48550/arxiv.1604.01485 · Cited by 112
Ask Your Neurons: A Deep Learning Approach to Visual Question Answering
Malinowski, M., Rohrbach, M., & Fritz, M. (2017) · International Journal of Computer Vision · doi:10.1007/s11263-017-1038-2 · Cited by 105
Self-citationFisher Vectors Derived from Hybrid Gaussian-Laplacian Mixture Models for Image Annotation
Klein, B., Lev, G., Sadeh, G., & Wolf, L. (2014) · arXiv (Cornell University) · doi:10.48550/arxiv.1411.7399 · Cited by 69 · cited 2×
“Some of such embeddings are based on Canonical Correlation Analysis (Hardoon et al., 2004) e.g. (Gong et al., 2014; Klein et al., 2015; Plummer et al., 2015), linear models with ranking loss (Frome et al., 2013; Karpathy and Fei-Fei, 2015; Socher et al., 2014; Weston et al., 2011) or non-linear…”
BackgroundCompact Bilinear PoolingPreprint
Gao, Y., Beijbom, O., Zhang, N., et al. (2015) · arXiv (Cornell University) · doi:10.48550/arxiv.1511.06062 · Cited by 46 · cited 5×
“In this paper, we adopt the idea from Gao et al. (2016) which shows how to efficiently compress bilinear pooling for a single modality.”
BackgroundMethodInfluentialFlickr30k Entities: Collecting Region-to-Phrase Correspondences for Richer Image-to-Sentence Models
Plummer, B. A., Wang, L., Cervantes, C. M., Caicedo, J. C., Hockenmaier, J., & Lazebnik, S. (2015) · arXiv (Cornell University) · doi:10.48550/arxiv.1505.04870 · Cited by 46 · cited 1×
“…et al., 2004) e.g. (Gong et al., 2014; Klein et al., 2015; Plummer et al., 2015), linear models with ranking loss (Frome et al., 2013; Karpathy and Fei-Fei, 2015; Socher et al., 2014; Weston et al., 2011) or non-linear deep learning models (Kiros et al., 2014; Mao et al., 2015; Ngiam et al., 2011).”
BackgroundHierarchical Co-Attention for Visual Question AnsweringPreprint
Lu, J., Yang, J., Batra, D., & Parikh, D. (2016) · arXiv (Cornell University) · Cited by 24
Research works printed but not linked: 3
- Ross Girshick. 2015. Fast R-CNN. In Proceedings of the IEEE International Conference on Computer Vision (ICCV).
- Ryan Kiros, Ruslan Salakhutdinov, and Rich Zemel. 2014. Multimodal neural language mod- els. In Proceedings of the International Conference on Machine Learning (ICML), pages 595-603.
- Ryan Kiros, Yukun Zhu, Ruslan Salakhutdinov, Richard S Zemel, Antonio Torralba, Raquel Urtasun, and Sanja Fidler. 2015. Skip-thought vectors. In Advances in Neural Information Processing Systems (NIPS).
Cited by
Arrieta, A. B., Díaz-Rodríguez, N., Del Ser, J., Bennetot, A., Tabik, S., Barbado, A., García, S., Gil-López, S., Molina, D., Benjamins, R., et al. (2019) · arXiv · doi:10.48550/arxiv.1910.10045 · Cited by 11,321
Barredo Arrieta, A., Díaz-Rodríguez, N., Del Ser, J., Bennetot, A., Tabik, S., Barbado, A., Garcia, S., Gil-Lopez, S., Molina, D., Benjamins, R., et al. (2020) · Information Fusion · doi:10.1016/j.inffus.2019.12.012 · Cited by 10,423
Bottom-Up and Top-Down Attention for Image Captioning and Visual Question Answering
Anderson, P., He, X., Buehler, C., Teney, D., Johnson, M., Gould, S., & Zhang, L. (2018) · 2018 IEEE/CVF Conference on Computer Vision and Pattern Recognition · doi:10.1109/cvpr.2018.00636 · Cited by 4,948
“Typically, these models can be characterized as top-down approaches, with context provided by a representation of a partially-completed caption in the case of image captioning [33, 27, 47, 45], or a representation of the question in the case of VQA [11, 28, 44, 46, 49].”
BackgroundMethodMultimodal Machine Learning: A Survey and Taxonomy
Baltrusaitis, T., Ahuja, C., & Morency, L.-P. (2019) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2018.2798607 · Cited by 5,018
Explaining Explanations: An Overview of Interpretability of Machine Learning
Gilpin, L. H., Bau, D., Yuan, B. Z., Bajwa, A., Specter, M., & Kagal, L. (2018) · 2018 IEEE 5th International Conference on Data Science and Advanced Analytics (DSAA) · doi:10.1109/dsaa.2018.00018 · Cited by 2,507
“This system builds upon the winner of the 2016 VQA challenge [73], with several simplification and additions.”
Background
Metadata
- Authors
- Fukui, A., Park, D. H., Yang, D., Rohrbach, A., Darrell, T., & Rohrbach, M.
- Affiliations
- Sony (Japan) (JP)
- University of California, Berkeley (US)
- Max Planck Institute for Informatics (DE)
- Venue
- Proceedings of the 2016 Conference on Empirical Methods in Natural Language Processing
- Published
- 2016
- Pages
- 457-468
- OpenAlex
- W2963383024
- Cited by
- 1,582
- References
- 60
- Citations by year
- 2026: 42 · 2025: 105 · 2024: 126 · 2023: 165 · 2022: 189 · 2021: 222 · 2020: 225 · 2019: 201 · 2018: 179 · 2017: 105 · 2016: 20
- FWCI
- 58.39
- Type
- conference paper
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- cc-by
- Locations
- Conference on Empirical Methods in Natural Language Processing (EMNLP) (publishedVersion, cc-by)
- arXiv (Cornell University) (submittedVersion)
- Max Planck Digital Library (submittedVersion)
- MPG.PuRe (Max Planck Society) (submittedVersion)
- arXiv (Cornell University)
- Funders
- National Science Foundation (1427425, 1212798, N000141110688)
- Defense Advanced Research Projects Agency
- Multidisciplinary University Research Initiative (N000141110688)
- Air Force Research Laboratory
- Topics
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Multimodal Machine Learning Applications
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Advanced Image and Video Retrieval Techniques
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Visual Attention and Saliency Detection
- Keywords
- visual question answering, visual grounding, multimodal fusion, outer product, attention mechanism, large language models
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
