

Quantity doesn’t buy quality syntax with neural language models
Open accessThe DOI matches its Crossref record; 32 of the 32 references it cites were found in a registry or an index.
Abstract
Marten van Schijndel, Aaron Mueller, Tal Linzen. Proceedings of the 2019 Conference on Empirical Methods in Natural Language Processing and the 9th International Joint Conference on Natural Language Processing (EMNLP-IJCNLP). 2019.
Overview
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Integrity signals
Registry
Cites
Statistics
Figures
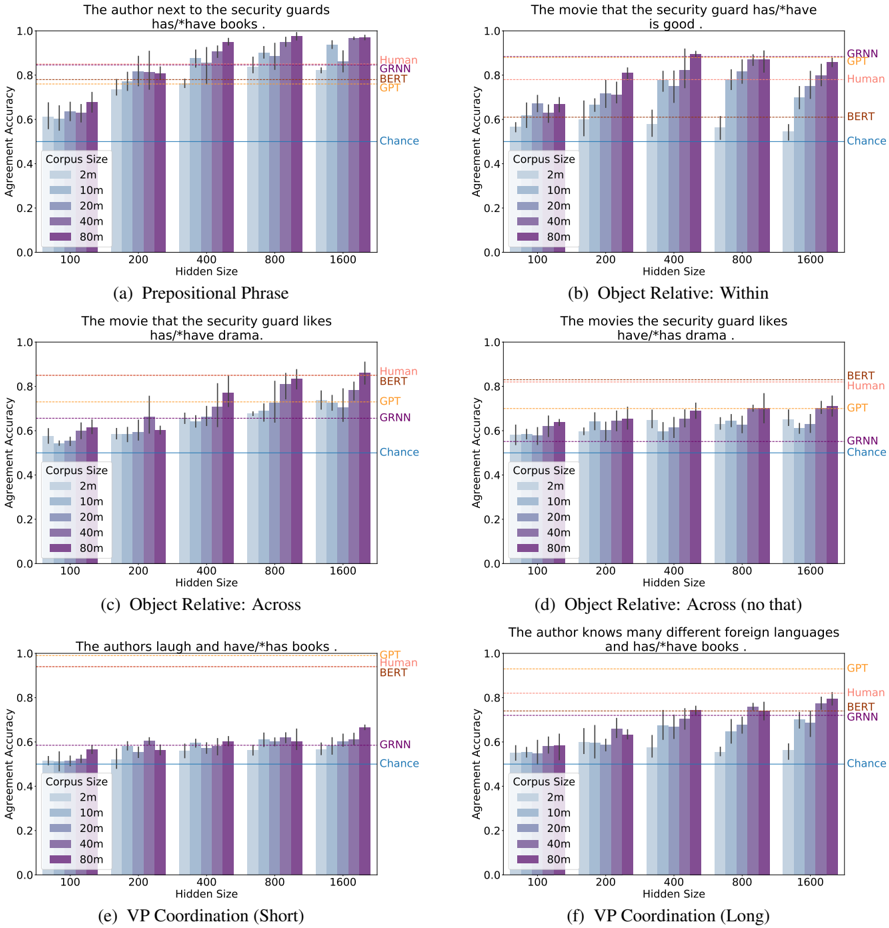
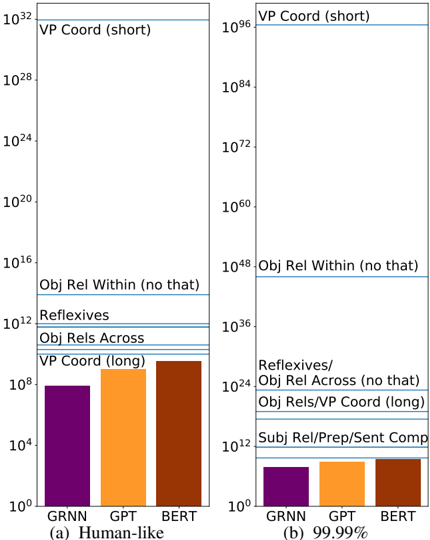
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“When restricted to developmentally plausible data volumes, language models no longer perform well on benchmarks for human-like syntactic and semantic behavior (van Schijndel et al., 2019;Zhang et al., 2021).”
From Findings of the BabyLM Challenge: Sample-Efficient Pretraining on Developmentally Plausible Corpora (2023) · cites this paper as van Schijndel et al., 2019
Experimental — accuracy not yet measuredIn the citing paper
“There is an emerging consensus that the creation of such training sets is feasible.”
From Natural syntax, artificial intelligence and language acquisition (2023) · cites this paper as [26]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Vaswani, A., Shazeer, N., Parmar, N., Uszkoreit, J., Jones, L., Gomez, A. N., Kaiser, L., & Polosukhin, I. (2017) · arXiv · doi:10.48550/arxiv.1706.03762 · Cited by 120,404 · cited 2×
“Comparison with Transformers: Finally, we report results from two publicly available LMs based on non-recurrent self-attention (Transform-ers; Vaswani et al., 2017): GPT (Radford et al., 2018) and BERT (Devlin et al., 2019).”
Hochreiter, S., & Schmidhuber, J. (1997) · Neural Computation · doi:10.1162/neco.1997.9.8.1735 · Cited by 102,318 · cited 1×
“We train 125 RNN LMs with long short-term memory (LSTM, Hochreiter and Schmidhuber, 1997) units, systematically varying the size of the training corpus and the dimensionality of the models’ hidden layer, and track the relationship between these parameters and the performance of the models on…”
Exploiting Generative AI to Scale up Intelligent Tutoring Systems
Jakubův, J., Chvalovský, K., Goertzel, Z., Kaliszyk, C., Olšák, M., Piotrowski, B., Schulz, S., Suda, M., & Urban, J. (2023) · DROPS (Schloss Dagstuhl – Leibniz Center for Informatics) · doi:10.4230/lipics.itp.2023.19 · Cited by 76,658
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2018) · arXiv · doi:10.48550/arxiv.1810.04805 · Cited by 73,173 · cited 3×
“Comparison with Transformers: Finally, we report results from two publicly available LMs based on non-recurrent self-attention (Transform-ers; Vaswani et al., 2017): GPT (Radford et al., 2018) and BERT (Devlin et al., 2019).”
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2019) · Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers) · doi:10.18653/v1/n19-1423 · Cited by 54,325 · cited 3×
“Comparison with Transformers: Finally, we report results from two publicly available LMs based on non-recurrent self-attention (Transform-ers; Vaswani et al., 2017): GPT (Radford et al., 2018) and BERT (Devlin et al., 2019).”
Glove: Global Vectors for Word Representation
Pennington, J., Socher, R., & Manning, C. (2014) · Proceedings of the 2014 Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.3115/v1/d14-1162 · Cited by 34,071 · cited 2×
“The vocabulary consisted of an intersection of the 400k word GloVe vocabulary (Pennington et al., 2014) with the 50k words used by GRNN (see below); the resulting vocabulary had 28,438 words.”
Greff, K., Srivastava, R. K., Koutnik, J., Steunebrink, B. R., & Schmidhuber, J. (2017) · IEEE Transactions on Neural Networks and Learning Systems · doi:10.1109/tnnls.2016.2582924 · Cited by 6,955 · cited 2×
“The limited effect of network size is consistent with previous findings on sequence labeling tasks (Reimers and Gurevych, 2017; Greff et al., 2017).”
Recurrent neural network based language model
Mikolov, T., Karafiát, M., Burget, L., Černocký, J., & Khudanpur, S. (2010) · Interspeech 2010 · doi:10.21437/interspeech.2010-343 · Cited by 5,390 · cited 2×
“Recurrent neural network language models (LMs) can learn to predict upcoming words with remarkably low perplexity (Mikolov et al., 2010; Jozefowicz et al., 2016; Radford et al., 2019).”
Bayesian t tests for accepting and rejecting the null hypothesis
Rouder, J. N., Speckman, P. L., Sun, D., Morey, R. D., & Iverson, G. (2009) · Psychonomic Bulletin & Review · doi:10.3758/pbr.16.2.225 · Cited by 3,688 · cited 1×
“We performed statistical tests of our hypotheses using Bayes factors, which quantify the support the data provide for a more complex model compared to a simpler one (Rouder et al., 2009).”
Transformer-XL: Attentive language models beyond a fixed-length context
Dai, Z., Yang, Z., Yang, Y., Carbonell, J., Le, Q., & Salakhutdinov, R. (2019) · Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics · doi:10.18653/v1/p19-1285 · Cited by 3,169 · cited 12×
“RNN LMs have been shown to favor the grammatical variant in the vast majority of cases sampled at random from a corpus (Linzen et al., 2016), but their accuracy decreases in the presence of distracting nouns intervening between the head of the subject and the verb, especially when those nouns are in relative clauses (…”
Influential
Research works printed but not linked: 3
- Kathryn Bock and Carol A. Miller. 1991. Broken agreement. Cognitive Psychology, 23(1):45-93.
- Guyon, U. V. Luxburg, S. Bengio, H. Wallach, R. Fergus, S. Vishwanathan, and R. Gar- nett, editors, Advances in Neural Information Pro- cessing Systems 30, pages 5998-6008.
- Ethan Wilcox, Peng Qian, Richard Futrell, Miguel Ballesteros, and Roger Levy. 2019. Structural su- pervision improves learning of non-local grammat- ical dependencies. In Proceedings of the 2019 An- nual Conference of the North American Chapter of the Association for Computational Linguistics. As- sociation for Computational Linguistics.
Cited by
A primer in BERTology: What we know about how BERT works
Rogers, A., Kovaleva, O., & Rumshisky, A. (2020) · Transactions of the Association for Computational Linguistics · doi:10.1162/tacl_a_00349 · Cited by 1,552
Pre-trained models: Past, present and future
Han, X., Zhang, Z., Ding, N., Gu, Y., Liu, X., Huo, Y., Qiu, J., Yao, Y., Zhang, A., Zhang, L., et al. (2021) · AI Open · doi:10.1016/j.aiopen.2021.08.002 · Cited by 994
Dissociating language and thought in large language models
Mahowald, K., Ivanova, A. A., Blank, I. A., Kanwisher, N., Tenenbaum, J. B., & Fedorenko, E. (2024) · Trends in Cognitive Sciences · doi:10.1016/j.tics.2024.01.011 · Cited by 345
“GPT-3 davinci-002 (Brown et al., 2020) The meaning of life is a mystery to us all, and a question that will never be answered.”
Bisk, Y., Holtzman, A., Thomason, J., Andreas, J., Bengio, Y., Chai, J., Lapata, M., Lazaridou, A., May, J., Nisnevich, A., et al. (2020) · Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2020.emnlp-main.703 · Cited by 274
Syntactic Structure from Deep Learning
Linzen, T., & Baroni, M. (2021) · Annual Review of Linguistics · doi:10.1146/annurev-linguistics-032020-051035 · Cited by 202
“This divergence limits the cognitive conclusions that can be drawn from testing off-the-shelf NLP systems and implies that linguists need to train their ownDNNs to assess how the volume of training data affects DNNs’ syntactic knowledge (van Schijndel et al. 2019).”
BackgroundSelf-citationCOGS: A Compositional Generalization Challenge Based on Semantic Interpretation
Kim, N., & Linzen, T. (2020) · Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2020.emnlp-main.731 · Cited by 153
Self-citationHow Can We Accelerate Progress Towards Human-like Linguistic Generalization?
Linzen, T. (2020) · Proceedings of the 58th Annual Meeting of the Association for Computational Linguistics · doi:10.18653/v1/2020.acl-main.465 · Cited by 148
Self-citationA Systematic Assessment of Syntactic Generalization in Neural Language Models
Hu, J., Gauthier, J., Qian, P., Wilcox, E., & Levy, R. (2020) · Proceedings of the 58th Annual Meeting of the Association for Computational Linguistics · doi:10.18653/v1/2020.acl-main.158 · Cited by 134
What Artificial Neural Networks Can Tell Us about Human Language Acquisition
Warstadt, A., & Bowman, S. R. (2022) · Algebraic Structures in Natural Language · doi:10.1201/9781003205388-2 · Cited by 111
Language Model Behavior: A Comprehensive Survey
Chang, T. A., & Bergen, B. K. (2024) · Computational Linguistics · doi:10.1162/coli_a_00492 · Cited by 105
Warstadt, A., Zhang, Y., Li, X., Liu, H., & Bowman, S. R. (2020) · Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2020.emnlp-main.16 · Cited by 98
Fixed Encoder Self-Attention Patterns in Transformer-Based Machine Translation
Raganato, A., Scherrer, Y., & Tiedemann, J. (2020) · Findings of the Association for Computational Linguistics: EMNLP 2020 · doi:10.18653/v1/2020.findings-emnlp.49 · Cited by 86
When Do You Need Billions of Words of Pretraining Data?
Zhang, Y., Warstadt, A., Li, X., & Bowman, S. R. (2021) · Proceedings of the 59th Annual Meeting of the Association for Computational Linguistics and the 11th International Joint Conference on Natural Language Processing (Volume 1: Long Papers) · doi:10.18653/v1/2021.acl-long.90 · Cited by 85
“…of rapid improvements in linguistic knowledge up to about 10M words of pretraining data, after which improvements slow down for most phenomena. van Schijndel et al. (2019) find large improvements in knowledge of subject-verb agreement and reflexive binding up to 10M words, and few improvements…”
BackgroundSinha, K., Parthasarathi, P., Pineau, J., & Williams, A. (2021) · Proceedings of the 59th Annual Meeting of the Association for Computational Linguistics and the 11th International Joint Conference on Natural Language Processing (Volume 1: Long Papers) · doi:10.18653/v1/2021.acl-long.569 · Cited by 71
“This is especially true for syntactic phenomena (Marvin and Linzen, 2018; Hu et al., 2020b; Gauthier et al., 2020; McCoy et al., 2020; Warstadt et al., 2020), where transformers are, for some phenomena and settings, worse than RNNs (van Schijndel et al., 2019).”
BackgroundFindings of the BabyLM Challenge: Sample-Efficient Pretraining on Developmentally Plausible Corpora
Warstadt, A., Mueller, A., Choshen, L., Wilcox, E., Zhuang, C., Ciro, J., Mosquera, R., Paranjabe, B., Williams, A., Linzen, T., et al. (2023) · Proceedings of the BabyLM Challenge at the 27th Conference on Computational Natural Language Learning · doi:10.18653/v1/2023.conll-babylm.1 · Cited by 74
“When restricted to developmentally plausible data volumes, language models no longer perform well on benchmarks for human-like syntactic and semantic behavior (van Schijndel et al., 2019; Zhang et al., 2021).”
Self-citationAnalysis and Evaluation of Language Models for Word Sense Disambiguation
Loureiro, D., Rezaee, K., Pilehvar, M. T., & Camacho-Collados, J. (2021) · Computational Linguistics · doi:10.1162/coli_a_00405 · Cited by 140
Hosseini, E. A., Schrimpf, M., Zhang, Y., Bowman, S., Zaslavsky, N., & Fedorenko, E. (2024) · Neurobiology of Language · doi:10.1162/nol_a_00137 · Cited by 63
“…is that their training data size (often, billions of words) far surpasses the amount of language exposure in humans during their learning phase (Chang & Bergen, 2021; Dupoux, 2018; Frank, 2023; Linzen & Leonard, 2018; van Schijndel et al., 2019; see Warstadt & Bowman, 2022, for discussion).”
BackgroundSyntaxGym: An Online Platform for Targeted Evaluation of Language Models
Gauthier, J., Hu, J., Wilcox, E., Qian, P., & Levy, R. (2020) · Proceedings of the 58th Annual Meeting of the Association for Computational Linguistics: System Demonstrations · doi:10.18653/v1/2020.acl-demos.10 · Cited by 61
“Recent empirical results suggest that models with similar perplexity measures can still exhibit substantial variance in syntactic knowledge (Hu et al., 2020; van Schijndel et al., 2019), according to evaluation paradigms described in the next section.”
BackgroundResultBERT is to NLP what AlexNet is to CV: Can Pre-Trained Language Models Identify Analogies?
Ushio, A., Espinosa-Anke, L., Schockaert, S., & Camacho-Collados, J. (2021) · doi:10.18653/v1/2021.acl-long.280 · Cited by 116
“The main aspects that have been studied in recent years are syntax (Goldberg, 2019; Saphra and Lopez, 2019; Hewitt and Manning, 2019; van Schijndel et al., 2019; Jawahar et al., 2019; Tenney et al., 2019b) and semantics (Ettinger, 2019; Tenney et al., 2019a).”
BackgroundCausal Analysis of Syntactic Agreement Mechanisms in Neural Language Models
Finlayson, M., Mueller, A., Gehrmann, S., Shieber, S., Linzen, T., & Belinkov, Y. (2021) · Proceedings of the 59th Annual Meeting of the Association for Computational Linguistics and the 11th International Joint Conference on Natural Language Processing (Volume 1: Long Papers) · doi:10.18653/v1/2021.acl-long.144 · Cited by 40
“Because larger models tend to exhibit correct subject-verb agreement more often than smaller ones (Hu et al., 2020; van Schijndel et al., 2019), we hypothesize that larger models will generally have larger TEs for the same structure (i.e., we predict that higher accuracy is indicative of larger…”
BackgroundSelf-citationCross-Linguistic Syntactic Evaluation of Word Prediction Models
Mueller, A., Nicolai, G., Petrou-Zeniou, P., Talmina, N., & Linzen, T. (2020) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2020.acl-main.490 · Cited by 101
Self-citationProbing for Referential Information in Language Models
Sorodoc, I.-T., Gulordava, K., & Boleda, G. (2020) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2020.acl-main.384 · Cited by 44
“On the other hand, van Schijndel et al. (2019) show that big Transformer model representations perform on par or even poorer than smaller LSTMs on tasks such as number agreement or coordination, and that, like LSTMs, they have the problem that agreement accuracy decreases as the subject becomes…”
BackgroundResultHow much pretraining data do language models need to learn syntax?
Pérez-Mayos, L., Ballesteros, M., & Wanner, L. (2021) · Proceedings of the 2021 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/2021.emnlp-main.118 · Cited by 26
“Several studies investigate the relation between pre-training data size and linguistic knowledge in language models. van Schijndel et al. (2019); Hu et al. (2020); Micheli et al. (2020) find out that, given a relatively large data size (e.g., 10M words), models with less pretraining perform…”
BackgroundInvestigating representations of verb bias in neural language models
Hawkins, R., Yamakoshi, T., Griffiths, T. L., & Goldberg, A. E. (2020) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2020.emnlp-main.376 · Cited by 53
Huber, E., Sauppe, S., Isasi-Isasmendi, A., Bornkessel‐Schlesewsky, I., Merlo, P., & Bickel, B. (2023) · Neurobiology of Language · doi:10.1162/nol_a_00121 · Cited by 34
“Building such mechanisms into models might improve their inductive biases (van Schijndel et al., 2019; E. Wilcox et al., 2021) and reduce the amount of data needed for a model to acquire linguistic structures.”
BackgroundDiscourse structure interacts with reference but not syntax in neural language models
Davis, F., & van Schijndel, M. (2020) · Conference on Computational Natural Language Learning · doi:10.18653/v1/2020.conll-1.32 · Cited by 23
(2022) · doi:10.18653/v1/2022.findings-acl.106 · Cited by 17
Recurrent Neural Network Language Models Always Learn English-Like Relative Clause Attachment
Davis, F., & van Schijndel, M. (2020) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2020.acl-main.179 · Cited by 26
When Do You Need Billions of Words of Pretraining Data?Preprint
Zhang, Y., Warstadt, A., Li, H.-S., & Bowman, S. R. (2020) · arXiv (Cornell University) · doi:10.48550/arxiv.2011.04946 · Cited by 16
“…of rapid improvements in linguistic knowledge up to about 10M words of pretraining data, after which improvements slow down for most phenomena. van Schijndel et al. (2019) find large improvements in knowledge of subject-verb agreement and reflexive binding up to 10M words, and few improvements…”
BackgroundDistilling Relation Embeddings from Pretrained Language Models
Ushio, A., Camacho-Collados, J., & Schockaert, S. (2021) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2021.emnlp-main.712 · Cited by 41
“…capabilities of such models, covering the extent to which they capture syntax (Goldberg, 2019; Saphra and Lopez, 2019; Hewitt and Manning, 2019; van Schijndel et al., 2019; Jawahar et al., 2019; Tenney et al., 2019), lexical semantics (Ethayarajh, 2019; Bommasani et al., 2020; Vulic et al., 2020),…”
BackgroundNoji, H., & Takamura, H. (2020) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2020.acl-main.309 · Cited by 20
Data-driven Cross-lingual Syntax: An Agreement Study with Massively Multilingual Models
de Varda, A. G., & Marelli, M. (2023) · Computational Linguistics · doi:10.1162/coli_a_00472 · Cited by 28
Beguš, G. (2021) · Computer Speech & Language · doi:10.1016/j.csl.2021.101244 · Cited by 15
“This stands in contrast to some recent studies of neural network models on the syntactic level that require very large training datasets and do not improve substantially with more data (van Schijndel et al., 2019).”
ResultUniversal linguistic inductive biases via meta-learning
McCoy, R. T., Grant, E., Smolensky, P., Griffiths, T. L., & Linzen, T. (2020) · arXiv · doi:10.48550/arxiv.2006.16324 · Cited by 13
Self-citationThe Grammar-Learning Trajectories of Neural Language Models
Choshen, L., Hacohen, G., Weinshall, D., & Abend, O. (2022) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2022.acl-long.568 · Cited by 61
Shapley Idioms: Analysing BERT Sentence Embeddings for General Idiom Token Identification
Nedumpozhimana, V., Klubička, F., & Kelleher, J. D. (2022) · Frontiers in Artificial Intelligence · doi:10.3389/frai.2022.813967 · Cited by 16
“…on syntactic structures of various kinds, such as parts of speech, syntactic chunks, and roles (Liu et al., 2019) and subject-predicate agreement (van Schijndel et al., 2019); and semantic knowledge, such as semantic roles (Ettinger, 2020), and entity types and relations (Tenney et al., 2019);…”
BackgroundThis is a BERT. Now there are several of them. Can they generalize to novel words?
Haley, C. (2020) · BlackboxNLP Workshop on Analyzing and Interpreting Neural Networks for NLP (BlackboxNLP) · doi:10.18653/v1/2020.blackboxnlp-1.31 · Cited by 26
“We probe this indirectly, though a number agreement task following the setup in van Schijndel et al. (2019). As in that study, We use the challenge set from Mar-”
BackgroundMethodInfluentialMueller, A., & Linzen, T. (2023) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2023.acl-long.629 · Cited by 45
Self-citationTransformers Generalize Linearly
Petty, J., & Frank, R. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2109.12036 · Cited by 10
“…much about the inductive bias in the Transformer: they are trained on vast datasets, leaving open the question of the impact of inductive bias as opposed to training data (Warstadt and Bowman (2020), but see Van Schijndel et al. (2019) for arguments that even massive data may not be sufficient).”
BackgroundTo Point or Not to Point: Understanding How Abstractive Summarizers Paraphrase Text
Wilber, M., Timkey, W., & van Schijndel, M. (2021) · Findings of the Association for Computational Linguistics: ACL (Findings of ACL) · doi:10.18653/v1/2021.findings-acl.298 · Cited by 10
Quantifying Structural and Non‐structural Expectations in Relative Clause Processing
Chen, Z., & Hale, J. (2021) · Cognitive Science · doi:10.1111/cogs.12927 · Cited by 8
On the Role of Corpus Ordering in Language Modeling
Agrawal, A., Singh, S., Schneider, L. R., & Samuels, M. (2021) · Workshop on Simple and Efficient Natural Language Processing (SustaiNLP) · doi:10.18653/v1/2021.sustainlp-1.15 · Cited by 10
“…many studies explore the relationship between the volume of training data and consequent model performance (Banko and Brill, 2001; Sun et al., 2017; van Schijndel et al., 2019; Hu et al., 2020; Raffel et al., 2020; Brown et al., 2020; Zhang et al., 2021), generally concluding that rapid…”
BackgroundPredicting Age of Acquisition in Early Word Learning Using Recurrent Neural Networks.
Portelance, E., Degen, J., & Frank, M. C. (2020) · eScholarship (California Digital Library) · Cited by 12
Natural syntax, artificial intelligence and language acquisition
O’Grady, W., & Lee, M. (2023) · Information · doi:10.3390/info14070418 · Cited by 5
Learning Context-free Languages with Nondeterministic Stack RNNs
DuSell, B., & Chiang, D. (2020) · Conference on Computational Natural Language Learning · doi:10.18653/v1/2020.conll-1.41 · Cited by 5
Language Models and Word Sense Disambiguation: An Overview and Analysis.Preprint
Loureiro, D., Rezaee, K., Pilehvar, M. T., & Camacho-Collados, J. (2020) · arXiv (Cornell University) · Cited by 5
Emergence of Syntax Needs Minimal Supervision
Bailly, R., & Gábor, K. (2020) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2020.acl-main.46 · Cited by 5
Biomedical Word Sense Disambiguation with Contextualized Representation Learning
Saeidi, M., Milios, E., & Zeh, N. (2022) · International World Wide Web Conference (WWW) · doi:10.1145/3487553.3524703 · Cited by 6
“The effectiveness of LSTM language models has been shown [18], as well as understanding their internal representations for predicting words in a context [52].”
BackgroundShin, U., Yi, E., & Song, S. (2023) · Frontiers in Psychology · doi:10.3389/fpsyg.2023.937656 · Cited by 8
The human unlikeness of neural language models in next-word prediction
Jacobs, C. L., & McCarthy, A. D. (2020) · Widening Natural Language Processing Workshop (WiNLP) · doi:10.18653/v1/2020.winlp-1.29 · Cited by 7
Speakers encode silent structures: Evidence from complementizer priming in English
Momma, S., Richards, N. W., & Ferreira, V. S. (2024) · Journal of Memory and Language · doi:10.1016/j.jml.2025.104671 · Cited by 4
Probe-Less Probing of BERT’s Layer-Wise Linguistic Knowledge with Masked Word Prediction
Aoyama, T., & Schneider, N. (2022) · Conference of the North American Chapter of the Association for Computational Linguistics: Student Research Workshop (NAACL SRW) · doi:10.18653/v1/2022.naacl-srw.25 · Cited by 11
“One plausible explanation is that identifying a correct pronoun requires a resolution of subject-verb agreement, which is shown to be handled well by BERT (Goldberg, 2019; van Schijndel et al., 2019) especially at layers 8 and 9 (Jawahar et al., 2019).”
BackgroundBERT is to NLP what AlexNet is to CV: Can Pre-Trained Language Models Identify Analogies?Preprint
Ushio, A., Espinosa-Anke, L., Schockaert, S., & Camacho-Collados, J. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2105.04949 · Cited by 3
“The main aspects that have been studied in recent years are syntax (Goldberg, 2019; Saphra and Lopez, 2019; Hewitt and Manning, 2019; van Schijndel et al., 2019; Jawahar et al., 2019; Tenney et al., 2019b) and semantics (Ettinger, 2019; Tenney et al., 2019a).”
BackgroundLearning Hierarchical Structures with Differentiable Nondeterministic StacksPreprint
DuSell, B., & Chiang, D. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2109.01982 · Cited by 5
“However, recurrent neural networks (RNNs) have difficulty learning to solve these tasks, or generalizing to held-out sequences, unless they have supervision or a hierarchical inductive bias (van Schijndel et al., 2019; Wilcox et al., 2019; McCoy et al., 2020).”
BackgroundKobzeva, A., Arehalli, S., Linzen, T., & Kush, D. (2025) · Journal of Memory and Language · doi:10.1016/j.jml.2025.104663 · Cited by 4
Self-citationFiller-gaps that neural networks fail to generalize
Bhattacharya, D., & van Schijndel, M. (2020) · Conference on Computational Natural Language Learning · doi:10.18653/v1/2020.conll-1.39 · Cited by 10
“We analyzed five of the highest performing models released by van Schijndel et al. (2019), 4 who showed that these models perform comparably to state-of-the-art transformers GPT and BERT on many simple syntactic agreement tasks.”
MethodLil-Bevo: Explorations of Strategies for Training Language Models in More Humanlike Ways
Govindarajan, V. S., Rodriguez, J. D., Bostrom, K., & Mahowald, K. (2023) · Proceedings of the BabyLM Challenge at the 27th Conference on Computational Natural Language Learning · doi:10.18653/v1/2023.conll-babylm.27 · Cited by 1
“One reason that has been posited not to take LLMs seriously as cognitive models, though, is the immense amount of data they are trained on relative to what a human child is exposed to (Warstadt and Bowman, 2022; van Schijndel et al., 2019).”
Huebner, P. A., & Willits, J. A. (2023) · Machine Learning with Applications · doi:10.1016/j.mlwa.2023.100478 · Cited by 3
Quantifying Context With and Without Statistical Language Models
Jacobs, C. L. (2022) · Springer eBooks · doi:10.1007/978-3-031-03945-4_17 · Cited by 1
Mini Minds: Exploring Bebeshka and Zlata Baby Models
Proskurina, I., Metzler, G., & Velcin, J. (2023) · Proceedings of the BabyLM Challenge at the 27th Conference on Computational Natural Language Learning · doi:10.18653/v1/2023.conll-babylm.4 · Cited by 1
“…cost by minimizing the training steps (van Schijn-del et al., 2019; Huebner et al., 2021; Schick and Schütze, 2021; Warstadt and Bowman, 2022). van Schijndel et al., 2019 have demonstrated that LMs trained on a small-volume corpus can reach human performance under some grammatical knowledge…”
BackgroundRecurrent Neural Network Language Models Always Learn English-Like Relative Clause Attachment
Davis, F., & van Schijndel, M. (2020) · Zenodo (CERN European Organization for Nuclear Research) · doi:10.5281/zenodo.3778993
Quantifying Context With and Without Statistical Language Models
Jacobs, C. L. (2021) · Springer eBooks · doi:10.1007/978-3-030-44982-7_17-1
How much pretraining data do language models need to learn syntax?Preprint
Pérez-Mayos, L., Ballesteros, M., & Wanner, L. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2109.03160 · Cited by 9
“Several studies investigate the relation between pre-training data size and linguistic knowledge in language models. van Schijndel et al. (2019); Hu et al. (2020); Micheli et al. (2020) find out that, given a relatively large data size (e.g., 10M words), models with less pretraining perform…”
BackgroundSun, S., Dillon, B., & Iyyer, M. (2022) · Workshop on Insights from Negative Results in NLP (Insights) · doi:10.18653/v1/2022.insights-1.6 · Cited by 1
“Previous works have intervened at least two aspects of LM training: (1) the size of training data (van Schijndel et al., 2019; Zhang et al., 2021) and (2) the training task (Linzen et al., 2016; Ravfogel et al., 2019).”
BackgroundSyntax and Geometry of Information
Bailly, R., Leblond, L., & Gábor, K. (2023) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2023.acl-long.590
“…shows that the performance drops when the test data contains natural or artificial examples which are deliberately different from the training examples (Lake and Baroni, 2017; Marvin and Linzen, 2018; Chowdhury and Zamparelli, 2018; van Schijndel et al., 2019; Maudslay and Cotterell, 2021).”
BackgroundBeinborn, L., & Hollenstein, N. (2023) · Synthesis lectures on human language technologies · doi:10.1007/978-3-031-43260-6_6
Evaluating L2 Training Methods in Neural Language Models
Lee, J., & Shin, J. (2024) · 어학연구 · doi:10.30961/lr.2024.60.3.323
Timkey, W., Huang, K.-J., Oh, B.-D., Prasad, G., Arehalli, S., Linzen, T., & Dillon, B. (2026) · Proceedings of the National Academy of Sciences · doi:10.1073/pnas.2532230123 · Cited by 10
Self-citation
Metadata
- Authors
- van Schijndel, M., Mueller, A., & Linzen, T.
- Affiliations
- Johns Hopkins University (US)
- Venue
- Proceedings of the 2019 Conference on Empirical Methods in Natural Language Processing and the 9th International Joint Conference on Natural Language Processing (EMNLP-IJCNLP)
- Published
- 2019
- Pages
- 5830-5836
- OpenAlex
- W2971016963
- Cited by
- 65
- References
- 30
- Citations by year
- 2026: 1 · 2025: 1 · 2024: 4 · 2023: 12 · 2022: 7 · 2021: 17 · 2020: 23
- FWCI
- 4.59
- Type
- conference paper
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- cc-by
- Locations
- Conference on Empirical Methods in Natural Language Processing (EMNLP) (publishedVersion, cc-by)
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Natural Language Processing Techniques
- Physical Sciences › Computer Science › Artificial Intelligence › Topic Modeling
- Social Sciences › Arts and Humanities › Language and Linguistics › Syntax, Semantics, Linguistic Variation
- Keywords
- neural language models, syntax, sentence length, model size
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
