

The DOI matches its Crossref record; 31 of the 33 references it cites were found in a registry or an index.
Multimodal and Multi-view Models for Emotion Recognition
Open accessAbstract
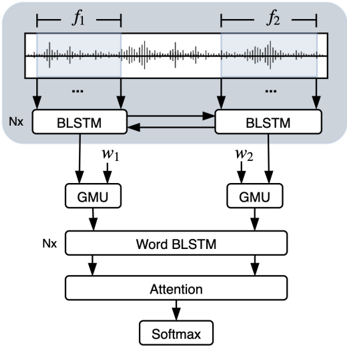
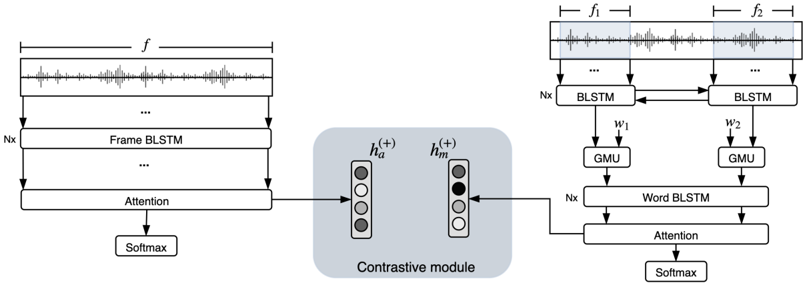
Studies on emotion recognition (ER) show that combining lexical and acoustic information results in more robust and accurate models.The majority of the studies focus on settings where both modalities are available in training and evaluation.However, in practice, this is not always the case; getting ASR output may represent a bottleneck in a deployment pipeline due to computational complexity or privacyrelated constraints.To address this challenge, we study the problem of efficiently combining acoustic and lexical modalities during training while still providing a deployable acoustic model that does not require lexical inputs.We first experiment with multimodal models and two attention mechanisms to assess the extent of the benefits that lexical information can provide.Then, we frame the task as a multi-view learning problem to induce semantic information from a multimodal model into our acoustic-only network using a contrastive loss function.Our multimodal model outperforms the previous state of the art on the USC-IEMOCAP dataset reported on lexical and acoustic information.Additionally, our multi-view-trained acoustic network significantly surpasses models that have been exclusively trained with acoustic features.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Existing multimodal fusion models trained on full-modality samples usually fail when partial modalities are missing (Aguilar et al., 2019; Pham et al., 2019; Cai et al., 2018; Parthasarathy and Sundaram, 2020).”
From Missing Modality Imagination Network for Emotion Recognition with Uncertain Missing Modalities (2021) · cites this paper as Aguilar et al., 2019
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Current multimodal models trained on complete data usually fail when tested on incomplete data (Aguilar et al., 2019; Pham et al., 2019).”
From Multimodal Prompt Learning with Missing Modalities for Sentiment Analysis and Emotion Recognition (2024) · cites this paper as Aguilar et al., 2019
Experimental — accuracy not yet measured
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Adam: A Method for Stochastic Optimization
Kingma, D. P., & Ba, J. (2014) · arXiv · doi:10.48550/arxiv.1412.6980 · Cited by 98,946
(2014) · Cited by 33,419
Batch Normalization: Accelerating Deep Network Training by Reducing Internal Covariate Shift
Ioffe, S., & Szegedy, C. (2015) · arXiv · doi:10.48550/arxiv.1502.03167 · Cited by 27,818
Neural Machine Translation by Jointly Learning to Align and Translate
Bahdanau, D., Cho, K., & Bengio, Y. (2014) · arXiv · doi:10.48550/arxiv.1409.0473 · Cited by 16,213
Batch Normalization: Accelerating Deep Network Training by Reducing Internal Covariate ShiftPreprint
Ioffe, S. (2024) · arXiv (Cornell University) · doi:10.57702/o9raffed · Cited by 15,273
Deep Contextualized Word Representations
Peters, M., Neumann, M., Iyyer, M., Gardner, M., Clark, C., Lee, K., & Zettlemoyer, L. (2018) · Proceedings of the 2018 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long Papers) · doi:10.18653/v1/n18-1202 · Cited by 11,983
(2016) · Cited by 11,679
Combining labeled and unlabeled data with co-training
Blum, A. L., & Mitchell, T. M. (1998) · Conference on Learning Theory · doi:10.1145/279943.279962 · Cited by 5,597
IEMOCAP: Interactive emotional dyadic motion capture database
Busso, C., Bulut, M., Lee, C.-C., Kazemzadeh, A., Mower, E., Kim, S., Chang, J. N., Lee, S., & Narayanan, S. S. (2008) · Language Resources and Evaluation · doi:10.1007/s10579-008-9076-6 · Cited by 3,869
Tensor Fusion Network for Multimodal Sentiment Analysis
Zadeh, A., Chen, M., Poria, S., Cambria, E., & Morency, L.-P. (2017) · Proceedings of the 2017 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/d17-1115 · Cited by 2,102
Research works printed but not linked: 2
- Matthew Peters, Mark Neumann, Mohit Iyyer, Matt Gardner, Christopher Clark, Kenton Lee, and Luke Zettlemoyer. 2018. Deep contextualized word rep- resentations. In Proceedings of the 2018 Confer- ence of the North American Chapter of the Associ- ation for Computational Linguistics: Human Lan- guage Technologies, Volume 1 (Long Papers), pages 2227-2237, New Orleans, Louisiana. Association for Computational Linguistics.
- Amir Zadeh, Minghai Chen, Soujanya Poria, Erik Cambria, and Louis-Philippe Morency. 2017. Ten- sor fusion network for multimodal sentiment analy- sis. CoRR, abs/1707.07250. · arXiv
Cited by
Sorted by citations
CTNet: Conversational Transformer Network for Emotion Recognition
Lian, Z., Liu, B., & Tao, J. (2021) · IEEE/ACM Transactions on Audio Speech and Language Processing · doi:10.1109/taslp.2021.3049898 · Cited by 309
Missing Modality Imagination Network for Emotion Recognition with Uncertain Missing Modalities
Zhao, J., Li, R., & Jin, Q. (2021) · Proceedings of the 59th Annual Meeting of the Association for Computational Linguistics and the 11th International Joint Conference on Natural Language Processing (Volume 1: Long Papers) · doi:10.18653/v1/2021.acl-long.203 · Cited by 275
“Existing multimodal fusion models trained on full-modality samples usually fail when partial modalities are missing (Aguilar et al., 2019; Pham et al., 2019; Cai et al., 2018; Parthasarathy and Sundaram, 2020).”
BackgroundInfluentialA survey of speech emotion recognition in natural environment
Fahad, M. S., Ranjan, A., Yadav, J., & Deepak, A. (2020) · Digital Signal Processing · doi:10.1016/j.dsp.2020.102951 · Cited by 167
C-GCN: Correlation Based Graph Convolutional Network for Audio-Video Emotion Recognition
Nie, W., Ren, M., Nie, J., & Zhao, S. (2020) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2020.3032037 · Cited by 92
Learning Audio-Video Modalities from Image Captions
Nagrani, A., Seo, P. H., Seybold, B., Hauth, A., Manén, S., Sun, C., & Schmid, C. (2022) · Lecture notes in computer science · doi:10.1007/978-3-031-19781-9_24 · Cited by 82
Sentiment Analysis: Comprehensive Reviews, Recent Advances, and Open Challenges
Lu, Q., Sun, X., Long, Y., Gao, Z., Feng, J. H., & Sun, T. S. (2023) · IEEE Transactions on Neural Networks and Learning Systems · doi:10.1109/tnnls.2023.3294810 · Cited by 77
Multimodal Emotion Recognition With Temporal and Semantic Consistency
Chen, B., Cao, Q., Hou, M., Zhang, Z., Lu, G., & Zhang, D. (2021) · IEEE/ACM Transactions on Audio, Speech, and Language Processing · doi:10.1109/taslp.2021.3129331 · Cited by 71
Inconsistent Matters: A Knowledge-Guided Dual-Consistency Network for Multi-Modal Rumor Detection
Sun, M., Zhang, X., Ma, J., Xie, S., Liu, Y., & Yu, P. S. (2023) · IEEE Transactions on Knowledge and Data Engineering · doi:10.1109/tkde.2023.3275586 · Cited by 69
Speech Databases, Speech Features, and Classifiers in Speech Emotion Recognition: A Review
Dar, G. H. M., & Delhibabu, R. (2024) · IEEE Access · doi:10.1109/access.2024.3476960 · Cited by 68
Multimodal Prompt Learning with Missing Modalities for Sentiment Analysis and Emotion Recognition
Guo, Z., Jin, T., & Zhao, Z. (2024) · Proceedings of the 62nd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) · doi:10.18653/v1/2024.acl-long.94 · Cited by 77
Group Gated Fusion on Attention-Based Bidirectional Alignment for Multimodal Emotion Recognition
Liu, P., Li, K., & Meng, H. M. L. (2020) · Interspeech (USB) · doi:10.21437/interspeech.2020-2067 · Cited by 65
Modeling Hierarchical Uncertainty for Multimodal Emotion Recognition in Conversation
Chen, F., Shao, J., Zhu, A., Ouyang, D., Liu, X., & Shen, H. T. (2022) · IEEE Transactions on Cybernetics · doi:10.1109/tcyb.2022.3185119 · Cited by 50
HGFM : A Hierarchical Grained and Feature Model for Acoustic Emotion Recognition
Xu, Y., Xu, H., & Zou, J. (2020) · IEEE International Conference on Acoustics Speech and Signal Processing · doi:10.1109/icassp40776.2020.9053039 · Cited by 50
Leveraging Knowledge of Modality Experts for Incomplete Multimodal Learning
Xu, W., Jiang, H., & Liang, X. (2024) · ACM International Conference on Multimedia (ACM MM) · doi:10.1145/3664647.3681683 · Cited by 44
PriMonitor: An adaptive tuning privacy-preserving approach for multimodal emotion detection
Yin, L., Lin, S., Sun, Z., Wang, S., Li, R., & He, Y. (2024) · World Wide Web · doi:10.1007/s11280-024-01246-7 · Cited by 40
Bimodal Speech Emotion Recognition Using Pre-Trained Language ModelsPreprint
Heußer, V., Freymuth, N., Constantin, S., & Waibel, A. (2019) · arXiv (Cornell University) · doi:10.48550/arxiv.1912.02610 · Cited by 30
Zhou, S., Jia, J., Wu, Z., Yang, Z., Wang, Y., Chen, W., Meng, F., Huang, S., Shen, J., & Wang, X. (2021) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v35i7.16753 · Cited by 25
Xiong, B., Yang, X., Song, Y., Wang, Y., & Xu, C. (2023) · ACM International Conference on Multimedia (ACM MM) · doi:10.1145/3581783.3611757 · Cited by 24
Audio Sentiment Analysis using Spectrogram and Bag-of- Visual- Words
Luitel, S., & Anwar, M. M. (2022) · IEEE International Conference on Information Reuse and Integration (IRI) · doi:10.1109/iri54793.2022.00052 · Cited by 22
A Deep Learning System for Sentiment Analysis of Service Calls
Jia, Y. (2020) · Workshop on e-Commerce and NLP (ECNLP) · doi:10.18653/v1/2020.ecnlp-1.4 · Cited by 21
Speech emotion recognition using feature fusion: a hybrid approach to deep learning
Khan, W. A., Qudous, H. U., & Farhan, A. A. (2024) · Multimedia Tools and Applications · doi:10.1007/s11042-024-18316-7 · Cited by 19
Saha, P., Mishra, D., Wagner, F., Kamnitsas, K., & Noble, J. A. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2402.05294 · Cited by 17
Transformer Based Multimodal Speech Emotion Recognition with Improved Neural Networks
Patamia, R. A., Wu, J., Acheampong, K. N., Sarpong, K., & Tenagyei, E. K. (2021) · IEEE International Conference on Pattern Recognition and Machine Learning (PRML) · doi:10.1109/prml52754.2021.9520692 · Cited by 13
M2P2: Multimodal Persuasion Prediction Using Adaptive Fusion
Bai, C., Chen, H., Kumar, S., Leskovec, J., & Subrahmanian, V. S. (2021) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2021.3134168 · Cited by 12
GAR-Net: A Graph Attention Reasoning Network for conversation understanding
Xu, H., Yuan, Z., Zhao, K., Xu, Y., Zou, J., & Gao, K. (2022) · Knowledge-Based Systems · doi:10.1016/j.knosys.2021.108055 · Cited by 12
Affective Latent Representation of Acoustic and Lexical Features for Emotion Recognition
Kim, E., Song, H., & Shin, J. W. (2020) · Sensors · doi:10.3390/s20092614 · Cited by 11
Saha, P., Mishra, D., Wagner, F., Kamnitsas, K., & Noble, J. A. (2025) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v39i27.35054 · Cited by 8
Semantic-wise guidance for efficient multimodal emotion recognition with missing modalities
Liu, S., Wang, Y., Wang, K., Li, B., Yang, F., & Yang, S. (2024) · Multimedia Systems · doi:10.1007/s00530-024-01310-2 · Cited by 8
ESTeR: Combining Word Co-occurrences and Word Associations for Unsupervised Emotion Detection
Gollapalli, S. D., Rozenshtein, P., & Ng, S.-K. (2020) · Findings of the Association for Computational Linguistics: EMNLP (Findings of EMNLP) · doi:10.18653/v1/2020.findings-emnlp.93 · Cited by 8
Lang, J., Hong, R., Cheng, Z., Zhong, T., Wang, Y. J., & Zhou, F. (2025) · ACM SIGKDD Conference on Knowledge Discovery and Data Mining (KDD) · doi:10.1145/3711896.3737101 · Cited by 5
Domain Adversarial Network for Cross-Domain Emotion Recognition in Conversation
Ma, H., Zhang, C., Zhou, X., Chen, J., & Zhou, Q. (2022) · Applied Sciences · doi:10.3390/app12115436 · Cited by 5
Multiview nonlinear discriminant structure learning for emotion recognition
Guo, S., Song, L., Xie, R., Li, L., & Liu, S. (2022) · Knowledge-Based Systems · doi:10.1016/j.knosys.2022.110042 · Cited by 5
Li, Y., Papayiannis, C., Rozgić, V., Shriberg, E. E., & Wang, C. (2022) · IEEE International Conference on Acoustics Speech and Signal Processing · doi:10.1109/icassp43922.2022.9746930 · Cited by 5
Self-citationCross-Modal Knowledge Transfer via Inter-Modal Translation and Alignment for Affect RecognitionPreprint
Rajan, V., Brutti, A., & Cavallaro, A. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2108.00809 · Cited by 5
Emotion Recognition with Conversational Generation Transfer
Ma, H., Wang, Z., Zhou, X., Zhou, G., & Zhou, Q. (2022) · ACM Transactions on Asian and Low-Resource Language Information Processing · doi:10.1145/3494532 · Cited by 4
Proceedings of The 3rd Workshop on e-Commerce and NLP
(2020) · doi:10.18653/v1/2020.ecnlp-1 · Cited by 4
Application of Artificial Intelligence Towards Successful Ageing
Miloulis, S.-T., Kakkos, I., Αναστασίου, Α., Matsopoulos, G. K., & Koutsouris, D. (2022) · Advances in human services and public health (AHSPH) book series · doi:10.4018/978-1-7998-9190-1.ch010 · Cited by 3
Tan, X., Gong, Z., Gan, M., Xie, W., & Wang, W. (2025) · Journal of King Saud University - Computer and Information Sciences · doi:10.1007/s44443-025-00091-6 · Cited by 2
Self-citationMulti-kernel Convolutional Neural Network for Wrist Pulse Signal Classification
Chen, X., Xu, H., Qian, P., Xu, Y., Li, F., & Li, S. (2022) · Conference of Open Innovations Association (FRUCT) · doi:10.23919/fruct56874.2022.9953841 · Cited by 2
AiM: Taking Answers in Mind to Correct Chinese Cloze Tests in Educational ApplicationsPreprint
Zhang, Y., Li, Z., Zhou, Q. S., Liu, Z., Li, C., Ma, M., Cao, Y., & Liu, H. (2022) · arXiv (Cornell University) · doi:10.48550/arxiv.2208.12505 · Cited by 2
Hierachical Delta-Attention Method for Multimodal FusionPreprint
Panchal, K. (2020) · arXiv (Cornell University) · doi:10.48550/arxiv.2011.10916 · Cited by 1
Multimodal transformers for emotion recognition
Vazquez-Rodriguez, J. (2023) · theses.fr (ABES) · doi:10.70675/a1927be2zdba6z405azbe6fz6856529b46bb · Cited by 1
Emotion Analysis in Speech Based on Audio-Visual FusionPreprint
Tuerhong, G., Jin, Y., & Wushouer, M. (2024) · SSRN Electronic Journal · doi:10.2139/ssrn.4857339
Chaptoukaev, H. (2025) · theses.fr (ABES) · doi:10.70675/d6c484f4zea27z4fedzac4dzd1a94b0332a6
Prompt-Guided Mixture-of-Experts for Robust Multimodal Sentiment Analysis with Missing Modalities
Shu, Z., Zhou, R., Wang, X., Wu, Q., & Cao, L. (2026) · IEEE International Conference on Acoustics Speech and Signal Processing · doi:10.1109/icassp55912.2026.11460508
Emotion Analysis in Speech Based on Audio-Visual Fusion
Zhitao, Z., Tuerhong, G., Wushouer, M., & Liwei, T. (2026) · Communications in computer and information science · doi:10.1007/978-3-032-22205-3_36
Wu, Z., Li, W., Qin, Z., & Wang, Q. (2026) · IEEE Transactions on Circuits and Systems for Video Technology · doi:10.1109/tcsvt.2026.3702958
Cross-Modal Probabilistic Representation Learning for Conversational Emotion Recognition
Zhou, Z., Feng, X., Wang, W., & Chen, J. (2026) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2026.3711930
Self-citationDiscriminative semantic learning for incomplete multimodal sentiment analysis
Shan, T., Chen, H., Liu, Y., Liu, Y., & Li, Z. (2026) · Multimedia Systems · doi:10.1007/s00530-026-02555-9
Metadata
- Authors
- Aguilar, G., Rozgic, V., Wang, W., & Wang, C.
- Affiliations
- University of Houston (US)
- Venue
- Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics
- Published
- 2019
- Pages
- 991-1002
- ISSN
- 0736-587X (ISSN-L)
- OpenAlex
- W2952307697
- Cited by
- 45
- References
- 33
- Citations by year
- 2026: 5 · 2025: 3 · 2024: 6 · 2023: 4 · 2022: 10 · 2021: 7 · 2020: 9 · 2019: 1
- FWCI
- 8.51
- Type
- conference paper
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- cc-by
- Locations
- Proceedings of the conference - Association for Computational Linguistics. Meeting (publishedVersion, cc-by)
- arXiv (Cornell University) (submittedVersion)
- arXiv (Cornell University)
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Emotion and Mood Recognition
- Physical Sciences › Computer Science › Artificial Intelligence › Sentiment Analysis and Opinion Mining
- Physical Sciences › Computer Science › Artificial Intelligence › Speech Recognition and Synthesis
- Keywords
- emotion recognition, multimodal fusion, lexical data, acoustic features, multi-view learning, contrastive loss, attention mechanism
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
