

Clinical Context–Aware Biomedical Text Summarization Using Deep Neural Network: Model Development and Validation.
Open accessPublished version of a preprint
The DOI matches its Crossref record; 46 of the 46 references it cites were found in a registry or an index.
Abstract
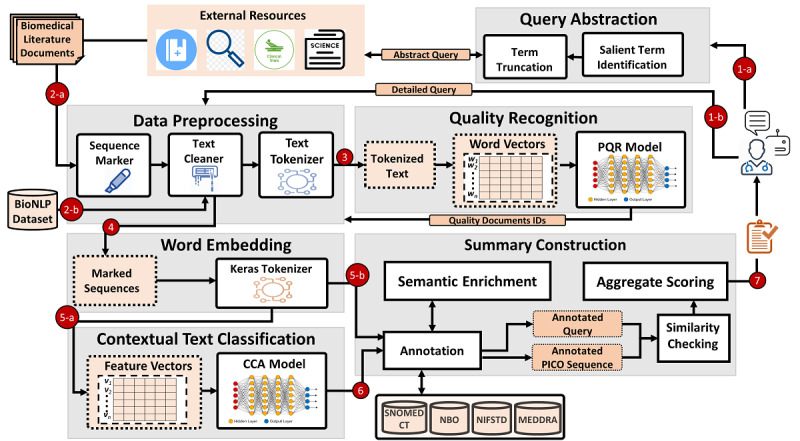
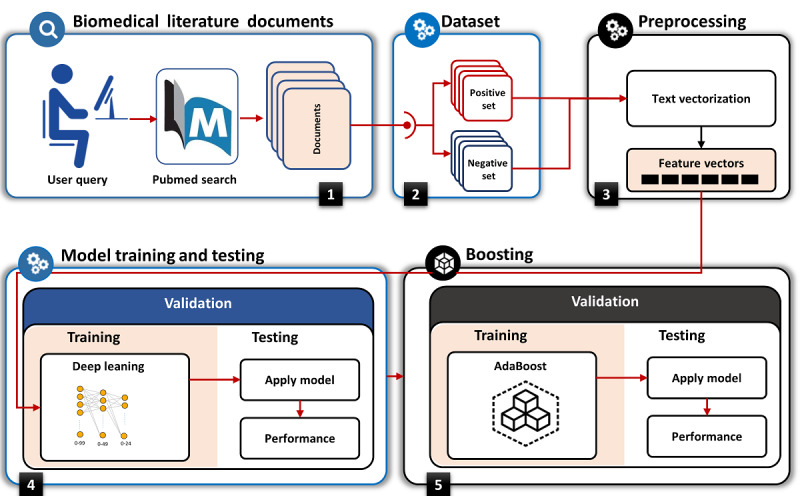
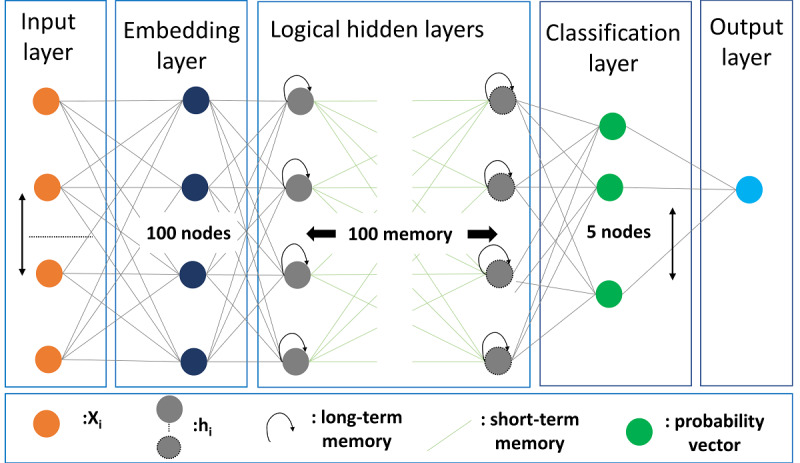
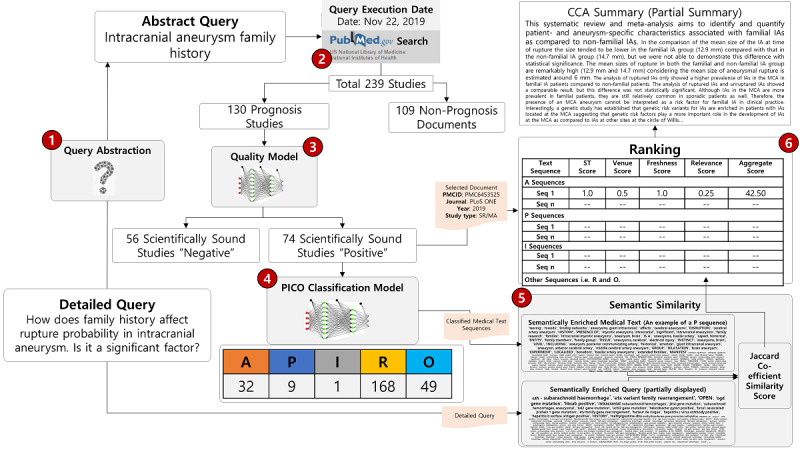
Background: Automatic text summarization (ATS) enables users to retrieve meaningful evidence from big data of biomedical repositories to make complex clinical decisions. Deep neural and recurrent networks outperform traditional machine-learning techniques in areas of natural language processing and computer vision; however, they are yet to be explored in the ATS domain, particularly for medical text summarization. Objective: Traditional approaches in ATS for biomedical text suffer from fundamental issues such as an inability to capture clinical context, quality of evidence, and purpose-driven selection of passages for the summary. We aimed to circumvent these limitations through achieving precise, succinct, and coherent information extraction from credible published biomedical resources, and to construct a simplified summary containing the most informative content that can offer a review particular to clinical needs. Methods: In our proposed approach, we introduce a novel framework, termed Biomed-Summarizer, that provides quality-aware Patient/Problem, Intervention, Comparison, and Outcome (PICO)-based intelligent and context-enabled summarization of biomedical text. Biomed-Summarizer integrates the prognosis quality recognition model with a clinical context–aware model to locate text sequences in the body of a biomedical article for use in the final summary. First, we developed a deep neural network binary classifier for quality recognition to acquire scientifically sound studies and filter out others. Second, we developed a bidirectional long-short term memory recurrent neural network as a clinical context–aware classifier, which was trained on semantically enriched features generated using a word-embedding tokenizer for identification of meaningful sentences representing PICO text sequences. Third, we calculated the similarity between query and PICO text sequences using Jaccard similarity with semantic enrichments, where the semantic enrichments are obtained using medical ontologies. Last, we generated a representative summary from the high-scoring PICO sequences aggregated by study type, publication credibility, and freshness score. Results: Evaluation of the prognosis quality recognition model using a large dataset of biomedical literature related to intracranial aneurysm showed an accuracy of 95.41% (2562/2686) in terms of recognizing quality articles. The clinical context–aware multiclass classifier outperformed the traditional machine-learning algorithms, including support vector machine, gradient boosted tree, linear regression, K-nearest neighbor, and naïve Bayes, by achieving 93% (16127/17341) accuracy for classifying five categories: aim, population, intervention, results, and outcome. The semantic similarity algorithm achieved a significant Pearson correlation coefficient of 0.61 (0-1 scale) on a well-known BIOSSES dataset (with 100 pair sentences) after semantic enrichment, representing an improvement of 8.9% over baseline Jaccard similarity. Finally, we found a highly positive correlation among the evaluations performed by three domain experts concerning different metrics, suggesting that the automated summarization is satisfactory. Conclusions: By employing the proposed method Biomed-Summarizer, high accuracy in ATS was achieved, enabling seamless curation of research evidence from the biomedical literature to use for clinical decision-making.
Overview
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The check wasn’t confident either way, so it gives no verdict — never disputed.
In the citing paper
“Dataset adaptations: 60, 167 PubMedPICO”
From Data extraction methods for systematic review (semi)automation: Update of a living systematic review (2025) · cites this paper as [60]
Experimental — accuracy not yet measuredIn the citing paper
“labelled automatically matching intervention strings from clinical trial registration 42000 sentences”
From Data extraction methods for systematic review (semi)automation: Update of a living systematic review (2025) · cites this paper as [60]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Glove: Global Vectors for Word Representation
Pennington, J., Socher, R., & Manning, C. (2014) · Proceedings of the 2014 Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.3115/v1/d14-1162 · Cited by 34,071 · cited 1×
“…representing the frequency of its use [3], more powerful word-embedding techniques have recently been introduced, such as word2vec [11,12] and GloVe [13], to combat the issues of data sparseness and context-overlooking by generating a vector space, typically of several hundred dimensions [14].”
MethodFundamentals of Recurrent Neural Network (RNN) and Long Short-Term Memory (LSTM) Network
Sherstinsky, A. (2020) · Physica D: Nonlinear Phenomena · doi:10.1016/j.physd.2019.132306 · Cited by 5,680
The Automatic Creation of Literature Abstracts
Luhn, H. P. (1958) · IBM Journal of Research and Development · doi:10.1147/rd.22.0159 · Cited by 3,246 · cited 1×
“For such a task, some researchers have used statistical features such as term frequency, sentence position, and similarity with the title [25,26], whereas other methods incorporated semantic information extracted from external linguistic resources [26,27].”
BackgroundNLTK: the Natural Language Toolkit
Loper, E., & Bird, S. (2002) · Proceedings of the ACL-02 Workshop on Effective tools and methodologies for teaching natural language processing and computational linguistics - · doi:10.3115/1118108.1118117 · Cited by 3,218
Neural Summarization by Extracting Sentences and Words
Cheng, J., & Lapata, M. (2016) · Proceedings of the 54th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) · doi:10.18653/v1/p16-1046 · Cited by 790 · cited 2×
“deep-learning approaches have been widely used in text summarization [3,46-49].”
MethodQuality in qualitative research
Kitto, S. C., Chesters, J., & Grbich, C. (2008) · Medical Journal of Australia · doi:10.5694/j.1326-5377.2008.tb01595.x · Cited by 728 · cited 1×
“Study types can be used to grade evidence concerning quality and other elements [34,51,52].”
MethodRecent automatic text summarization techniques: a survey
Gambhir, M., & Gupta, V. (2017) · Artificial Intelligence Review · doi:10.1007/s10462-016-9475-9 · Cited by 727 · cited 2×
“Extractive summarization approaches are classified into different categories such as statistical-, topic, graph, discourse, and machine learning–based approaches [5].”
BackgroundScikit-learn: Machine Learning Without Learning the Machinery
Varoquaux, G., Buitinck, L., Louppe, G., Grisel, O., Pedregosa, F., & Mueller, A. (2015) · GetMobile: Mobile Computing and Communications · doi:10.1145/2786984.2786995 · Cited by 650
Text Summarization Techniques: A Brief Survey
Allahyari, M., Pouriyeh, S., Assefi, M., Safaei, S., D., E., B., J., & Kochut, K. (2017) · International Journal of Advanced Computer Science and Applications · doi:10.14569/ijacsa.2017.081052 · Cited by 558
A comparison of word embeddings for the biomedical natural language processing
Wang, Y., Liu, S., Afzal, N., Rastegar-Mojarad, M., Wang, L., Shen, F., Kingsbury, P., & Liu, H. (2018) · Journal of Biomedical Informatics · doi:10.1016/j.jbi.2018.09.008 · Cited by 370
Atkins, D., Briss, P. A., Eccles, M., Flottorp, S., Guyatt, G. H., Harbour, R. T., Hill, S., Jaeschke, R., Liberati, A., Magrini, N., et al. (2005) · BMC Health Services Research · doi:10.1186/1472-6963-5-25 · Cited by 331 · cited 1×
“Study types can be used to grade evidence concerning quality and other elements [34,51,52].”
MethodAnswering Clinical Questions with Knowledge-Based and Statistical Techniques
Demner-Fushman, D., & Lin, J. (2007) · Computational Linguistics · doi:10.1162/coli.2007.33.1.63 · Cited by 296 · cited 2×
“PICO-based ATS remains an unexplored area; however, work has been done on individual aspects such as PICO elements identification in the text [21,29,30], quality recognition of therapy-related biomedical studies [40,41], and sentence-based summarization without PICO and quality evaluation [3,32].”
MethodWilczynski, N. L., Haynes, R. B., & the Hedges Team (2004) · BMC Medicine · doi:10.1186/1741-7015-2-23 · Cited by 291
Automated methods for the summarization of electronic health records
Pivovarov, R., & Elhadad, N. (2015) · Journal of the American Medical Informatics Association · doi:10.1093/jamia/ocv032 · Cited by 217 · cited 1×
“Medical text summarization poses a unique set of challenges compared to summarization in other domains [10].”
BackgroundAutomatic classification of sentences to support Evidence Based Medicine.
Kim, S. N., Martinez, D., Cavedon, L., & Yencken, L. (2011) · BMC Bioinformatics · doi:10.1186/1471-2105-12-s2-s5 · Cited by 214 · cited 3×
“In addition, in previous works, the dataset used for training and testing [29] contained only 1000 abstracts, which is not sufficient for a deep-learning model to be generalized.”
MethodText summarization in the biomedical domain: A systematic review of recent research
Mishra, R., Bian, J., Fiszman, M., Weir, C. R., Jonnalagadda, S., Mostafa, J., & Del Fiol, G. (2014) · Journal of Biomedical Informatics · doi:10.1016/j.jbi.2014.06.009 · Cited by 200
Text Categorization Models for High-Quality Article Retrieval in Internal Medicine
Aphinyanaphongs, Y. (2004) · Journal of the American Medical Informatics Association · doi:10.1197/jamia.m1641 · Cited by 177 · cited 1×
“Some methods have also used supervised machine-learning algorithms such as SVM, naïve Bayes, and decision tree to identify scientifically rigorous studies from PubMed [34,37,38,42].”
MethodBIOSSES: a semantic sentence similarity estimation system for the biomedical domain
Soğancıoğlu, G., Öztürk, H., & Özgür, A. (2017) · Bioinformatics · doi:10.1093/bioinformatics/btx238 · Cited by 164 · cited 3×
“The semantic similarity algorithm achieved a significant Pearson correlation coefficient of 0.61 (0-1 scale) on a well-known BIOSSES dataset (with 100 pair sentences) after semantic enrichment, representing an improvement of 8.9% over baseline Jaccard similarity.”
MethodInfluentialSummarization from medical documents: a survey
Afantenos, S., Karkaletsis, V., & Stamatopoulos, P. (2005) · Artificial Intelligence in Medicine · doi:10.1016/j.artmed.2004.07.017 · Cited by 163 · cited 2×
“Various methods have been proposed to choose what text should be included in the final summary [1,4-8, 23, 24 , 44].”
BackgroundMethod(2016) · PubMed · Cited by 134
Combining classifiers for robust PICO element detection.
Boudin, F., Nie, J.-Y., Bartlett, J. C., Grad, R., Pluye, P., & Dawes, M. (2010) · BMC Medical Informatics and Decision Making · doi:10.1186/1472-6947-10-29 · Cited by 131 · cited 2×
“To retrieve positive studies, we used the interface of Clinical Queries [33].”
MethodAlami, N., Meknassi, M., & En-Nahnahi, N. (2019) · Expert Systems with Applications · doi:10.1016/j.eswa.2019.01.037 · Cited by 120 · cited 3×
“…of words (BoW) approach, in which the text is tokenized into multiple words and each word is given a number representing the frequency of its use [3], more powerful word-embedding techniques have recently been introduced, such as word2vec [11,12] and GloVe [13], to combat the issues of data…”
BackgroundMethodA multi-document summarization system based on statistics and linguistic treatment
Ferreira, R., Cabral, L., Freitas, F., Lins, R. D., Silva, G. D. F., Simske, S. J., & Favaro, L. (2014) · Expert Systems with Applications · doi:10.1016/j.eswa.2014.03.023 · Cited by 110 · cited 1×
“For such a task, some researchers have used statistical features such as term frequency, sentence position, and similarity with the title [25,26], whereas other methods incorporated semantic information extracted from external linguistic resources [26,27].”
BackgroundTowards Automatic Recognition of Scientifically Rigorous Clinical Research Evidence
Kilicoglu, H., Demner-Fushman, D., Rindflesch, T. C., Wilczynski, N. L., & Haynes, R. B. (2009) · Journal of the American Medical Informatics Association · doi:10.1197/jamia.m2996 · Cited by 101 · cited 3×
“Several promising approaches have been explored [34-41] to retrieve high-quality (ie, scientifically sound) studies from the PubMed database.”
BackgroundMethodA text summarization method based on fuzzy rules and applicable to automated assessment
Goularte, F. B., Nassar, S. M., Fileto, R., & Saggion, H. (2018) · Expert Systems with Applications · doi:10.1016/j.eswa.2018.07.047 · Cited by 97 · cited 1×
“The most common method is the frequency-based approach, in which a sentence with a word holding the highest frequency is given more importance [45].”
MethodAn overview of the design and methods for retrieving high-quality studies for clinical care
Wilczynski, N. L., Morgan, D. R., Haynes, R. B., & the Hedges Team (2005) · BMC Medical Informatics and Decision Making · doi:10.1186/1472-6947-5-20 · Cited by 96
Graph-based biomedical text summarization: An itemset mining and sentence clustering approach
Azadani, M. N., Ghadiri, N., & Davoodijam, E. (2018) · Journal of Biomedical Informatics · doi:10.1016/j.jbi.2018.06.005 · Cited by 80 · cited 3×
“Various methods have been proposed to choose what text should be included in the final summary [1,4-8,23,24,44].”
BackgroundMethodBui, D. D. A., Del Fiol, G., Hurdle, J. F., & Jonnalagadda, S. (2016) · Journal of Biomedical Informatics · doi:10.1016/j.jbi.2016.10.014 · Cited by 70 · cited 2×
“The existing studies are categorized based on three aspects: individual PICO element identification [9,18,28], sentence classification [21,29], and question and answer with summarization [9,30].”
BackgroundMethodIrwin, A. N., & Rackham, D. M. (2016) · Research in Social and Administrative Pharmacy · doi:10.1016/j.sapharm.2016.04.006 · Cited by 70 · cited 1×
“The limitation of approaches that use MeSH terms is the availability, as MeSH terms are added to PubMed citations with an average time gap of 20 to 252 days after an article is published [40,43].”
MethodPICO Element Detection in Medical Text via Long Short-Term Memory Neural Networks.
Jin, D., & Szolovits, P. (2018) · Proceedings of the BioNLP 2018 workshop · doi:10.18653/v1/w18-2308 · Cited by 61
Malik, K. M., Krishnamurthy, M., Alobaidi, M., Hussain, M., Alam, F., & Malik, G. (2020) · Expert Systems with Applications · doi:10.1016/j.eswa.2019.113120 · Cited by 56 · cited 1×
“An accurate clinical summarization is expected to revolutionize the field of domain-specific knowledge graphs [57] and clinical decision support systems.”
BackgroundSelf-citationPICO element detection in medical text without metadata: are first sentences enough?
Huang, K.-C., Chiang, I.-J., Xiao, F., Liao, C.-C., Liu, C. C.-H., & Wong, J.-M. (2013) · Journal of Biomedical Informatics · doi:10.1016/j.jbi.2013.07.009 · Cited by 52
Del Fiol, G., Michelson, M., Iorio, A., Cotoi, C., & Haynes, R. B. (2018) · Journal of Medical Internet Research · doi:10.2196/10281 · Cited by 51 · cited 5×
“Several promising approaches have been explored [34-41] to retrieve high-quality (ie, scientifically sound) studies from the PubMed database.”
BackgroundMethodInfluentialMEDLINE clinical queries are robust when searching in recent publishing years
Wilczynski, N. L., McKibbon, K. A., Walter, S. D., Garg, A. X., & Haynes, R. B. (2013) · Journal of the American Medical Informatics Association · doi:10.1136/amiajnl-2012-001075 · Cited by 50 · cited 2×
“Among these, some methods such as PubMed Clinical Queries rely on Boolean-based strategies using Medical Subject Heading (MeSH) terms and keywords [39,40].”
MethodClassification of clinically useful sentences in clinical evidence resources
Morid, M. A., Marcelo Fiszman, B., Raja, K., Jonnalagadda, S., & Fiol, G. D. (2016) · Journal of Biomedical Informatics · doi:10.1016/j.jbi.2016.01.003 · Cited by 50 · cited 1×
“Various methods have been proposed to choose what text should be included in the final summary [1,4-8, 23, 24 , 44].”
MethodQuantifying the informativeness for biomedical literature summarization: An itemset mining method
Moradi, M., & Ghadiri, N. (2017) · Computer Methods and Programs in Biomedicine · doi:10.1016/j.cmpb.2017.05.011 · Cited by 46 · cited 2×
“Various methods have been proposed to choose what text should be included in the final summary [1,4-8, 23, 24 , 44].”
MethodClassification of PICO elements by text features systematically extracted from PubMed abstracts.
Huang, K.-C., Liu, C. C.-H., Yang, S.-S., Xiao, F., Wong, J.-M., Liao, C.-C., & Chiang, I.-J. (2011) · 2011 IEEE International Conference on Granular Computing · doi:10.1109/grc.2011.6122608 · Cited by 26 · cited 1×
“Subsequently, researchers have used the PICO structure for information retrieval and sentence identification in the text of biomedical documents [18-21].”
MethodAphinyanaphongs, Y., Statnikov, A., & Aliferis, C. F. (2006) · Journal of the American Medical Informatics Association · doi:10.1197/jamia.m2031 · Cited by 24 · cited 1×
“Some methods have also used supervised machine-learning algorithms such as SVM, naïve Bayes, and decision tree to identify scientifically rigorous studies from PubMed [34,37,38,42].”
MethodImproving Medical Information Retrieval with PICO Element Detection.
Boudin, F., Shi, L., & Nie, J.-Y. (2010) · Lecture Notes in Computer Science · doi:10.1007/978-3-642-12275-0_8 · Cited by 21 · cited 2×
“The existing studies are categorized based on three aspects: individual PICO element identification [9,18,28], sentence classification [21,29], and question and answer with summarization [9,30].”
MethodLynn, H. M., Choi, C., & Kim, P. (2017) · Soft Computing · doi:10.1007/s00500-017-2612-9 · Cited by 19 · cited 1×
“For such a task, some researchers have used statistical features such as term frequency, sentence position, and similarity with the title [25,26], whereas other methods incorporated semantic information extracted from external linguistic resources [26,27].”
BackgroundContext-aware grading of quality evidences for evidence-based decision-making
Afzal, M., Hussain, M., Haynes, R. B., & Lee, S. (2017) · Health Informatics Journal · doi:10.1177/1460458217719560 · Cited by 16 · cited 1×
“Some methods have also used supervised machine-learning algorithms such as SVM, naïve Bayes, and decision tree to identify scientifically rigorous studies from PubMed [34,37,38,42].”
MethodSelf-citationAfzal, M., Hussain, M., Malik, K. M., & Lee, S. (2019) · JMIR Medical Informatics · doi:10.2196/13430 · Cited by 13 · cited 3×
“Several promising approaches have been explored [34-41] to retrieve high-quality (ie, scientifically sound) studies from the PubMed database.”
BackgroundMethodSelf-citationPICO Extraction by combining the robustness of machine-learning methods with the rule-based methods.
Chabou, S., & Iglewski, M. (2015) · 2015 World Congress on Information Technology and Computer Applications (WCITCA) · doi:10.1109/wcitca.2015.7367038 · Cited by 7 · cited 2×
“We measured the correlation strength based on the standard guideline of the Pearson correlation coefficient in the biomedical domain [20].”
MethodMining E-commercial data: A text-rich heterogeneous network embedding approach
Chen, W., Liu, C., Yin, J., Yan, H., & Zhang, Y. (2017) · International Joint Conference on Neural Networks (IJCNN) · doi:10.1109/ijcnn.2017.7966017 · Cited by 7 · cited 1×
“The word2vec approach creates vectors at the sentence or document level by employing the sentence2vec or doc2vec model [15].”
MethodAPPLICATIONS OF TEXT SUMMARIZATION
Khargharia, D. (2018) · International Journal of Advanced Research in Computer Science · doi:10.26483/ijarcs.v9i3.6037 · Cited by 5
(2011) · SpringerReference · doi:10.1007/springerreference_35069 · Cited by 2
Research works printed but not linked: 12
- SchulzeFNevesMEntity-Supported Summarization of Biomedical AbstractsThe COLING 2016 Organizing CommitteeProceedings of the Fifth Workshop on Building and Evaluating Resources for Biomedical Text Mining (BioTxtM2016)December 2016Osaka, Japan4049
- Allahyari, M, 2017, arXiv, 1
- Khatri, C, 2018, arxiv, 1807.08000 · arXiv
- MikolovTYihWZweigGLinguistic Regularities in Continuous Space Word Representations Internet201306Proceedings of the 2013 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language TechnologiesJune 2013Atlanta, GeorgiaAssociation for Computational Linguistics746751
- Moradi, M, 2019, arXiv, 1903.02861 · arXiv
- ZlabingerMAnderssonLHanburyAAnderssonMQuasnikVBrasseyJMedical entity corpus with pico elements and sentiment analysisEuropean Language Resources Association (ELRA)201805Eleventh International Conference on Language Resources and Evaluation (LREC 2018)2018Miyazaki, Japan
- Wallace, B, 2016, J Mach Learn Res, 17, 132
- Cao, Z, 2016, arXiv, 1604.00125 · arXiv
- Nallapati, R, 2016, arxiv, 1611.04230 · arXiv
- Cheng, J, 2016, arXiv, 1603.07252 · arXiv
- Loper, E, 2002, arXiv, 0205028
- Pedregosa, F, 2011, J Machine Learn Res, 2825
Cited by
Natural Language Processing for Smart Healthcare
Zhou, B., Yang, G., Shi, Z., & Ma, S. (2024) · IEEE Reviews in Biomedical Engineering · doi:10.1109/rbme.2022.3210270 · Cited by 230
“ease the access of medical knowledge [1], [83], [85], [134], [187], [189], [190] question answering, information retrieval, machine translation generate medical case-based questions [191] question generation construct simplified summaries [65] text summarization population screening identify target populations [192] i…”
BackgroundData extraction methods for systematic review (semi)automation: a living systematic review
Schmidt, L., Olorisade, B. K., McGuinness, L. A., Thomas, J., & Higgins, J. P. T. (2021) · F1000Research · doi:10.12688/f1000research.51117.1 · Cited by 106
Ensemble Multifeatured Deep Learning Models and Applications: A Survey
Abimannan, S., El-Alfy, E.-S. M., Chang, Y., Hussain, S., Shukla, S., & Satheesh, D. (2023) · IEEE Access · doi:10.1109/access.2023.3320042 · Cited by 119
“Word embeddings (e.g., Word2Vec, GloVe, and BERT) are high-dimensional vector representations of words that capture semantic and syntactic relationships between words within a given context [131].”
BackgroundHuang, E., Yang, J., Liao, K. Y.-K., Tseng, W. C. W., Lee, C. K., Gill, M., Compas, C. B., See, S. C. W., & Tsai, F. (2024) · Scientific Reports · doi:10.1038/s41598-024-66897-y · Cited by 109
Overview of the MEDIQA 2021 Shared Task on Summarization in the Medical Domain
Ben Abacha, A., Mrabet, Y., Zhang, Y., Shivade, C., Langlotz, C., & Demner-Fushman, D. (2021) · Proceedings of the 20th Workshop on Biomedical Language Processing · doi:10.18653/v1/2021.bionlp-1.8 · Cited by 68
“However, despite its importance, fewer efforts have tackled text summarization in the biomedical domain for both consumer and clinical text and its applications in Question Answering (QA) (Afantenos et al., 2005; Mishra et al., 2014; Afzal et al., 2020).”
Background
Metadata
- Authors
- Afzal, M., Alam, F., Malik, K. M., & Malik, G. M.
- Affiliations
- Oakland University (US)
- Henry Ford Health (US)
- Corresponding author
- Malik, Khalid Mahmood
- Venue
- Journal of Medical Internet Research
- Publisher
- JMIR Publications Inc.
- Published
- 2020-10-23
- Volume
- 22
- Issue
- 10
- Pages
- e19810
- ISSN
- 1438-8871 (ISSN-L)
- PMC
- PMC7647812
- OpenAlex
- W3086767710
- Cited by
- 65
- References
- 46
- Citations by year
- 2026: 11 · 2025: 8 · 2024: 16 · 2023: 14 · 2022: 12 · 2021: 4
- FWCI
- 2.43
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Licence
- cc-by
- Locations
- Journal of Medical Internet Research (publishedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion, cc-by-sa)
- Funders
- Brain Aneurysm Foundation
- Topics
- Health Sciences › Medicine › Health Informatics › Biomedical Text Mining and Ontologies
- Physical Sciences › Computer Science › Artificial Intelligence › Advanced Text Analysis Techniques
- Physical Sciences › Computer Science › Artificial Intelligence › Topic Modeling
- Keywords
- biomedical text summarization, PICO framework, bidirectional LSTM, semantic enrichment, medical ontologies, Jaccard similarity, query-document matching, intracranial aneurysm, clinical decision support, word embeddings, clinical decision support systems, evidence-based medicine
- MeSH terms
- Humans, Reproducibility of Results, Information Storage and Retrieval, Neural Networks, Computer
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
