

The DOI matches its Crossref record; 38 of the 38 references it cites were found in a registry or an index.
Deep Learning Application for Vocal Fold Disease Prediction Through Voice Recognition: Preliminary Development Study
Open accessPublished version of a preprint
Abstract
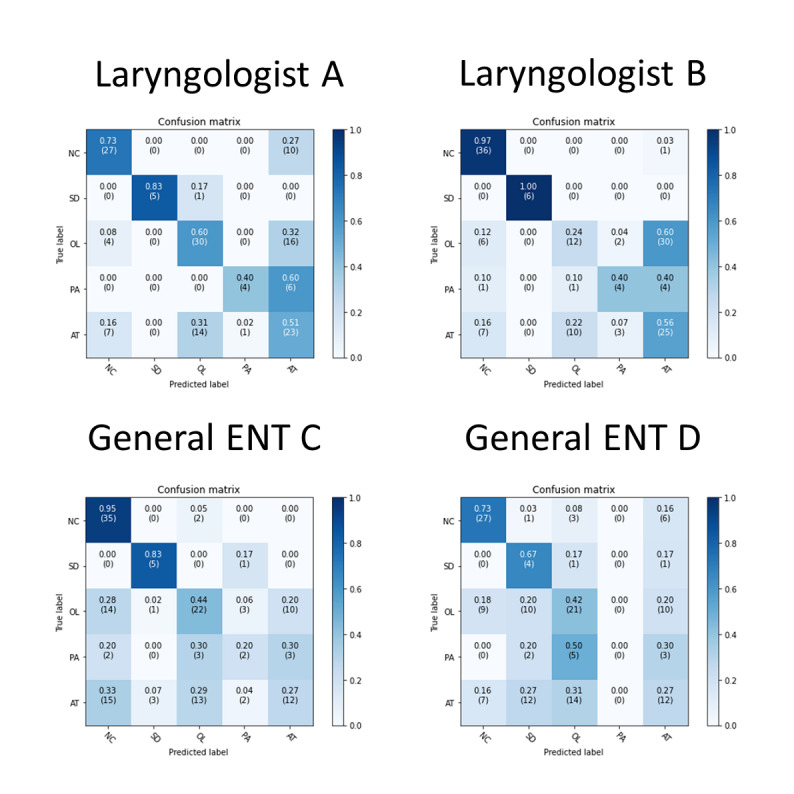
Background: Dysphonia influences the quality of life by interfering with communication. However, a laryngoscopic examination is expensive and not readily accessible in primary care units. Experienced laryngologists are required to achieve an accurate diagnosis. Objective: This study sought to detect various vocal fold diseases through pathological voice recognition using artificial intelligence. Methods: We collected 189 normal voice samples and 552 samples of individuals with voice disorders, including vocal atrophy (n=224), unilateral vocal paralysis (n=50), organic vocal fold lesions (n=248), and adductor spasmodic dysphonia (n=30). The 741 samples were divided into 2 sets: 593 samples as the training set and 148 samples as the testing set. A convolutional neural network approach was applied to train the model, and findings were compared with those of human specialists. Results: The convolutional neural network model achieved a sensitivity of 0.66, a specificity of 0.91, and an overall accuracy of 66.9% for distinguishing normal voice, vocal atrophy, unilateral vocal paralysis, organic vocal fold lesions, and adductor spasmodic dysphonia. Compared with the accuracy of human specialists, the overall accuracy rates were 60.1% and 56.1% for the 2 laryngologists and 51.4% and 43.2% for the 2 general ear, nose, and throat doctors. Conclusions: Voice alone could be used for common vocal fold disease recognition through a deep learning approach after training with our Mandarin pathological voice database. This approach involving artificial intelligence could be clinically useful for screening general vocal fold disease using the voice. The approach includes a quick survey and a general health examination. It can be applied during telemedicine in areas with primary care units lacking laryngoscopic abilities. It could support physicians when prescreening cases by allowing for invasive examinations to be performed only for cases involving problems with automatic recognition or listening and for professional analyses of other clinical examination results that reveal doubts about the presence of pathologies.
Overview
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Integrity signals
Registry
Cites
Statistics
Figures


Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“performance decreases to 70–85% when distinguishing between specific disorders, highlighting an intrinsic limitation that cannot be resolved through increased model complexity [6,7,24,25,42].”
From Diagnostic Accuracy of Artificial Intelligence in Laryngeal Disorders: An Integrative Review (2026) · cites this paper as [42]
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Intelligent denoising approaches based on probabilistic noise models and perceptually motivated time–frequency representations have been proposed to improve signal quality exploitable by AI models.”
From Diagnostic Accuracy of Artificial Intelligence in Laryngeal Disorders: An Integrative Review (2026) · cites this paper as [42]
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“a study on voice disorders revealed that the diagnostic accuracy between AI and voice experts did not exceed 60.1%.”
From Artificial intelligence in assessment and intervention of speech and language disorders: A literature review (2025) · cites this paper as [27]
Experimental — accuracy not yet measuredThe cited source says what the claim attributes to it.
In the citing paper
“Several pathophysiologically distinct disorders produce overlapping acoustic signatures, leading to inherent diagnostic ambiguity within the vocal signal itself [6,7,19,42].”
From Diagnostic Accuracy of Artificial Intelligence in Laryngeal Disorders: An Integrative Review (2026) · cites this paper as [42]
The check wasn’t confident either way, so it gives no verdict — never disputed.
In the citing paper
“Recent research demonstrates that some approaches even maintain high performance under unfavorable signal-to-noise ratios [31,42].”
From Diagnostic Accuracy of Artificial Intelligence in Laryngeal Disorders: An Integrative Review (2026) · cites this paper as [42]
Experimental — accuracy not yet measured
2 more claims about this paper
Create a free account to see every claim other papers make about this one.
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Squeeze-and-Excitation Networks
Hu, J., Shen, L., & Sun, G. (2018) · 2018 IEEE/CVF Conference on Computer Vision and Pattern Recognition · doi:10.1109/cvpr.2018.00745 · Cited by 35,667
A Study on CNN Transfer Learning for Image Classification
Hussain, M., Bird, J. J., & Faria, D. R. (2019) · Advances in Intelligent Systems and Computing · doi:10.1007/978-3-319-97982-3_16 · Cited by 607
Clinical Practice Guideline: Hoarseness (Dysphonia) (Update)
Stachler, R. J., Francis, D. O., Schwartz, S. R., Damask, C. C., Digoy, G. P., Krouse, H. J., McCoy, S. J., Ouellette, D. R., Patel, R. R., Reavis, C. (. W., et al. (2018) · Otolaryngology–Head and Neck Surgery · doi:10.1177/0194599817751030 · Cited by 368
Godino-Llorente, J. I., Gomez-Vilda, P., & Blanco-Velasco, M. (2006) · IEEE Transactions on Biomedical Engineering · doi:10.1109/tbme.2006.871883 · Cited by 322 · cited 2×
“Most previous studies have used sustained vowel sounds for pathological voice detection [5,7,8].”
BackgroundTowards dropout training for convolutional neural networks
Wu, H., & Gu, X. (2015) · Neural Networks · doi:10.1016/j.neunet.2015.07.007 · Cited by 314
Prevalence and causes of dysphonia in a large treatment‐seeking population
Cohen, S. M., Kim, J., Roy, N., Asche, C., & Courey, M. (2012) · The Laryngoscope · doi:10.1002/lary.22426 · Cited by 314
Detection of Pathological Voice Using Cepstrum Vectors: A Deep Learning Approach
Fang, S.-H., Tsao, Y., Hsiao, M.-J., Chen, J.-Y., Lai, Y.-H., Lin, F.-C., & Wang, C.-T. (2019) · Journal of Voice · doi:10.1016/j.jvoice.2018.02.003 · Cited by 278
Self-citationQuality-of-Life Impact of Non-Neoplastic Voice Disorders: A Meta-Analysis
Cohen, S. M., Dupont, W. D., & Courey, M. S. (2006) · Annals of Otology, Rhinology & Laryngology · doi:10.1177/000348940611500209 · Cited by 258
Discrimination of pathological voices using a time-frequency approach
Umapathy, K., Krishnan, S., Parsa, V., & Jamieson, D. G. (2005) · IEEE Transactions on Biomedical Engineering · doi:10.1109/tbme.2004.842962 · Cited by 149
Current dysphonia trends in patients over the age of 65: Is vocal atrophy becoming more prevalent?
Davids, T., Klein, A. M., & Johns, M. M. E. (2012) · The Laryngoscope · doi:10.1002/lary.22397 · Cited by 142
Research works printed but not linked: 11
- Salhi, L, 2010, Int Arab J Inf Technol, 2, 177
- Zhang, H, 2018, arXiv
- Branco, P, 2015, arXiv
- LoganBMel Frequency cepstral coefficients for music modeling20001st International Symposium on Music Information RetrievalOctober 23-25, 2000Plymouth, MA
- Ravi Kumar, KM, 2011, Int J Adv Netw Appl, 2, 854
- Tan, M, 2020, arXiv
- Perez, L, 2017, arXiv
- Lym, S, 2018, arXiv
- Huang, G, 2017, arXiv
- Smith, L, 2018, arXiv
- Kingma, D, 2017, arXiv
Cited by
Developing an Artificial Intelligence Tool to Predict Vocal Cord Pathology in Primary Care Settings
Compton, E. C., Cruz, T., Andreassen, M., Beveridge, S., Bosch, D., Randall, D. R., & Livingstone, D. (2023) · The Laryngoscope · doi:10.1002/lary.30432 · Cited by 38
“showcase the importance of developing a tool to help family physicians, who lack specialized equipment, refine their differential diagnoses for patients with hoarseness.(7) The discrepancy between the accuracy of the Calgary model when tested on similar data versus when tested on the Saarbruecken data set brings up se…”
BackgroundResultInfluentialThe Use of Deep Learning Software in the Detection of Voice Disorders: A Systematic Review
Barlow, J., Sragi, Z., Rivera‐Rivera, G., Al‐Awady, A., Daşdöğen, Ü., Courey, M. S., & Kirke, D. N. (2024) · Otolaryngology–Head and Neck Surgery · doi:10.1002/ohn.636 · Cited by 25
Deep learning in voice analysis for diagnosing vocal cord pathologies: a systematic review
Tessler, I., Primov-Fever, A., Soffer, S., Anteby, R., Gecel, N. A., Livneh, N., Alon, E. E., Zimlichman, E., & Klang, E. (2024) · European Archives of Oto-Rhino-Laryngology · doi:10.1007/s00405-023-08362-6 · Cited by 18
Low, D. M., Rao, V., Randolph, G., Song, P. C., & Ghosh, S. S. (2024) · PLOS Digital Health · doi:10.1371/journal.pdig.0000516 · Cited by 16
Kim, Y. E., Dobko, M., Li, H., Shao, T., Periyakoil, P., Tipton, C., Colasacco, C., Serpedin, A., Elemento, O., Sabuncu, M., et al. (2025) · The Laryngoscope · doi:10.1002/lary.32036 · Cited by 9
Metadata
- Authors
- Hu, H.-C., Chang, S.-Y., Wang, C.-H., Li, K.-J., Cho, H.-Y., Chen, Y.-T., Lu, C.-J., Tsai, T.-P., & Lee, O. K.-S.
- Affiliations
- Fu Jen Catholic University (TW)
- Cheng Hsin General Hospital (TW)
- National Yang Ming Chiao Tung University (TW)
- Corresponding author
- Lee, Oscar Kuang-Sheng
- ORCID
- Venue
- Journal of Medical Internet Research
- Publisher
- JMIR Publications Inc.
- Published
- 2021-06-08
- Volume
- 23
- Issue
- 6
- Pages
- e25247
- ISSN
- 1438-8871 (ISSN-L)
- PMC
- PMC8241431
- OpenAlex
- W3166913861
- Cited by
- 82
- References
- 38
- Citations by year
- 2026: 11 · 2025: 22 · 2024: 17 · 2023: 15 · 2022: 15 · 2021: 1
- FWCI
- 7.53
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Licence
- cc-by
- Locations
- Journal of Medical Internet Research (publishedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion, cc-by-sa)
- Funders
- Shanghai Educational Development Foundation
- Ministry of Science and Technology, Taiwan (MOST109-2622-B010-006, MOST109-2321-B010-005, MOST109-2321-B010-006)
- National Yang-Ming University
- Fu Jen Catholic University
- Topics
- Health Sciences › Health Professions › Speech and Hearing › Voice and Speech Disorders
- Health Sciences › Health Professions › Health Information Management › Artificial Intelligence in Healthcare
- Physical Sciences › Computer Science › Artificial Intelligence › Speech Recognition and Synthesis
- Keywords
- dysphonia, spasmodic dysphonia, convolutional neural networks, telemedicine
- MeSH terms
- Deep Learning, Voice Recognition, Artificial Intelligence, Humans, Quality of Life, Vocal Cords
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
How to cite
Cite CoChat for the checks on this page, and the paper for its own findings.
- This page
- CoChat. (2026). Citation check: Deep Learning Application for Vocal Fold Disease Prediction Through Voice Recognition: Preliminary Development Study. https://app.cochat.ai/papers/10.2196/25247
- The paper
- Hu, H.-C., Chang, S.-Y., Wang, C.-H., Li, K.-J., Cho, H.-Y., Chen, Y.-T., Lu, C.-J., Tsai, T.-P., & Lee, O. K.-S. (2021). Deep Learning Application for Vocal Fold Disease Prediction Through Voice Recognition: Preliminary Development Study. Journal of Medical Internet Research. https://doi.org/10.2196/25247
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
