

The DOI matches its Crossref record; 204 of the 204 references it cites were found in a registry or an index; 10 of the 14 sources its claims cite were checked for support.
Deepfake Media Forensics: Status and Future Challenges
Open accessAbstract
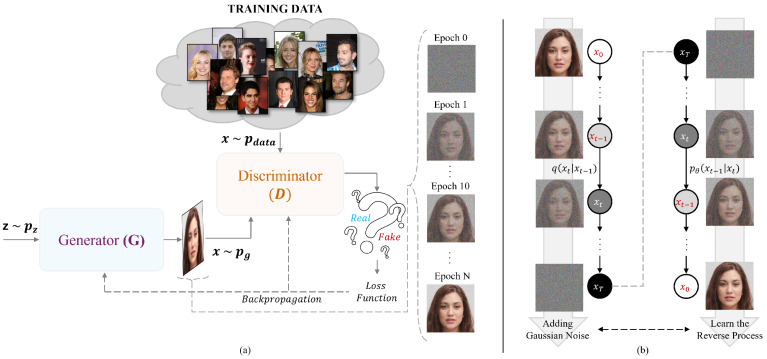
The rise of AI-generated synthetic media, or deepfakes, has introduced unprecedented opportunities and challenges across various fields, including entertainment, cybersecurity, and digital communication. Using advanced frameworks such as Generative Adversarial Networks (GANs) and Diffusion Models (DMs), deepfakes are capable of producing highly realistic yet fabricated content, while these advancements enable creative and innovative applications, they also pose severe ethical, social, and security risks due to their potential misuse. The proliferation of deepfakes has triggered phenomena like "Impostor Bias", a growing skepticism toward the authenticity of multimedia content, further complicating trust in digital interactions. This paper is mainly based on the description of a research project called FF4ALL (FF4ALL-Detection of Deep Fake Media and Life-Long Media Authentication) for the detection and authentication of deepfakes, focusing on areas such as forensic attribution, passive and active authentication, and detection in real-world scenarios. By exploring both the strengths and limitations of current methodologies, we highlight critical research gaps and propose directions for future advancements to ensure media integrity and trustworthiness in an era increasingly dominated by synthetic media.
Overview
CoChat Summary
TL;DR
This review/position paper surveys deepfake media forensics within the FF4ALL project, covering generation, detection, attribution, passive/active authentication, continual learning, explainability, and ethics. It argues that detection must adapt to evolving generative models, real-world compression and adversarial conditions, and calls for scalable, interpretable, and ethically governed tools.
Key findings
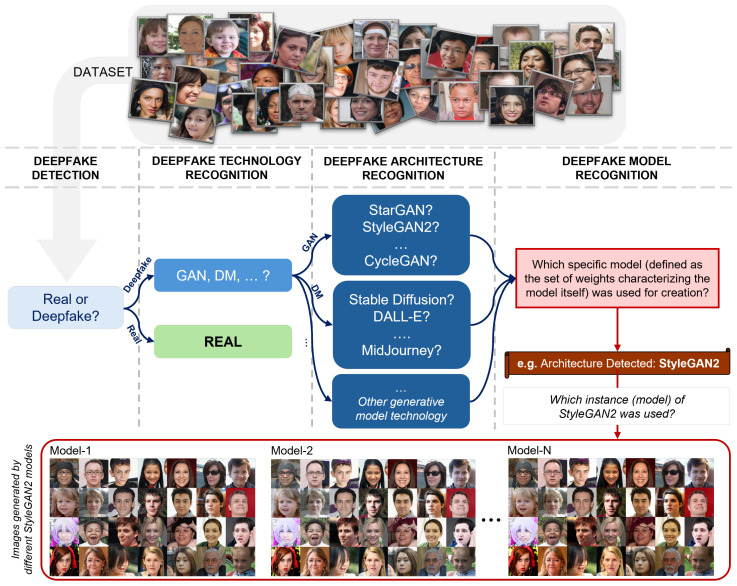
- The paper synthesizes detection approaches including undirected deep learning, visual artifacts, biological artifacts, and texture/spatio-temporal consistency; attribution aims to identify architecture and even model instance, with one cited method using ResNET-18 plus metric learning to distinguish 100 different StyleGAN2-ADA instances.
- It reports dataset scales: WildFake has over 3.6 million images (2.6 M fake and 1 M real); Artifact has over 2.4 million images (1.5 million synthetic from 25 methods); DIFF has over 500,000 images from 13 diffusion models; DFDC has nearly 120,000 videos (100,000 fake); ASVspoof 2019 contains 78 speakers (33 male, 45 female).
- Continual learning results include DFWF achieving an Average Equal Error Rate reduction of 81.63% compared to fine-tuning on ASVspoof 2019, and a Transformer-based continual learning method achieving 90–95% AUC on unseen datasets using ASVspoof datasets and over 2 million synthetic samples.
- Real-world challenges include social media compression degrading forensic traces, adversarial and laundering attacks evading detectors, active authentication via cryptographic signatures/BLS and JPEG Trust, and ethical/privacy risks alongside “Impostor Bias.”
Methods
- Design: review/position paper based on the FF4ALL project, extending previous work and providing a structured comparison of deepfake detection approaches, datasets, continual learning, explainability, attribution, passive/active authentication, and realistic scenarios.
- Data or sample: no new primary dataset or experiment is reported; the paper draws on cited state-of-the-art datasets and methods across image, audio, video, and multimodal modalities.
- Main analysis: narrative synthesis and tables (e.g., Table 1 on project topics, Table 3 comparing detection methods), identifying strengths, weaknesses, research gaps, and future directions.
Limitations
- The paper states that scalability, real-time applicability, and robustness in dynamic environments remain persistent challenges; many state-of-the-art techniques require high computational resources and extensive labeled datasets, suffer latency, and are vulnerable to adversarial/laundering attacks. It also notes the lack of universally accepted benchmarks, sensitivity to media compression, insufficient interpretability for legal/forensic use, and ethical/privacy concerns.
- The provided text makes evident that several sections are empty or truncated (e.g., Introduction, Conclusions, and some subsections), so not all details can be assessed from this version.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures




Verification
Claims the paper makes
9 Valid · 0 Not valid · 3 Not checked · 13 Own results and interpretations
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“ASVspoof 2019 [39,40] is a benchmark dataset for synthetic speech detection, containing both real and synthetic audio tracks from 78 speakers (33 male, 45 female) based on the VCTK corpus.”
§ Deepfake Media Forensics: Status and Future Challenges > 4. State-of-the-Art Deepfake Datasets > 4.2. Audio Datasets
What the sources say
- Supportedcites [39] Todisco, M., Wang, X., Vestman, V., Sahidullah, M., Delgado, H., Nautsch, A., Yamagishi, J., Evans, N., Kinnunen, T., and Lee, K.A. (2019, January 15–19). ASVspoof 2019: Future horizons in spoofed and fake audio detection. Proceedings of the International Speech Communication Association Conference (INTERSPEECH), Graz, Austria. source
Section 2 (p. 1) describes the ASVspoof 2019 database as VCTK-derived and lists disjoint training, development and evaluation sets of 20, 10 and 48 speakers—78 in total (33 male, 45 female). Section 2.1 (p. 1) says its logical-access database contains bona fide speech and spoofed speech generated using text-to-speech and voice-conversion systems. (LLM, conf=0.94)
- Partly supportedcites [40] Wang, 2020, ASVspoof 2019: A large-scale public database of synthesized, converted and replayed speech, Comput. Speech Lang. sourceExperimental — accuracy not yet measured
The Introduction (p. 2) describes ASVspoof 2019 as a dataset of bona fide and spoofed speech, including synthetic speech. But §2.1 (p. 3) says it uses utterances from 107 speakers (46 male, 61 female), not 78 speakers (33 male, 45 female). The reported 20 training, 10 development target, and 48 evaluation target speakers sum to 78, but exclude non-target speakers. (LLM, conf=0.90)
- Supported
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“DeepfakeTIMIT [48] is a video deepfake dataset derived from the VidTIMIT corpus [49], which consists of real audio–video recordings of 43 individuals, each reciting short sentences, resulting in a total of 430 videos.”
§ Deepfake Media Forensics: Status and Future Challenges > 4. State-of-the-Art Deepfake Datasets > 4.3. Video and Multimodal Datasets
What the sources say
- Supportedcites [48] Korshunov, P., and Marcel, S. (2018). Deepfakes: A new threat to face recognition? Assessment and detection. arXiv. source
The Introduction (p. 1) identifies this paper’s dataset as Deepfake videos generated from VidTIMIT. The Deepfake Database section (p. 2) says VidTIMIT has 10 videos for each of 43 subjects, so the citing sentence’s 430 videos refers to the original VidTIMIT corpus, not DeepfakeTIMIT. The Conclusion (p. 4) reports 620 Deepfake videos. (LLM, conf=0.91)
- Not matchedcites [49] Sanderson, C. (2025, January 15). The VidTIMIT database. Technical Report, IDIAP. Available online: https://www.google.com/url?sa=t&source=web&rct=j&opi=89978449&url=https://publications.idiap.ch/downloads/reports/2002/com02-06.pdf&ved=2ahUKEwid9vKeueWLAxVuvokEHTziMbQQFnoECBUQAQ&usg=AOvVaw0kiW0MZbBb8yeSzteosaGP.
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
- Supported
Every source the paper cites for this claim was checked and supports it.
In the paper
“ASVspoof 2021 [41] is an updated version of ASVspoof 2019, released for a subsequent challenge. It includes three evaluation partitions (LA, PA, and DF), with no new training or development data.”
§ Deepfake Media Forensics: Status and Future Challenges > 4. State-of-the-Art Deepfake Datasets > 4.2. Audio Datasets
What the sources say
- Supportedcites [41] Yamagishi, J., Wang, X., Todisco, M., Sahidullah, M., Patino, J., Nautsch, A., Liu, X., Lee, K.A., Kinnunen, T., and Evans, N. (2021, January 16). ASVspoof 2021: Accelerating progress in spoofed and deepfake speech detection. Proceedings of the Automatic Speaker Verification and Spoofing Countermeasures Challenge, Online. source
The Database section (p. 1) explicitly says ASVspoof 2021 has three new evaluation partitions for LA, PA, and DF, and that no new training or development data were released. It says participants were expected to use the ASVspoof 2019 training and development partitions instead. (LLM, conf=0.95)
- Supported
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“Traditional deep learning approaches assume that training and testing data share a static distribution, which is unrealistic in scenarios where new spoofing attacks emerge regularly [59].”
§ Deepfake Media Forensics: Status and Future Challenges > 5. Continual Learning for Deepfake Detection
What the sources say
- Partly supportedcites [59] Almutairi, Z., and Elgibreen, H. (2022). A Review of Modern Audio Deepfake Detection Methods: Challenges and Future Directions. Algorithms, 15. sourceExperimental — accuracy not yet measured
The Fake Audio Detection Methods table (p. 8) says one deep-learning model overfits synthetic data and cannot generalize to unknown attacks. The Introduction (p. 1) says emerging types of audio deepfake increase the detection challenge. The paper does not state that traditional deep learning assumes a static, shared training-and-testing distribution or that new attacks emerge regularly. (LLM, conf=0.83)
- Partly supported
Every source the paper cites for this claim was checked and supports it.
In the paper
“With over 3.6 million images (2.6 M fake and 1 M real), WildFake provides a comprehensive resource for training and evaluation.”
§ Deepfake Media Forensics: Status and Future Challenges > 4. State-of-the-Art Deepfake Datasets > 4.1. Image Datasets
What the sources say
- Supportedcites [33] Hong, Y., and Zhang, J. (2024). Wildfake: A large-scale challenging dataset for ai-generated images detection. arXiv. source
The Baseline Datasets and §3.3 passages report 3,694,313 images: 2,680,867 fake and 1,013,446 real. They also describe training and testing splits, supporting the cited description of WildFake as a resource for both purposes. (LLM, conf=0.94)
- Supported
20 more claims · 4 with their cited sources checked
Create a free account to see all 25 claims and every source verdict.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“The widespread availability of generative AI has increased the volume of images and videos produced and circulated through online platforms [1][2][3].”
From A Study on Broker-Assisted Blockchain Trust Chains for Provenance and Integrity Verification of Generative Media Using Watermarking, Semantic Fingerprinting, and C2PA (2026) · cites this paper as [2]
Experimental — accuracy not yet measured
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Each contradiction between two passages listed here was confirmed by an independent check.
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ Deepfake Media Forensics: Status and Future Challenges > Abstract
“a research project called FF4ALL (FF4ALL-Detection of Deep Fake Media and Life-Long Media Authentication)”
§ Deepfake Media Forensics: Status and Future Challenges > 11. Discussion > 11.2. Ff4ll’S Goals in Deepfake Detection and Media Authentication
“The FF4LL project is designed to address the evolving challenges of deepfake detection and media authenticity”
Citations
Cites
Deep Residual Learning for Image Recognition
He, K., Zhang, X., Ren, S., & Sun, J. (2016) · 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2016.90 · Cited by 235,474
Vaswani, A., Shazeer, N., Parmar, N., Uszkoreit, J., Jones, L., Gomez, A. N., Kaiser, L., & Polosukhin, I. (2017) · arXiv · doi:10.48550/arxiv.1706.03762 · Cited by 120,404
A Style-Based Generator Architecture for Generative Adversarial Networks
Karras, T., Laine, S., & Aila, T. (2019) · 2019 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2019.00453 · Cited by 11,714
Rudin, C. (2019) · Nature Machine Intelligence · doi:10.1038/s42256-019-0048-x · Cited by 10,561
Explaining and Harnessing Adversarial Examples
Goodfellow, I. J., Shlens, J., & Szegedy, C. (2014) · arXiv · doi:10.48550/arxiv.1412.6572 · Cited by 10,381
Denoising Diffusion Probabilistic Models
Ho, J., Jain, A., & Abbeel, P. (2020) · arXiv · doi:10.48550/arxiv.2006.11239 · Cited by 8,712
Intriguing properties of neural networks
Szegedy, C., Zaremba, W., Sutskever, I., Bruna, J., Erhan, D., Goodfellow, I., & Fergus, R. (2013) · arXiv · doi:10.48550/arxiv.1312.6199 · Cited by 8,143
Overcoming catastrophic forgetting in neural networks
Kirkpatrick, J., Pascanu, R., Rabinowitz, N., Veness, J., Desjardins, G., Rusu, A. A., Milan, K., Quan, J., Ramalho, T., Grabska-Barwinska, A., et al. (2017) · Proceedings of the National Academy of Sciences · doi:10.1073/pnas.1611835114 · Cited by 7,899
Towards Deep Learning Models Resistant to Adversarial Attacks
Madry, A., Makelov, A., Schmidt, L., Tsipras, D., & Vladu, A. (2017) · arXiv · doi:10.48550/arxiv.1706.06083 · Cited by 6,602
Analyzing and Improving the Image Quality of StyleGAN
Karras, T., Laine, S., Aittala, M., Hellsten, J., Lehtinen, J., & Aila, T. (2020) · 2020 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr42600.2020.00813 · Cited by 6,332
Research works printed but not linked: 9
- Goodfellow, I., Pouget-Abadie, J., Mirza, M., Xu, B., Warde-Farley, D., Ozair, S., Courville, A., and Bengio, Y. (2014). Generative Adversarial Nets. Adv. Neural Inf. Process. Syst., 27.
- Dolhansky, B., Bitton, J., Pflaum, B., Lu, J., Howes, R., Wang, M., and Ferrer, C.C. (2020). The deepfake detection challenge (DFDC) dataset. arXiv.
- Barrington, S., Bohacek, M., and Farid, H. (2024). DeepSpeak Dataset v1.0. arXiv.
- Kang, S., Shi, Z., and Zhang, X. (2023, January 23–29). Poisoning Generative Replay in Continual Learning to Promote Forgetting. Proceedings of the International Conference on Machine Learning, PMLR, Honolulu, HI, USA.
- Nguyen Le, T.D., Teh, K.K., and Dat Tran, H. (2024). Continuous Learning of Transformer-based Audio Deepfake Detection. arXiv.
- Zhang, X., Yi, J., and Tao, J. (2024). EVDA: Evolving Deepfake Audio Detection Continual Learning Benchmark. arXiv.
- National Research Council, Policy and Global Affairs, Division on Engineering and Physical Sciences, Committee on Science, Technology, and Law, Committee on Applied and Theoretical Statistics, and Committee on Identifying the Needs of the Forensic Sciences Community (2009). Strengthening Forensic Science in the United States: A path forward, National Academies Press.
- Koopman, M., Rodriguez, A.M., and Geradts, Z. (2018, January 29–31). Detection of DeepFake Video Manipulation. Proceedings of the Irish Machine Vision and Image Processing Conference (IMVIP), Belfast, Northern Ireland.
- Tsipras, D., Santurkar, S., Engstrom, L., and Turner, A. (2018). Robustness May Be at Odds with Accuracy. arXiv.
Cited by
Audio Deepfake Detection: What Has Been Achieved and What Lies Ahead
Zhang, B., Cui, H., Nguyen, V., & Whitty, M. (2025) · Sensors · doi:10.3390/s25071989 · Cited by 72
Furizal, F., Ma’arif, A., Maghfiroh, H., Suwarno, I., Prayogi, D., Kariyamin, K., Lonang, S., & Sharkawy, A. (2025) · Social Sciences & Humanities Open · doi:10.1016/j.ssaho.2025.101882 · Cited by 59
Generative AI and health misinformation: production, propagation, and mitigation—a systematic review
Saeidnia, H. R., Jahani, S., Ghiasi, N., & Keshavarz, H. (2026) · BMC Public Health · doi:10.1186/s12889-025-26148-9 · Cited by 43
Kumru, E., Ugurlu, G., Sevindik, М., Ekinci, F., Güzel, M. S., Açıcı, K., & Akata, İ. (2025) · Biology · doi:10.3390/biology14070816 · Cited by 15
Back-in-Time Diffusion: Unsupervised Detection of Medical Deepfakes
Grabovski, F. M., Yasur, L., Amit, G., & Mirsky, Y. (2025) · ACM Transactions on Intelligent Systems and Technology · doi:10.1145/3744656 · Cited by 19
Metadata
- Authors
- Amerini, I., Barni, M., Battiato, S., Bestagini, P., Boato, G., Bruni, V., Caldelli, R., De Natale, F., De Nicola, R., Guarnera, L., Mandelli, S., Majid, T., Marcialis, G. L., Micheletto, M., Montibeller, A., Orrù, G., Ortis, A., Perazzo, P., Puglisi, G., Purnekar, N., Salvi, D., Tubaro, S., Villari, M., & Vitulano, D.
- Affiliations
- Sapienza University of Rome (IT)
- University of Siena (IT)
- University of Catania (IT)
- Politecnico di Milano (IT)
- University of Trento (IT)
- Consorzio Nazionale Interuniversitario per le Telecomunicazioni (IT)
- Department of Information Engineering and Computer Science, University of Trento, 38123 Trento, Italy
- IMT School for Advanced Studies, 55100 Lucca, Italy
- Department of Computer, Control and Management Engineering, Sapienza University of Rome, 00185 Roma, Italy
- University of Cagliari (IT)
- University of Pisa (IT)
- University of Messina (IT)
- Corresponding author
- Guarnera, Luca
- ORCID
- Amerini, Irene
- Barni, Mauro
- Battiato, Sebastiano
- Bestagini, Paolo
- Boato, Giulia
- Bruni, Vittoria
- Caldelli, Roberto
- De Natale, Francesco
- De Nicola, Rocco
- Guarnera, Luca
- Mandelli, Sara
- Majid, Taiba
- Marcialis, Gian Luca
- Micheletto, Marco
- Montibeller, Andrea
- Orrù, Giulia
- Ortis, Alessandro
- Perazzo, Pericle
- Puglisi, Giovanni
- Purnekar, Nischay
- Salvi, Davide
- Tubaro, Stefano
- Villari, Massimo
- Vitulano, Domenico
- Venue
- Journal of Imaging
- Publisher
- MDPI AG
- Published
- 2025-02-28
- Volume
- 11
- Issue
- 3
- Pages
- 73
- ISSN
- 2313-433X (ISSN-L)
- PMC
- PMC11943306
- OpenAlex
- W4408054937
- Cited by
- 113
- References
- 197
- Citations by year
- 2026: 68 · 2025: 45
- FWCI
- 39.26
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Licence
- Locations
- Journal of Imaging (publishedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- Use Siena air (University of Siena) (submittedVersion, cc-by)
- CINECA IRIS Institutial research information system (University of Pisa) (submittedVersion)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion)
- UNICA IRIS Institutional Research Information System (University of Cagliari) (submittedVersion, other-oa)
- IRIS Research product catalog (Sapienza University of Rome) (submittedVersion, cc-by)
- Iris (University of Trento) (submittedVersion, cc-by)
- Funders
- SERICS (PE00000014)
- European Union—NextGenerationEU (PE00000014)
- Topics
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Digital Media Forensic Detection
- Social Sciences › Sociology and Political Science › Misinformation and Its Impacts
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Advanced Steganography and Watermarking Techniques
- Keywords
- deepfake detection, synthetic media, generative adversarial networks, diffusion models, media authentication, passive authentication, continuous authentication, media integrity
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
The claim verdicts this report counts are experimental: their accuracy is not yet measured.
A language model drew the claims from the paper on 2026-09-26 (prompt extract-v2).
Cited sources are checked with a language model’s help (gpt-6-sol).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
How to cite
Cite CoChat for the checks on this page, and the paper for its own findings.
- This page
- CoChat. (2026). Citation check: Deepfake Media Forensics: Status and Future Challenges. https://app.cochat.ai/papers/10.3390/jimaging11030073
- The paper
- Amerini, I., Barni, M., Battiato, S., Bestagini, P., Boato, G., Bruni, V., Caldelli, R., De Natale, F., De Nicola, R., Guarnera, L., Mandelli, S., Majid, T., Marcialis, G. L., Micheletto, M., Montibeller, A., Orrù, G., Ortis, A., Perazzo, P., Puglisi, G., . . . Vitulano, D. (2025). Deepfake Media Forensics: Status and Future Challenges. Journal of Imaging. https://doi.org/10.3390/jimaging11030073
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
