

The DOI matches its Crossref record; 44 of the 44 references it cites were found in a registry or an index; 2 of the 6 sources its claims cite were checked for support.
A High-Precision Vehicle Detection and Tracking Method Based on the Attention Mechanism
Open accessAbstract
Vehicle detection and tracking technology plays an important role in intelligent transportation management and control systems. This paper proposes a novel vehicle detection and tracking method for small target vehicles to achieve high detection and tracking accuracy based on the attention mechanism. We first develop a new vehicle detection model (YOLOv5-NAM) by adding the normalization-based attention module (NAM) to the classical YOLOv5s model. By exploiting the YOLOv5-NAM model as the vehicle detector, we then propose a real-time small target vehicle tracking method (JDE-YN), where the feature extraction process is embedded in the prediction head for joint training. Finally, we present extensive experimental results to verify our method on the UA-DETRAC dataset and to demonstrate that the method can effectively detect small target vehicles in real time. It is shown that compared with the original YOLOv5s model, the mAP value of the YOLOv5-NAM vehicle detection model is improved by 1.6%, while the MOTA value of the JDE-YN method improved by 0.9% compared with the original JDE method.
Overview
CoChat Summary
## TL;DR
This paper proposes a vehicle detection-and-tracking pipeline for small targets by adding a normalization-based attention module to YOLOv5s and combining it with a joint detection/tracking method. On UA-DETRAC, the authors report that detection mAP improves by 1.6%, tracking MOTA improves by 0.9%, and vehicle identity switches drop by 15%.
## Key findings
- The proposed YOLOv5-NAM detector improves mAP over YOLOv5s by 1.6% overall on UA-DETRAC; the paper also reports 1.4% improvement from NAM alone and 0.2% more from SD-NMS.
- For single-class detection on UA-DETRAC, the paper reports AP gains of 0.3% for cars, 2.7% for buses, 3.6% for other vehicles, while vans slightly decreased; with both NAM and SD-NMS, overall mAP improved by 1.6%.
- The proposed JDE-YN tracking method improves MOTA by 0.9% compared with the original JDE method, and the paper says vehicle identity switching times decrease by 15%.
- The paper reports the model after adding NAM increases network layers from 213 to 219 and model size from 13.7 M to 13.9 M, while FPS decreases by 0.4; replacing NMS with SD-NMS lowers FPS by 3 for YOLOv5s and 2.8 for YOLOv5-NAM.
## Methods
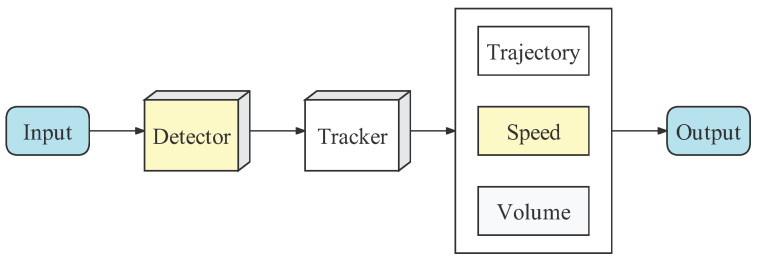
- The paper uses a detection + tracking system model: YOLOv5-based vehicle detector plus a tracker built around Kalman filter state estimation and data association.
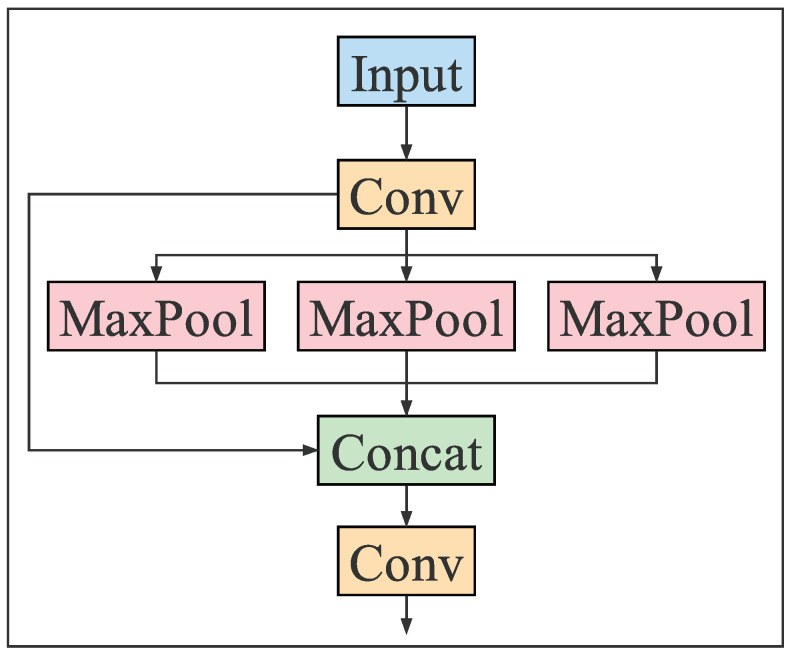
- For detection, it modifies YOLOv5s by adding the NAM attention module to the Neck, uses CIoU_Loss instead of GIoU_Loss, and proposes Soft-DIoU NMS (SD-NMS).
- For tracking, it proposes JDE-YN, embedding appearance feature extraction into the detection head and using a cascade matching algorithm based on direction correction.
- Experiments are run on UA-DETRAC; the paper states it selects 16,542 train images / 102,562 labels and 11,235 test images / 86,559 labels for detection experiments, and for tracking uses 60 video sequences for training and 40 for testing.
## Limitations
- The paper states the dataset is challenging because UA-DETRAC includes multiple weather conditions and vehicles of different scales, which keeps MOTA and MOTP low (between 0.3 and 0.4).
- It explicitly notes a tradeoff: the proposed method improves accuracy but can reduce speed, e.g. FPS drops when adding NAM or SD-NMS. This is stated in the paper.
- Evident from the text: the reported improvements are demonstrated mainly on UA-DETRAC, with a secondary COCO2017 retraining check; broader generalization beyond these datasets is not established in the provided text.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures




Verification
Claims the paper makes
2 Valid · 2 Not valid · 4 Not checked · 45 Own results and interpretations
Every source the paper cites for this claim was checked and supports it.
In the paper
“the NAM attention module chooses the weight of the image channel and spatial information as a measure of image characteristics of significance, through a normalized scaling factor to represent the importance of the weight, and suppress the unimportant channel information and pixel information in the image.”
§ A High-Precision Vehicle Detection and Tracking Method Based on the Attention Mechanism > 3. Vehicle Detection and Tracking Method > 3.1. The YOLOv5-NAM Vehicle Detection Model
What the sources say
- Supportedcites [39] Liu, Y., Shao, Z., Teng, Y., and Hoffmann, N. (2021). NAM: Normalization-based Attention Module. arXiv. source
The Introduction (p. 1) says NAM aims to suppress insignificant channels or pixels. The Methodology (p. 2) describes normalization-based scaling factors that measure the importance of channels and pixels, supporting the cited sentence's explanation. (LLM, conf=0.93)
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Supported
Every source the paper cites for this claim was checked and supports it.
In the paper
“As an extension of the CBAM attention module, NAM is a lightweight and efficient new attention module achieved by redesigning the channel and spatial attention submodule based on normalization technology [39].”
§ A High-Precision Vehicle Detection and Tracking Method Based on the Attention Mechanism > 3. Vehicle Detection and Tracking Method > 3.1. The YOLOv5-NAM Vehicle Detection Model
What the sources say
- Supportedcites [39] Liu, Y., Shao, Z., Teng, Y., and Hoffmann, N. (2021). NAM: Normalization-based Attention Module. arXiv. source
The Methodology (p. 2) calls NAM an efficient, lightweight attention mechanism that adopts CBAM’s module integration and redesigns its channel and spatial attention submodules using normalization scaling factors. The Introduction (p. 1) explains that this approach avoids adding fully connected and convolutional layers. (LLM, conf=0.95)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Supported
A result the paper states — it cites no source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The inter-class similarity and the intra-class difference between the vehicles will lead to the failure of vehicle data association and also vehicle identity switching when the vehicles occlude each other during the driving process.”
§ A High-Precision Vehicle Detection and Tracking Method Based on the Attention Mechanism > 3. Vehicle Detection and Tracking Method > 3.5. The Cascade Matching Algorithm Based on Direction Correction
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper states — it cites no source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“our proposed method obtained the identity of the switching times at least”
§ A High-Precision Vehicle Detection and Tracking Method Based on the Attention Mechanism > 4. Detection and Tracking Experience Results > 4.3. Tracking Results on UA-DETRAC
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“When we use the CIoU_Loss to replace the GIoU_Loss, the YOLOv5s and YOlOv5-NAM models’ mAP values increase by 0.2% and 0.3%, respectively.”
§ A High-Precision Vehicle Detection and Tracking Method Based on the Attention Mechanism > 4. Detection and Tracking Experience Results > 4.1. Detection Results on UA-DETRAC
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
19 more claims
Create a free account to see all 53 claims and to verify the 1 reference still open.
- It may state two separate claims as one. 22
- The quote only partly states this claim. 1
- Probably not a substantial claim. 8
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Each contradiction between two passages listed here was confirmed by an independent check.
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ A High-Precision Vehicle Detection and Tracking Method Based on the Attention Mechanism > Abstract
“It is shown that compared with the original YOLOv5s model, the mAP value of the YOLOv5-NAM vehicle detection model is improved by 1.6%,”
§ A High-Precision Vehicle Detection and Tracking Method Based on the Attention Mechanism > 4. Detection and Tracking Experience Results > 4.1. Detection Results on UA-DETRAC
“According to the Table, after adding the NAM attention mechanism into the original YOLOv5s model, the overall mAP value of the model increases by 1.4%.”
Citations
Cites
Faster R-CNN: Towards Real-Time Object Detection with Region Proposal Networks
Ren, S., He, K., Girshick, R., & Sun, J. (2017) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2016.2577031 · Cited by 73,472 · cited 4×
“Twostage vehicle detection methods such as Cascade R-CNN [22], Faster R-CNN [23], Mask RCNN [24], R-FCN [25], and SPP-Net [26] first extract the candidate regions of the vehicle in the image and then send them into the CNN model for feature extraction and classification.”
MethodInfluentialYou Only Look Once: Unified, Real-Time Object Detection
Redmon, J., Divvala, S., Girshick, R., & Farhadi, A. (2016) · 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2016.91 · Cited by 53,803 · cited 3×
“Based on the initial version of YOLO in [20], several algorithms including YOLOv2 [27], YOLOv3 [28], YOLOv4 [29], and YOLOv5 [30] were continuously developed to further improve the classification accuracy.”
MethodA New Approach to Linear Filtering and Prediction Problems
Kalman, R. E. (1960) · Journal of Basic Engineering · doi:10.1115/1.3662552 · Cited by 31,751
(2016) · Cited by 31,590
He, K., Gkioxari, G., Dollar, P., & Girshick, R. (2017) · 2017 IEEE International Conference on Computer Vision (ICCV) · doi:10.1109/iccv.2017.322 · Cited by 29,137
SSD: Single Shot MultiBox Detector
Liu, W., Anguelov, D., Erhan, D., Szegedy, C., Reed, S., Fu, C.-Y., & Berg, A. C. (2016) · Lecture Notes in Computer Science · doi:10.1007/978-3-319-46448-0_2 · Cited by 22,128 · cited 3×
“From Table 5, the AP value of our proposed method is higher than some classical object detection algorithms such as Faster R-CNN, SSD, and YOLOv3, and slightly lower than the RetainNet and CenterNet algorithms.”
MethodInfluentialYOLO9000: Better, Faster, Stronger
Redmon, J., & Farhadi, A. (2017) · 2017 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2017.690 · Cited by 19,892 · cited 1×
“Based on the initial version of YOLO in [20], several algorithms including YOLOv2 [27], YOLOv3 [28], YOLOv4 [29], and YOLOv5 [30] were continuously developed to further improve the classification accuracy.”
MethodYOLOv3: An Incremental Improvement
Redmon, J., & Farhadi, A. (2018) · arXiv · doi:10.48550/arxiv.1804.02767 · Cited by 17,141
Spatial Pyramid Pooling in Deep Convolutional Networks for Visual Recognition
He, K., Zhang, X., Ren, S., & Sun, J. (2015) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2015.2389824 · Cited by 11,971
YOLOv4: Optimal Speed and Accuracy of Object Detection
Bochkovskiy, A., Wang, C.-Y., & Liao, H.-Y. M. (2020) · arXiv · doi:10.48550/arxiv.2004.10934 · Cited by 10,307
Cited by
Bakırcı, M. (2024) · Applied Soft Computing · doi:10.1016/j.asoc.2024.112015 · Cited by 170
Bakırcı, M. (2024) · Digital Signal Processing · doi:10.1016/j.dsp.2024.104594 · Cited by 113
Jain, D. K., Zhao, X., Gan, C., Shukla, P. K., Jain, A., & Sharma, S. (2024) · Information Fusion · doi:10.1016/j.inffus.2024.102429 · Cited by 50
Multi-Object Vehicle Detection and Tracking Algorithm Based on Improved YOLOv8 and ByteTrack
You, L., Chen, Y., Xiao, C., Sun, C., & Li, R. (2024) · Electronics · doi:10.3390/electronics13153033 · Cited by 42
Semantic Segmentation and YOLO Detector over Aerial Vehicle Images
Qureshi, A. M. (2024) · Computers, materials & continua/Computers, materials & continua (Print) · doi:10.32604/cmc.2024.052582 · Cited by 65
Metadata
- Authors
- Wang, J., Dong, Y., Zhao, S., & Zhang, Z.
- Affiliations
- Xidian University (CN)
- Corresponding author
- Zhao, Shuangrui
- Venue
- Sensors
- Publisher
- MDPI AG
- Published
- 2023-01-08
- Volume
- 23
- Issue
- 2
- Pages
- 724
- ISSN
- 1424-8220 (ISSN-L)
- PMC
- PMC9863854
- OpenAlex
- W4313894539
- Cited by
- 60
- References
- 44
- Citations by year
- 2026: 6 · 2025: 16 · 2024: 26 · 2023: 12
- FWCI
- 5.42
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Licence
- Locations
- Sensors (publishedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion, cc-by-sa)
- Funders
- National Key R/D Program of China (2018YFE0207600, 61972308, 2019JC-17)
- Natural Science Foundation of China (NSFC) (2018YFE0207600, 61972308, 2019JC-17)
- Natural Science Basic Research Program of Shaanxi (2018YFE0207600, 61972308, 2019JC-17)
- Topics
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Video Surveillance and Tracking Methods
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Advanced Neural Network Applications
- Physical Sciences › Engineering › Automotive Engineering › Autonomous Vehicle Technology and Safety
- Keywords
- vehicle detection, vehicle tracking, small object detection, attention mechanism, YOLOv5, real-time tracking, intelligent transportation management, UA-DETRAC
- MeSH terms
- Intelligence, Technology, Transportation
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
A language model drew the claims from the paper on 2026-10-10, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-10-10 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Cited sources are checked with a language model’s help (gpt-6-sol).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
How to cite
Cite CoChat for the checks on this page, and the paper for its own findings.
- This page
- CoChat. (2026). Citation check: A High-Precision Vehicle Detection and Tracking Method Based on the Attention Mechanism. https://app.cochat.ai/papers/10.3390/s23020724
- The paper
- Wang, J., Dong, Y., Zhao, S., & Zhang, Z. (2023). A High-Precision Vehicle Detection and Tracking Method Based on the Attention Mechanism. Sensors. https://doi.org/10.3390/s23020724
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
