

Effective Techniques for Multimodal Data Fusion: A Comparative Analysis
Open accessThe DOI matches its Crossref record; 31 of the 31 references it cites were found in a registry or an index.
Abstract
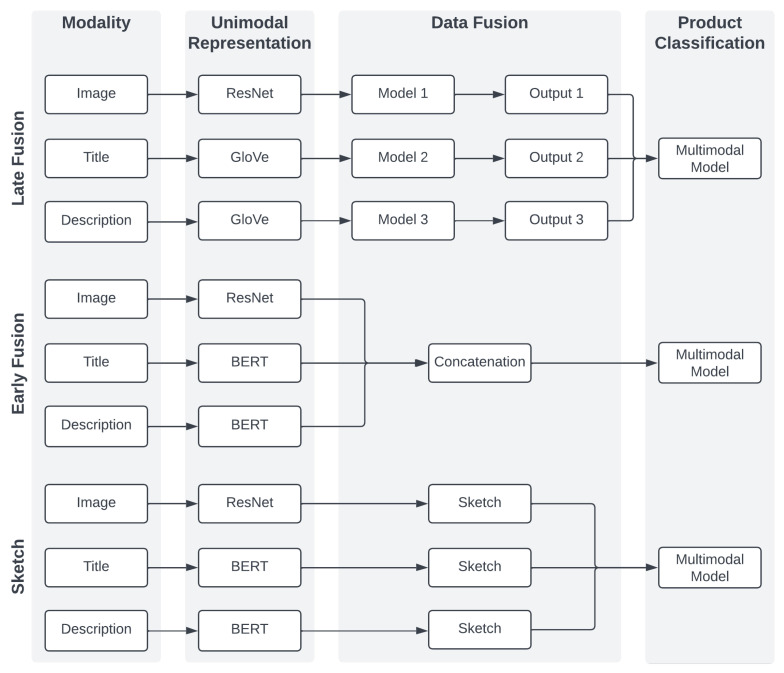
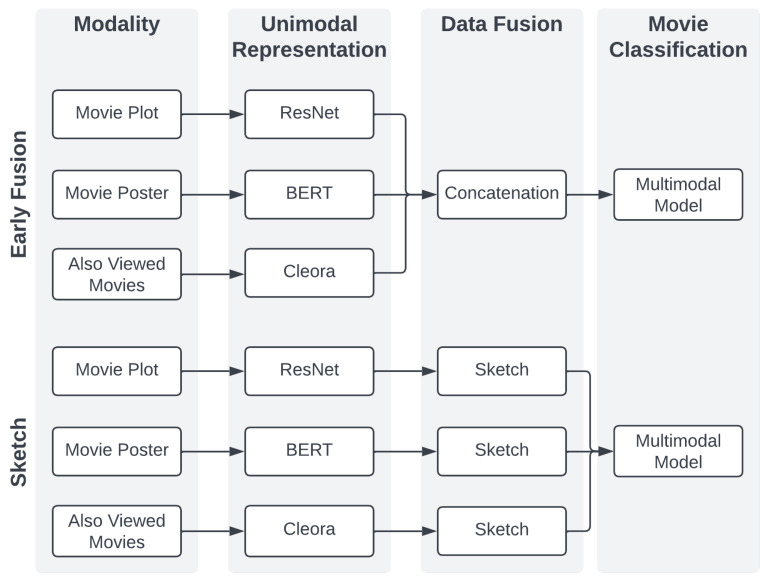
Data processing in robotics is currently challenged by the effective building of multimodal and common representations. Tremendous volumes of raw data are available and their smart management is the core concept of multimodal learning in a new paradigm for data fusion. Although several techniques for building multimodal representations have been proven successful, they have not yet been analyzed and compared in a given production setting. This paper explored three of the most common techniques, (1) the late fusion, (2) the early fusion, and (3) the sketch, and compared them in classification tasks. Our paper explored different types of data (modalities) that could be gathered by sensors serving a wide range of sensor applications. Our experiments were conducted on Amazon Reviews, MovieLens25M, and Movie-Lens1M datasets. Their outcomes allowed us to confirm that the choice of fusion technique for building multimodal representation is crucial to obtain the highest possible model performance resulting from the proper modality combination. Consequently, we designed criteria for choosing this optimal data fusion technique.
Overview
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Integrity signals
Registry
Cites
Statistics
Figures

Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The cited source says what the claim attributes to it.
In the citing paper
“the choice of fusion strategy is now recognized as a critical component of model design rather than a secondary implementation detail [7].”
From Benchmarking Multimodal Deep Fusion Strategies for Heterogeneous Neuroimaging and Cognitive Data Using a Controlled Sex Classification Task (2026) · cites this paper as [7]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Deep Residual Learning for Image Recognition
He, K., Zhang, X., Ren, S., & Sun, J. (2016) · 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2016.90 · Cited by 235,474 · cited 1×
“The problem of unimodal representation has already been solved with modality-dedicated models, such as BERT [17] for textual data, ResNet [18] for images, etc.”
MethodBERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2018) · arXiv · doi:10.48550/arxiv.1810.04805 · Cited by 73,173
Representation Learning: A Review and New Perspectives
Bengio, Y., Courville, A., & Vincent, P. (2013) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2013.50 · Cited by 13,001 · cited 1×
“Bengio et al. [19] characterized several features that an appropriate vector representation should possess, including: • Smoothness: a transformation should preserve objects similarities,expressed mathe-matically as x ≈ y ⇒ f ( x ) ≈ f ( y ) .”
BackgroundThe MovieLens Datasets: History and Context
Harper, F. M., & Konstan, J. A. (2016) · ACM Transactions on Interactive Intelligent Systems · doi:10.1145/2827872 · Cited by 6,627 · cited 1×
“We conduct experiments on three datasets, Amazon Reviews [7], MovieLens25M, and MovieLens1M [8].”
MethodMultimodal Machine Learning: A Survey and Taxonomy
Baltrusaitis, T., Ahuja, C., & Morency, L.-P. (2019) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2018.2798607 · Cited by 5,018
GLUE: A Multi-Task Benchmark and Analysis Platform for Natural Language Understanding
Wang, A., Singh, A., Michael, J., Hill, F., Levy, O., & Bowman, S. (2018) · Proceedings of the 2018 EMNLP Workshop BlackboxNLP: Analyzing and Interpreting Neural Networks for NLP · doi:10.18653/v1/w18-5446 · Cited by 4,222 · cited 1×
“Designing a multimodal benchmark, similar to GLUE [29] for NLP applications, is crucial for establishing the standards of multimodal representation research.”
BackgroundMultimodal Learning with Deep Boltzmann Machines
Srivastava, N., & Salakhutdinov, R. (2012) · Journal of Machine Learning Research · doi:10.5555/2627435.2697059 · Cited by 1,807 · cited 1×
“[20] identifies more factors that should be taken into account: (1) the similarity between individual modalities should be preserved in their joint representation and (2) robustness to the absence of some modalities; it should still be possible to create multimodal embedding.”
BackgroundHe, R., & McAuley, J. (2016) · Proceedings of the 25th International Conference on World Wide Web · doi:10.1145/2872427.2883037 · Cited by 1,459 · cited 1×
“We conduct experiments on three datasets, Amazon Reviews [7], MovieLens25M, and MovieLens1M [8].”
MethodA survey on deep learning for multimodal data fusion
Gao, J., Li, P., Chen, Z., & Zhang, J. (2020) · Neural Computation · doi:10.1162/neco_a_01273 · Cited by 821 · cited 7×
“A few issues should be taken into account [4] when it comes to fusing several modalities:”
BackgroundMethodInfluentialGandhi, A., Adhvaryu, K., Poria, S., Cambria, E., & Hussain, A. (2023) · Information Fusion · doi:10.1016/j.inffus.2022.09.025 · Cited by 783 · cited 1×
“Furthermore, modalities might naturally coexist, and the analyzed machine learning (ML) problem cannot be solved unless all modalities are considered [5].”
BackgroundMultimodal deep learning for biomedical data fusion: a review
Stahlschmidt, S. R., Ulfenborg, B., & Synnergren, J. (2022) · Briefings in Bioinformatics · doi:10.1093/bib/bbab569 · Cited by 766
Towards VQA Models That Can Read
Singh, A., Natarajan, V., Shah, M., Jiang, Y., Chen, X., Batra, D., Parikh, D., & Rohrbach, M. (2019) · 2019 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2019.00851 · Cited by 711 · cited 2×
“Text and images [13] Question answering based on images containing some textual data.”
BackgroundBayoudh, K., Knani, R., Hamdaoui, F., & Mtibaa, A. (2022) · The Visual Computer · doi:10.1007/s00371-021-02166-7 · Cited by 456 · cited 1×
“According to [24], the best approach is based on deep learning; the challenge is modality fusion.”
BackgroundAdvances in multimodal data fusion in neuroimaging: Overview, challenges, and novel orientation
Zhang, Y.-D., Dong, Z., Wang, S.-H., Yu, X., Yao, X., Zhou, Q., Hu, H., Li, M., Jiménez-Mesa, C., Ramirez, J., et al. (2020) · Information Fusion · doi:10.1016/j.inffus.2020.07.006 · Cited by 453 · cited 1×
“For instance, recent research on biomedical applications [31,32] exposed the limitations and strengths of existing multimodal fusion strategies.”
BackgroundDeep multimodal fusion for semantic image segmentation: A survey
Zhang, Y., Sidibé, D., Morel, O., & Mériaudeau, F. (2021) · Image and Vision Computing · doi:10.1016/j.imavis.2020.104042 · Cited by 261 · cited 1×
“Additionally, in [10], the authors concentrated on the image segmentation task to learn the optimal joint representation from rich and complementary features of the same scene based on images retrieved from different sensors.”
El-Sappagh, S., Abuhmed, T., Riazul Islam, S. M., & Kwak, K. S. (2020) · Neurocomputing · doi:10.1016/j.neucom.2020.05.087 · Cited by 229 · cited 1×
“Images, time series, and tabular [11] Prediction of Alzheimer’s disease based on magnetic resonance imaging and positron emission tomography (images) that are performed multiple times on one patient within specified periods of time (time series).”
BackgroundIntegration of acoustic and visual speech signals using neural networks
Yuhas, B. P., Goldstein, M. H., & Sejnowski, T. J. (1989) · IEEE Communications Magazine · doi:10.1109/35.41402 · Cited by 209 · cited 1×
“In one of the first papers on the subject [1], the authors demonstrated that acoustic and visual data could be successfully combined in a speech recognition sensor system.”
BackgroundEfficient Large-Scale Multi-Modal Classification
Kiela, D., Grave, E., Joulin, A., & Mikolov, T. (2018) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v32i1.11945 · Cited by 177
A Review of Multisensor Data Fusion Solutions in Smart Manufacturing: Systems and Trends
Tsanousa, A., Bektsis, E., Kyriakopoulos, C. A., González, A. G., Leturiondo, U., Gialampoukidis, I., Καρακώστας, Α., Vrochidis, S., & Kompatsiaris, I. Y. (2022) · Sensors · doi:10.3390/s22051734 · Cited by 156 · cited 1×
“Finally, recent improvements in multisensor solutions [6] have offered high-quality modalities, which require an appropriate fusion technique to fit to the ML problem.”
Multimodal Classification: Current Landscape, Taxonomy and Future Directions
Sleeman, W. C., Kapoor, R., & Ghosh, P. (2023) · ACM Computing Surveys · doi:10.1145/3543848 · Cited by 124 · cited 1×
“Multimodal interpretability is the process of understanding multimodal deep neural nets [33,34].”
BackgroundMultiBench: Multiscale Benchmarks for Multimodal Representation Learning
Liang, P. P., Lyu, Y., Fan, X., Wu, Z., Cheng, Y., Wu, J., Chen, L., Wu, P., Lee, M. A., Zhu, Y., et al. (2021) · arXiv · doi:10.48550/arxiv.2107.07502 · Cited by 85 · cited 1×
“Multi-bench [30] could be considered a promising candidate for such a benchmark.”
Cornac: A Comparative Framework for Multimodal Recommender Systems
Salah, A., Truong, Q., & Lauw, H. W. (2020) · Singapore Management University Institutional Knowledge (InK) (Singapore Management University) · doi:10.25440/smu.14256614.v1 · Cited by 73
MuSE: a Multimodal Dataset of Stressed Emotion
Jaiswal, M., Bara, C.-P., Luo, Y., Burzo, M. G., Mihalcea, R. F., & Provost, E. M. (2020) · Language Resources and Evaluation · Cited by 70
Multimodal Classification Fusion in Real-World Scenarios
Gallo, I., Calefati, A., & Nawaz, S. (2017) · IAPR International Conference on Document Analysis and Recognition (ICDAR) · doi:10.1109/icdar.2017.326 · Cited by 64 · cited 3×
“Classically, the existing multimodal representation techniques are divided into two categories [2,22]: early (feature) and late (decision) fusion.”
BackgroundA Review of Hashing Methods for Multimodal Retrieval
Cao, W., Feng, W., Lin, Q., Cao, G., & He, Z. (2020) · IEEE Access · doi:10.1109/access.2020.2968154 · Cited by 40 · cited 3×
“The main advantages [3] of hashing methods are that they (1) are cost-effective in terms of memory usage, (2) detect and work within manifolds, (3) preserve semantic similarities between points, (4) are usually data-independent, and (5) are suitable for production cases as they are robust to any data changes.”
BackgroundFoundations and Trends in Multimodal Machine Learning: Principles, Challenges, and Open Questions
Liang, P. P., Zadeh, A., & Morency, L.-P. (2022) · arXiv · doi:10.48550/arxiv.2209.03430 · Cited by 38
Vision-and-Language or Vision-for-Language? On Cross-Modal Influence in Multimodal Transformers
Frank, S., Bugliarello, E., & Elliott, D. (2021) · Proceedings of the 2021 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/2021.emnlp-main.775 · Cited by 35 · cited 2×
“No reasonable conclusions can be drawn from data unless all their modalities are joined [21]; • Missing data: for some cases, particular modalities might not be available.”
A Comparative Study of Outfit Recommendation Methods with a Focus on Attention-based Fusion
Laenen, K., & Moens, M. (2020) · Information Processing & Management · doi:10.1016/j.ipm.2020.102316 · Cited by 33
An Efficient Manifold Density Estimator for All Recommendation Systems
Dąbrowski, J., Rychalska, B., Daniluk, M., Basaj, D., Gołuchowski, K., Bąbel, P., Michałowski, A., & Jakubowski, A. (2021) · Lecture notes in computer science · doi:10.1007/978-3-030-92273-3_27 · Cited by 23
Cleora: A Simple, Strong and Scalable Graph Embedding Scheme
Rychalska, B., Bąbel, P., Gołuchowski, K., Michałowski, A., Dąbrowski, J., & Biecek, P. (2021) · Lecture notes in computer science · doi:10.1007/978-3-030-92273-3_28 · Cited by 20
A benchmarking study of classification techniques for behavioral data
Cnudde, S. D., Martens, D., Evgeniou, T., & Provost, F. J. (2019) · International Journal of Data Science and Analytics · doi:10.1007/s41060-019-00185-1 · Cited by 18 · cited 1×
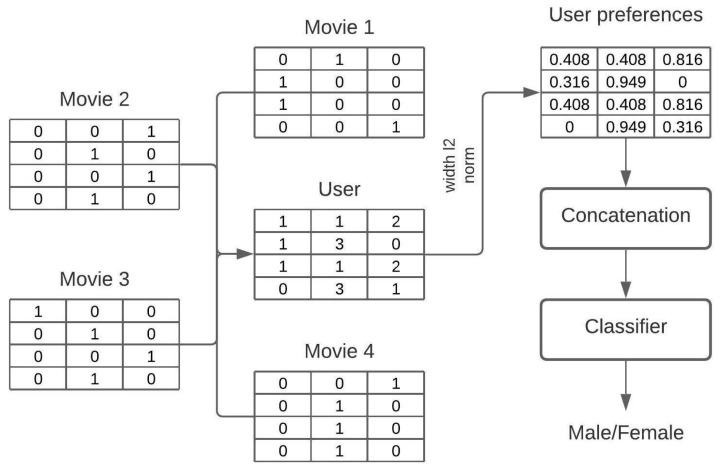
“To date, the existing approaches [28] have considered only the behavioral data, which in the case of MovieLens1M is present as ratings that users give to movies.”
Background
Research works printed but not linked: 3
- Varshney, K. (2021, March 23). Trust in Machine Learning, Manning Publications, Shelter Island, Chapter 4 Data Sources and Biases, Section 4.1 Modalities. Available online: https://livebook.manning.com/book/trust-in-machine-learning/chapter-4/v-2/.
- Rychalska, B., Basaj, D.B., Dabrowski, J., and Daniluk, M. (2020). I know why you like this movie: Interpretable Efficient Multimodal Recommender. arXiv.
- Wirojwatanakul, P., and Wangperawong, A. (2019). Multi-Label Product Categorization Using Multi-Modal Fusion Models. arXiv.
Cited by
A Comprehensive Survey on Deep Learning Multi-Modal Fusion: Methods, Technologies and Applications
Jiao, T., Guo, C., Feng, X., Chen, Y., & Song, J. (2024) · Computers, Materials & Continua · doi:10.32604/cmc.2024.053204 · Cited by 158
Fraiwan, M., & Khasawneh, N. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2305.00237 · Cited by 56
“Another approach is to use multimodal fusion techniques to combine the outputs of separate models trained on different modalities [63].”
BackgroundDeep Learning in Multimodal Fusion for Sustainable Plant Care: A Comprehensive Review
Yang, Z., Li, Y., Wang, R.-F., Hu, P., & Su, W. (2025) · Sustainability · doi:10.3390/su17125255 · Cited by 115
A Comparative Analysis of Early and Late Fusion for the Multimodal Two-Class Problem
Pereira, L. M., Salazar, A., & Vergara, L. (2023) · IEEE Access · doi:10.1109/access.2023.3296098 · Cited by 69
“Sofar, there exists some research comparing early and late fusion [10], [11], [12], [13], [14], [15], [16], [17].”
BackgroundDigital twin systems for musculoskeletal applications: A current concepts review
Diniz, P., Grimm, B., Garcia, F., Fayad, J., Ley, C., Mouton, C., Oeding, J. F., Hirschmann, M. T., Samuelsson, K., & Seil, R. (2025) · Knee Surgery, Sports Traumatology, Arthroscopy · doi:10.1002/ksa.12627 · Cited by 100
Metadata
- Authors
- Pawłowski, M., Wróblewska, A., & Sysko-Romańczuk, S.
- Affiliations
- Warsaw University of Technology (PL)
- Corresponding author
- Pawłowski, Maciej
- Wróblewska, Anna
- Venue
- Sensors
- Publisher
- MDPI AG
- Published
- 2023-02-21
- Volume
- 23
- Issue
- 5
- Pages
- 2381
- ISSN
- 1424-8220 (ISSN-L)
- PMC
- PMC10007548
- OpenAlex
- W4321497840
- Cited by
- 180
- References
- 30
- Citations by year
- 2026: 50 · 2025: 94 · 2024: 30 · 2023: 6
- FWCI
- 16.31
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Licence
- Locations
- Sensors (publishedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- arXiv (Cornell University) (submittedVersion)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion, cc-by-sa)
- arXiv (Cornell University) (cc-by)
- Funders
- Centre for Priority Research Area Artificial Intelligence and Robotics of Warsaw University of Technology within the Excellence Initiative: Research University (IDUB) programme (1820/27/Z01/POB2/2021, POIR.01.01.01-00-0066/22)
- National Centre for Research and Development in Poland, Smart Growth Operational Program for 2014-2020, Digital Innovations (1820/27/Z01/POB2/2021, POIR.01.01.01-00-0066/22)
- Topics
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Multimodal Machine Learning Applications
- Physical Sciences › Engineering › Media Technology › Advanced Image Fusion Techniques
- Social Sciences › Psychology › Experimental and Cognitive Psychology › Multisensory perception and integration
- Keywords
- multimodal fusion, decision fusion, feature-level fusion, multimodal representation learning, classification, sensor data, recommender systems, Amazon reviews, MovieLens
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
