

The DOI matches its DataCite record; 28 of the 29 references it cites were found in a registry or an index, and 1 are not checked yet.
Differentiate ChatGPT-generated and Human-written Medical Texts
Open accessAbstract
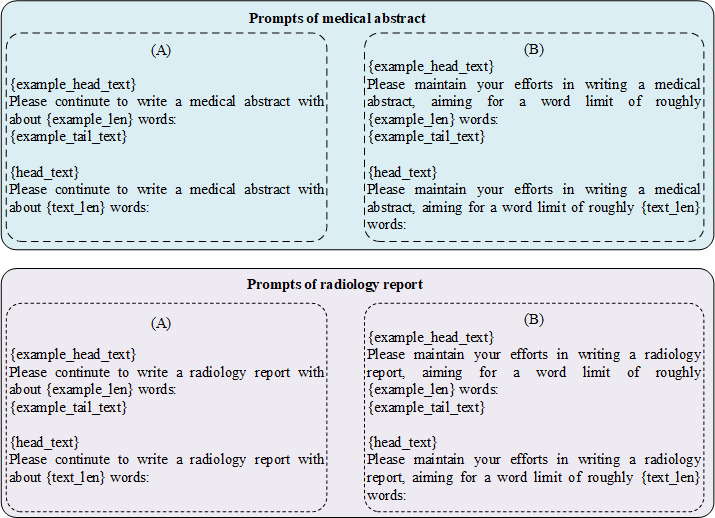
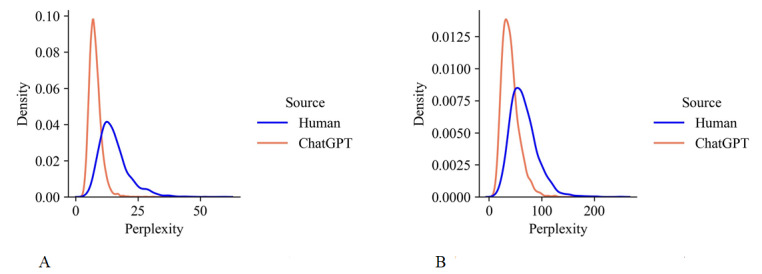
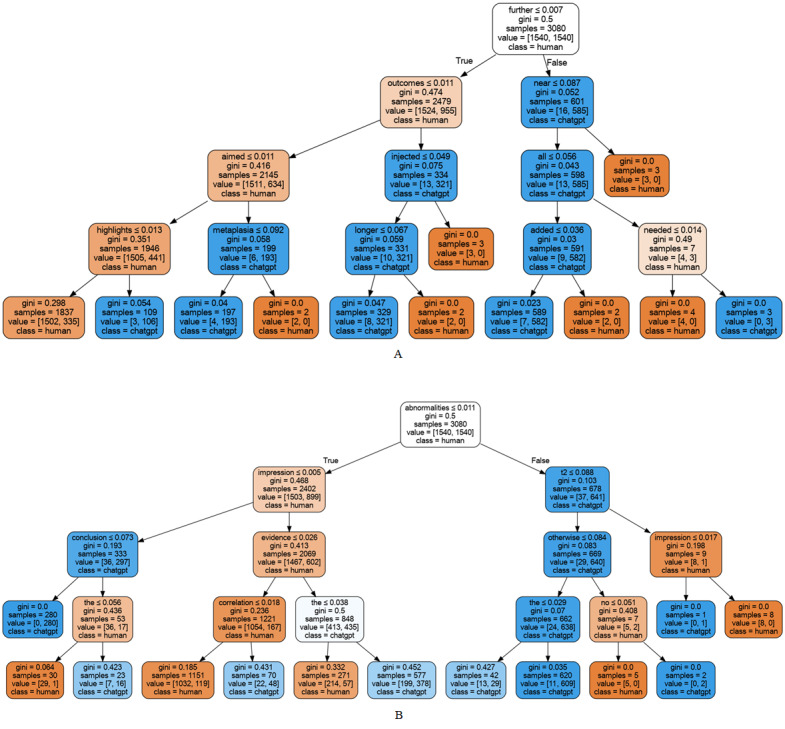
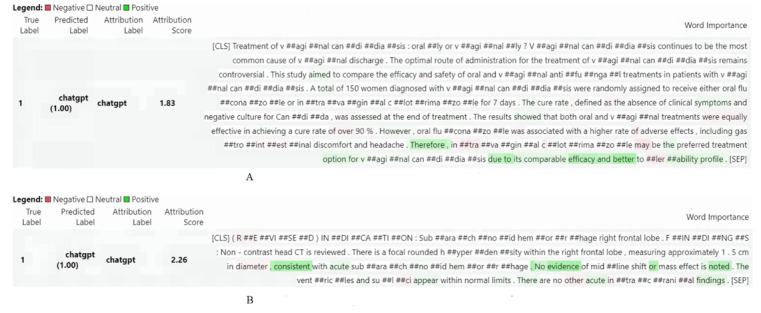
Background: Large language models such as ChatGPT are capable of generating grammatically perfect and human-like text content, and a large number of ChatGPT-generated texts have appeared on the Internet. However, medical texts such as clinical notes and diagnoses require rigorous validation, and erroneous medical content generated by ChatGPT could potentially lead to disinformation that poses significant harm to healthcare and the general public. Objective: This research is among the first studies on responsible and ethical AIGC (Artificial Intelligence Generated Content) in medicine. We focus on analyzing the differences between medical texts written by human experts and generated by ChatGPT, and designing machine learning workflows to effectively detect and differentiate medical texts generated by ChatGPT. Methods: We first construct a suite of datasets containing medical texts written by human experts and generated by ChatGPT. In the next step, we analyze the linguistic features of these two types of content and uncover differences in vocabulary, part-of-speech, dependency, sentiment, perplexity, etc. Finally, we design and implement machine learning methods to detect medical text generated by ChatGPT. Results: Medical texts written by humans are more concrete, more diverse, and typically contain more useful information, while medical texts generated by ChatGPT pay more attention to fluency and logic, and usually express general terminologies rather than effective information specific to the context of the problem. A BERT-based model can effectively detect medical texts generated by ChatGPT, and the F1 exceeds 95%.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The cited source doesn’t support the claim as written.
In the citing paper
“In contrast, LLM-generated papers exhibit fewer grammatical and other types of errors and demonstrate a broader variety of expression (Yan et al. 2023; Liao et al. 2023a).”
From A Survey on LLM-Generated Text Detection: Necessity, Methods, and Future Directions (2025) · cites this paper as Liao et al. 2023a
Checked by a reasoning model — may be wrong.
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Machine-generated text has a more complex syntactic structure and uses more normalization, whereas human essays tend to be more lexically complex [81,83].”
From Survey on Plagiarism Detection in Large Language Models: The Impact of ChatGPT and Gemini on Academic Integrity (2024) · cites this paper as [83]
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Recent research (Giorgi et al. 2023; Liao et al. 2023b) has elucidated distinct disparities between LLM-generated text and human-written text, underscoring a tangible and discernible gap between the two.”
From A Survey on LLM-Generated Text Detection: Necessity, Methods, and Future Directions (2025) · cites this paper as Liao et al. 2023b
Experimental — accuracy not yet measuredThe check wasn’t confident either way, so it gives no verdict — never disputed.
In the citing paper
“In an experiment, AI models were able to generate more high-quality argumentative essays than German high school students in an online forum [83].”
From Survey on Plagiarism Detection in Large Language Models: The Impact of ChatGPT and Gemini on Academic Integrity (2024) · cites this paper as [83]
Experimental — accuracy not yet measured
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
XGBoost: A Scalable Tree Boosting System
Chen, T., & Guestrin, C. (2016) · Proceedings of the 22nd ACM SIGKDD International Conference on Knowledge Discovery and Data Mining · doi:10.1145/2939672.2939785 · Cited by 54,569
Lewis, M., Liu, Y., Goyal, N., Ghazvininejad, M., Mohamed, A., Levy, O., Stoyanov, V., & Zettlemoyer, L. (2020) · Proceedings of the 58th Annual Meeting of the Association for Computational Linguistics · doi:10.18653/v1/2020.acl-main.703 · Cited by 8,821
MIMIC-III, a freely accessible critical care database
Johnson, A. E. W., Pollard, T. J., Shen, L., Lehman, L.-W. H., Feng, M., Ghassemi, M., Moody, B., Szolovits, P., Anthony Celi, L., & Mark, R. G. (2016) · Scientific Data · doi:10.1038/sdata.2016.35 · Cited by 8,141
The Stanford CoreNLP Natural Language Processing Toolkit
Manning, C. D., Surdeanu, M., Bauer, J., Finkel, J. R., Bethard, S. J., & McClosky, D. (2014) · Annual Meeting of the Association for Computational Linguistics: System Demonstrations (ACL Demo) · doi:10.3115/v1/p14-5010 · Cited by 7,252
BioBERT: a pre-trained biomedical language representation model for biomedical text mining
Lee, J., Yoon, W., Kim, S., Kim, D., Kim, S., So, C. H., & Kang, J. (2020) · Bioinformatics · doi:10.1093/bioinformatics/btz682 · Cited by 7,218
Gilson, A., Safranek, C. W., Huang, T., Socrates, V., Chi, L., Taylor, R. A., & Chartash, D. (2023) · JMIR Medical Education · doi:10.2196/45312 · Cited by 2,078
Alsentzer, E., Murphy, J., Boag, W., Weng, W.-H., Jindi, D., Naumann, T., & McDermott, M. (2019) · Proceedings of the 2nd Clinical Natural Language Processing Workshop · doi:10.18653/v1/w19-1909 · Cited by 1,736
BioGPT: generative pre-trained transformer for biomedical text generation and mining
Luo, R., Sun, L., Xia, Y., Qin, T., Zhang, S., Poon, H., & Liu, T.-Y. (2022) · Briefings in Bioinformatics · doi:10.1093/bib/bbac409 · Cited by 1,150
Self-citationChatGPT and other large language models are double-edged swords
Shen, Y., Heacock, L., Elias, J., Hentel, K. D., Reig, B., Shih, G., & Moy, L. (2023) · Radiology · doi:10.1148/radiol.230163 · Cited by 1,008
Summary of ChatGPT-Related research and perspective towards the future of large language models
Liu, Y., Han, T., Ma, S., Zhang, J., Yang, Y., Tian, J., He, H., Li, A., He, M., Liu, Z., et al. (2023) · Meta-Radiology · doi:10.1016/j.metrad.2023.100017 · Cited by 855
Self-citation
Research works printed but not linked: 22
- Devlin J, Chang MW, Lee K, Toutanova K. Bert: pre-training of deep bidirectional transformers for language understanding. 2019 Presented at: North American Chapter of the Association for Computational Linguistics: Human Language Technologies; June 2-7, 2019; Minneapolis p. 4171-4186
- Vaswani A, Shazeer N, Parmar N, Uszkoreit J, Jones L, Gomez AN, et al. Attention is all you need. Adv Neural Inf Process Syst. 2017;30:1-11
- Brown T, Mann B, Ryder N, Subbiah M, Kaplan JD, Dhariwal P, et al. Language models are few-shot learners. Adv Neural Inf Process Syst. 2020;33:1877-1901
- Ouyang L, Wu J, Jiang X, Almeida D, Wainwright CL, Mishkin P, et al. Training language models to follow instructions with human feedback. arXiv. Preprint posted online on March 4, 2022. [FREE Full text]
- Christiano PF, Leike J, Brown T, Martic M, Legg S, Amodei D. Deep reinforcement learning from human preferences. Adv Neural Inf Process Syst. 2017;30:1-9
- Schulman J, Wolski F, Dhariwal P, Radford A, Klimov O. Proximal policy optimization algorithms. arXiv. Preprint posted online on July 20, 2017. [FREE Full text]
- Guan Z, Wu Z, Liu Z, Wu D, Ren H, Li Q, et al. Cohortgpt: an enhanced gpt for participant recruitment in clinical study. arXiv. Preprint posted online on July 21, 2023. [FREE Full text]
- Dai H, Liu Z, Liao W, Huang X, Wu Z, Zhao L, et al. AugGPT: leveraging ChatGPT for text data augmentation. arXiv. Preprint posted online on February 25, 2023. [FREE Full text]
- Ma C, Wu Z, Wang J, Xu S, Wei Y, Liu Z, et al. ImpressionGPT: an iterative optimizing framework for radiology report summarization with ChatGPT. arXiv. Preprint posted online on April 17, 2023. [FREE Full text]
- Liu Z, Yu X, Zhang L, Wu Z, Cao C, Dai H, et al. Deid-GPT: zero-shot medical text de-identification by GPT-4. arXiv. Preprint posted online on March 20, 2023. [FREE Full text]
- Shi Y, Xu S, Liu Z, Liu T, Li X, Liu N. MedEdit: model editing for medical question answering with external knowledge bases. arXiv. Preprint posted online on September 27, 2023. [FREE Full text]
- Mitrović S, Andreoletti D, Ayoub O. ChatGPT or human? Detect and explain. Explaining decisions of machine learning model for detecting short ChatGPT-generated text. arXiv. Preprint posted online on January 30, 2023. [FREE Full text]
- Liu Y, Ott M, Goyal N, Du J, Joshi M, Chen D, et al. RoBERTa: a robustly pptimized BERT pretraining approach. arXiv. Preprint posted online on July 26, 2019. [FREE Full text]
- Lan Z, Chen M, Goodman S, Gimpel K, Sharma P, Soricut R. ALBERT: A lite BERT for self-supervised learning of language representations. arXiv. Preprint posted online on Septemeber 26, 2019. [FREE Full text]
- Radford A, Wu J, Child R, Luan D, Amodei D, Sutskever I. Language models are unsupervised multitask learners. Semantic Scholar. 2019. URL: https://www.semanticscholar.org/paper/ Language-Models-are-Unsupervised-Multitask-Learners-Radford-Wu/9405cc0d6169988371b2755e573cc28650d14dfe [accessed 2023-10-18]
- Raffel C, Shazeer N, Roberts A, Lee K, Narang S, Matena M, et al. Exploring the limits of transfer learning with a unified text-to-text transformer. J Mach Learn Res. 2020;21(1):1-67
- Liao W, Liu Z, Dai H, Wu Z, Zhang Y, Huang X, et al. Mask-guided BERT for few shot text classification. arXiv. Preprint posted online on February 21, 2023. [FREE Full text]
- Cai H, Liao W, Liu Z, Huang X, Zhang Y, Ding S, et al. Coarse-to-fine knowledge graph domain adaptation based on distantly-supervised iterative training. arXiv. Preprint posted online on November 5, 2022. [FREE Full text]
- Liu Z, Li Y, Shu P, Zhong A, Yang L, Ju C, et al. Radiology-Llama2: best-in-class large language model for radiology. arXiv. Preprint posted online on August 29, 2023. [FREE Full text] [doi: 10.1007/978-3-031-45673-2_46] · DOI
- Guo B, Zhang X, Wang Z, Jiang M, Nie J, Ding Y, et al. How close is chatgpt to human experts? Comparison corpus, evaluation, and detection. arXiv. Preprint posted online on January 18, 2023. [FREE Full text]
- Bird S, Klein E, Loper E. Natural Language Processing with Python -Analyzing Text with the Natural Language Toolkit. Sebastopol. O'Reilly Media; 2009.
- Carlini N, Tramer F, Wallace E, Jagielski M, Herbert-Voss A, Lee K, et al. Extracting training data from large language models. In: Proceedings of the 30th USENIX Security Symposium. 2021 Presented at: 30th USENIX Security Symposium; August 11-13, 2021; Vancouver
Cited by
Sorted by citations
Summary of ChatGPT-Related research and perspective towards the future of large language models
Liu, Y., Han, T., Ma, S., Zhang, J., Yang, Y., Tian, J., He, H., Li, A., He, M., Liu, Z., et al. (2023) · Meta-Radiology · doi:10.1016/j.metrad.2023.100017 · Cited by 855
Self-citationLarge language models in healthcare and medical domain: A review
Nazi, Z. A., & Peng, W. (2024) · Informatics · doi:10.3390/informatics11030057 · Cited by 415
A Survey of GPT-3 Family Large Language Models Including ChatGPT and GPT-4
Kalyan, K. S. (2024) · Natural Language Processing Journal · doi:10.1016/j.nlp.2023.100048 · Cited by 335
Younis, H. A., Eisa, T. A. E., Nasser, M., Sahib, T. M., Noor, A. A., Alyasiri, O. M., Salisu, S., Hayder, I. M., & Younis, H. A. (2024) · Diagnostics · doi:10.3390/diagnostics14010109 · Cited by 242
Review of large vision models and visual prompt engineering
Wang, J., Liu, Z., Zhao, L., Wu, Z., Ma, C., Yu, S., Dai, H., Yang, Q., Liu, Y., Zhang, S., et al. (2023) · Meta-Radiology · doi:10.1016/j.metrad.2023.100047 · Cited by 257
Self-citationAugGPT: Leveraging ChatGPT for Text Data Augmentation
Dai, H., Liu, Z., Liao, W., Huang, X., Cao, Y., Wu, Z., Zhao, L., Xu, S., Zeng, F., Liu, W., et al. (2025) · IEEE Transactions on Big Data · doi:10.1109/tbdata.2025.3536934 · Cited by 503
Self-citationA Survey on LLM-Generated Text Detection: Necessity, Methods, and Future Directions
Wu, J., Yang, S., Zhan, R., Yuan, Y., Chao, L. S., & Wong, D. F. (2025) · Computational Linguistics · doi:10.1162/coli_a_00549 · Cited by 212
Oniani, D., Hilsman, J., Peng, Y., Poropatich, R. K., Pamplin, J. C., Legault, G. L., & Wang, Y. (2023) · npj Digital Medicine · doi:10.1038/s41746-023-00965-x · Cited by 143
A Systematic Study and Comprehensive Evaluation of ChatGPT on Benchmark Datasets
Laskar, M. T. R., Bari, M. S., Rahman, M., Bhuiyan, M. A. H., Joty, S., & Huang, J. X. (2023) · Findings of the Association for Computational Linguistics: ACL (Findings of ACL) · doi:10.18653/v1/2023.findings-acl.29 · Cited by 160
Contrasting Linguistic Patterns in Human and LLM-Generated News Text
Muñoz-Ortiz, A., Gómez-Rodríguez, C., & Vilares, D. (2024) · Artificial Intelligence Review · doi:10.1007/s10462-024-10903-2 · Cited by 94
When brain-inspired AI meets AGI
Zhao, L., Zhang, L., Wu, Z., Chen, Y., Dai, H., Yu, X., Liu, Z., Zhang, T., Hu, X., Jiang, X., et al. (2023) · Meta-Radiology · doi:10.1016/j.metrad.2023.100005 · Cited by 116
Self-citationPudasaini, S., Miralles-Pechuán, L., Lillis, D., & Llorens Salvador, M. (2025) · Journal of Academic Ethics · doi:10.1007/s10805-024-09576-x · Cited by 70
Impact of a Digital Scribe System on Clinical Documentation Time and Quality: Usability Study
van Buchem, M. M., Kant, I. M. J., King, L., Kazmaier, J., Steyerberg, E. W., & Bauer, M. P. (2024) · JMIR AI · doi:10.2196/60020 · Cited by 70
Understanding LLMs: A comprehensive overview from training to inference
Liu, Y., He, H., Han, T., Zhang, X., Liu, M., Tian, J., Zhang, Y., Wang, J., Gao, X., Zhong, T., et al. (2024) · Neurocomputing · doi:10.1016/j.neucom.2024.129190 · Cited by 81
Self-citationZaitsu, W., & Jin, M. (2023) · PLoS ONE · doi:10.1371/journal.pone.0288453 · Cited by 77
Radiology-GPT: A large language model for radiology
Liu, Z., Li, Y., Shu, P., Zhong, A., Jiang, H., Pan, Y., Yang, L., Ju, C., Wu, Z., Ma, C., et al. (2025) · Meta-Radiology · doi:10.1016/j.metrad.2025.100153 · Cited by 120
Self-citationLarge Language Models in Biomedical and Health Informatics: A Review with Bibliometric Analysis
Yu, H., Fan, L., Li, L., Zhou, J., Ma, Z., Xian, L., Hua, W., He, S., Jin, M., Zhang, Y., et al. (2024) · Journal of Healthcare Informatics Research · doi:10.1007/s41666-024-00171-8 · Cited by 82
Self-citationAnalysis of ChatGPT Responses to Ophthalmic Cases: Can ChatGPT Think like an Ophthalmologist?
Chen, J., Reddy, A. J., Al-Sharif, E. M., Shoji, M. K., Kalaw, F. G. P., Eslani, M., Lang, P. Z., Arya, M., Koretz, Z. A., Bolo, K. A., et al. (2024) · Ophthalmology Science · doi:10.1016/j.xops.2024.100600 · Cited by 45
Li, F., & Yang, Y. Y. (2024) · JMIR Formative Research · doi:10.2196/60024 · Cited by 59
Liu, Z., Zhong, A., Li, Y., Yang, L., Ju, C., Wu, Z., Ma, C., Shu, P., Chen, C., Kim, S., et al. (2023) · Lecture notes in computer science · doi:10.1007/978-3-031-45673-2_46 · Cited by 42
Self-citationRezayi, S., Liu, Z., Wu, Z., Dhakal, C., Ge, B., Dai, H., Mai, G., Liu, N., Zhen, C., Liu, T., et al. (2024) · IEEE Transactions on Big Data · doi:10.1109/tbdata.2024.3442542 · Cited by 65
Self-citationKim, S.-J. (2024) · Science Editing · doi:10.6087/kcse.343 · Cited by 42
Surviving ChatGPT in healthcare
Liu, Z., Zhang, L., Wu, Z., Yu, X., Cao, C., Dai, H., Liu, N., Liu, J., Liu, W., Li, Q., et al. (2024) · Frontiers in Radiology · doi:10.3389/fradi.2023.1224682 · Cited by 41
Self-citationA feasibility study for the application of AI-generated conversations in pragmatic analysis
Chen, X., Li, J., & Ye, Y. (2024) · Journal of Pragmatics · doi:10.1016/j.pragma.2024.01.003 · Cited by 37
Artificial general intelligence for radiation oncology
Liu, C., Liu, Z., Holmes, J., Zhang, L., Zhang, L., Ding, Y., Shu, P., Wu, Z., Dai, H., Li, Y., et al. (2023) · Meta-Radiology · doi:10.1016/j.metrad.2023.100045 · Cited by 39
Self-citationBrainstorming Will Never Be the Same Again—A Human Group Supported by Artificial Intelligence
Lavrič, F., & Škraba, A. (2023) · Machine Learning and Knowledge Extraction · doi:10.3390/make5040065 · Cited by 41
Georgiou, G. P. (2025) · Information · doi:10.3390/info16110979 · Cited by 57
Hakam, H. T., Prill, R., Korte, L., Lovreković, B., Ostojić, M., Ramadanov, N., & Muehlensiepen, F. (2023) · JMIR Formative Research · doi:10.2196/52164 · Cited by 44
Practical Evaluation of ChatGPT Performance for Radiology Report Generation
Soleimani, M., Seyyedi, N., Ayyoubzadeh, S. M., Kalhori, S. R. N., & Keshavarz, H. (2024) · Academic Radiology · doi:10.1016/j.acra.2024.07.020 · Cited by 33
Fight Fire With Fire: How Much Can We Trust ChatGPT on Source Code-Related Tasks?
Yu, X., Liu, L., Hu, X., Keung, J., Liu, J., & Xia, X. (2024) · IEEE Transactions on Software Engineering · doi:10.1109/tse.2024.3492204 · Cited by 34
Doru, B., Maier, C., Busse, J. S., Lücke, T., Schönhoff, J., Enax‐Krumova, E., Hessler, S., Berger, M., & Tokic, M. C. (2025) · JMIR Medical Education · doi:10.2196/62779 · Cited by 42
Can we trust academic AI detective? Accuracy and limitations of AI-output detectors
Erol, G., Ergen, A., Gülşen Erol, B., Kaya Ergen, Ş., Bora, T. S., Çölgeçen, A. D., Araz, B., Şahin, C., Bostancı, G., Kılıç, İ., et al. (2025) · Acta Neurochirurgica · doi:10.1007/s00701-025-06622-4 · Cited by 28
Unveiling ChatGPT text using writing style
Berriche, L., & Larabi-Marie-Sainte, S. (2024) · Heliyon · doi:10.1016/j.heliyon.2024.e32976 · Cited by 33
Hybrid Arabic handwritten character segmentation using CNN and graph theory algorithm
Berriche, L., Alqahtani, A., & Rekik, S. (2023) · Journal of King Saud University - Computer and Information Sciences · doi:10.1016/j.jksuci.2023.101872 · Cited by 27
Wani, M. A., ELAffendi, M. A., & Shakil, K. A. (2024) · Computers · doi:10.3390/computers13100264 · Cited by 31
Bibliometric Overview of ChatGPT: New Perspectives in Social Sciences
Oliński, M., Krukowski, K., & Sieciński, K. (2024) · Publications · doi:10.3390/publications12010009 · Cited by 31
A collaborative large language model for drug analysis
Zhou, H., Liu, F., Wu, J., Zhang, W., Huang, G., Clifton, L., Eyre, D. W., Luo, H., Liu, F., Branson, K., et al. (2025) · Nature Biomedical Engineering · doi:10.1038/s41551-025-01471-z · Cited by 31
Arbel, Y., Gimmon, Y., & Shmueli, L. (2025) · Physical Therapy · doi:10.1093/ptj/pzaf010 · Cited by 21
Large language models for bioinformatics
Ruan, W., Lyu, Y., Zhang, J., Cai, J., Shu, P., Yang, G., Lu, Y., Gao, S., Wang, Y., Wang, P., et al. (2025) · Quantitative Biology · doi:10.1002/qub2.70014 · Cited by 37
Self-citationAD-AutoGPT: An autonomous GPT for Alzheimer’s disease infodemiology
Dai, H., Li, Y., Liu, Z., Zhao, L., Wu, Z., Song, S., Ye, S., Zhu, D., Li, X., Sheng, L., et al. (2025) · PLOS Global Public Health · doi:10.1371/journal.pgph.0004383 · Cited by 49
Self-citationPark, S. H., Han, K., & Lee, J. (2024) · La radiologia medica · doi:10.1007/s11547-024-01886-9 · Cited by 18
Mapping the individual, social and biospheric impacts of Foundation Models
Hernández, A. D., Krishna, S., Perini, A., Katell, M. A., Bennett, S., Borda, A., Hashem, Y., Hadjiloizou, S., Mahomed, S., Jayadeva, S., et al. (2024) · ACM Conference on Fairness, Accountability, and Transparency (FAccT) · doi:10.1145/3630106.3658939 · Cited by 38
Yang, S., Chen, S.-K., Hailin, Z. H. U., Lin, J., & Wang, X. (2024) · System · doi:10.1016/j.system.2024.103494 · Cited by 16
Wei, S., Hu, A., Liang, Y., Yang, J., Yu, L., Li, W., Yang, B., & Qiu, J. (2025) · Radiation Oncology · doi:10.1186/s13014-025-02660-5 · Cited by 21
Discriminating Human-authored from ChatGPT-Generated Code Via Discernable Feature Analysis
Li, K., Hong, S., Fu, C., Zhang, Y., & Liu, M. (2023) · IEEE International Symposium on Software Reliability Engineering Workshops (ISSREW) · doi:10.1109/issrew60843.2023.00059 · Cited by 18
Self-citationThe ChatGPT application on quality management: a comprehensive review
Atalan, A. (2025) · Journal of Management Analytics · doi:10.1080/23270012.2025.2484225 · Cited by 15
Ensemble learning approach for distinguishing human and computer-generated Arabic reviews
Alhayan, F., & Himdi, H. (2024) · PeerJ Computer Science · doi:10.7717/peerj-cs.2345 · Cited by 13
Appliances of Generative AI-Powered Language Tools in Academic Writing: A Scoping Review
Raitskaya, L., & Тихонова, Е. В. (2024) · Journal of language and Education · doi:10.17323/jle.2024.24181 · Cited by 23
Is This You, LLM? Recognizing AI-written Programs with Multilingual Code Stylometry
Gurioli, A., Gabbrielli, M., & Zacchiroli, S. (2025) · IEEE International Conference on Software Analysis, Evolution and Reengineering (SANER) · doi:10.1109/saner64311.2025.00044 · Cited by 18
Classifying human vs. AI text with machine learning and explainable transformer models
Masih, A., Afzal, B., Firdoos, S., Mahmood, J., Ali, A., Abdulnabi, M. S. H., & Balungu, D. M. (2025) · Scientific Reports · doi:10.1038/s41598-025-27377-z · Cited by 17
Arshed, M. A., Gherghina, Ș., Dewi, C., Iqbal, A., & Mumtaz, S. (2024) · De Computis · doi:10.3390/computation12050101 · Cited by 13
Zero-shot detection of LLM-generated text via text reorder
Sun, J., & Lv, Z. (2025) · Neurocomputing · doi:10.1016/j.neucom.2025.129829 · Cited by 14
ChatGPT vs. Human Journalists: Analyzing News Summaries Through BERTScore and Moderation Standards
Kim, H.-S., Kang, J.-W., & Choi, S. (2025) · Electronics · doi:10.3390/electronics14112115 · Cited by 12
Pudasaini, S., Miralles-Pechuán, L., Lillis, D., & Salvador, M. L. (2024) · arXiv · doi:10.48550/arxiv.2407.13105 · Cited by 8
Litake, O., Park, B. H., Tully, J. L., & Gabriel, R. A. (2024) · Journal of the American Medical Informatics Association · doi:10.1093/jamia/ocae081 · Cited by 14
Kayabaşı, M., Köksaldı, S., & Engin, C. D. (2024) · Clinical and Experimental Optometry · doi:10.1080/08164622.2024.2419524 · Cited by 9
Phillips, V., Kiryakoza, F., Arefin, S., Choudhary, N., & GARIFULLIN, R. F. (2024) · Discover Artificial Intelligence · doi:10.1007/s44163-024-00189-2 · Cited by 10
Sheikh, M. S., KASHANI, K. B., Gregoire, J. R., Thongprayoon, C., Miao, J., Craici, I. M., Cheungpasitporn, W., & Qureshi, F. (2025) · Digital Health · doi:10.1177/20552076251328807 · Cited by 9
Zhang, M. (2025) · Frontiers in Psychology · doi:10.3389/fpsyg.2025.1641212 · Cited by 15
Differentiating between GPT-generated and human-written feedback for radiology residents
Zhou, Z., Rizwan, A. P., Rogoza, N., Chung, A. D., & Kwan, B. Y. M. (2025) · Current Problems in Diagnostic Radiology · doi:10.1067/j.cpradiol.2025.02.002 · Cited by 8
Wang, J., Yao, Z., Mitra, A., Osebe, S., Yang, Z., & Yu, H. Q. (2023) · Clinical Natural Language Processing Workshop (ClinicalNLP) · doi:10.18653/v1/2023.clinicalnlp-1.49 · Cited by 15
Battle of the authors: Comparing neurosurgery articles written by humans and AI
Akgün, M. Y., Savasci, M., Günerbüyük, C., Günara, S. O., Öktenoğlu, T., Özer, A. F., & Ateş, Ö. (2025) · Journal of Clinical Neuroscience · doi:10.1016/j.jocn.2025.111152 · Cited by 7
Barrot, J. S., & Aranda, M. R. R. (2025) · Technology Knowledge and Learning · doi:10.1007/s10758-025-09884-0 · Cited by 12
Carvalho, I., Loureiro, S. M. C., Ivanov, S. H., Björk, P., & Seyitoğlu, F. (2025) · Journal of Hospitality and Tourism Insights · doi:10.1108/jhti-01-2025-0126 · Cited by 9
Dahlberg, A., Käenniemi, T., Winther-Jensen, T., Tapiola, O., Luisto, R., Puranen, T., Gordon, M., Sanmark, E., & Vartiainen, V. A. (2026) · Artificial Intelligence in Medicine · doi:10.1016/j.artmed.2026.103421 · Cited by 13
Kim, N., Homer, M., & Jang, H. (2025) · American Journal of Speech-Language Pathology · doi:10.1044/2025_ajslp-24-00464 · Cited by 9
Chappidi, S., Belue, M. J., Harmon, S. A., Jagasia, S., Zhuge, Y., Taşçı, E., Türkbey, B., Singh, J., Camphausen, K. A., & Krauze, A. V. (2025) · PLOS Digital Health · doi:10.1371/journal.pdig.0000755 · Cited by 5
Jia, L., Liu, X., Chen, T. D., Wang, Y., Takahashi, K., & Wang, Y. (2026) · Information Technology and People · doi:10.1108/itp-06-2025-0773 · Cited by 5
Hosni, J. A. (2024) · Journal of English Language Teaching and Applied Linguistics · doi:10.32996/jeltal.2024.6.3.5 · Cited by 6
Matalon, J., Spurzem, A., Ahsan, S., White, E., Kothari, R., & Varma, M. (2024) · Frontiers in Artificial Intelligence · doi:10.3389/frai.2024.1477535 · Cited by 4
Zhong, T., Zhao, W., Zhang, Y., Pan, Y., Dong, P., Jiang, Z., Jiang, H., Zhou, Y., Kui, X., Shang, Y., et al. (2025) · IEEE Transactions on Biomedical Engineering · doi:10.1109/tbme.2025.3597325 · Cited by 4
Self-citationXu, H., Xue, T., Liu, D., Zhang, F., Westin, C., Kikinis, R., O’Donnell, L. J., & Cai, W. (2024) · Lecture notes in computer science · doi:10.1007/978-3-031-73471-7_8 · Cited by 4
Hong, Y., Pan, T., Zhu, S., Hu, M., Zhou, Z., & Xu, T. (2025) · Scientific Reports · doi:10.1038/s41598-025-01733-5 · Cited by 4
Ricieri, D. D. V., de Farias, A. M. G., Barreto, R. V. G., & de Souza, F. R. (2024) · Peer Review · doi:10.53660/prw-1986-3703 · Cited by 6
Pei, E., Zhao, H., Zhang, T., Jiang, D., He, L., & Chen, H. (2025) · Information Fusion · doi:10.1016/j.inffus.2025.104063 · Cited by 3
Raya, J. T., Islam, N., & Maisha, M. T. (2024) · International Conference on Computer and Information Technology (ICCIT) · doi:10.1109/iccit64611.2024.11022427 · Cited by 4
Detecting authorship between generative AI models and humans: a Burrows’s Delta approach
Zhu, H., & Lei, L. (2025) · Digital Scholarship in the Humanities · doi:10.1093/llc/fqaf048 · Cited by 3
Automatic Design Summary Generation with Generative AI
Ikoma, D., Aoki, E., Taniguchi, T., Suzuki, S., & Ohkuma, T. (2024) · International World Wide Web Conference (WWW) · doi:10.1145/3589335.3651901 · Cited by 3
Investigating the Impact of Utilizing the ChatGPT for Arabic Sentiment Analysis
Al-Gaphari, G. H., Al-Hagree, S., & Al-Helali, B. M. (2024) · Lecture notes on data engineering and communications technologies · doi:10.1007/978-3-031-59711-4_9 · Cited by 3
Human or Algorithm? The Visual Turing Test of AI-Generated Images
Wang, C. (2024) · Journal of Multimedia Information System · doi:10.33851/jmis.2024.11.3.201 · Cited by 3
Detection and Classification of AI-Generated Text
Gupta, S., & Gupta, D. (2024) · International Conference on Computing, Communication and Networking Technologies (ICCCNT) · doi:10.1109/icccnt61001.2024.10724991 · Cited by 2
A Novel Approach for Distinguishing Human and AI-Generated Texts
Abdulhamed, A. A., Ranjan, P., & Xiong, S. (2026) · ACM Transactions on Asian and Low-Resource Language Information Processing · doi:10.1145/3793195 · Cited by 2
From chalkboards to chatbots: generative AI impact on education in emerging economies
Virmani, N., Sharma, D., Sahu, A., & Garza‐Reyes, J. A. (2026) · Interactive Learning Environments · doi:10.1080/10494820.2026.2632172 · Cited by 3
Text Origin Detection: Unmasking the Source – AI vs Human
Pandita, V., Mujawar, A. M., Norbu, T., Verma, V. C., & Patil, P. C. (2024) · International Conference for Emerging Technology (INCET) · doi:10.1109/incet61516.2024.10592990 · Cited by 2
Data Augmentation using Generative-AI
Gowda, S. R., C., P. H., Sunitha, R., M., S. K., H., S. S., & Rao, Y. R. (2024) · Journal of Innovative Image Processing · doi:10.36548/jiip.2024.3.005 · Cited by 1
Kumandaş, M. T., & Murat, N. (2025) · Expert Systems with Applications · doi:10.1016/j.eswa.2025.127042 · Cited by 1
Gondode, P. G., Bhoi, D., Kumar, S., Singh, R., Duggal, S., Shanker, D., & Kumar, S. (2025) · A&A Practice · doi:10.1213/xaa.0000000000002070 · Cited by 1
El‐Dakhs, D. A. S., Afzaal, M., & Siyanova‐Chanturia, A. (2025) · Corpus Pragmatics · doi:10.1007/s41701-025-00210-8 · Cited by 1
HQML-NLP: A hybrid quantum machine learning framework for scholarly AI-text detection
Hazim, L. R., & Ata, O. (2026) · Applied Soft Computing · doi:10.1016/j.asoc.2026.114634 · Cited by 3
Kong, L., & Wang, J. (2026) · Smart innovation, systems and technologies · doi:10.1007/978-3-032-13048-8_13 · Cited by 1
Ton‐Nu, A. T., & Barrot, J. S. (2026) · Innovation in Language Learning and Teaching · doi:10.1080/17501229.2026.2642394 · Cited by 2
Meyer, T., Schlosser, T., Moniri, S., Kumar, A. S., Friedrich, M., & Kowerko, D. (2026) · Engineering Applications of Artificial Intelligence · doi:10.1016/j.engappai.2026.114962 · Cited by 1
Epistemic Modality in Human and AI-Generated Academic Abstracts: A Corpus-Based Analysis
Mahmud, A., Hasan, W., & Khan, A. A. (2026) · Qlantic journal of social sciences. · doi:10.55737/qjss.vii-i.26494 · Cited by 1
Arshed, M. A., Gherghina, Ş. C., Dur-E-Zahra, & Manzoor, M. (2024) · Electronics · doi:10.3390/electronics13112222 · Cited by 2
Hamouda, N., Ibrahim, M. K., & Jabal, M. S. (2023) · medRxiv · doi:10.1101/2023.06.28.23291928 · Cited by 1
Xu, T., Hong, Y., Pan, T., Zhu, S., & Zhou, Z. (2024) · doi:10.2196/preprints.56740
Chow, J. C., Yeh, Y.-T., & Chou, W. (2024) · doi:10.2196/preprints.64556
Cheima, M., Altayyar, S., Vergonjeanne, M., Gellé, T., & Preux, P. (2025) · Journal of Epidemiology and Population Health · doi:10.1016/j.jeph.2025.202990
The Rephrased Reality: Analysing Sentiment Shifts in LLM-Rephrased Text
Richardson, F. L., Villavicencio, A., & de Menezes, R. P. (2025) · ACM Symposium on Applied Computing · doi:10.1145/3672608.3707717
Metadata
- Authors
- Liao, W., Liu, Z., Dai, H., Xu, S., Wu, Z., Zhang, Y., Huang, X., Zhu, D., Cai, H., Liu, T., & Li, X.
- Affiliations
- South China University of Technology (CN)
- University of Georgia (US)
- The University of Texas at Arlington (US)
- Massachusetts General Hospital (US)
- Corresponding author
- Li, Xiang
- ORCID
- Venue
- arXiv
- Publisher
- arXiv
- Published
- 2023
- Volume
- 9
- Pages
- e48904-e48904
- ISSN
- 2369-3762 (ISSN-L)
- arXiv
- 2304.11567
- PMC
- PMC10784984
- OpenAlex
- W4390347092
- Cited by
- 119
- References
- 28
- Citations by year
- 2026: 26 · 2025: 36 · 2024: 42 · 2023: 15
- FWCI
- 11.22
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Licence
- Locations
- JMIR Medical Education (publishedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- arXiv (Cornell University) (submittedVersion)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion, cc-by-sa)
- arXiv (Cornell University)
- Funders
- National Natural Science Foundation of China (U21A20520, 62172112)
- National Key Research and Development Program of China (2022YFE0112200)
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Authorship Attribution and Profiling
- Physical Sciences › Computer Science › Artificial Intelligence › Topic Modeling
- Social Sciences › Sociology and Political Science › Misinformation and Its Impacts
- Keywords
- ChatGPT, large language models, AI-generated text detection, medical texts, clinical notes, disinformation, linguistic features, perplexity, BERT, responsible AI
- MeSH terms
- Disinformation, Algorithms, Artificial Intelligence, Health Facilities, Humans, Electric Power Supplies
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
