

The DOI matches its DataCite record.
The Future of Open Human Feedback
Abstract
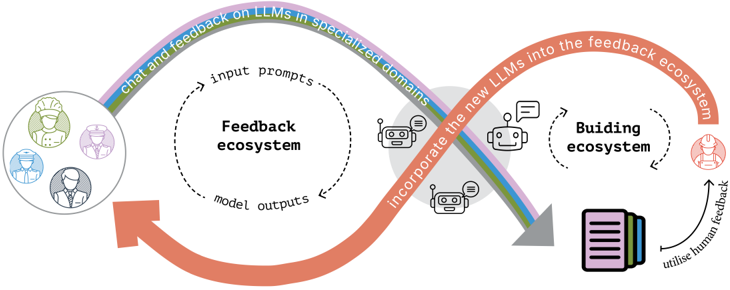
Human feedback on conversations with language language models (LLMs) is central to how these systems learn about the world, improve their capabilities, and are steered toward desirable and safe behaviors. However, this feedback is mostly collected by frontier AI labs and kept behind closed doors. In this work, we bring together interdisciplinary experts to assess the opportunities and challenges to realizing an open ecosystem of human feedback for AI. We first look for successful practices in peer production, open source, and citizen science communities. We then characterize the main challenges for open human feedback. For each, we survey current approaches and offer recommendations. We end by envisioning the components needed to underpin a sustainable and open human feedback ecosystem. In the center of this ecosystem are mutually beneficial feedback loops, between users and specialized models, incentivizing a diverse stakeholders community of model trainers and feedback providers to support a general open feedback pool.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
“In contrast, Chatbot Arena has been widely adopted in part because it allows human users to ask any questions they want, which creates a non-static test set (Don-Yehiya et al., 2024).”
From The Leaderboard Illusion (2025) · cites this paper as Don-Yehiya et al., 2024
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
No references could be resolved yet.
Research works printed but not linked: 129
- Achiam, J., Adler, S., Agarwal, S., Ahmad, L., Akkaya, I., Aleman, F.L., Almeida, D., Altenschmidt, J., Altman, S., Anadkat, S., et al.: Gpt-4 technical report. arXiv preprint arXiv:2303.08774 (2023) · arXiv
- Aakanksha, Ahmadian, A., Ermis, B., Goldfarb-Tarrant, S., Kreutzer, J., Fadaee, M., Hooker, S.: The Multilingual Alignment Prism: Aligning Global and Local Preferences to Reduce Harm (2024). https://arxiv.org/abs/2406.18682 · arXiv
- Ash, J., Anderson, B., Gordon, R., Langley, P.: Digital interface design and power: Friction, threshold, transition. Environment and planning D: society and space 36(6), 1136-1153 (2018)
- Askell, A., Bai, Y., Chen, A., Drain, D., Ganguli, D., Henighan, T., Jones, A., Joseph, N., Mann, B., DasSarma, N., Elhage, N., Hatfield-Dodds, Z., Hernandez, D., Kernion, J., Ndousse, K., Olsson, C., Amodei, D., Brown, T., Clark, J., McCandlish, S., Olah, C., Kaplan, J.: A General Language Assistant as a Laboratory for Alignment. arXiv. arXiv:2112.00861 [cs] (2021). http://arxiv.org/abs/2112.00861 Accessed 2022-10-03 · arXiv
- Agnew, W., Bergman, A.S., Chien, J., Díaz, M., El-Sayed, S., Pittman, J., Mohamed, S., McKee, K.R.: The illusion of artificial inclusion. In: Proceedings of the CHI Conference on Human Factors in Computing Systems, pp. 1-12 (2024)
- Ahmadian, A., Cremer, C., Gallé, M., Fadaee, M., Kreutzer, J., Pietquin, O., Üstün, A., Hooker, S.: Back to Basics: Revisiting REINFORCE Style Optimization for Learning from Human Feedback in LLMs (2024). https://arxiv.org/abs/2402.14740 · arXiv
- Act, A.: Health insurance portability and accountability act of 1996. Public law 104, 191 (1996)
- Ågerfalk, P.J., Fitzgerald, B.: Outsourcing to an unknown workforce: Exploring opensurcing as a global sourcing strategy. MIS quarterly, 385-409 (2008)
- Aroyo, L., Taylor, A.S., Diaz, M., Homan, C.M., Parrish, A., Serapio-Garcia, G., Prab- hakaran, V., Wang, D.: DICES Dataset: Diversity in Conversational AI Evaluation for Safety. arXiv. arXiv:2306.11247 [cs] (2023). https://doi.org/10.48550/arXiv.2306. 11247 . http://arxiv.org/abs/2306.11247 Accessed 2024-02-16 · DOI
- Barbosa, N.a.M., Chen, M.: Rehumanized crowdsourcing: A labeling framework address- ing bias and ethics in machine learning. In: Proceedings of the 2019 CHI Conference on Human Factors in Computing Systems. CHI '19, pp. 1-12. Association for Computing Machinery, New York, NY, USA (2019). https://doi.org/10.1145/3290605.3300773 . https://doi.org/10.1145/3290605.3300773 · DOI
- Balestra, M., Cheshire, C., Arazy, O., Nov, O.: Investigating the motivational paths of peer production newcomers. In: Proceedings of the 2017 CHI Conference on Human Factors in Computing Systems. CHI '17, pp. 6381-6385. Association for Computing Machinery, New York, NY, USA (2017). https://doi.org/10.1145/3025453.3026057 . https://doi.org/10.1145/3025453.3026057 · DOI
- Bourtoule, L., Chandrasekaran, V., Choquette-Choo, C.A., Jia, H., Travers, A., Zhang, B., Lie, D., Papernot, N.: Machine unlearning. In: 2021 IEEE Symposium on Security and Privacy (SP), pp. 141-159 (2021). IEEE
- Bryant, S.L., Forte, A., Bruckman, A.: Becoming wikipedian: transformation of participation in a collaborative online encyclopedia. In: Proceedings of the 2005 ACM International Conference on Supporting Group Work. GROUP '05, pp. 1- 10. Association for Computing Machinery, New York, NY, USA (2005). https: //doi.org/10.1145/1099203.1099205 . https://doi.org/10.1145/1099203.1099205 · DOI
- Bender, E.M., Gebru, T., McMillan-Major, A., Shmitchell, S.: On the dangers of stochastic parrots: Can language models be too big? In: Proceedings of the 2021 ACM Conference on Fairness, Accountability, and Transparency. FAccT '21, pp. 610-623. Association for Computing Machinery, New York, NY, USA (2021). https: //doi.org/10.1145/3442188.3445922 . https://doi.org/10.1145/3442188.3445922 · DOI · Paper page
- Birhane, A., Isaac, W., Prabhakaran, V., Diaz, M., Elish, M.C., Gabriel, I., Mohamed, S.: Power to the people? opportunities and challenges for participatory ai. In: Proceedings of the 2nd ACM Conference on Equity and Access in Algorithms, Mechanisms, and Optimization, pp. 1-8 (2022)
- Birkinbine, B.: Incorporating the digital commons: Corporate involvement in free and open source software. University of Westminster Press (2020)
- Bai, Y., Jones, A., Ndousse, K., Askell, A., Chen, A., DasSarma, N., Drain, D., Fort, S., Ganguli, D., Henighan, T., et al.: Training a helpful and harmless assistant with reinforcement learning from human feedback. arXiv preprint arXiv:2204.05862 (2022) · arXiv
- Butler, B., Joyce, E., Pike, J.: Don't look now, but we've created a bureaucracy: the nature and roles of policies and rules in wikipedia. In: Proceedings of the SIGCHI Conference on Human Factors in Computing Systems. CHI '08, pp. 1101- 1110. Association for Computing Machinery, New York, NY, USA (2008). https: //doi.org/10.1145/1357054.1357227 . https://doi.org/10.1145/1357054.1357227 · DOI · Paper page
- Barke, S., James, M.B., Polikarpova, N.: Grounded copilot: How programmers interact with code-generating models. Proceedings of the ACM on Programming Languages 7(OOPSLA1), 85-111 (2023)
- Boubdir, M., Kim, E., Ermis, B., Fadaee, M., Hooker, S.: Which Prompts Make The Difference? Data Prioritization For Efficient Human LLM Evaluation (2023). https://arxiv.org/abs/2310.14424 · arXiv
- Bonatti, P., Kirrane, S., Polleres, A., Wenning, R.: Transparent personal data processing: The road ahead. In: Computer Safety, Reliability, and Security: SAFECOMP 2017 Workshops, ASSURE, DECSoS, SASSUR, TELERISE, and TIPS, Trento, Italy, September 12, 2017, Proceedings 36, pp. 337-349 (2017). Springer
- Bonaccorsi, A., Rossi, C.: Comparing motivations of individual programmers and firms to take part in the open source movement: From community to business. Knowledge, Technology & Policy 18(4), 40-64 (2006)
- Biderman, S., Schoelkopf, H., Anthony, Q.G., Bradley, H., O'Brien, K., Hallahan, E., Khan, M.A., Purohit, S., Prashanth, U.S., Raff, E., et al.: Pythia: A suite for analyzing large language models across training and scaling. In: International Conference on Machine Learning, pp. 2397-2430 (2023). PMLR. https://proceedings. mlr.press/v202/biderman23a.html
- Cummings, R., Desfontaines, D., Evans, D., Geambasu, R., Jagielski, M., Huang, Y., Kairouz, P., Kamath, G., Oh, S., Ohrimenko, O., et al.: Challenges towards the next frontier in privacy. arXiv preprint arXiv:2304.06929 1 (2023) · arXiv
- Chen, S., Epps, J., Ruiz, N., Chen, F.: Eye activity as a measure of human mental effort in hci. In: Proceedings of the 16th International Conference on Intelligent User Interfaces, pp. 315-318 (2011)
- Chen, Y., Harper, F.M., Konstan, J., Li, S.X.: Social comparisons and contributions to online communities: A field experiment on movielens. American Economic Review 100(4), 1358-1398 (2010)
- Cui, G., Yuan, L., Ding, N., Yao, G., Zhu, W., Ni, Y., Xie, G., Liu, Z., Sun, M.: UltraFeedback: Boosting Language Models with High-quality Feedback. arXiv. arXiv:2310.01377 [cs] (2023). https://doi.org/10.48550/arXiv.2310.01377 . http: //arxiv.org/abs/2310.01377 Accessed 2024-04-01 · DOI · Paper page
- Chiang, W.-L., Zheng, L., Sheng, Y., Angelopoulos, A.N., Li, T., Li, D., Zhang, H., Zhu, B., Jordan, M., Gonzalez, J.E., et al.: Chatbot arena: An open platform for evaluating llms by human preference. arXiv preprint arXiv:2403.04132 (2024) · arXiv
- Dang, J., Ahmadian, A., Marchisio, K., Kreutzer, J., Üstün, A., Hooker, S.: RLHF Can Speak Many Languages: Unlocking Multilingual Preference Optimization for LLMs (2024). https://arxiv.org/abs/2407.02552 · arXiv
- Deci, E.L.: Effects of externally mediated rewards on intrinsic motivation. Journal of personality and Social Psychology 18(1), 105 (1971)
- Dwork, C., McSherry, F., Nissim, K., Smith, A.: Calibrating noise to sensitivity in private data analysis. In: Theory of Cryptography: Third Theory of Cryptography Conference, TCC 2006, New York, NY, USA, March 4-7, 2006. Proceedings 3, pp. 265-284 (2006). Springer
- Dwork, C., Roth, A., et al.: The algorithmic foundations of differential privacy. Foundations and Trends® in Theoretical Computer Science 9(3-4), 211-407 (2014)
- Don-Yehiya, S., Choshen, L., Abend, O.: Learning from Naturally Occurring Feedback (2024). https://arxiv.org/abs/2407.10944 · arXiv
- Emerson, R.W.: Convenience sampling, random sampling, and snowball sampling: How does sampling affect the validity of research? Journal of visual impairment & blindness 109(2), 164-168 (2015)
- Feller, J., Fitzgerald, B.: Understanding open source software development. Addison- Wesley Longman Publishing Co., Inc. (2002)
- Fink, M.: The business and economics of linux and open source. Prentice Hall Professional (2003)
- Fang, J., Liang, J.-W., Wang, H.-C.: How people initiate and respond to discussions around online community norms: A preliminary analysis on meta stack overflow discussions. In: Companion Publication of the 2023 Conference on Computer Supported Cooperative Work and Social Computing. CSCW '23 Companion, pp. 221-225. Association for Computing Machinery, New York, NY, USA (2023). https: //doi.org/10.1145/3584931.3606966 . https://doi.org/10.1145/3584931.3606966 · DOI
- Germonprez, M., Allen, J.P., Warner, B., Hill, J., McClements, G.: Open source communities of competitors. ACM Interactions 20(6), 54-59 (2013)
- Gougherty, A.V., Clipp, H.L.: Testing the reliability of an ai-based large language model to extract ecological information from the scientific literature. npj Biodiversity 3(1), 13 (2024)
- Goggins, S., Lumbard, K., Germonprez, M.: Open source community health: Analytical metrics and their corresponding narratives. In: 2021 IEEE/ACM 4th International Workshop on Software Health in Projects, Ecosystems and Communities (SoHeal), pp. 25-33 (2021). IEEE
- Gebru, T., Morgenstern, J., Vecchione, B., Vaughan, J.W., Wallach, H., Iii, H.D., Crawford, K.: Datasheets for datasets. Communications of the ACM 64(12), 86-92 (2021)
- Hancock, B., Bordes, A., Mazare, P.-E., Weston, J.: Learning from dialogue after deployment: Feed yourself, chatbot! In: Korhonen, A., Traum, D., Màrquez, L. (eds.) Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics, pp. 3667-3684. Association for Computational Linguistics, Florence, Italy (2019). https://doi.org/10.18653/v1/P19-1358 . https://aclanthology.org/P19-1358 · DOI · Paper page
- Hughes, S., Vries, H., Robinson, J., Ferrandis, C.M., Allal, L.B., Werra, L., Ding, J., Paquet, S., Jernite, Y., et al.: The bigcode project governance card. arXiv preprint arXiv:2312.03872 (2023) · arXiv
- Halfaker, A., Geiger, R.S.: Ores: Lowering barriers with participatory machine learning in wikipedia. Proc. ACM Hum.-Comput. Interact. 4(CSCW2) (2020) https://doi. org/10.1145/3415219 · DOI · Paper page
- Heltweg, P., Riehle, D.: A systematic analysis of problems in open collaborative data engineering. Trans. Soc. Comput. 6(3-4) (2023) https://doi.org/10.1145/3629040 · DOI
- Hwang, S., Shaw, A.: Rules and rule-making in the five largest wikipedias. In: Pro- ceedings of the International AAAI Conference on Web and Social Media, vol. 16, pp. 347-357 (2022)
- Hettiachchi, D., Sanderson, M., Goncalves, J., Hosio, S., Kazai, G., Lease, M., Schaek- ermann, M., Yilmaz, E.: Investigating and mitigating biases in crowdsourced data. In: Companion Publication of the 2021 Conference on Computer Supported Cooper- ative Work and Social Computing. CSCW '21 Companion, pp. 331-334. Association for Computing Machinery, New York, NY, USA (2021). https://doi.org/10.1145/ 3462204.3481729 . https://doi.org/10.1145/3462204.3481729 · DOI
- Imran, M., Almusharraf, N.: Analyzing the role of chatgpt as a writing assistant at higher education level: A systematic review of the literature. Contemporary Educational Technology 15(4), 464 (2023)
- Iren, D., Bilgen, S.: Cost of quality in crowdsourcing. Human Computation 1(2) (2014) https://doi.org/10.15346/hc.v1i2. · DOI
- Ivanova, A.A., Sathe, A., Lipkin, B., Kumar, U., Radkani, S., Clark, T.H., Kauf, C., Hu, J., Pramod, R., Grand, G., et al.: Elements of world knowledge (ewok): A cognition- inspired framework for evaluating basic world knowledge in language models. arXiv preprint arXiv:2405.09605 (2024) · arXiv
- Illman, E., Temple, P.: California consumer privacy act. The Business Lawyer 75(1), 1637-1646 (2019)
- Kriplean, T., Beschastnikh, I., McDonald, D.W.: Articulations of wikiwork: uncovering valued work in wikipedia through barnstars. In: Proceedings of the 2008 ACM Conference on Computer Supported Cooperative Work. CSCW '08, pp. 47-56. Association for Computing Machinery, New York, NY, USA (2008). https://doi.org/ 10.1145/1460563.1460573 . https://doi.org/10.1145/1460563.1460573 · DOI
- Kiela, D., Bartolo, M., Nie, Y., Kaushik, D., Geiger, A., Wu, Z., Vidgen, B., Prasad, G., Singh, A., Ringshia, P., Ma, Z., Thrush, T., Riedel, S., Waseem, Z., Stenetorp, P., Jia, R., Bansal, M., Potts, C., Williams, A.: Dynabench: Rethinking benchmarking in NLP. In: Toutanova, K., Rumshisky, A., Zettlemoyer, L., Hakkani-Tur, D., Beltagy, I., Bethard, S., Cotterell, R., Chakraborty, T., Zhou, Y. (eds.) Proceedings of the 2021 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, pp. 4110-4124. Association for Computa- tional Linguistics, Online (2021). https://doi.org/10.18653/v1/2021.naacl-main.324 . https://aclanthology.org/2021.naacl-main.324 · DOI · Paper page
- Kuo, T.-S., Halfaker, A.L., Cheng, Z., Kim, J., Wu, M.-H., Wu, T., Holstein, K., Zhu, H.: Wikibench: Community-driven data curation for ai evaluation on wikipedia. In: Proceedings of the CHI Conference on Human Factors in Computing Systems. CHI '24. Association for Computing Machinery, New York, NY, USA (2024). https: //doi.org/10.1145/3613904.3642278 · DOI
- Kim, M.: The creative commons and copyright protection in the digital era: Uses of creative commons licenses. Journal of computer-mediated communication 13(1), 187-209 (2007)
- Köpf, A., Kilcher, Y., Rütte, D., Anagnostidis, S., Tam, Z.R., Stevens, K., Barhoum, A., Nguyen, D., Stanley, O., Nagyfi, R., et al.: Openassistant conversations-democratizing large language model alignment. Advances in Neural Information Processing Systems 36 (2024)
- Klie, J.-C., Lee, J.-U., Stowe, K., S ¸ahin, G.G., Moosavi, N.S., Bates, L., Petrak, D., De Castilho, R.E., Gurevych, I.: Lessons learned from a citizen science project for natural language processing. arXiv preprint arXiv:2304.12836 (2023) · arXiv
- Kumar, M., Moser, B., Fischer, L., Freudenthaler, B.: Towards practical secure privacy-preserving machine (deep) learning with distributed data. In: Interna- tional Conference on Database and Expert Systems Applications, pp. 55-66 (2022).
- Kop, M.: Ai & intellectual property: Towards an articulated public domain. University of Texas School of Law, Texas Intellectual Property Law Journal (TIPLJ) 28(1) (2020)
- Krishnamurthy, S., Tripathi, A.K.: Bounty programs in free/libre/open source software. In: The Economics of Open Source Software Development, pp. 165-183. Elsevier, ??? (2006)
- Kirk, H.R., Whitefield, A., Röttger, P., Bean, A., Margatina, K., Ciro, J., Mosquera, R., Bartolo, M., Williams, A., He, H., Vidgen, B., Hale, S.A.: The PRISM Alignment Project: What Participatory, Representative and Individualised Human Feedback Reveals About the Subjective and Multicultural Alignment of Large Language Models. arXiv. arXiv:2404.16019 null (2024). http://arxiv.org/abs/2404.16019 Accessed 2024-04-25 · arXiv
- Liesenfeld, A., Dingemanse, M.: Rethinking open source generative ai: open washing and the eu ai act. In: The 2024 ACM Conference on Fairness, Accountability, and Transparency, pp. 1774-1787 (2024)
- Lin, B.Y., Deng, Y., Chandu, K., Brahman, F., Ravichander, A., Pyatkin, V., Dziri, N., Bras, R.L., Choi, Y.: Wildbench: Benchmarking llms with challenging tasks from real users in the wild. arXiv preprint arXiv:2406.04770 (2024) · arXiv
- Lynch, A., Guo, P., Ewart, A., Casper, S., Hadfield-Menell, D.: Eight methods to evaluate robust unlearning in llms. arXiv preprint arXiv:2402.16835 (2024) · arXiv
- Liu, Z., Iqbal, U., Saxena, N.: Opted out, yet tracked: Are regulations enough to protect your privacy? CoRR abs/2202.00885 (2022) 2202.00885 · arXiv
- Lindman, J., Juutilainen, J.-P., Rossi, M.: Beyond the business model: Incentives for organizations to publish software source code. In: IFIP International Conference on Open Source Systems, pp. 47-56 (2009).
- Li, N., Pan, A., Gopal, A., Yue, S., Berrios, D., Gatti, A., Li, J.D., Dombrowski, A.-K., Goel, S., Phan, L., Mukobi, G., Helm-Burger, N., Lababidi, R., Justen, L., Liu, A.B., Chen, M., Barrass, I., Zhang, O., Zhu, X., Tamirisa, R., Bharathi, B., Khoja, A., Zhao, Z., Herbert-Voss, A., Breuer, C.B., Marks, S., Patel, O., Zou, A., Mazeika, M., Wang, Z., Oswal, P., Lin, W., Hunt, A.A., Tienken-Harder, J., Shih, K.Y., Talley, K., Guan, J., Kaplan, R., Steneker, I., Campbell, D., Jokubaitis, B., Levinson, A., Wang, J., Qian, W., Karmakar, K.K., Basart, S., Fitz, S., Levine, M., Kumaraguru, P., Tupakula, U., Varadharajan, V., Wang, R., Shoshitaishvili, Y., Ba, J., Esvelt, K.M., Wang, A., Hendrycks, D.: The WMDP Benchmark: Measuring and Reducing Malicious Use With Unlearning. arXiv (2024). https://doi.org/10.48550/arXiv.2403. 03218 . http://arxiv.org/abs/2403.03218 Accessed 2024-06-11 · DOI · Paper page
- Lerner, J., Tirole, J.: Some simple economics of open source. The Journal of Industrial Economics 50(2), 197-234 (2002)
- Liu, X.-Y., Wang, G., Zha, D.: Fingpt: Democratizing internet-scale data for financial large language models. arXiv preprint arXiv:2307.10485 (2023) · arXiv
- Langenkamp, M., Yue, D.N.: How open source machine learning software shapes ai. In: Proceedings of the 2022 AAAI/ACM Conference on AI, Ethics, and Society, pp. 385-395 (2022)
- Lu, Y., Zhu, W., Li, L., Qiao, Y., Yuan, F.: LLaMAX: Scaling Linguistic Horizons of LLM by Enhancing Translation Capabilities Beyond 100 Languages (2024). https: //arxiv.org/abs/2407.05975
- Li, X., Zhang, Y., Osborne, C., Zhou, M., Jin, Z., Liu, H.: Systematic Literature Review of Commercial Participation in Open Source Software (2024). https://arxiv.org/abs/ 2405.16880
- Movshovitz-Attias, D., Movshovitz-Attias, Y., Steenkiste, P., Faloutsos, C.: Analysis of the reputation system and user contributions on a question answering website: Stackoverflow. In: Proceedings of the 2013 IEEE/ACM International Conference on Advances in Social Networks Analysis and Mining. ASONAM '13, pp. 886- 893. Association for Computing Machinery, New York, NY, USA (2013). https: //doi.org/10.1145/2492517.2500242 . https://doi.org/10.1145/2492517.2500242 MetaAI: Introducing Meta Llama 3: The most capable openly available LLM to date (2024). https://ai.meta.com/blog/meta-llama-3/ Accessed 2024-04-23 · DOI · Paper page
- Mamykina, L., Manoim, B., Mittal, M., Hripcsak, G., Hartmann, B.: Design lessons from the fastest q&a site in the west. In: Proceedings of the SIGCHI Conference on Human Factors in Computing Systems. CHI '11, pp. 2857-2866. Association for Computing Machinery, New York, NY, USA (2011). https://doi.org/10.1145/1978942.1979366 . https://doi.org/10.1145/1978942.1979366 · DOI
- Masakhane, M., Orife, I., Kreutzer, J., Sibanda, B.K., Whitenack, D., Siminyu, K., Martinus, L., Ali, J.T., Abbott, J.Z., Marivate, V., Kabongo, S., Meressa, M., Murhabazi, E., Ahia, O., Biljon, E.V., Ramkilowan, A., Akinfaderin, A., Öktem, A., Akin, W., Kioko, G., Degila, K., Kamper, H., Dossou, B., Emezue, C., Ogueji, K., Bashir, A.: Masakhane -machine translation for africa. In: Siminyu, K., Martinus, L., Marivate, V. (eds.) 1st AfricaNLP Workshop Proceedings, AfricaNLP@ICLR 2020, Virtual Conference, Formerly Addis Ababa Ethiopia, 26th April 2020 (2020). https://arxiv.org/abs/2003.11529 · arXiv
- Nov, O., Arazy, O., Anderson, D.: Scientists@ home: what drives the quantity and quality of online citizen science participation? PloS one 9(4), 90375 (2014)
- Narayanan, A., Shmatikov, V.: Robust de-anonymization of large sparse datasets. In: 2008 IEEE Symposium on Security and Privacy (sp 2008), pp. 111-125 (2008). IEEE
- O'Mahony, S., Bechky, B.A.: Boundary organizations: Enabling collaboration among unexpected allies. Administrative science quarterly 53(3), 422-459 (2008)
- Osborne, C., Ding, J., Kirk, H.R.: The ai community building the future? a quantitative analysis of development activity on hugging face hub. Journal of Computational Social Science, 1-39 (2024)
- Osborne, C.: Public-private funding models in open source software development: A case study on scikit-learn (2024). https://arxiv.org/abs/2404.06484 · arXiv
- Ouyang, L., Wu, J., Jiang, X., Almeida, D., Wainwright, C., Mishkin, P., Zhang, C., Agarwal, S., Slama, K., Ray, A., et al.: Training language models to follow instructions with human feedback. Advances in neural information processing systems 35, 27730-27744 (2022)
- Ouyang, L., Wu, J., Jiang, X., Almeida, D., Wainwright, C., Mishkin, P., Zhang, C., Agarwal, S., Slama, K., Ray, A., Schulman, J., Hilton, J., Kelton, F., Miller, L., Simens, M., Askell, A., Welinder, P., Christiano, P.F., Leike, J., Lowe, R.: Training language models to follow instructions with human feed- back. In: Advances in Neural Information Processing Systems, vol. 35, pp. 27730-27744 (2022). https://proceedings.neurips.cc/paper files/paper/2022/hash/ b1efde53be364a73914f58805a001731-Abstract-Conference.html Accessed 2024-03-18
- Patel, D., Ahmad, A.: Google "we have no moat, and neither does openai.". SemiAnalysis. May 4, 2023 (2023)
- Peng, B., Alcaide, E., Anthony, Q.G., Albalak, A., Arcadinho, S., Biderman, S., Cao, H., Cheng, X., Chung, M., Grella, M., Kranthikiran, G., He, X., Hou, H., Kazienko, P., Kocoń, J., Kong, J., Koptyra, B., Lau, H., Mantri, K.S.I., Mom, F., Saito, A., Tang, X., Wang, B., Wind, J.S., Wozniak, S., Zhang, R., Zhang, Z., Zhao, Q., Zhou, P., Zhu, J., Zhu, R.: Rwkv: Reinventing rnns for the transformer era. In: Conference on Empirical Methods in Natural Language Processing (2023). https://api.semanticscholar.org/CorpusID:258832459
- Pozzobon, L., Ermis, B., Lewis, P., Hooker, S.: Goodtriever: Adaptive Toxicity Mitigation with Retrieval-augmented Models (2023). https://arxiv.org/abs/2310. 07589
- Pistilli, G., Ferrandis, C.M., Jernite, Y., Mitchell, M.: Stronger together: on the artic- ulation of ethical charters, legal tools, and technical documentation in ML. In: Proceedings of the 2023 ACM Conference on Fairness, Accountability, and Trans- parency, FAccT 2023, Chicago, IL, USA, June 12-15, 2023, pp. 343-354. ACM, ??? (2023). https://doi.org/10.1145/3593013.3594002 . https://doi.org/10.1145/3593013. 3594002 · DOI
- Peters, D., Hansen, S., McMullan, J., Ardler, T., Mooney, J., Calvo, R.A.: Par- ticipation is not enough: Towards indigenous-led co-design. In: Proceedings of the 30th Australian Conference on Computer-Human Interaction. OzCHI '18, pp. 97-101. Association for Computing Machinery, New York, NY, USA (2018). https://doi.org/10.1145/3292147.3292204 . https://doi.org/10.1145/3292147.3292204 Accessed 2024-07-12 · DOI
- Pipatanakul, K., Jirabovonvisut, P., Manakul, P., Sripaisarnmongkol, S., Patomwong, R., Chokchainant, P., Tharnpipitchai, K.: Typhoon: Thai large language models. arXiv preprint arXiv:2312.13951 (2023) · arXiv
- Pokrywka, J., Kaczmarek, J., Gorzela'nczyk, E.: Gpt-4 passes most of the 297 written polish board certification examinations. (2024). https://api.semanticscholar.org/ CorpusID:269588160
- Pavlick, E., Post, M., Irvine, A., Kachaev, D., Callison-Burch, C.: The language demographics of amazon mechanical turk. Transactions of the Association for Computational Linguistics 2, 79-92 (2014)
- Pustejovsky, J., Stubbs, A.: Natural language annotation for machine learning: A guide to corpus-building for applications. " O'Reilly Media, Inc." (2012)
- Palen, L., Soden, R., Anderson, T.J., Barrenechea, M.: Success & scale in a data- producing organization: The socio-technical evolution of openstreetmap in response to humanitarian events. In: Proceedings of the 33rd Annual ACM Conference on Human Factors in Computing Systems. CHI '15, pp. 4113-4122. Association for Computing Machinery, New York, NY, USA (2015). https://doi.org/10.1145/2702123.2702294 . https://doi.org/10.1145/2702123.2702294 · DOI
- Pitt, L.F., Watson, R.T., Berthon, P., Wynn, D., Zinkhan, G.: The penguin's window: Corporate brands from an open-source perspective. Journal of the Academy of Marketing Science 34(2), 115-127 (2006)
- Pushkarna, M., Zaldivar, A., Kjartansson, O.: Data cards: Purposeful and transpar- ent dataset documentation for responsible ai. In: Proceedings of the 2022 ACM Conference on Fairness, Accountability, and Transparency, pp. 1776-1826 (2022)
- Quaye, J., Parrish, A., Inel, O., Rastogi, C., Kirk, H.R., Kahng, M., Van Liemt, E., Bartolo, M., Tsang, J., White, J., et al.: Adversarial nibbler: An open red-teaming method for identifying diverse harms in text-to-image generation. In: The 2024 ACM Conference on Fairness, Accountability, and Transparency, pp. 388-406 (2024)
- Ryan, R.M., Deci, E.L.: Intrinsic and extrinsic motivation from a self-determination the- ory perspective: Definitions, theory, practices, and future directions. Contemporary educational psychology 61, 101860 (2020)
- Rein, D., Hou, B.L., Stickland, A.C., Petty, J., Pang, R.Y., Dirani, J., Michael, J., Bowman, S.R.: Gpqa: A graduate-level google-proof q&a benchmark. arXiv preprint arXiv:2311.12022 (2023) · arXiv
- Reid, M., Savinov, N., Teplyashin, D., Lepikhin, D., Lillicrap, T., Alayrac, J.-b., Soricut, R., Lazaridou, A., Firat, O., Schrittwieser, J., et al.: Gemini 1.5: Unlocking multimodal understanding across millions of tokens of context. arXiv preprint arXiv:2403.05530 (2024) · arXiv
- Raji, I.D., Smart, A., White, R.N., Mitchell, M., Gebru, T., Hutchinson, B., Smith- Loud, J., Theron, D., Barnes, P.: Closing the ai accountability gap: defining an end-to-end framework for internal algorithmic auditing. In: Proceedings of the 2020 Conference on Fairness, Accountability, and Transparency. FAT* '20, pp. 33- 44. Association for Computing Machinery, New York, NY, USA (2020). https: //doi.org/10.1145/3351095.3372873 . https://doi.org/10.1145/3351095.3372873 · DOI · Paper page
- Radford, A., Wu, J., Child, R., Luan, D., Amodei, D., Sutskever, I.: Language models are unsupervised multitask learners. OpenAI Blog 1, 9 (2019)
- Seth, A., Ahuja, S., Bali, K., Sitaram, S.: Dosa: A dataset of social artifacts from different indian geographical subcultures. arXiv preprint arXiv:2403.14651 (2024) · arXiv
- Shimorina, A., Belz, A.: The human evaluation datasheet 1.0: A template for recording details of human evaluation experiments in nlp. arXiv preprint arXiv:2103.09710 (2021) · arXiv
- Santurkar, S., Durmus, E., Ladhak, F., Lee, C., Liang, P., Hashimoto, T.: Whose opinions do language models reflect? In: International Conference on Machine Learning, pp. 29971-30004 (2023).
- PMLR
- Schick, T., Dwivedi-Yu, J., Dessì, R., Raileanu, R., Lomeli, M., Hambro, E., Zettlemoyer, L., Cancedda, N., Scialom, T.: Toolformer: Language models can teach themselves to use tools. Advances in Neural Information Processing Systems 36 (2024)
- Scao, T.L., Fan, A., Akiki, C., Pavlick, E., Ilic, S., Hesslow, D., Castagné, R., Luc- cioni, A.S., Yvon, F., Gallé, M., Tow, J., Rush, A.M., Biderman, S., Webson, A., Ammanamanchi, P.S., Wang, T., Sagot, B., Muennighoff, N., Moral, A.V., Ruwase, O., Bawden, R., Bekman, S., McMillan-Major, A., Beltagy, I., Nguyen, H., Saulnier, L., Tan, S., Suarez, P.O., Sanh, V., Laurençon, H., Jernite, Y., Launay, J., Mitchell, M., Raffel, C., Gokaslan, A., Simhi, A., Soroa, A., Aji, A.F., Alfassy, A., Rogers, A., Nitzav, A.K., Xu, C., Mou, C., Emezue, C., Klamm, C., Leong, C., Strien, D., Adelani, D.I., al.: BLOOM: A 176b-parameter open-access multilingual language model. CoRR abs/2211.05100 (2022) https://doi.org/10.48550/ARXIV.2211.05100 2211.05100 · DOI · Paper page
- Shah, S.K.: Motivation, governance, and the viability of hybrid forms in open source software development. Management science 52(7), 1000-1014 (2006)
- Shi, W., Lee, J., Huang, Y., Malladi, S., Zhao, J., Holtzman, A., Liu, D., Zettlemoyer, L., Smith, N.A., Zhang, C.: Muse: Machine unlearning six-way evaluation for language models. arXiv preprint arXiv:2407.06460 (2024) · arXiv
- Sloane, M., Moss, E., Awomolo, O., Forlano, L.: Participation is not a design fix for machine learning. In: Proceedings of the 2nd ACM Conference on Equity and Access in Algorithms, Mechanisms, and Optimization, pp. 1-6 (2022)
- Stiennon, N., Ouyang, L., Wu, J., Ziegler, D., Lowe, R., Voss, C., Radford, A., Amodei, D., Christiano, P.F.: Learning to summarize with human feedback. In: Advances in Neural Information Processing Systems, vol. 33, pp. 3008-3021.
- Subramanyam, R., Xia, M.: Free/libre open source software development in developing and developed countries: A conceptual framework with an exploratory study. Decision support systems 46(1), 173-186 (2008)
- Team, G., Anil, R., Borgeaud, S., Wu, Y., Alayrac, J.-B., Yu, J., Soricut, R., Schalkwyk, J., Dai, A.M., Hauth, A., et al.: Gemini: a family of highly capable multimodal models. arXiv preprint arXiv:2312.11805 (2023) · arXiv
- Takhteyev, Y.: Coding places: Software practice in a south american city. Mit Press (2012)
- Thoppilan, R., De Freitas, D., Hall, J., Shazeer, N., Kulshreshtha, A., Cheng, H.- T., Jin, A., Bos, T., Baker, L., Du, Y., et al.: Lamda: Language models for dialog applications. arXiv preprint arXiv:2201.08239 (2022) · arXiv
- Thorat, P.B., Goudar, R.M., Barve, S.: Survey on collaborative filtering, content-based filtering and hybrid recommendation system. International Journal of Computer Applications 110(4), 31-36 (2015)
- Tran, V.H., Mehrotra, A., Chetty, M., Feamster, N., Frankenreiter, J., Strahilevitz, L.: Measuring compliance with the california consumer privacy act over space and time. In: Proceedings of the CHI Conference on Human Factors in Computing Systems, pp. 1-19 (2024)
- Touvron, H., Martin, L., Stone, K., Albert, P., Almahairi, A., Babaei, Y., Bashlykov, N., Batra, S., Bhargava, P., Bhosale, S., et al.: Llama 2: Open foundation and fine-tuned chat models. arXiv preprint arXiv:2307.09288 (2023) · arXiv
- Tsatsou, P.: Digital divides revisited: what is new about divides and their research? Media, Culture & Society 33(2), 317-331 (2011)
- Von Krogh, G., Haefliger, S., Spaeth, S., Wallin, M.W.: Carrots and rainbows: Motiva- tion and social practice in open source software development. MIS quarterly, 649-676 (2012)
- Wang, Z., Dong, Y., Delalleau, O., Zeng, J., Shen, G., Egert, D., Zhang, J.J., Sreedhar, M.N., Kuchaiev, O.: Helpsteer2: Open-source dataset for training top-performing reward models. arXiv preprint arXiv:2406.08673 (2024) · arXiv
- White, C., Dooley, S., Roberts, M., Pal, A., Feuer, B., Jain, S., Shwartz-Ziv, R., Jain, N., Saifullah, K., Naidu, S., Hegde, C., LeCun, Y., Goldstein, T., Neiswanger, W., Goldblum, M.: LiveBench: A Challenging, Contamination-Free LLM Benchmark (2024). https://arxiv.org/abs/2406.19314 · arXiv
- West, J., Gallagher, S.: Challenges of open innovation: the paradox of firm investment in open-source software. R&D Management 36(3), 319-331 (2006)
- White, M., Haddad, I., Osborne, C., Abdelmonsef, A., Varghese, S., et al.: The Model Openness Framework: Promoting Completeness and Openness for Reproducibility, Transparency and Usability in AI. arXiv preprint arXiv:2403.13784 (2024) · arXiv
- Wu, S., Irsoy, O., Lu, S., Dabravolski, V., Dredze, M., Gehrmann, S., Kambadur, P., Rosenberg, D., Mann, G.: Bloomberggpt: A large language model for finance. arXiv preprint arXiv:2303.17564 (2023) · arXiv
- Zhao, W., Chiu, J., Hwang, J., Brahman, F., Hessel, J., Choudhury, S., Choi, Y., Li, X., Suhr, A.: UNcommonsense reasoning: Abductive reasoning about uncommon situations. In: Duh, K., Gomez, H., Bethard, S. (eds.) Proceedings of the 2024 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies (Volume 1: Long Papers), pp. 8487- 8505. Association for Computational Linguistics, Mexico City, Mexico (2024). https: //aclanthology.org/2024.naacl-long.469
- Zheng, L., Chiang, W.-L., Sheng, Y., Zhuang, S., Wu, Z., Zhuang, Y., Lin, Z., Li, Z., Li, D., Xing, E., Zhang, H., Gonzalez, J.E., Stoica, I.: Judging LLM-as-a-Judge with MT-Bench and Chatbot Arena. Advances in Neural Information Processing Systems 36, 46595-46623 (2023). Accessed 2024-04-01
- Zheng, L., Chiang, W.-L., Sheng, Y., Li, T., Zhuang, S., Wu, Z., Zhuang, Y., Li, Z., Lin, Z., Xing, E., Gonzalez, J.E., Stoica, I., Zhang, H.: LMSYS-chat-1m: A large-scale real-world LLM conversation dataset. In: The Twelfth International Conference on Learning Representations (2024). https://openreview.net/forum?id=BOfDKxfwt0
- Zhao, W., Ren, X., Hessel, J., Cardie, C., Choi, Y., Deng, Y.: Wildchat: 1m chatGPT interaction logs in the wild. In: The Twelfth International Conference on Learning Representations (2024). https://openreview.net/forum?id=Bl8u7ZRlbM
- Zuckerman, E., Rajendra-Nicolucci, C.: From community governance to customer service and back again: re-examining pre-web models of online governance to address platforms' crisis of legitimacy. Social Media+ Society 9(3), 20563051231196864 (2023)
Cited by
Singh, S., Nan, Y., Wang, A., D'Souza, D., Kapoor, S., Üstün, A., Koyejo, S., Deng, Y., Longpre, S., Smith, N. A., et al. (2025) · arXiv · doi:10.48550/arxiv.2504.20879 · Cited by 108
Self-citation
Metadata
- Authors
- Don-Yehiya, S., Burtenshaw, B., Astudillo, R. F., Osborne, C., Jaiswal, M., Kuo, T.-S., Zhao, W., Shenfeld, I., Peng, A., Yurochkin, M., Kasirzadeh, A., Huang, Y., Hashimoto, T., Jernite, Y., Vila-Suero, D., Abend, O., Ding, J., Hooker, S., Kirk, H. R., & Choshen, L.
- Venue
- arXiv
- Publisher
- arXiv
- Published
- 2024
- arXiv
- 2408.16961
- References
- 0
- Type
- Preprint
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
